
Technical Schematic Speculative Decoding Llm Stock Illustration
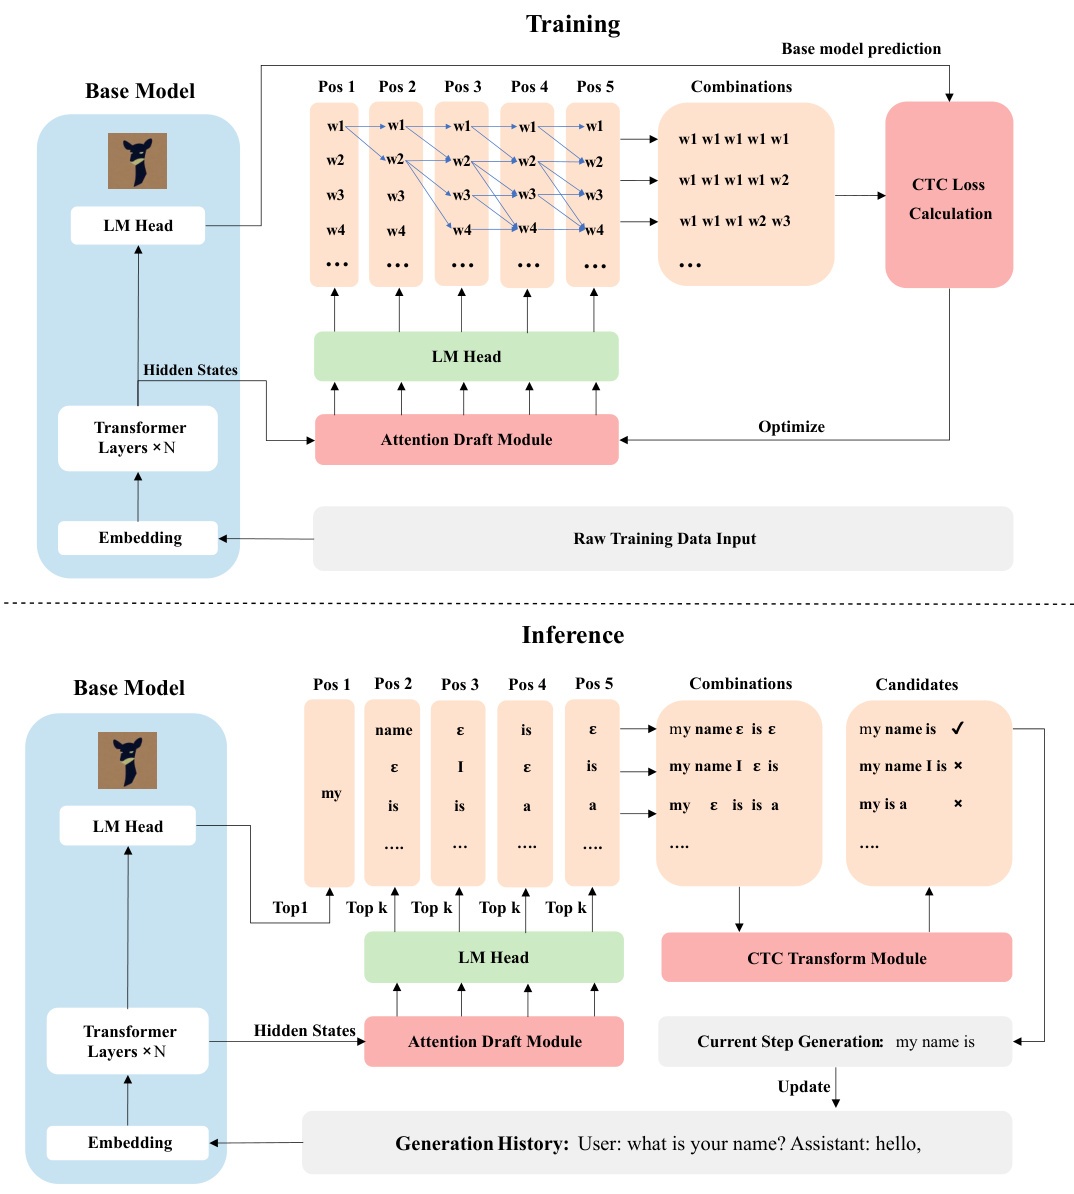
Speculative Decoding with CTC-based Draft Model for LLM Inference ...
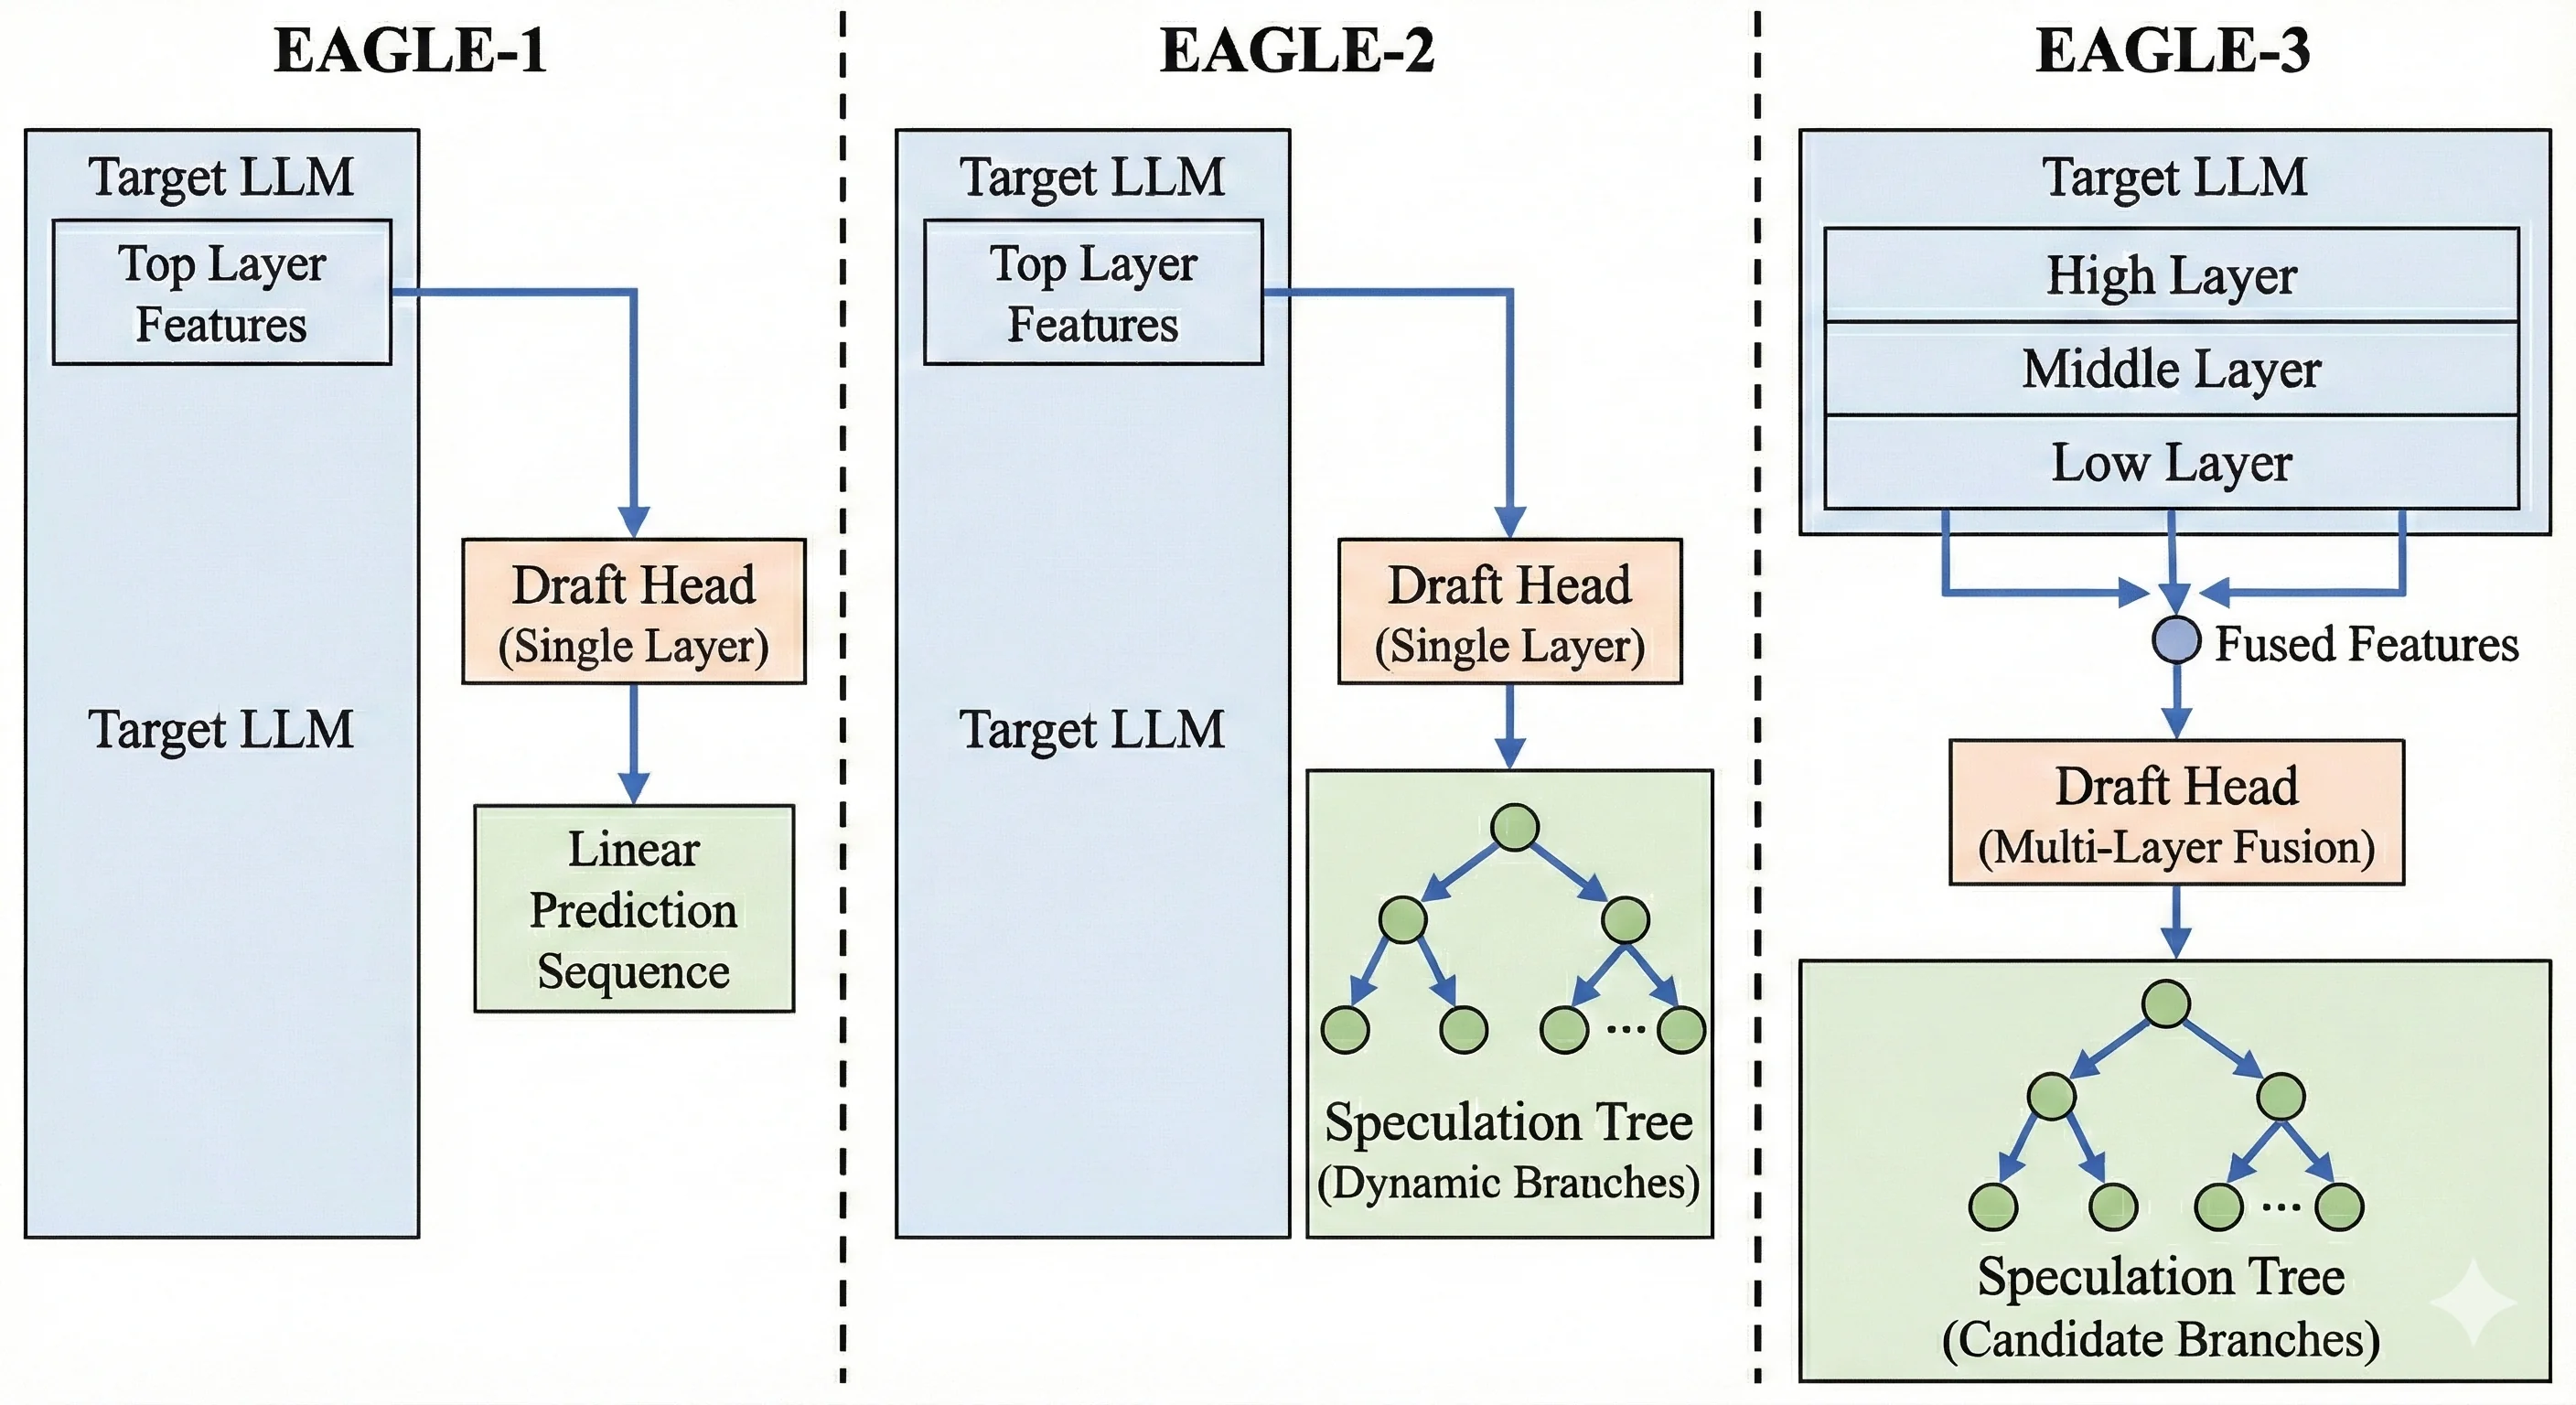
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...

[논문 리뷰] SLED: A Speculative LLM Decoding Framework for Efficient Edge ...
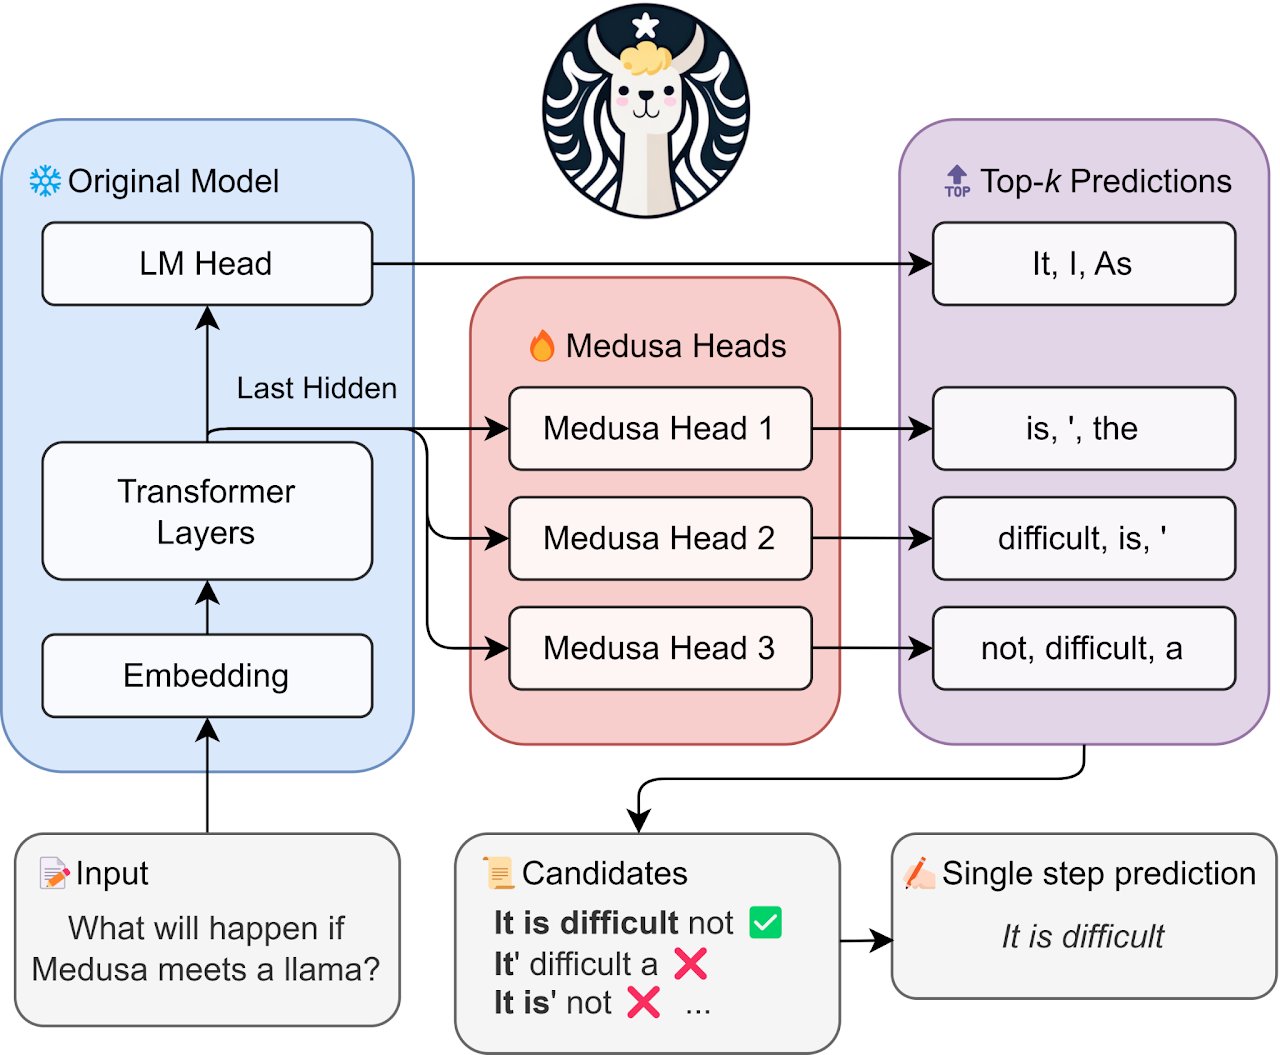
Accelerate LLM Inference with Speculative Decoding | Charles Xu

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...
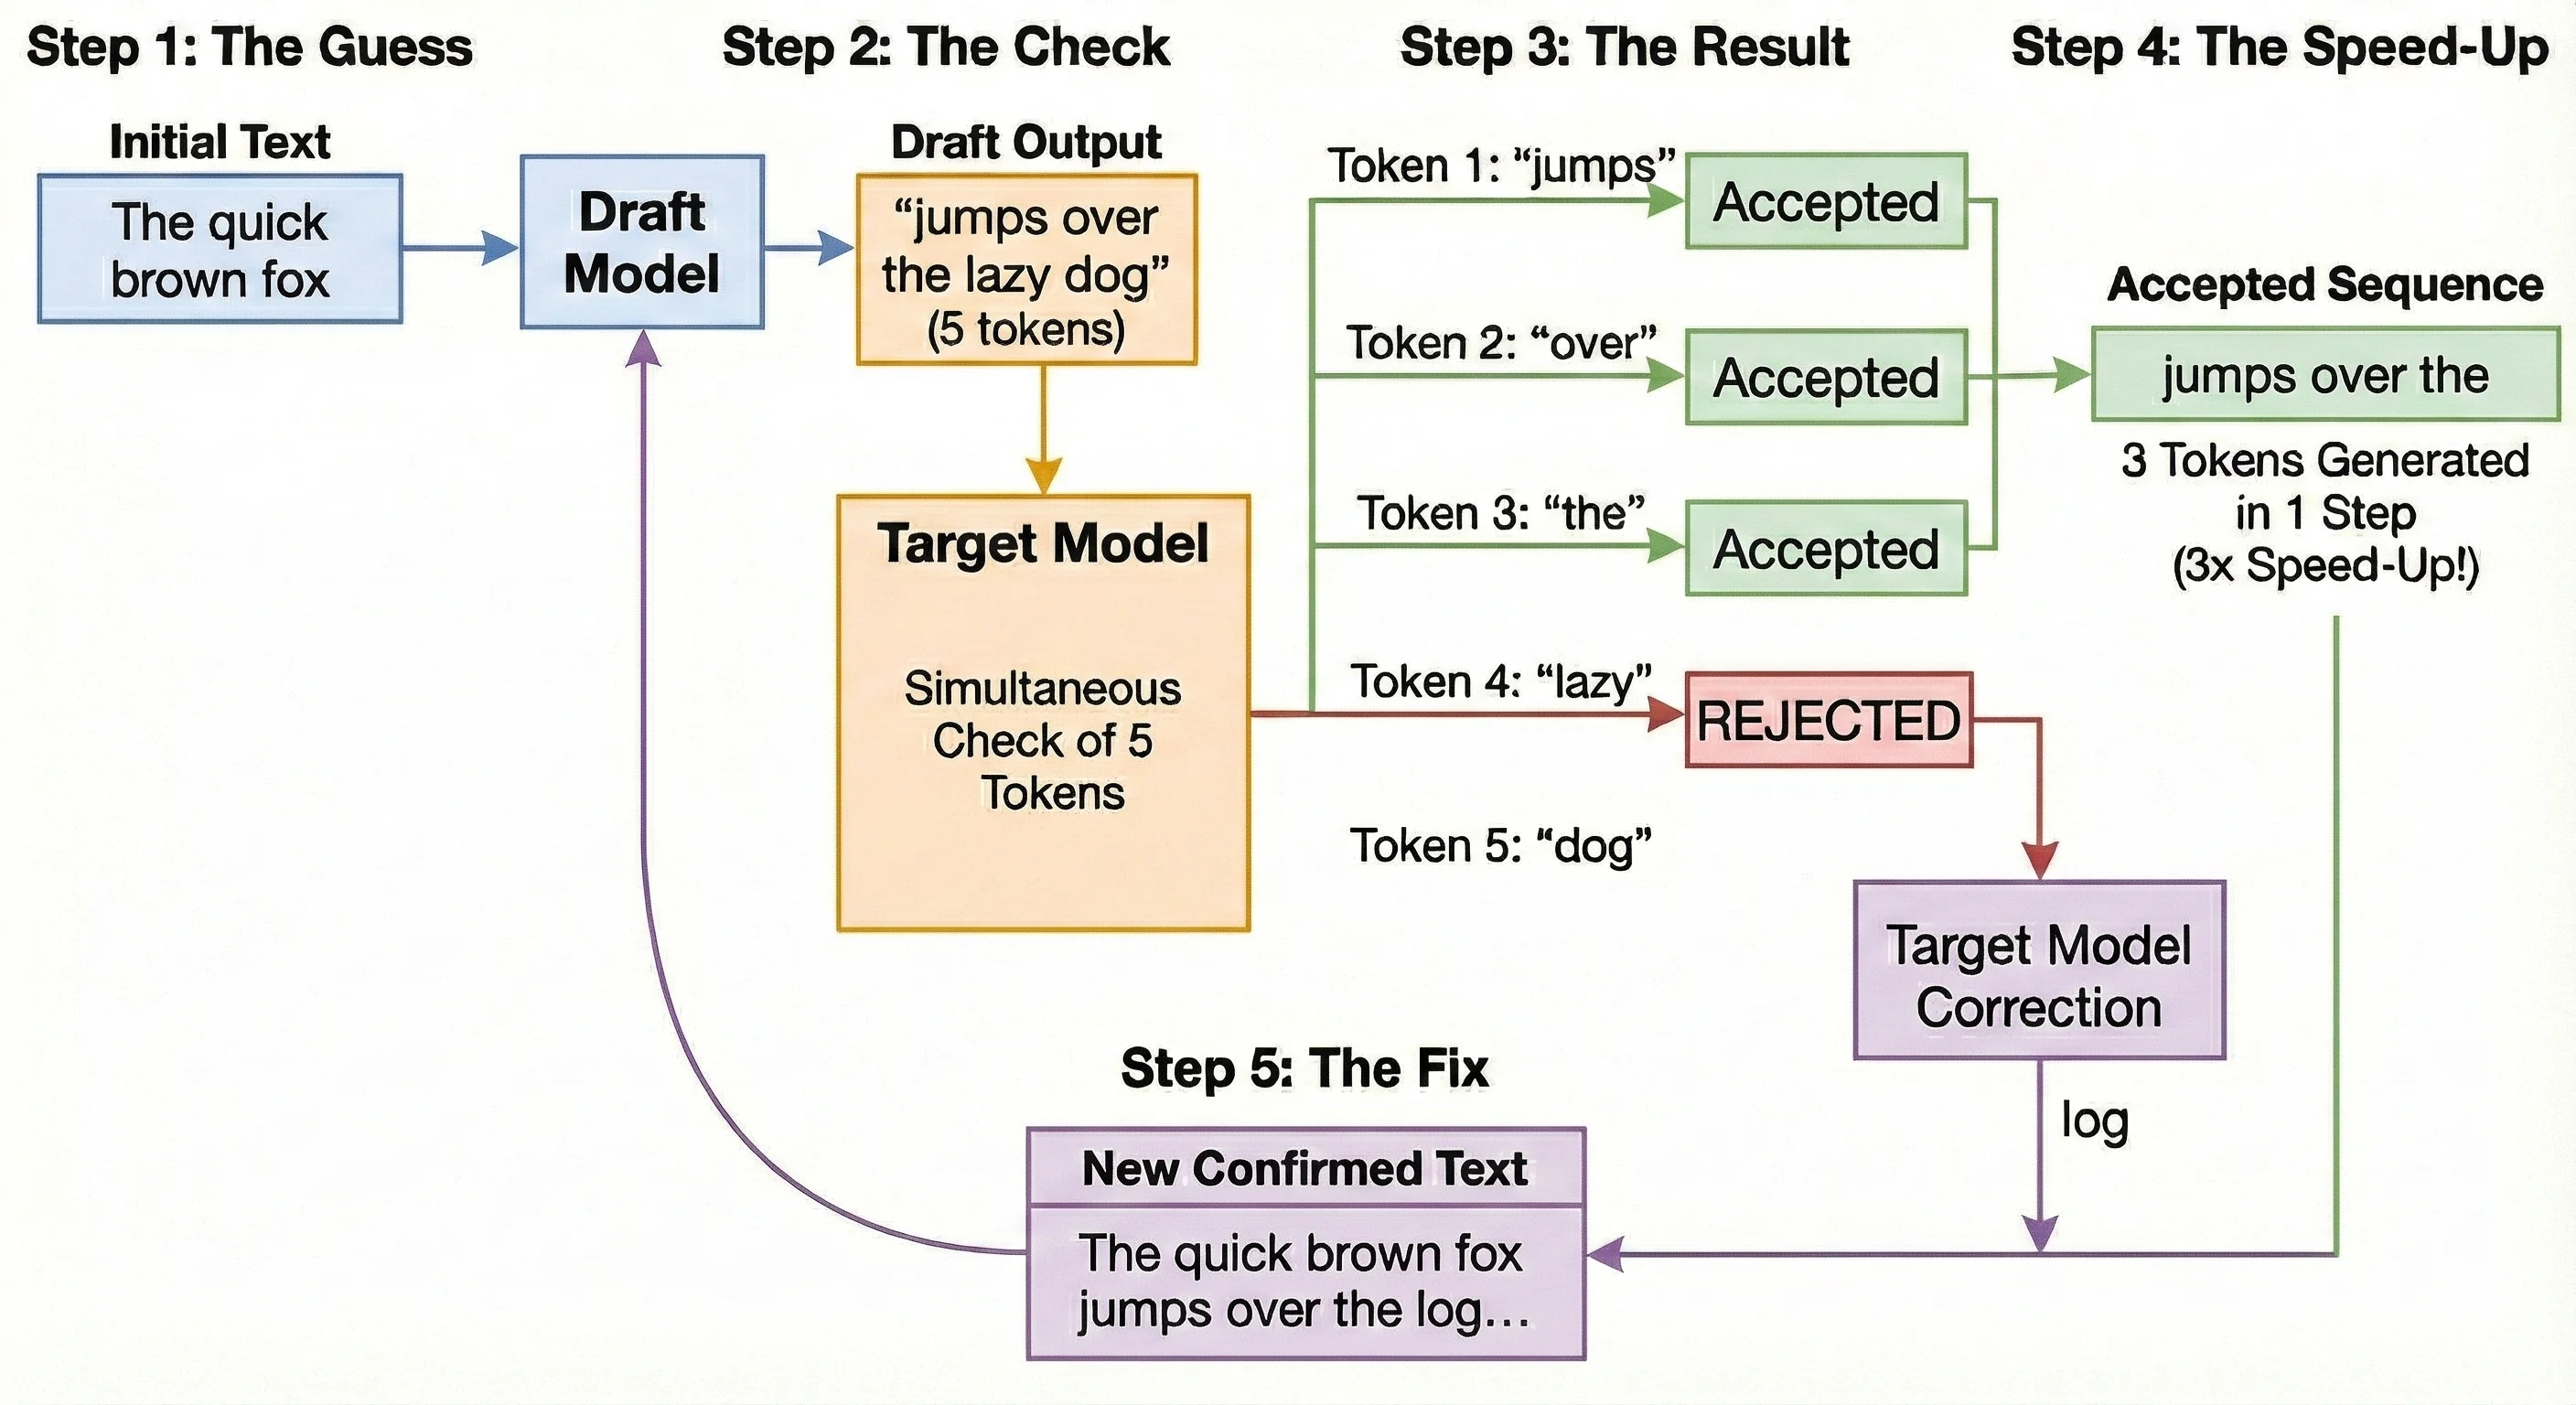
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
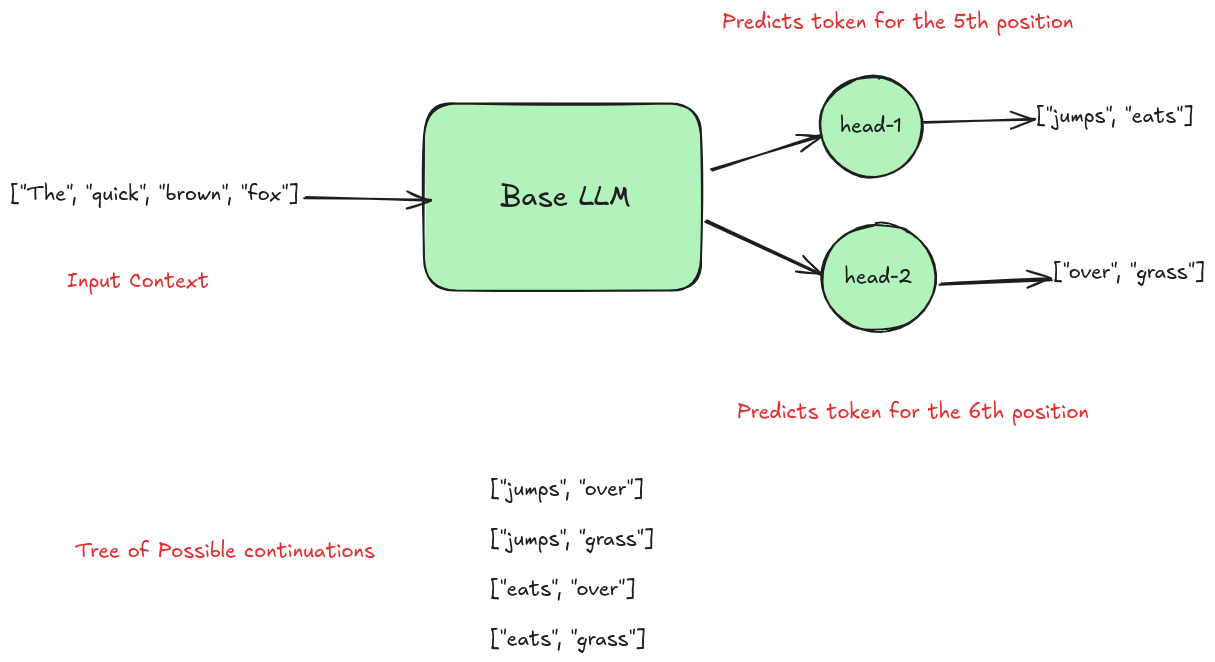
A Survey of Speculative Decoding Techniques in LLM Inference
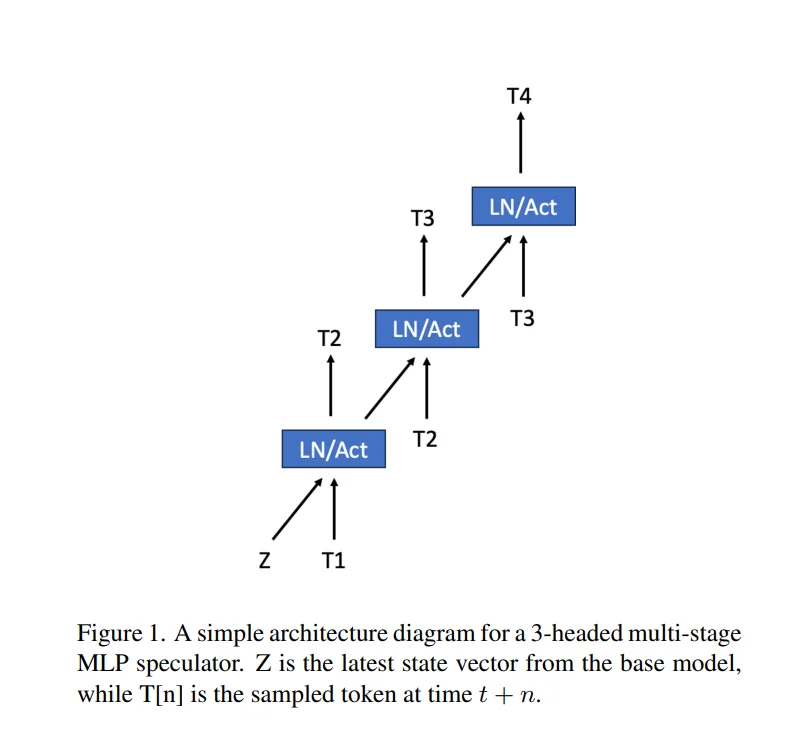
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
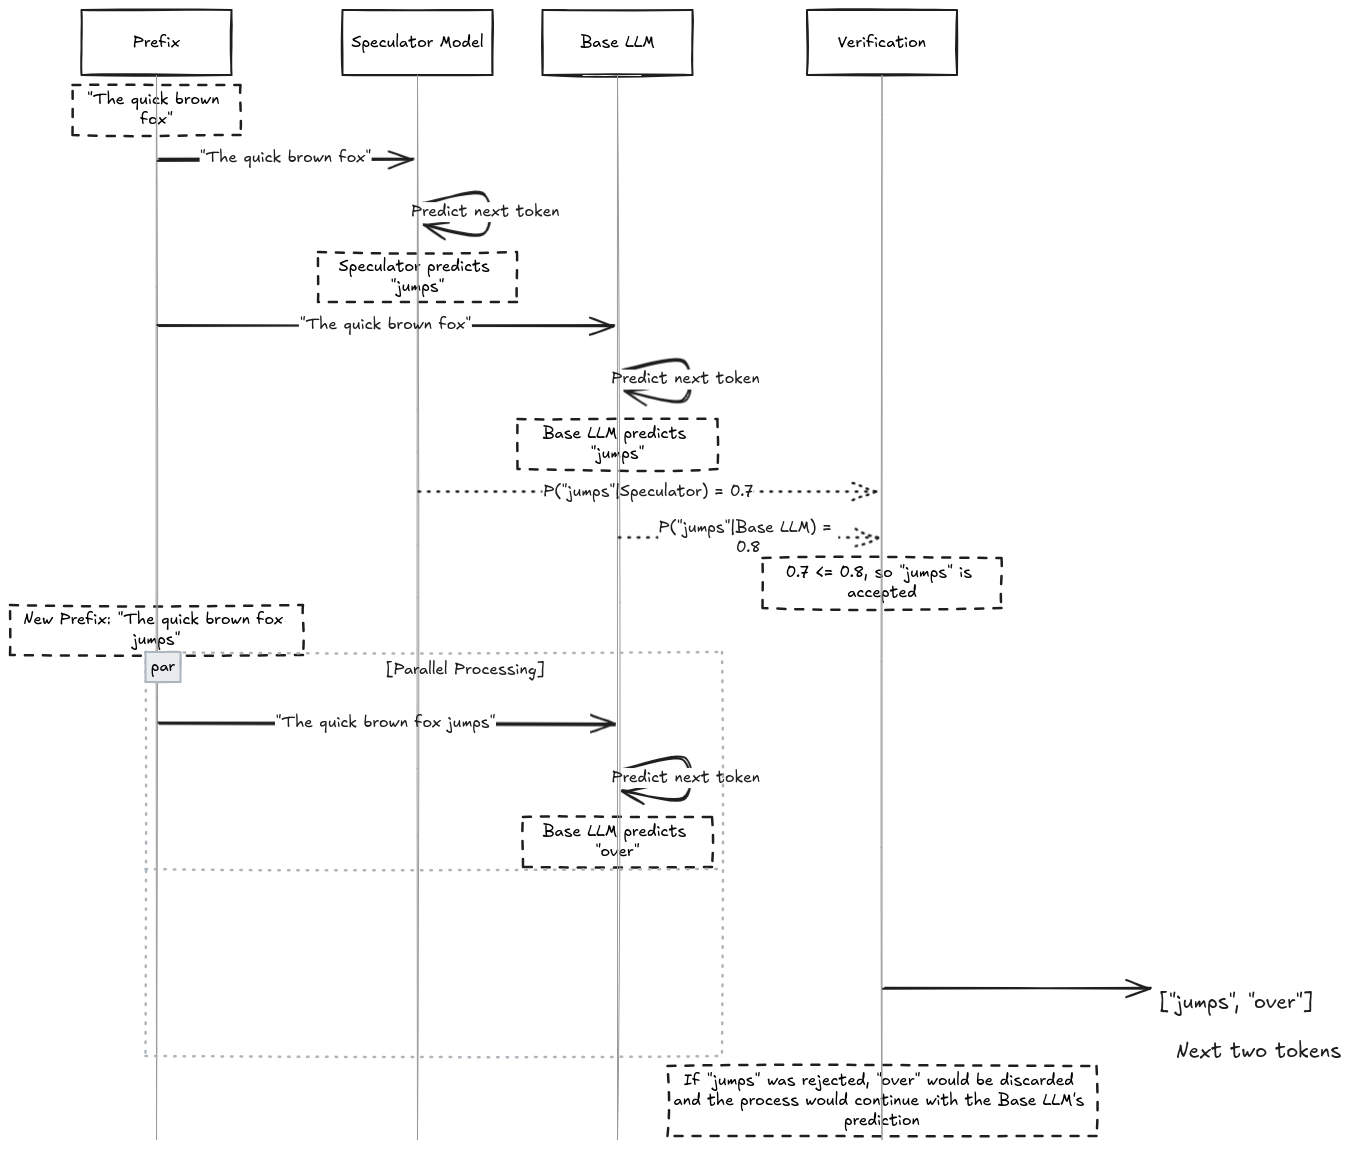
A Survey of Speculative Decoding Techniques in LLM Inference
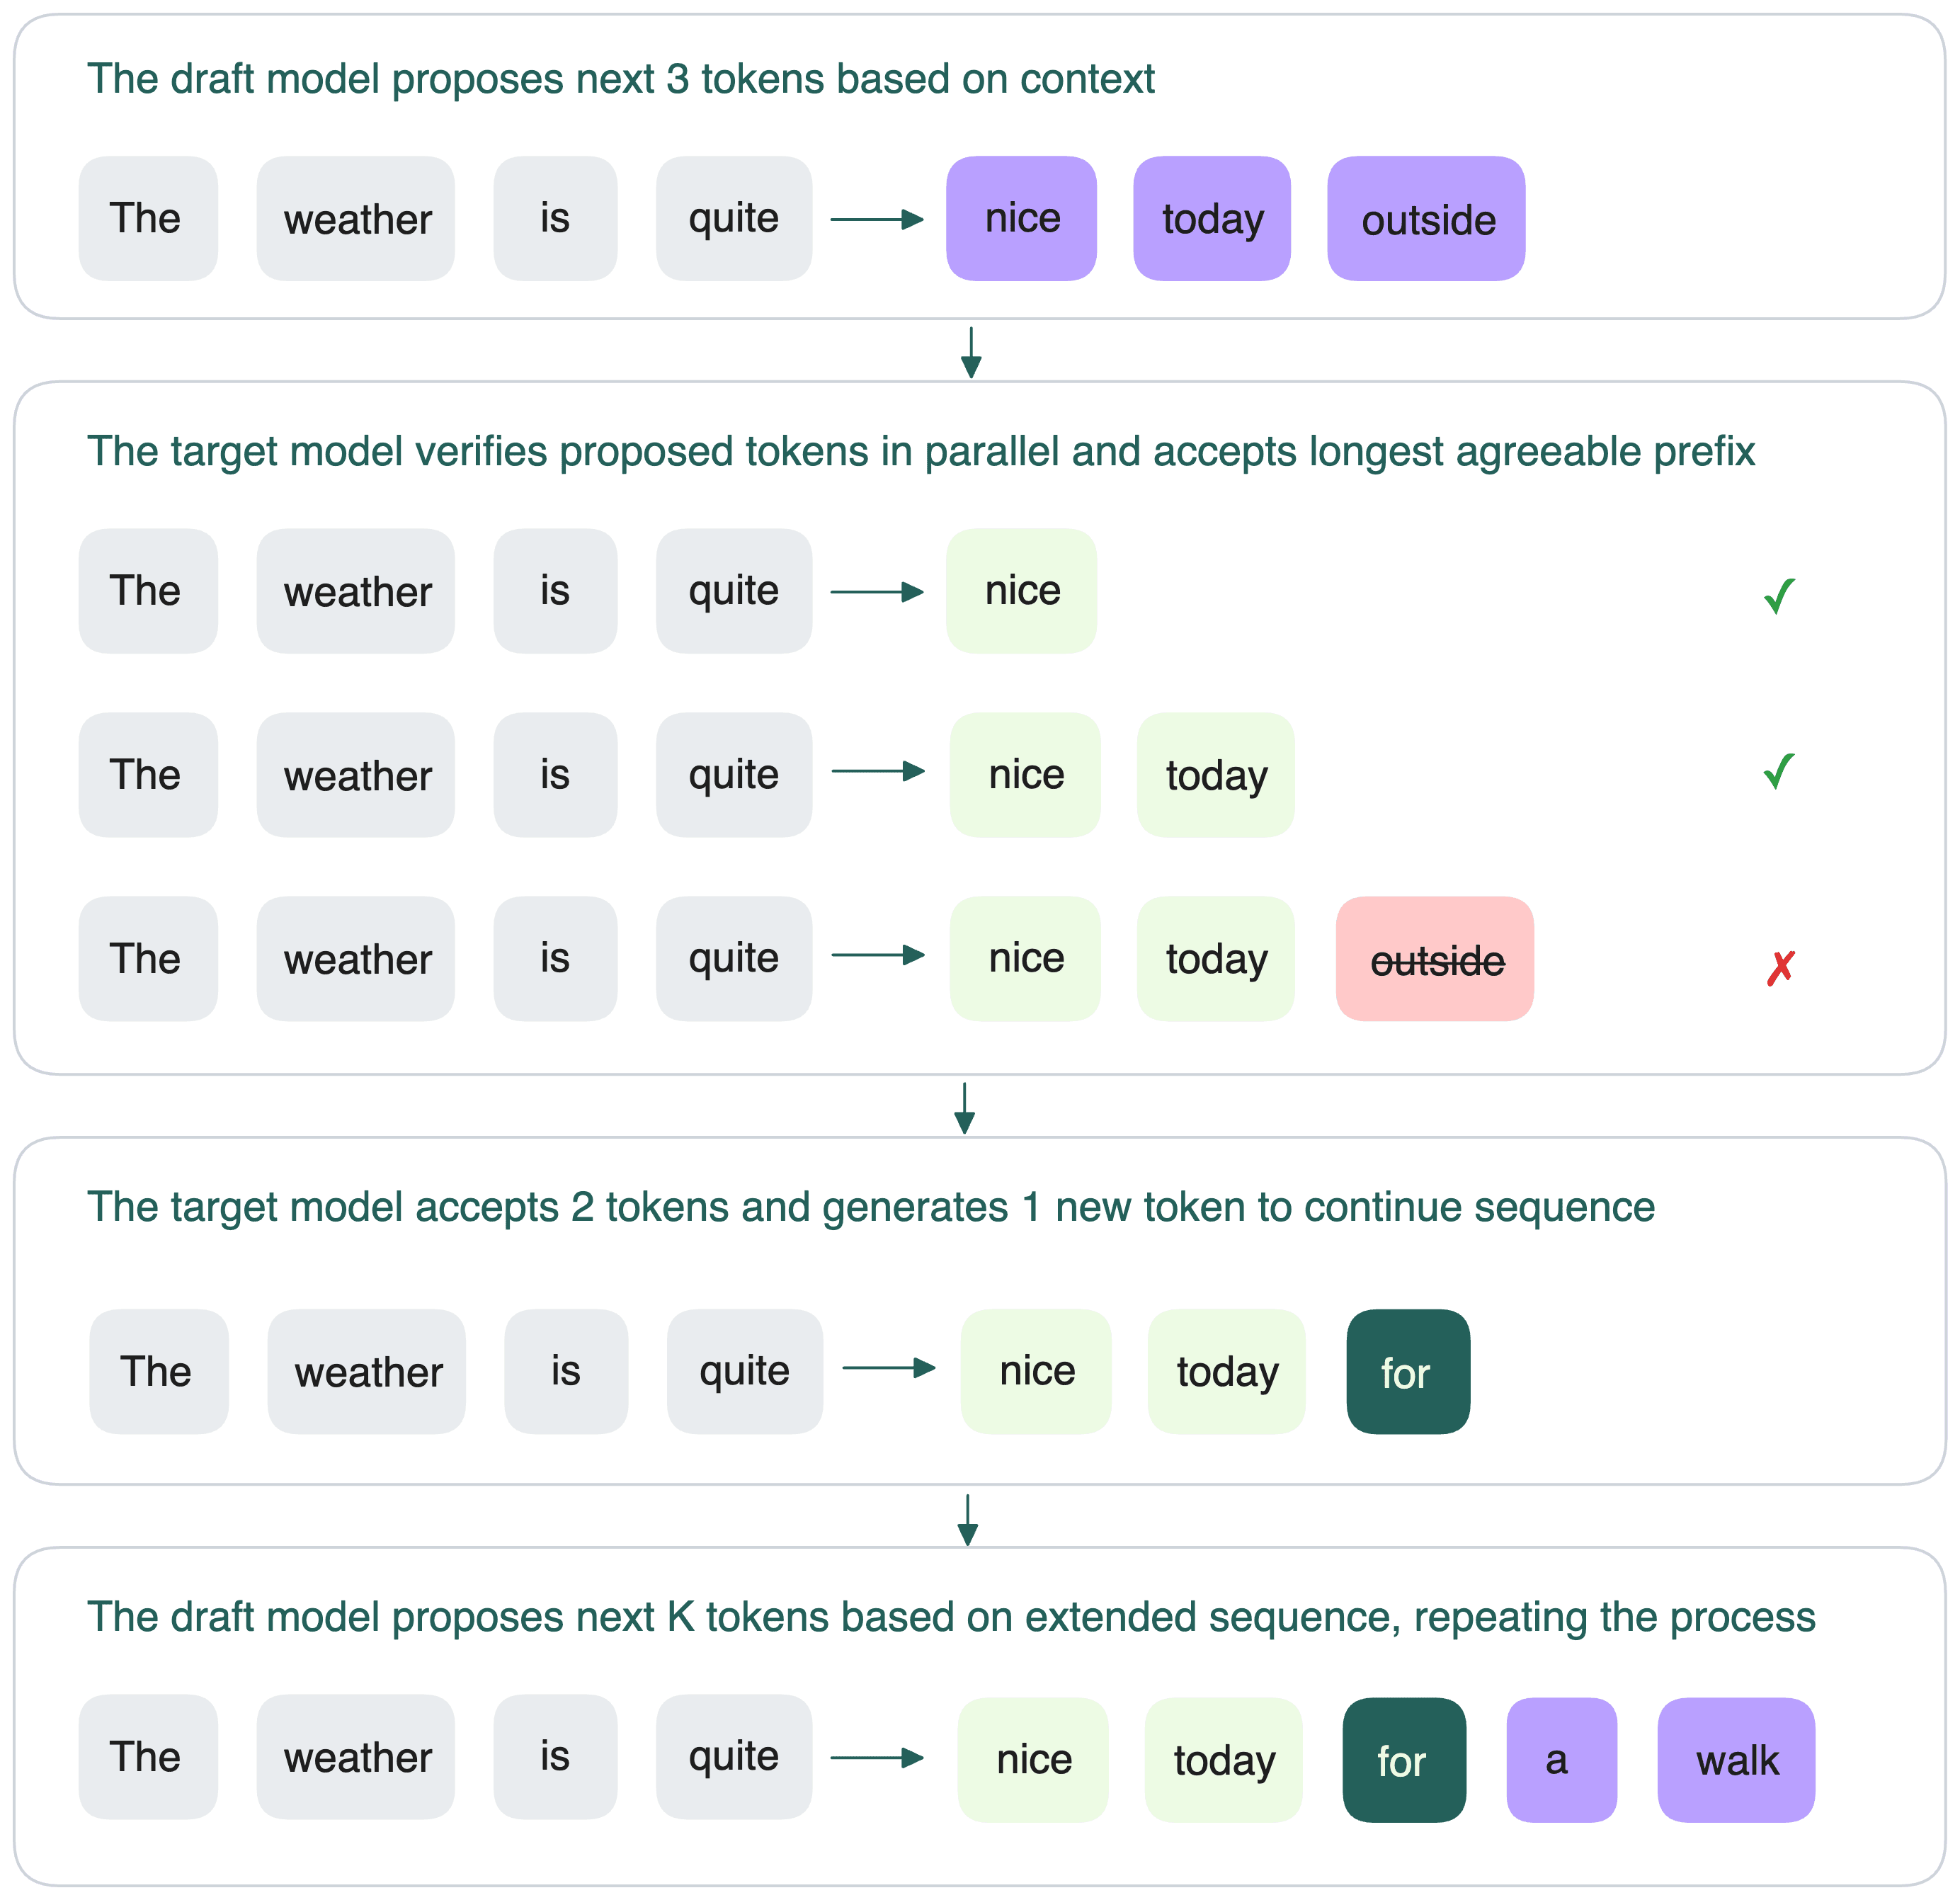
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...
Advertisement Space (300x250)
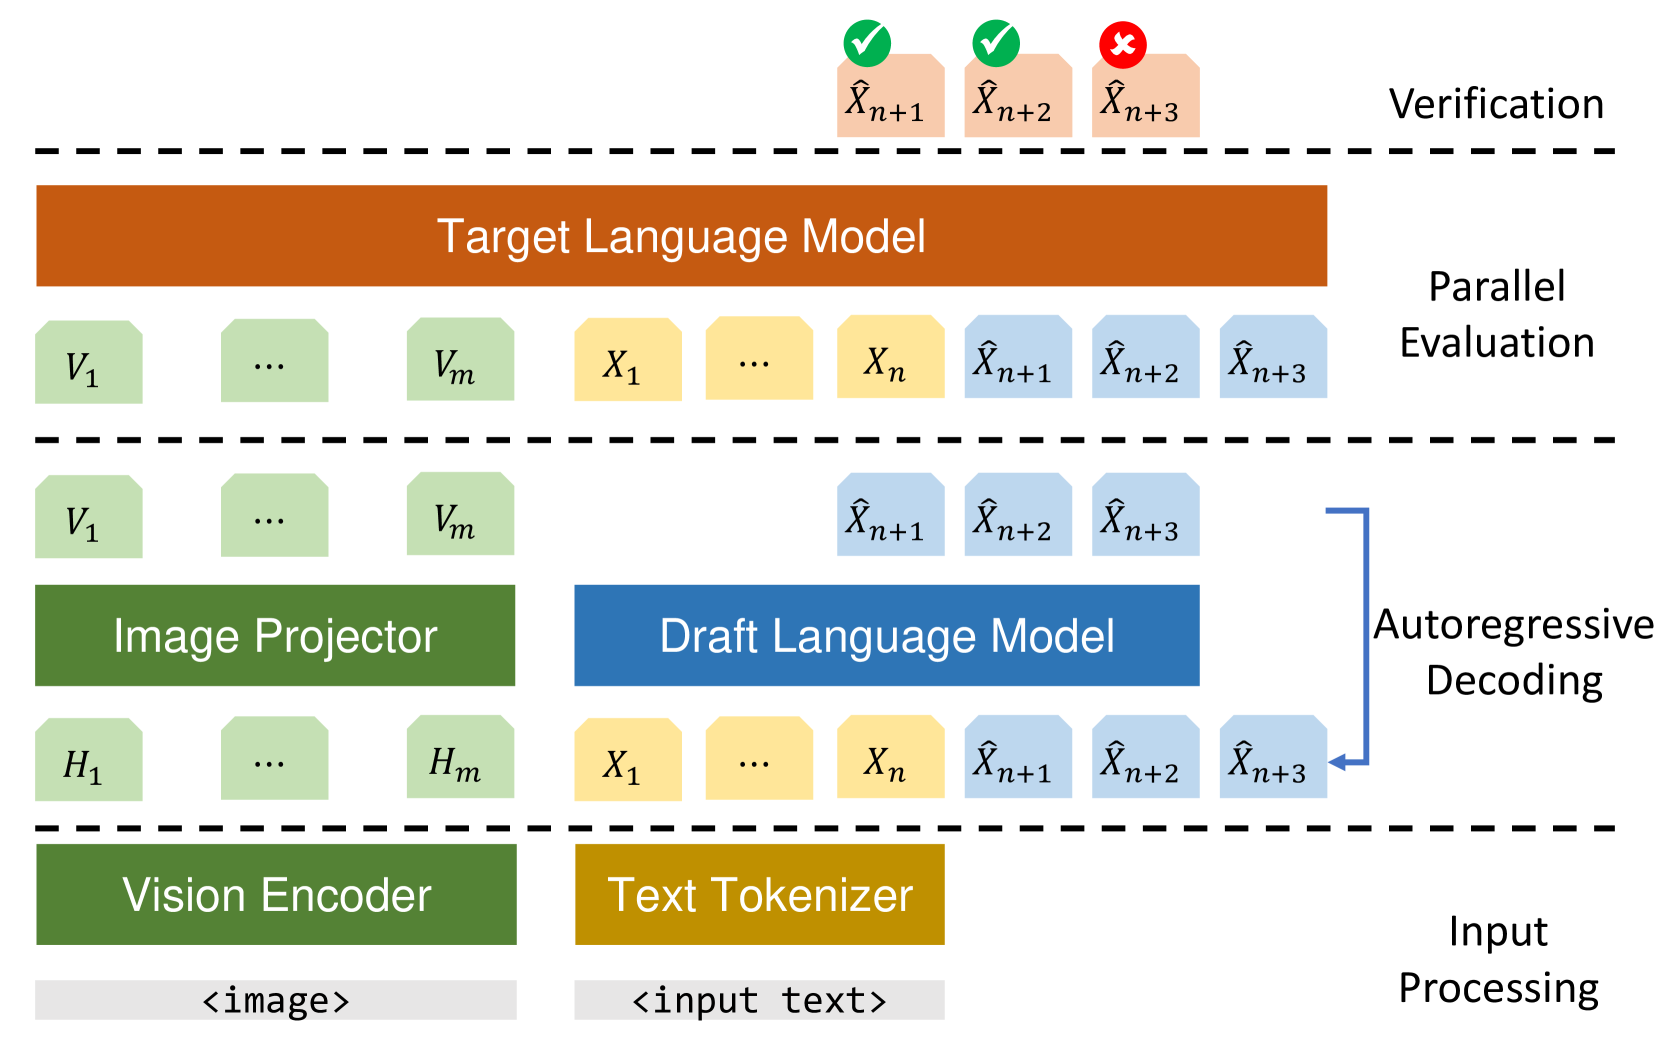
SpecExec: Massively Parallel Speculative Decoding for Interactive LLM ...

SSD 一个实现 Speculative Speculative Decoding 的 LLM 高性能推理引擎 → 把传统 ...

[논문 리뷰] SDSAT: Accelerating LLM Inference through Speculative Decoding ...
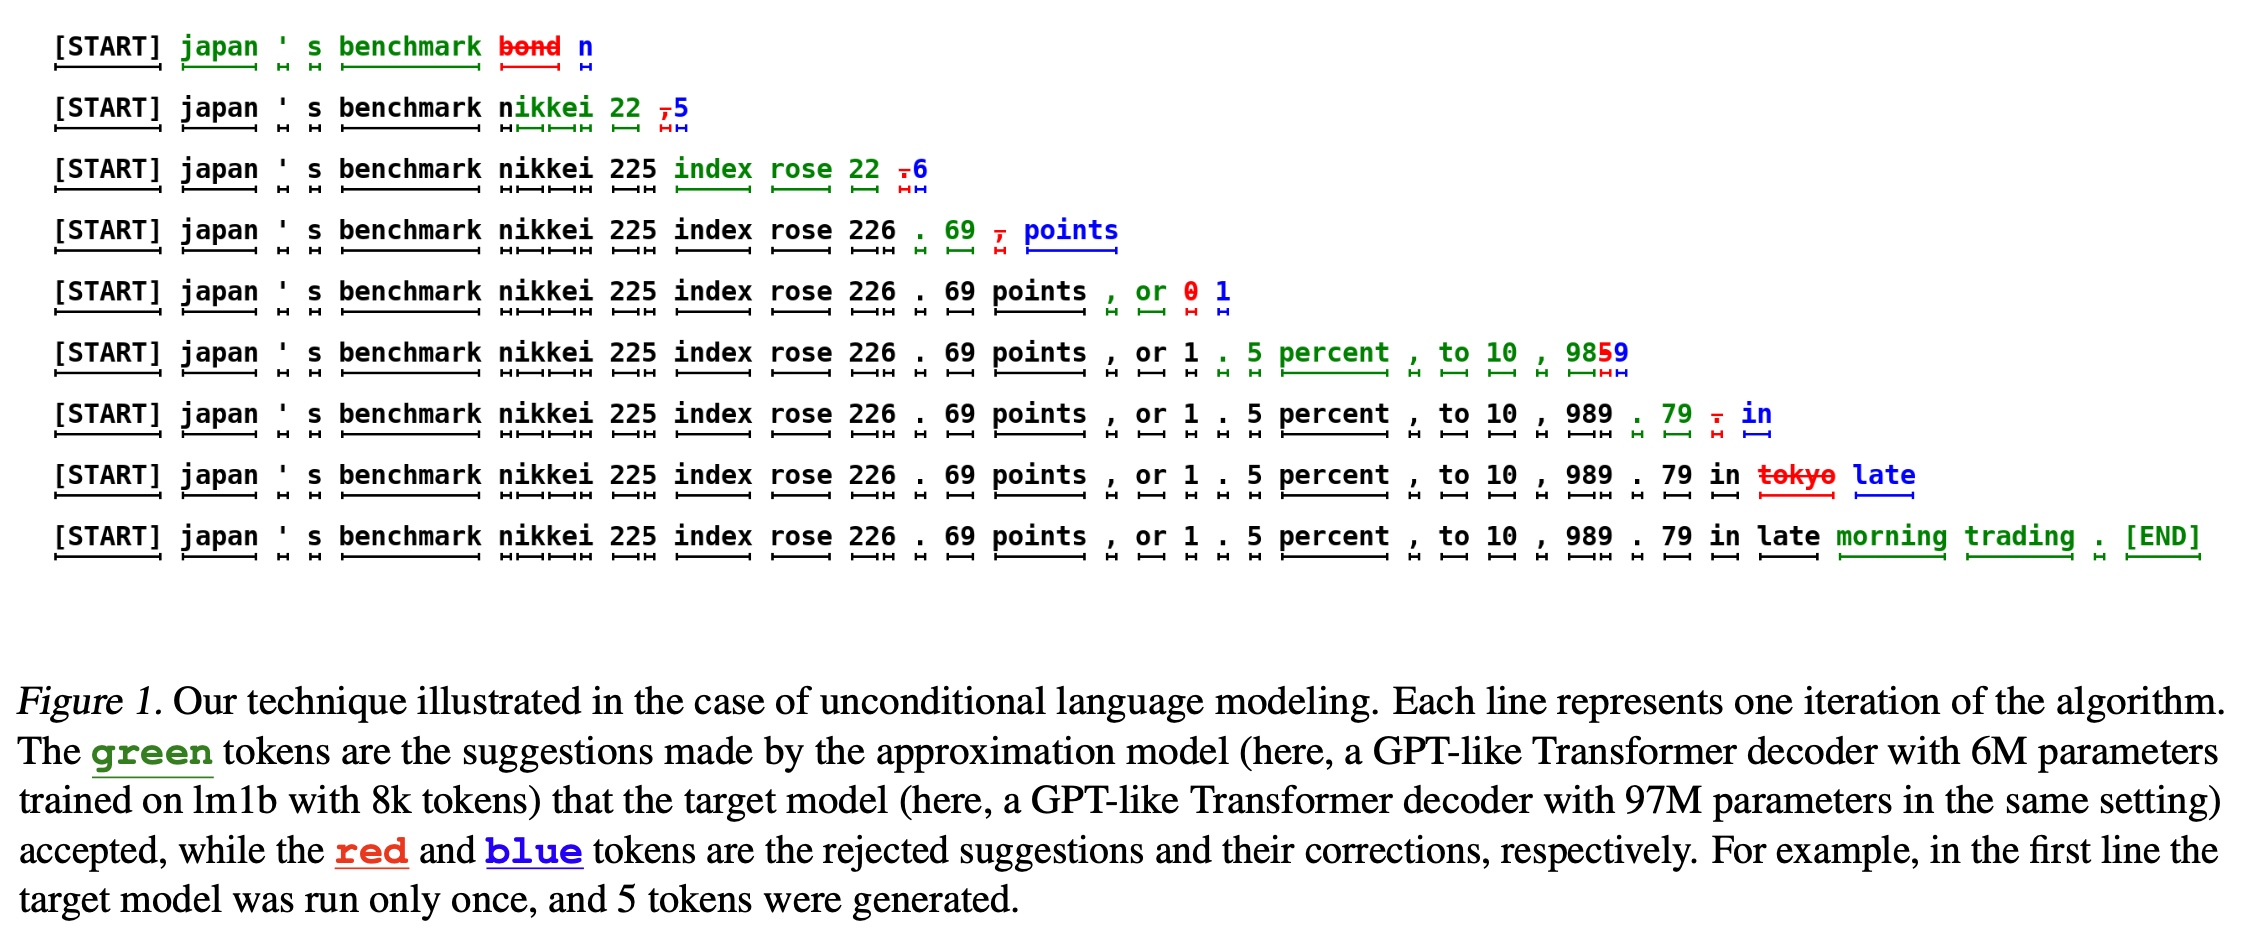
Accelerate LLM Inference with Speculative Decoding | Charles Xu

[논문 리뷰] Reward-Guided Speculative Decoding for Efficient LLM Reasoning
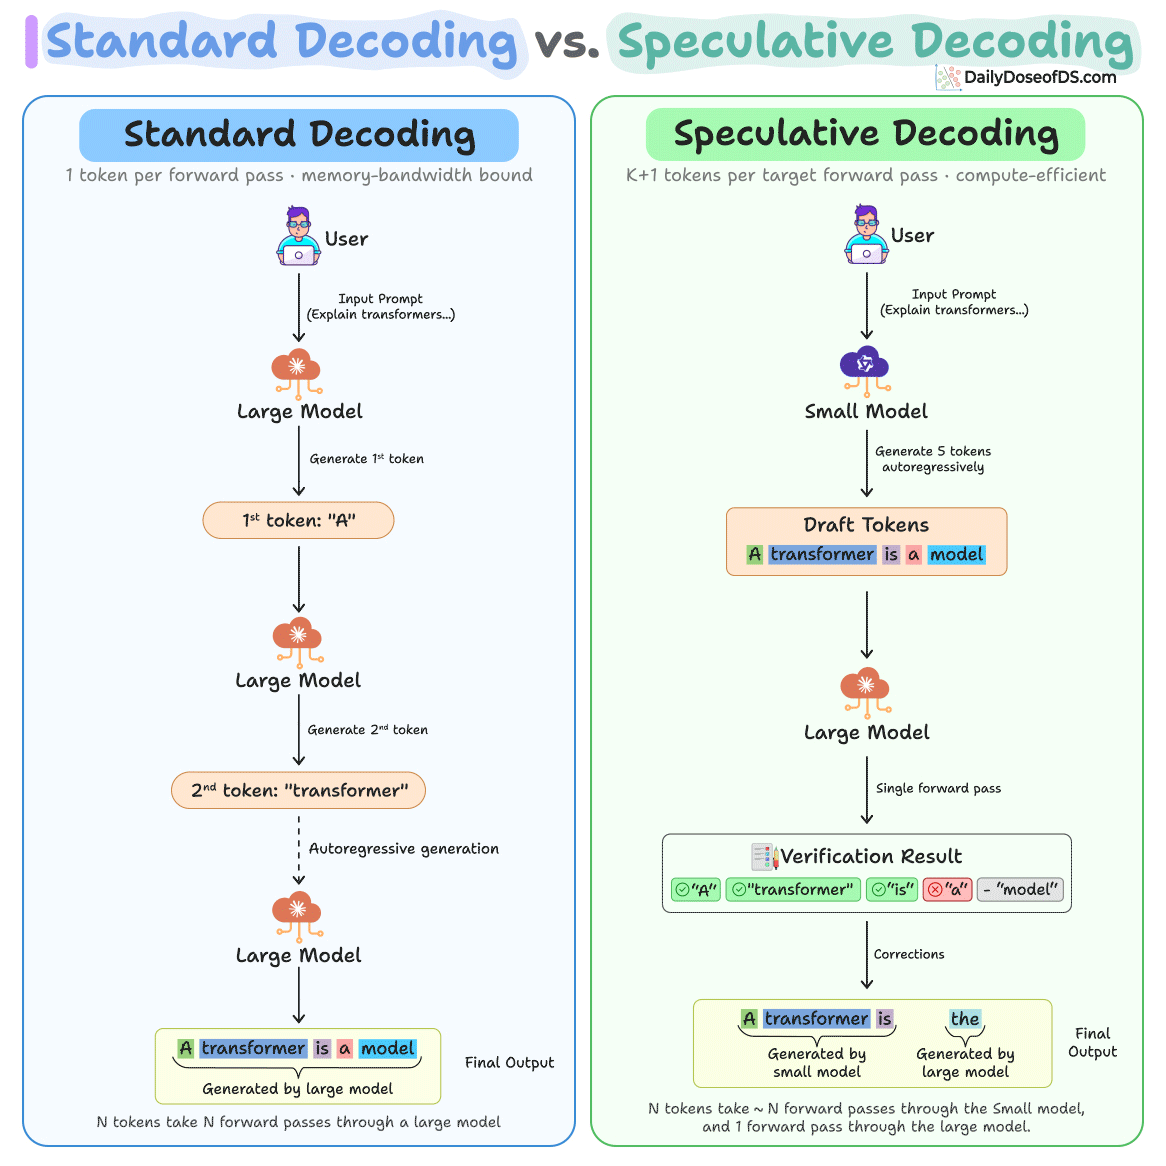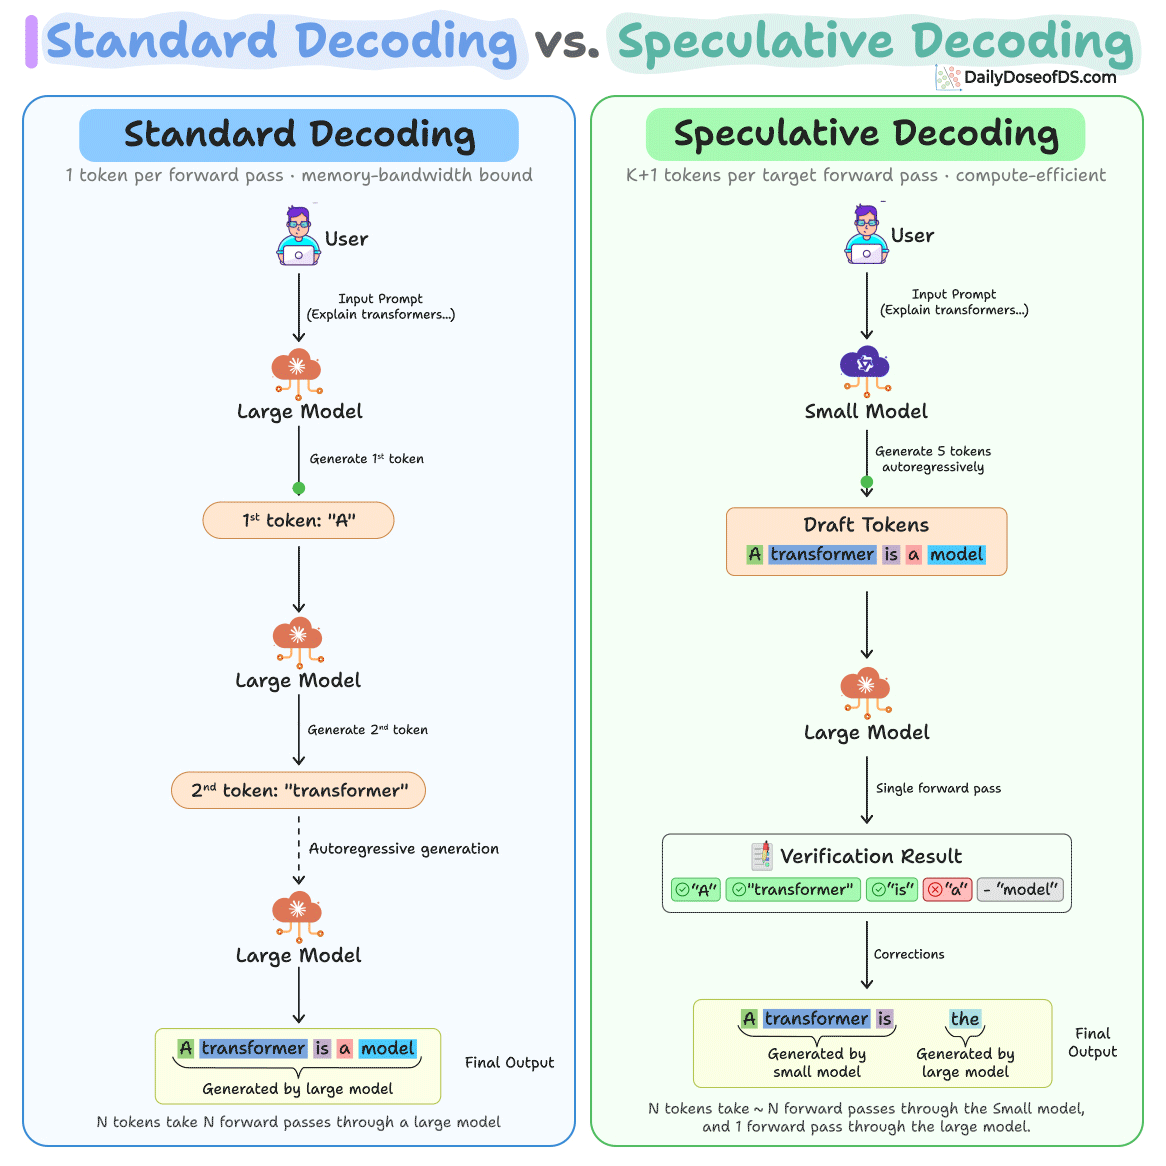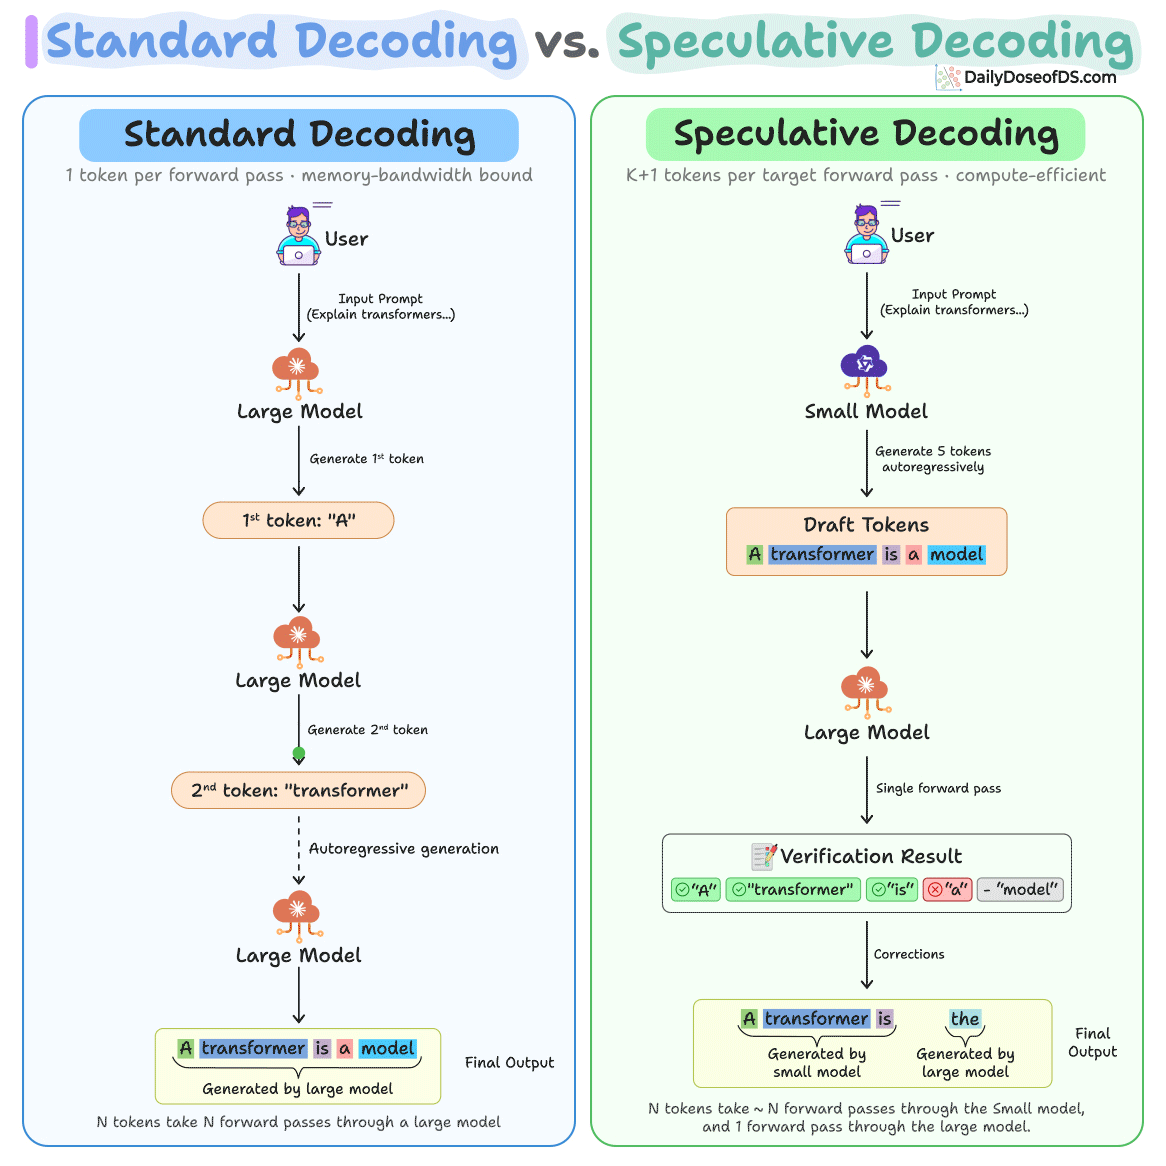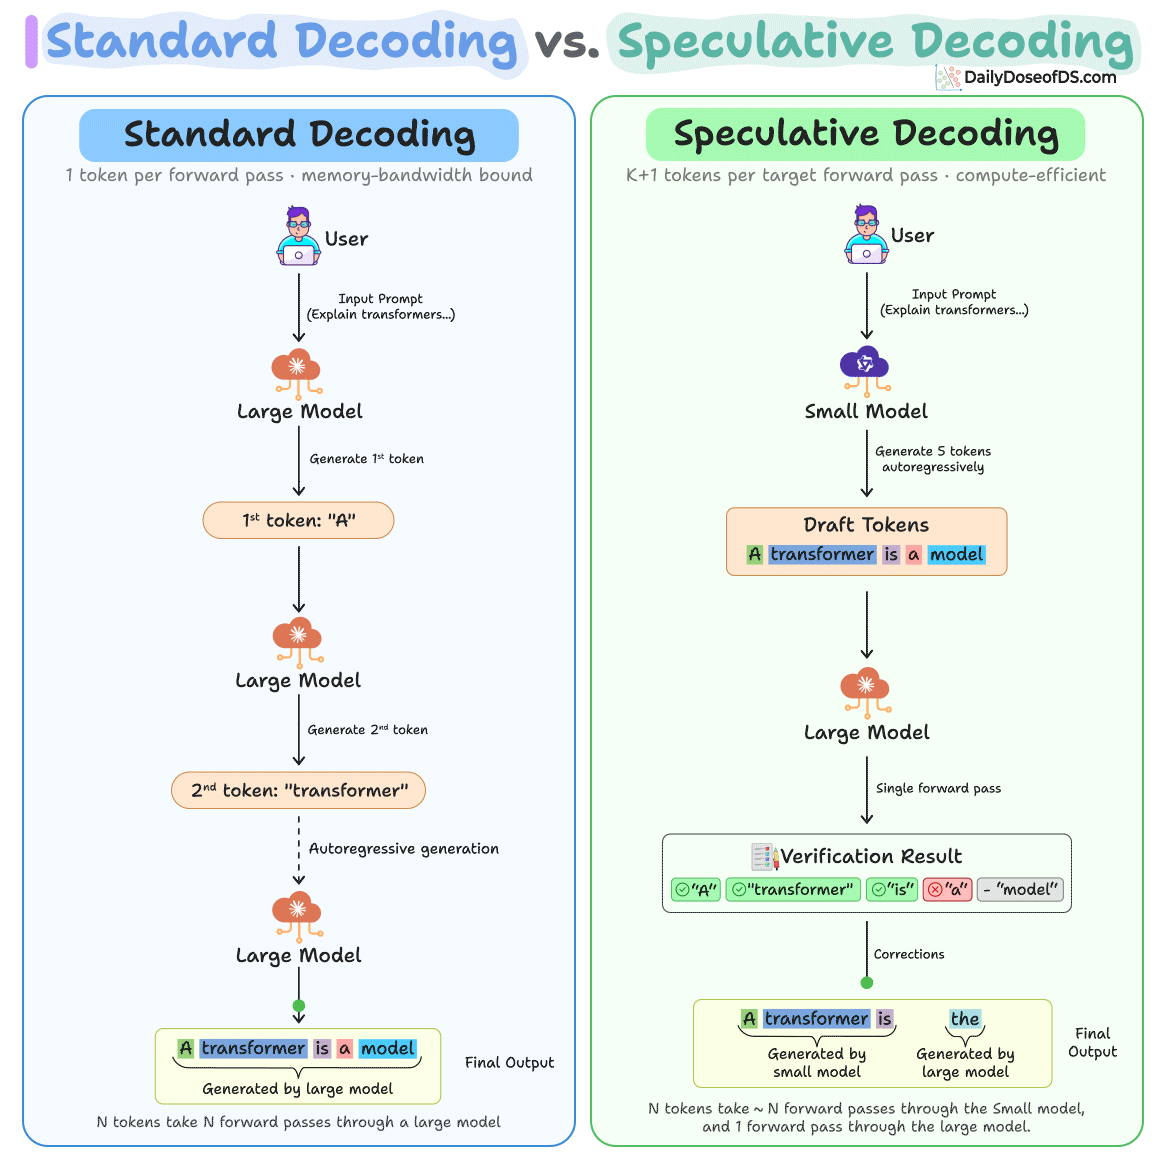
Speculative Decoding in LLMs

Your LLM Is Guessing Ahead. Then It Checks Itself aka Speculative ...
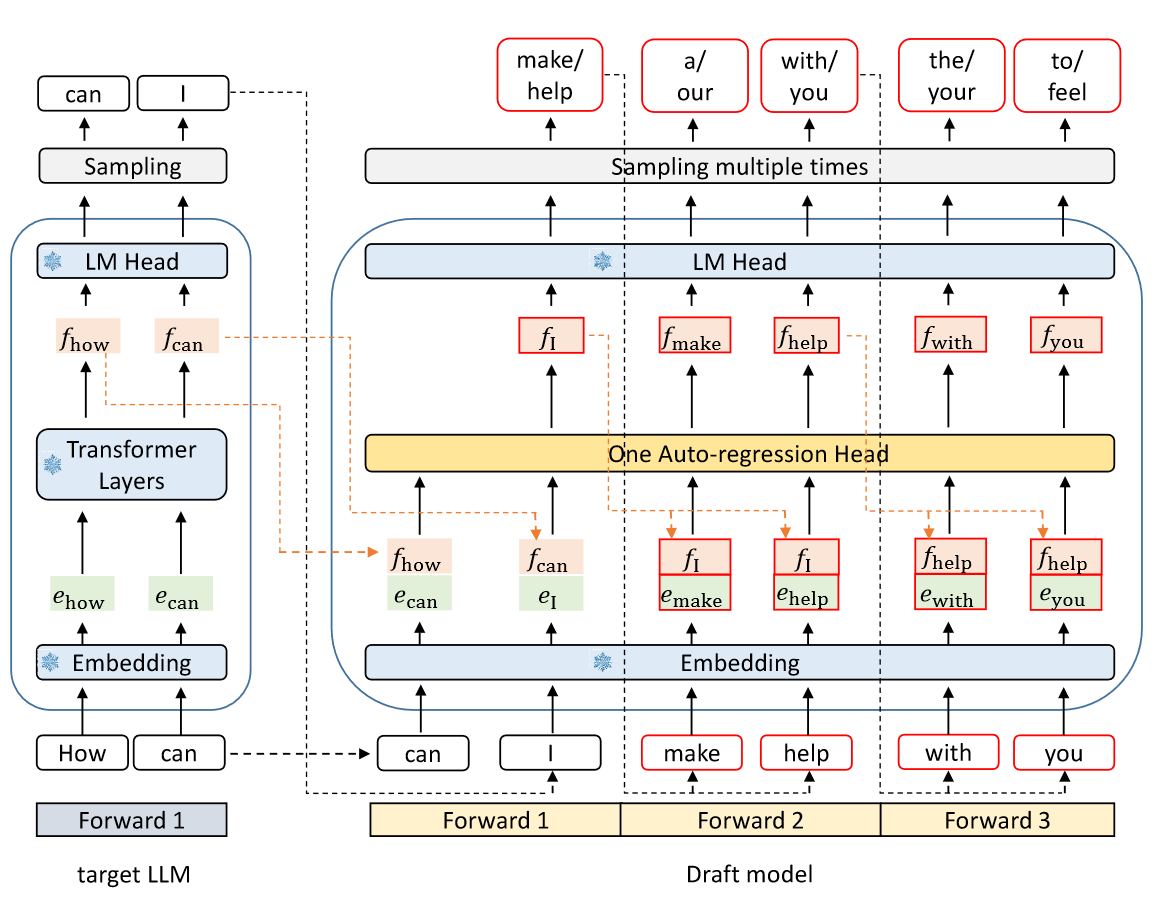
LLM推理加速: Speculative Decoding 概述 - 知乎
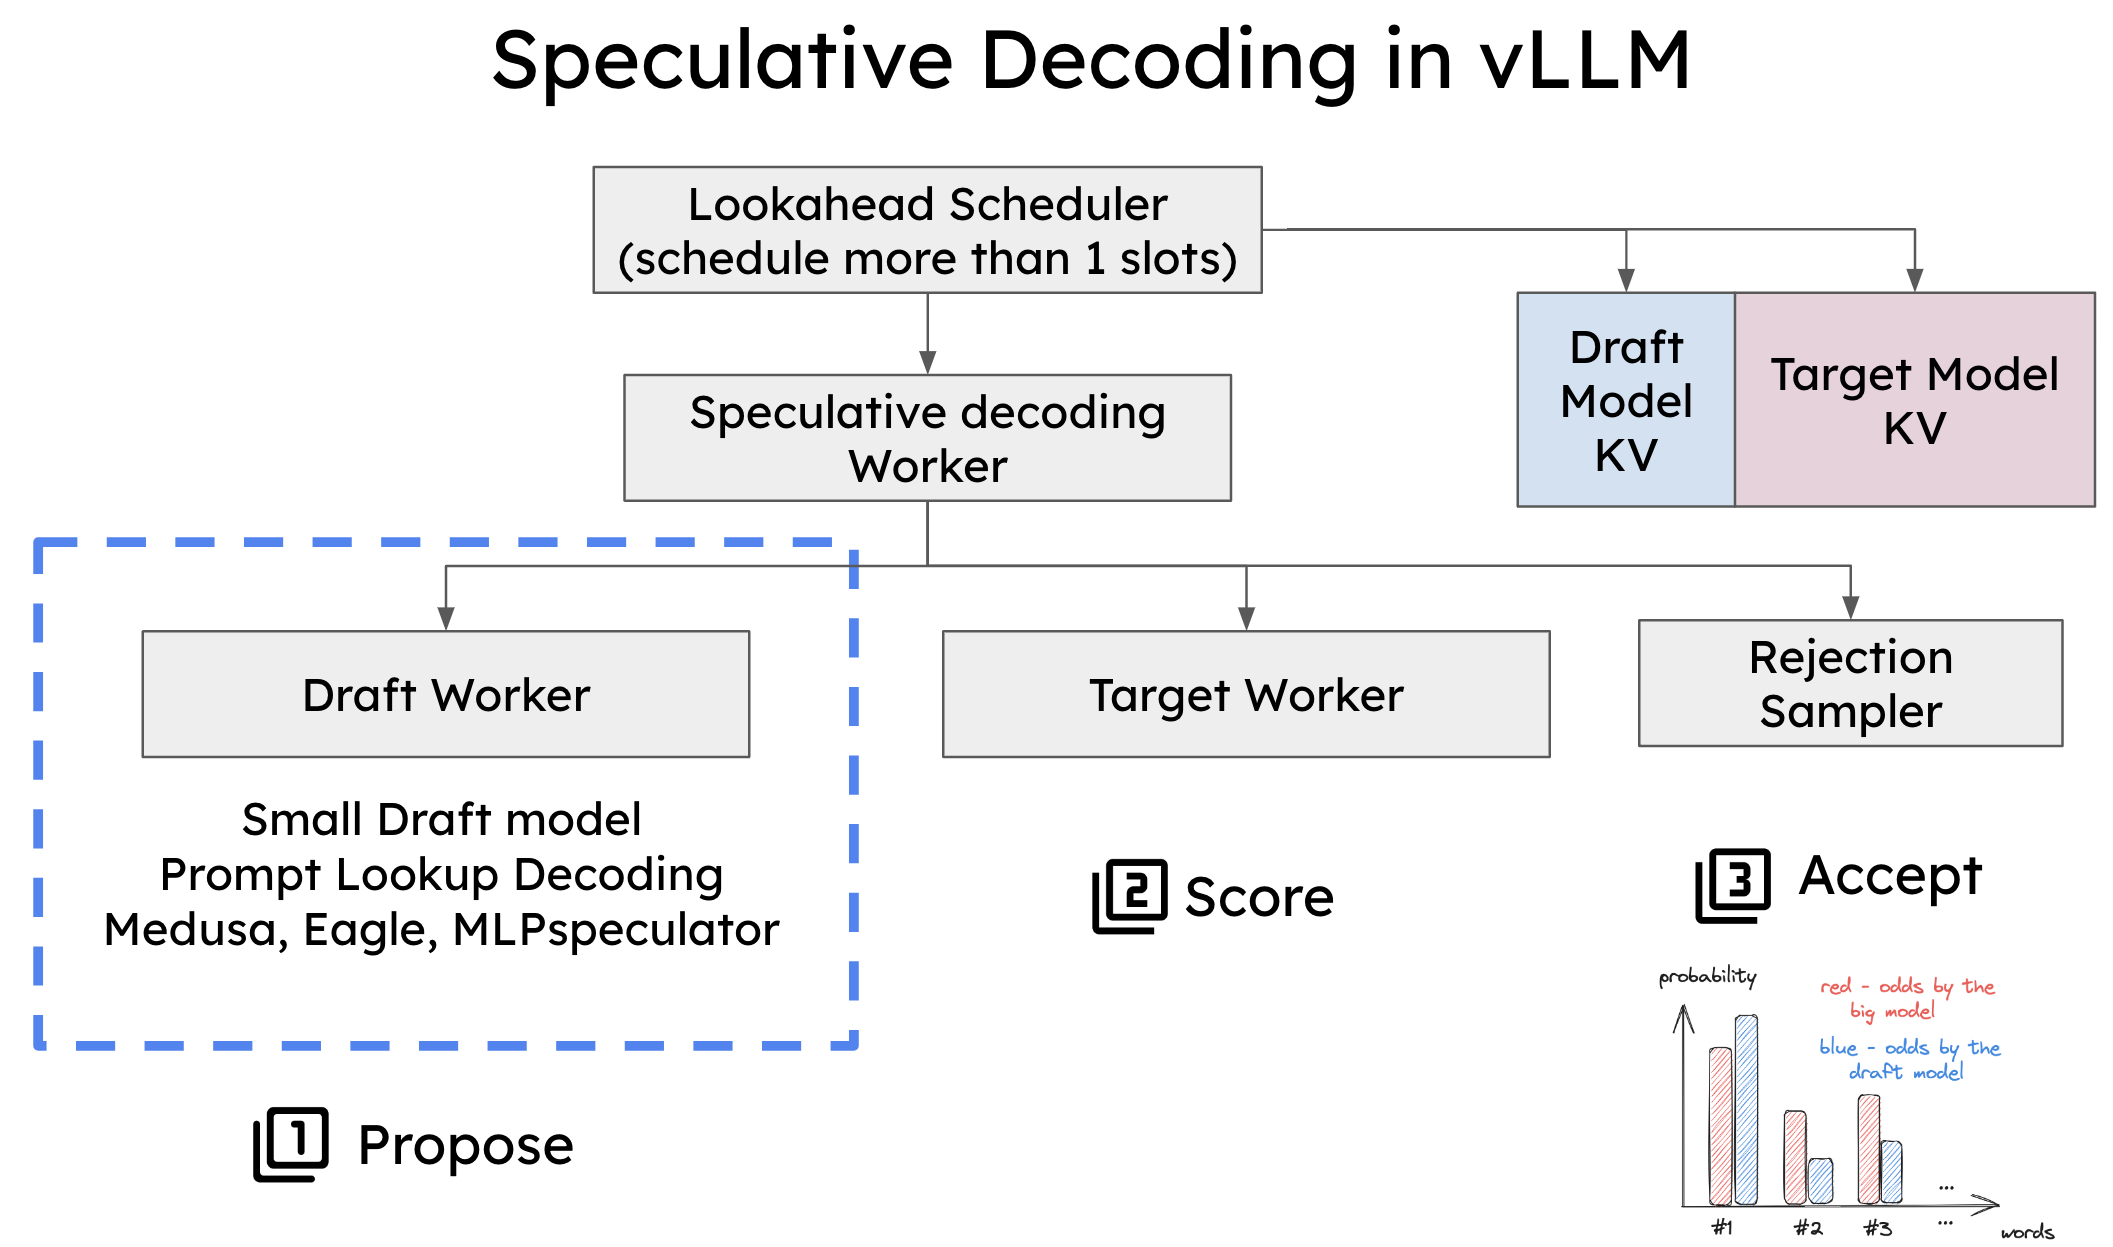
Speculative Decoding in vLLM | OpenLM.ai
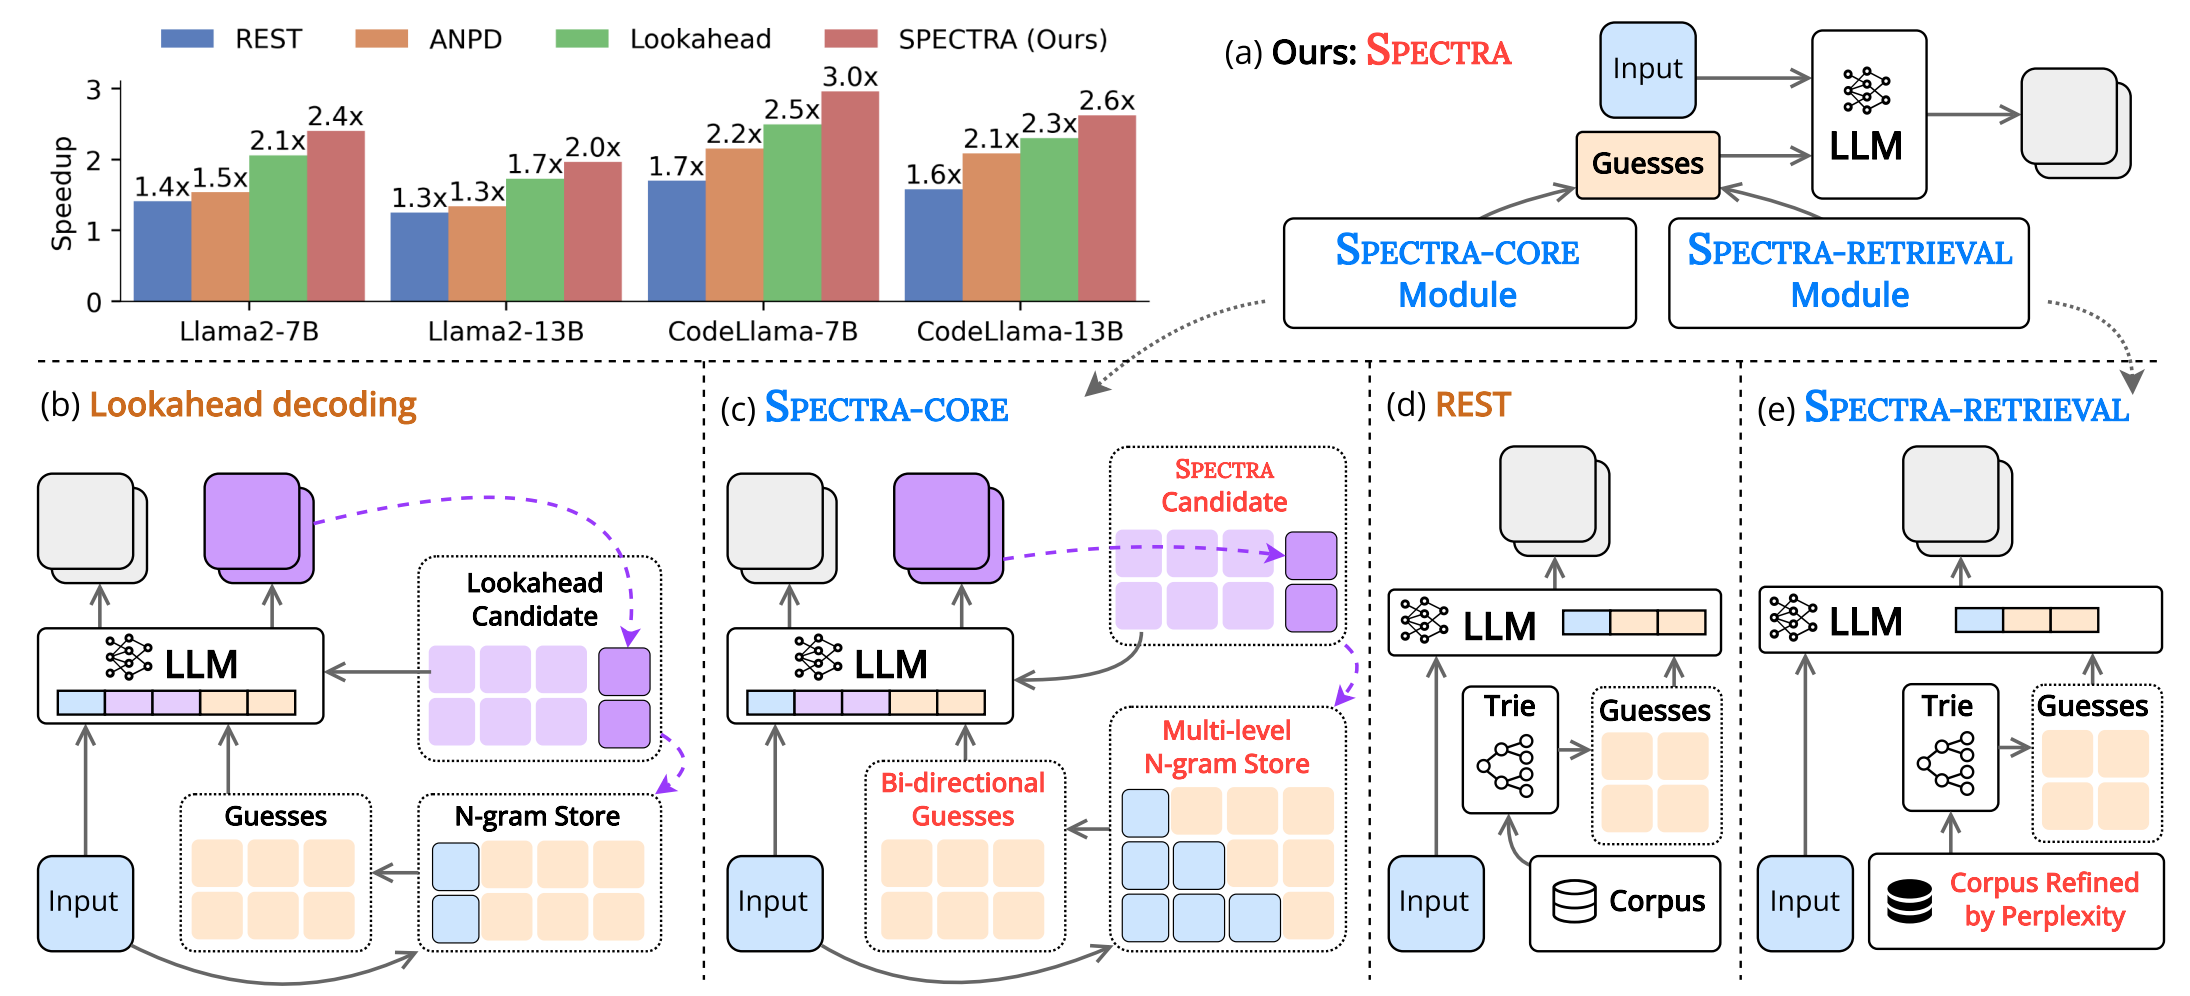
Nguyen Lab's Speculative Decoding Research Group
Advertisement Space (336x280)
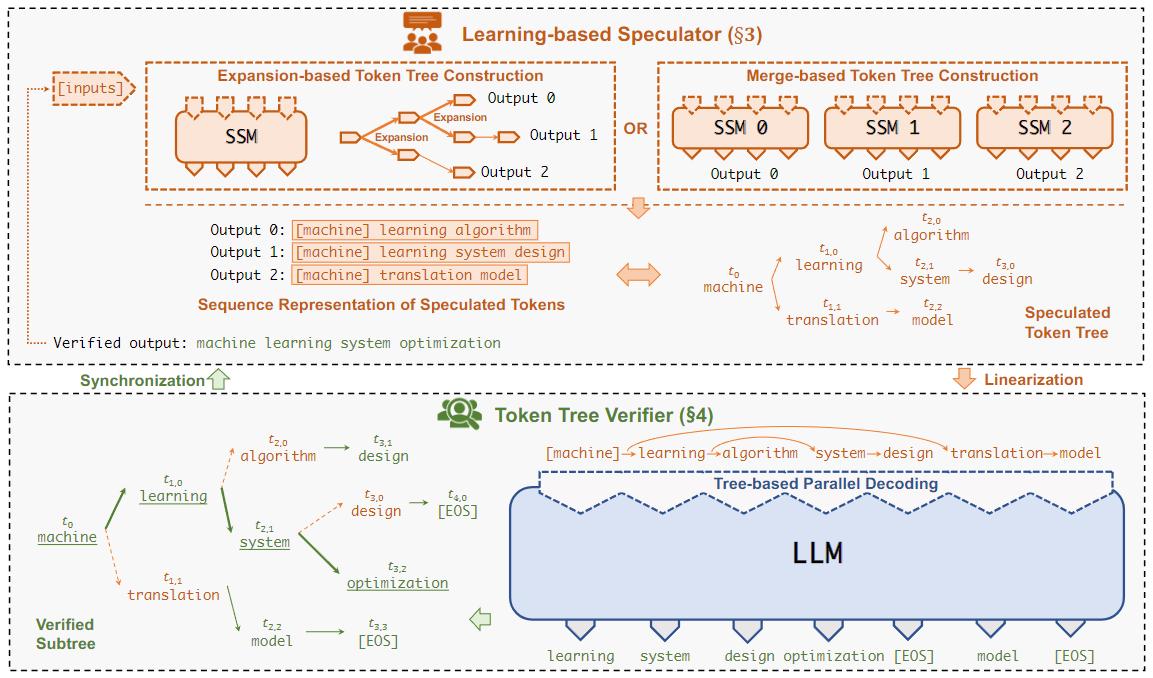
Speculative Decoding 论文阅读合订本 - 知乎
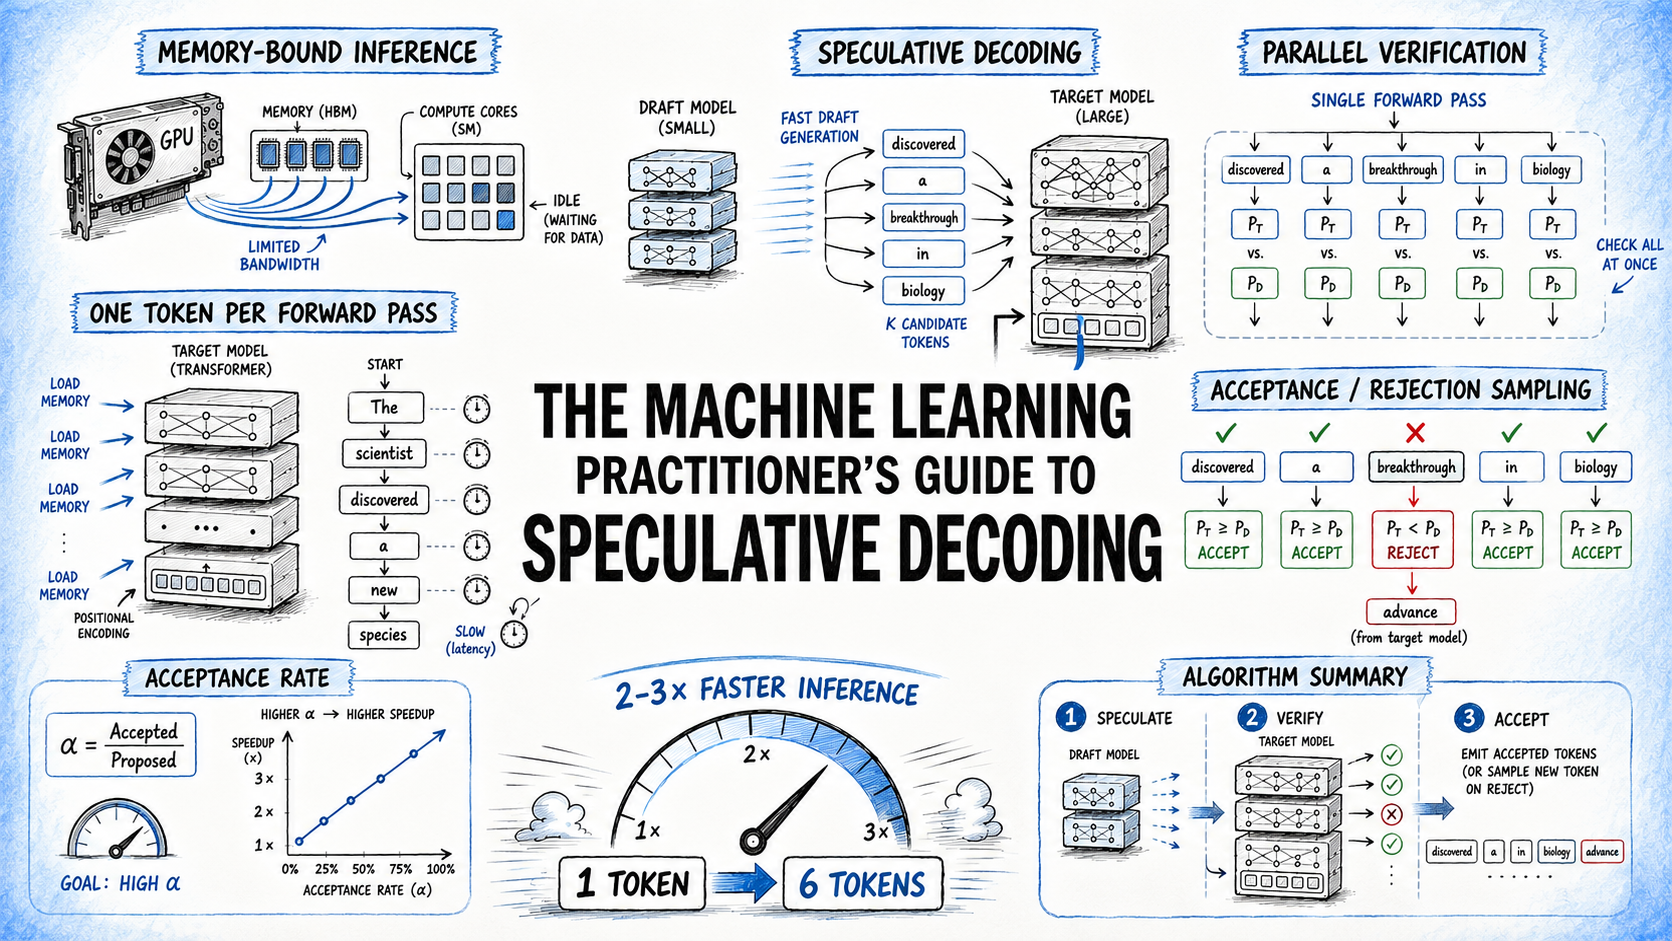
The Machine Learning Practitioner's Guide to Speculative Decoding ...

TensorRT-LLM Speculative Decoding Boosts Inference Throughput by up to ...

Speculative Decoding - Making Language Models Generate Faster Without ...
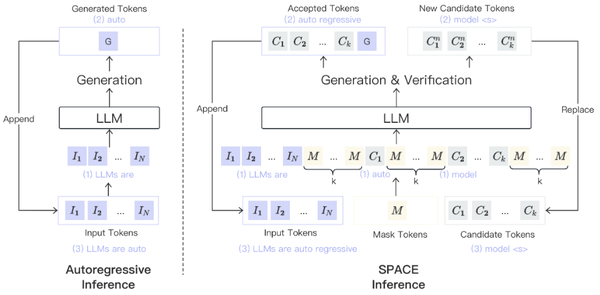
Speculative Decoding 论文阅读合订本 - 知乎
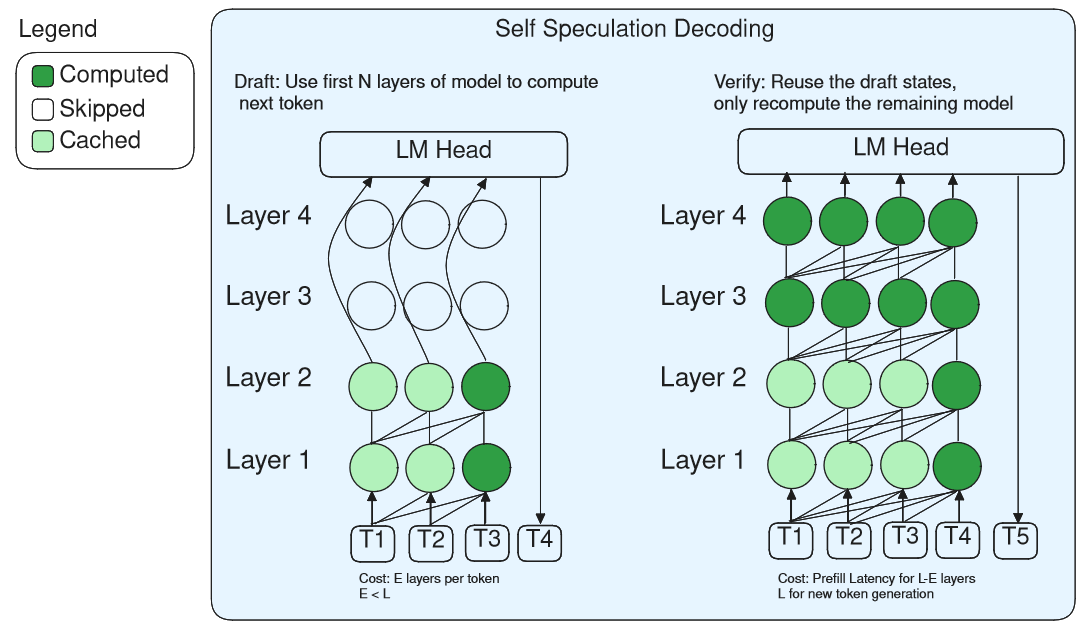
Speculative Decoding 论文阅读合订本 - 知乎
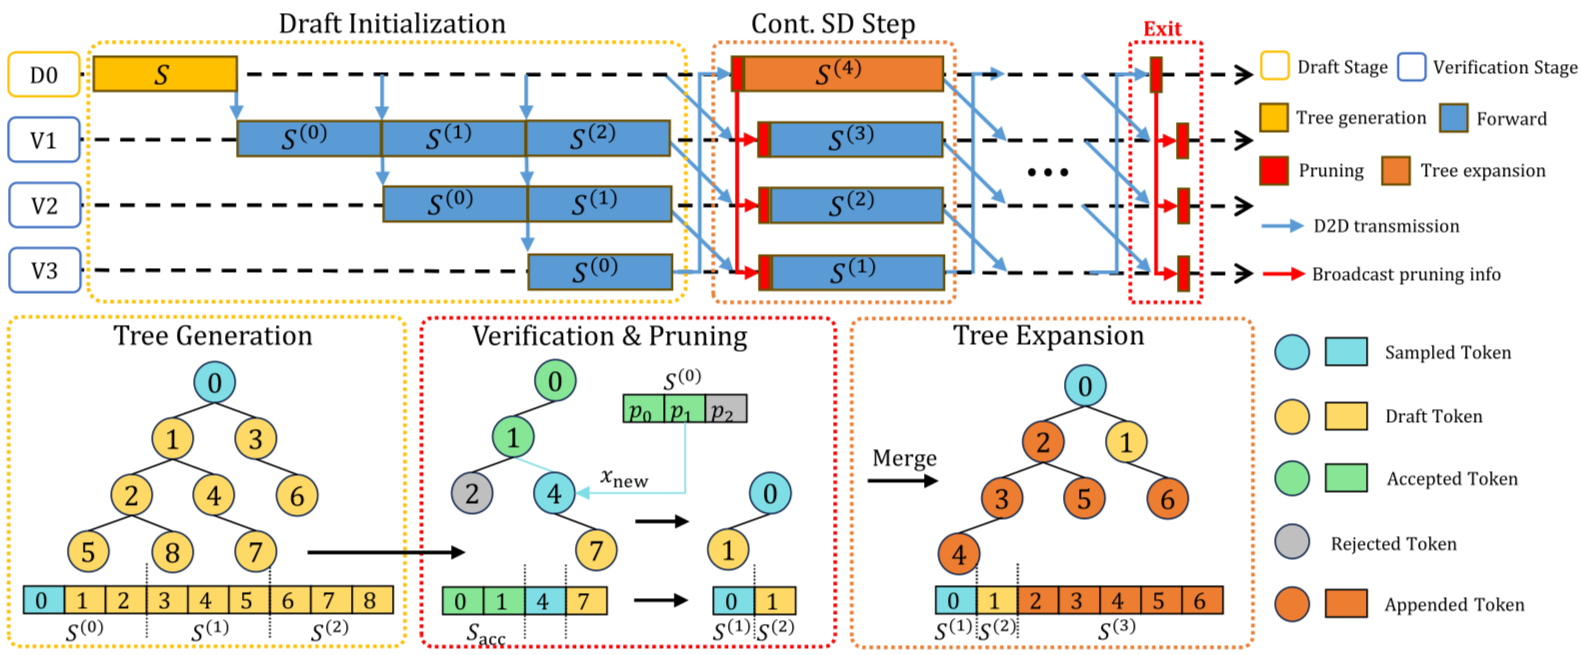
[论文评述] FlowSpec: Continuous Pipelined Speculative Decoding for ...
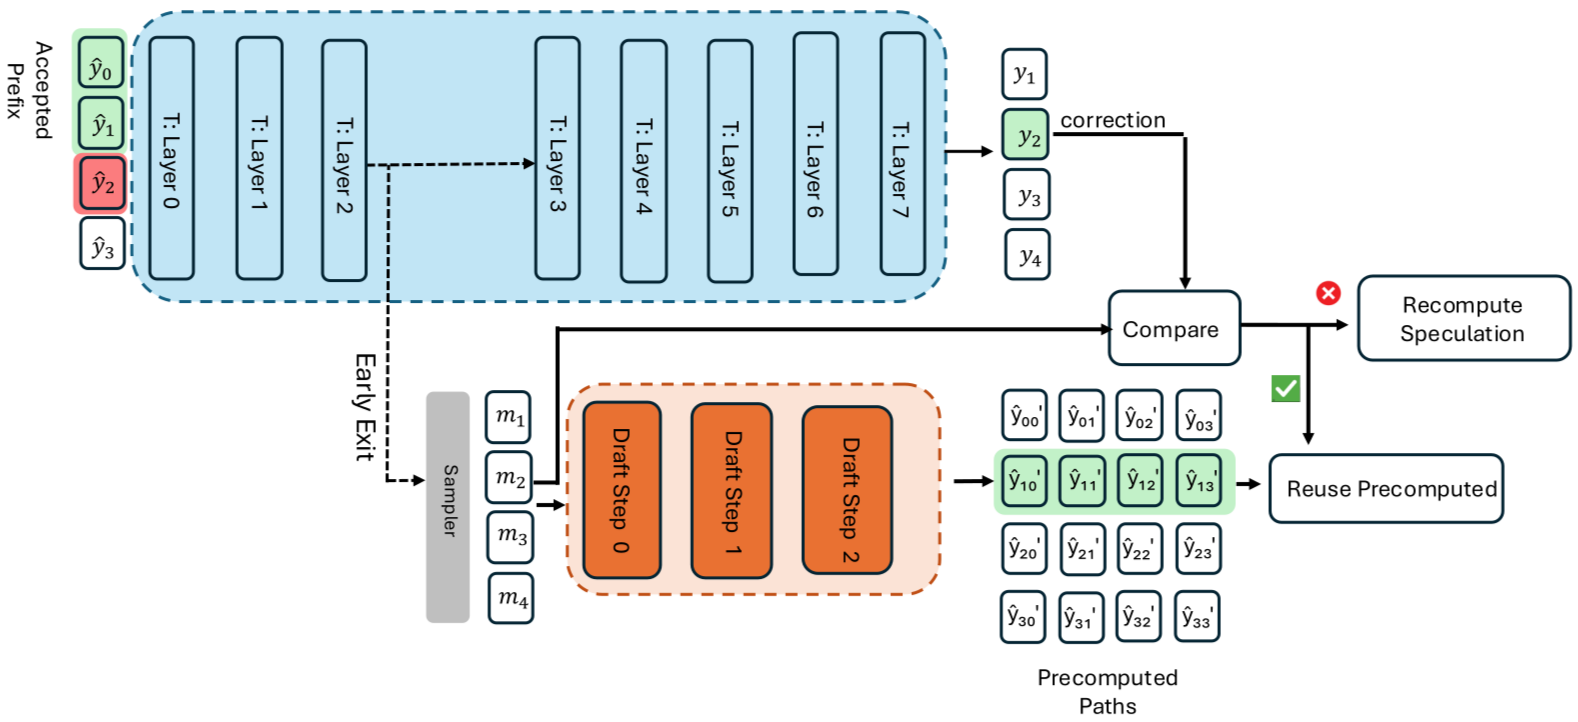
[论文评述] Mirror Speculative Decoding: Breaking the Serial Barrier in LLM ...

[论文评述] Speculative Decoding and Beyond: An In-Depth Review of Techniques

Speculative Decoding: Acelera Inferencia LLM 2-4x en Producción [Guía ...
Advertisement Space (336x280)
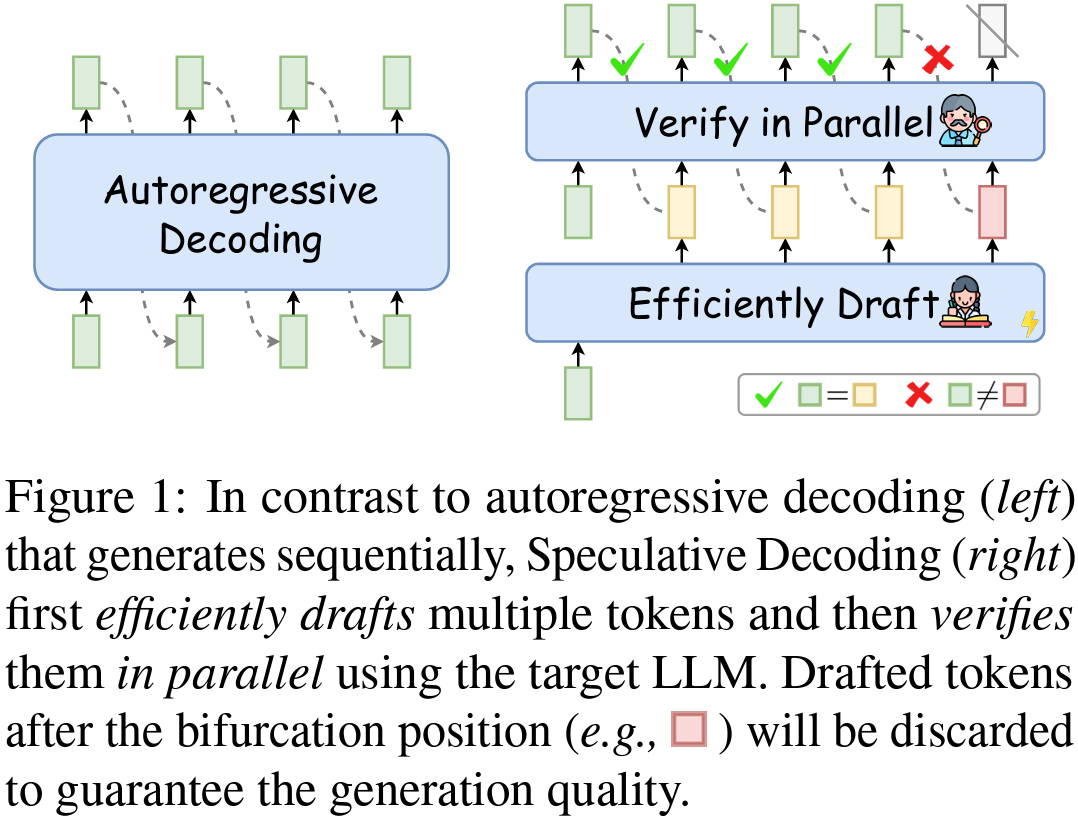
This AI Paper Unveils the Potential of Speculative Decoding for Faster ...

Faster LLMs with speculative decoding and AWS Inferentia2 | Artificial ...
Speculative Decoding Explained: Faster Inference Without Quality Loss
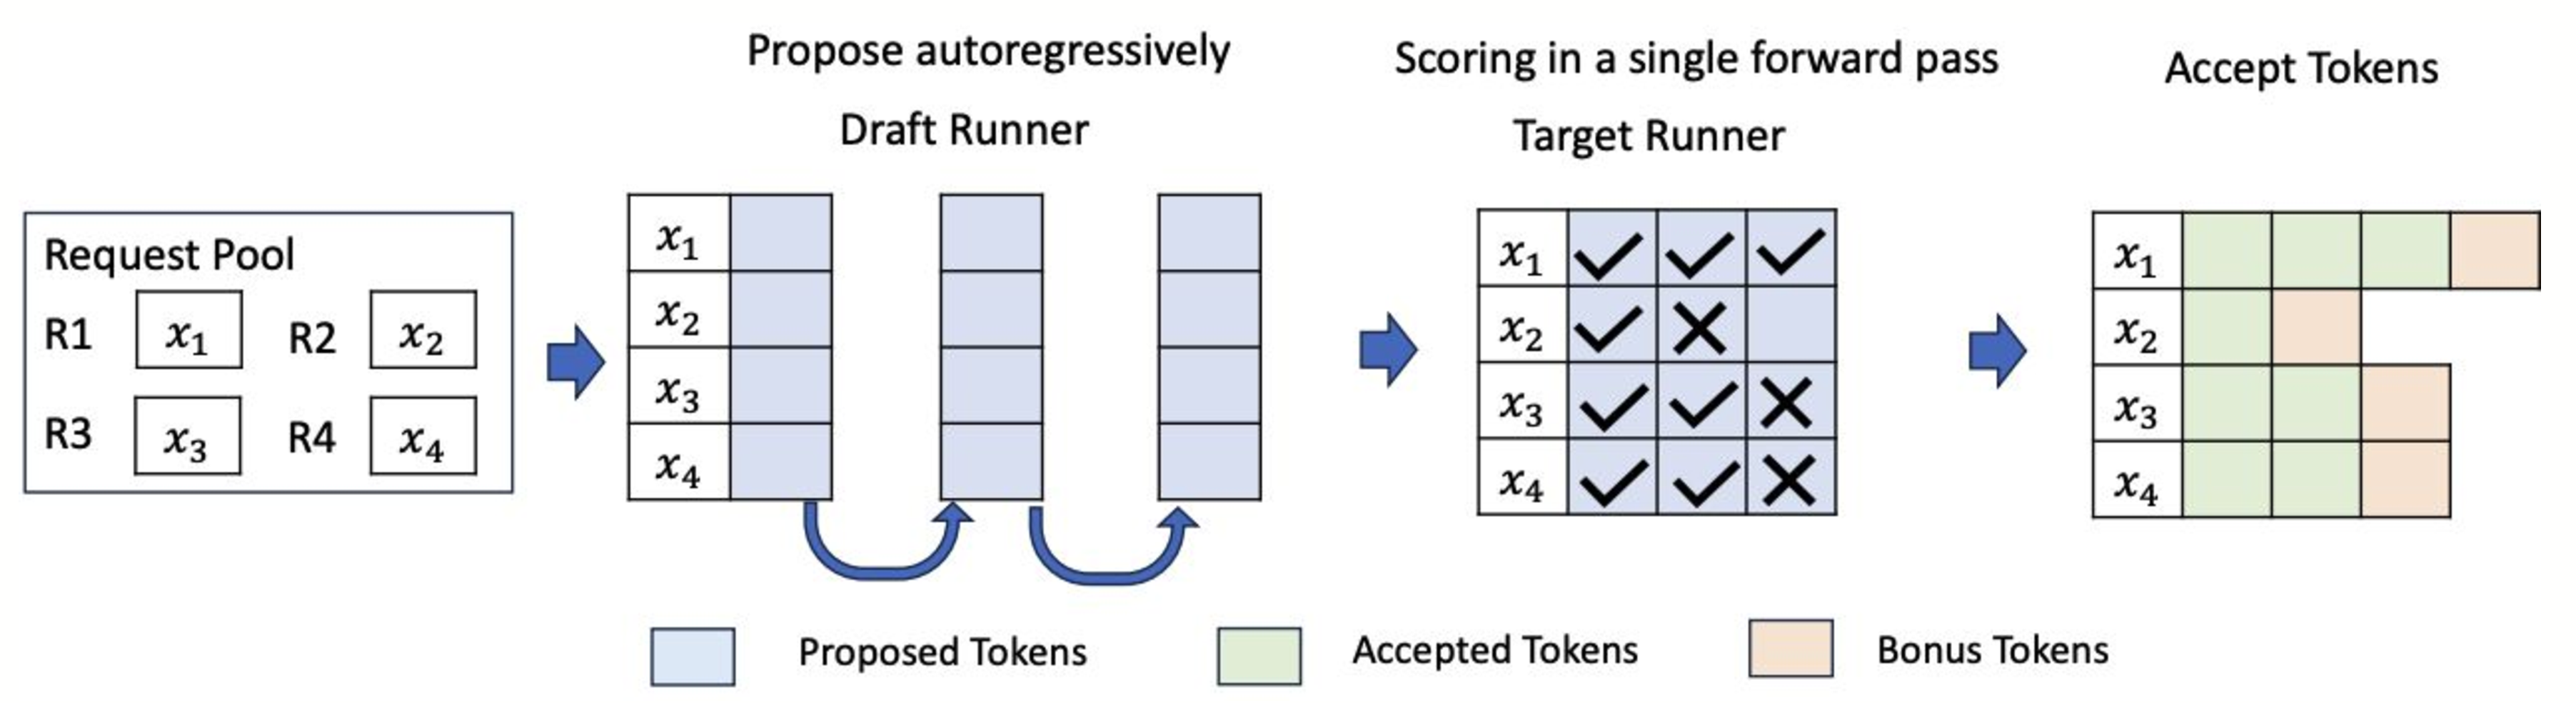
Speculative Decoding in vLLM | OpenLM.ai
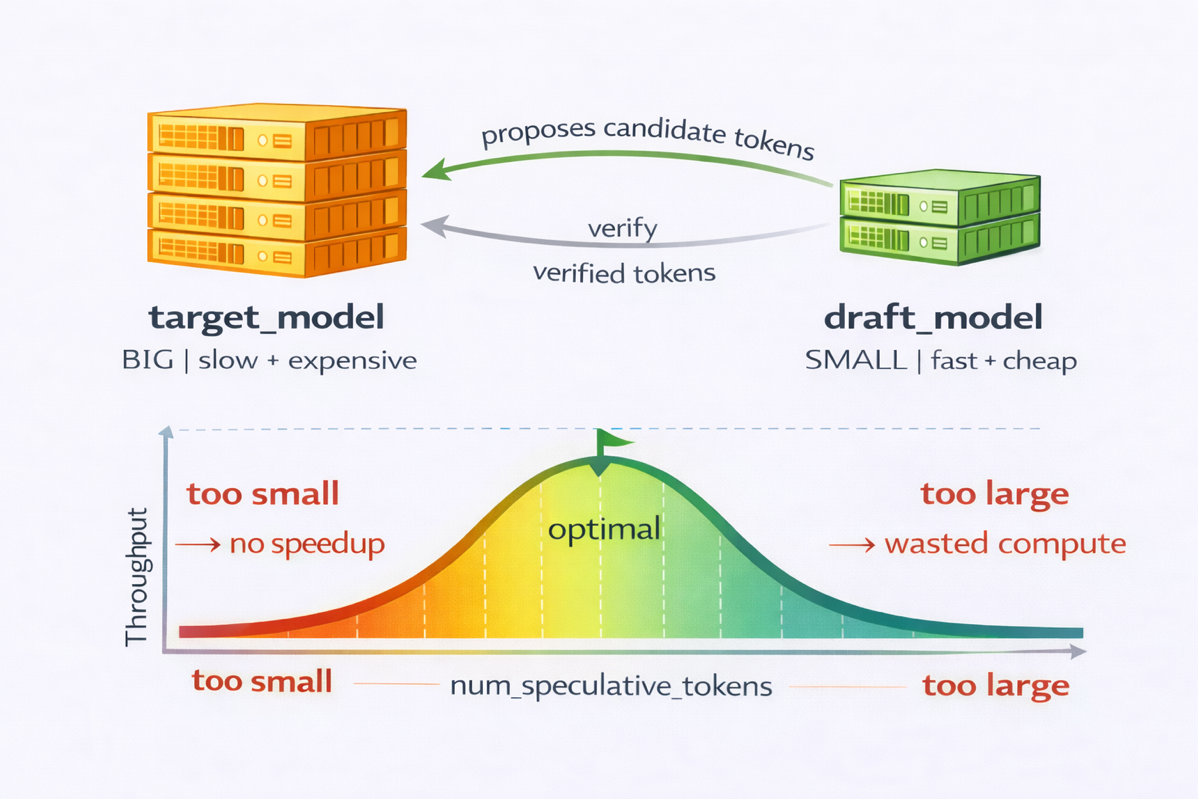
Tuto Startup - Accelerating decode-heavy LLM inference with speculative dec