
Speculative Decoding For Accelerated Rl Post Training Rollouts Youtube
Speculative Decoding for Accelerated RL Post-Training Rollouts - YouTube

Distribution-Aware Speculative Decoding Accelerates RL Rollouts | OJO

Beat the long tail: Distribution-Aware Speculative Decoding for RL ...
SpecForge: Accelerating Speculative Decoding Training for SGLang ...
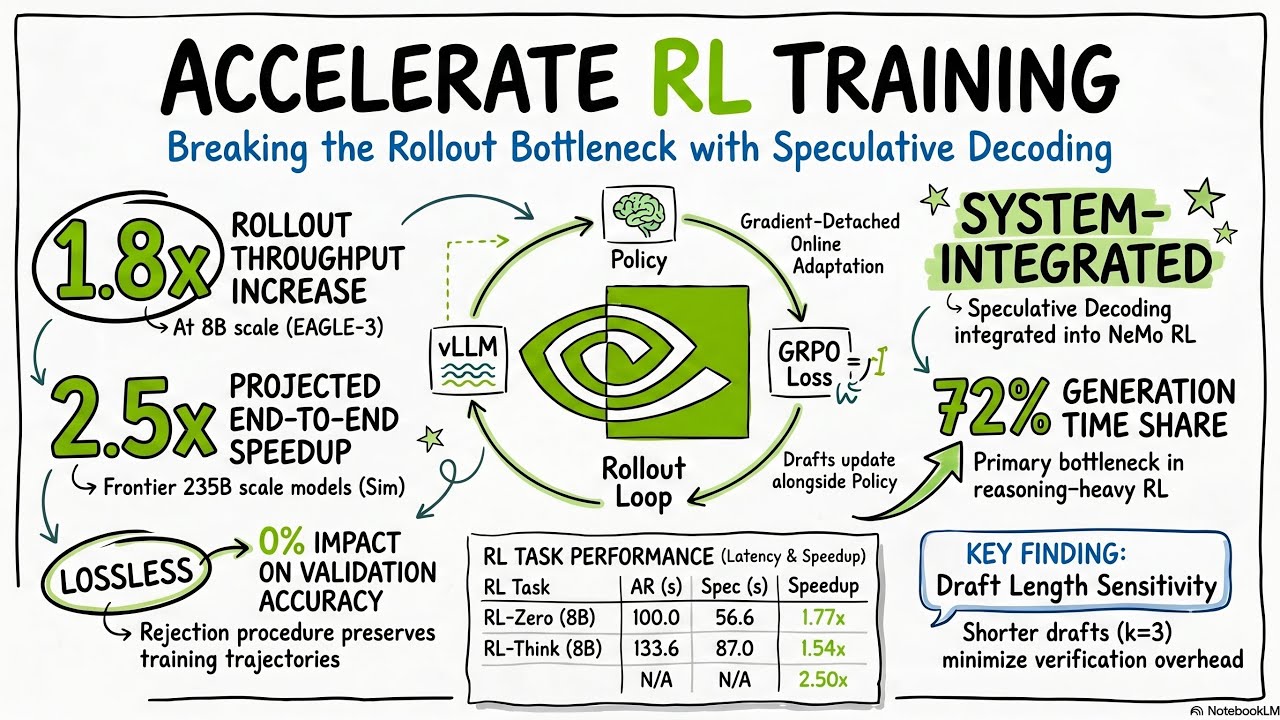
A New NVIDIA Research Shows Speculative Decoding in NeMo RL Achieves 1. ...
Accelerating RL Post-Training with Speculative Decoding in NeMo RL ...

A New NVIDIA Research Shows Speculative Decoding in NeMo RL Achieves 1. ...
Accelerate RL rollouts by up to 50% with distribution-aware speculative ...

Accelerate RL rollouts by up to 50% with distribution-aware speculative ...
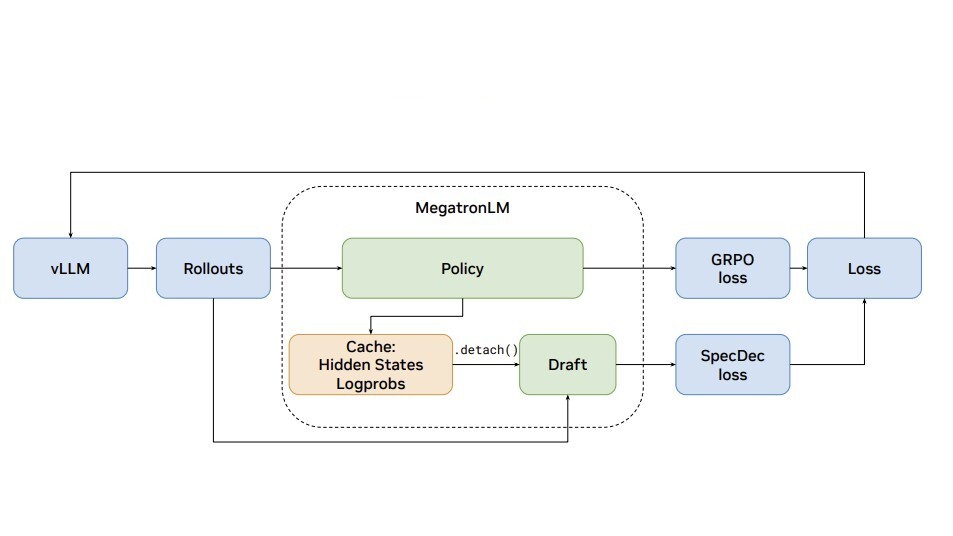
NVIDIA Accelerates Reasoning Model Training With Speculative Decoding ...
Advertisement Space (300x250)
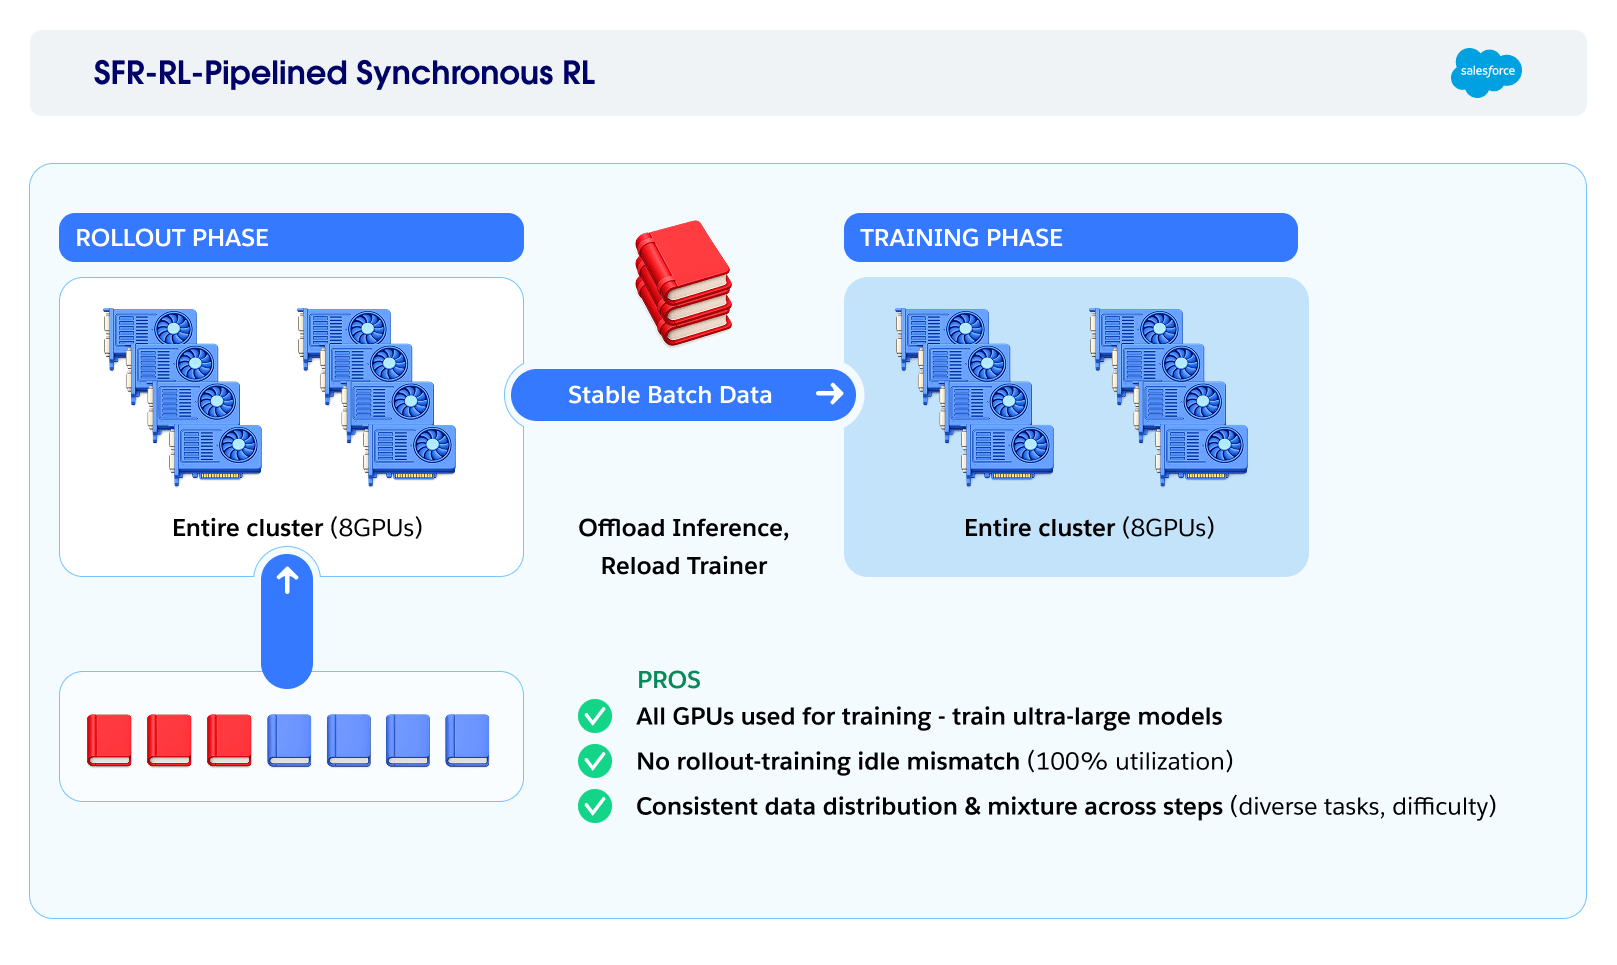
Building Efficient RL Training for the Agentic Era - Salesforce

A New NVIDIA Research Shows Speculative Decoding in NeMo RL Achieves 1. ...
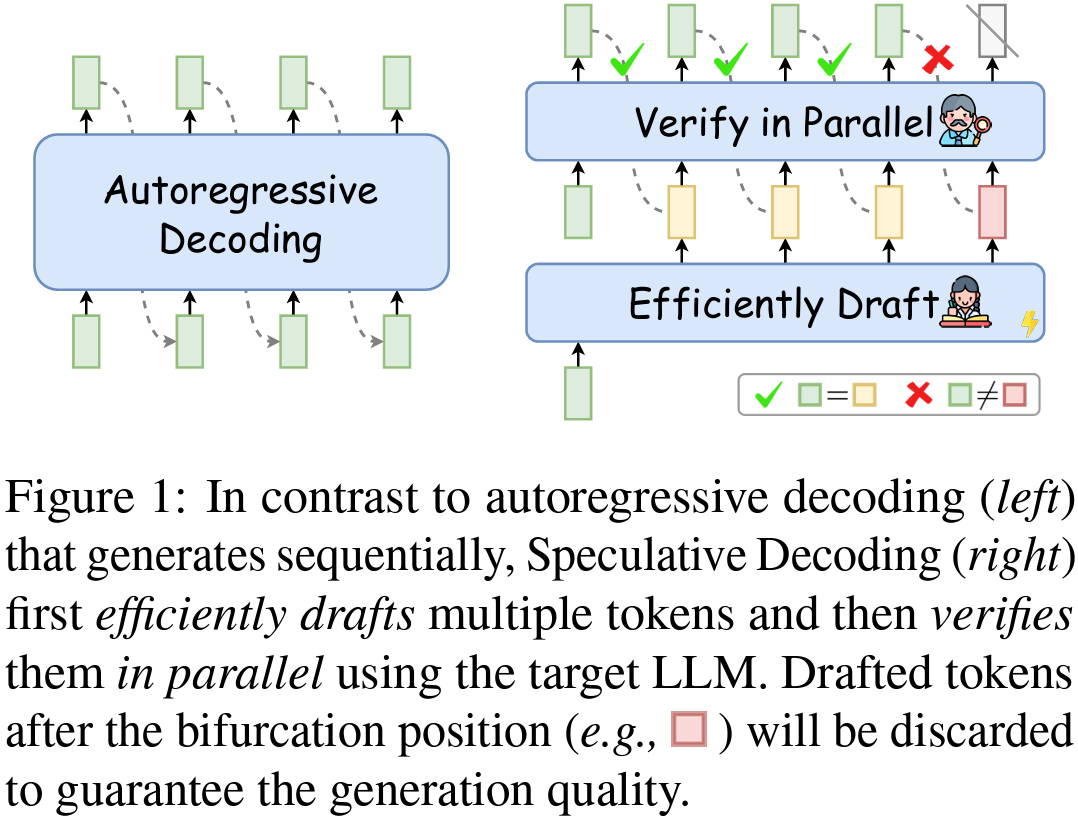
This AI Paper Unveils the Potential of Speculative Decoding for Faster ...
UniSpec: Training-Free Speculative Decoding for Robust LLM Acceleration ...

Building Efficient RL Training for the Agentic Era - Salesforce

Efficient RL Training for LLMs with Experience Replay @Gradient_HQ Meta ...
TLT: Training-time Speculative Decoding to Speed LLM Training | ToolScopeAI
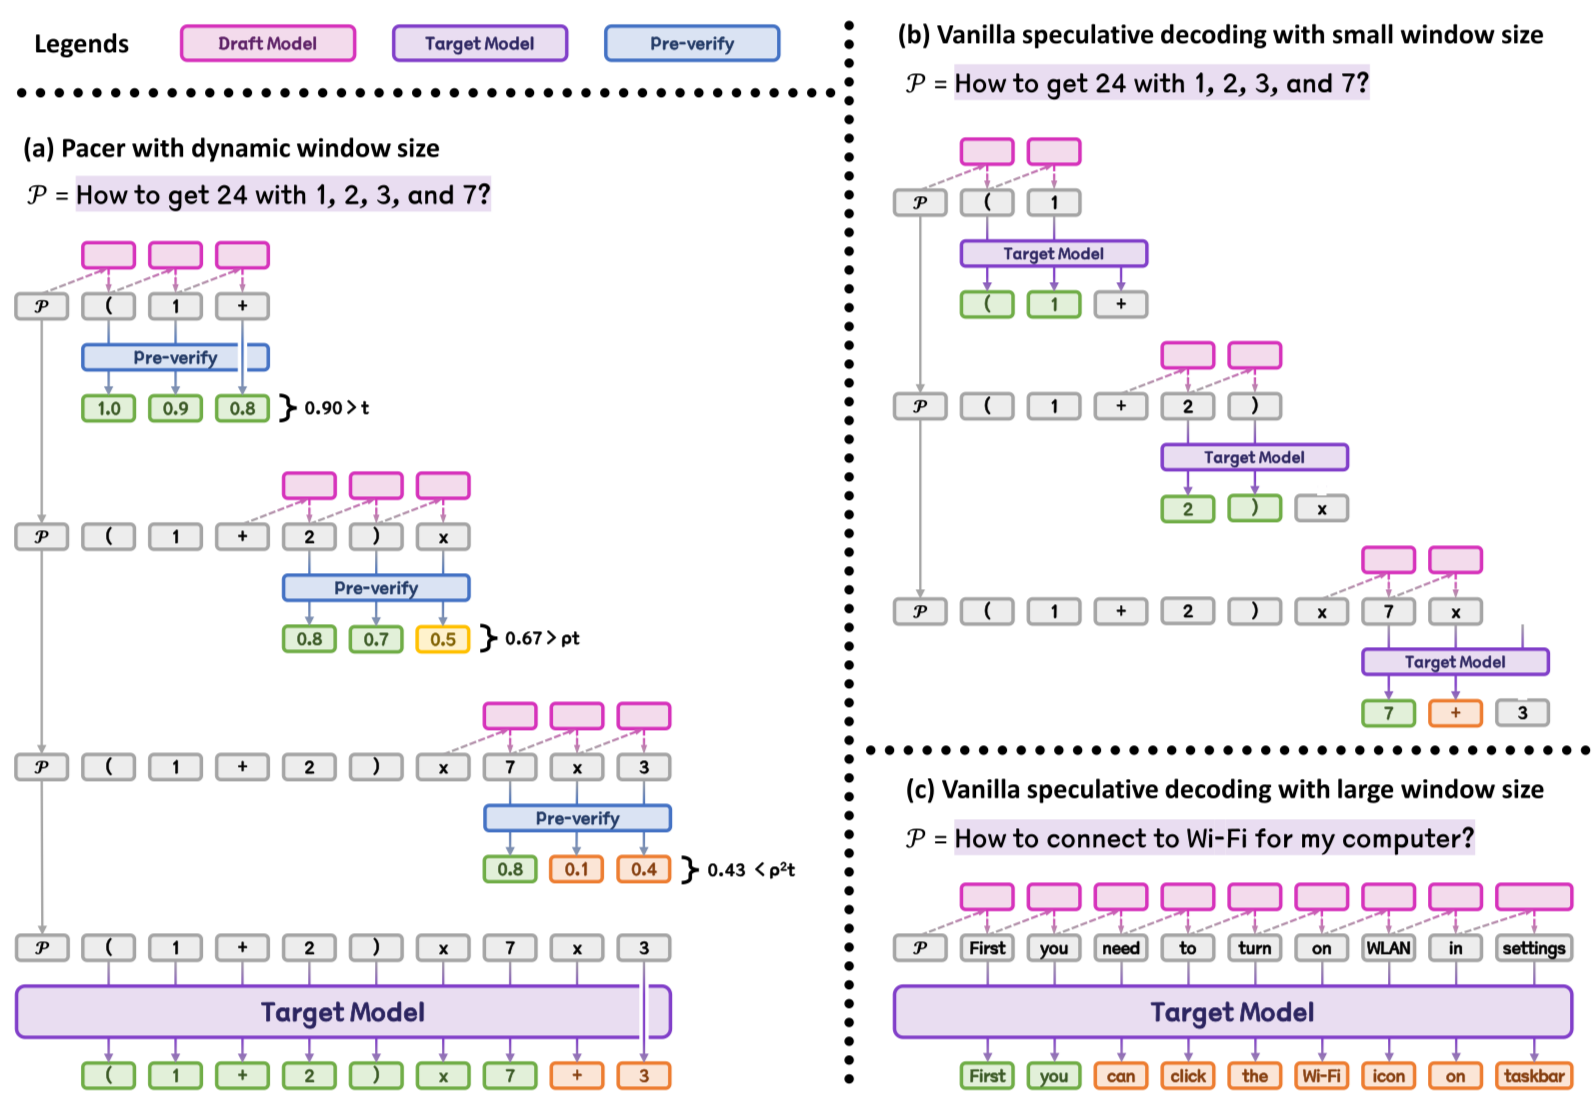
[論文レビュー] PACER: Blockwise Pre-verification for Speculative Decoding ...
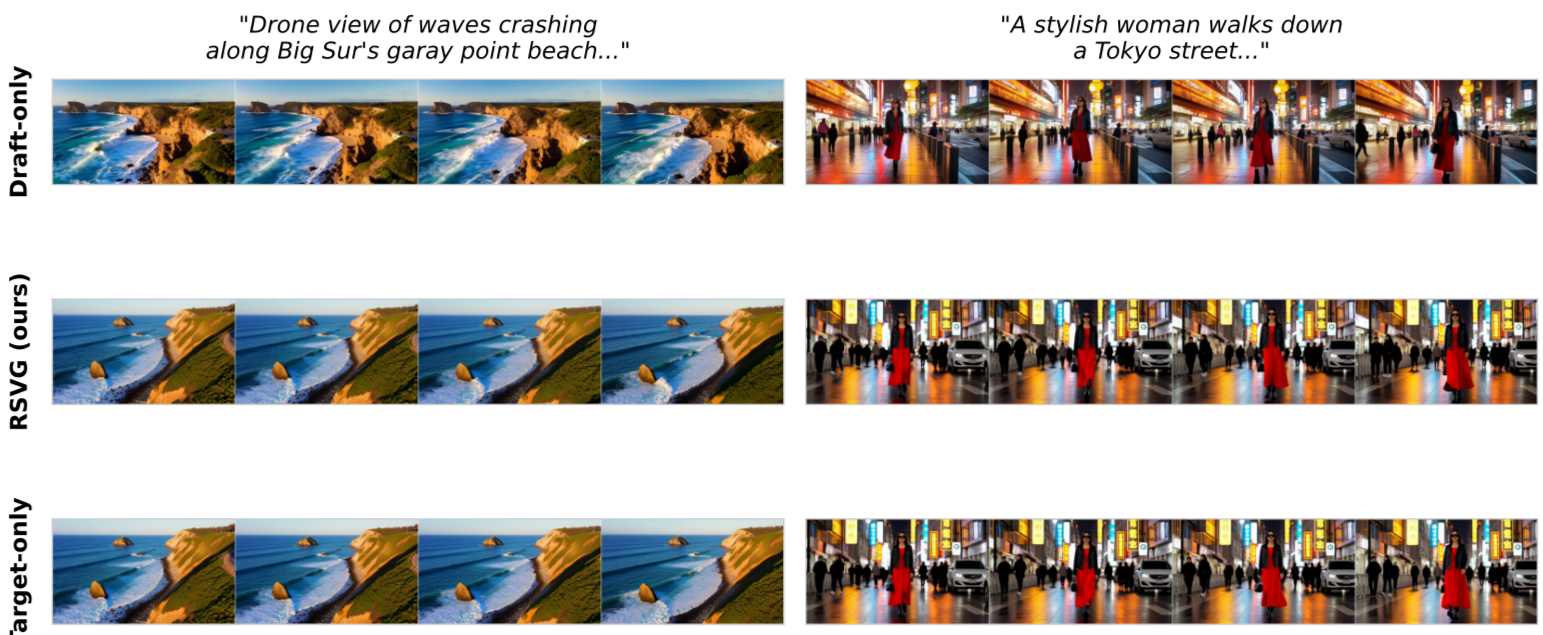
[论文评述] Speculative Decoding for Autoregressive Video Generation
Speculative decoding moves into production for decode-heavy LLMs | AI News
Advertisement Space (336x280)
Accelerating RL Post-Training Rollouts via System-Integrated ...

NeMo RL:Speculative Decoding 把 8B rollout 提速到 1.8×,235B 估计可达2.5× - YouTube
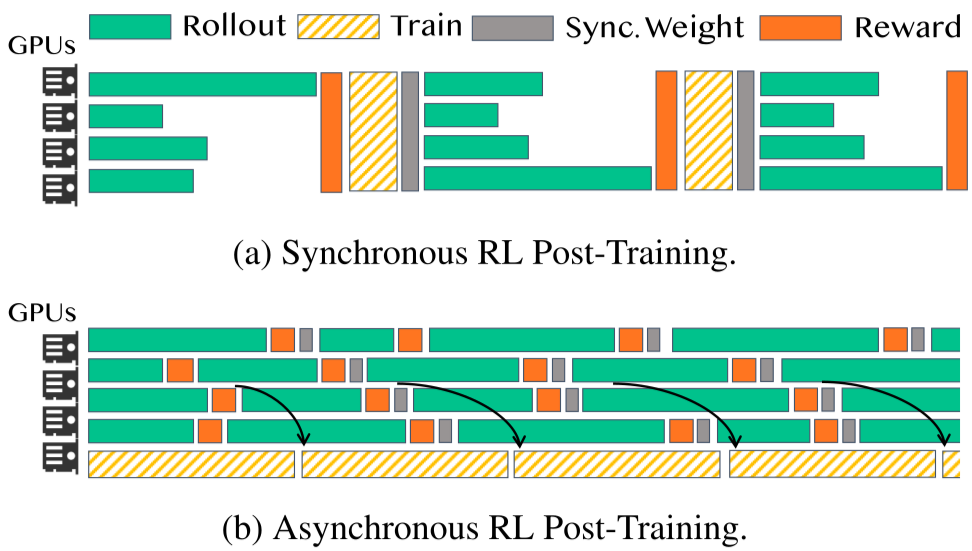
[논문 리뷰] RollPacker: Mitigating Long-Tail Rollouts for Fast, Synchronous ...

[2604.26779] Accelerating RL Post-Training Rollouts via System ...

Accelerating RL Post-Training Rollouts via System-Integrated ...

Accelerating RL Post-Training Rollouts via System-Integrated ...

NVIDIA NeMo RL Speculative Decoding: 1.8×… | gentic.news

Accelerating RL Post-Training Rollouts via System-Integrated ...

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...

EfficientRollout A system-aware self-speculative decoding framework for ...
Advertisement Space (336x280)

Free Video: Speculative Decoding: Techniques for Faster LLM Inference ...

Speculative Decoding - Making Language Models Generate Faster Without ...
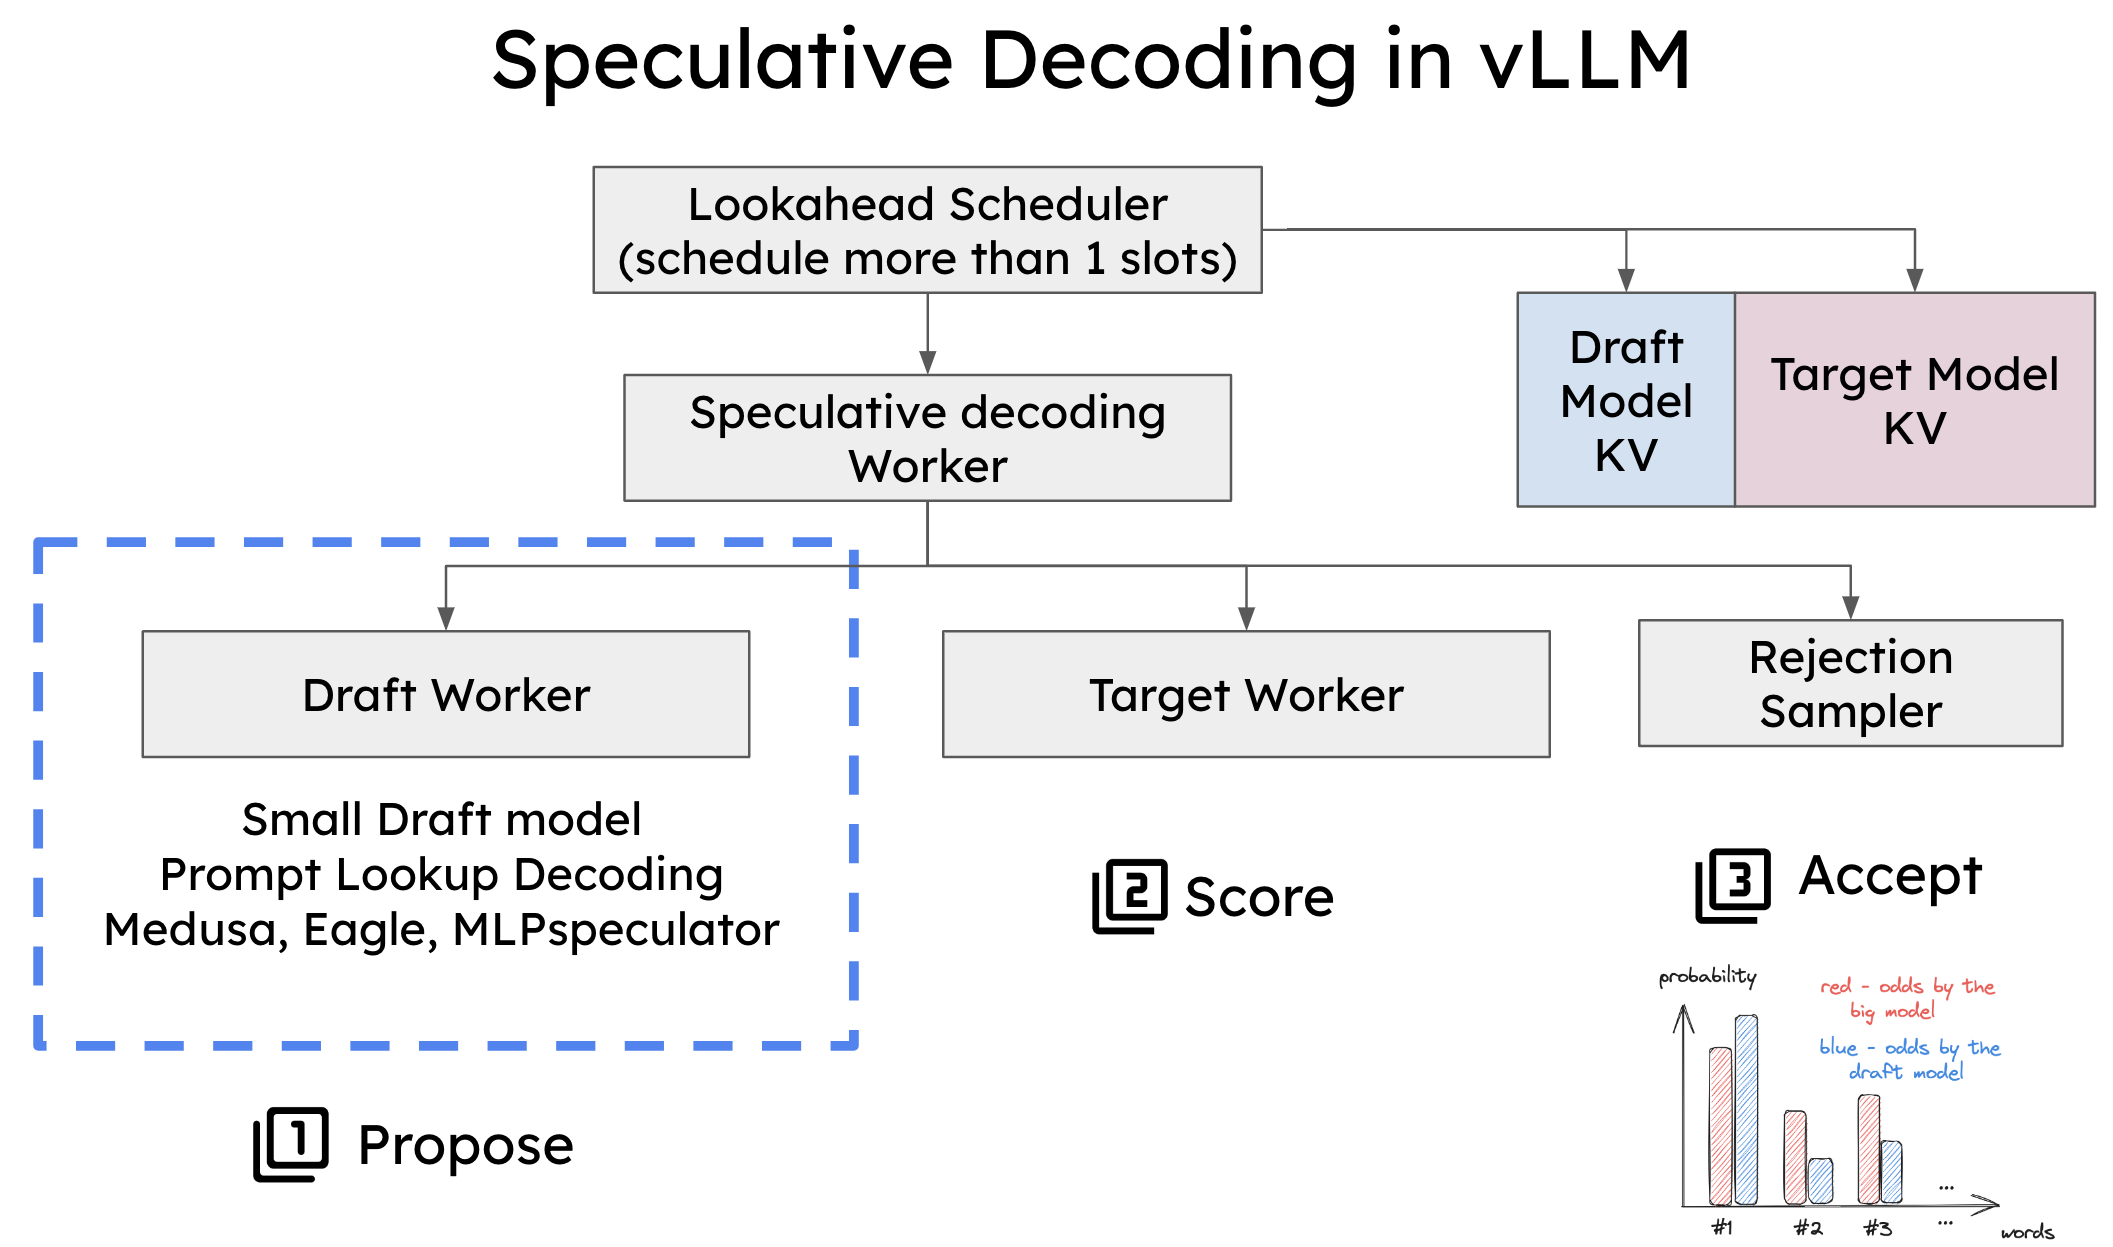
Speculative Decoding in vLLM | OpenLM.ai
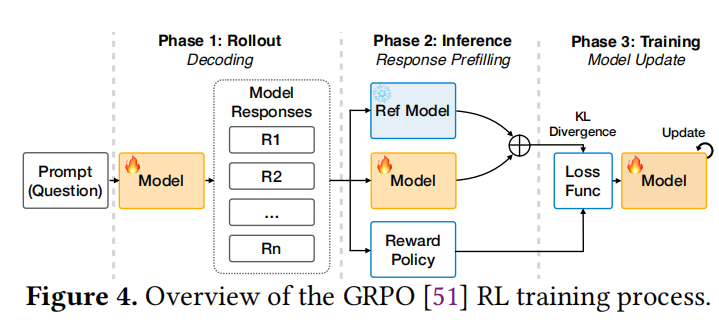
📝 Taming the Long-Tail: Efficient Reasoning RL Training with Adaptive ...
NVIDIA Achieves 2.5x RL Training Speedup with System-Integrated ...

S2D2: Fast Decoding for Diffusion LLMs via Training-Free Self-Speculation