
Step By Step Model Merging And Gguf Imatrix Quantization K4yt3x
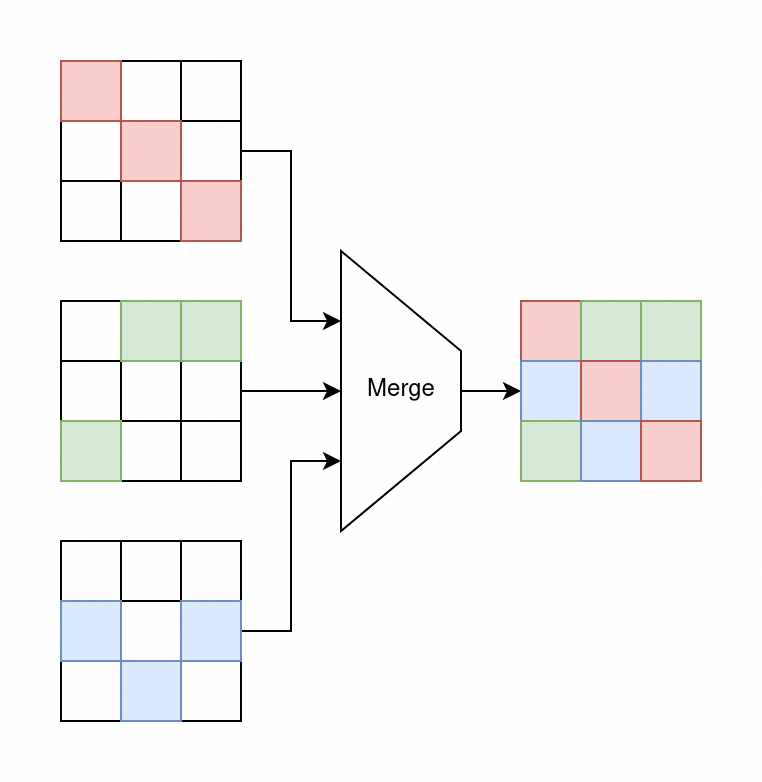
Step-by-Step Model Merging and GGUF imatrix Quantization | K4YT3X
Step-by-Step Model Merging and GGUF imatrix Quantization | K4YT3X
Step-by-Step Model Merging and GGUF imatrix Quantization | K4YT3X
Step-by-Step Model Merging and GGUF imatrix Quantization
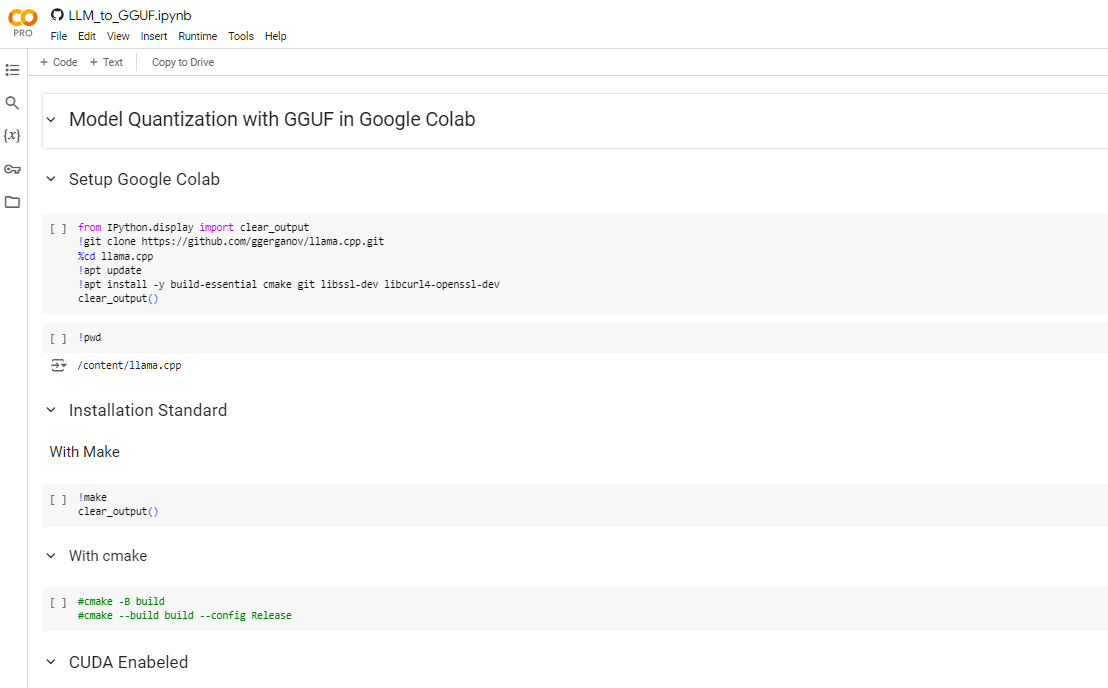
Convert a Hugging Face Model to GGUF in Google Colab (Step by Step ...
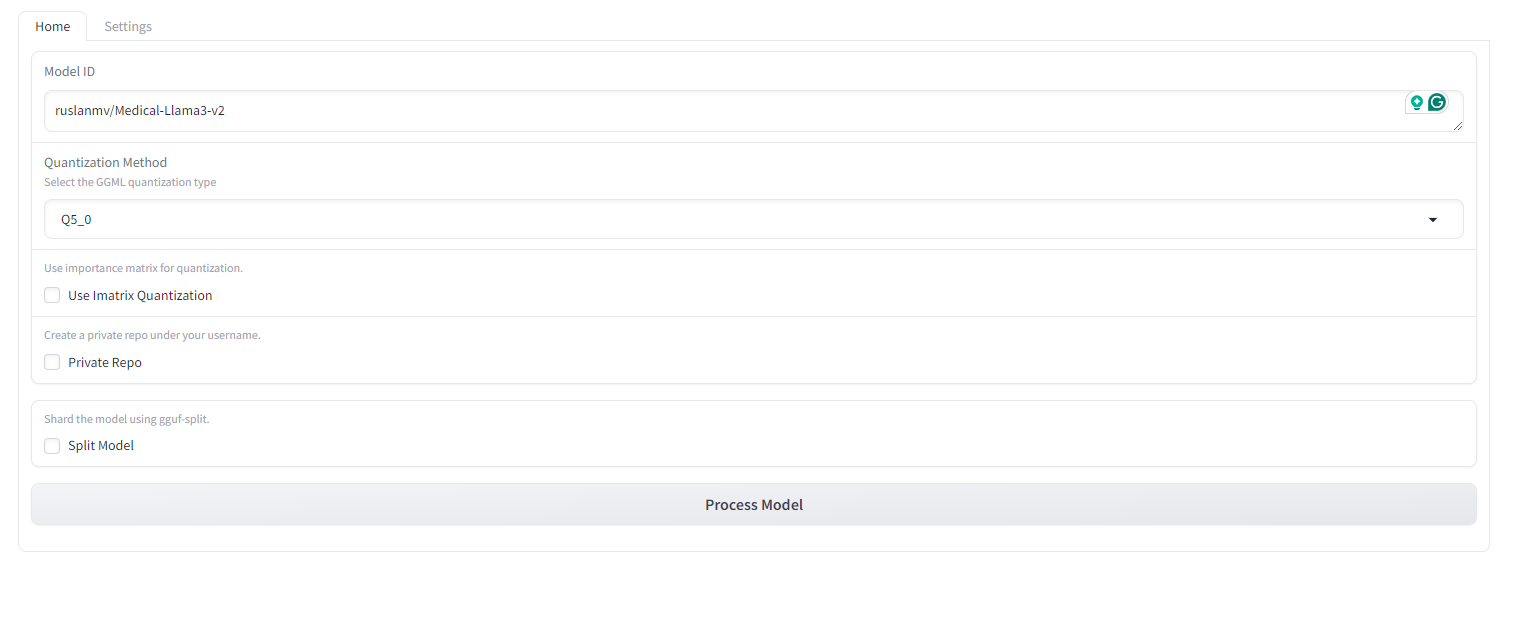
Convert a Hugging Face Model to GGUF in Google Colab (Step by Step ...

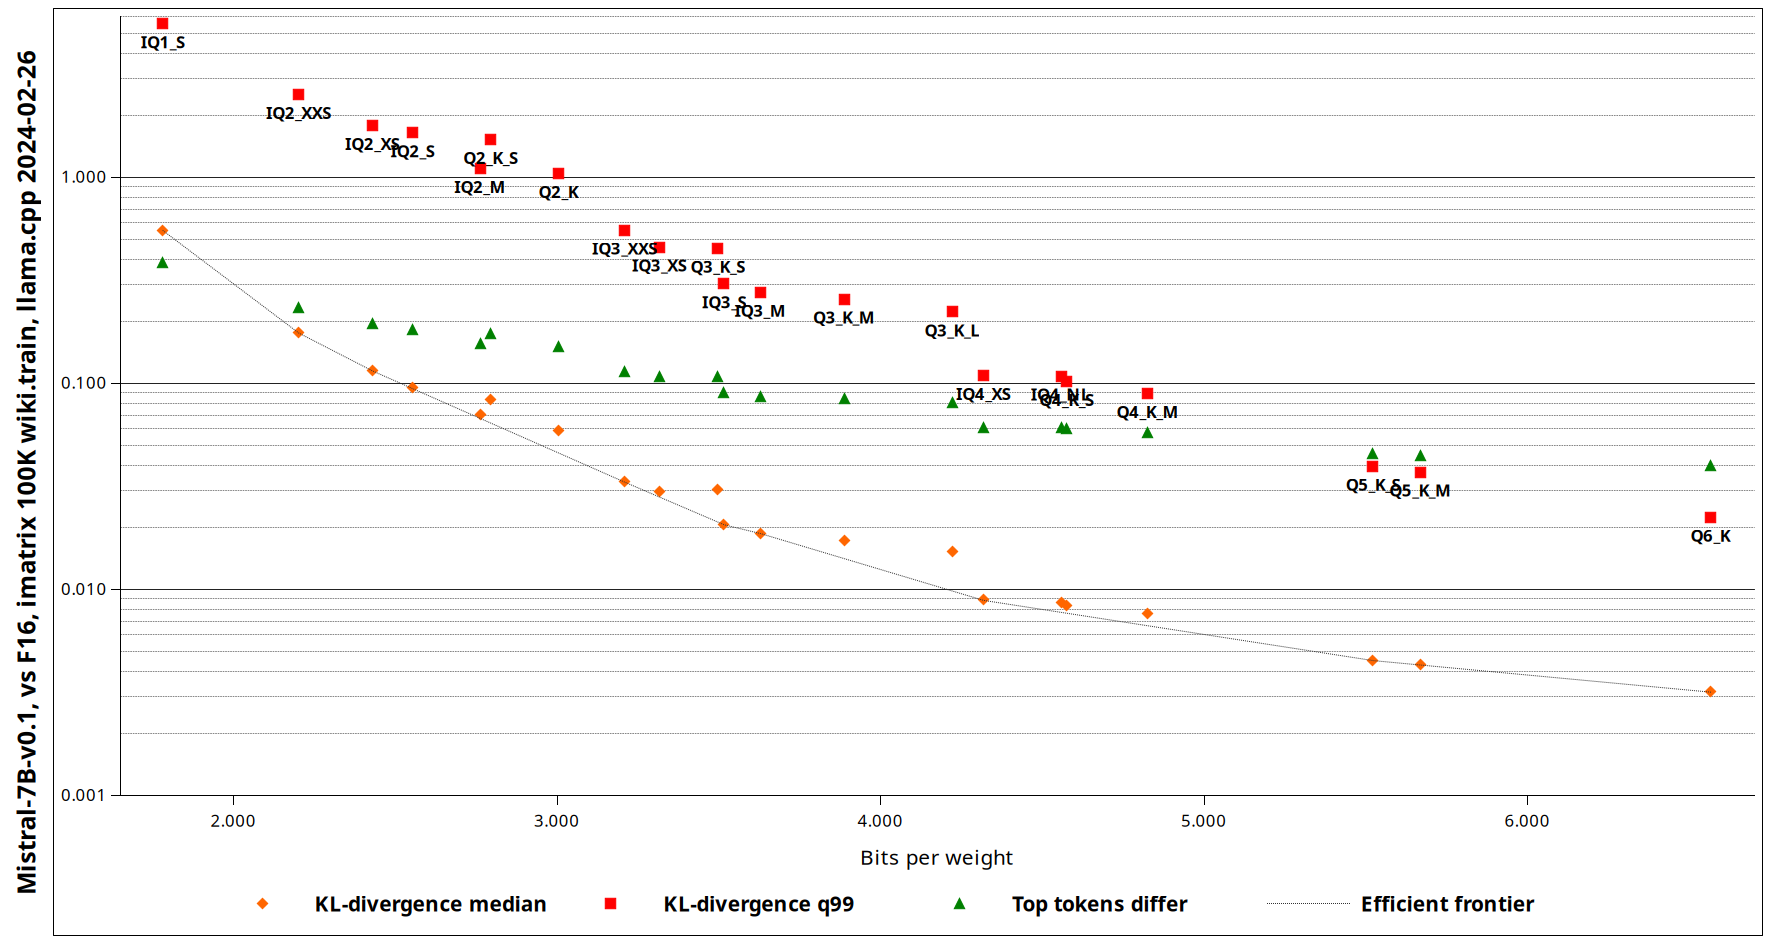
GGUF Quantization with Imatrix and K-Quantization to Run LLMs on Your CPU

GGUF Quantization with Imatrix and K-Quantization to Run LLMs on Your CPU
GGUF Quantization with Imatrix and K-Quantization to Run LLMs on Your CPU

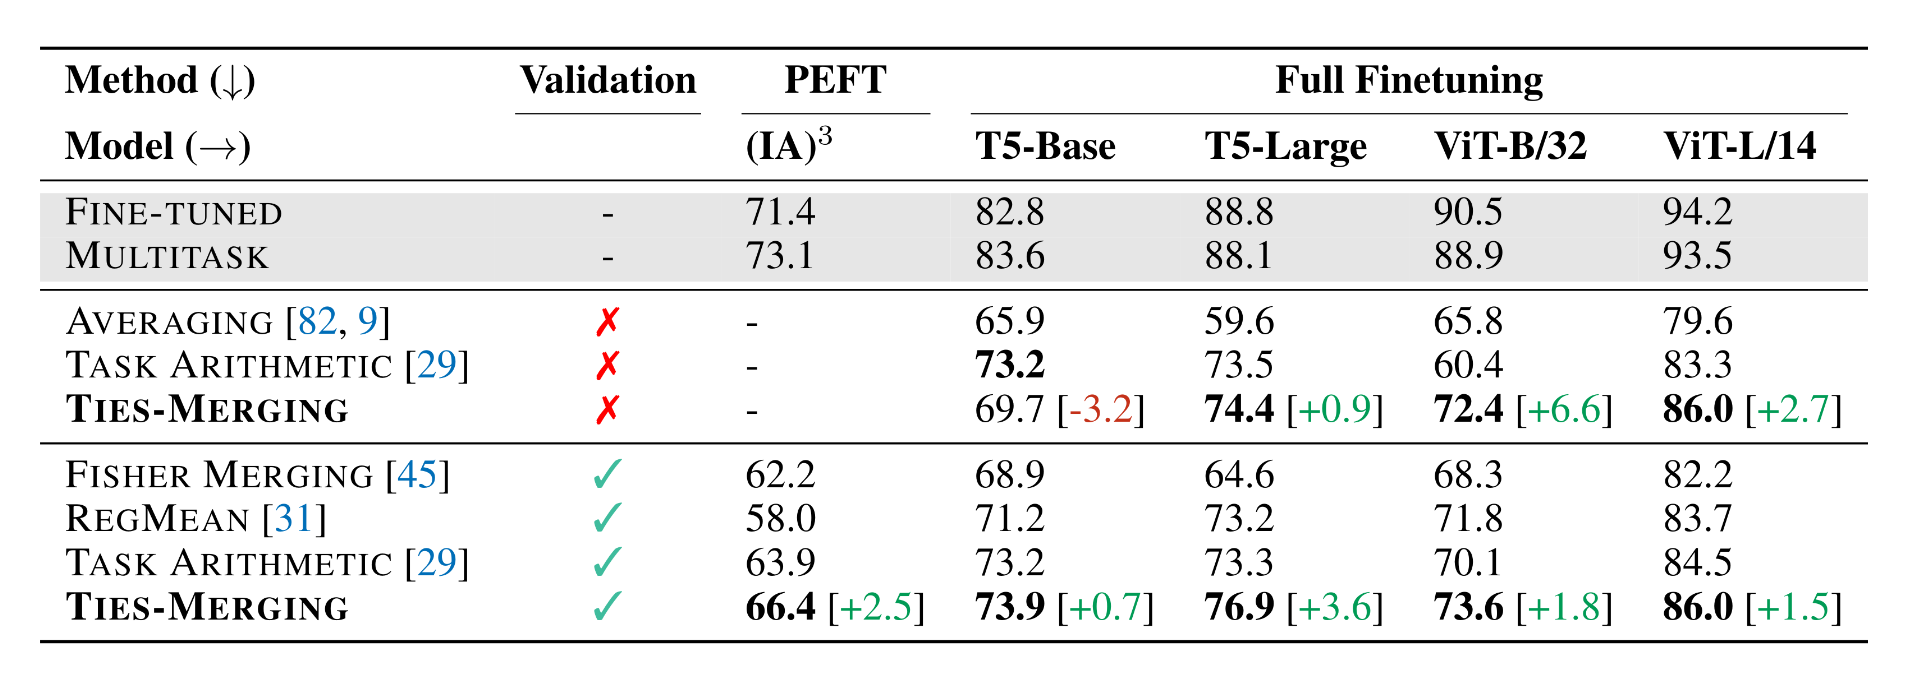
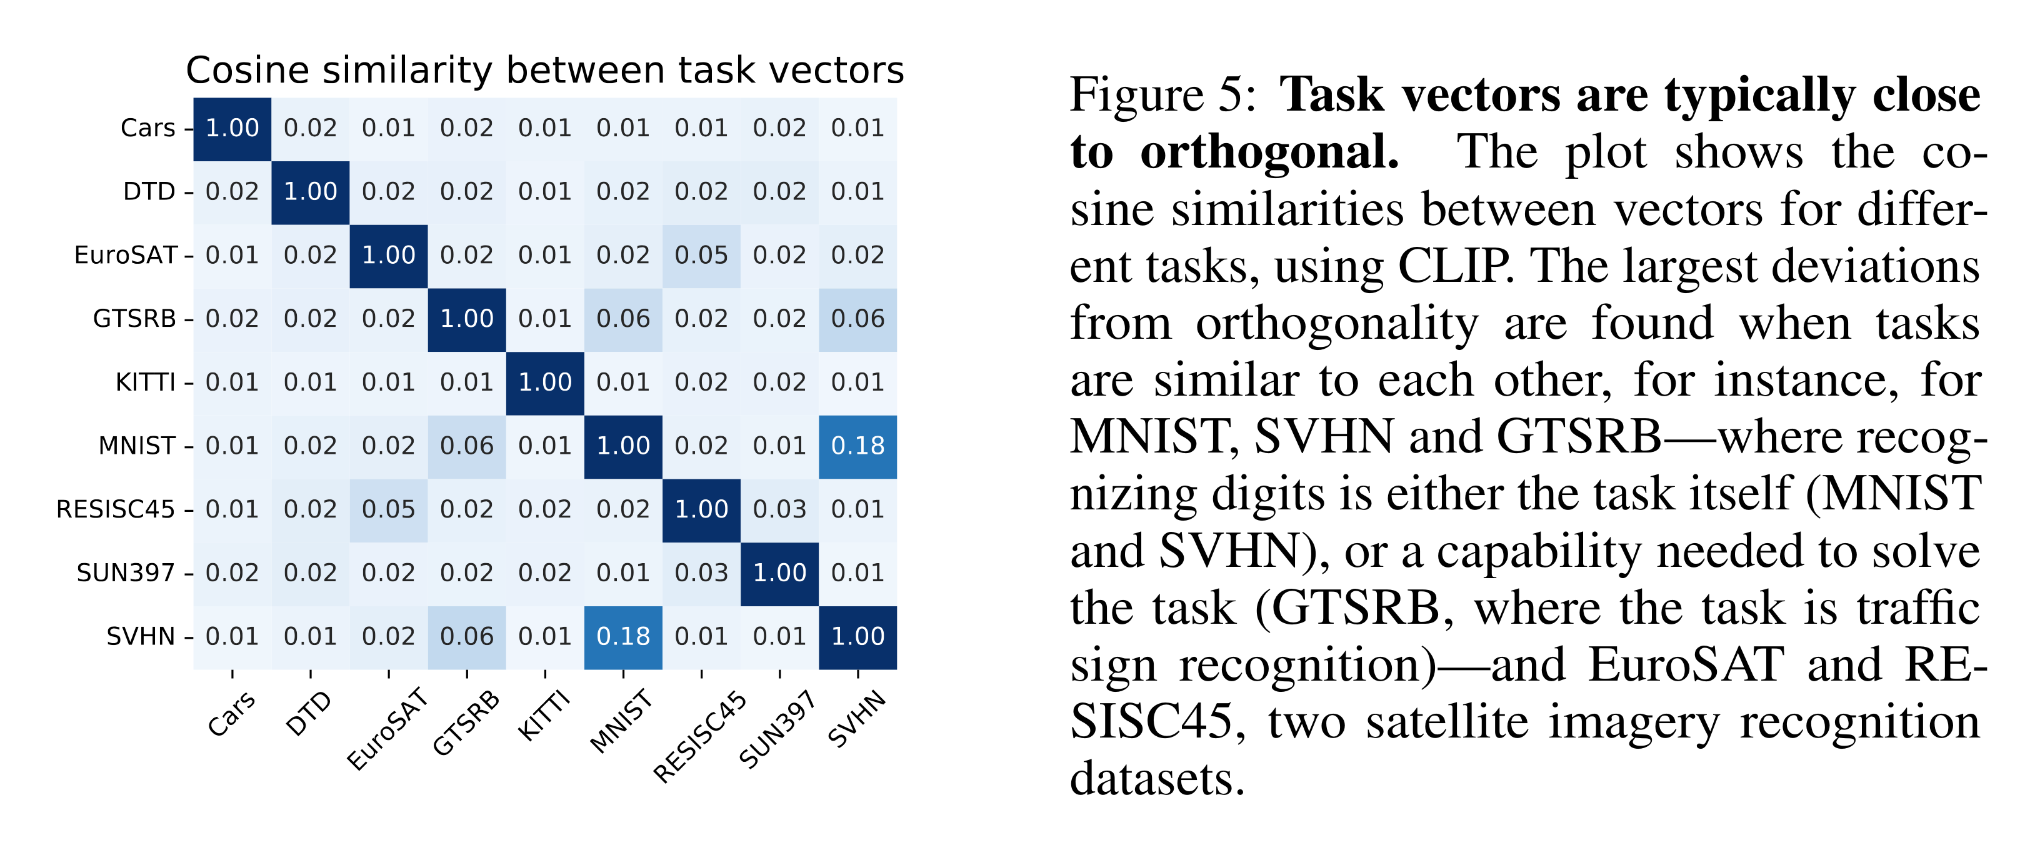
Task Vector Quantization for Memory-Efficient Model Merging
Advertisement Space (300x250)

Task Vector Quantization for Memory-Efficient Model Merging
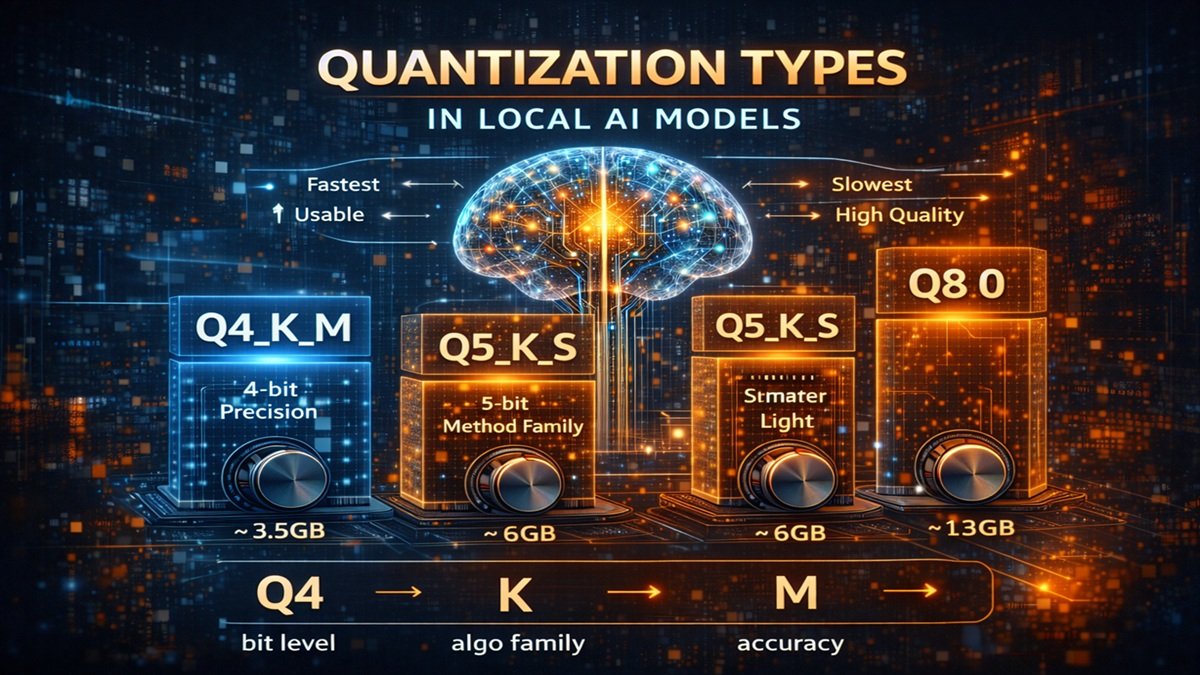
GGUF Quantization Explained: What Q4_K_M, Q5_K_S, and Q8_0 Really Mean ...

Simplifying Quantization in LLMs: GGUF, GPTQ, AWQ and More | by Anand ...

AutoGGUF - GUI for GGUF Model Quantization - Install Locally - YouTube
มาลอง Quantization Flux Model ใดๆด้วยวิธี GGUF กันเถอะ | vjumpkung
K-Quants Explained: GGUF Quantization and Super-Blocks · Microscale
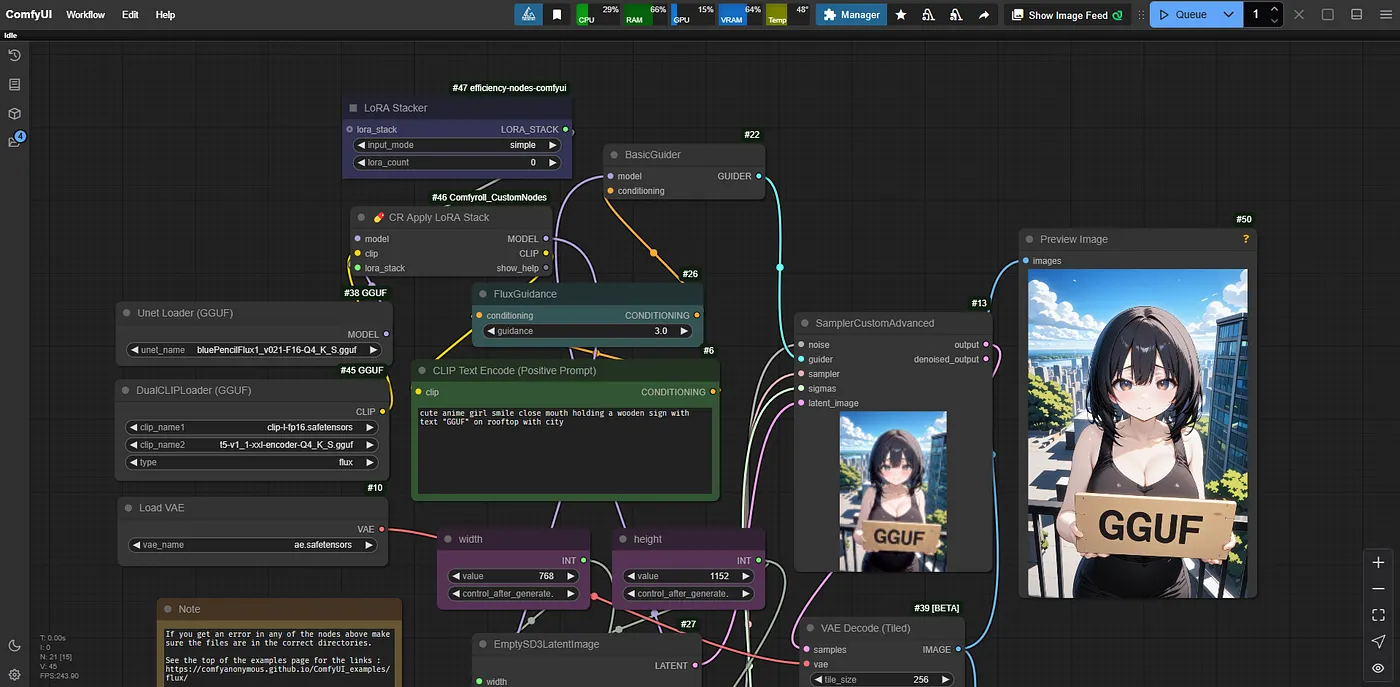
มาลอง Quantization Flux Model ใดๆด้วยวิธี GGUF กันเถอะ | vjumpkung
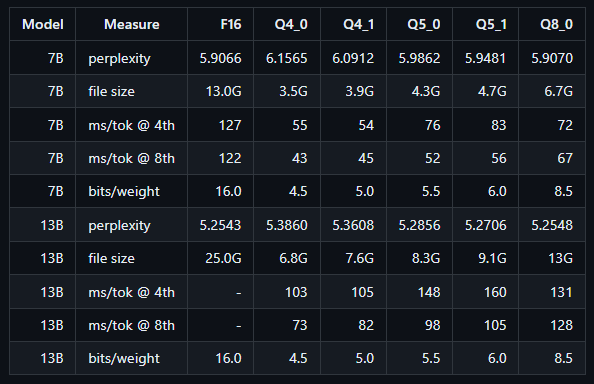
GGUF Quantization for Fast and Memory-Efficient Inference on Your CPU
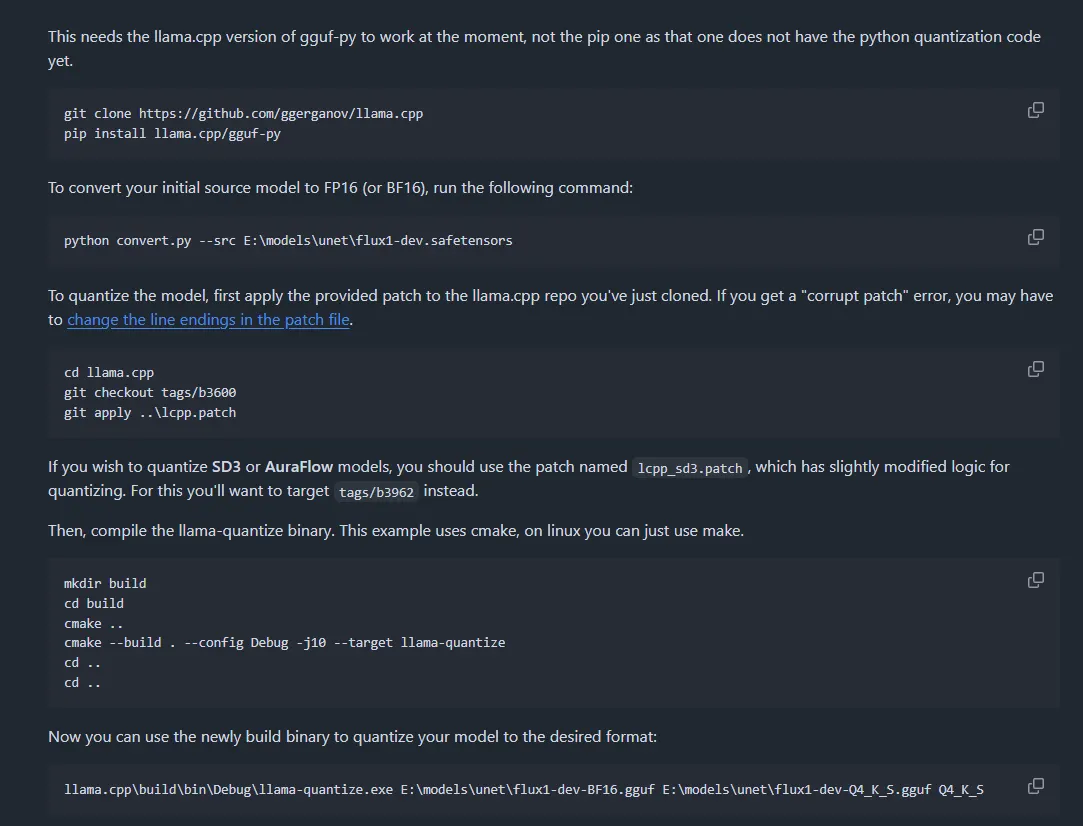
มาลอง Quantization Flux Model ใดๆด้วยวิธี GGUF กันเถอะ | vjumpkung

Quantization tech of LLMs-GGUF. We can use GGUF to offload any layer of ...
Advertisement Space (336x280)
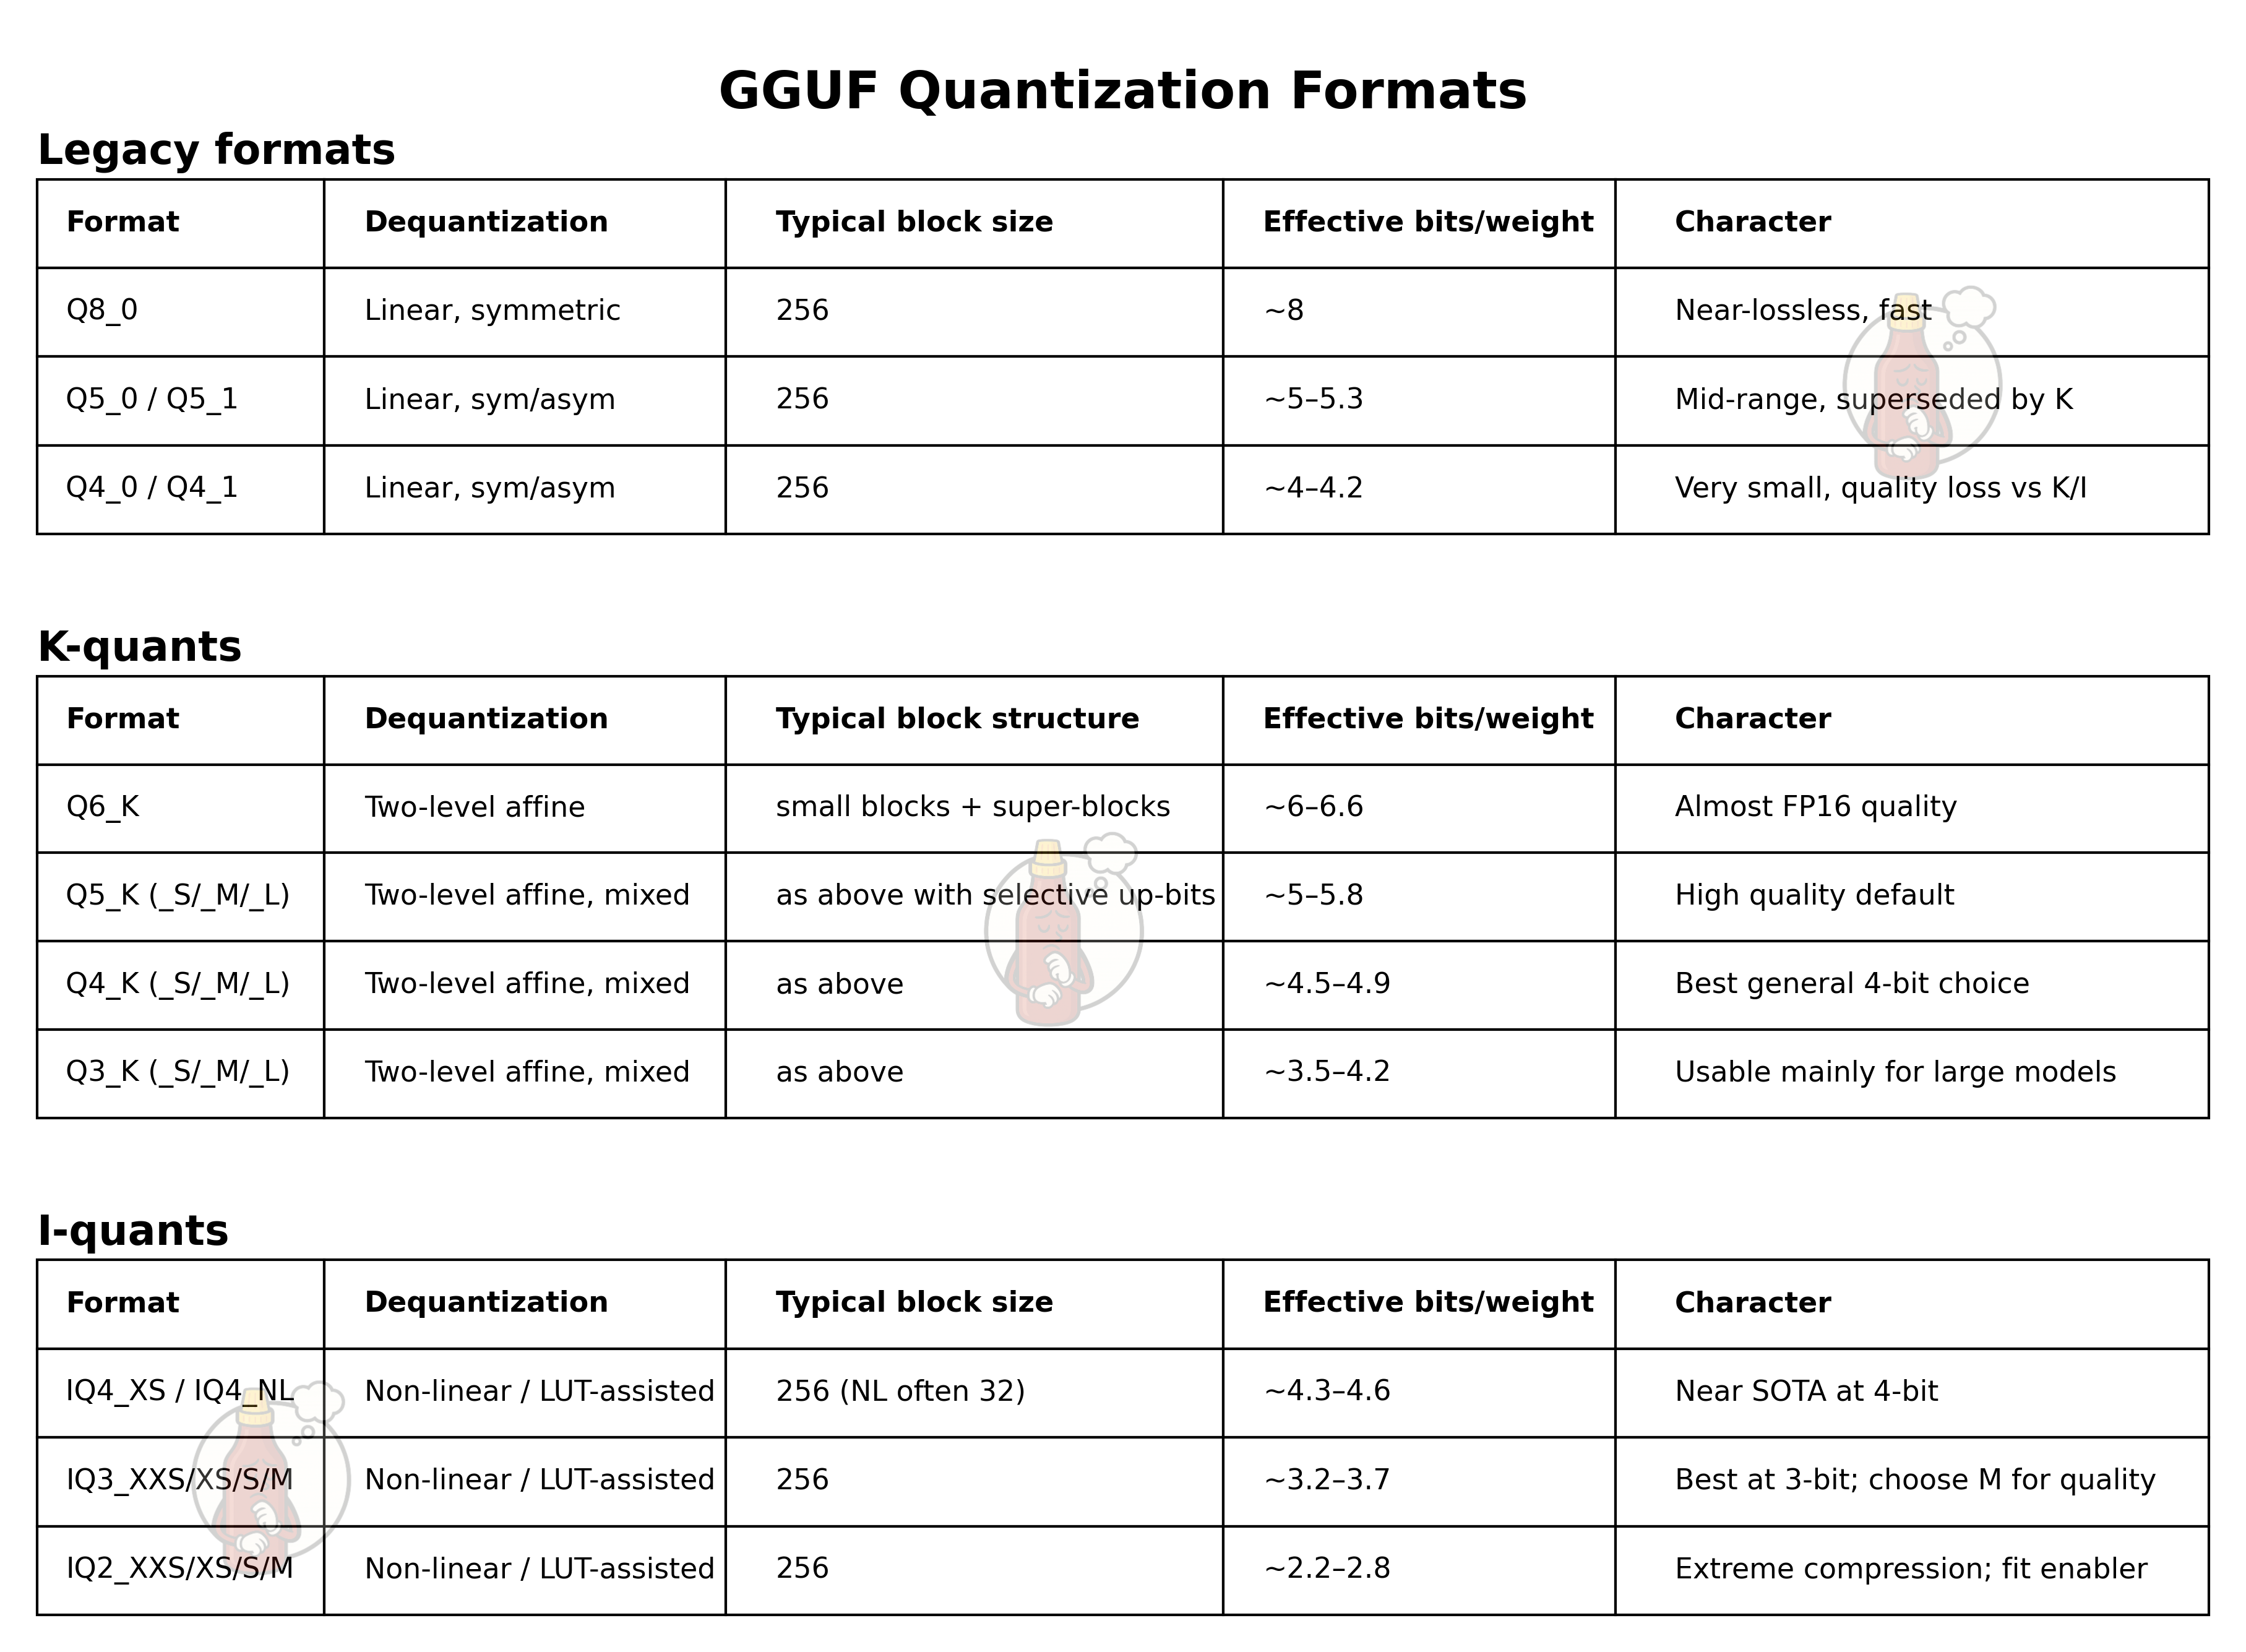
Choosing a GGUF Model: K-Quants, I-Quants, and Legacy Formats

GitHub - som1tokmynam/FusionQuant: FusionQuant Model Merge & GGUF ...
GitHub - bateikoEd/llm-quantized-evaluation: The page provides a step ...

How to boost LLM quantization with GGUF | MarTechRichard posted on the ...
Q4_K_M vs Q5_K_M vs Q8 — Which GGUF Quantization Should You Use? (2026 ...

Run a LLM on your WINDOWS PC | Convert Hugging face model to GGUF ...
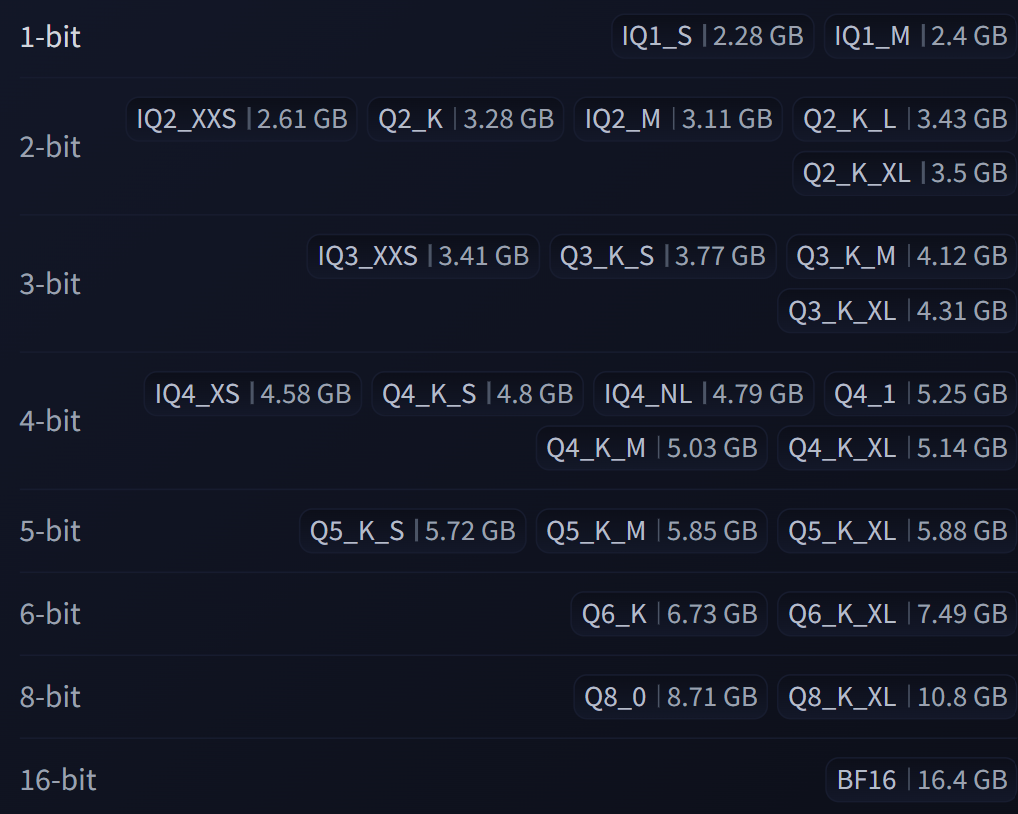
Choosing a GGUF Model: K-Quants, I-Quants, and Legacy Formats

使用 Imatrix 和 K-Quantization 进行 GGUF 量化以在 CPU 上运行 LLM - 知乎
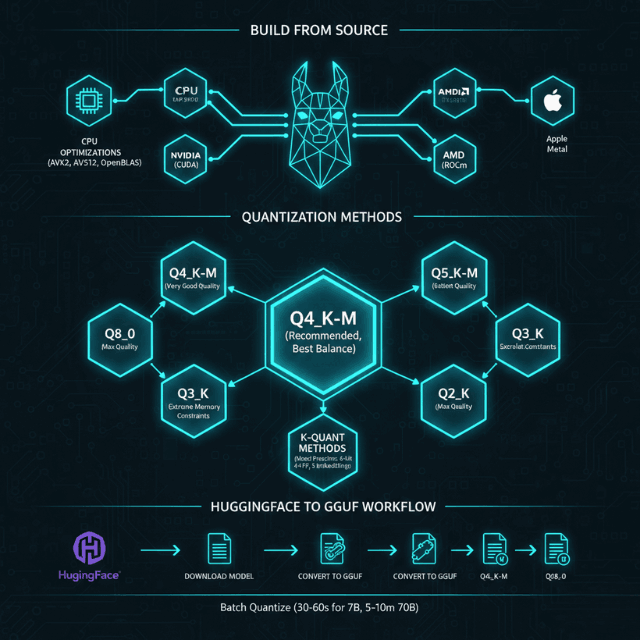
Run 70B LLMs on Consumer GPU - VRAM and Quantization Guide (2026)

Unsloth의 Qwen3.5 GGUF 최종 업데이트: iMatrix 및 새로운 동적 알고리즘 적용 | AI Trends
Advertisement Space (336x280)

Which Quantization Method is Right for You? (GPTQ vs. GGUF vs. AWQ)

Which Quantization Method is Right for You? (GPTQ vs. GGUF vs. AWQ)
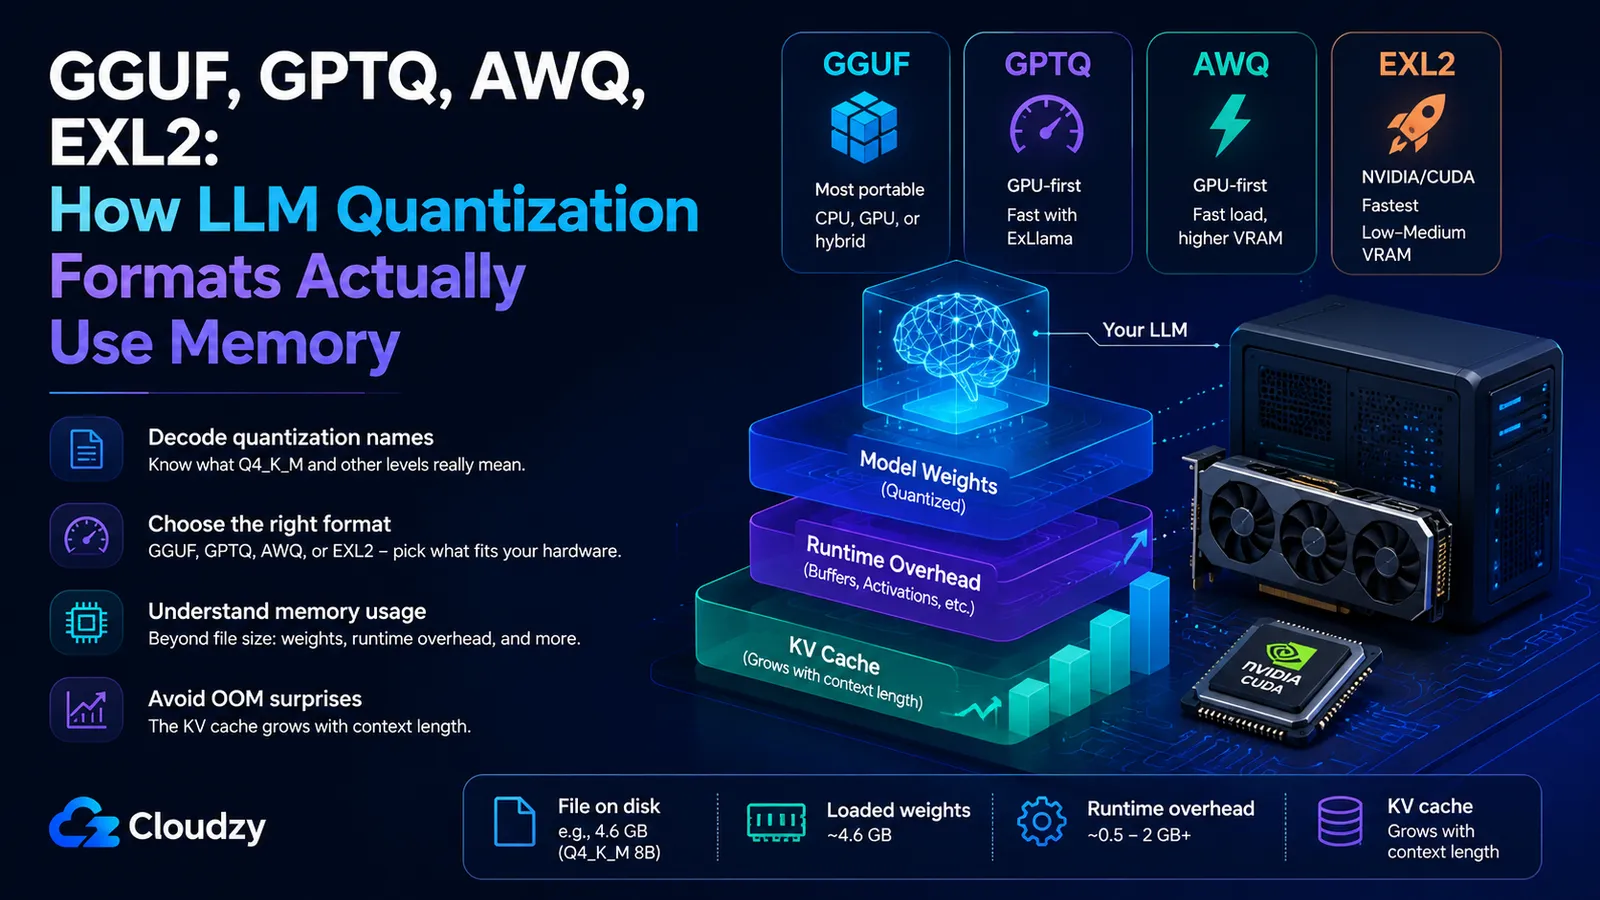
GGUF vs GPTQ vs AWQ vs EXL2: Quantization Formats Explained · Cloudzy Blog

Paper page - Mind the Gap: A Practical Attack on GGUF Quantization
GGUF Dynamic Quantization on GPU Cloud: Deploy LLMs 50% Cheaper with ...
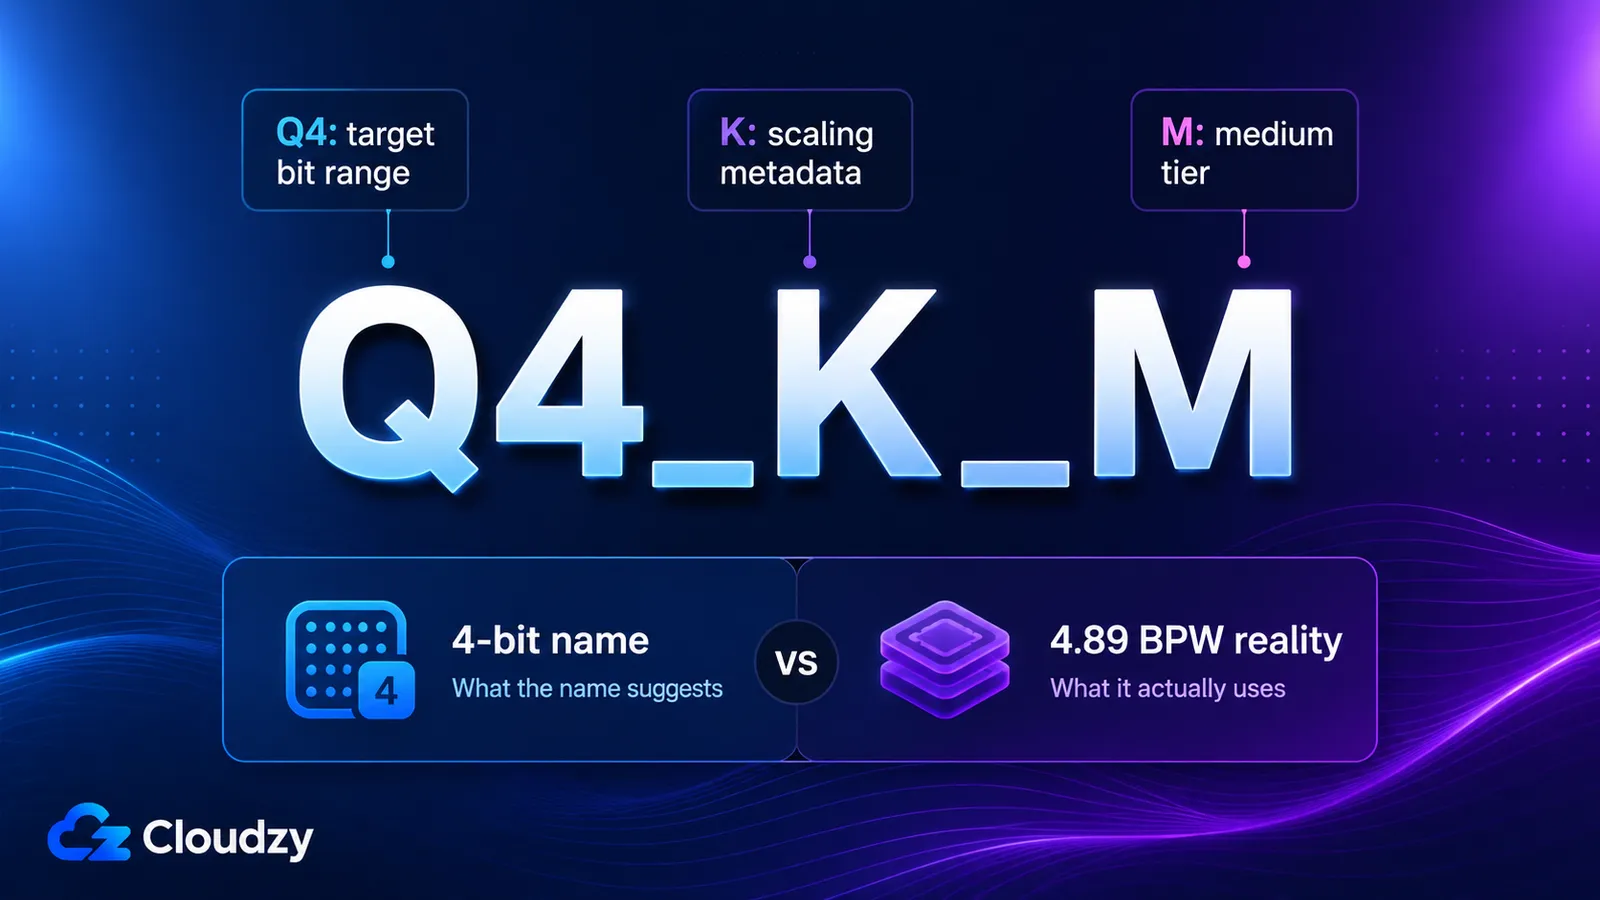
GGUF vs GPTQ vs AWQ vs EXL2: Quantization Formats Explained · Cloudzy Blog