
Gguf Quantization With Imatrix And K Quantization To Run Llms On Your Cpu

GGUF Quantization with Imatrix and K-Quantization to Run LLMs on Your CPU

GGUF Quantization with Imatrix and K-Quantization to Run LLMs on Your CPU
GGUF Quantization with Imatrix and K-Quantization to Run LLMs on Your CPU

GGUF Quantization Tutorial: Run Fine-Tuned LLMs on CPU with llama.cpp ...
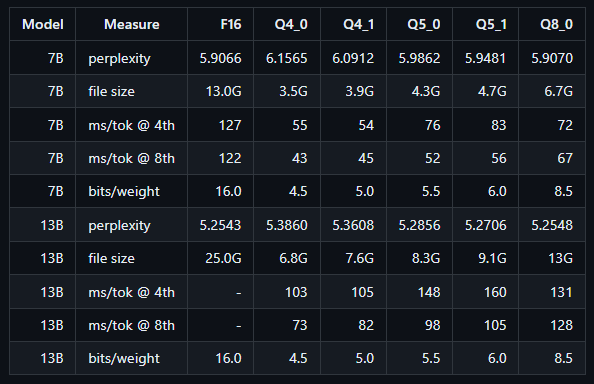
GGUF Quantization for Fast and Memory-Efficient Inference on Your CPU

Run Big LLMs on Small GPUs: A Hands-On Guide to 4-bit Quantization and ...
GGUF Dynamic Quantization on GPU Cloud: Deploy LLMs 50% Cheaper with ...

Run GGUF Quantized 7B LLMs with no GPU on your laptop - YouTube

LLMs on CPU: The Power of Quantization with GGUF, AWQ, & GPTQ
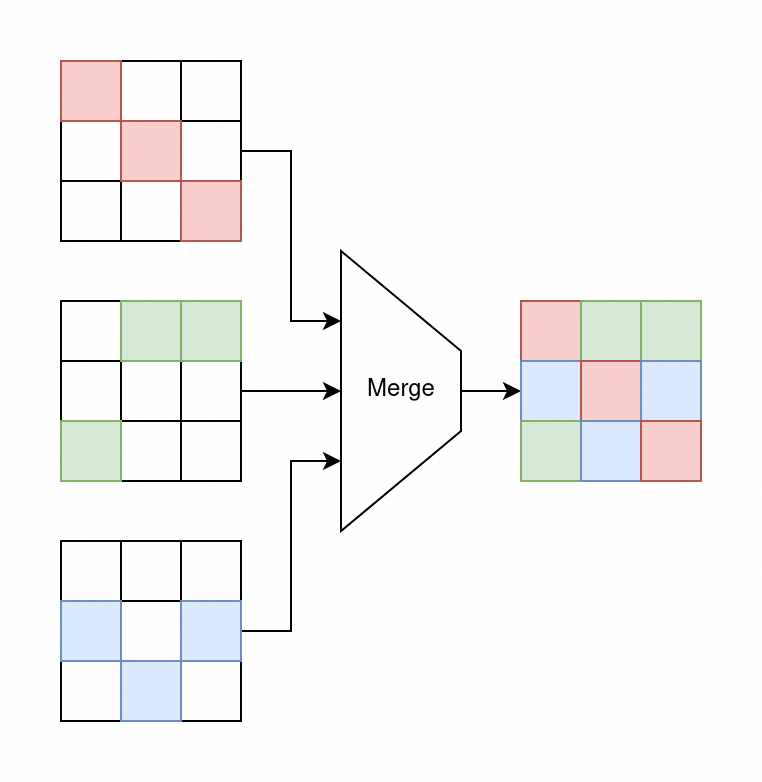
Step-by-Step Model Merging and GGUF imatrix Quantization | K4YT3X
Advertisement Space (300x250)
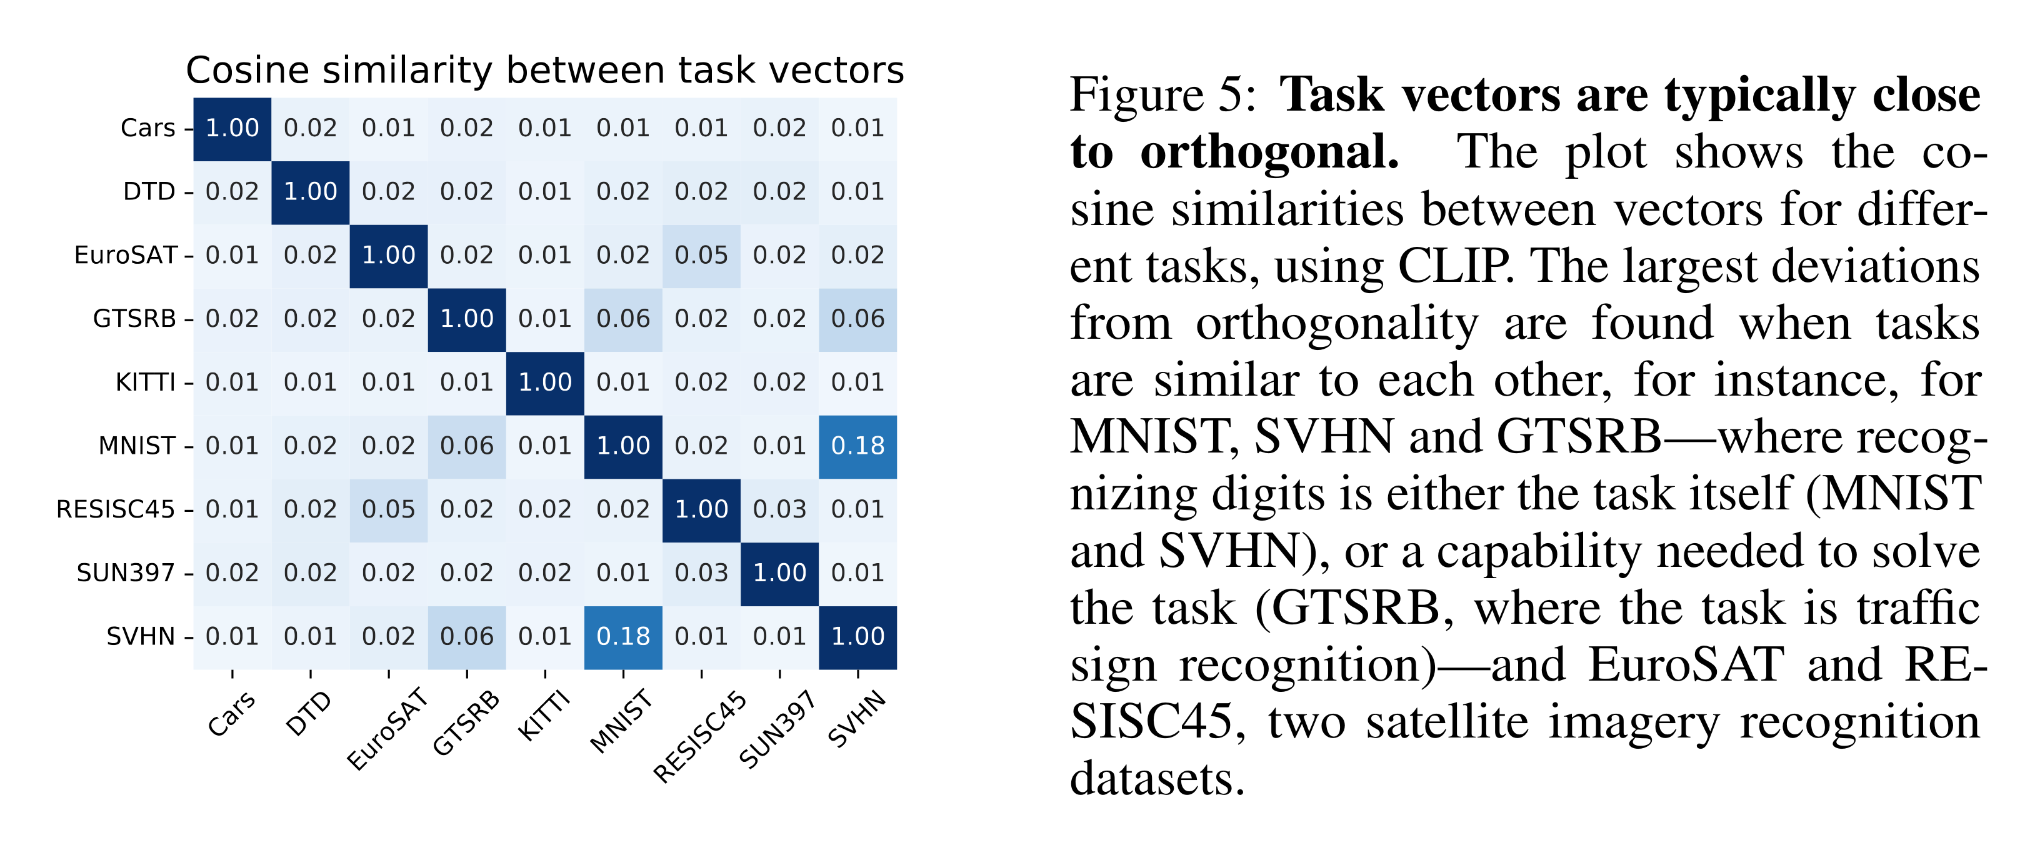
Step-by-Step Model Merging and GGUF imatrix Quantization

LLMs on CPU: The Power of Quantization with GGUF, AWQ, & GPTQ

Run a LLM on your WINDOWS PC | Convert Hugging face model to GGUF ...

GGUF quantization of LLMs with llama cpp - YouTube

LLMs on CPU: The Power of Quantization with GGUF, AWQ, & GPTQ
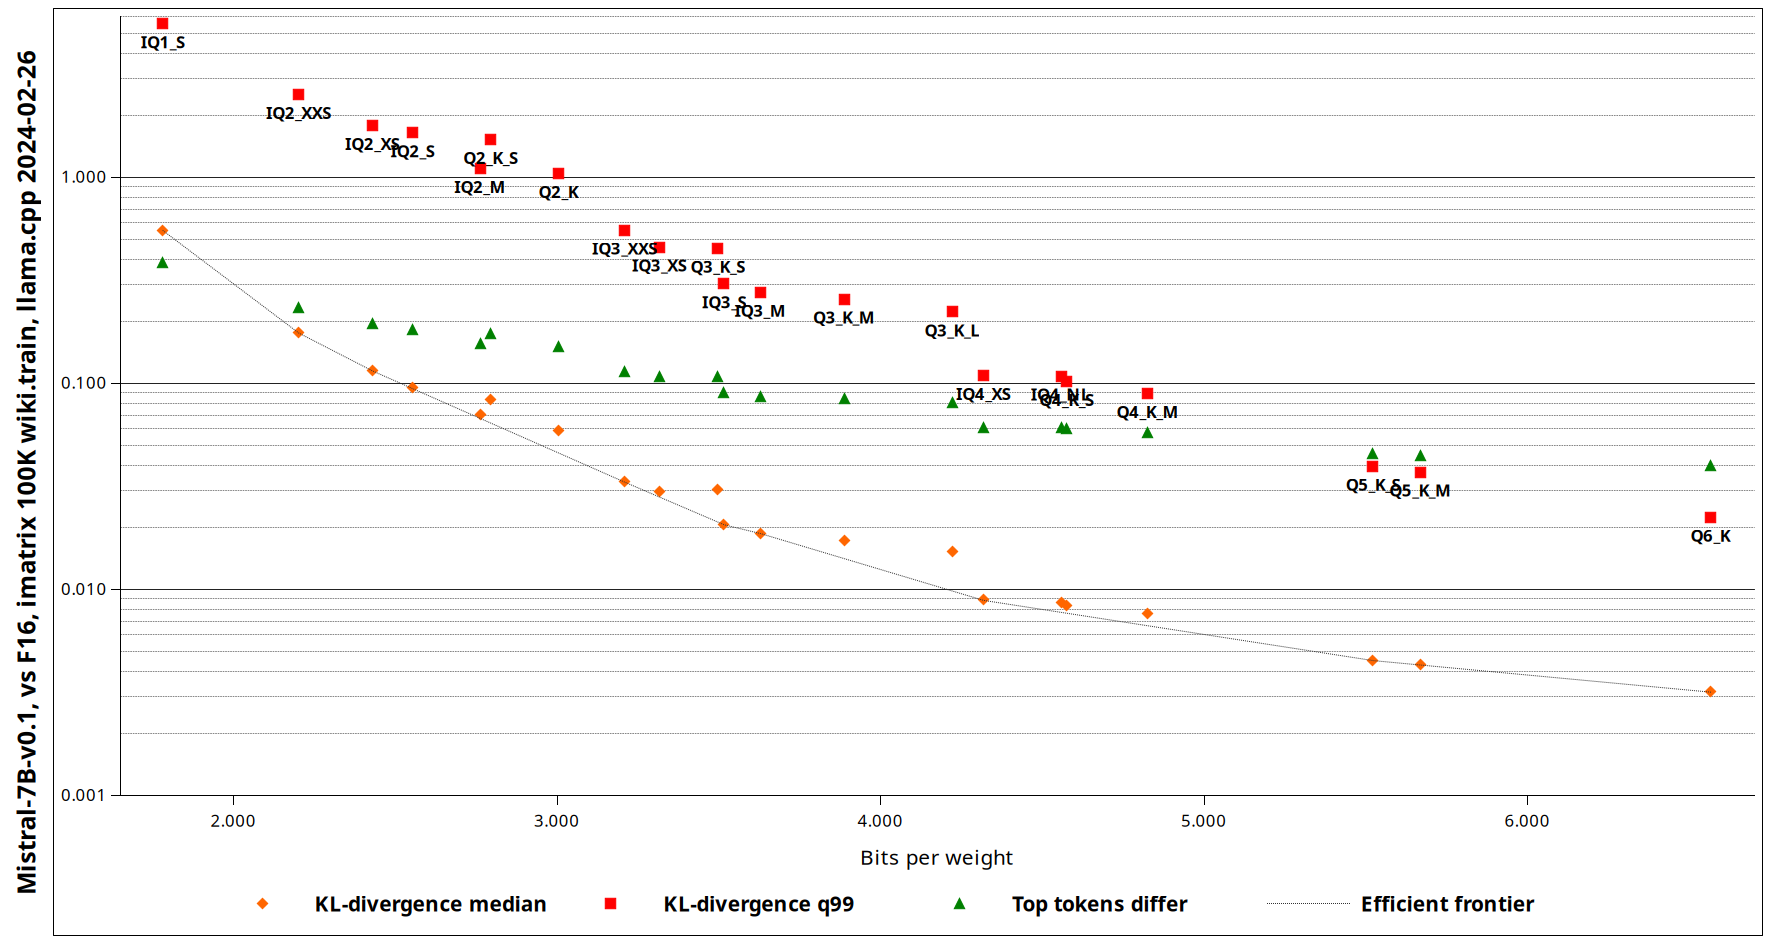
Step-by-Step Model Merging and GGUF imatrix Quantization
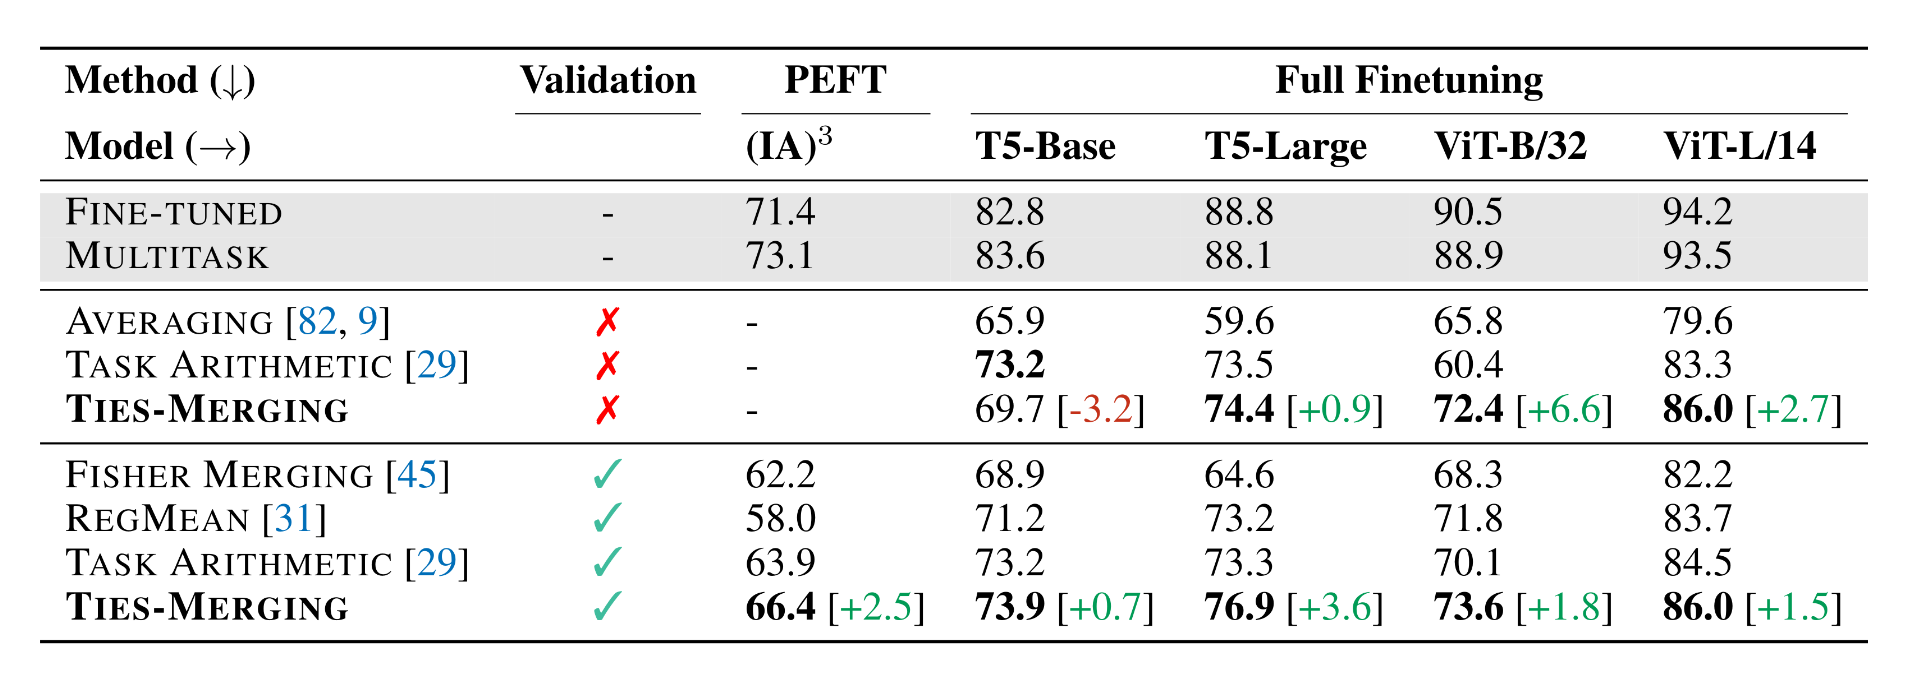
Step-by-Step Model Merging and GGUF imatrix Quantization
Faster LLMs with Quantization - How to get faster inference times with ...
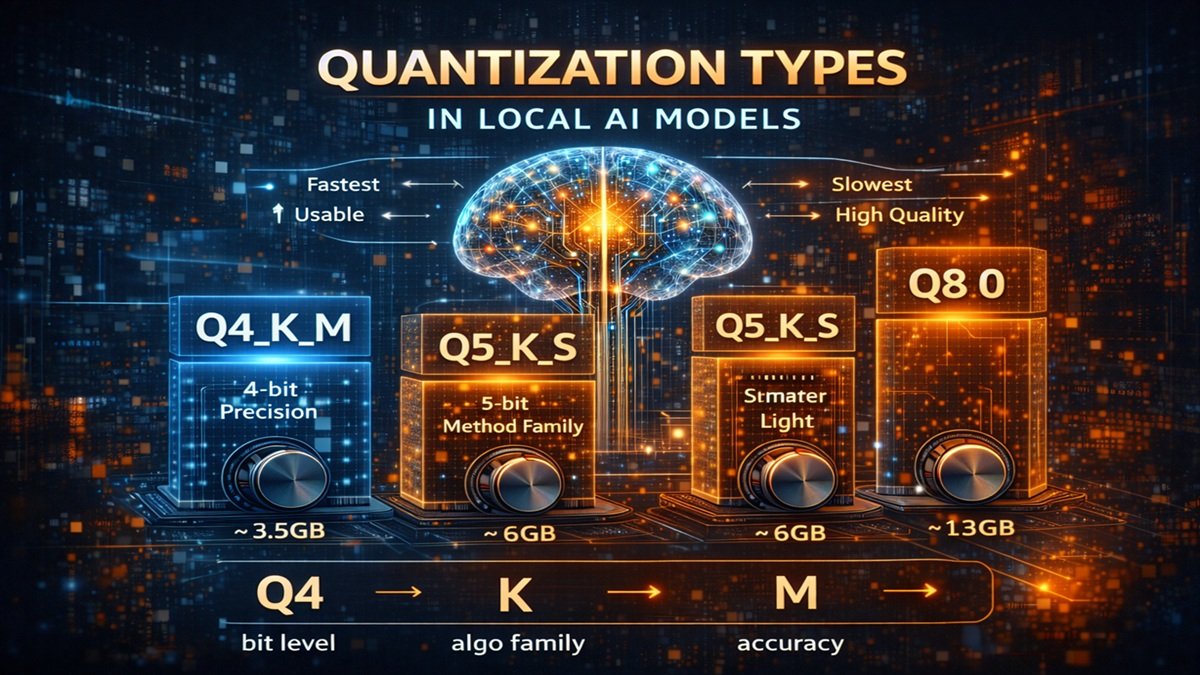
GGUF Quantization Explained: What Q4_K_M, Q5_K_S, and Q8_0 Really Mean ...

Quantization tech of LLMs-GGUF. We can use GGUF to offload any layer of ...
Advertisement Space (336x280)

How to run LLMs on CPU-based systems | UnfoldAI

GGUF Quantization Explained: Q4_K_M vs Q5_K_M vs Q8 — Which to Pick ...
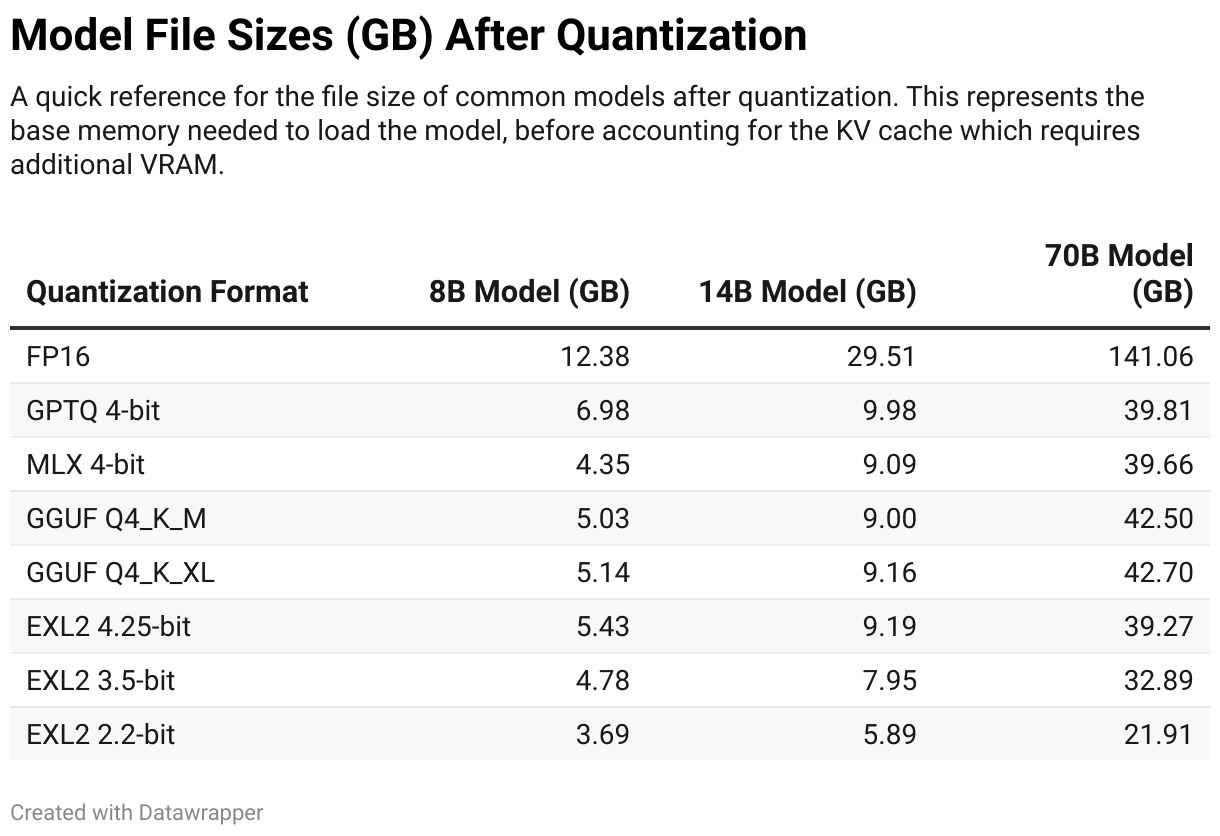
Quantization for Local LLMs: How It Works and Which Formats Fit Your Setup

[GGML] Machine learning Tensor Library. GGUF and Quantization for Edge ...

4Bit Quantization GPTQ and GGUF and 1Bit LLM - Kyle’s Tech Blog
LLM Quantization on Kubernetes: Run Production AI Inference Without ...

Paper page - Mind the Gap: A Practical Attack on GGUF Quantization
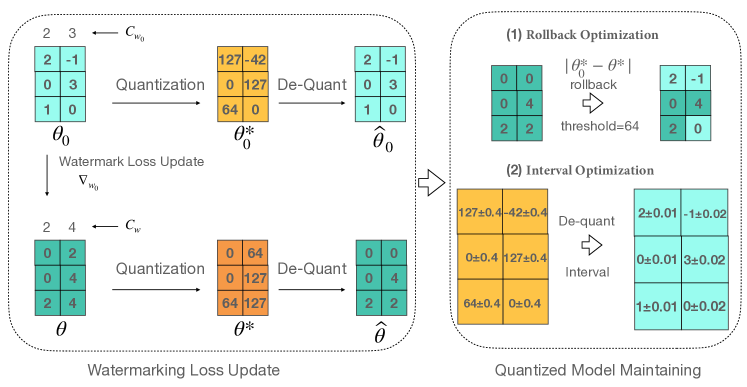
[2310.11237] Watermarking LLMs with Weight Quantization
A Guide to Quantization in LLMs | Symbl.ai

wave-on-discord/gemini-nano · how to quantize to GGUF quantization
Advertisement Space (336x280)

4Bit Quantization GPTQ and GGUF and 1Bit LLM - Kyle’s Tech Blog

Local AI Basics: GGUF Quantization And Llama.cpp Explained - YouTube

4Bit Quantization GPTQ and GGUF and 1Bit LLM - Kyle’s Tech Blog

Simplifying Quantization in LLMs: GGUF, GPTQ, AWQ and More | by Anand ...

使用 Imatrix 和 K-Quantization 进行 GGUF 量化以在 CPU 上运行 LLM - 知乎

LLM Quantization Methods: GPTQ, AWQ, GGUF - Cast AI