
Table 1 From Copr Continual Human Preference Learning Via Optimal

Figure 1 from COPR: Continual Human Preference Learning via Optimal ...
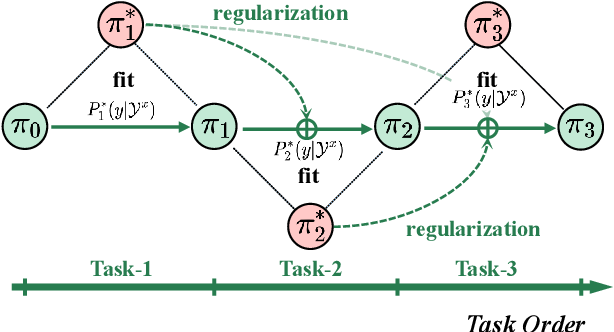
Figure 1 from COPR: Continual Human Preference Learning via Optimal ...

Table 2 from COPR: Continual Human Preference Learning via Optimal ...
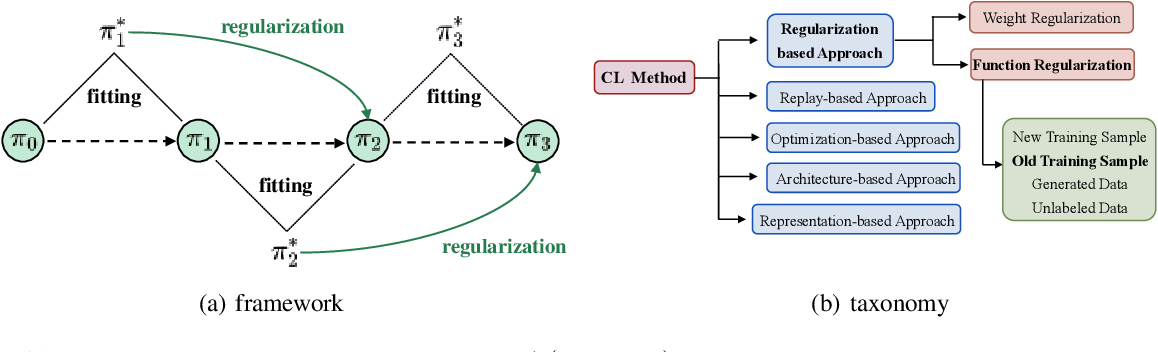
Figure 1 from COPR: Continual Learning Human Preference through Optimal ...
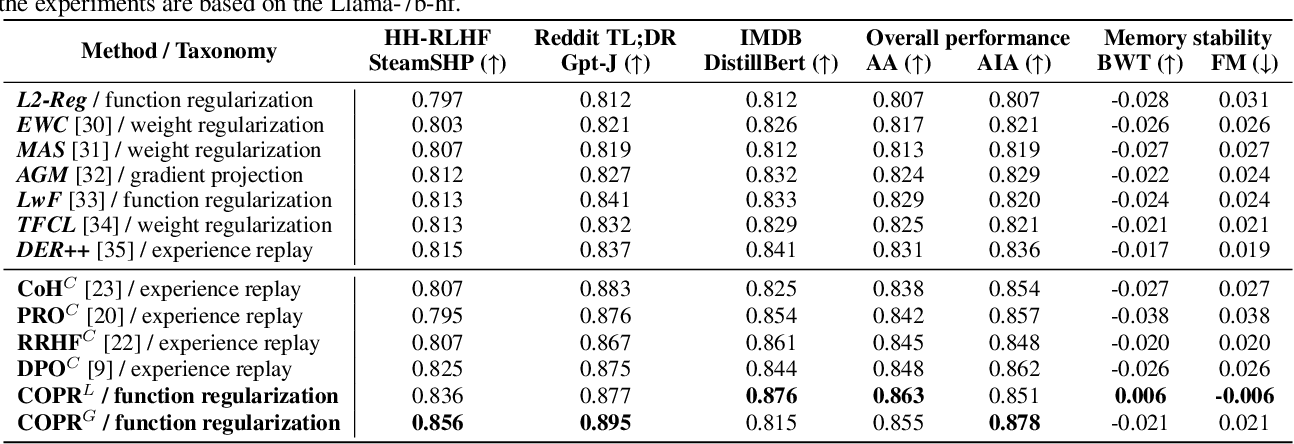
Table 3 from COPR: Continual Learning Human Preference through Optimal ...
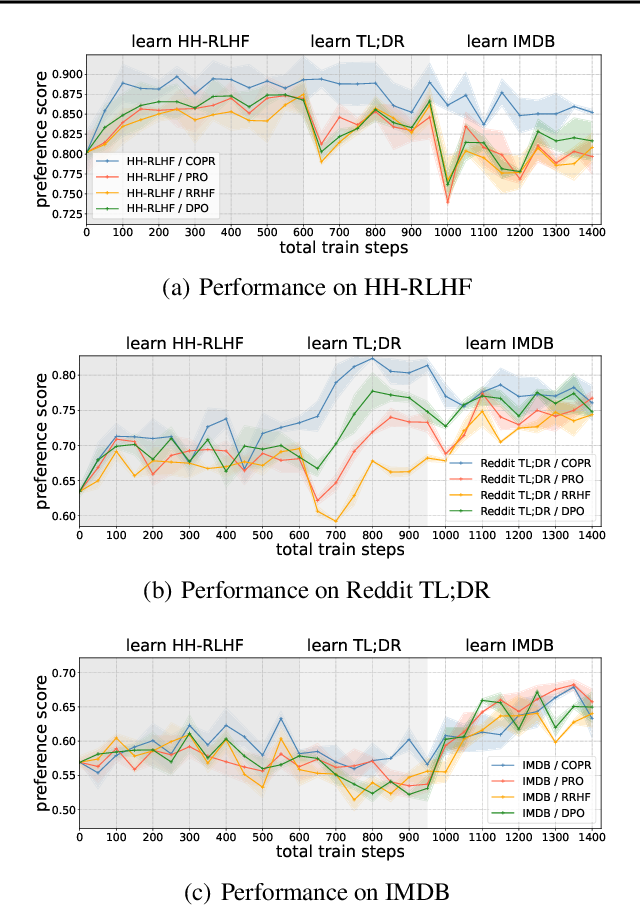
Figure 2 from COPR: Continual Human Preference Learning via Optimal ...
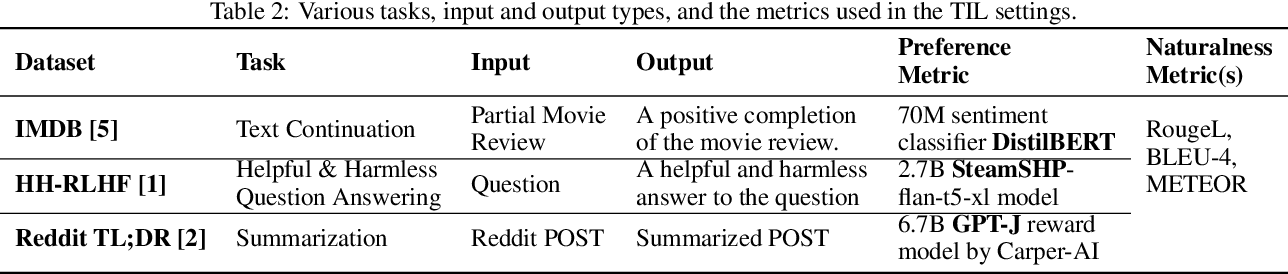
Table 2 from COPR: Continual Learning Human Preference through Optimal ...

COPR: Continual Human Preference Learning via Optimal Policy ...
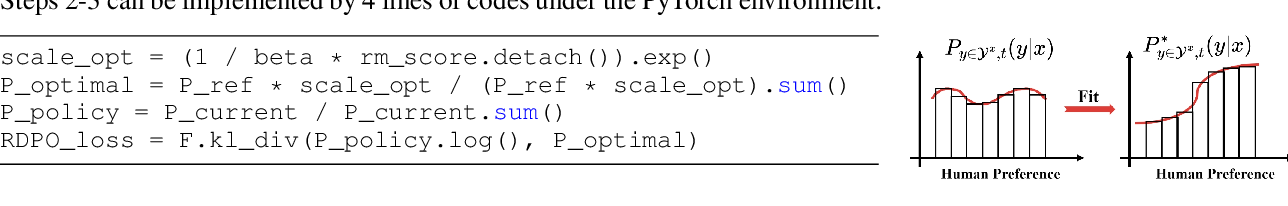
Figure 2 from COPR: Continual Learning Human Preference through Optimal ...
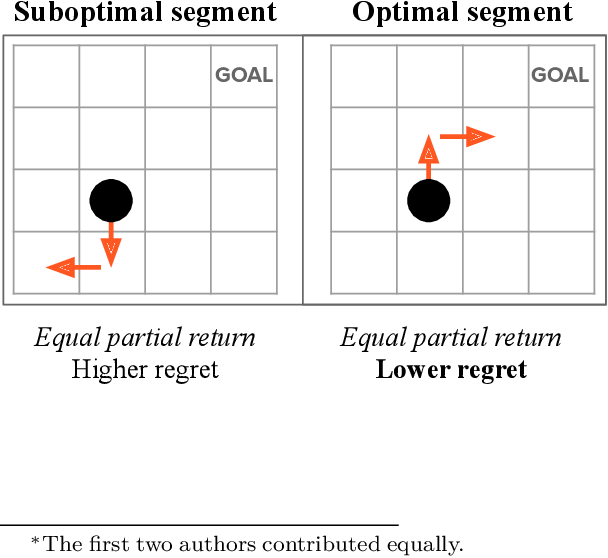
Figure 1 from Models of human preference for learning reward functions ...
Advertisement Space (300x250)

Table 2 from Models of human preference for learning reward functions ...

Table 1 from Continual semi-supervised learning through contrastive ...

Table 4 from Models of human preference for learning reward functions ...

Table 1 from Can LLMs Capture Human Preferences? | Semantic Scholar
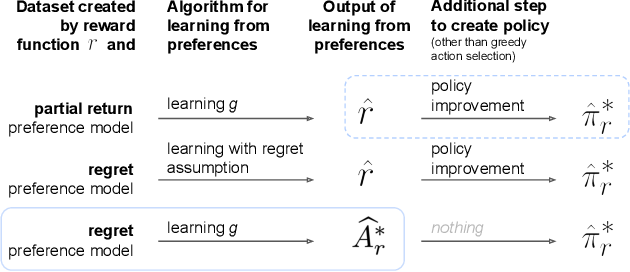
Figure 1 from Learning Optimal Advantage from Preferences and Mistaking ...

Figure 16 from Models of human preference for learning reward functions ...

Table 1 from Self-Supervised Primal-Dual Learning for Constrained ...

Optimal protocols for continual learning via statistical physics and ...
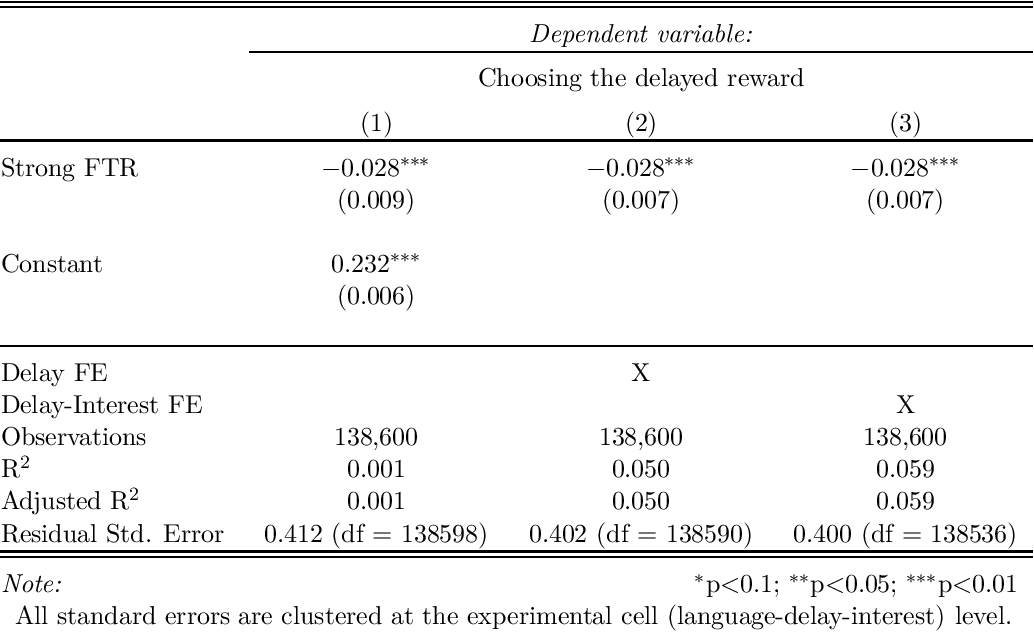
Table 1 from Can LLMs Capture Human Preferences? | Semantic Scholar
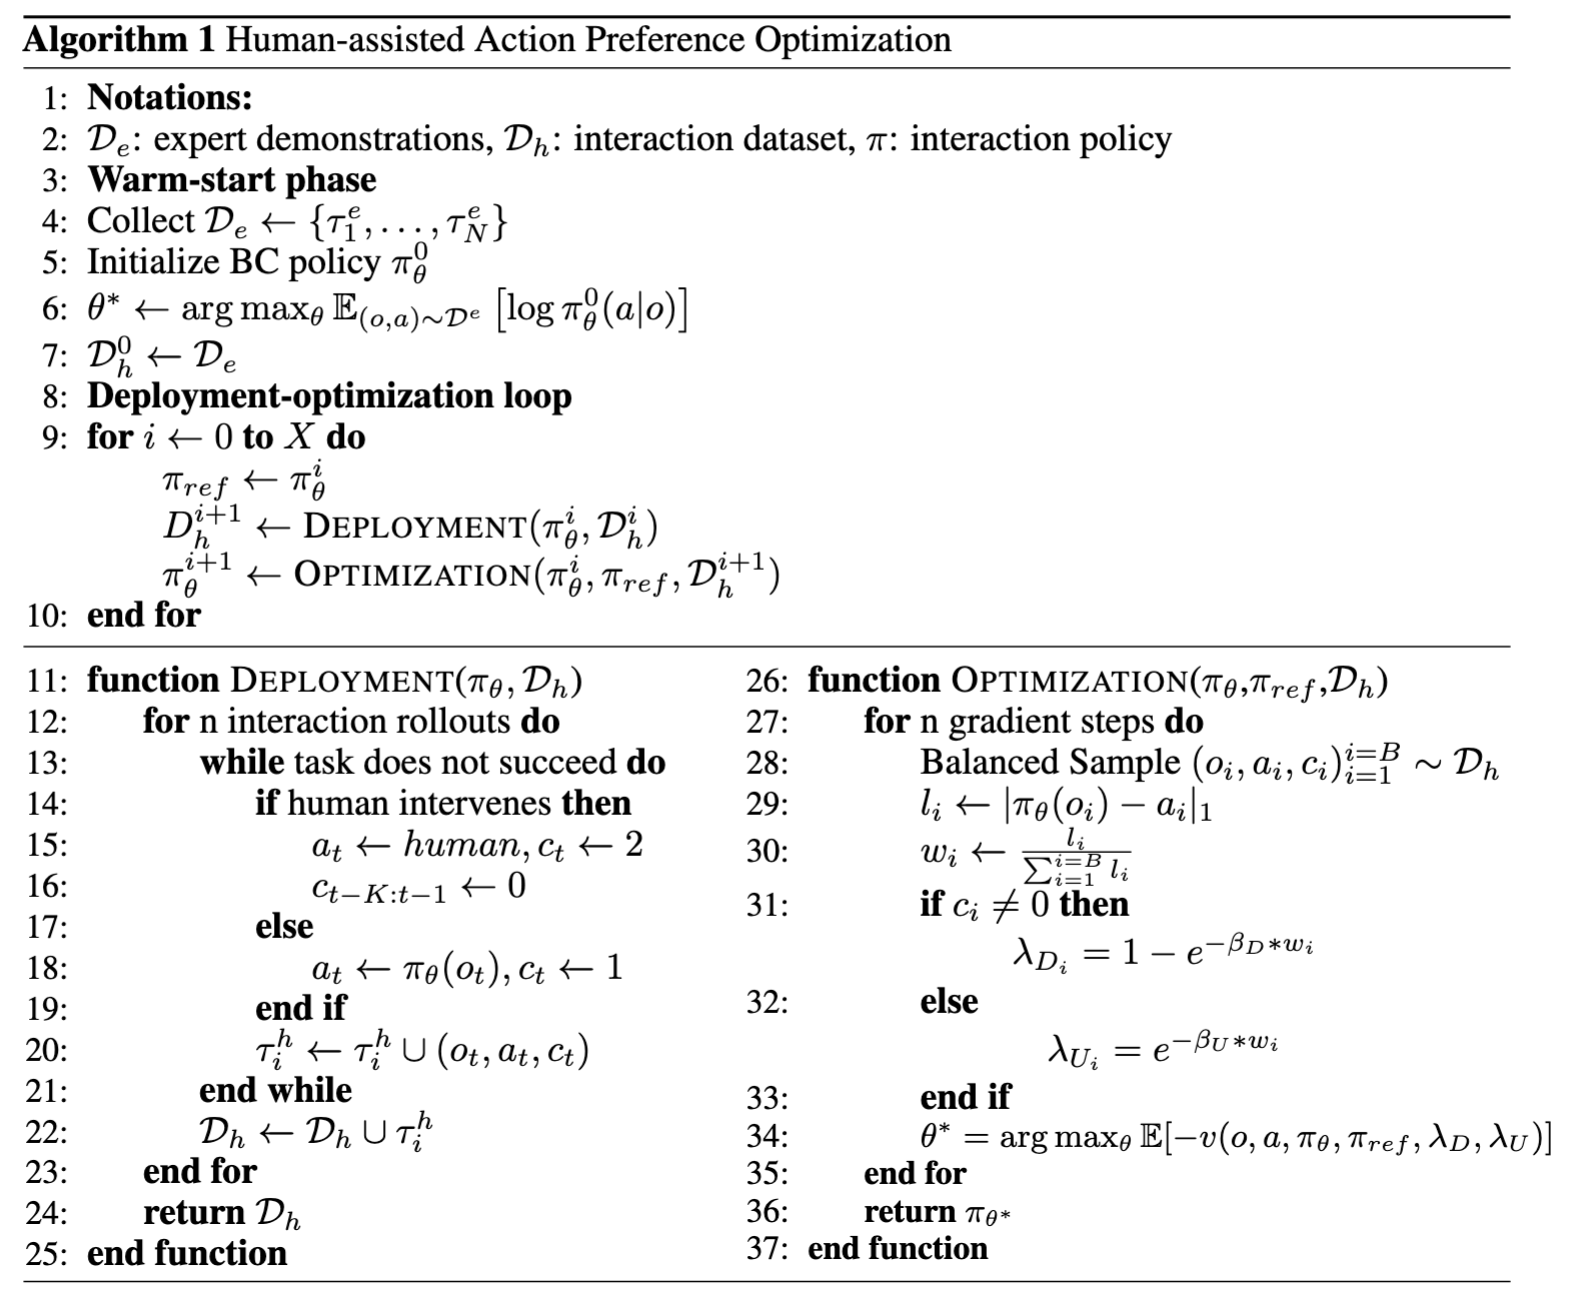
Robotic Policy Learning via Human-assisted Action Preference Optimization
Advertisement Space (336x280)

Robotic Policy Learning via Human-assisted Action Preference Optimization

[논문 리뷰] LRHP: Learning Representations for Human Preferences via ...

PILAF: Optimal Human Preference Sampling for Reward Modeling · HF Daily ...

Robotic Policy Learning via Human-assisted Action Preference Optimization

A Survey on Human Preference Learning for Aligning Large Language ...
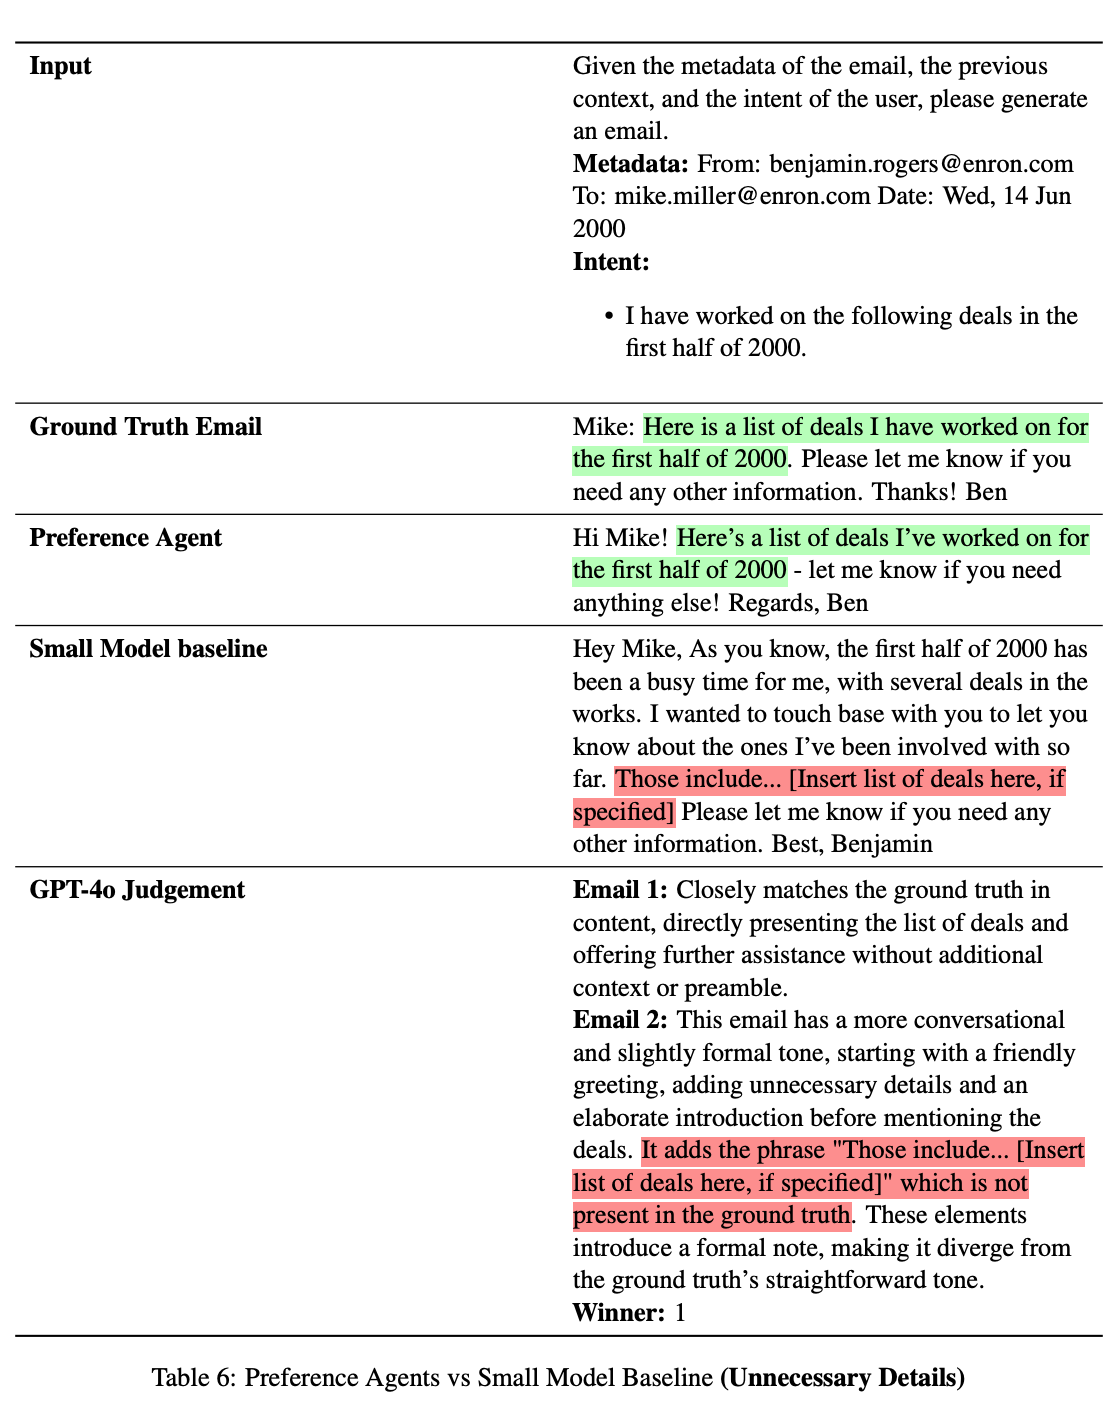
Unsupervised Human Preference Learning
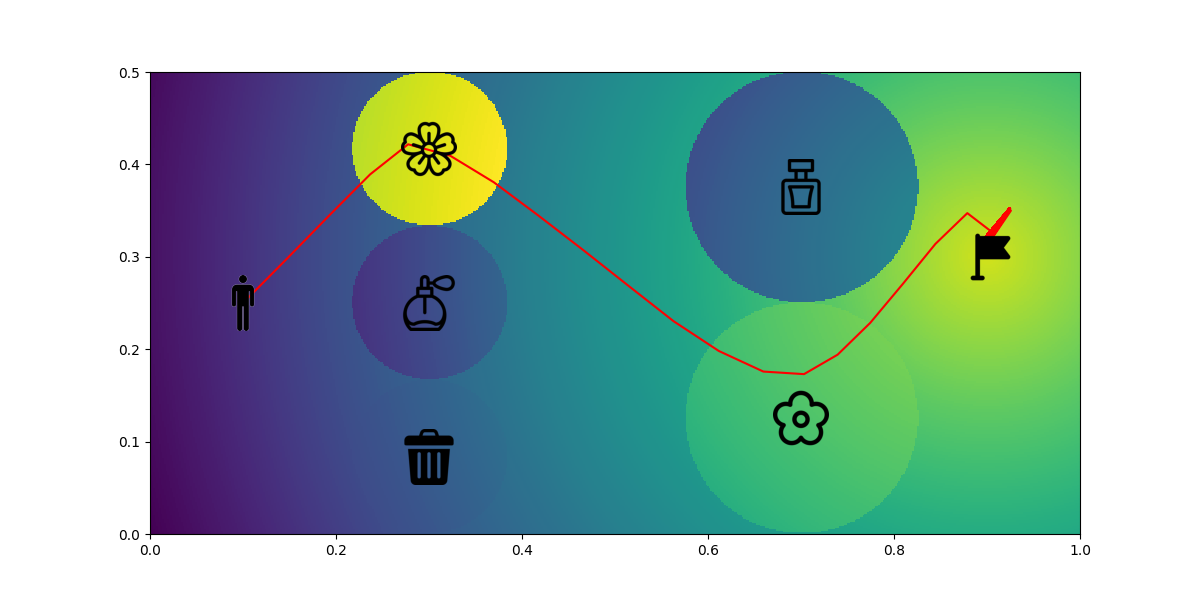
Planning & Prediction with Human Preference via Deep Inverse ...
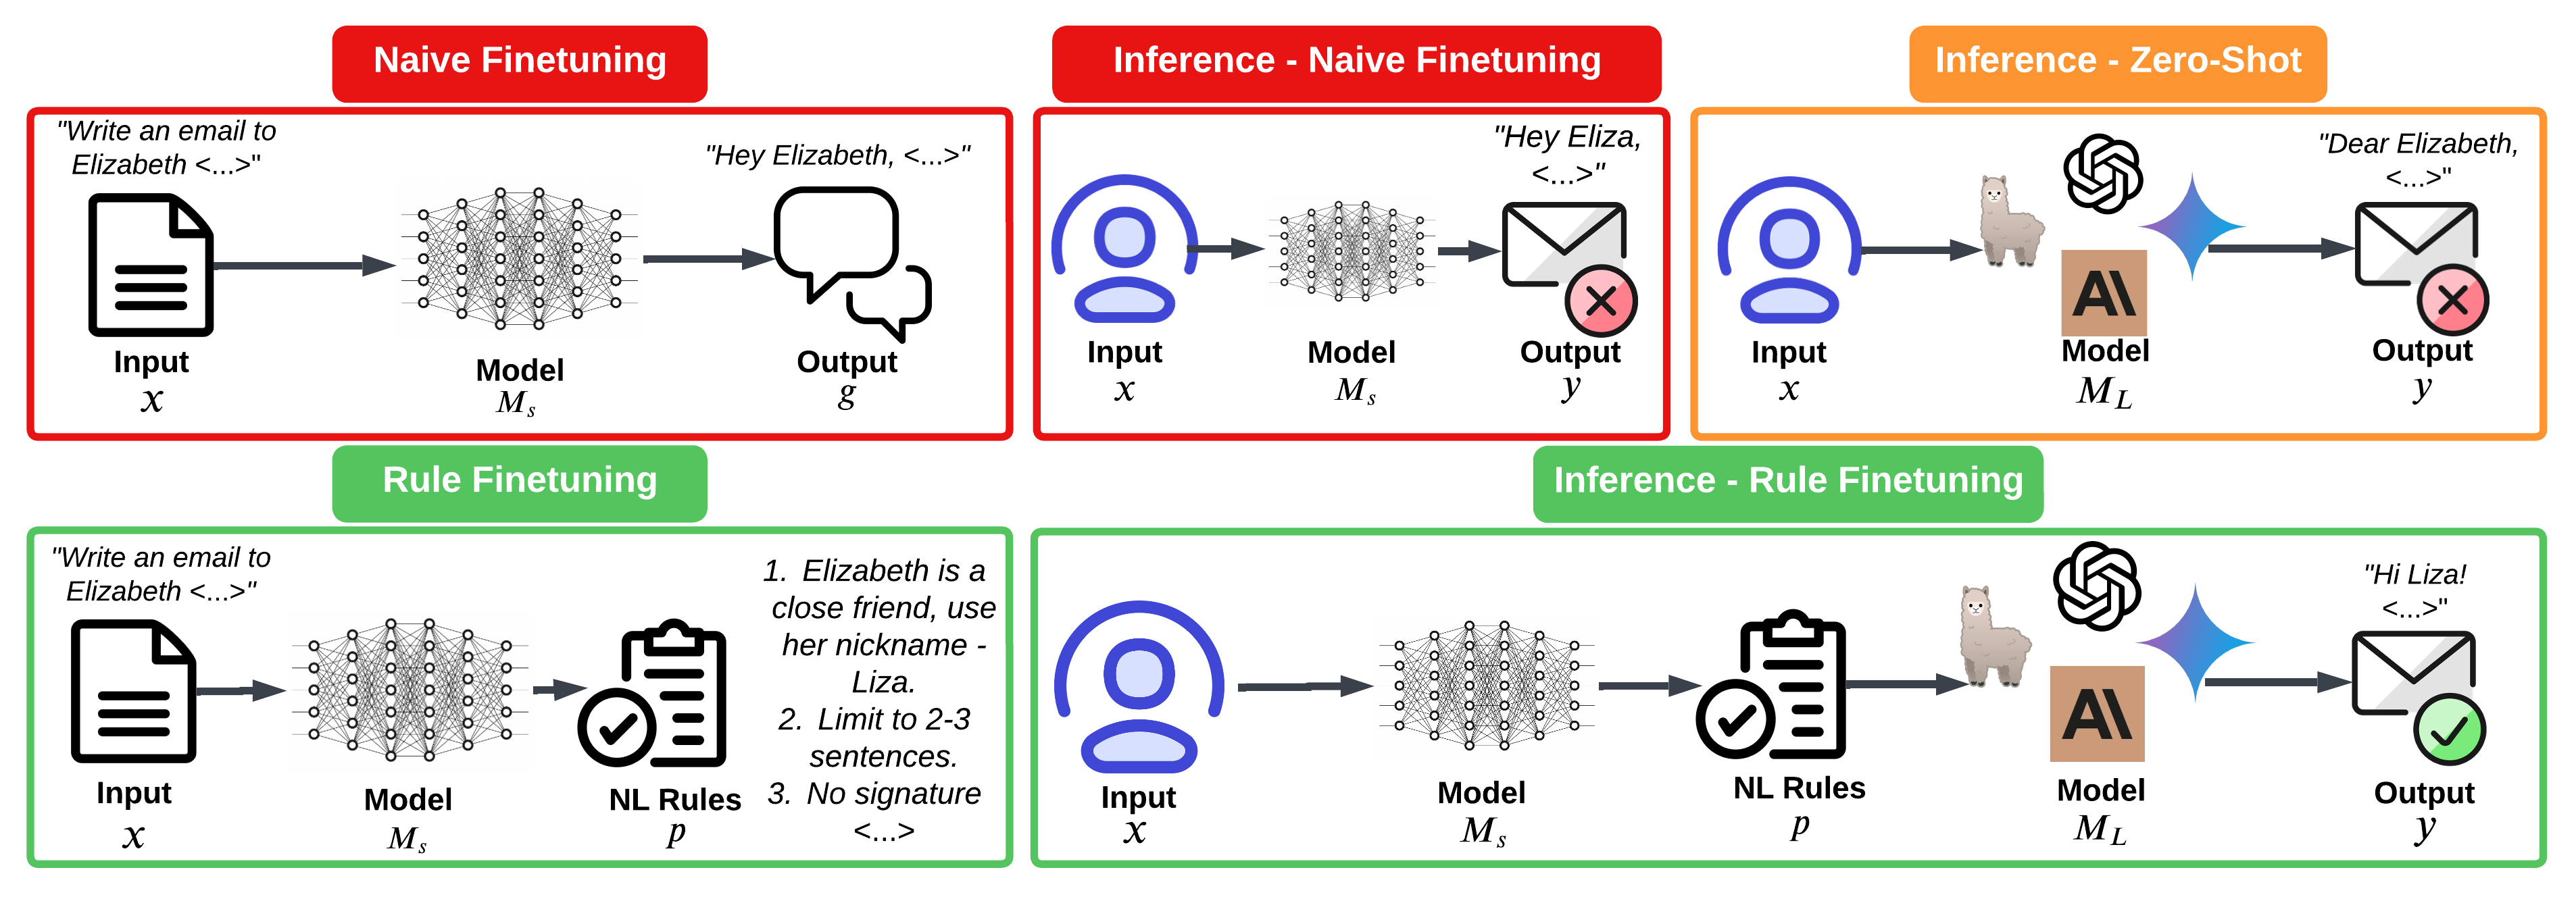
Unsupervised Human Preference Learning

A Study on Efficiency in Continual Learning Inspired by Human Learning
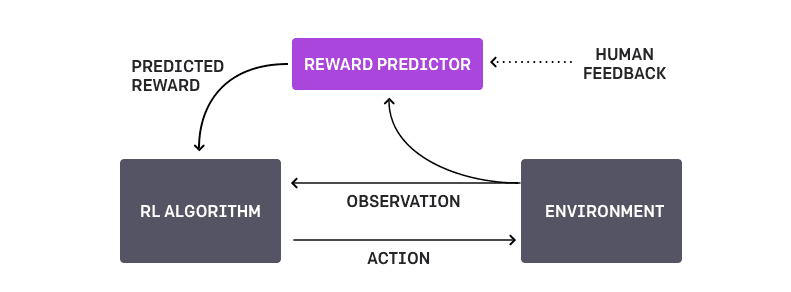
ChatGPT Series: Learning from Human Preferences - Sijun He's ...
Advertisement Space (336x280)
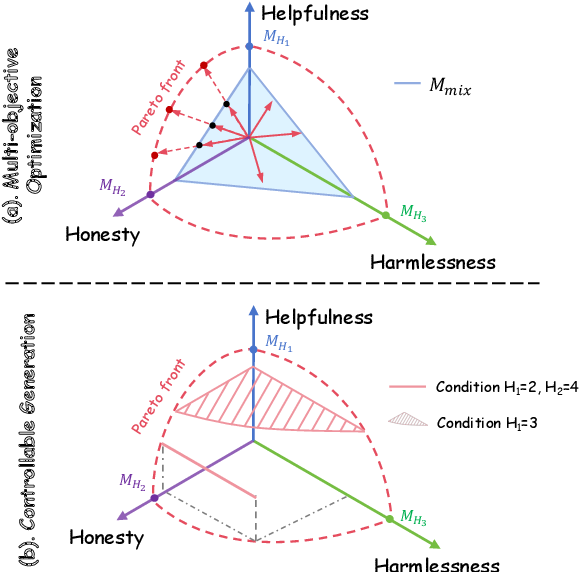
Figure 1 from Controllable Preference Optimization: Toward Controllable ...

Figure 1 from A General Theoretical Paradigm to Understand Learning ...

In learning from human preference, the learning agent presents two ...

Paper page - Models of human preference for learning reward functions

Table 1 from Continuous Hyper-parameter OPtimization (CHOP) in an ...
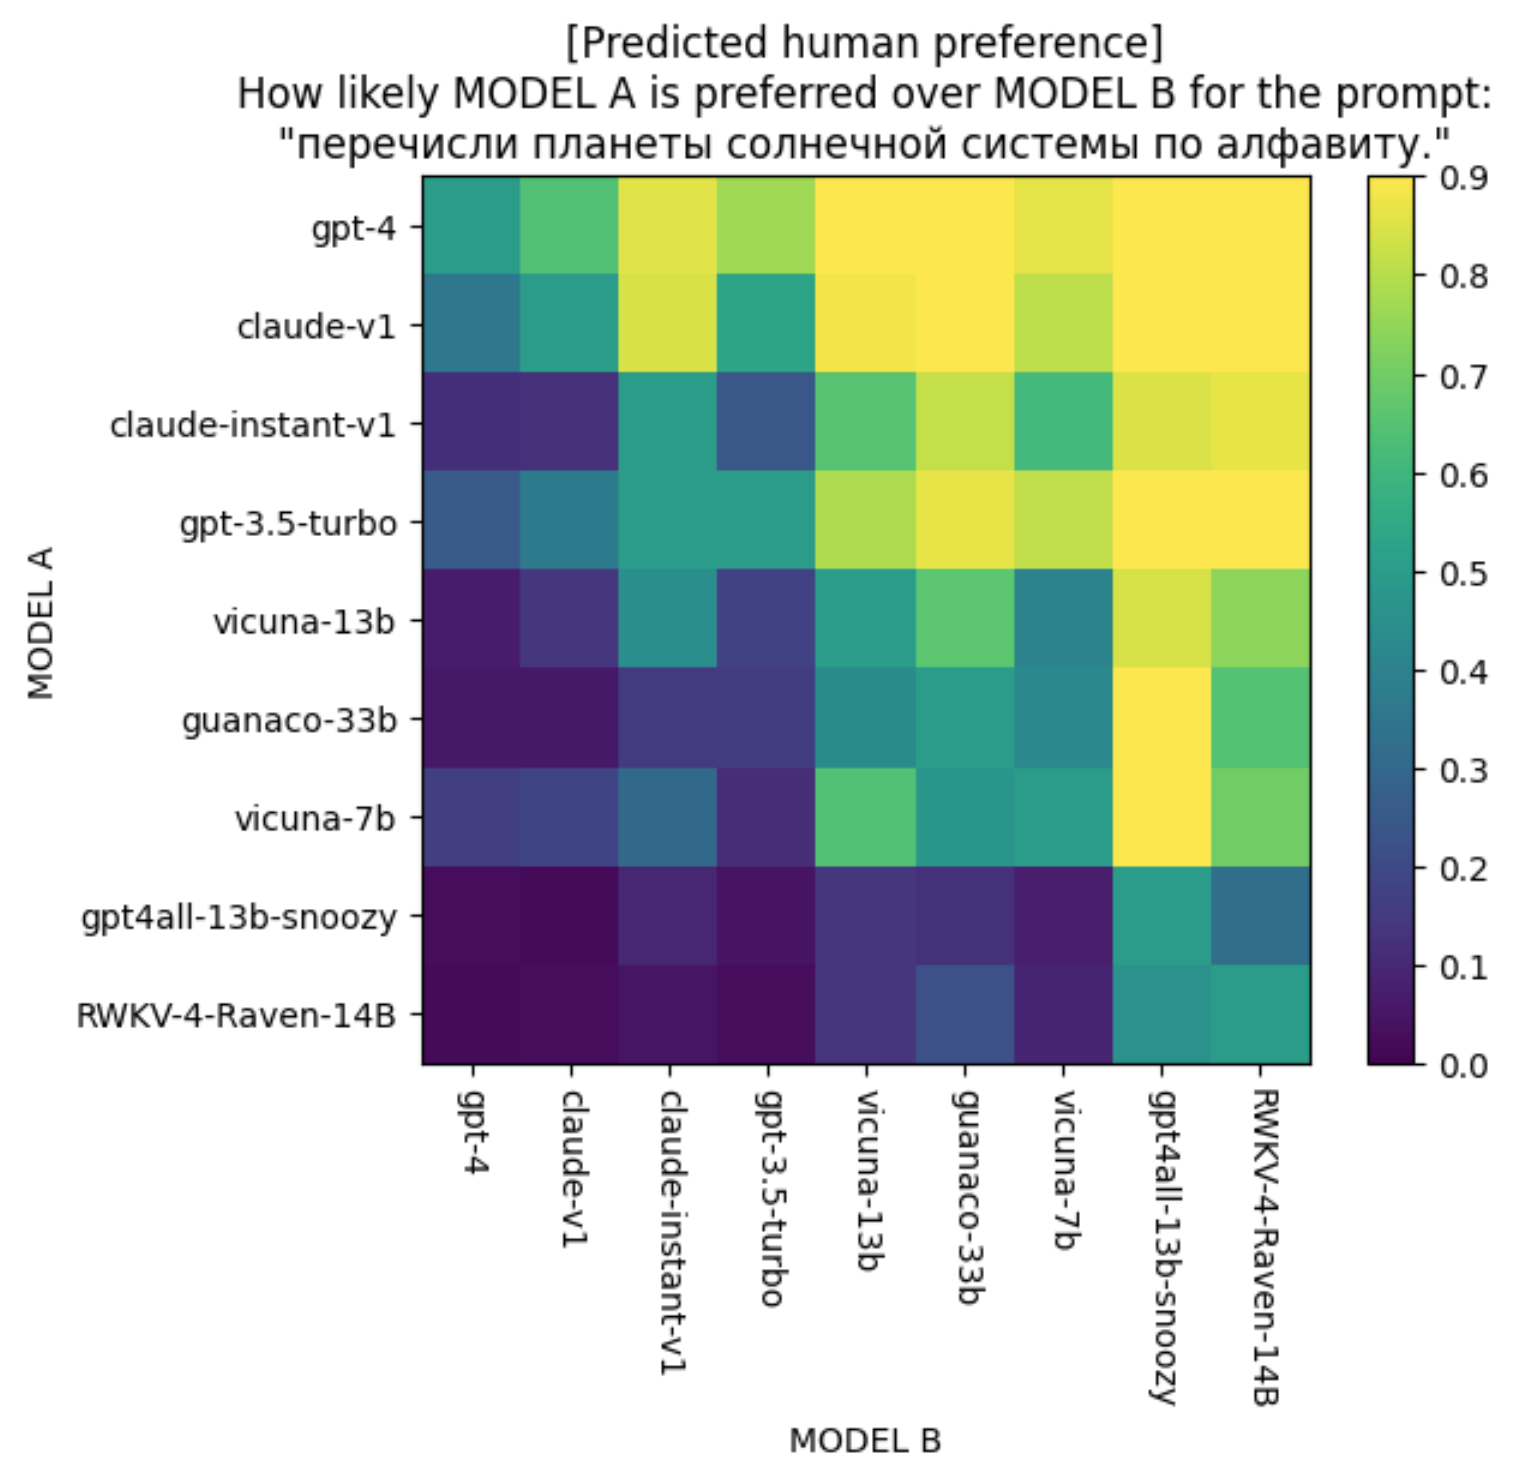
Predictive Human Preference: From Model Ranking to Model Routing