
Table 2 From Copr Continual Human Preference Learning Via Optimal

Table 2 from COPR: Continual Human Preference Learning via Optimal ...
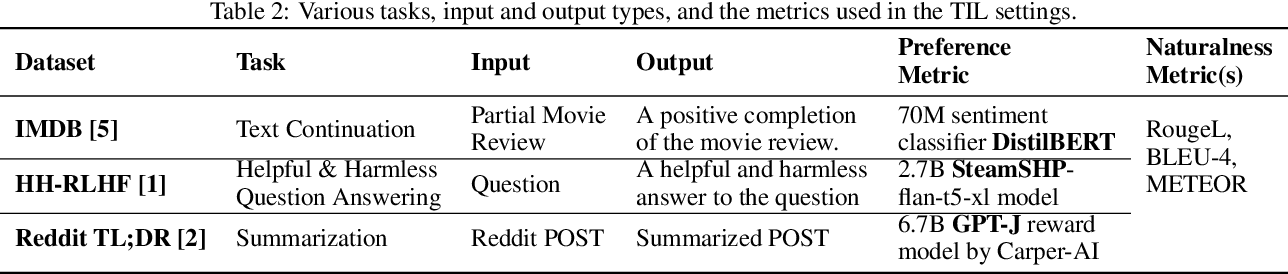
Table 2 from COPR: Continual Learning Human Preference through Optimal ...
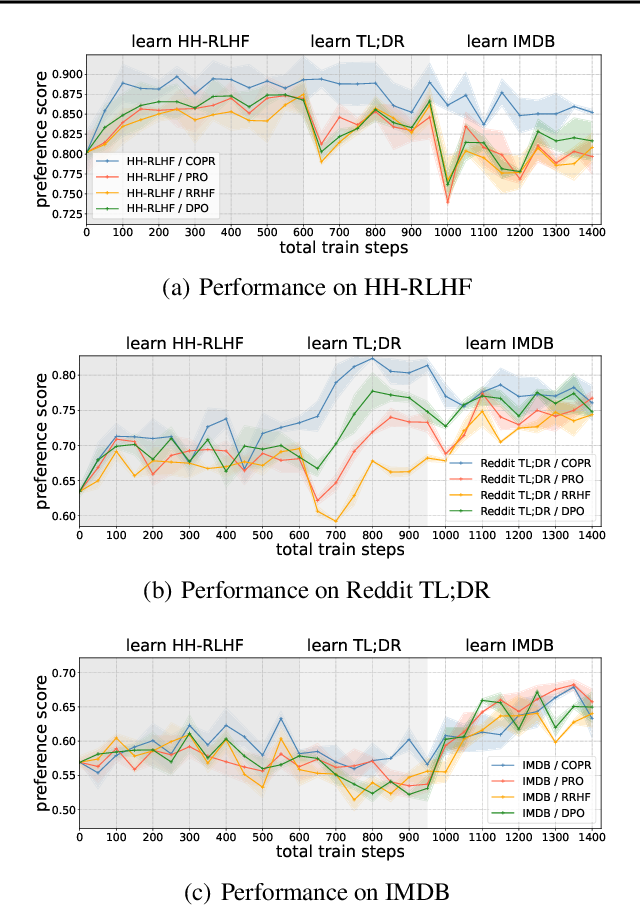
Figure 2 from COPR: Continual Human Preference Learning via Optimal ...
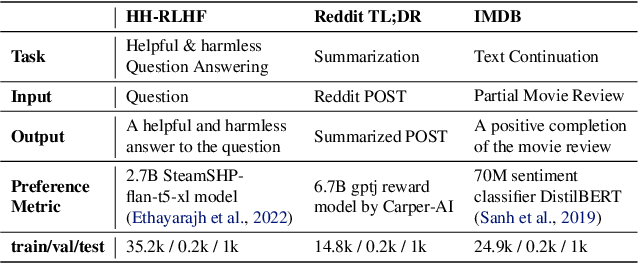
Table 1 from COPR: Continual Human Preference Learning via Optimal ...

Table 1 from COPF: Continual Learning Human Preference through Optimal ...
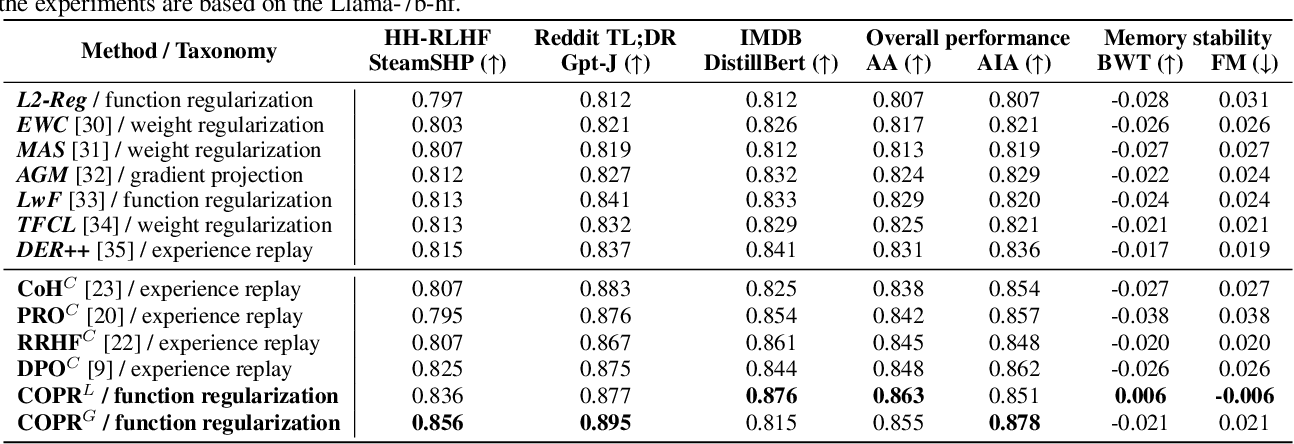
Table 3 from COPR: Continual Learning Human Preference through Optimal ...
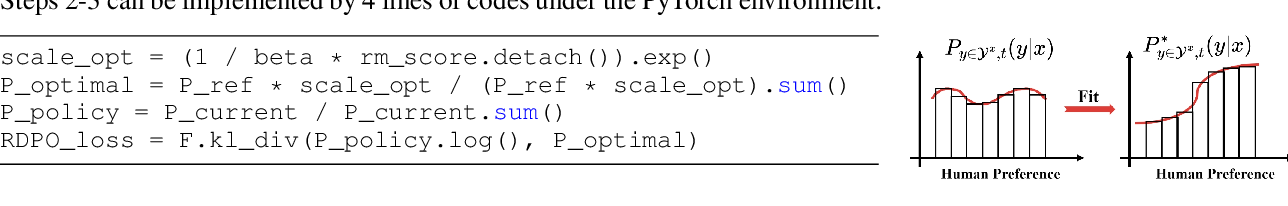
Figure 2 from COPR: Continual Learning Human Preference through Optimal ...
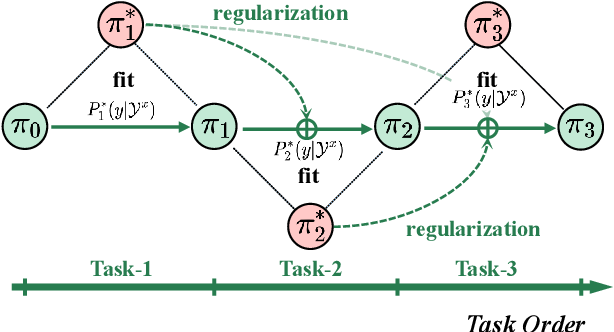
Figure 1 from COPR: Continual Human Preference Learning via Optimal ...

Table 2 from Models of human preference for learning reward functions ...
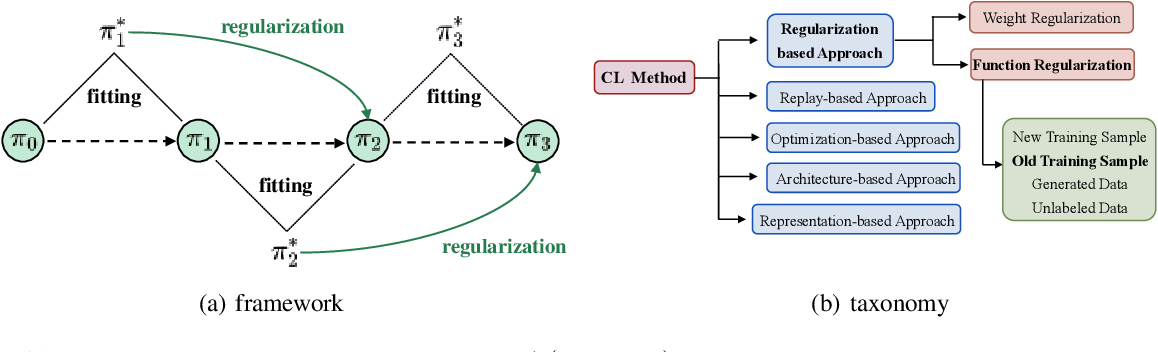
Figure 1 from COPR: Continual Learning Human Preference through Optimal ...
Advertisement Space (300x250)

Table 4 from Models of human preference for learning reward functions ...
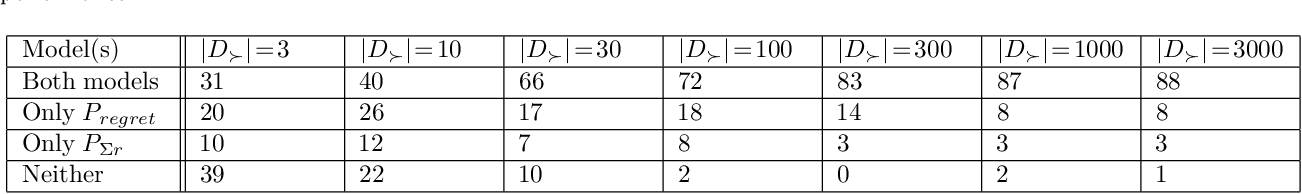
Table 5 from Models of human preference for learning reward functions ...

Figure 1 from Contrastive Preference Learning: Learning from Human ...

Optimal protocols for continual learning via statistical physics and ...

Figure 1 from A Survey on Human Preference Learning for Large Language ...
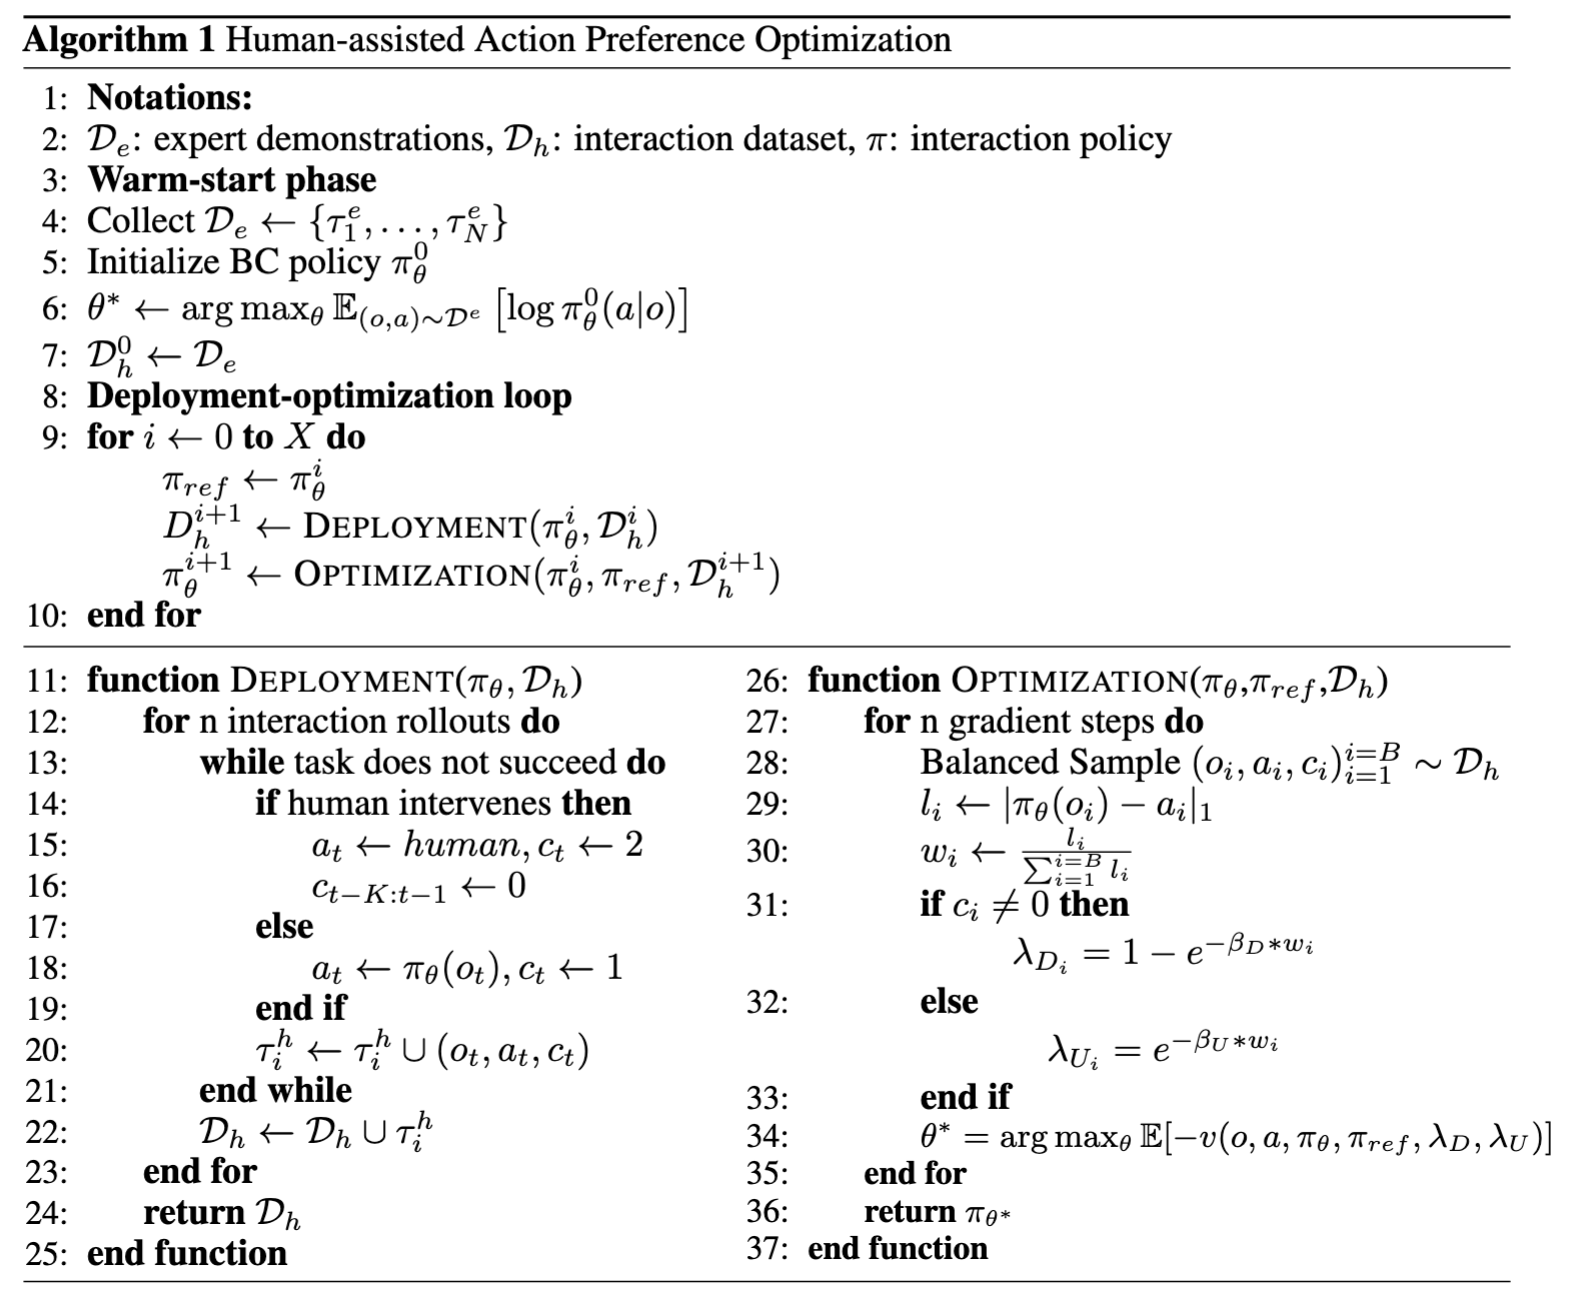
Robotic Policy Learning via Human-assisted Action Preference Optimization

[논문 리뷰] LRHP: Learning Representations for Human Preferences via ...
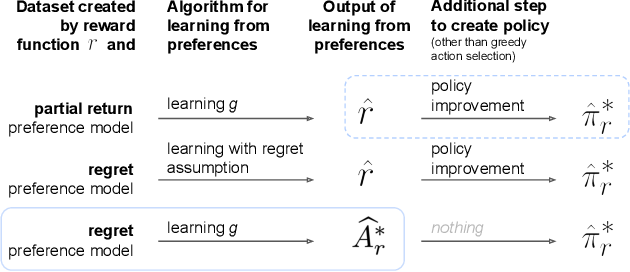
Figure 1 from Learning Optimal Advantage from Preferences and Mistaking ...

A Study on Efficiency in Continual Learning Inspired by Human Learning

Robotic Policy Learning via Human-assisted Action Preference Optimization
Advertisement Space (336x280)

A Survey on Human Preference Learning for Aligning Large Language ...
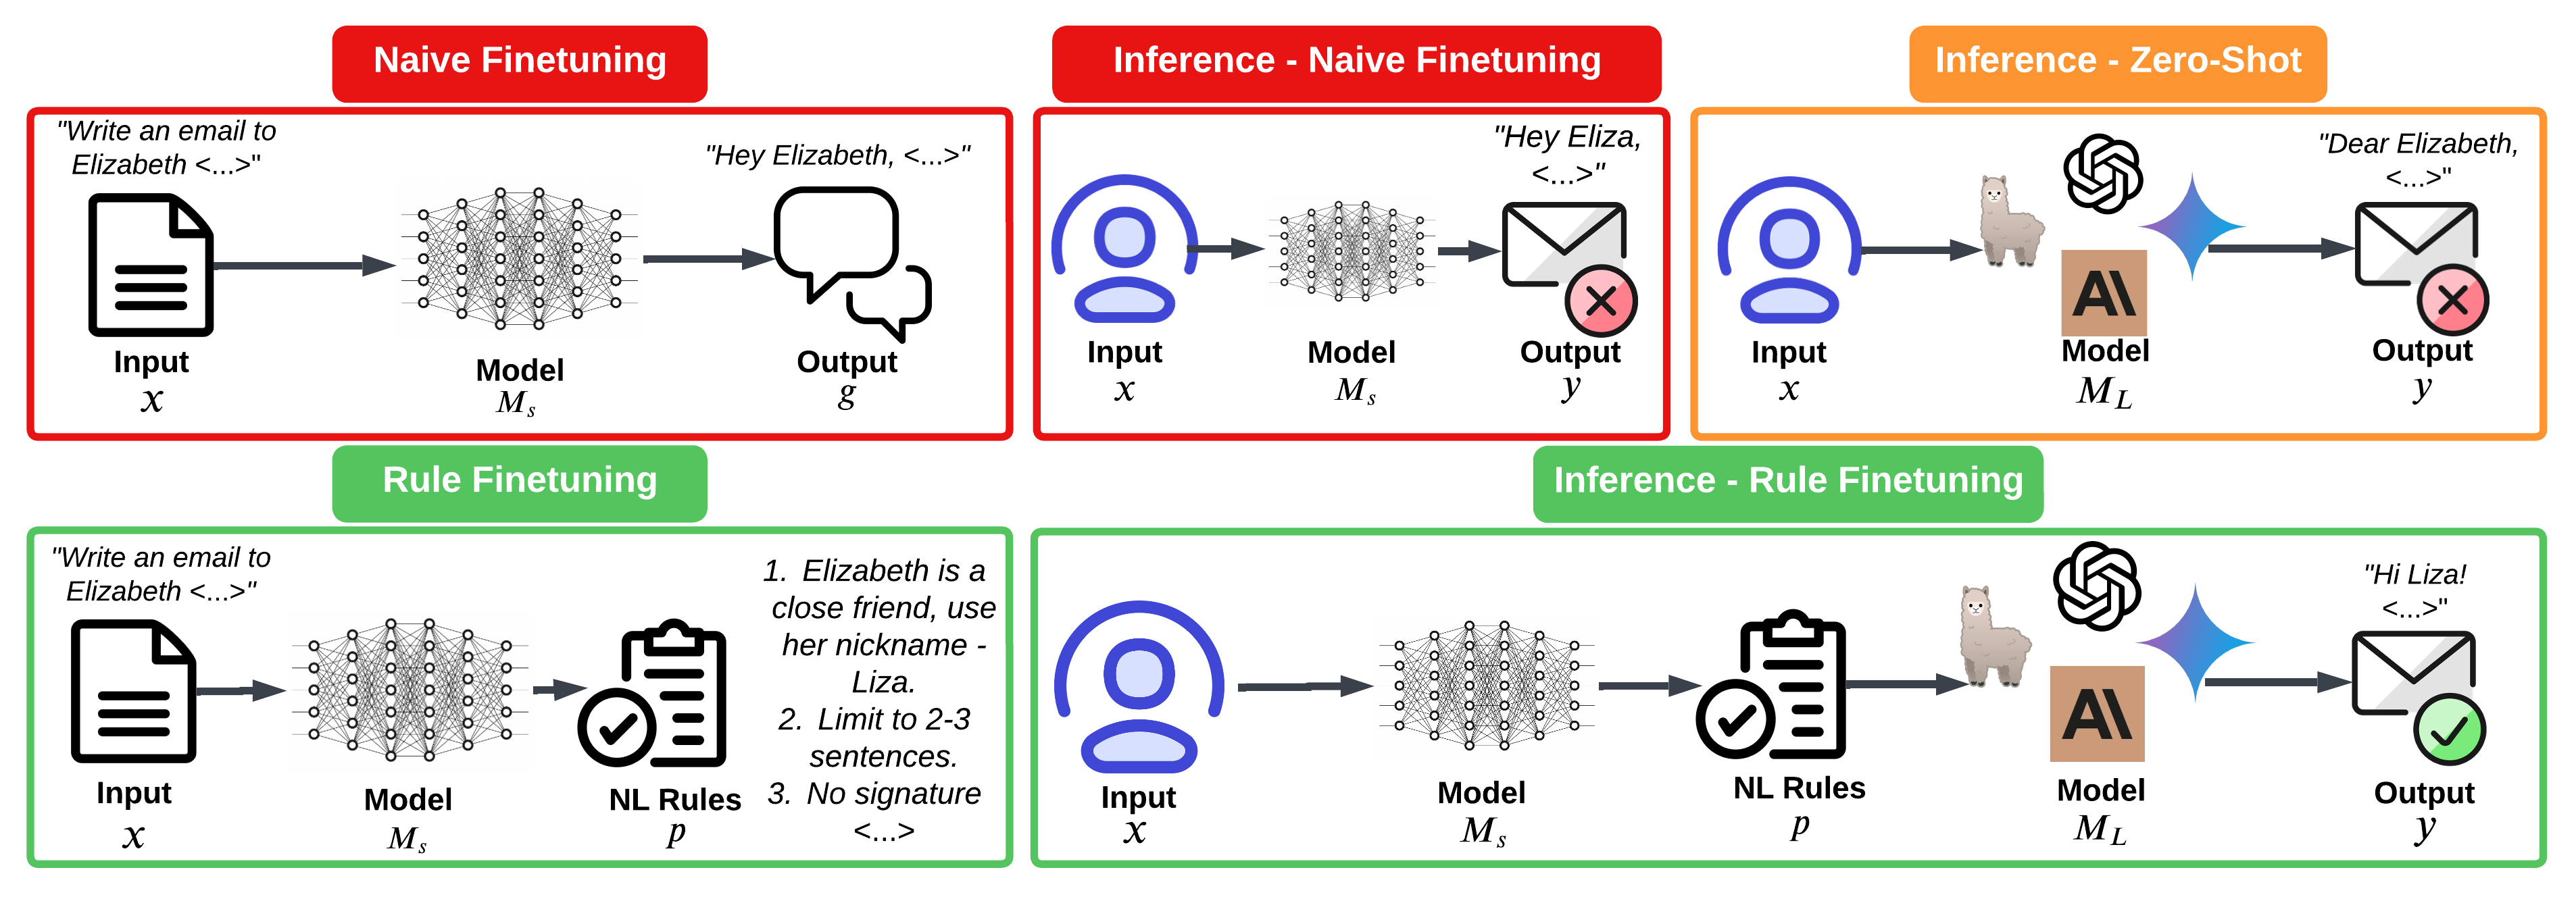
Unsupervised Human Preference Learning

Table 1 from Self-Supervised Primal-Dual Learning for Constrained ...
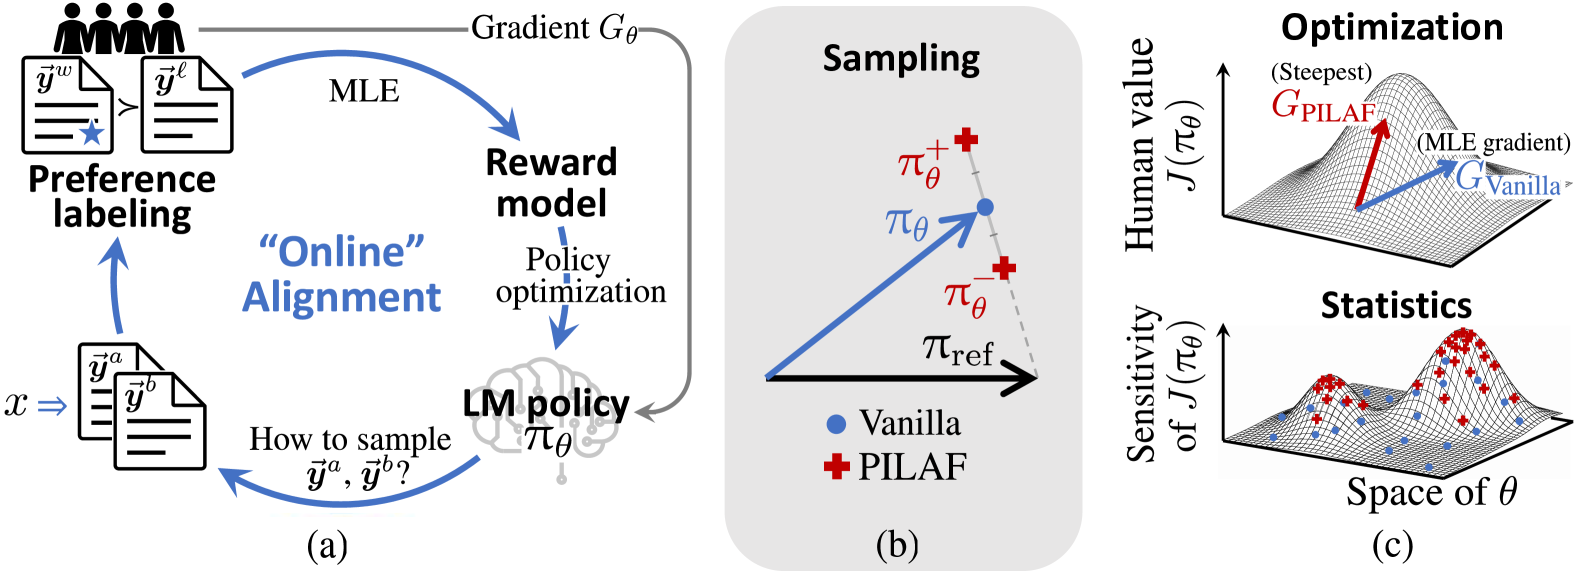
PILAF: Optimal Human Preference Sampling for Reward Modeling · HF Daily ...
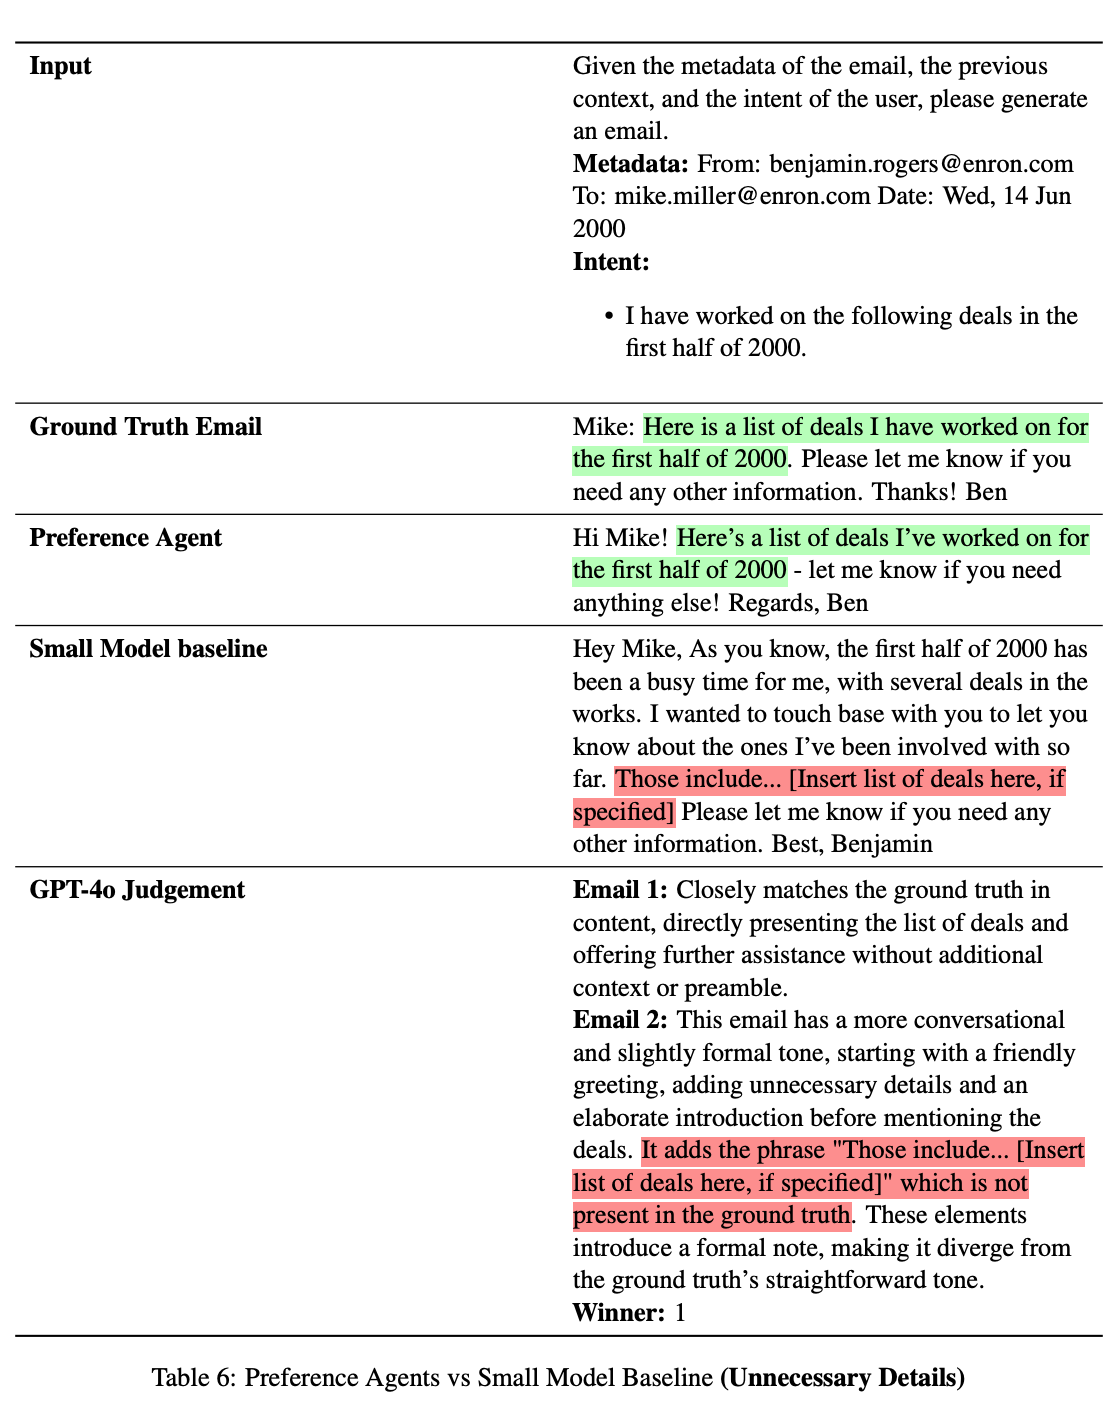
Unsupervised Human Preference Learning

PILAF: Optimal Human Preference Sampling for Reward Modeling · HF Daily ...

[论文评述] Ordinal Preference Optimization: Aligning Human Preferences via NDCG
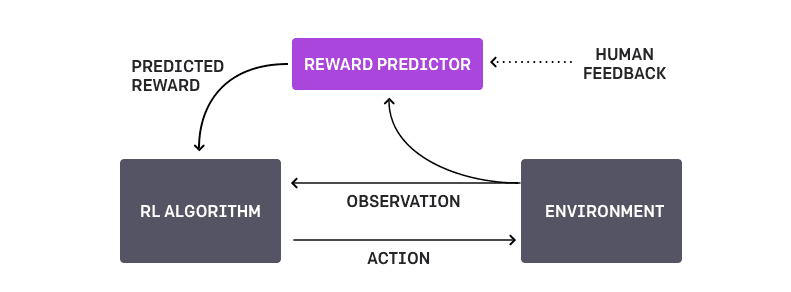
ChatGPT Series: Learning from Human Preferences - Sijun He's ...

Table 1 from Can LLMs Capture Human Preferences? | Semantic Scholar

[논문 리뷰] Personalizing Reinforcement Learning from Human Feedback with ...
Advertisement Space (336x280)
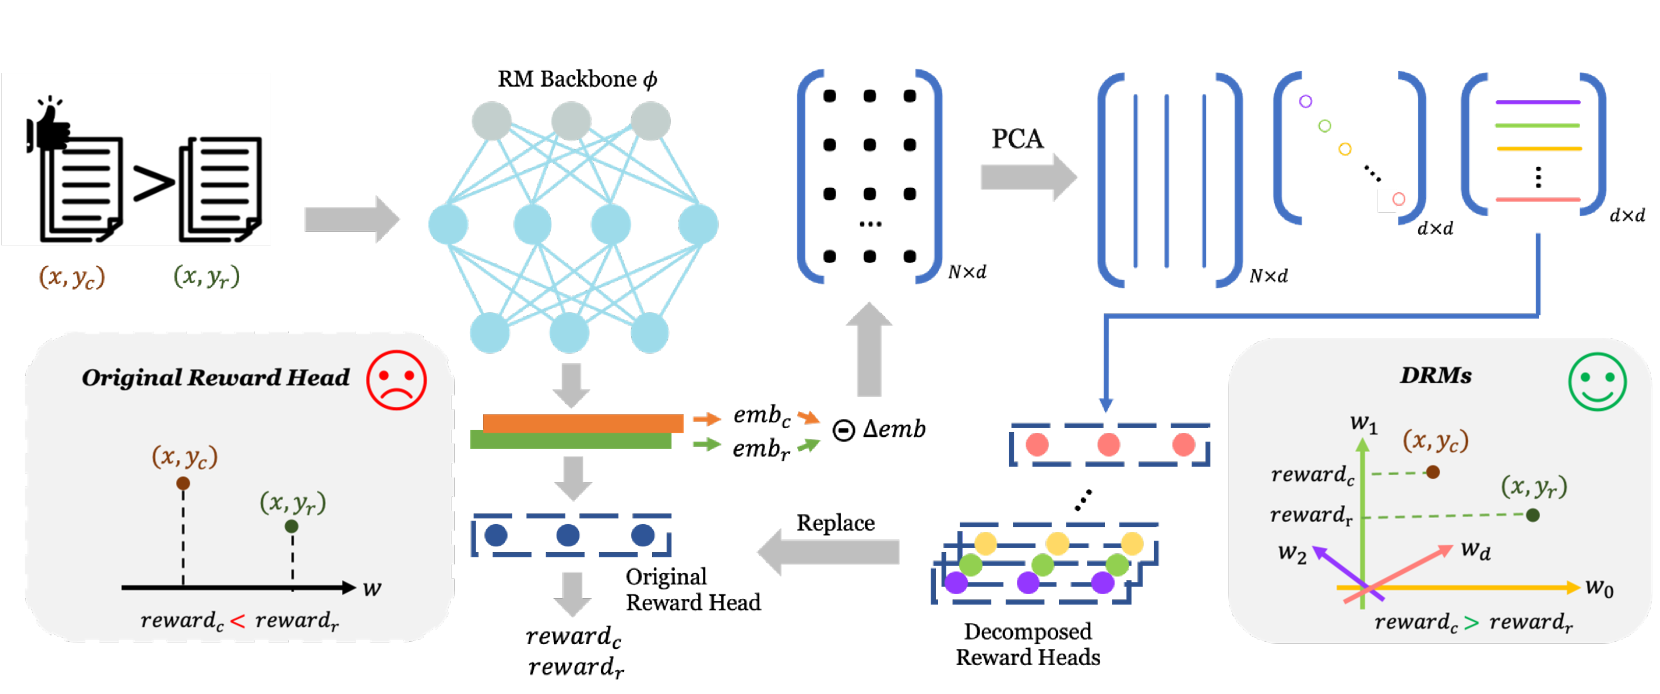
Rethinking Diverse Human Preference Learning through Principal ...

In learning from human preference, the learning agent presents two ...

Paper page - Models of human preference for learning reward functions
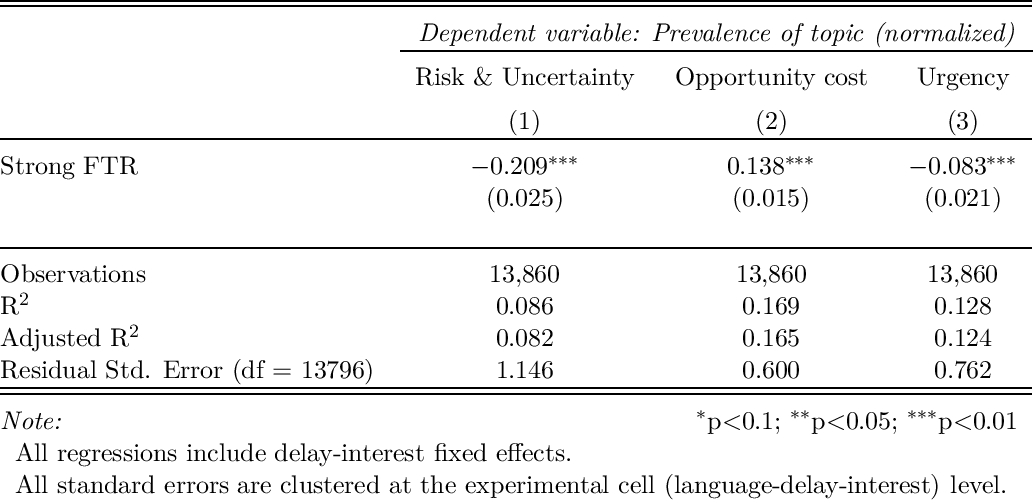
Table 1 from Can LLMs Capture Human Preferences? | Semantic Scholar
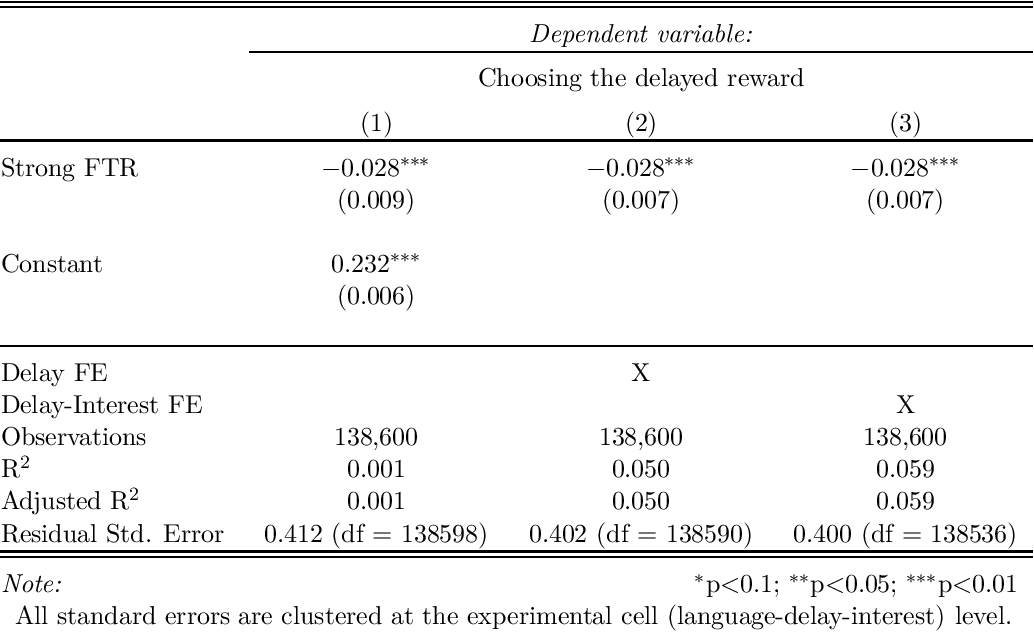
Table 1 from Can LLMs Capture Human Preferences? | Semantic Scholar

Deep Learning From Human Preferences | Two Minute Papers #196 - YouTube