
Table 1 From Xmodel Vlm A Simple Baseline For Multimodal Vision

Table 1 from Xmodel-VLM: A Simple Baseline for Multimodal Vision ...

Table 1 from OpenUni: A Simple Baseline for Unified Multimodal ...

Xmodel-VLM: A Simple Baseline for Multimodal Vision Language Model | AI ...
Xmodel-VLM: A Simple Baseline for Multimodal Vision Language Model ...

Xmodel-VLM: A Simple Baseline for Multimodal Vision Language Model ...

Xmodel-VLM: A Simple Baseline for Multimodal Vision Language Model | AI ...

Xmodel-VLM: A Simple Baseline for Multimodal Vision Language Model - 智源社区论文
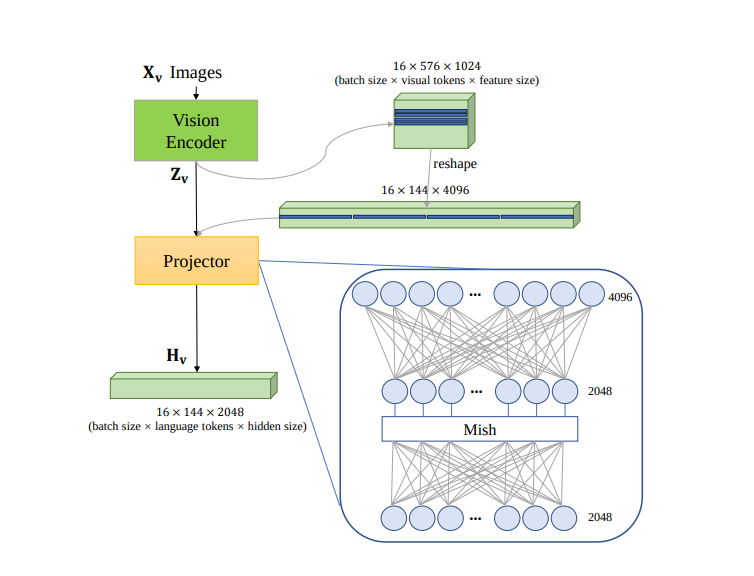
Santosh Sawant - Xmodel-VLM: A Simple Baseline for Multimodal Vision ...

Paper page - Xmodel-VLM: A Simple Baseline for Multimodal Vision ...
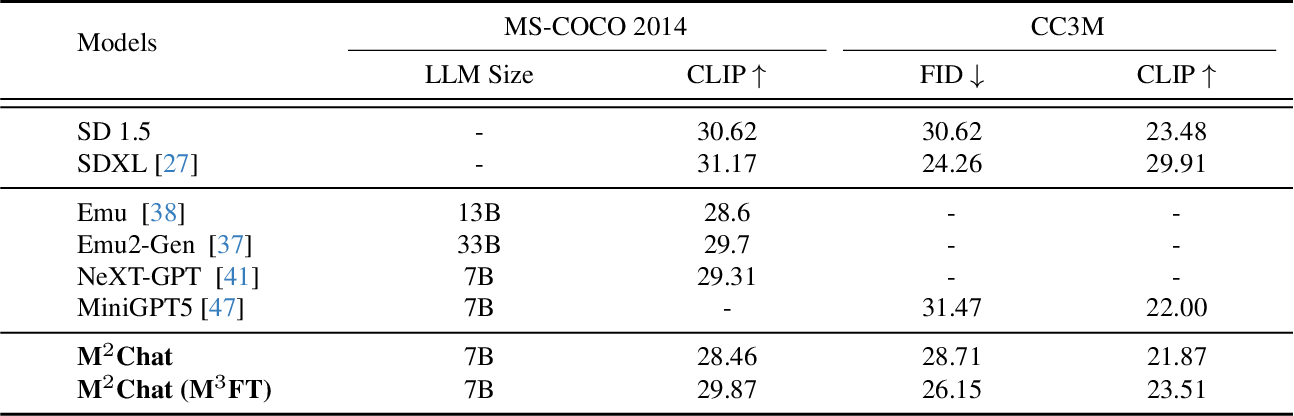
Table 1 from M$^{2}$Chat: Empowering VLM for Multimodal LLM Interleaved ...
Advertisement Space (300x250)

Figure 2 from A Simple Aerial Detection Baseline of Multimodal Language ...
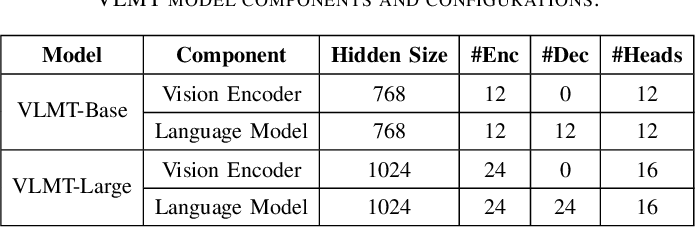
Table I from VLMT: Vision-Language Multimodal Transformer for ...
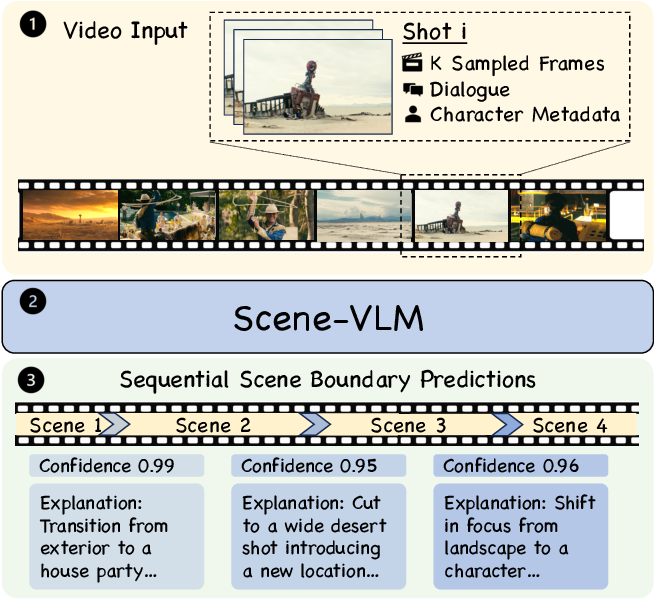
Figure 1 from Scene-VLM: Multimodal Video Scene Segmentation via Vision ...

A Simple Aerial Detection Baseline of Multimodal Language Models
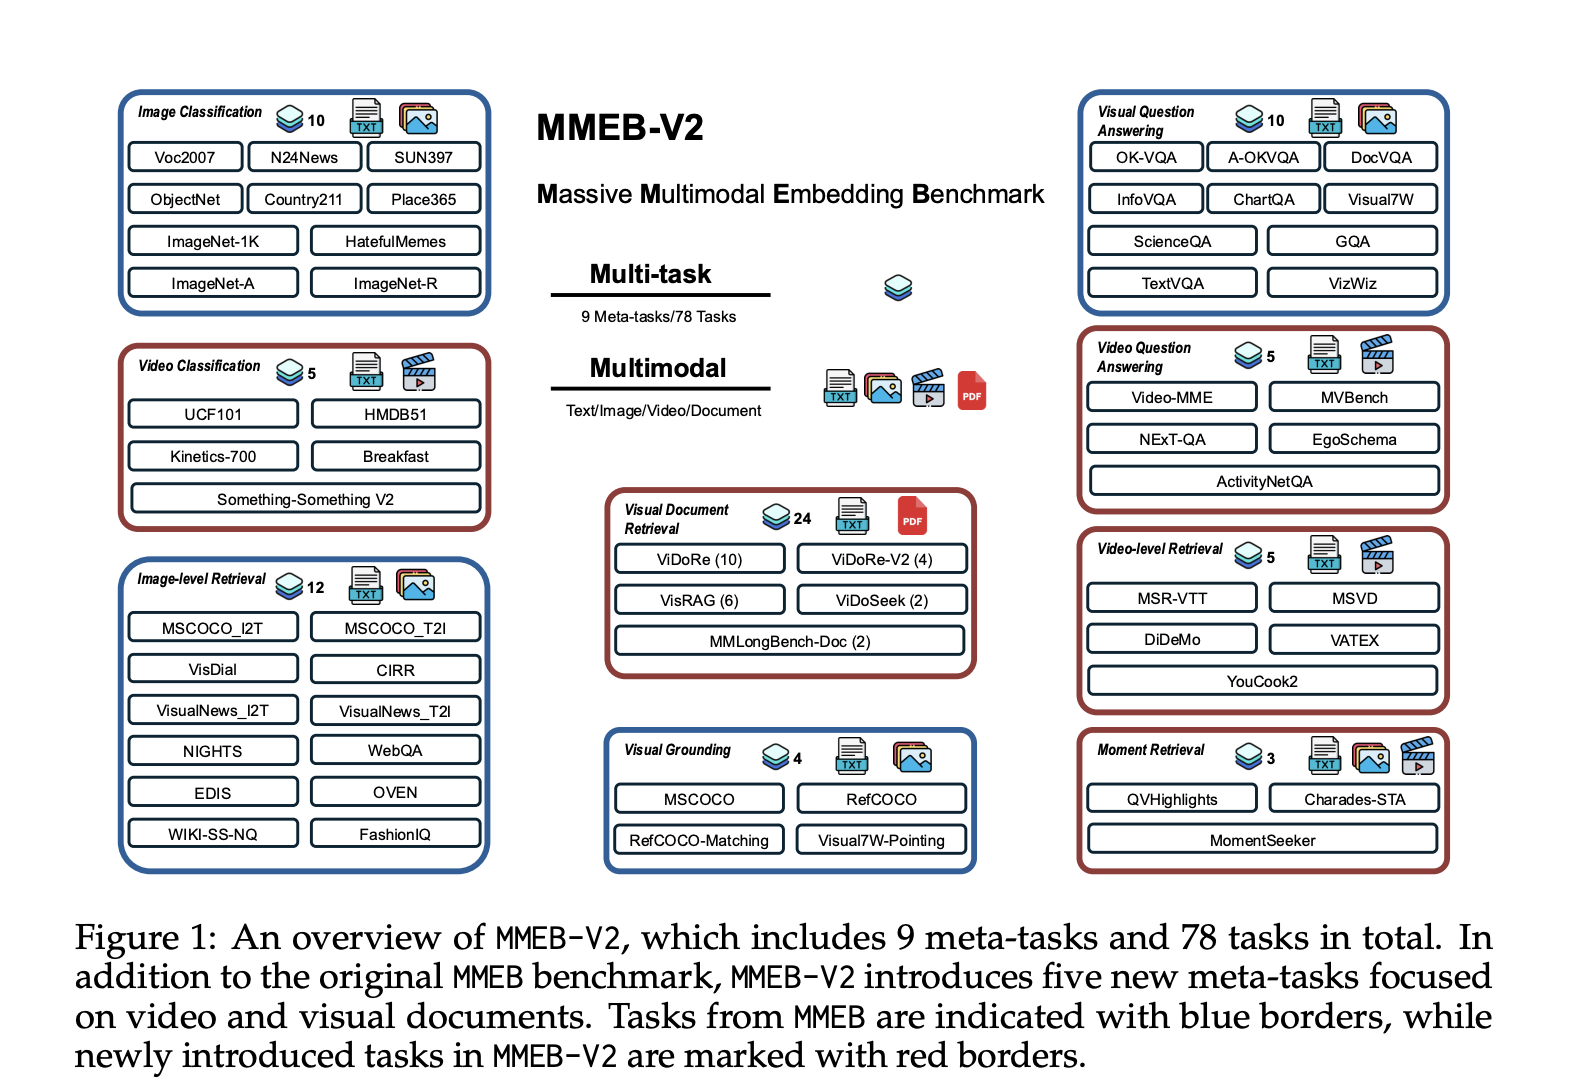
VLM2Vec-V2: A Unified Computer Vision Framework for Multimodal ...
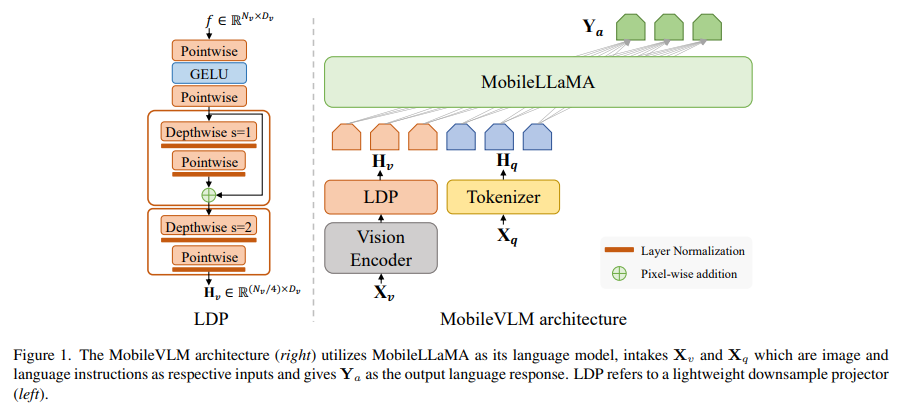
Meet MobileVLM: A Competent Multimodal Vision Language Model (MMVLM ...

This AI Paper Introduces VLM-R³: A Multimodal Framework for Region ...

This Article AI Presents VLM-R³: A Multimodal Framework For The ...

Table 1 from Xmodel-LM Technical Report | Semantic Scholar

Training a Vision Language Model from scratch (VLM multi-modal) | by ...
Advertisement Space (336x280)
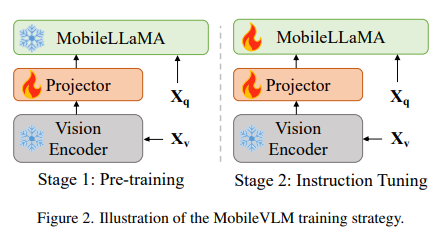
Meet MobileVLM: A Competent Multimodal Vision Language Model (MMVLM ...

Building a Simple VLM-Based Multimodal Information Retrieval System ...

Table 1 from Reformulating Vision-Language Foundation Models and ...

Meet MobileVLM: A Competent Multimodal Vision Language Model (MMVLM ...

Paper page - MobileVLM V2: Faster and Stronger Baseline for Vision ...
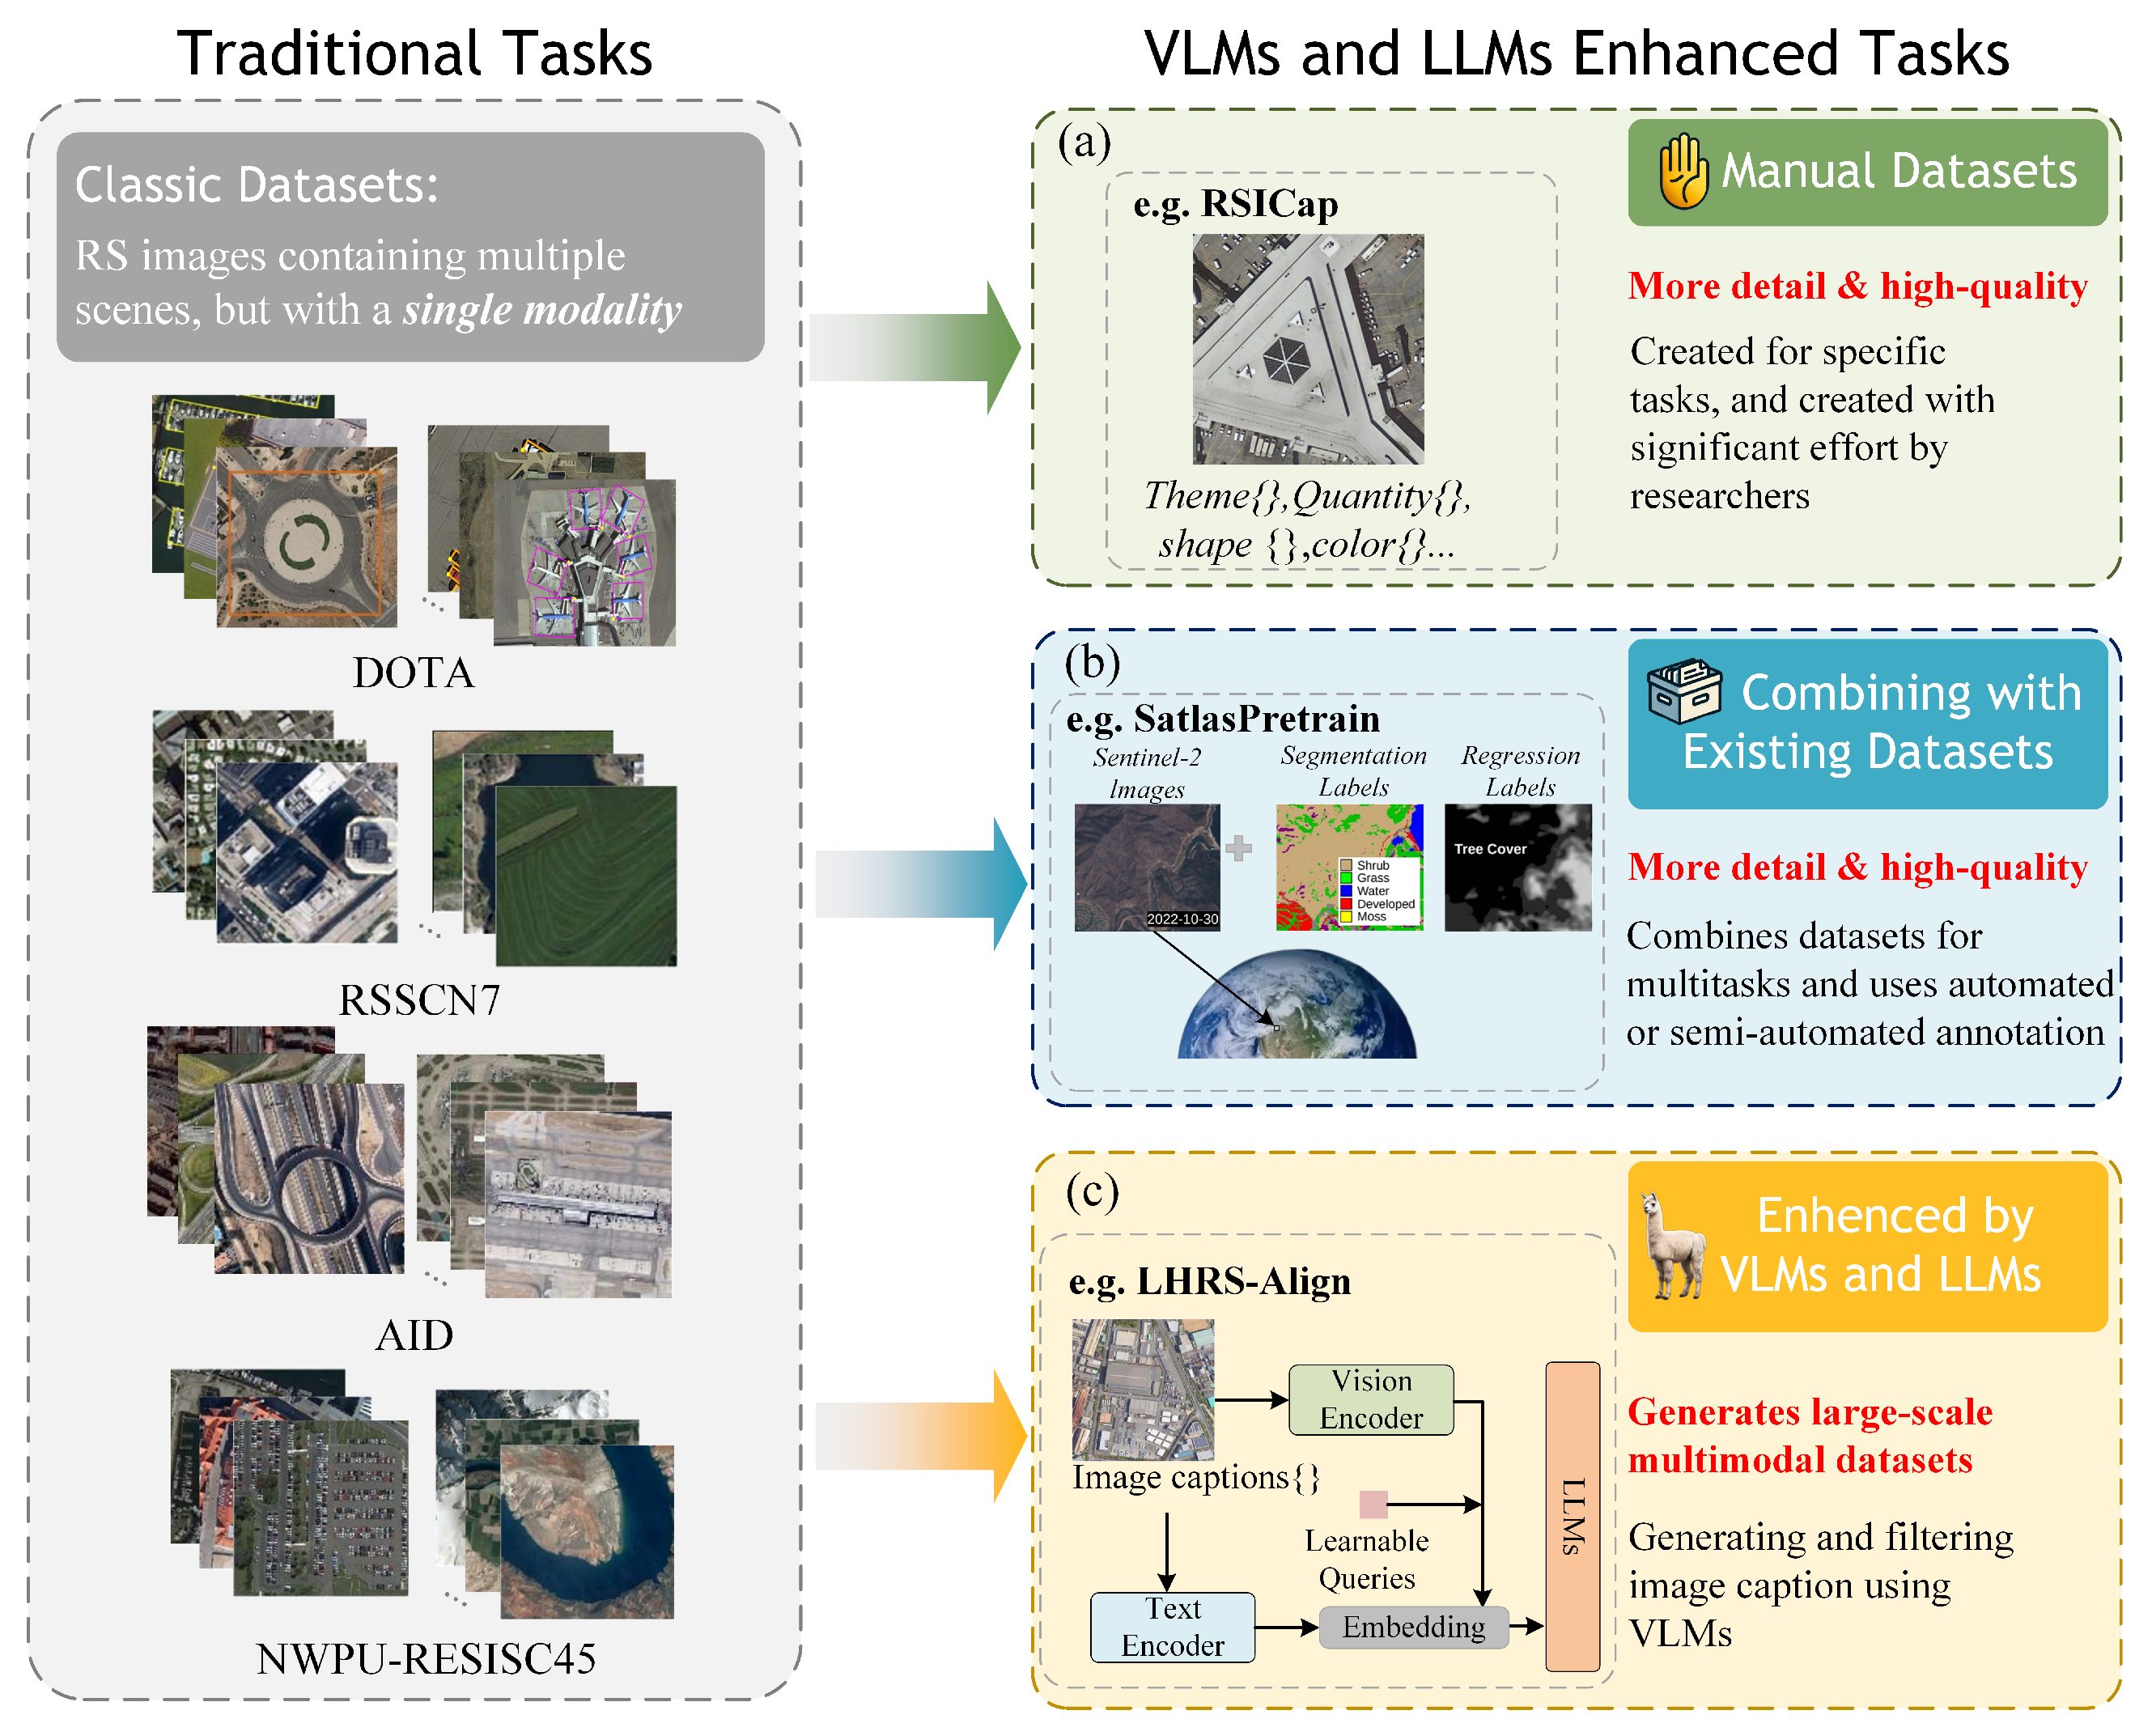
Vision–Language Models for Remote Sensing: A New Era of Multimodal ...

Figure 2 from Time-VLM: Exploring Multimodal Vision-Language Models for ...

【论文笔记】VCoder: Versatile Vision Encoders for Multimodal Large Language ...
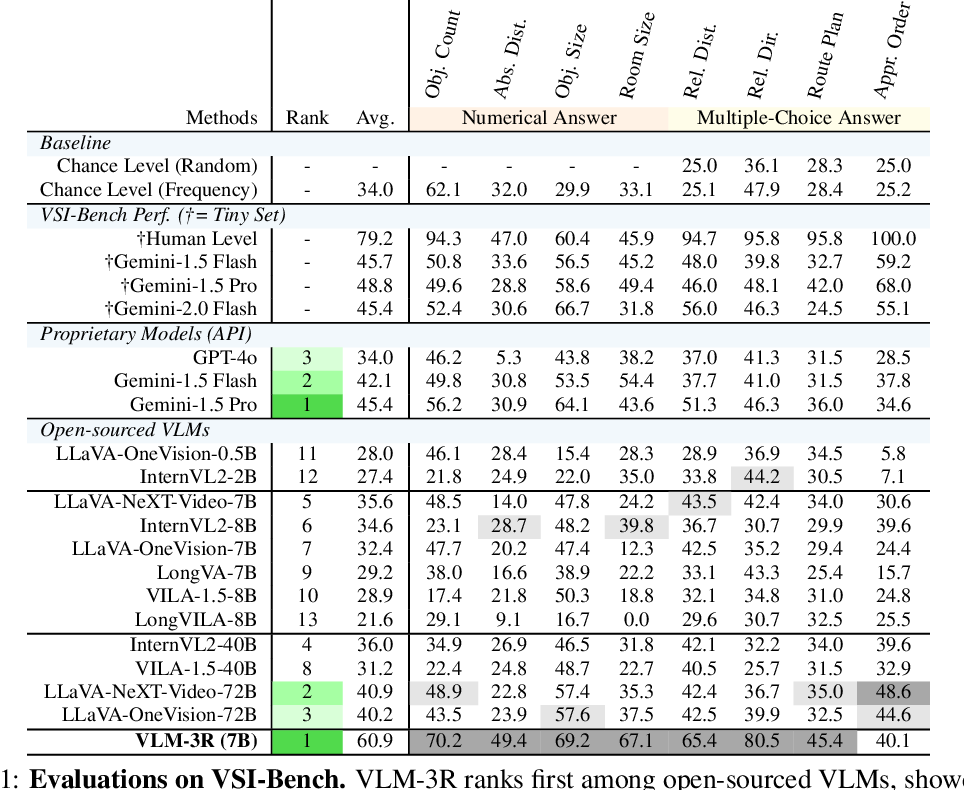
Table 1 from VLM-3R: Vision-Language Models Augmented with Instruction ...

Open-Source Vision Language Models (VLMs) in Multimodal AI
Advertisement Space (336x280)

(PDF) Vision Language Model-driven Multimodal Occlusion Analysis (VLM ...

[논문 리뷰] Time-VLM: Exploring Multimodal Vision-Language Models for ...
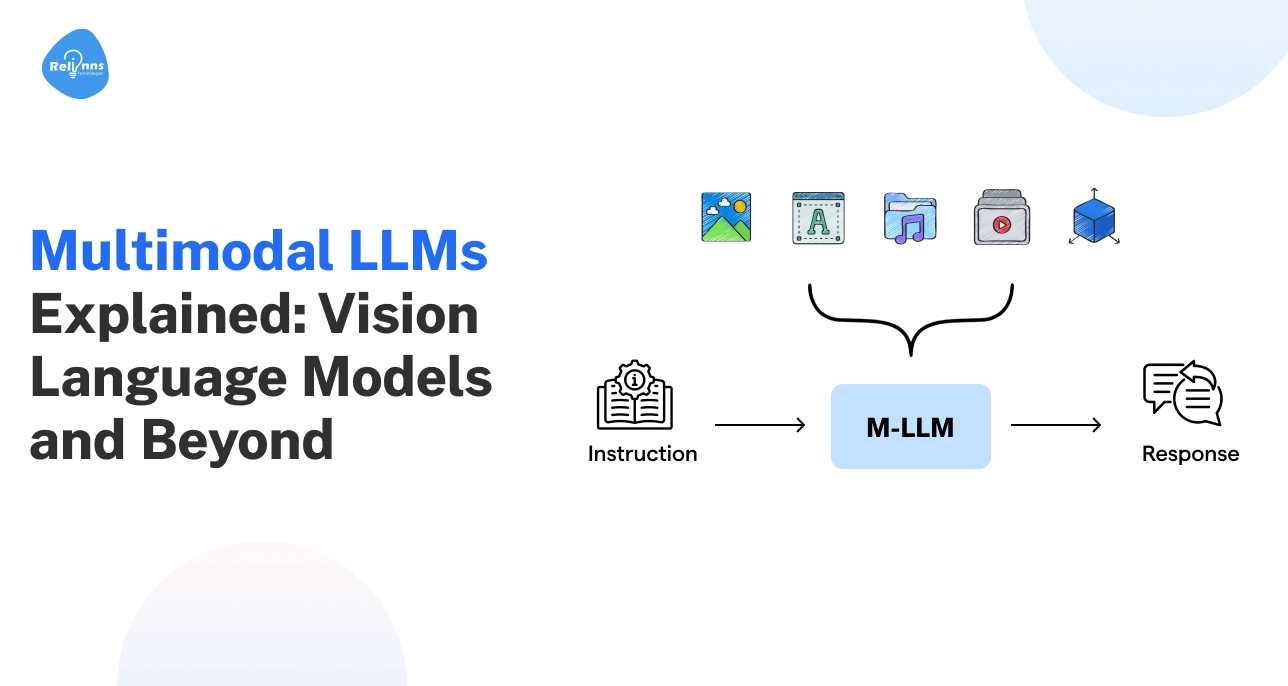
Multimodal LLMs Explained: Vision Language Models and Beyond

[VLM] Vision Language Models 1

Time-VLM:Exploring Multimodal Vision-Language Models for Augmented Time ...
Demystifying Vision Language Models (VLMs): The Core of Multimodal AI