
Tensorrt Llm Backend Nvidia Triton Inference Server
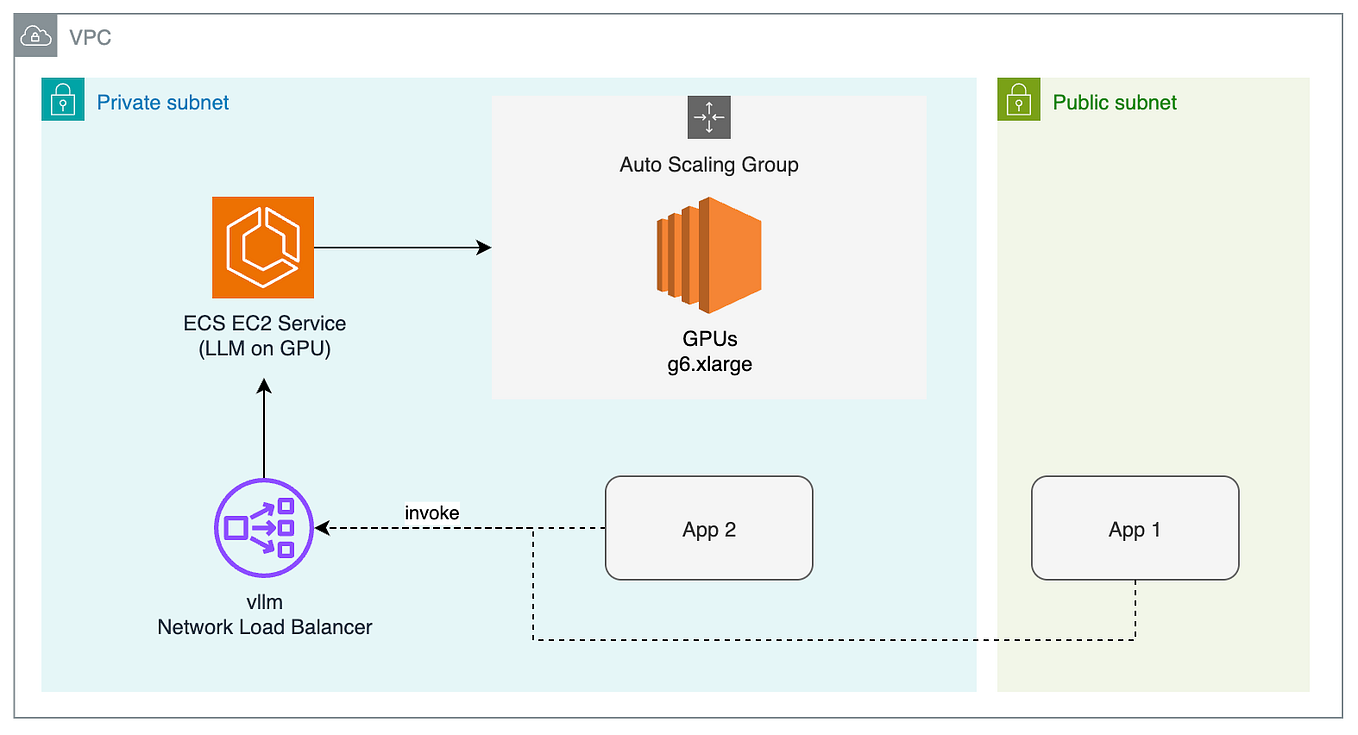
LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...

LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...
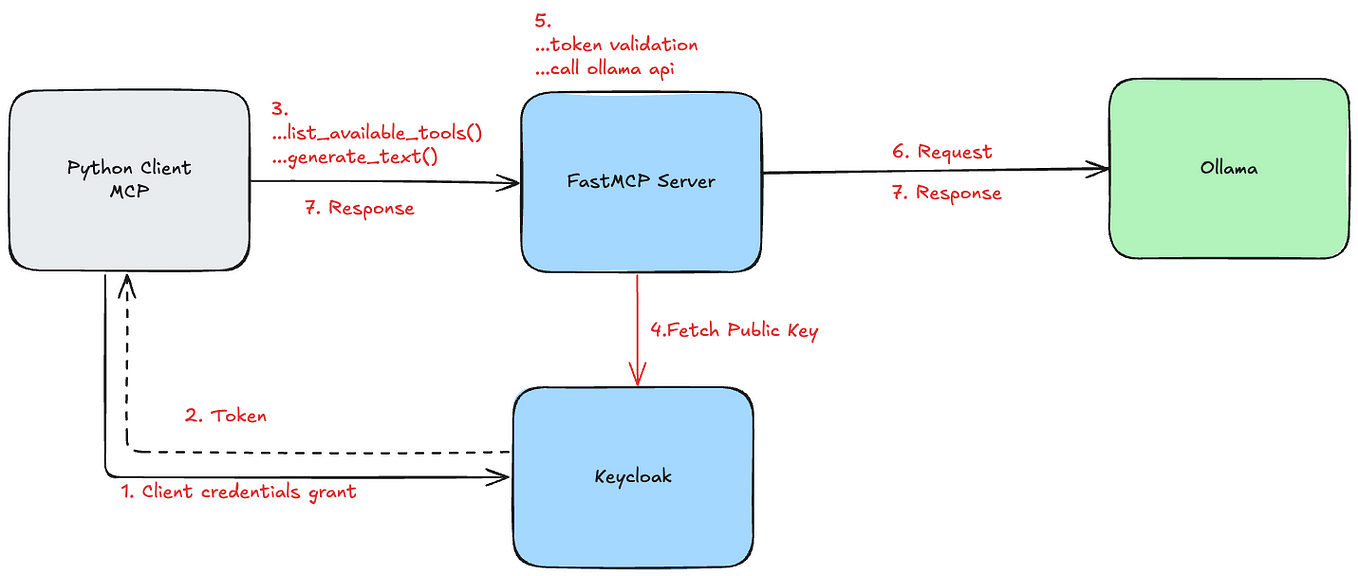
LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...

LLM Deployment: A Guide to NVIDIA Triton Inference Server and TensorRT ...

TensorRT-LLM Backend — NVIDIA Triton Inference Server

TensorRT-LLM Backend — NVIDIA Triton Inference Server

Triton Inference Server + vLLM Backend on the NVIDIA Jetson AGX Orin ...

Triton Inference Server - TensorRT - NVIDIA Developer Forums
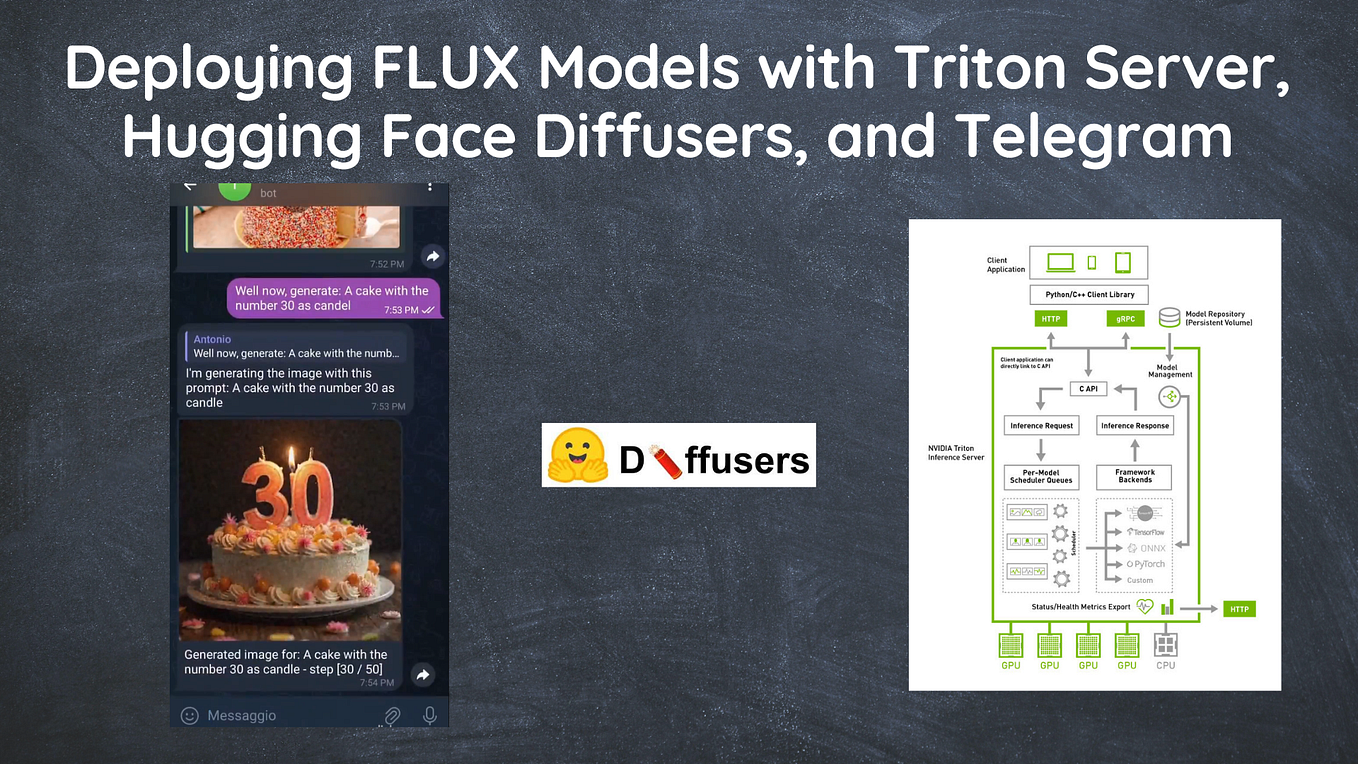
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...

DALI TRITON Backend — NVIDIA Triton Inference Server
Advertisement Space (300x250)
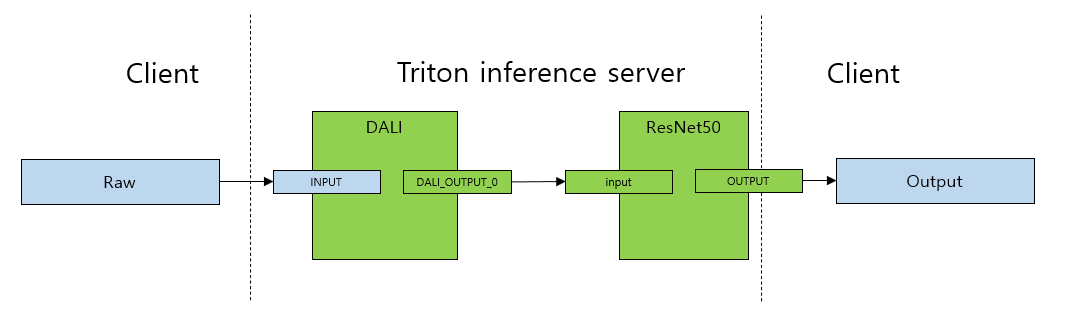
Triton Inference Server with DALI backend — NVIDIA Triton Inference Server
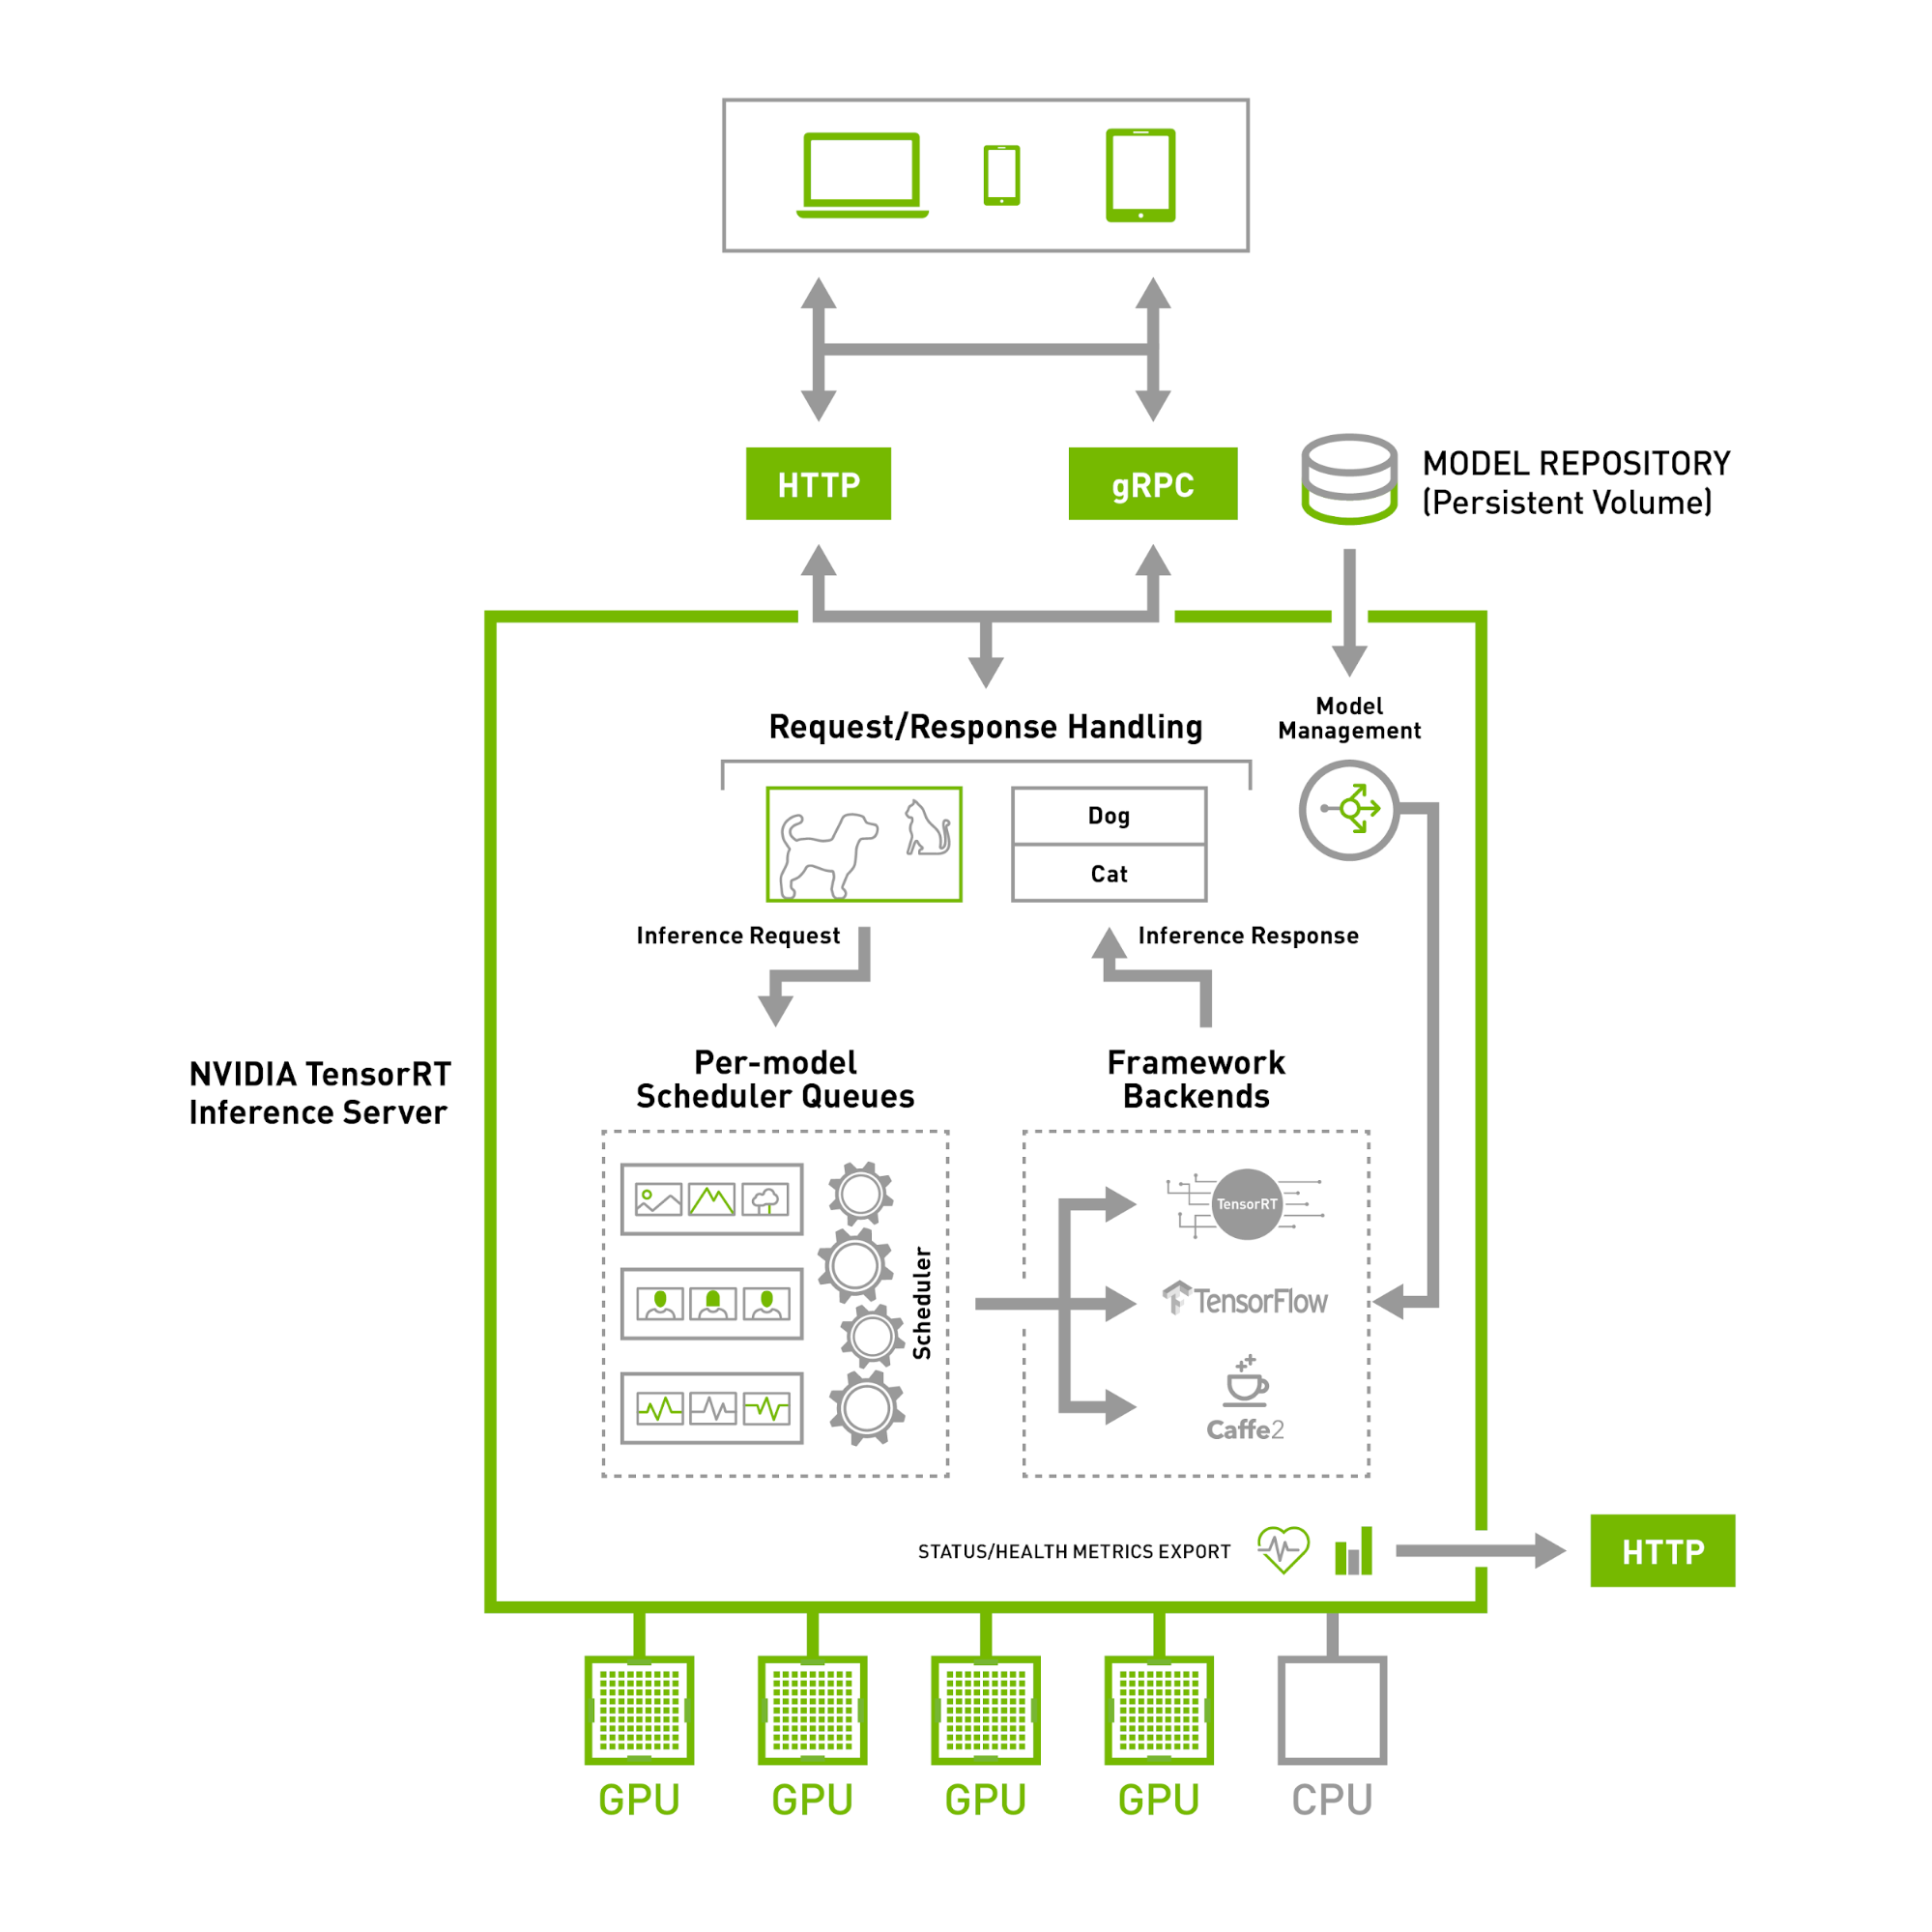
Architecture — NVIDIA Triton Inference Server 1.12.0 documentation

TensorRT LLM vs. Triton Inference Server: Optimizing Large Language ...

🤖 LLM Inferencing with TensorRT-LLM + Triton Inference Server | by ...
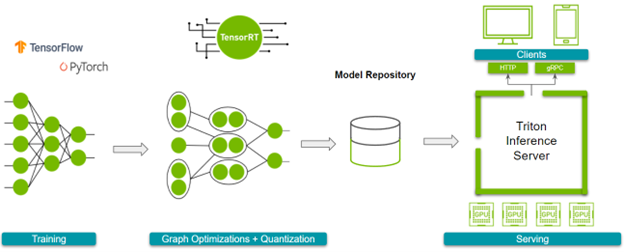
Nvidia Triton Inference _ NVIDIA Triton Inference Server – KDSK
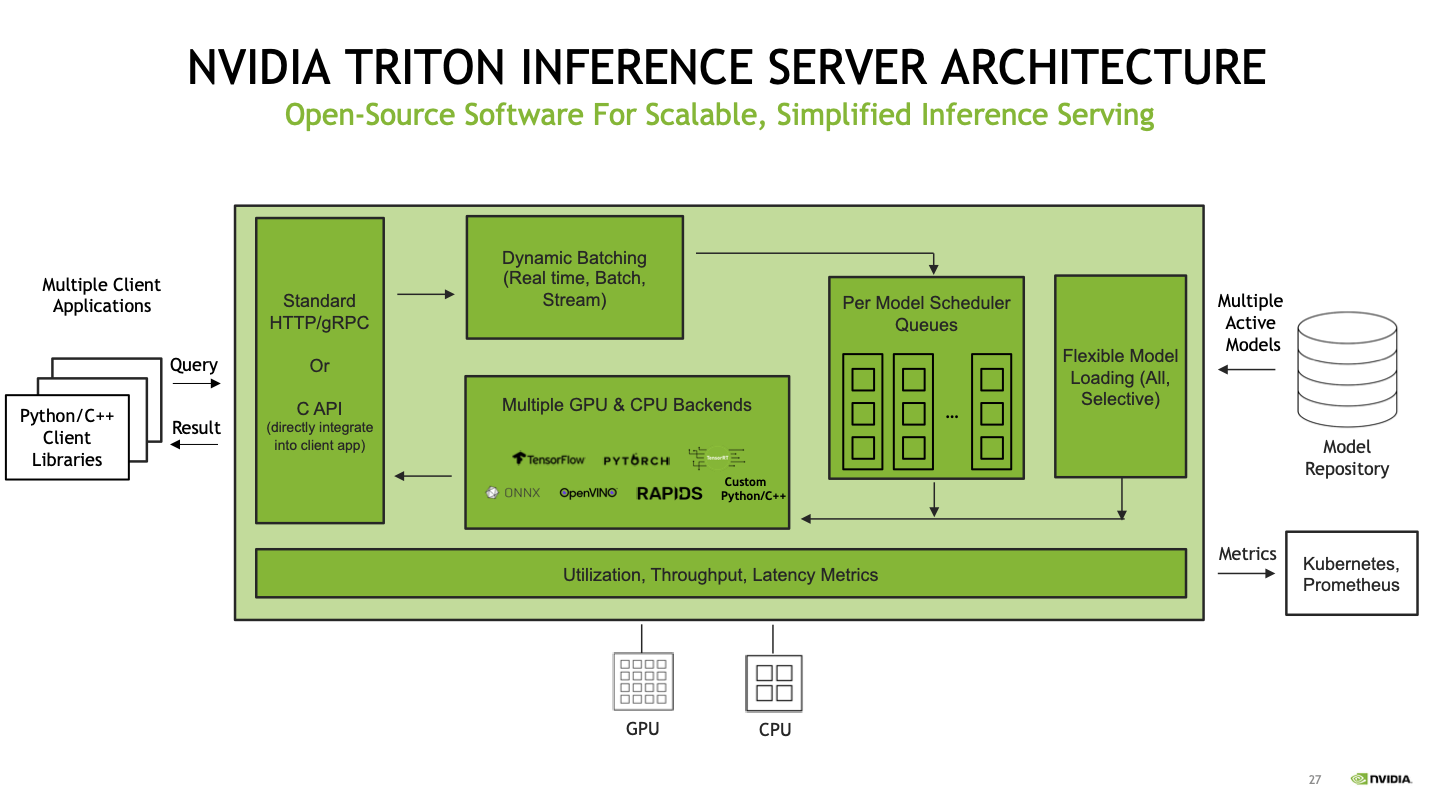
Deploy fast and scalable AI with NVIDIA Triton Inference Server in ...

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...
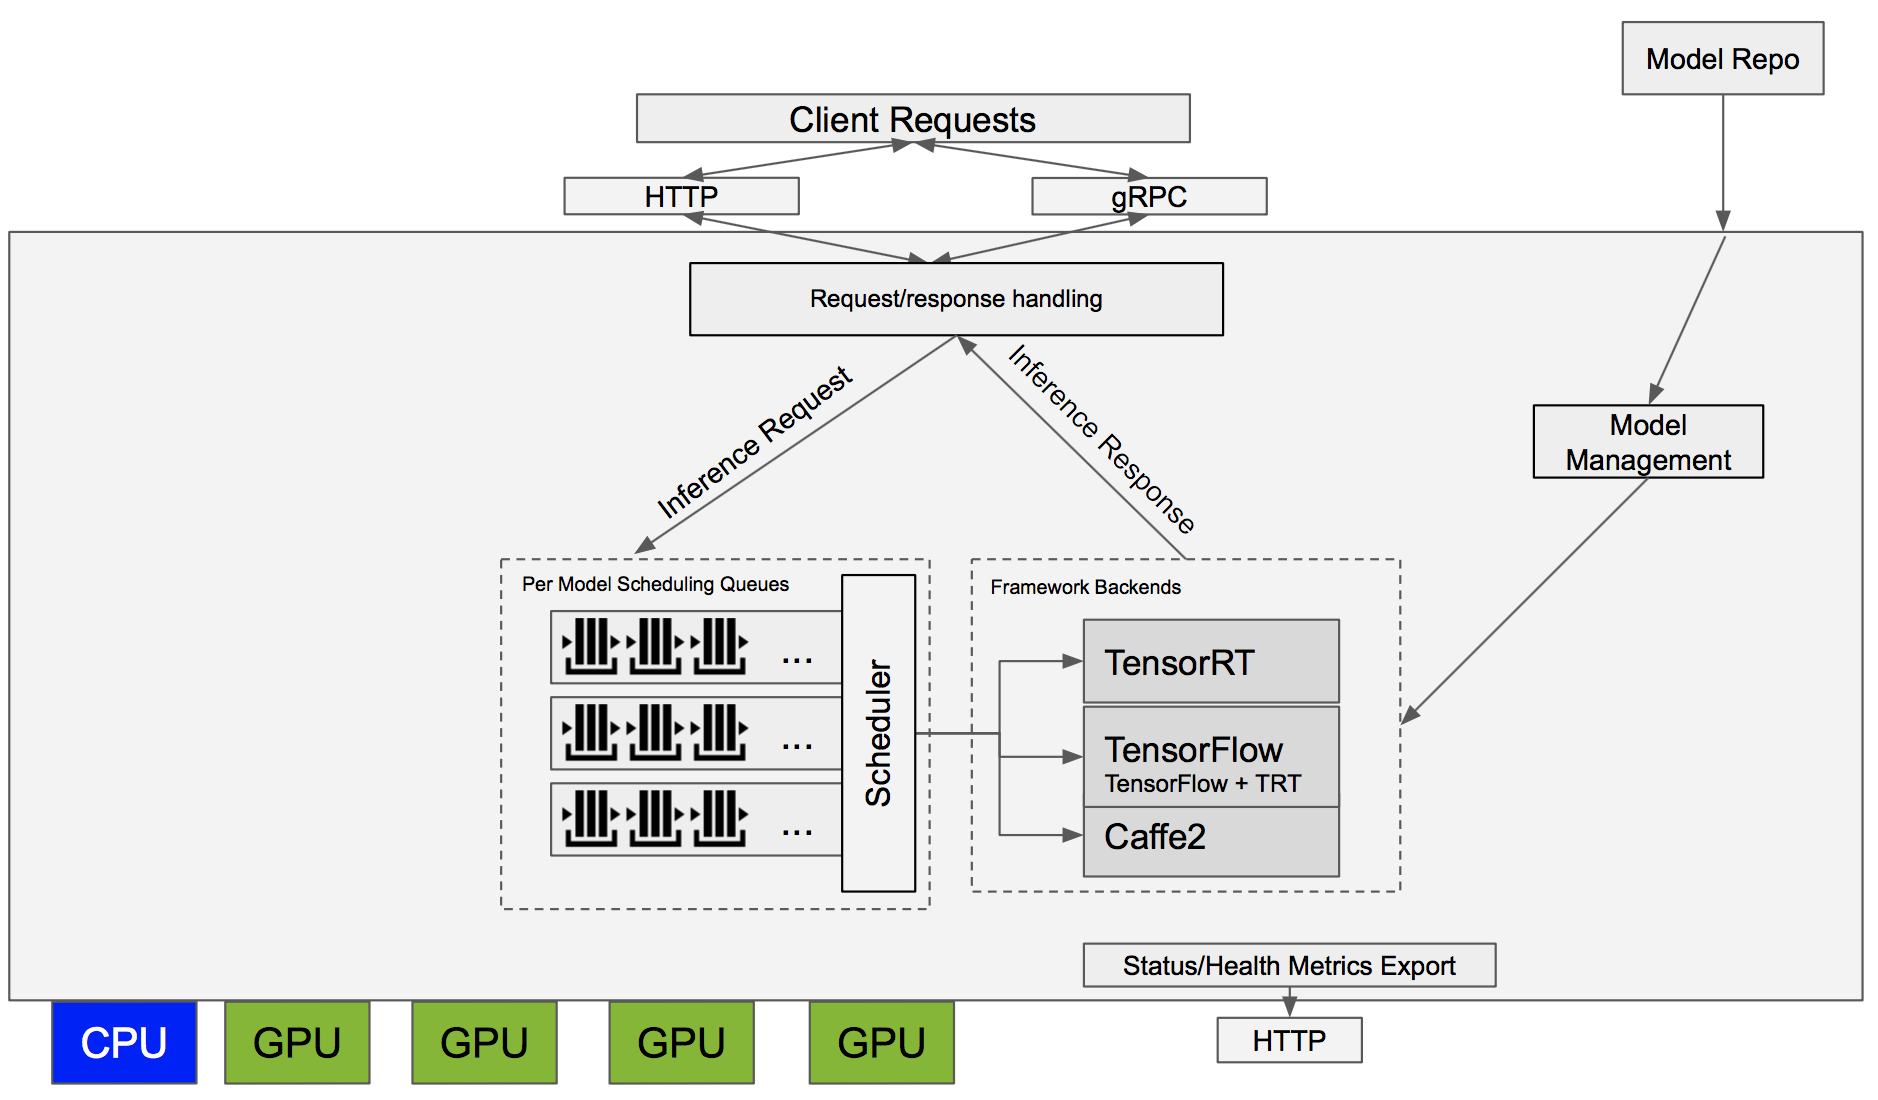
NVIDIA Triton Inference Server Boosts Deep Learning Inference | NVIDIA ...

TensorRT LLM vs. Triton Inference Server: Optimizing Large Language ...

TensorRT LLM vs. Triton Inference Server: Optimizing Large Language ...
Advertisement Space (336x280)
Triton Inference Server Backend | NVIDIA/TensorRT-LLM | DeepWiki

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...
Power Your AI Inference with New NVIDIA Triton and NVIDIA TensorRT ...
Deploy NVIDIA Triton Inference Server on GPU Cloud: Production Multi ...

Inference VILA 3b using The Triton TensorRT-LLM Backend - TensorRT ...
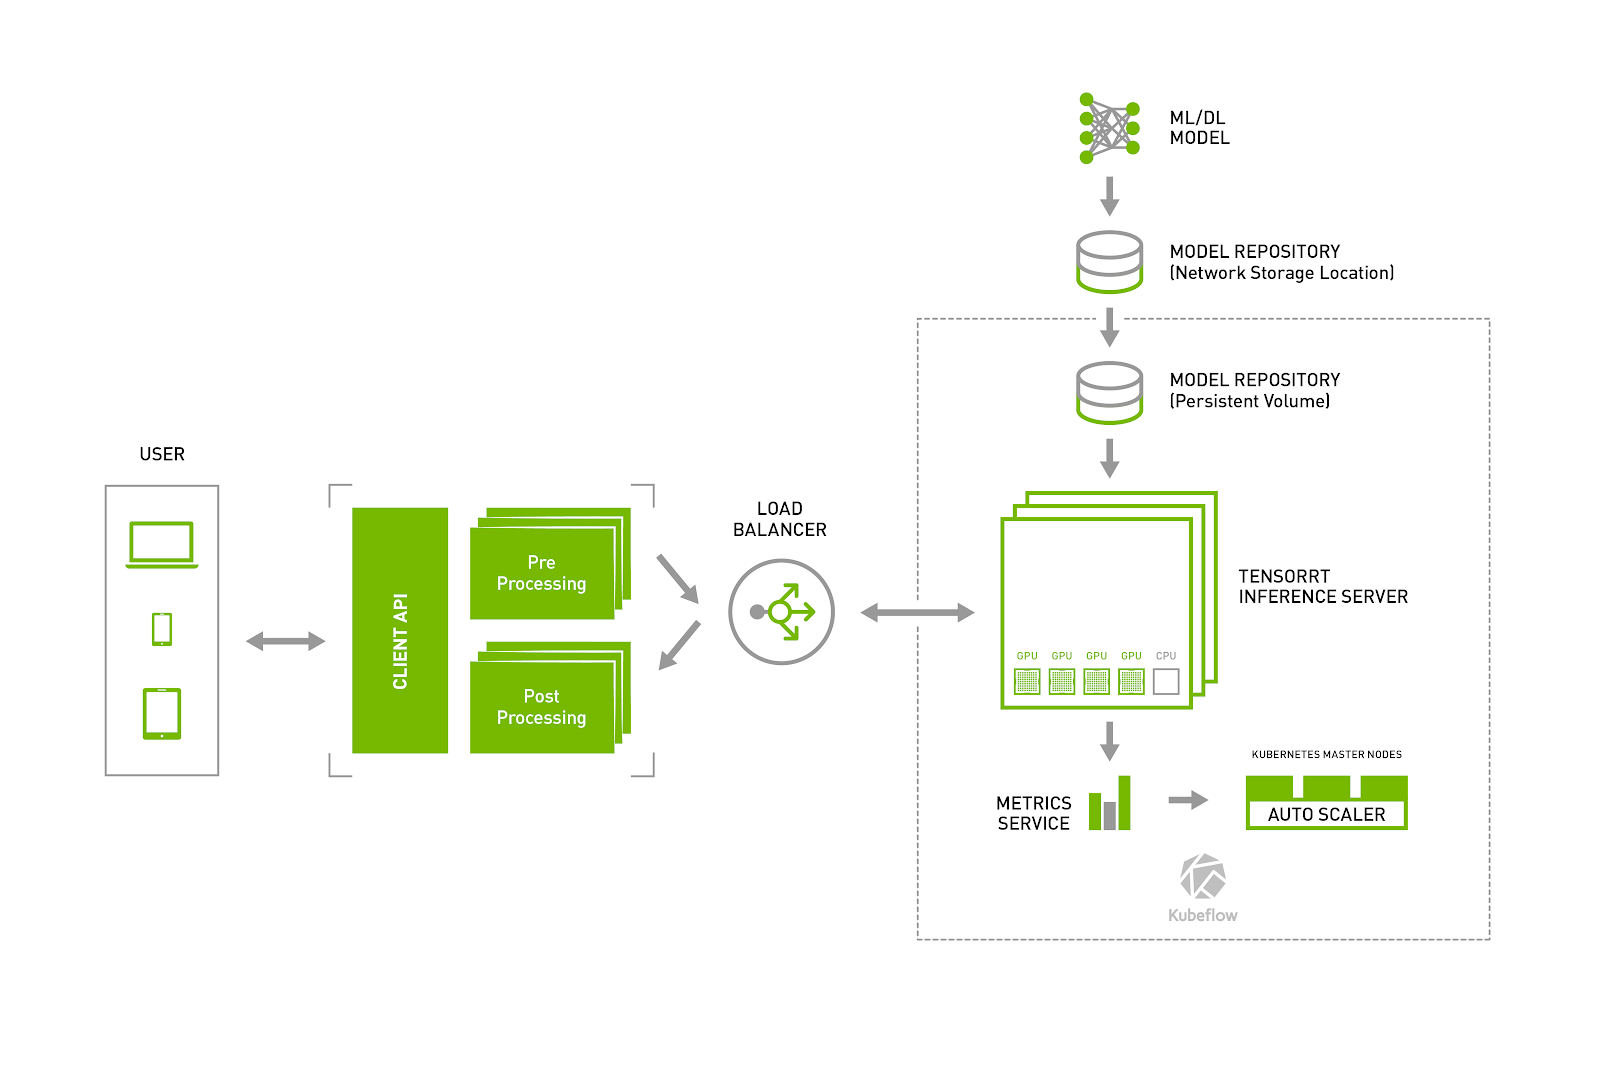
NVIDIA TensorRT Inference Server and Kubeflow Make Deploying Data ...

Automating Inference Optimizations with NVIDIA TensorRT LLM AutoDeploy ...
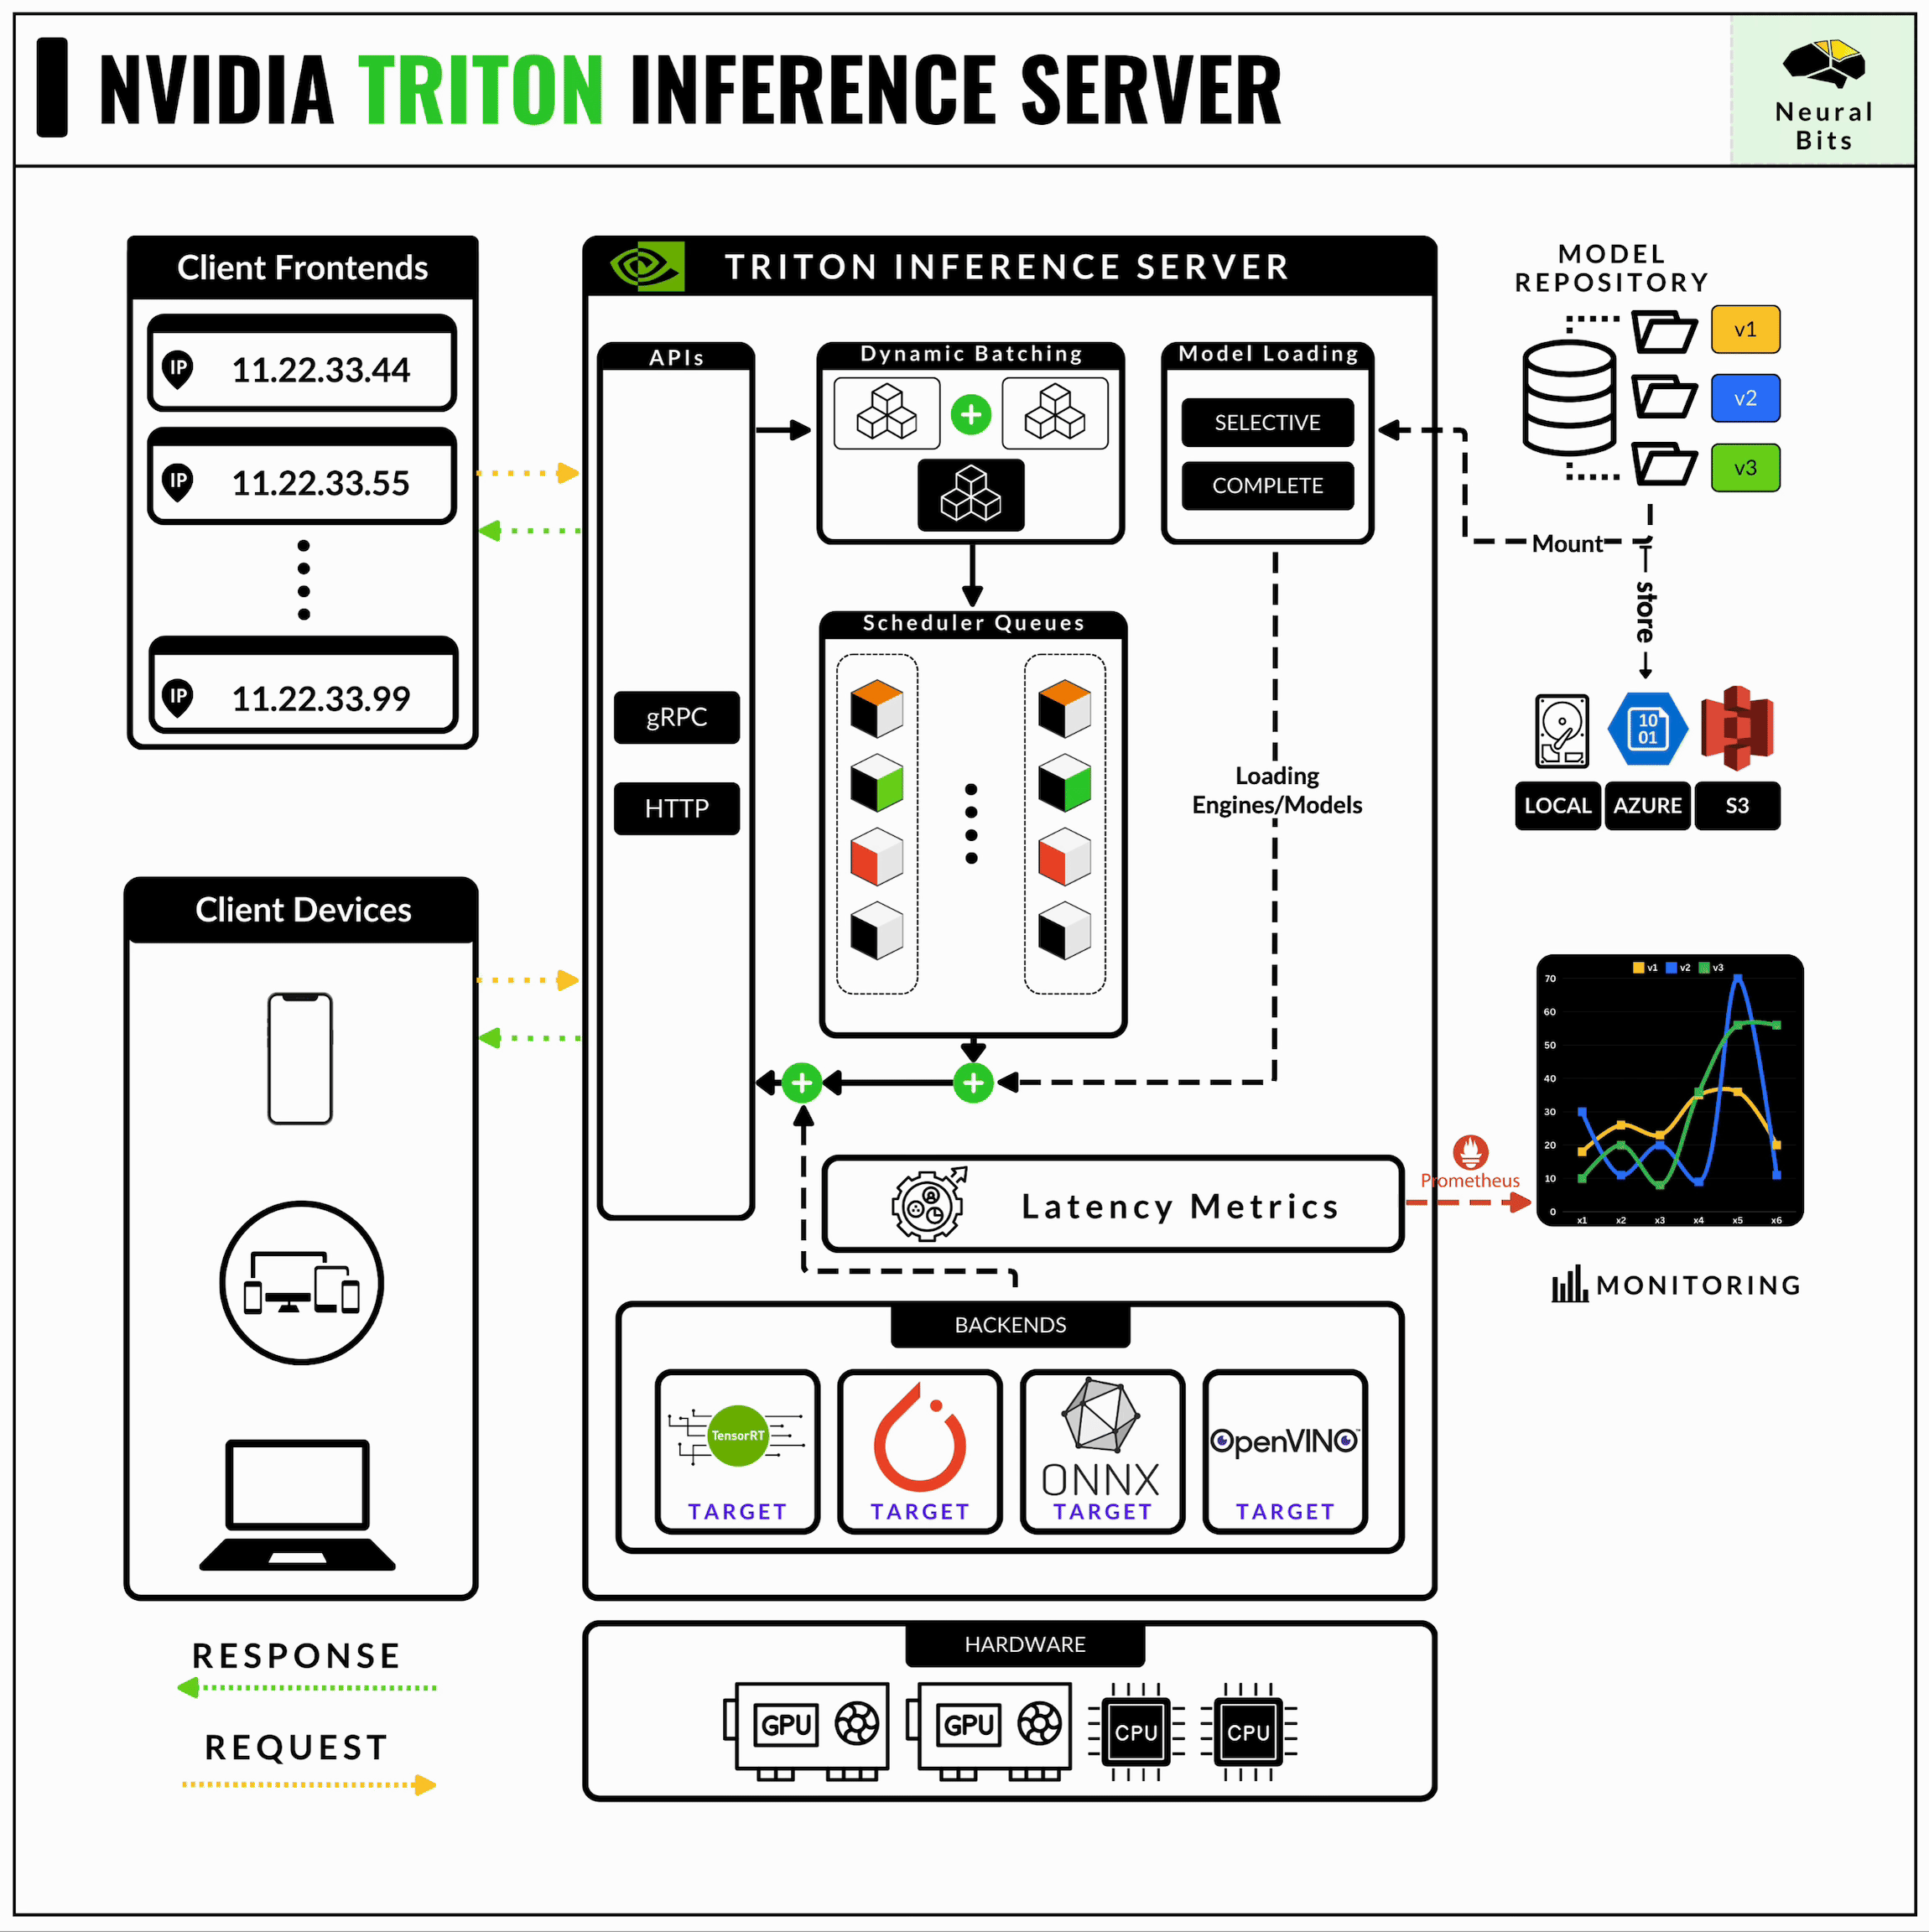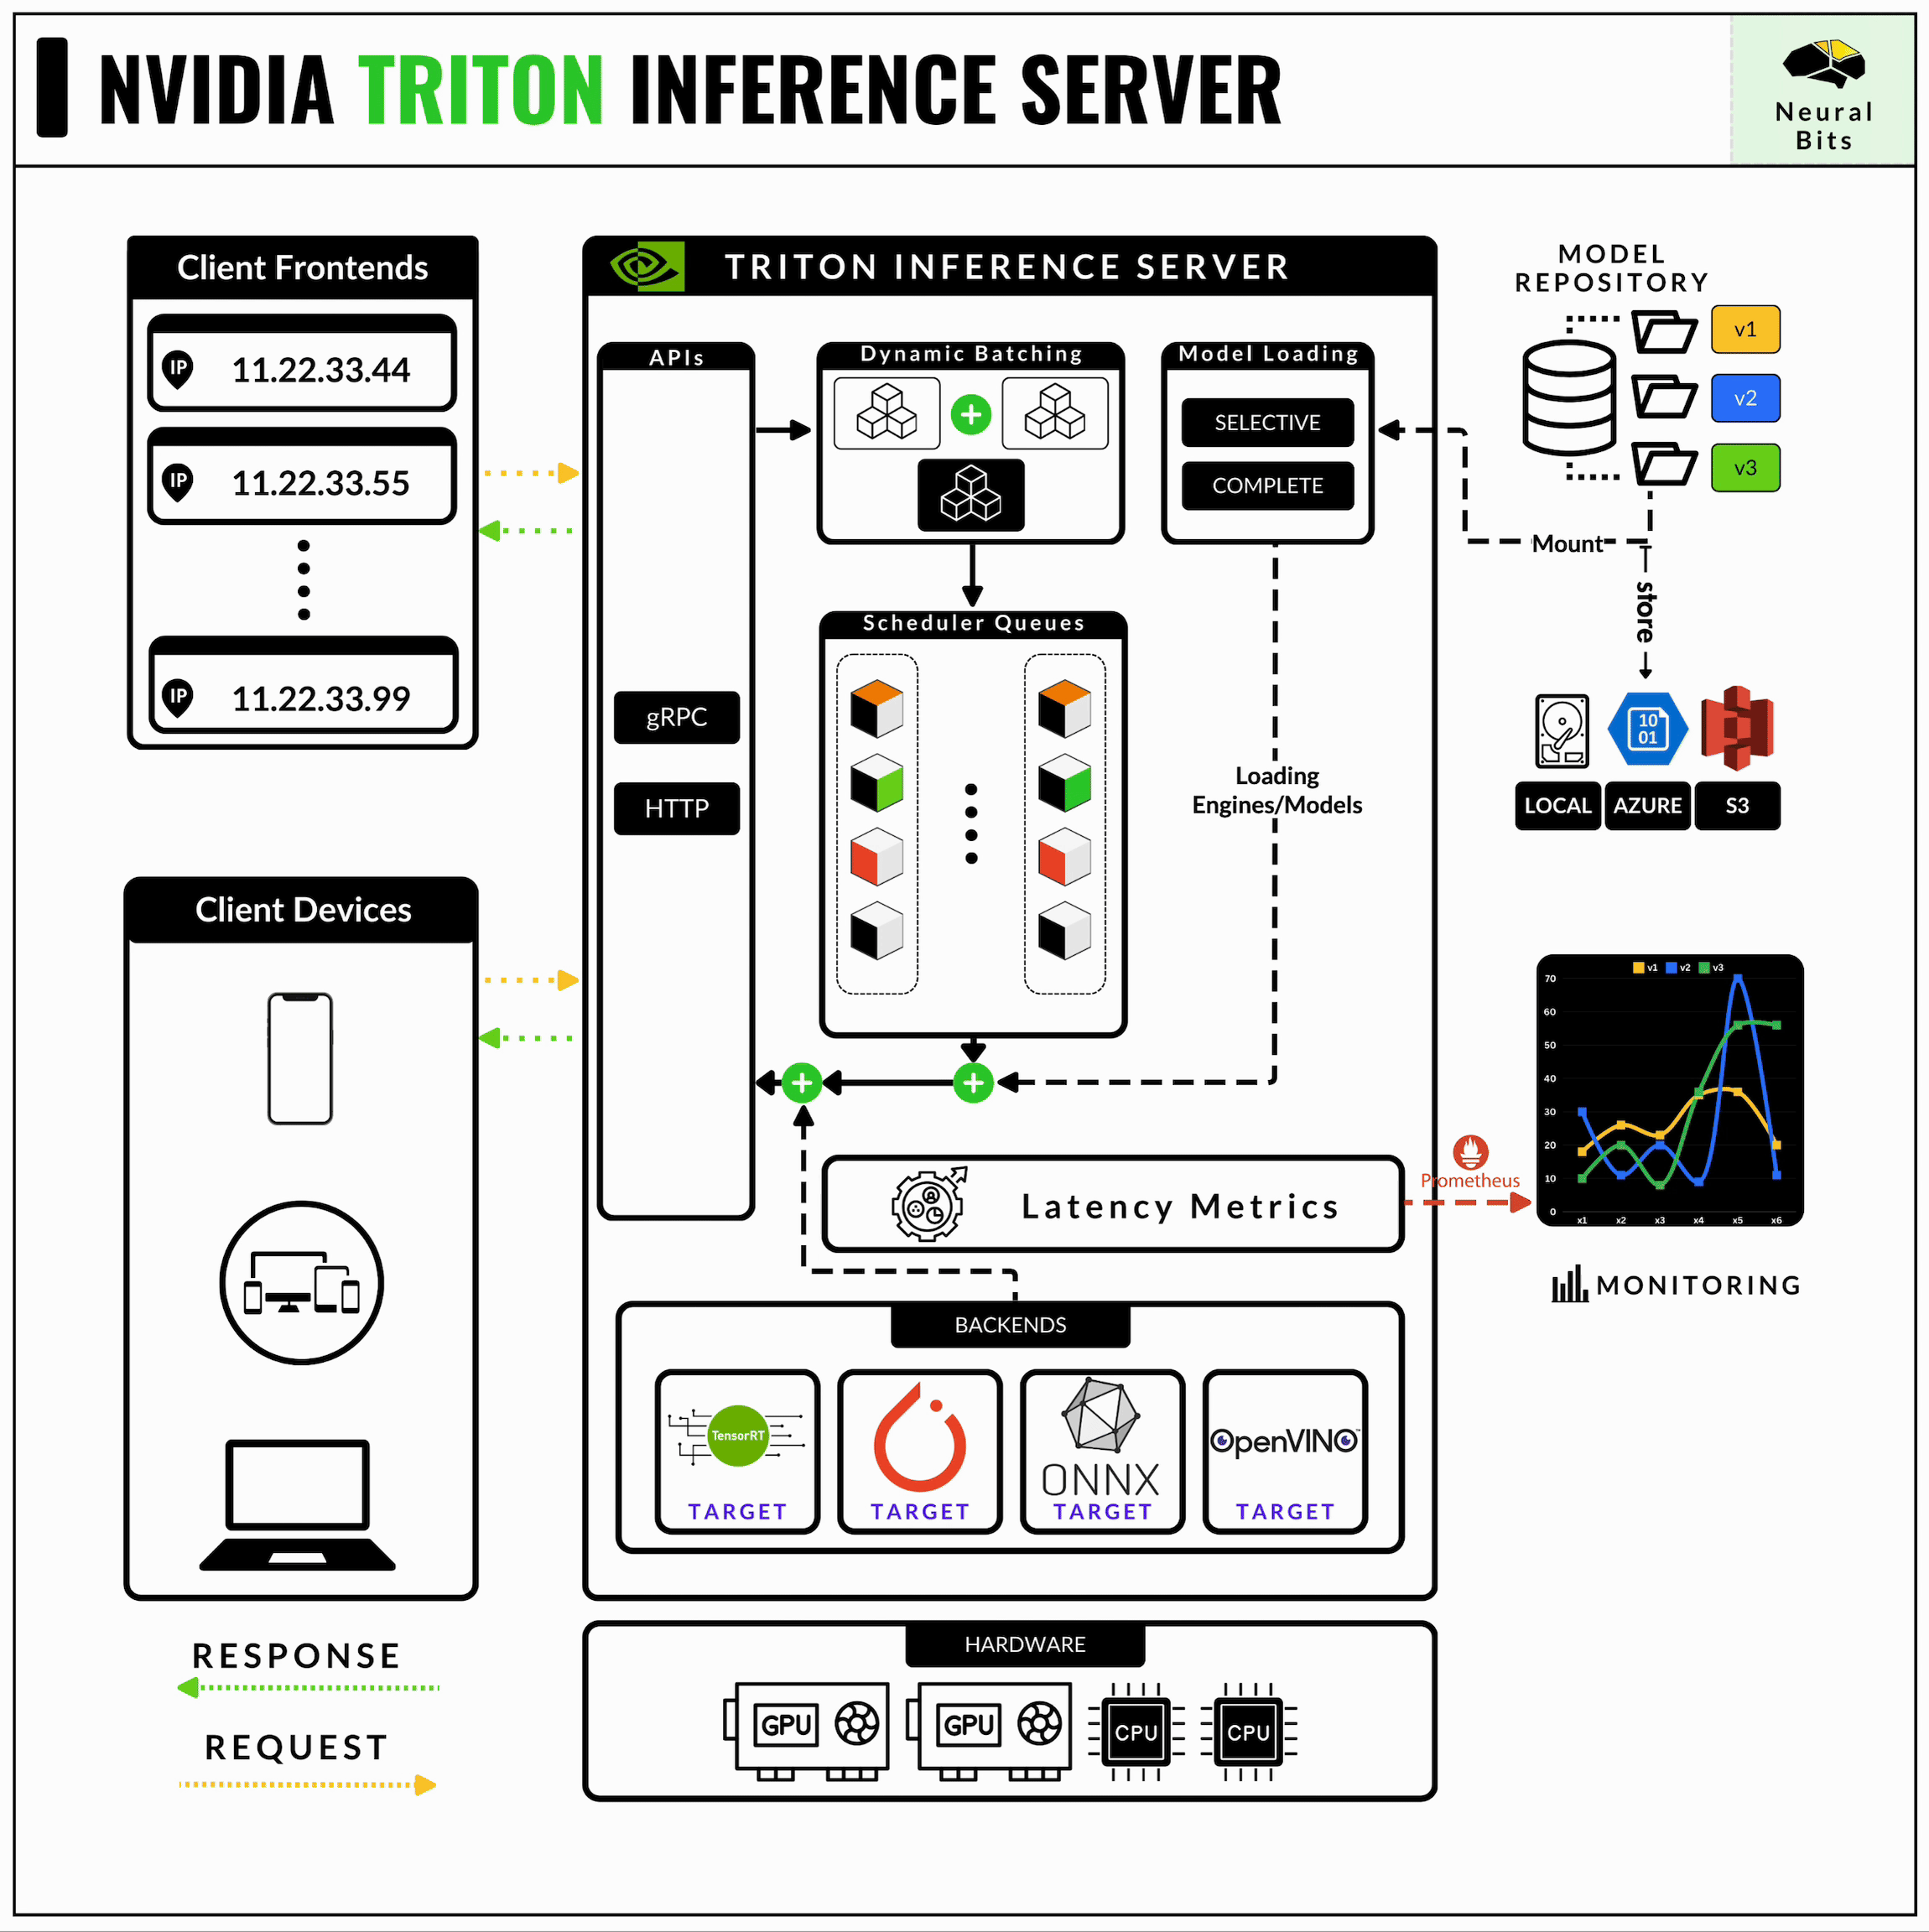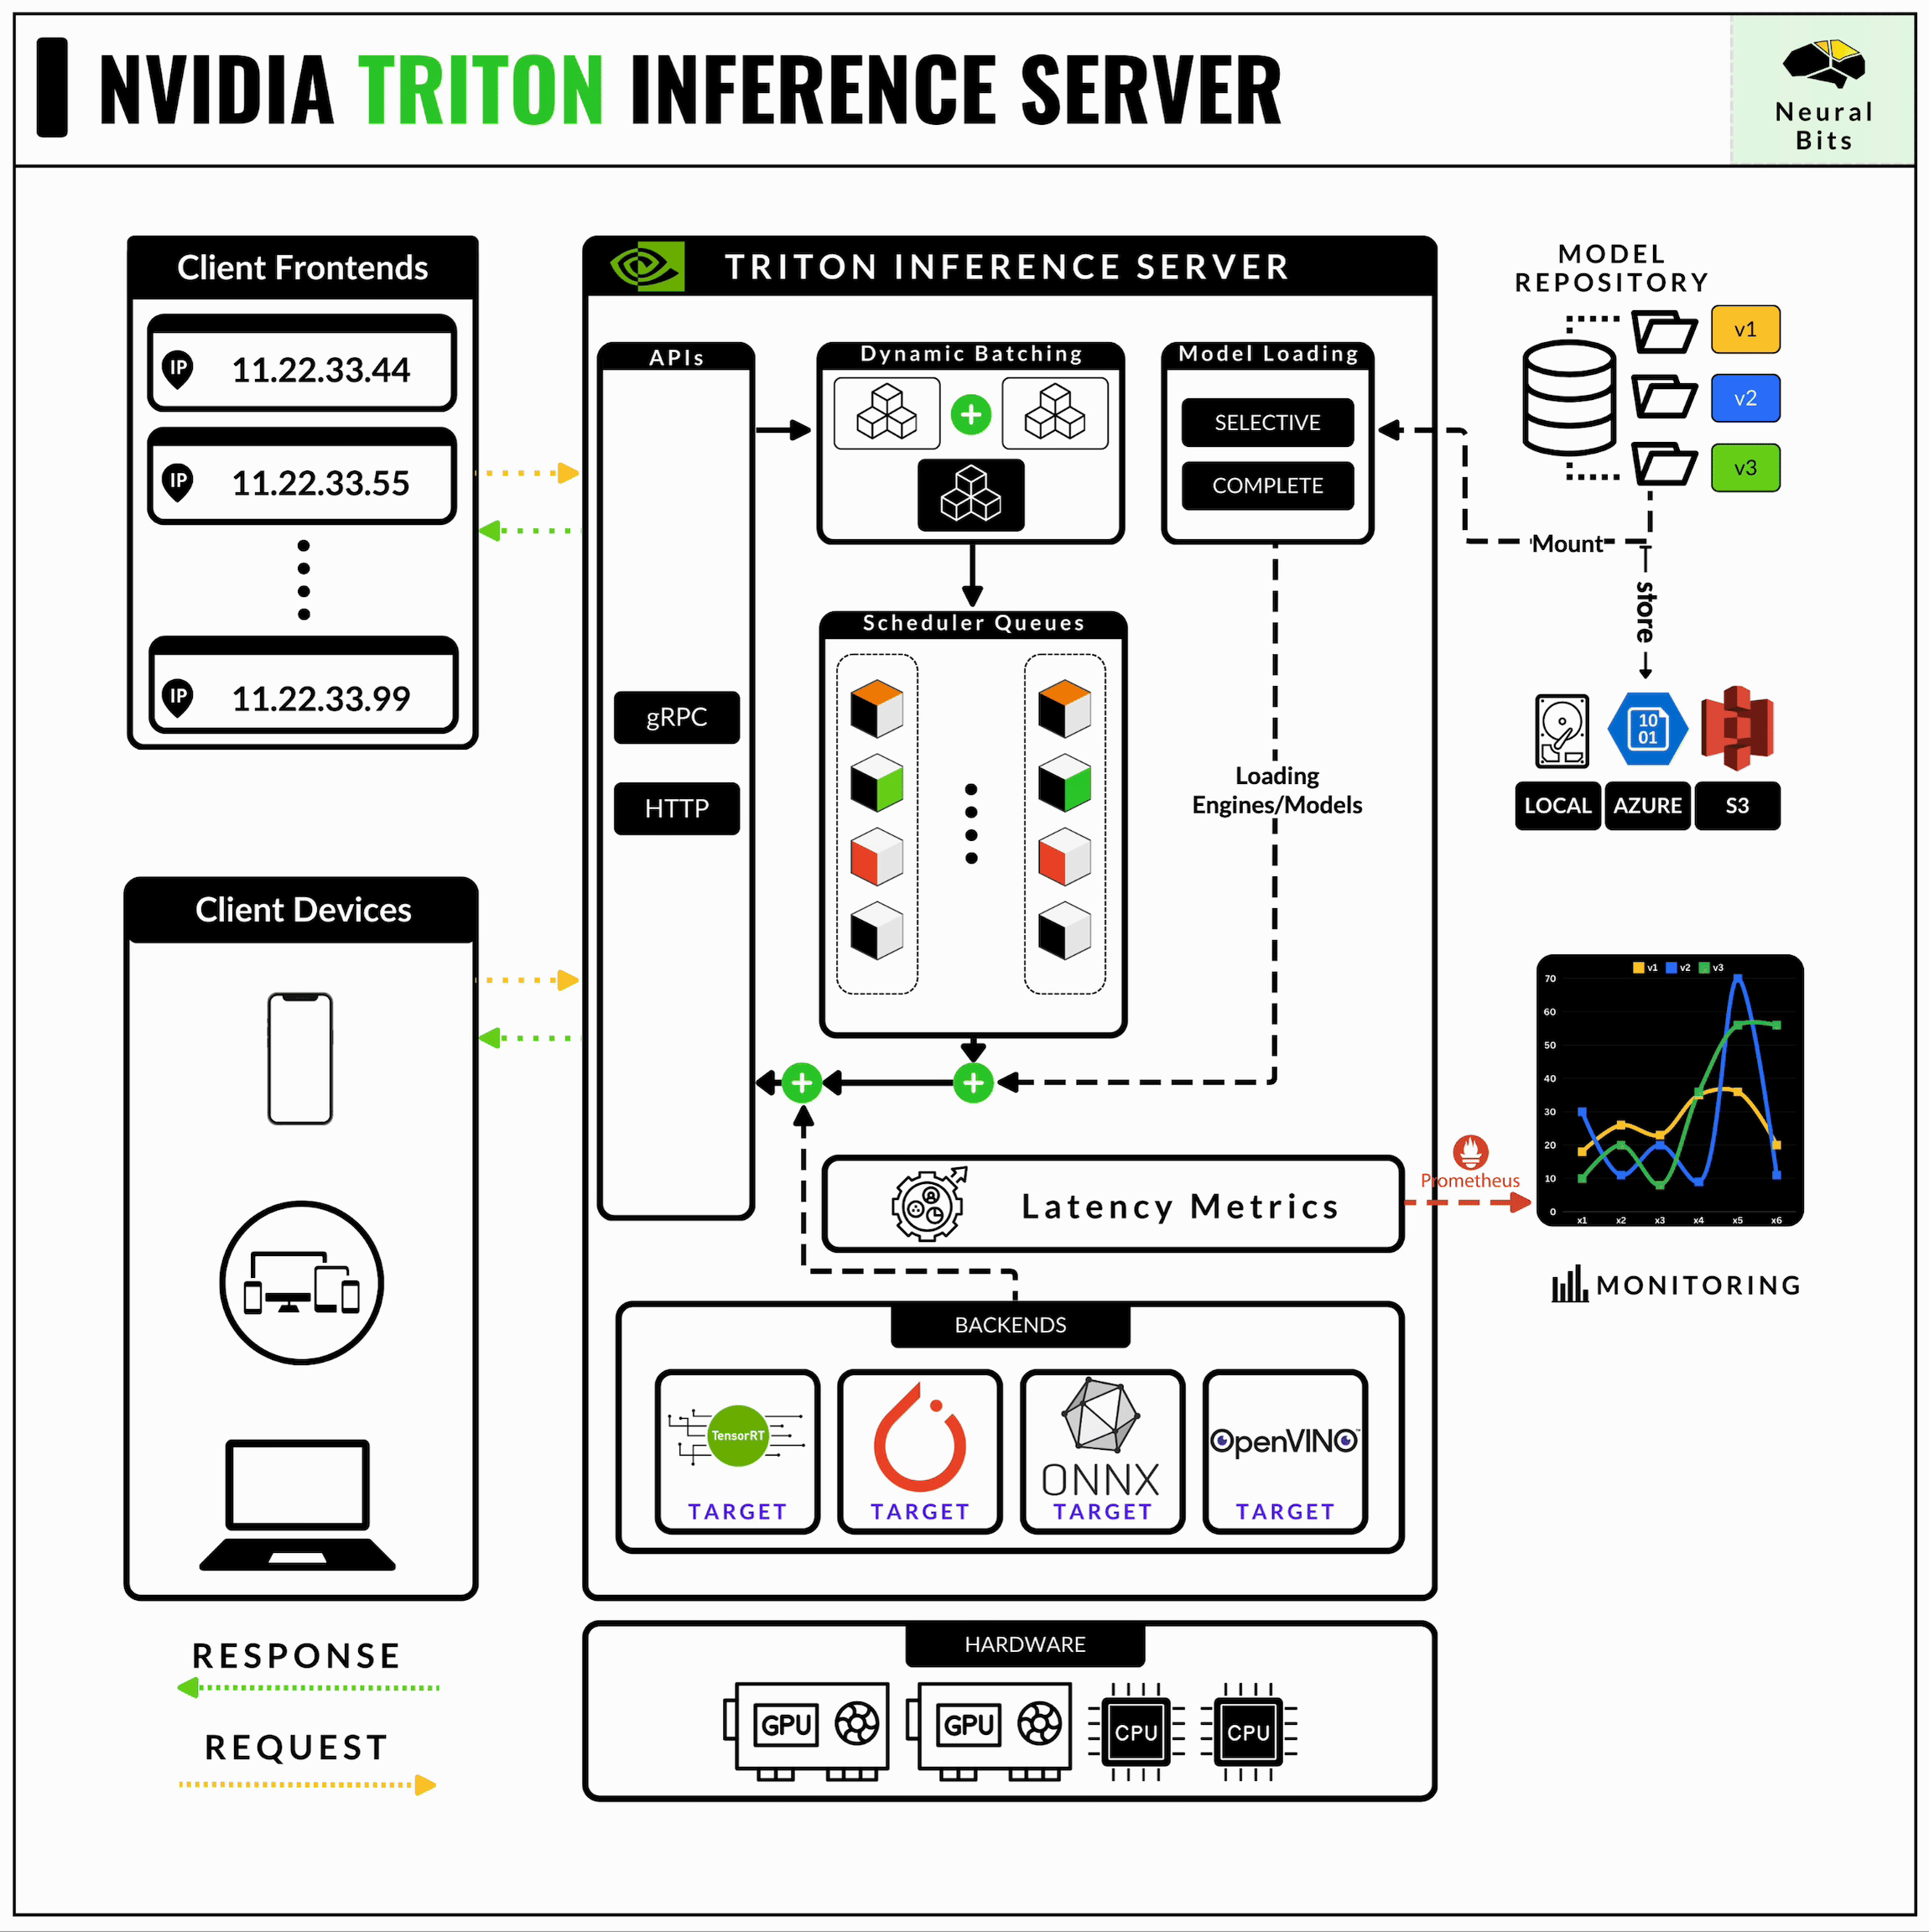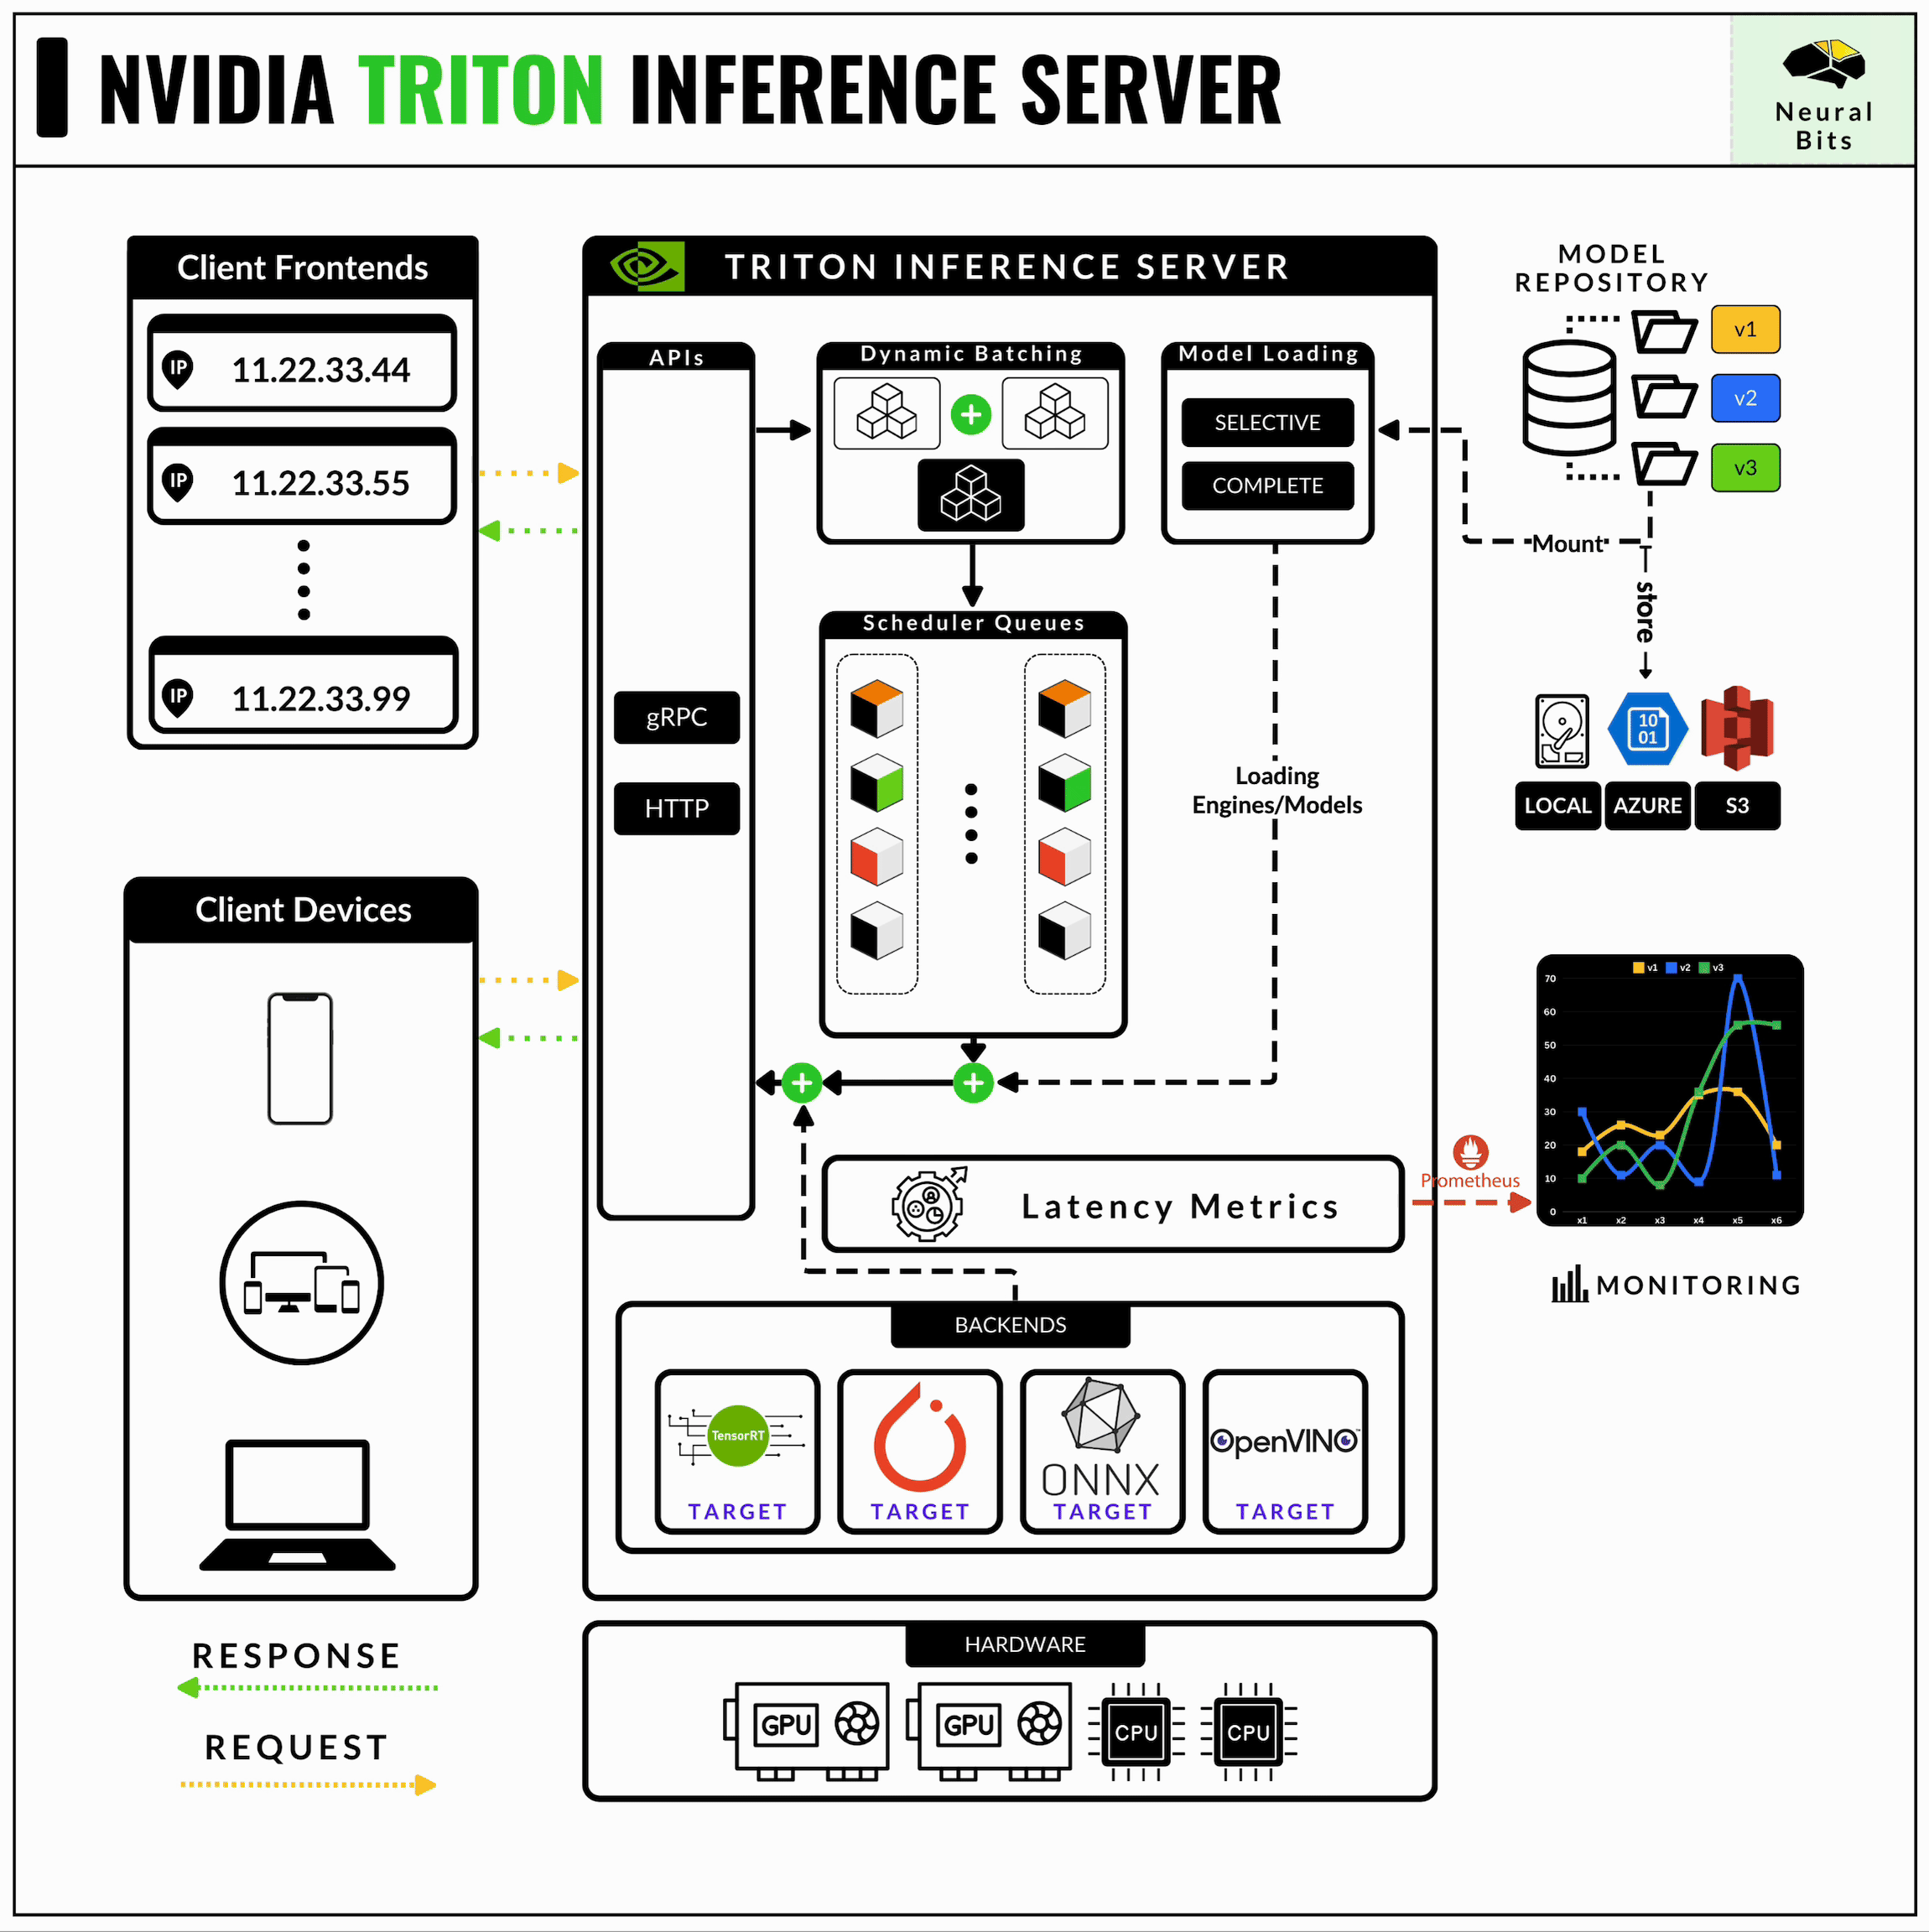
Deploy Triton Inference server and TensorRT-LLM - Cerebrium

Accelerating Inference for Deep Learning Models — NVIDIA Triton ...

Accelerated Inference for Large Transformer Models Using NVIDIA Triton ...
Advertisement Space (336x280)

Accelerated Inference for Large Transformer Models Using NVIDIA Triton ...

The Triton Inference server is a powerhouse inference server from ...

Optimizing and Serving Models with NVIDIA TensorRT and NVIDIA Triton ...

LLM 推理:Nvidia TensorRT-LLM 与 Triton Inference Server_tensorrt llm ...
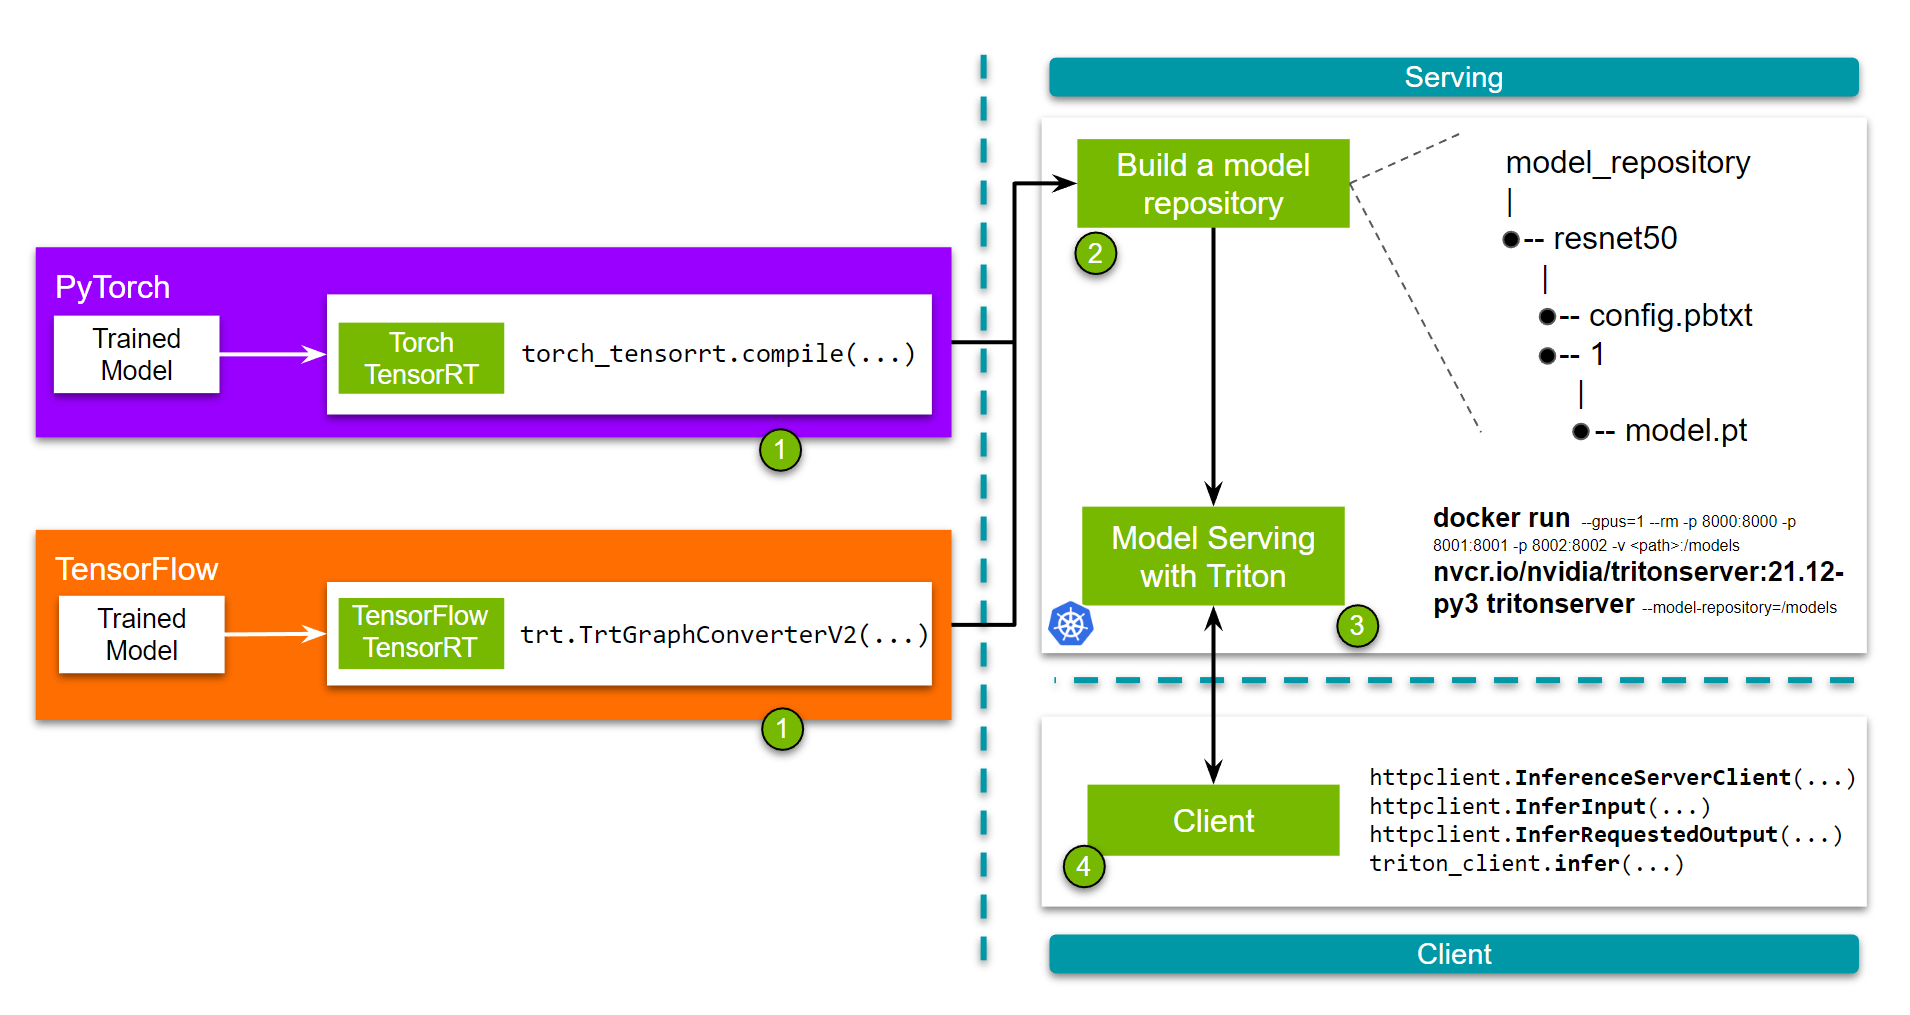
Accelerating Inference for Deep Learning Models — NVIDIA Triton ...

利用 NVIDIA Triton 和 NVIDIA TensorRT-LLM 及 Kubernetes 实现 LLM 扩展 - NVIDIA 技术博客