
Token Sparse Attention Efficient Long Context Inference With

Token Sparse Attention: Efficient Long-Context Inference with ...
Token Sparse Attention: Efficient Long-Context Inference with ...

Token Sparse Attention: Efficient Long-Context Inference with ...

Token Sparse Attention: Efficient Long-Context Inference with ...

Token Sparse Attention: Efficient Long-Context Inference with ...

STS: Efficient Sparse Attention with Speculative Token Sparsity

STS: Efficient Sparse Attention with Speculative Token Sparsity
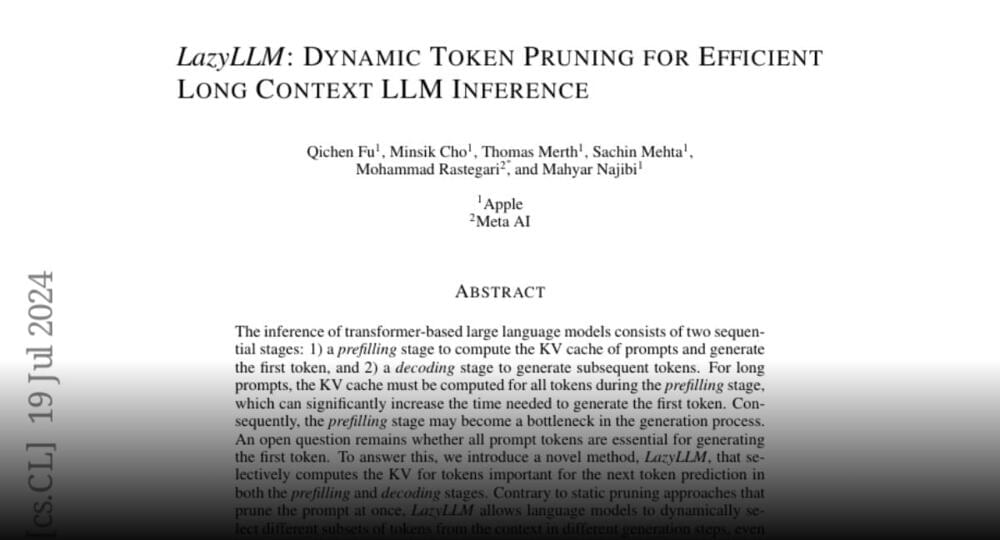
LazyLLM: Dynamic Token Pruning for Efficient Long Context LLM Inference ...

STS: Efficient Sparse Attention with Speculative Token Sparsity

An Efficient Hybrid Sparse Attention with CPU-GPU Parallelism for Long ...
Advertisement Space (300x250)
Token Sparse Attention: Efficient Long-Context Inference with ...

An Efficient Hybrid Sparse Attention with CPU-GPU Parallelism for Long ...

Token Sparse Attention: Efficient Long-Context Inference with ...

Unifying Sparse Attention with Hierarchical Memory for Scalable Long ...

Near-Lossless Acceleration of Long Context LLM Inference with Adaptive ...

[QA] LazyLLM: Dynamic Token Pruning for Efficient Long Context LLM ...

Unifying Sparse Attention with Hierarchical Memory for Scalable Long ...

LServe: Efficient Long-sequence LLM Serving with Unified Sparse Attention

论文翻译 | LazyLLM: DYNAMIC TOKEN PRUNING FOR EFFICIENT LONG CONTEXT LLM ...
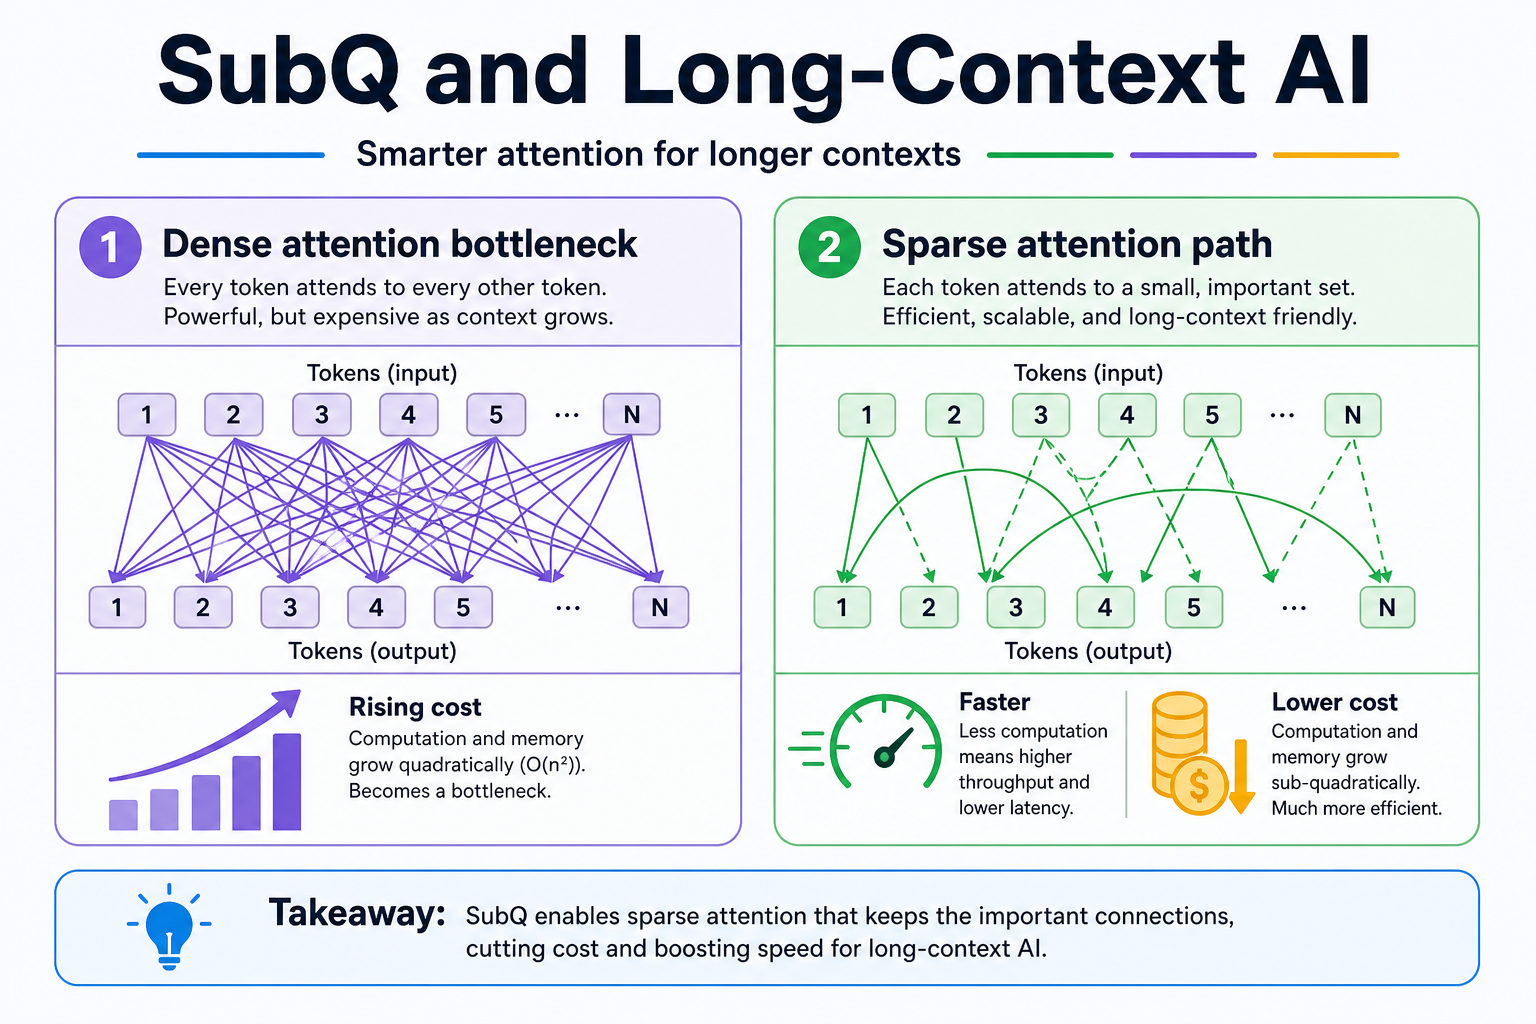
SubQ Sparse Attention Explained: How Ultra-Long Context Could Reshape ...
Advertisement Space (336x280)
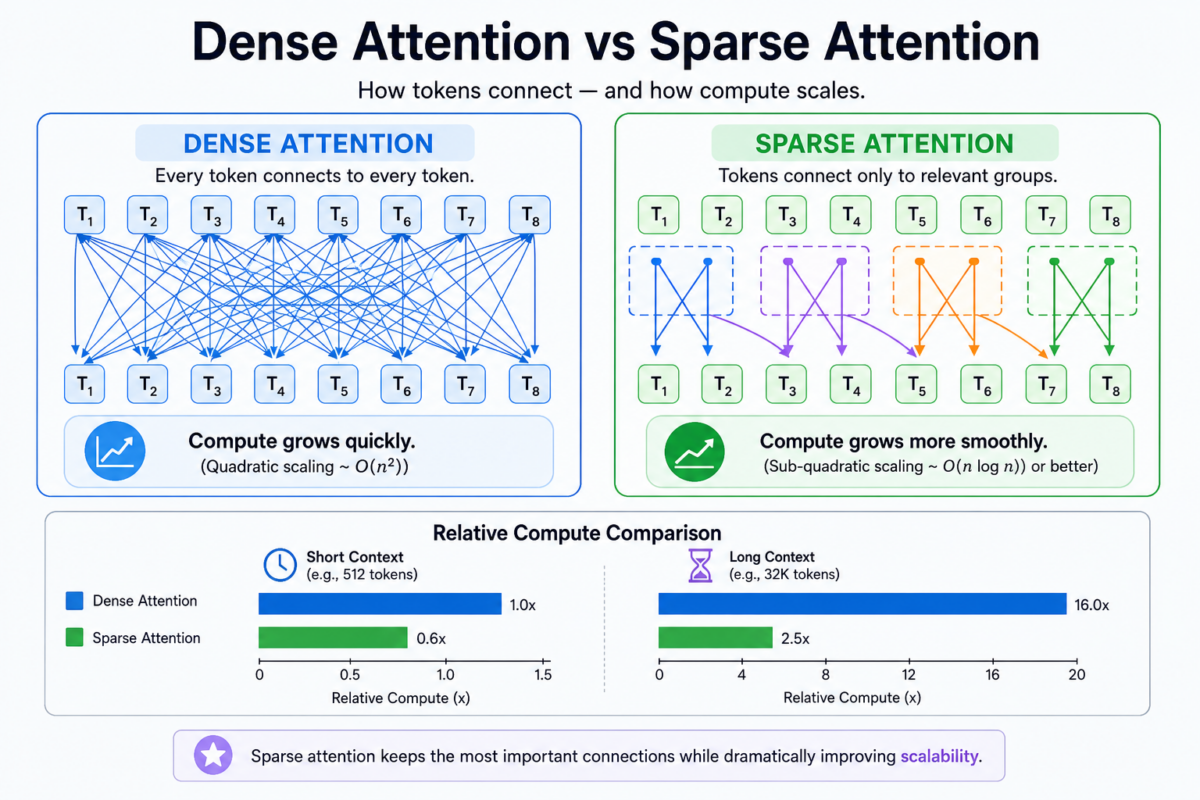
SubQ Sparse Attention Explained: How Ultra-Long Context Could Reshape ...
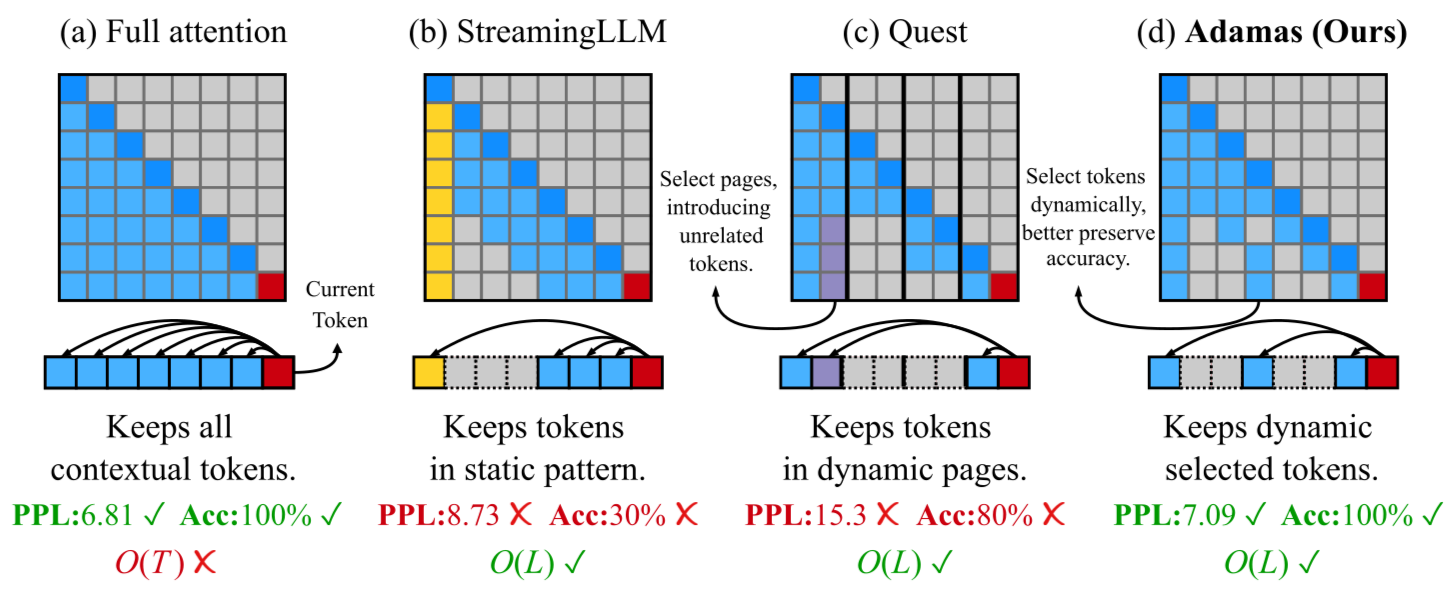
[논문 리뷰] Adamas: Hadamard Sparse Attention for Efficient Long-Context ...

Long-Context Modeling with Dynamic Hierarchical Sparse Attention for ...

Long-Context Modeling with Dynamic Hierarchical Sparse Attention for ...
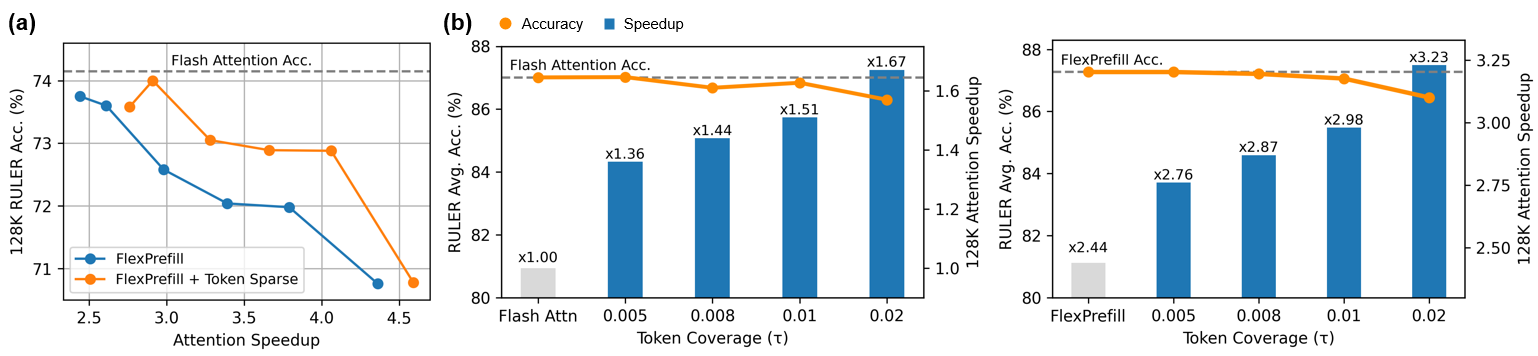
Token Sparse Attention Dongwon Jo

Latent-Condensed Transformer for Efficient Long Context Modeling | AI ...

DuoAttention: Efficient Long-Context LLM Inference with Retrieval and ...

MSA Memory Sparse Attention for Efficient End to End Memory Model ...

Long-Context Modeling with Dynamic Hierarchical Sparse Attention for ...

Long-Context Modeling with Dynamic Hierarchical Sparse Attention for ...
Advertisement Space (336x280)

[2024 Best AI Paper] LazyLLM: Dynamic Token Pruning for Efficient Long ...

GitHub - NVIDIA/Star-Attention: Efficient LLM Inference over Long ...
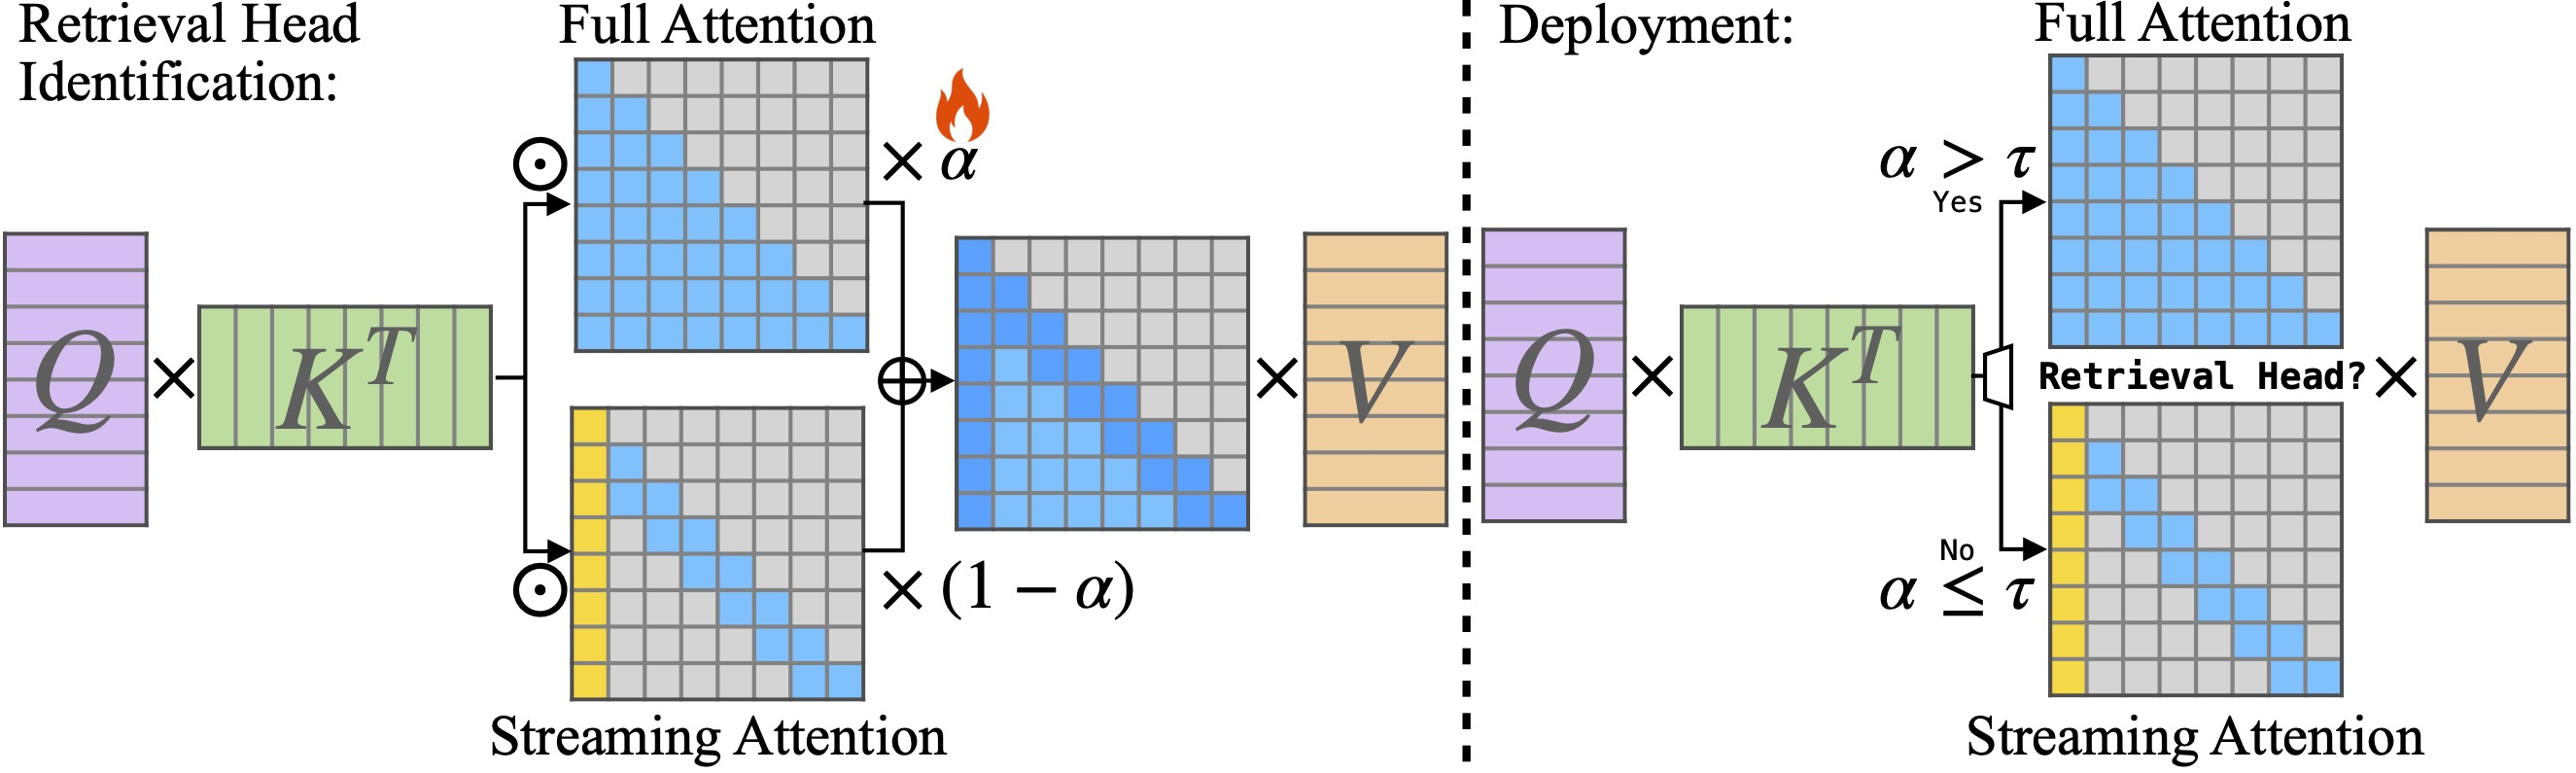
DuoAttention: Efficient Long-Context LLM Inference with Retrieval and ...
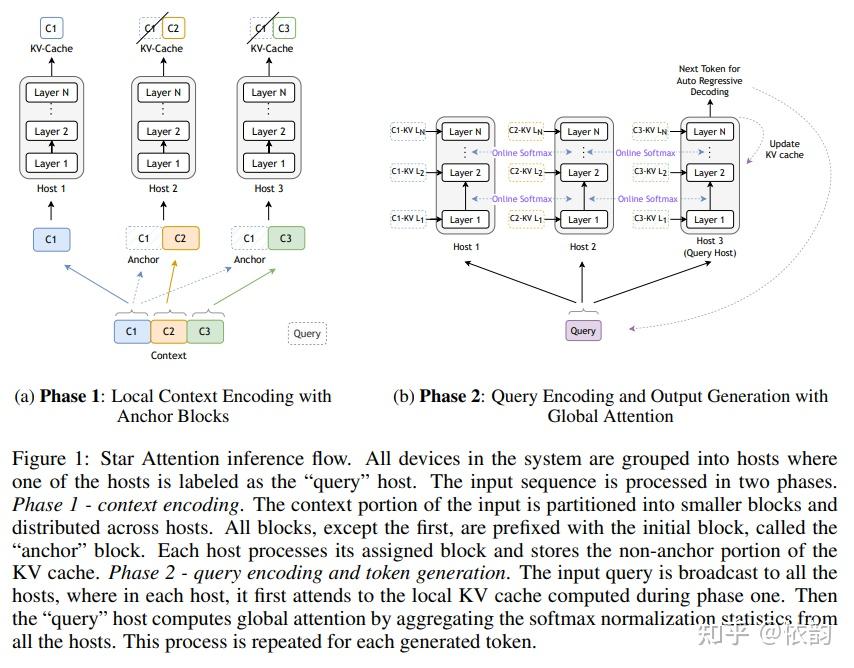
论文阅读 STAR ATTENTION: EFFICIENT LLM INFERENCE OVER LONG SEQUENCES - 知乎

Long-Context Generalization with Sparse Attention
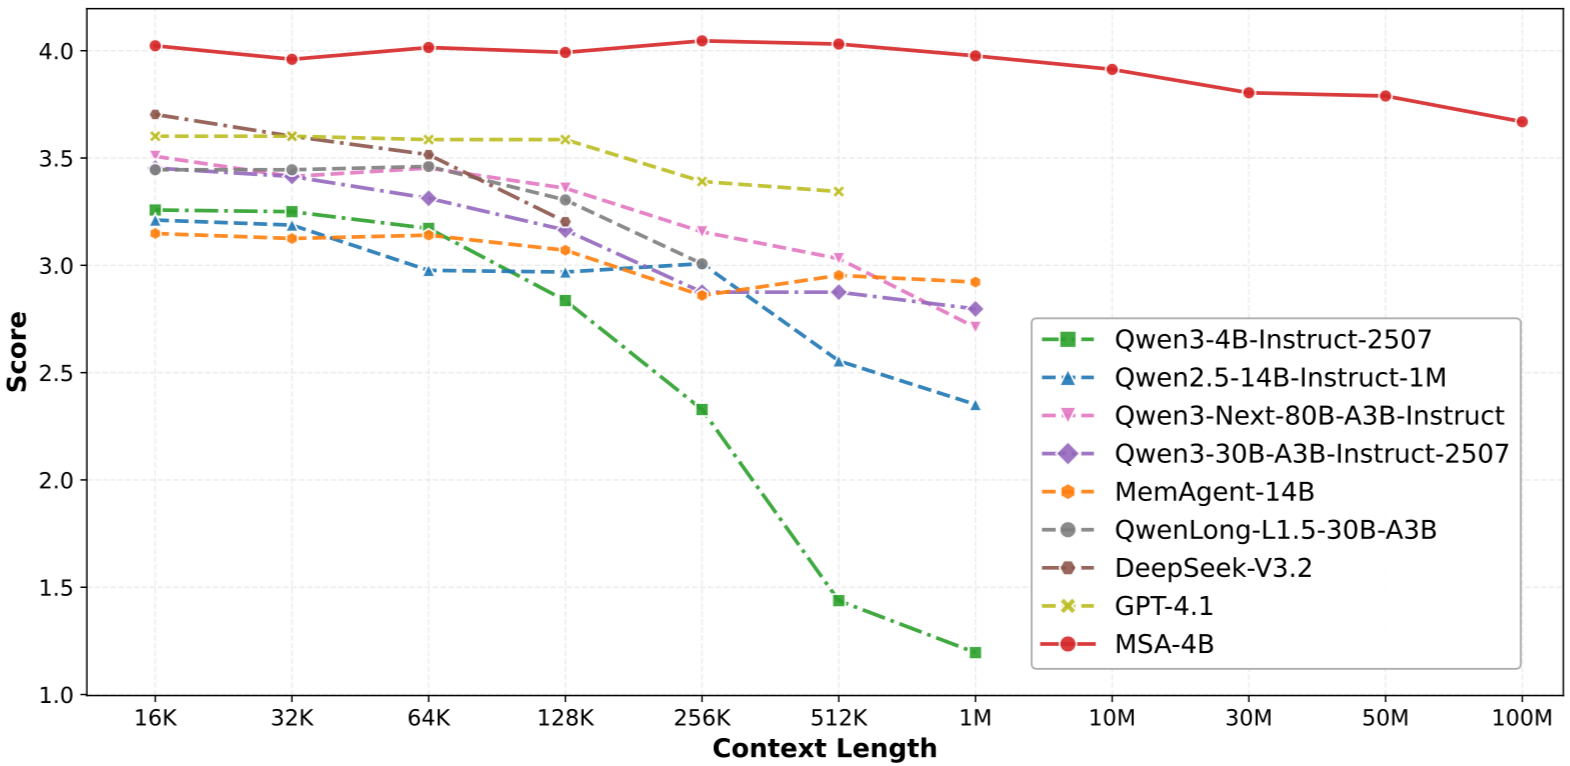
[論文レビュー] MSA: Memory Sparse Attention for Efficient End-to-End Memory ...