
Train Your Large Model On Multiple Gpus With Tensor Parallelism
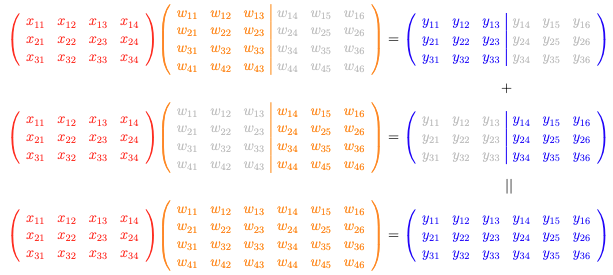
Train Your Large Model on Multiple GPUs with Tensor Parallelism ...
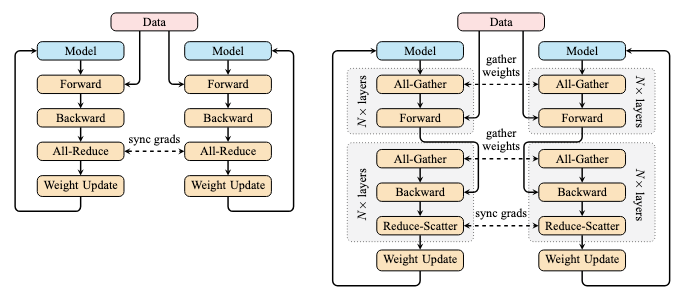
Train Your Large Model on Multiple GPUs with Fully Sharded Data ...

Scaling State-Space Models on Multiple GPUs with Tensor Parallelism ...
Training a Model on Multiple GPUs with Data Parallelism | daily.dev

Sharding Large Models with Tensor Parallelism
Tensor Parallelism: Model Parallelism for Large LLMs | Inference Systems
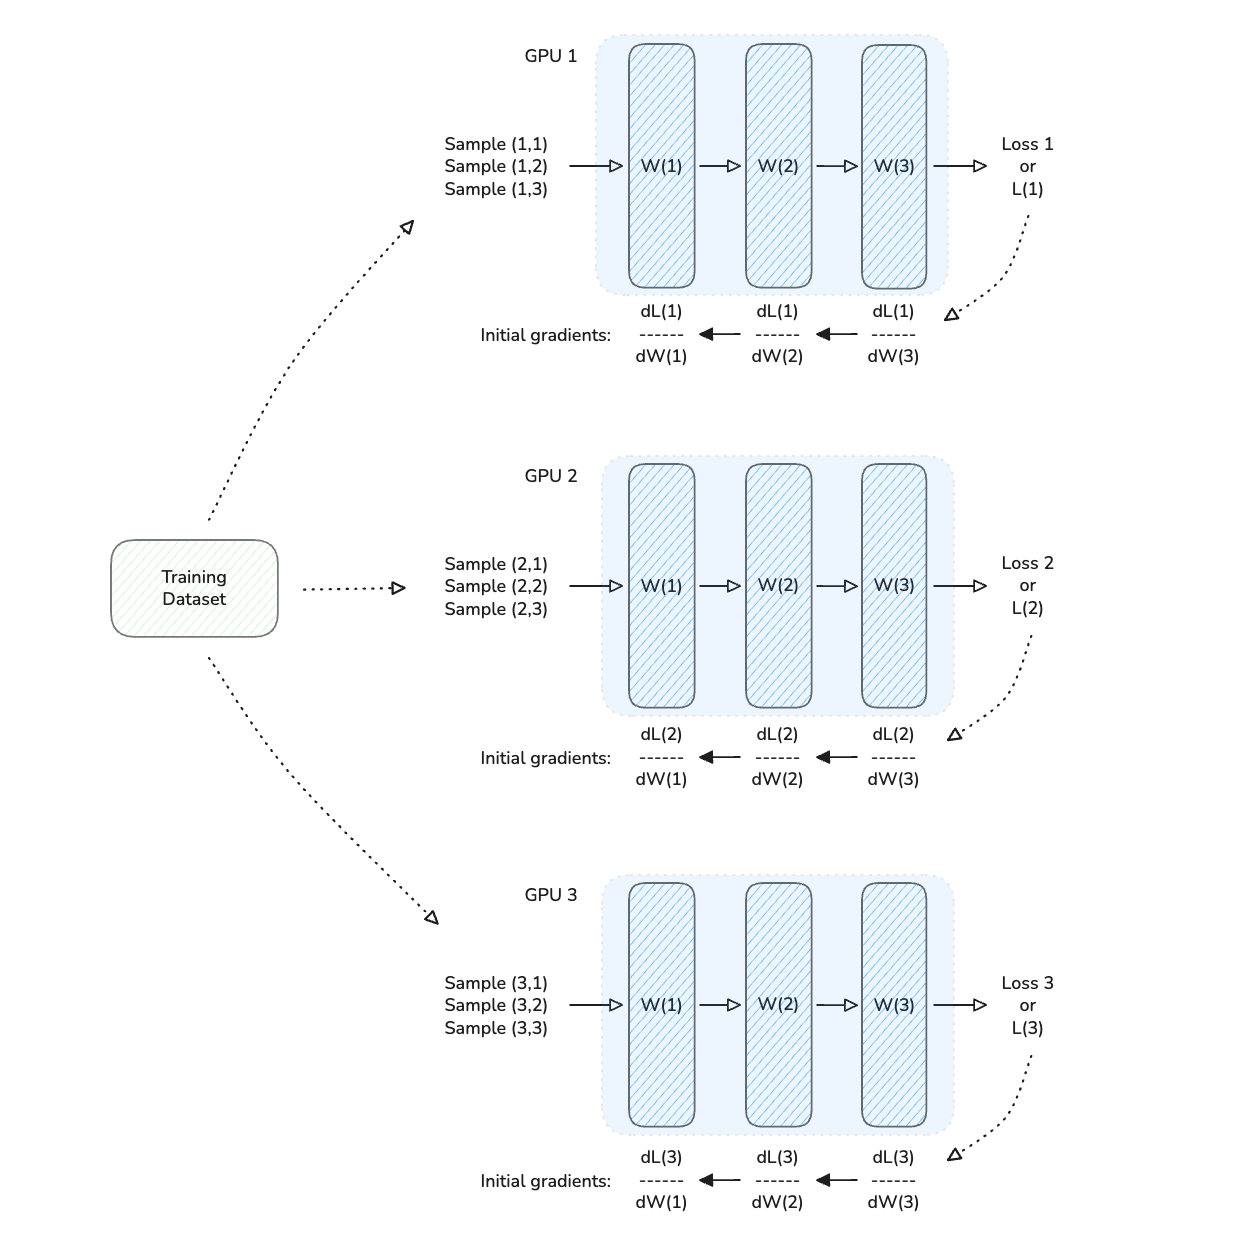
Learn to train deep learning models on multiple GPUs

Scaling Large MoE Models with Wide Expert Parallelism on NVL72 Rack ...
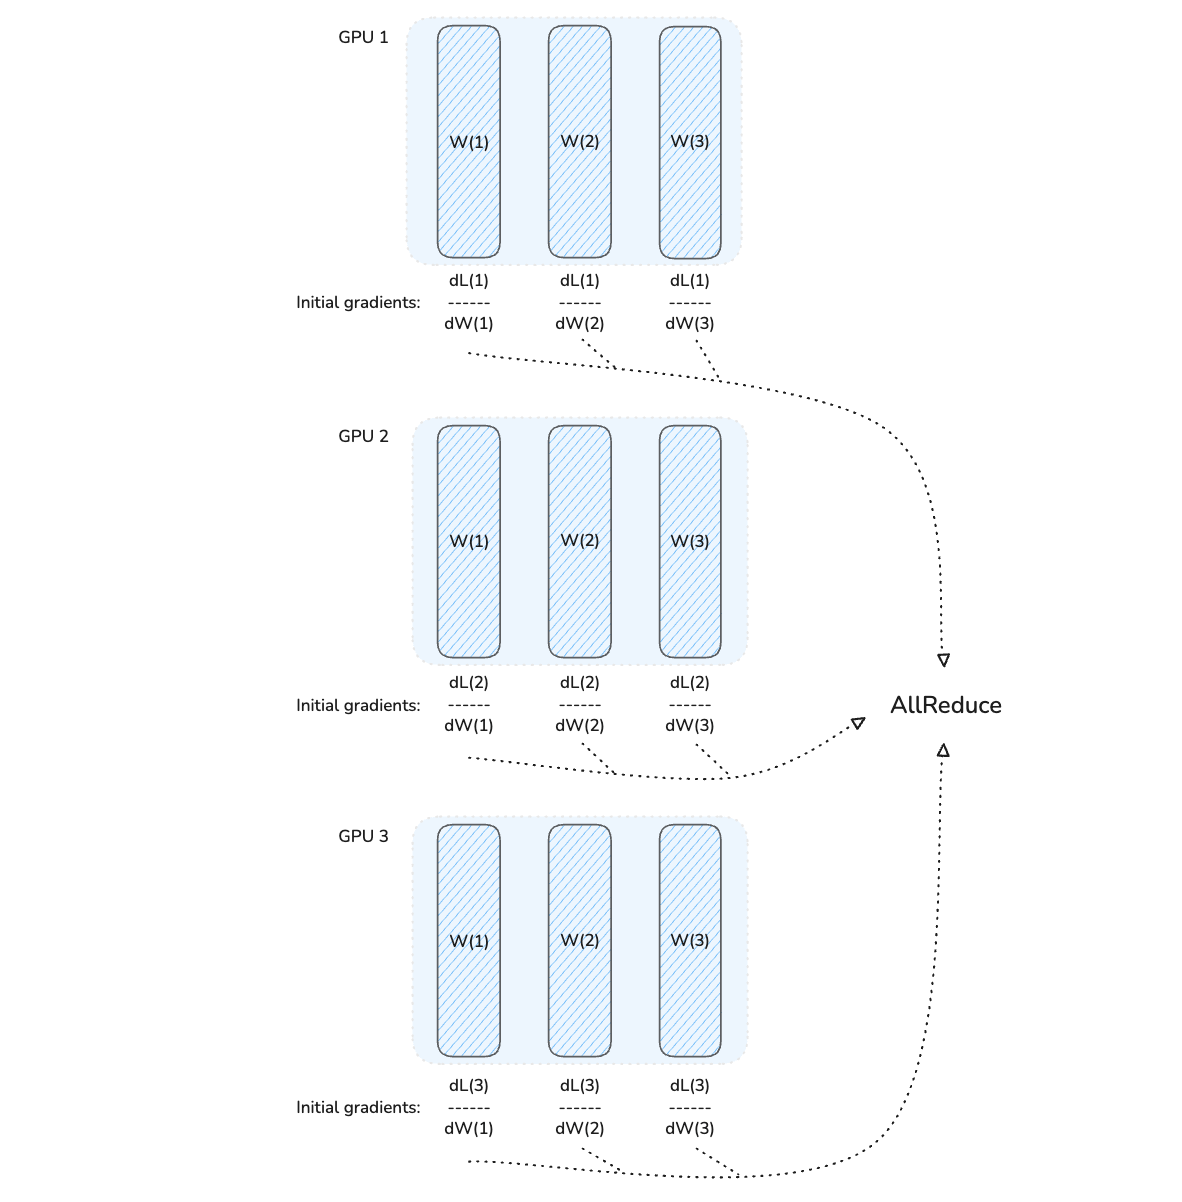
Learn to train deep learning models on multiple GPUs

Data Parallelism: How to Train Deep Learning Models on Multiple GPUs ...
Advertisement Space (300x250)
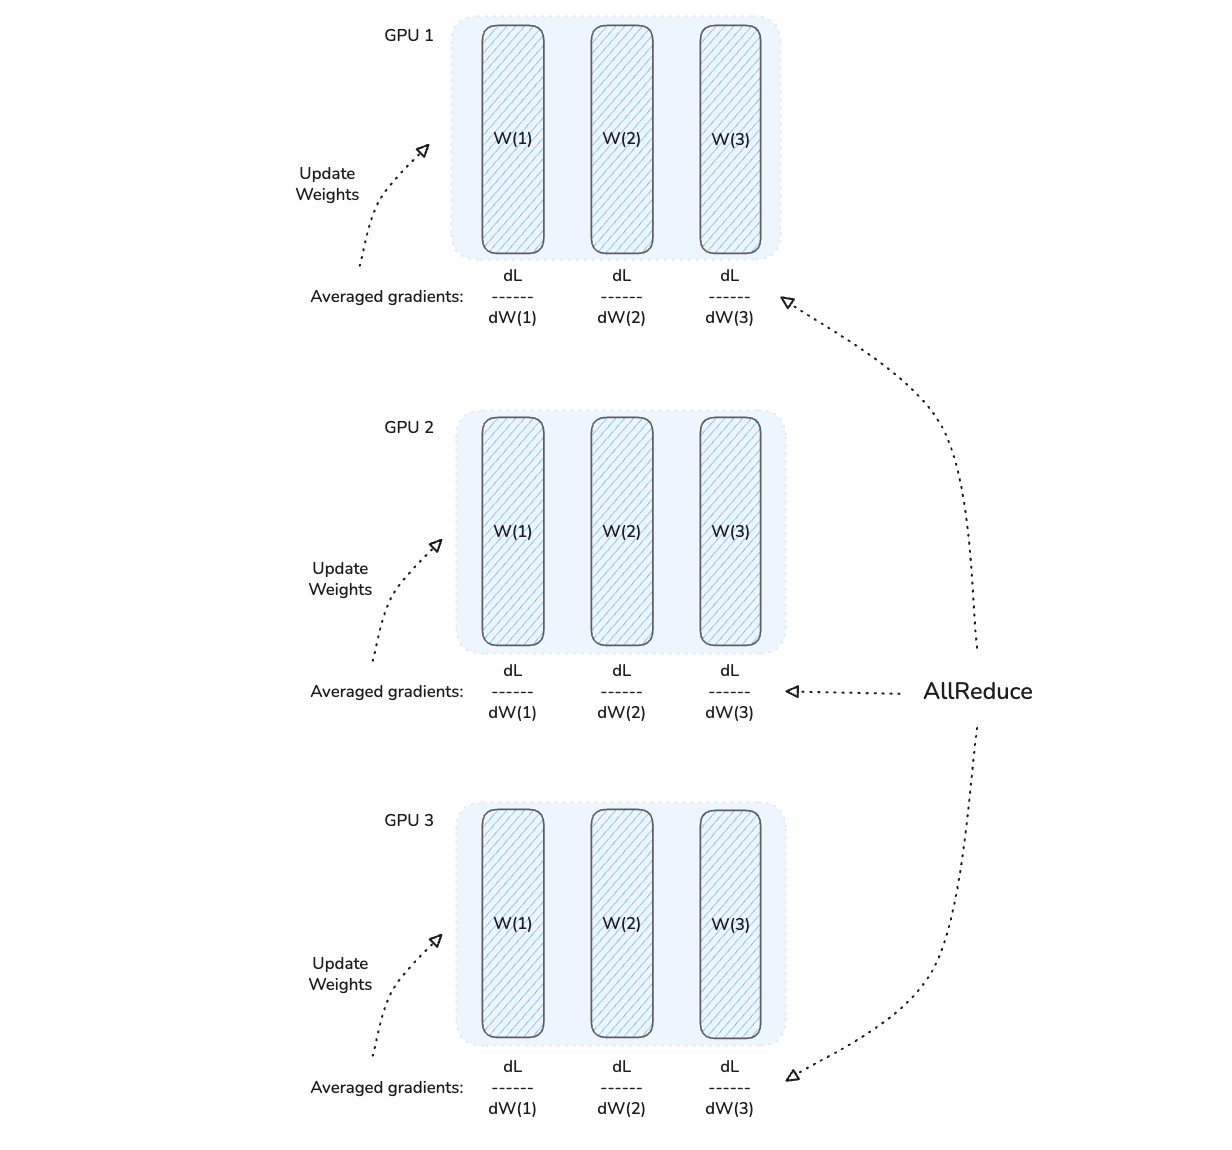
Learn to train deep learning models on multiple GPUs

Learn to train deep learning models on multiple GPUs

Parallelism Techniques for Large Language Model Training | Vinoth Kumar ...
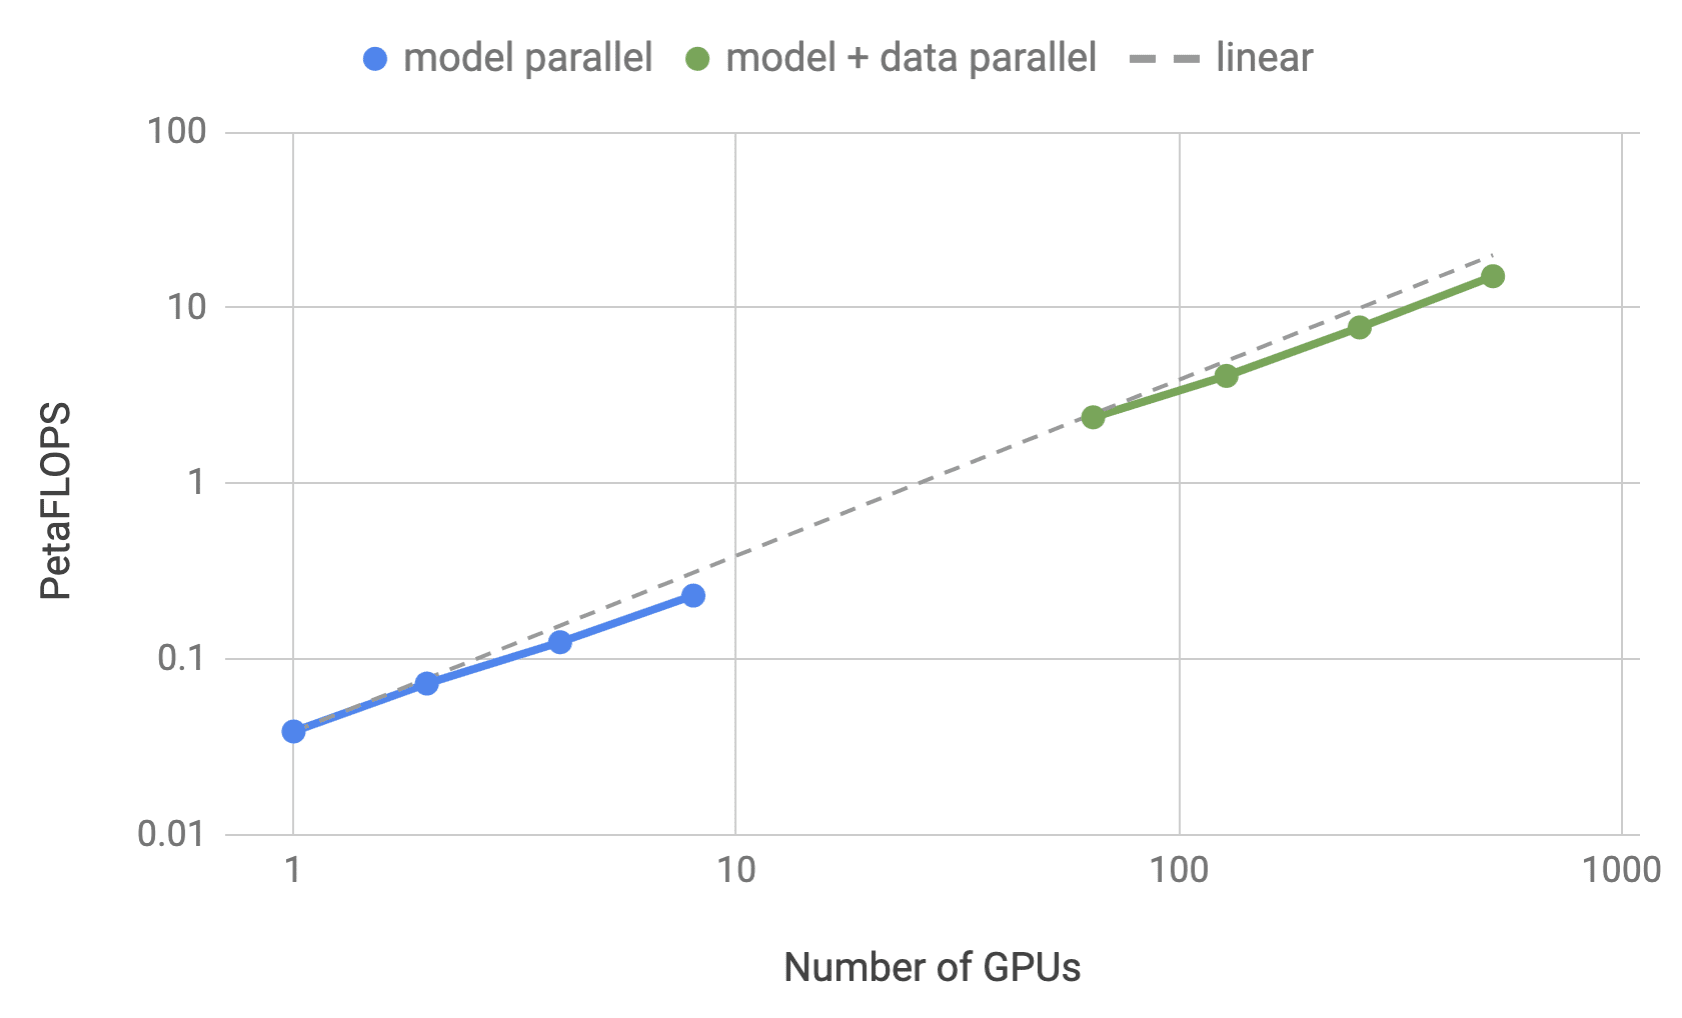
How to train a Large Language Model using limited hardware? - deepsense.ai
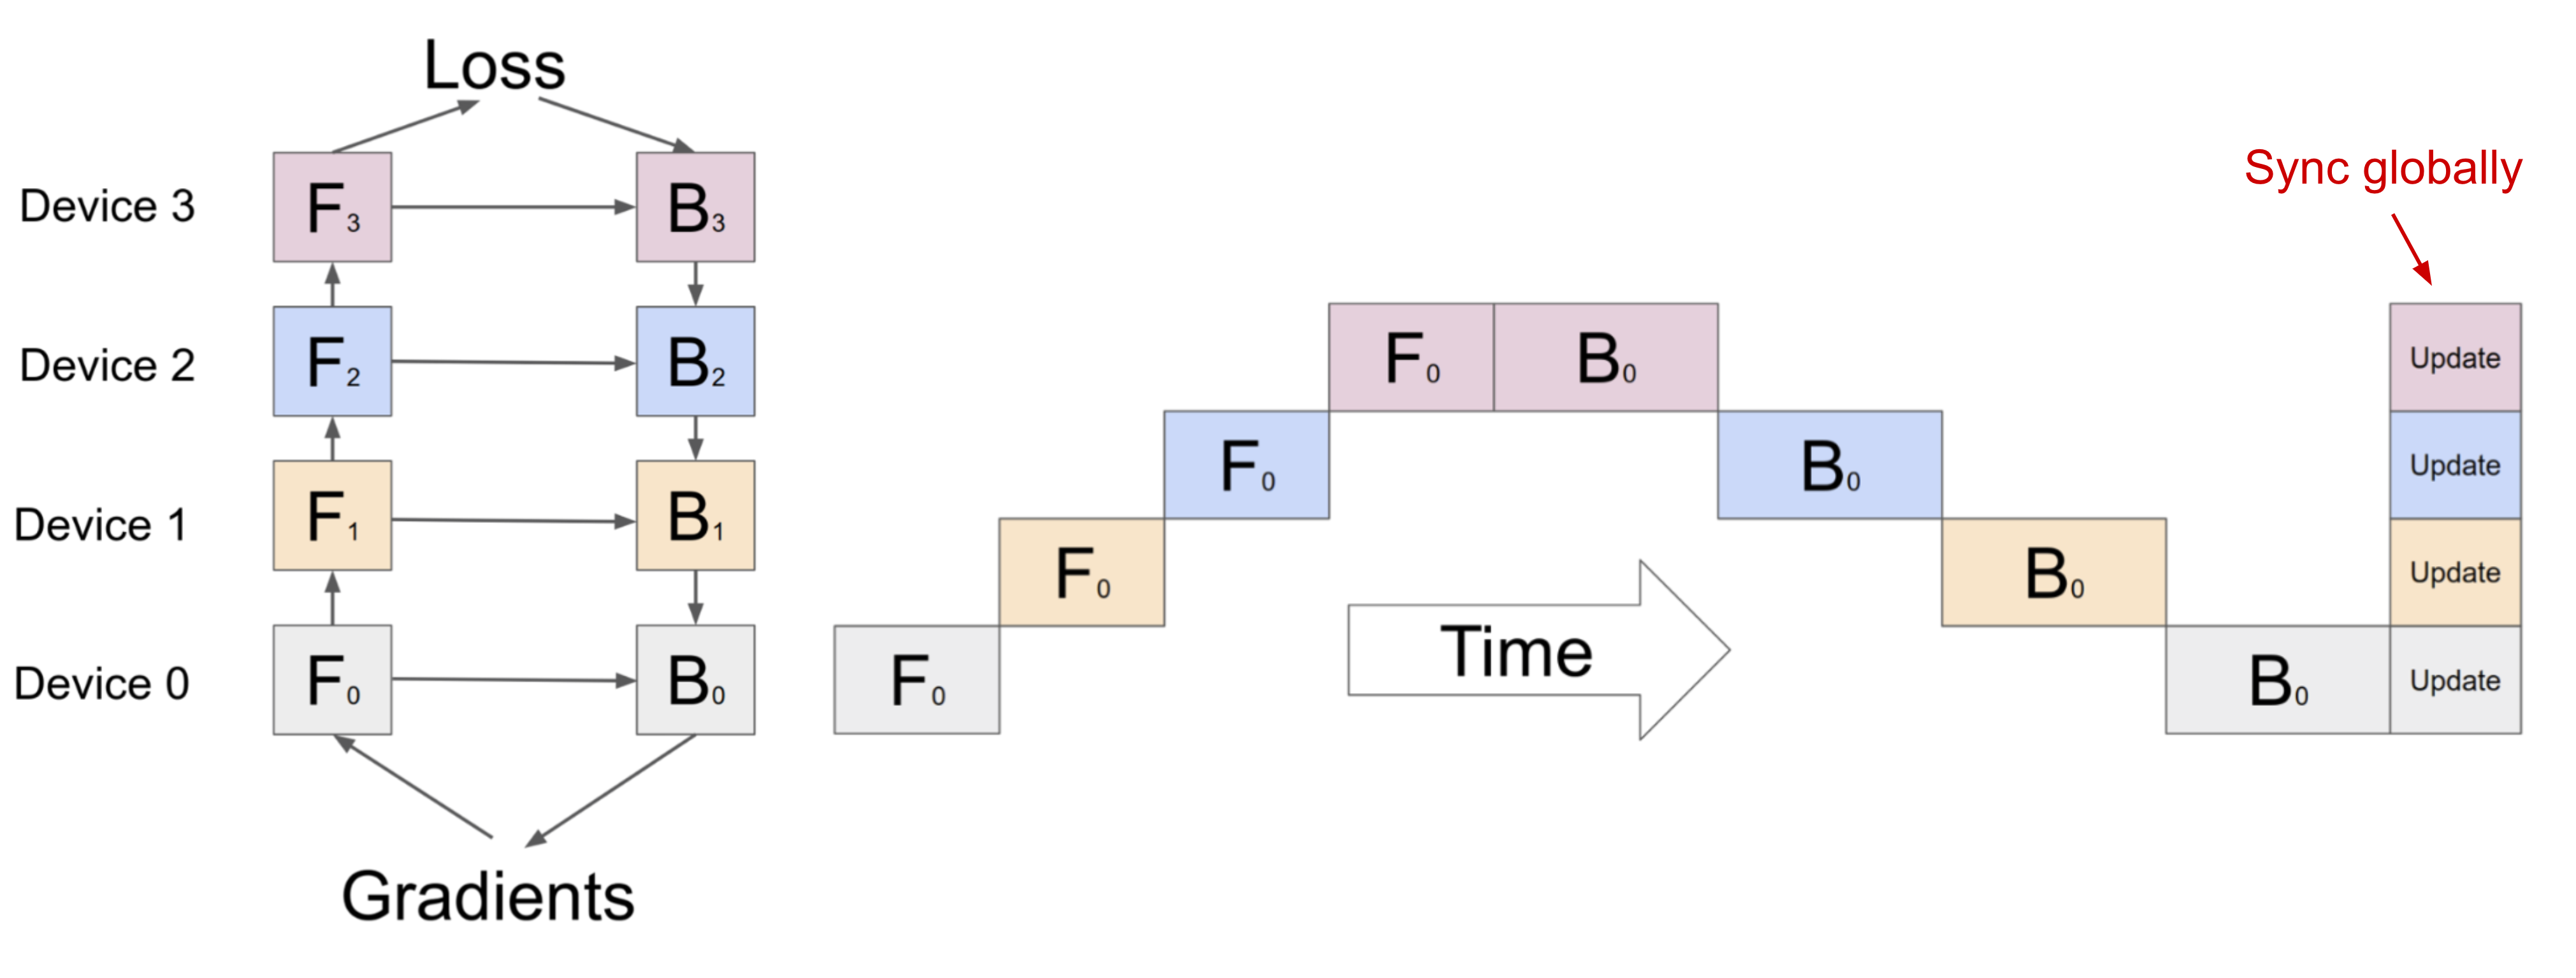
How to Train Really Large Models on Many GPUs? | Lil'Log
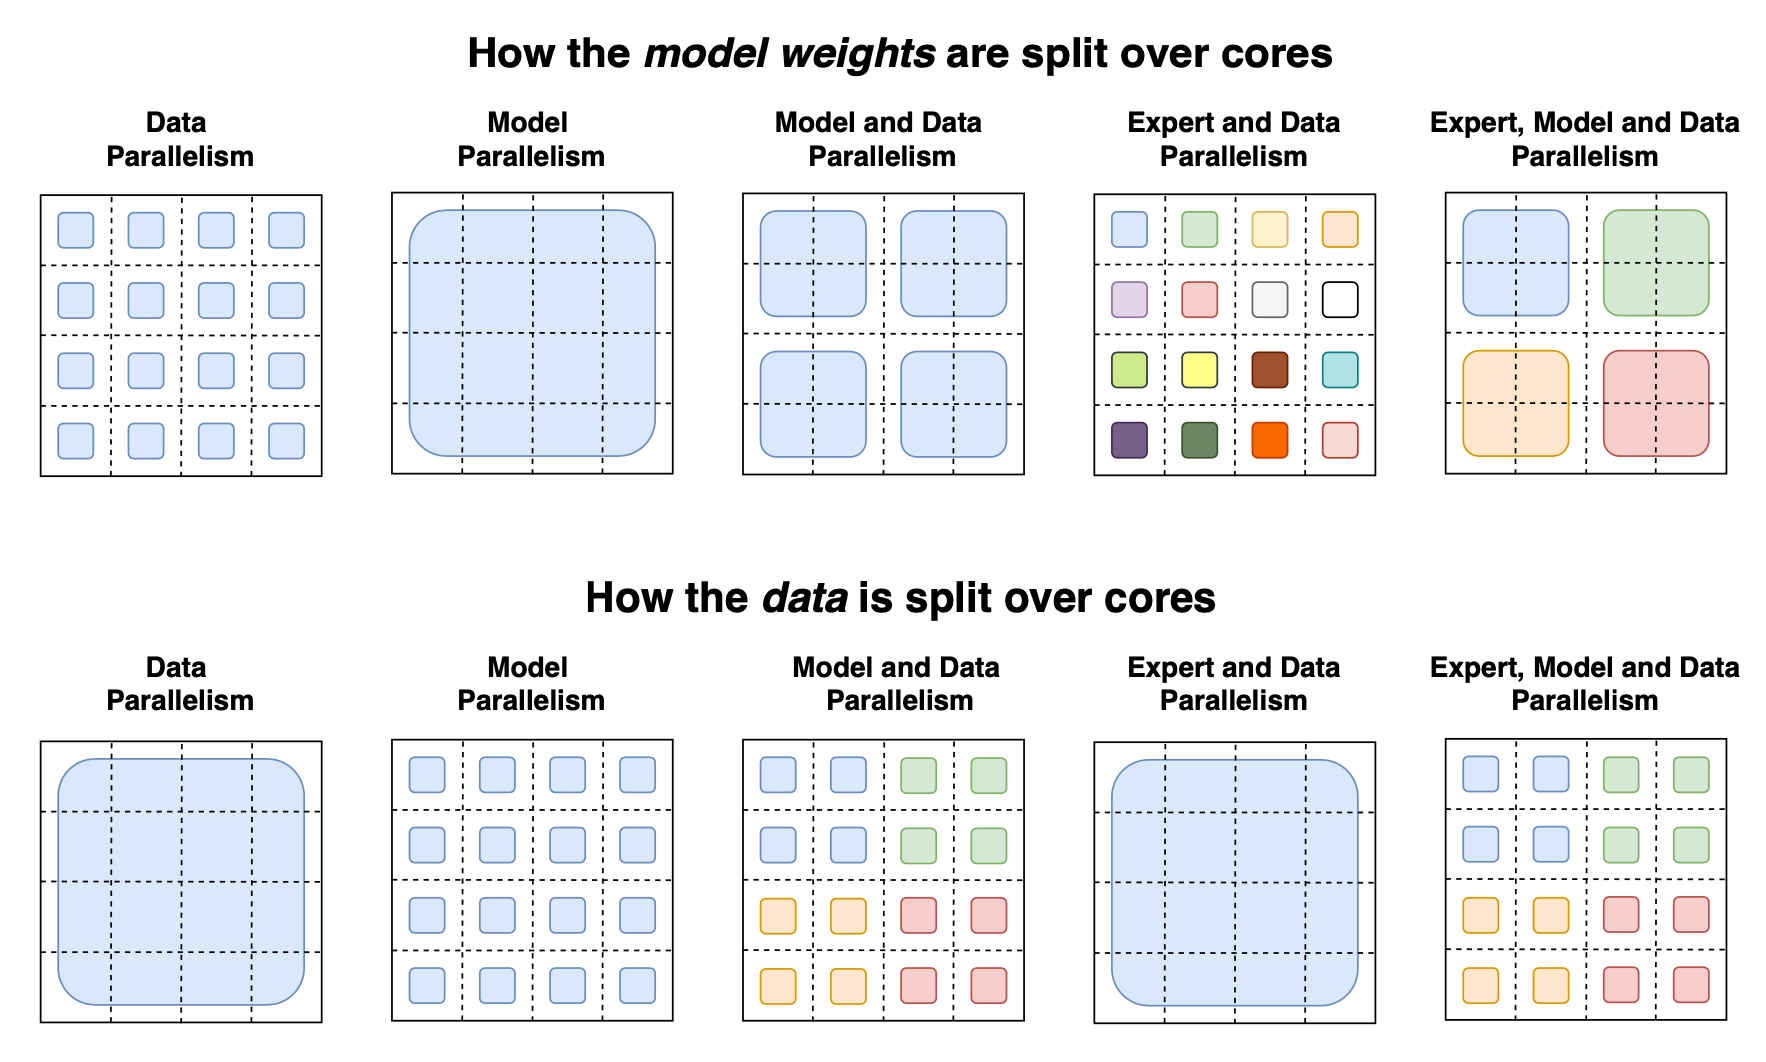
How to Train Really Large Models on Many GPUs? | Lil'Log
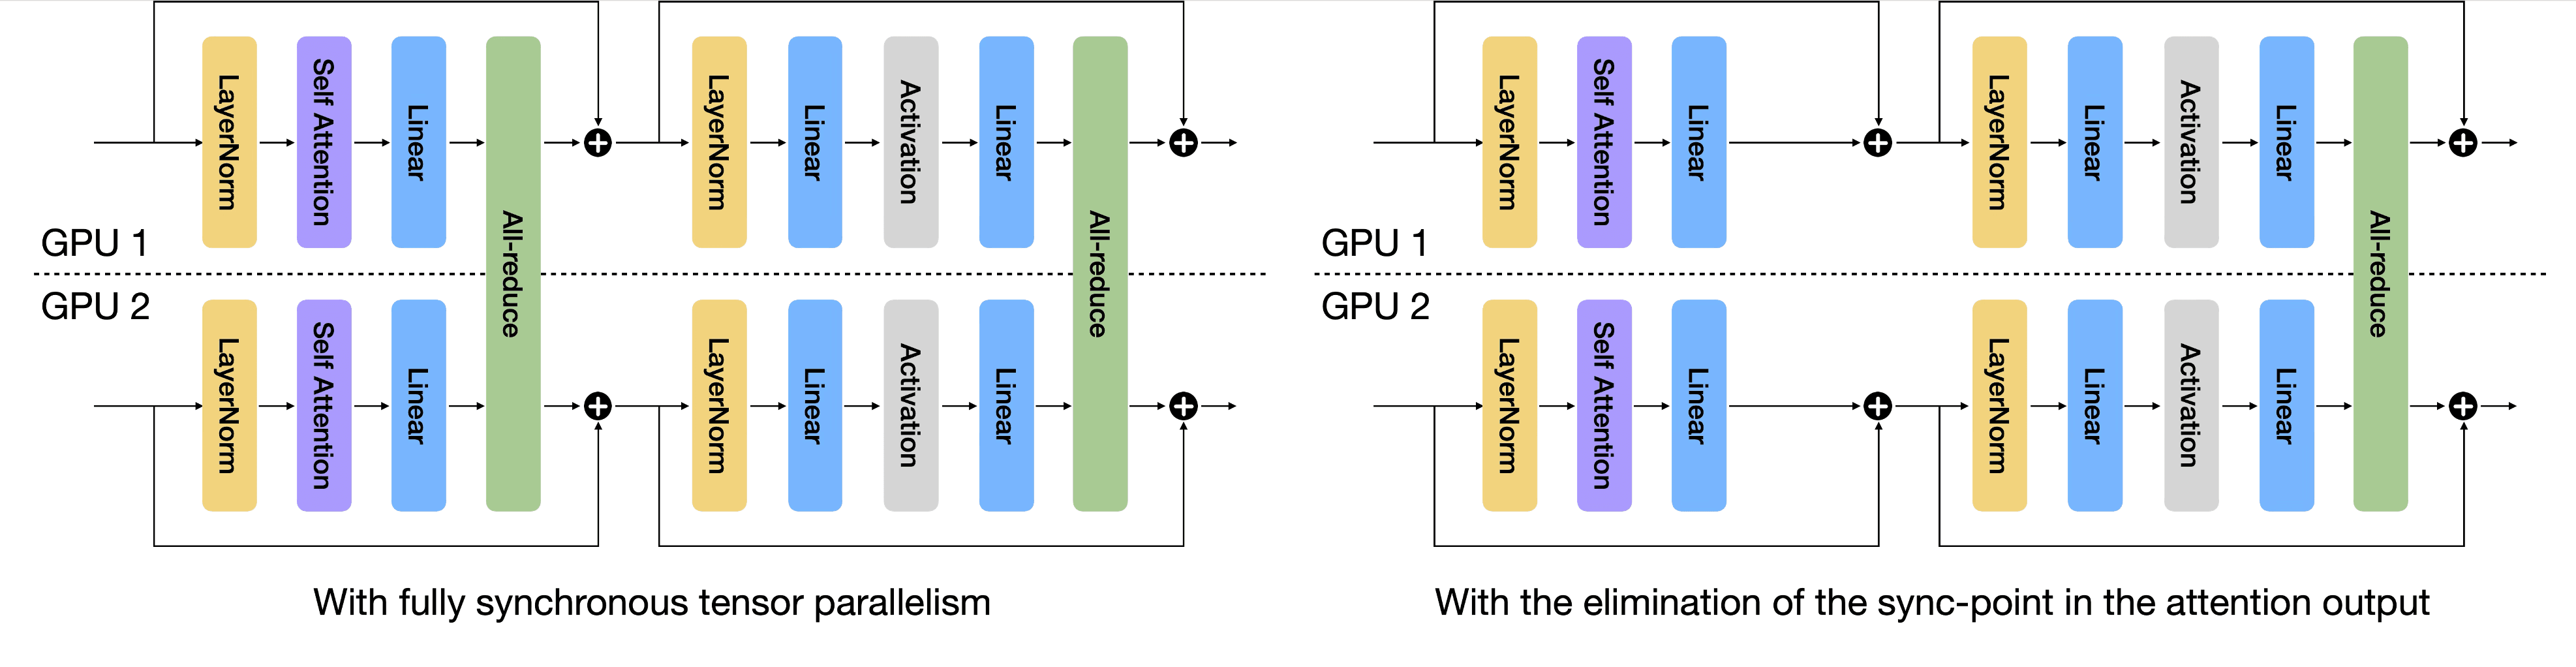
SPD: Sync-Point Drop for Efficient Tensor Parallelism of Large Language ...

13.5. Training on Multiple GPUs — Dive into Deep Learning 1.0.3 ...

Perception Model Training for Autonomous Vehicles with Tensor ...
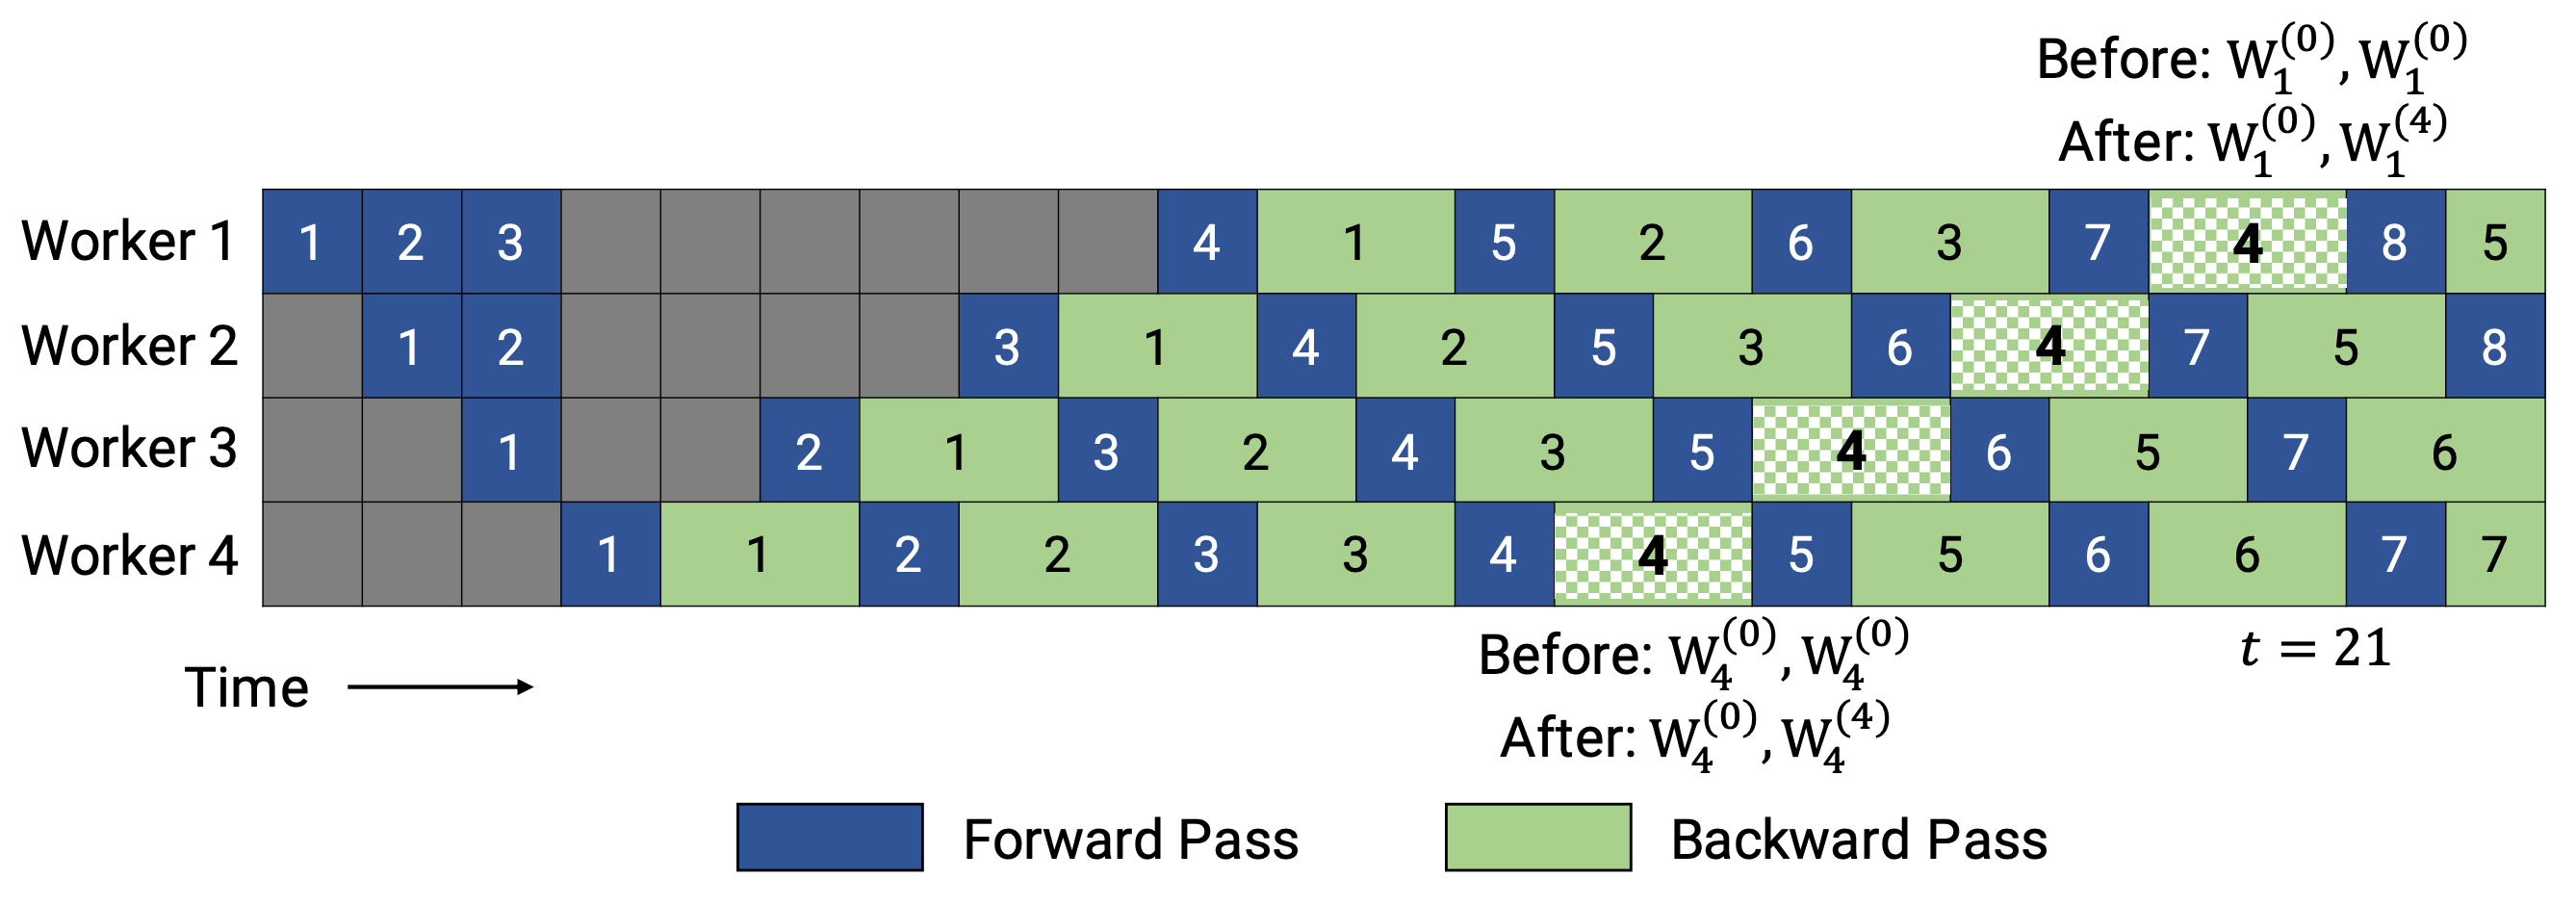
How to Train Really Large Models on Many GPUs? | Lil'Log
Advertisement Space (336x280)

(a)Training process on data parallelism method in [7] using two GPUs ...

Train 175+ billion parameter NLP models with model parallel additions ...

Time breakdown for tensor parallel plans on T5-large model on 8 and 16 ...

Parallelizing Deep Learning on GPUs: Model Parallelism

Tensor Parallelism
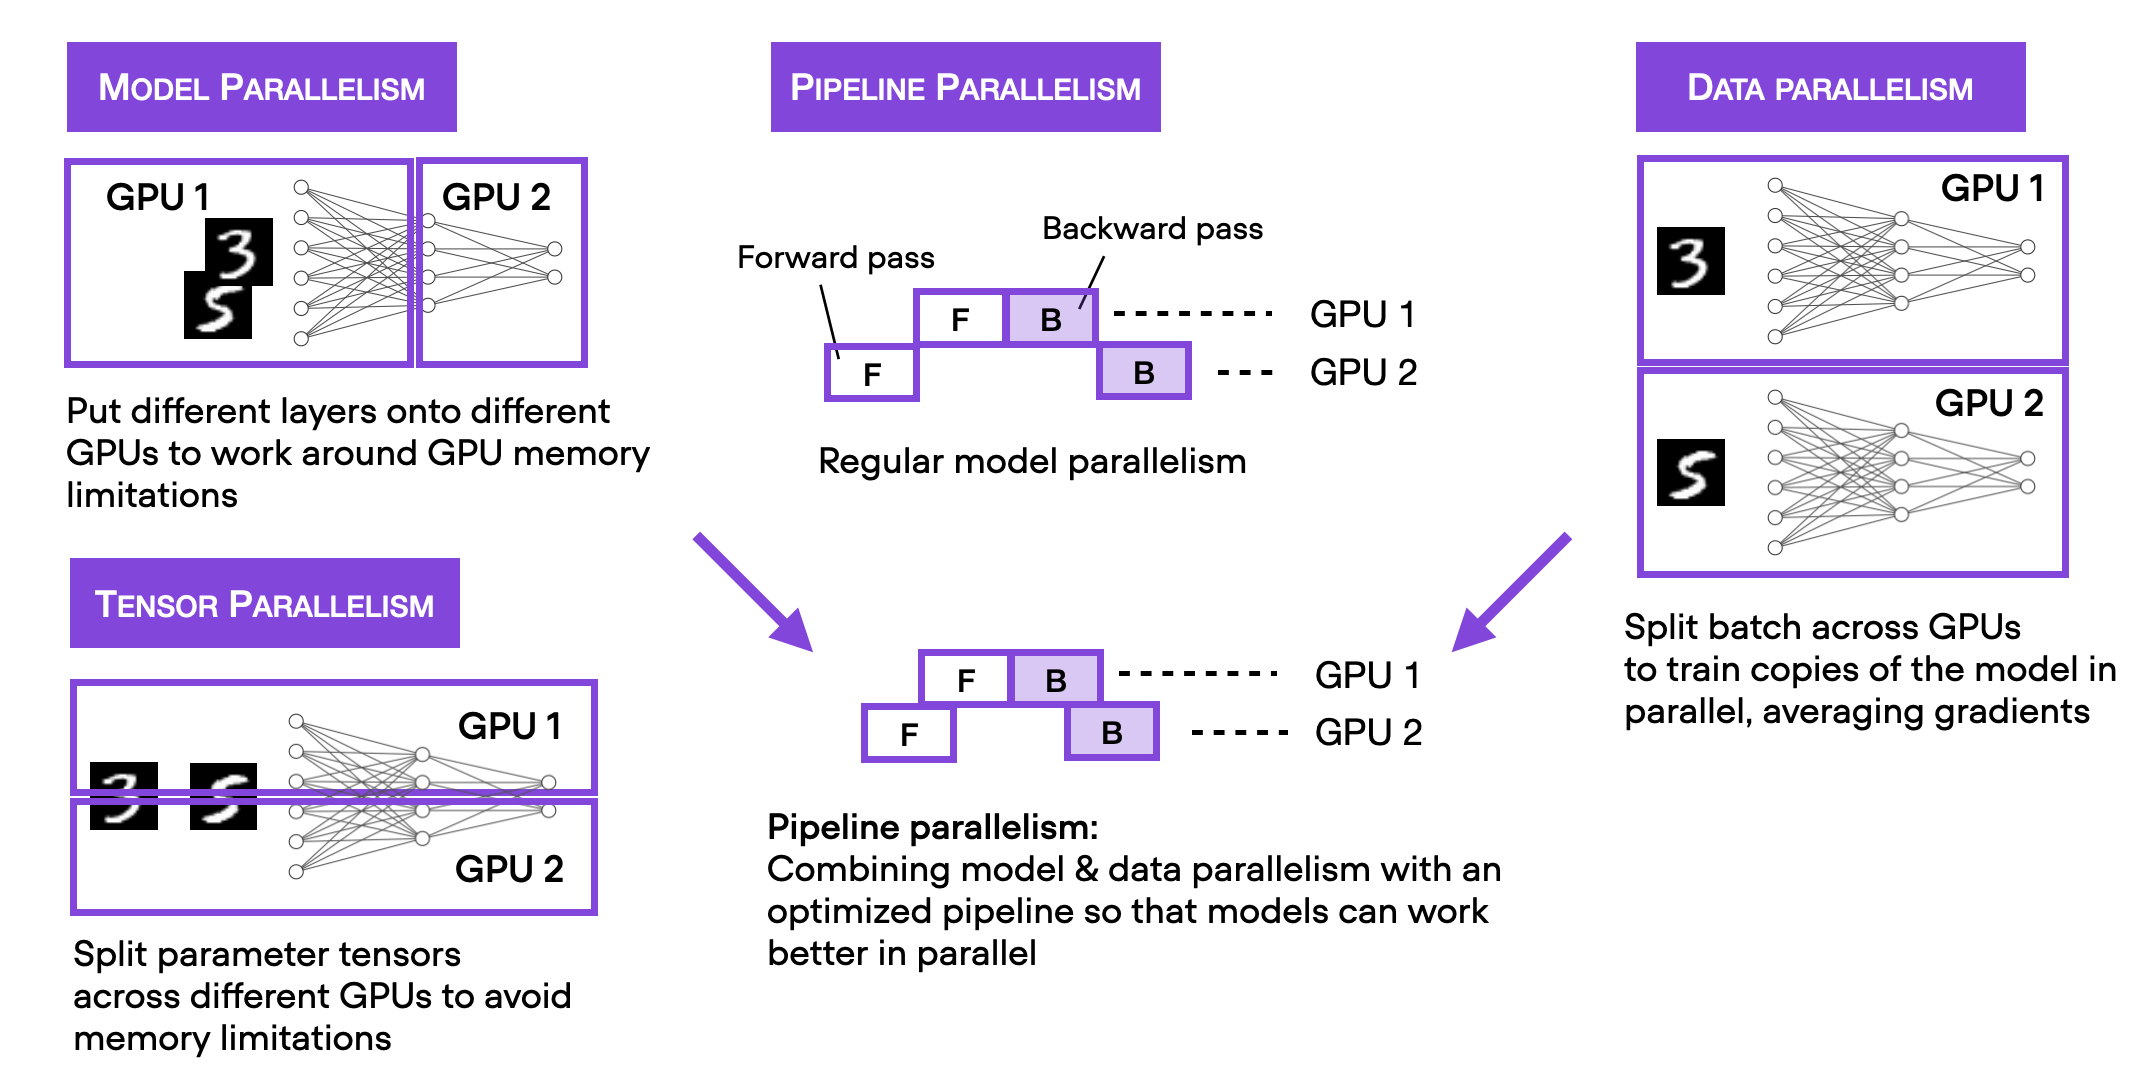
Some Techniques To Make Your PyTorch Models Train (Much) Faster ...

Data Parallelism vs Model Parallelism in AI Training

Parallelism and Memory Optimization Techniques for Training Large ...

Data Parallelism vs Model Parallelism in AI Training
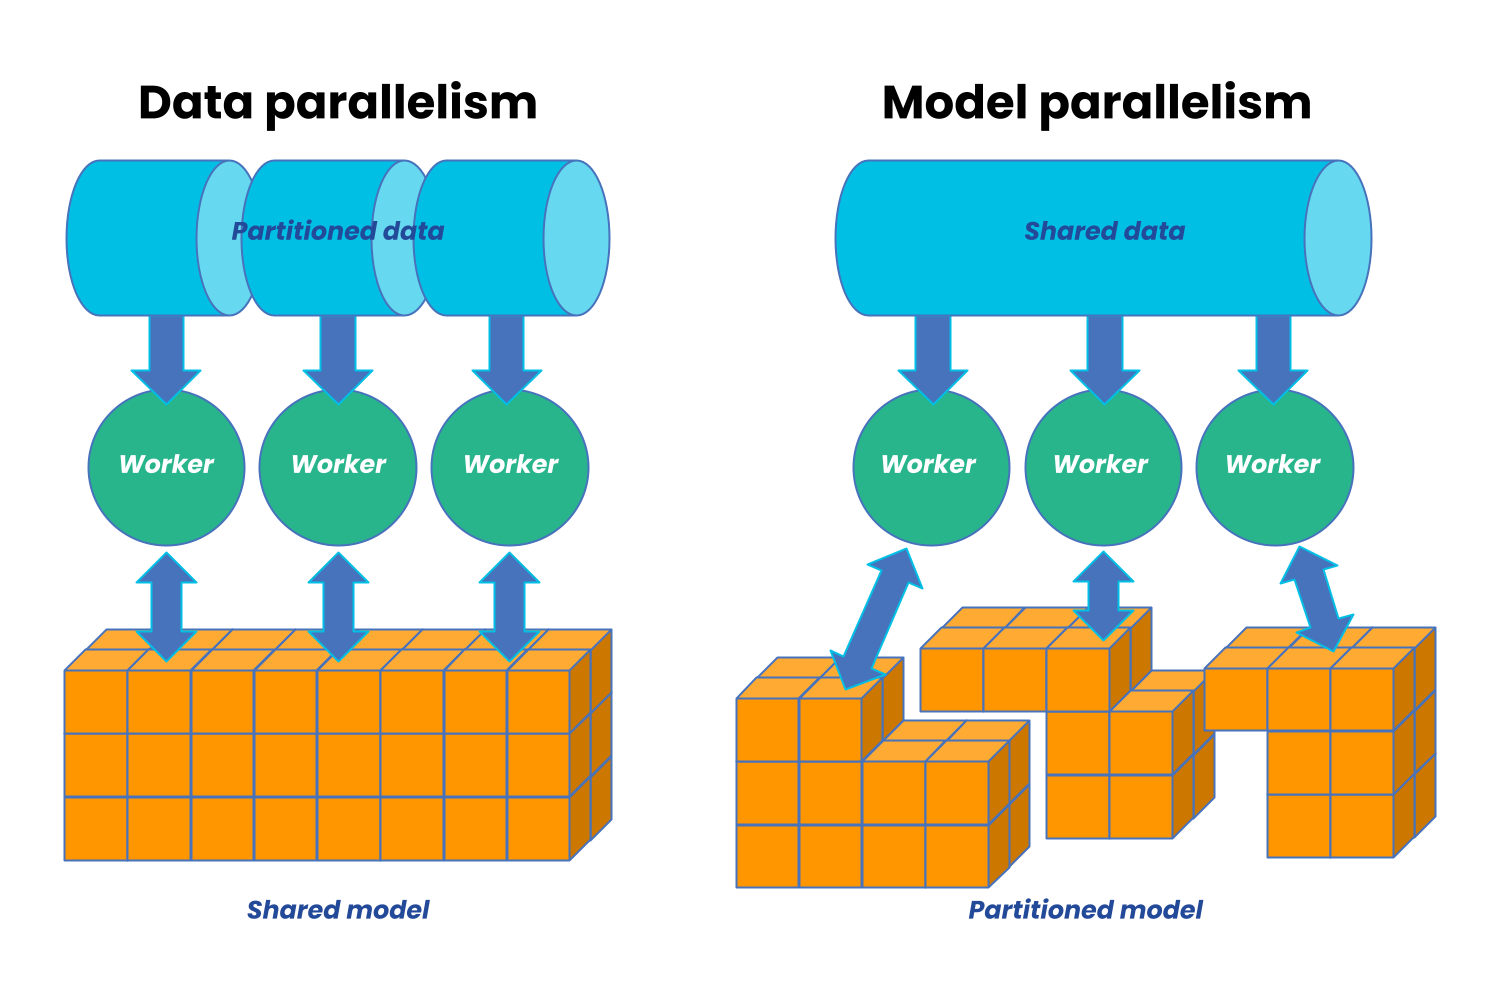
Multi-Gpu Training In Pytorch. Data And Model Parallelism – OBEA
Advertisement Space (336x280)
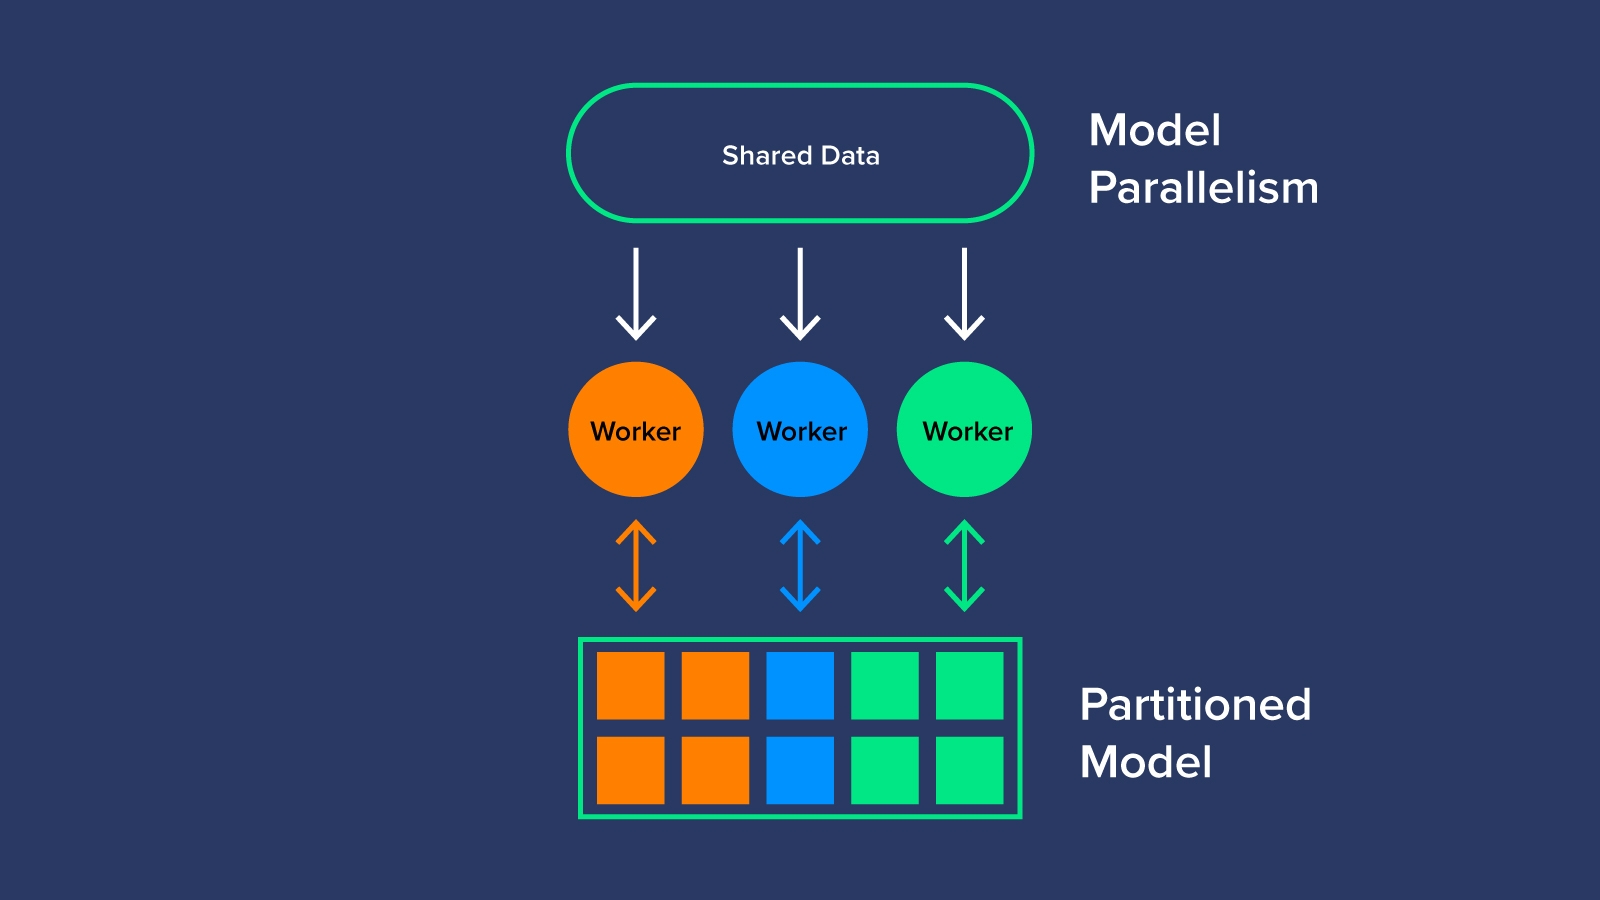
Why and How to Use Multiple GPUs for Distributed Training | Exxact Blog
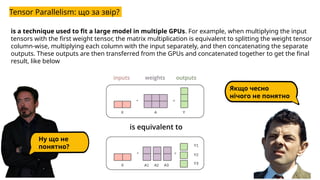
Kateryna Hrytsaienko: Deploy Gemma2 with multiple LoRA adapters (UA) | PPTX
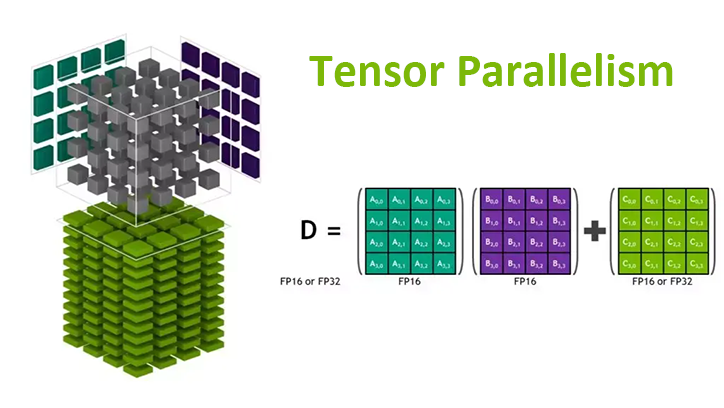
Tensor Parallelism - NADDOD Blog
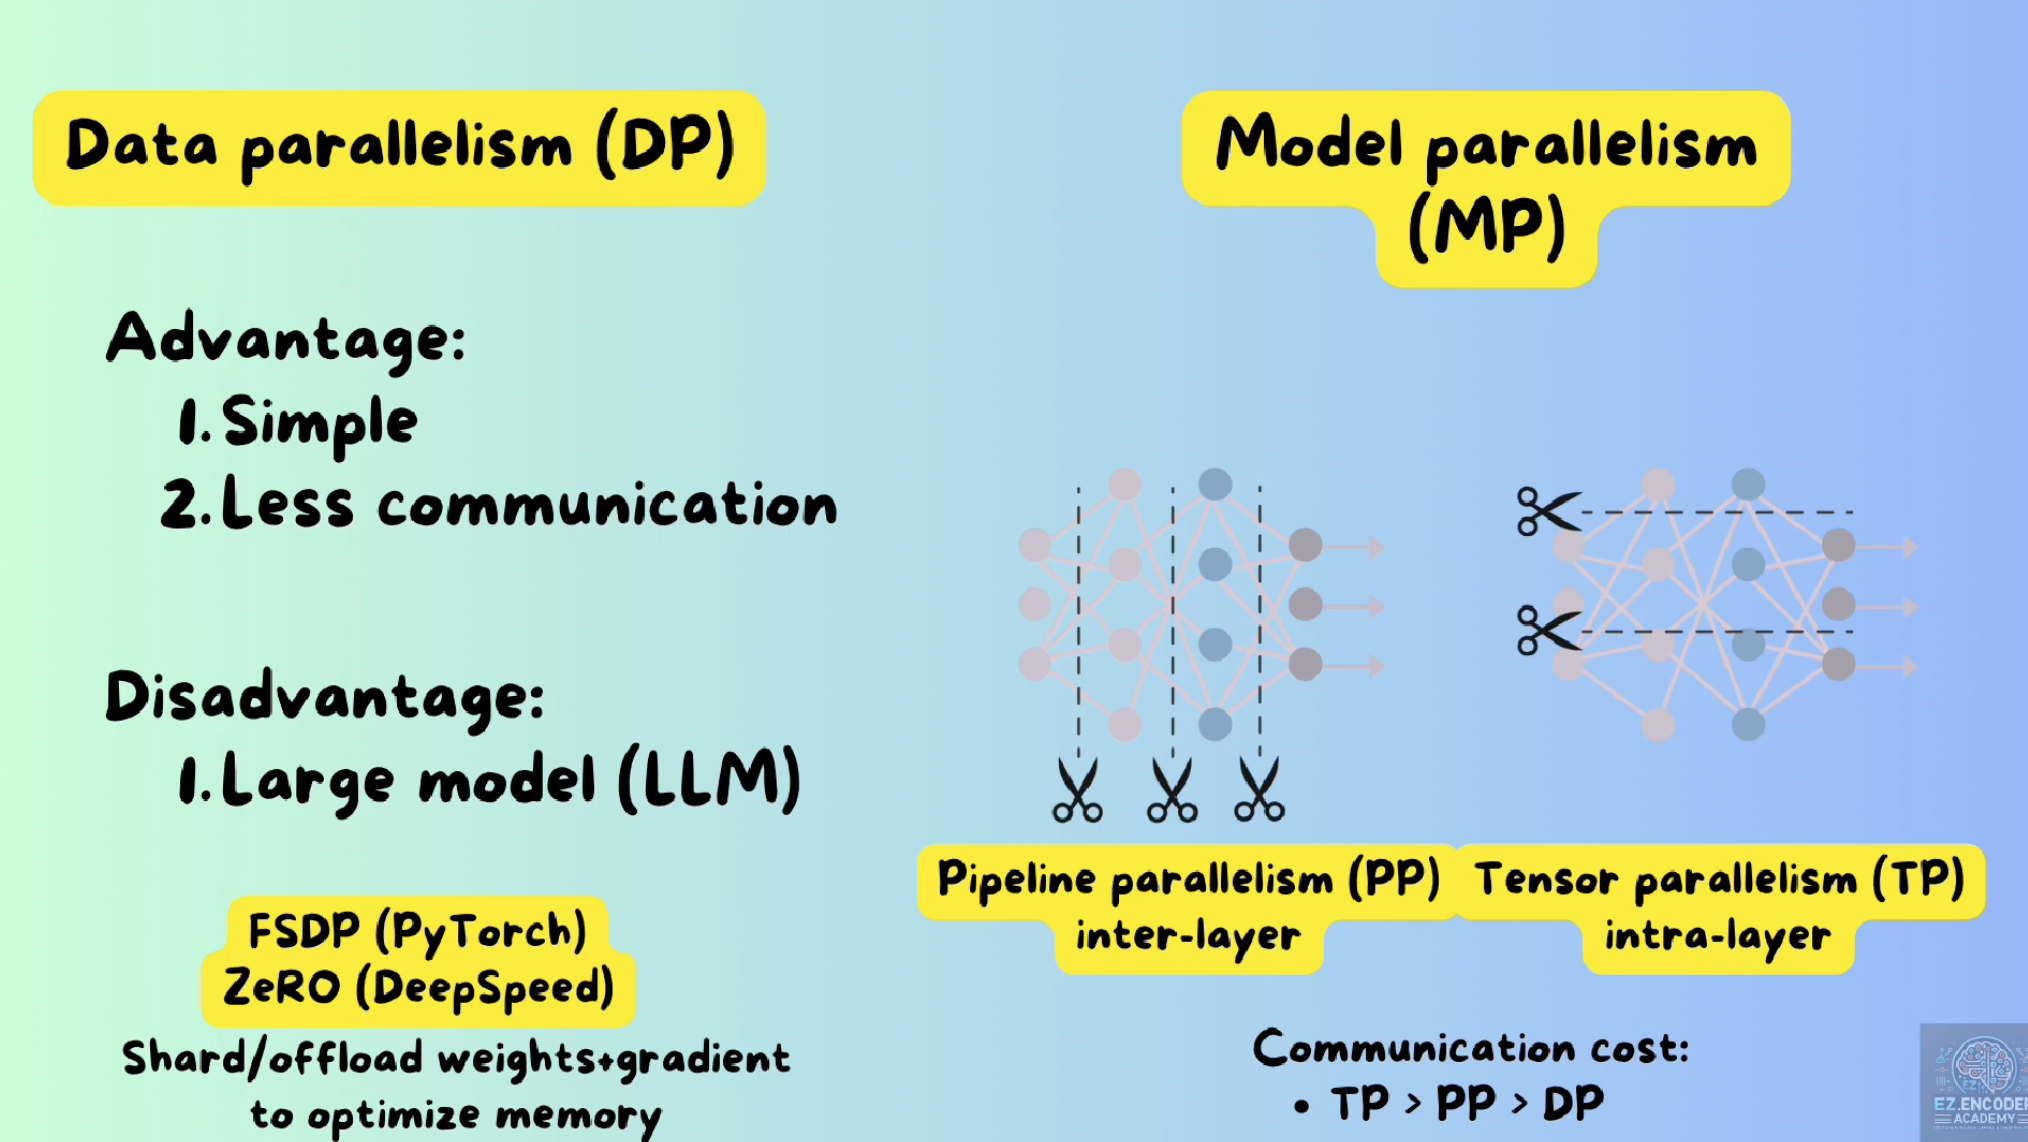
Tensor Parallelism and Pipeline Parallelism - Kyle’s Tech Blog
Maximizing Business Potential with Large Language Models (LLMs)

PyTorch 101 Memory Management and Using Multiple GPUs | DigitalOcean