
Triton Gpu Segmentfault

人工智能 - Triton 实战:从零开始构建一个 GPU 序列化算子-基础实现 - 个人文章 - SegmentFault 思否

人工智能 - Triton 实战:从零开始构建一个 GPU 序列化算子-基础实现 - 个人文章 - SegmentFault 思否

人工智能 - Triton 实战:从零开始构建一个 GPU 序列化算子-基础实现 - 个人文章 - SegmentFault 思否

人工智能 - 首个完整 Triton 中文文档上线!开启 GPU 推理加速新时代 - 超神经HyperAI - SegmentFault 思否

人工智能 - 首个完整 Triton 中文文档上线!开启 GPU 推理加速新时代 - 超神经HyperAI - SegmentFault 思否

人工智能 - 从零开始用自定义 Triton 内核编写 FlashAttention-2 - deephub - SegmentFault 思否

AMD AI 架构师张宁:多视角解析 AMD Triton 编译器,助力开源生态建设 - 超神经HyperAI - SegmentFault 思否

AMD AI 架构师张宁:多视角解析 AMD Triton 编译器,助力开源生态建设 - 超神经HyperAI - SegmentFault 思否

人工智能 - 面向国产 DCU 加速卡的 LLM Agent 驱动 GPU 内核优化框架适配与验证 - 个人文章 - SegmentFault 思否
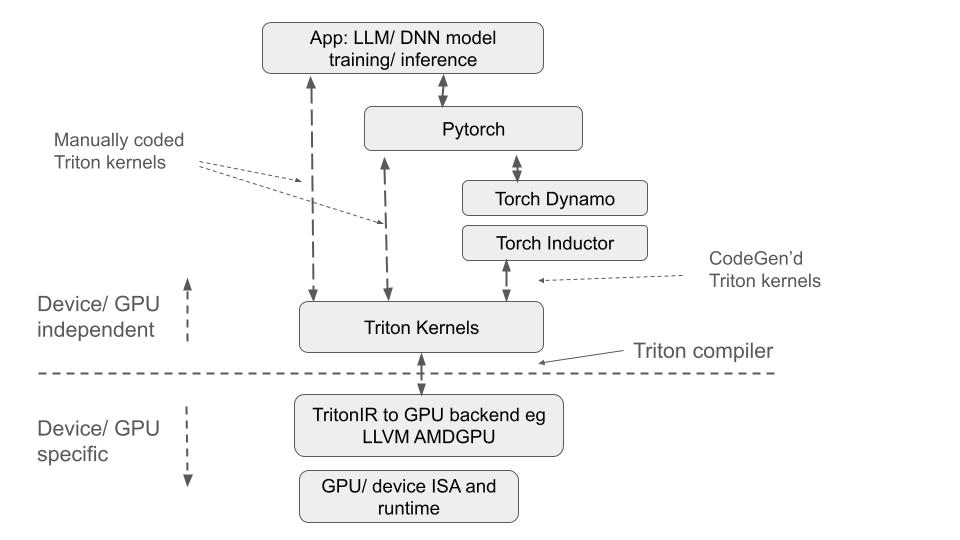
Democratizing AI Accelerators and GPU Kernel Programming using Triton ...
Advertisement Space (300x250)
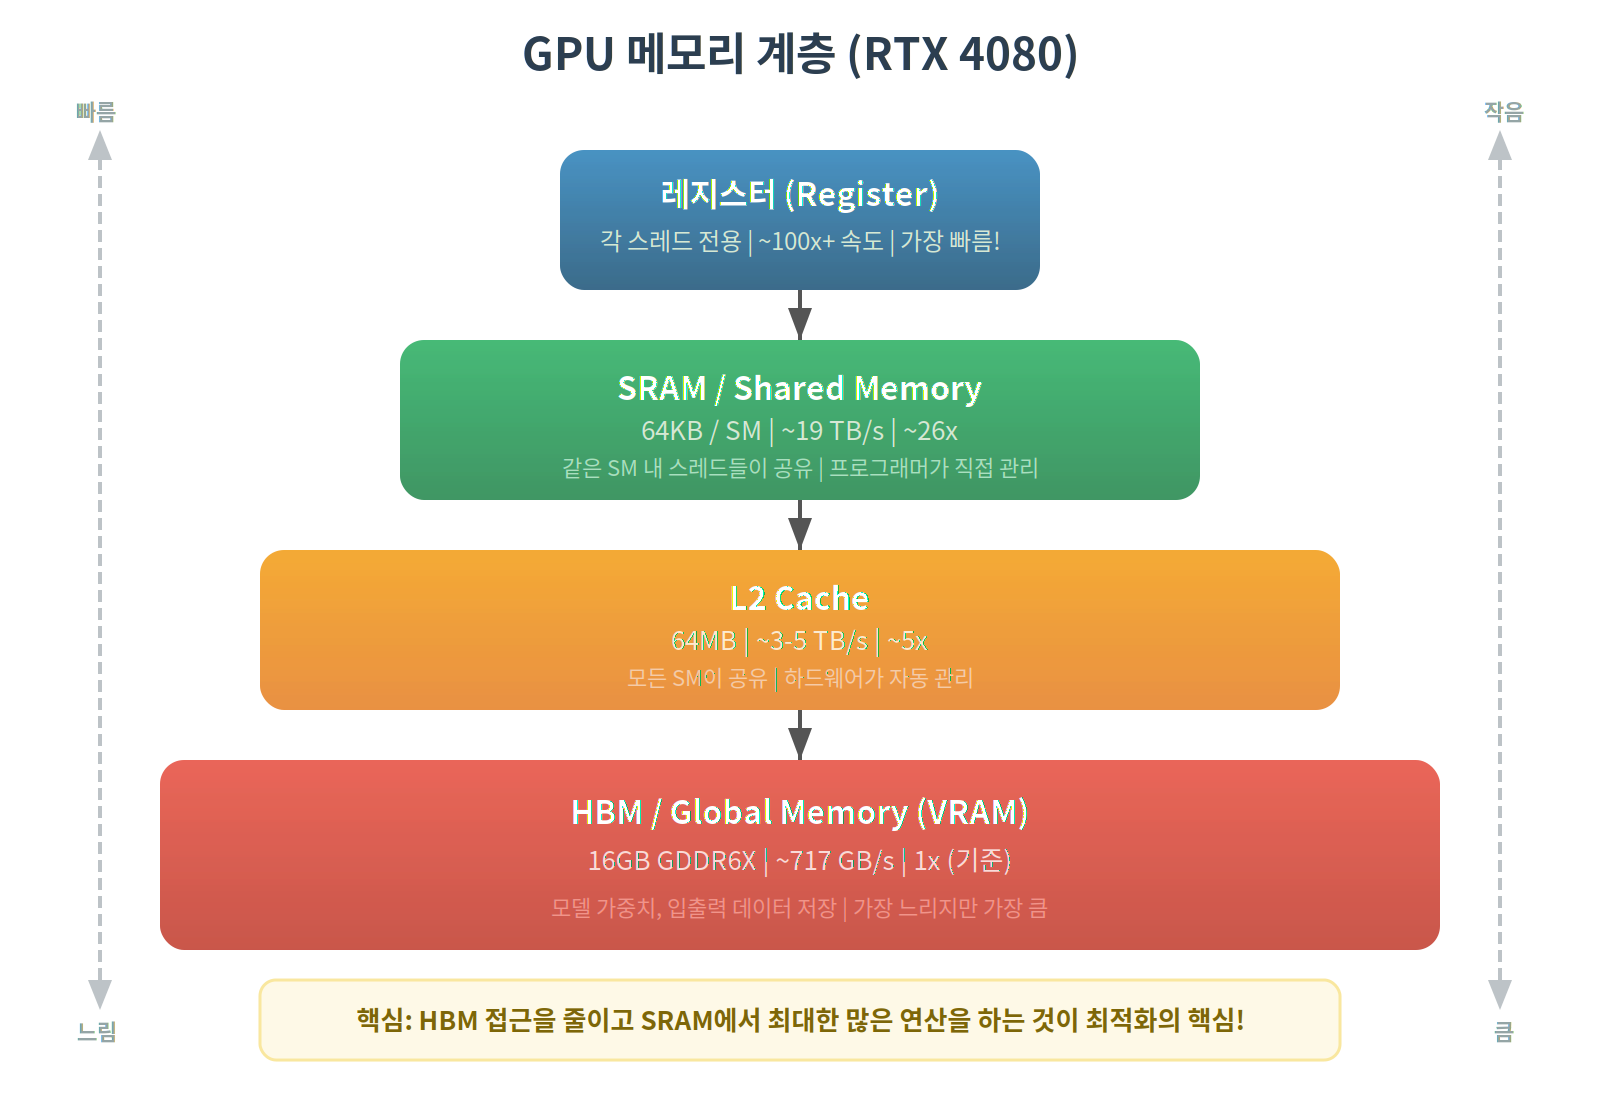
Triton 00: GPU 기초 — Triton을 시작하기 전에 알아야 할 것들 | Wonbeom Jang
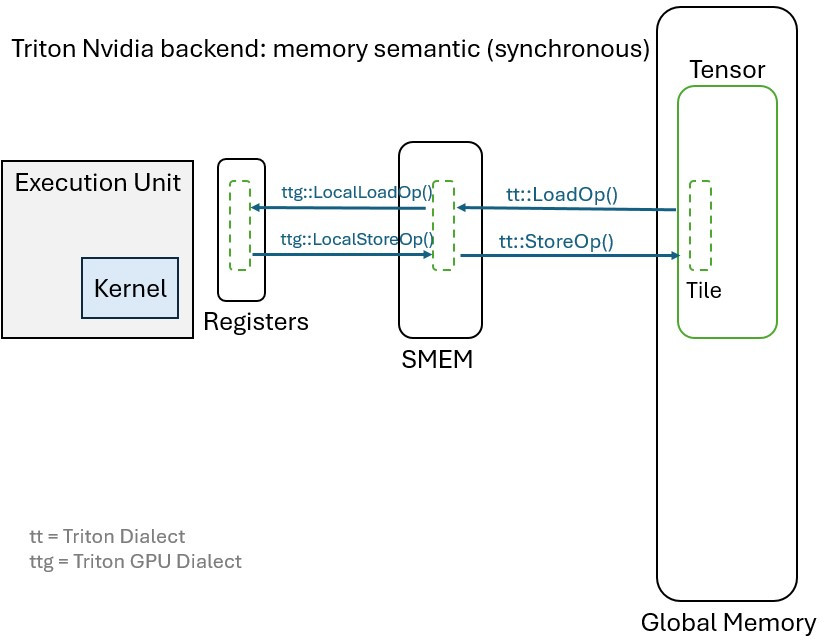
Improving Triton FlashAttention Performance on Intel GPU - Codeplay ...
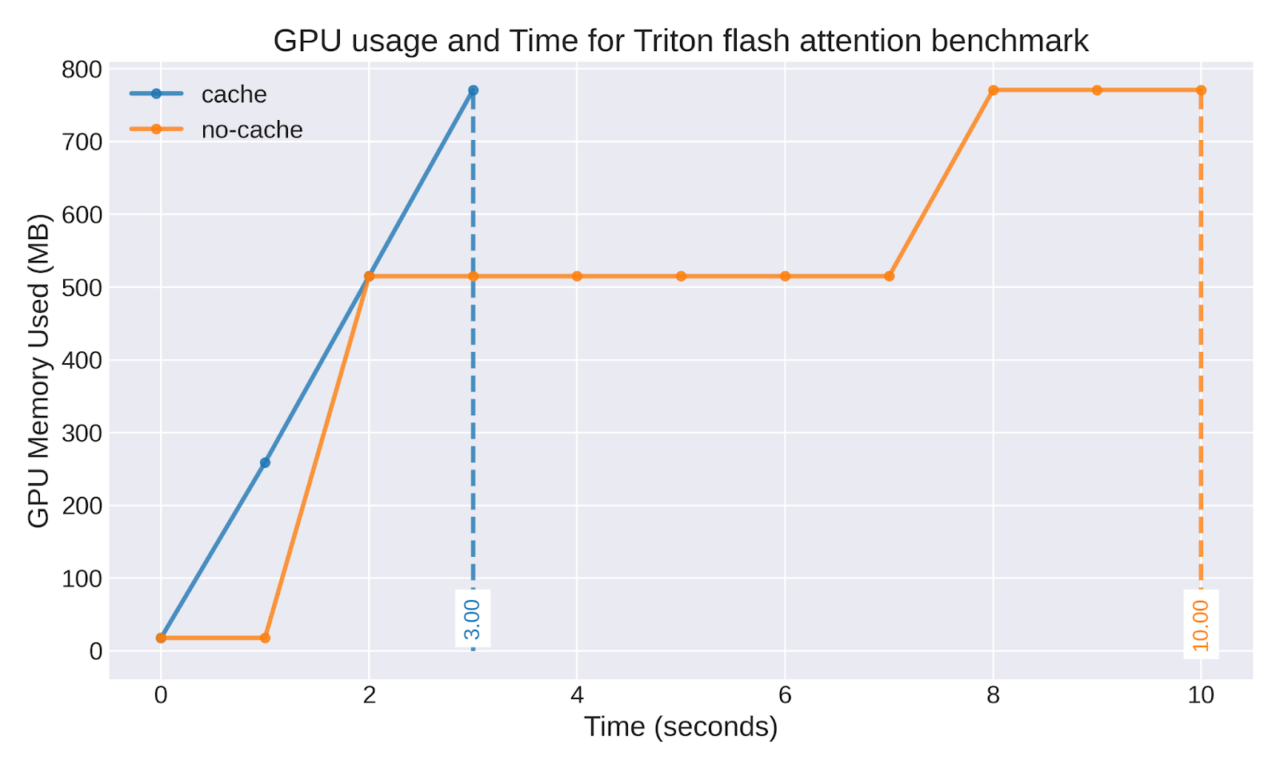
Understanding Triton Cache: Optimizing GPU Kernel Compilation - Red Hat ...
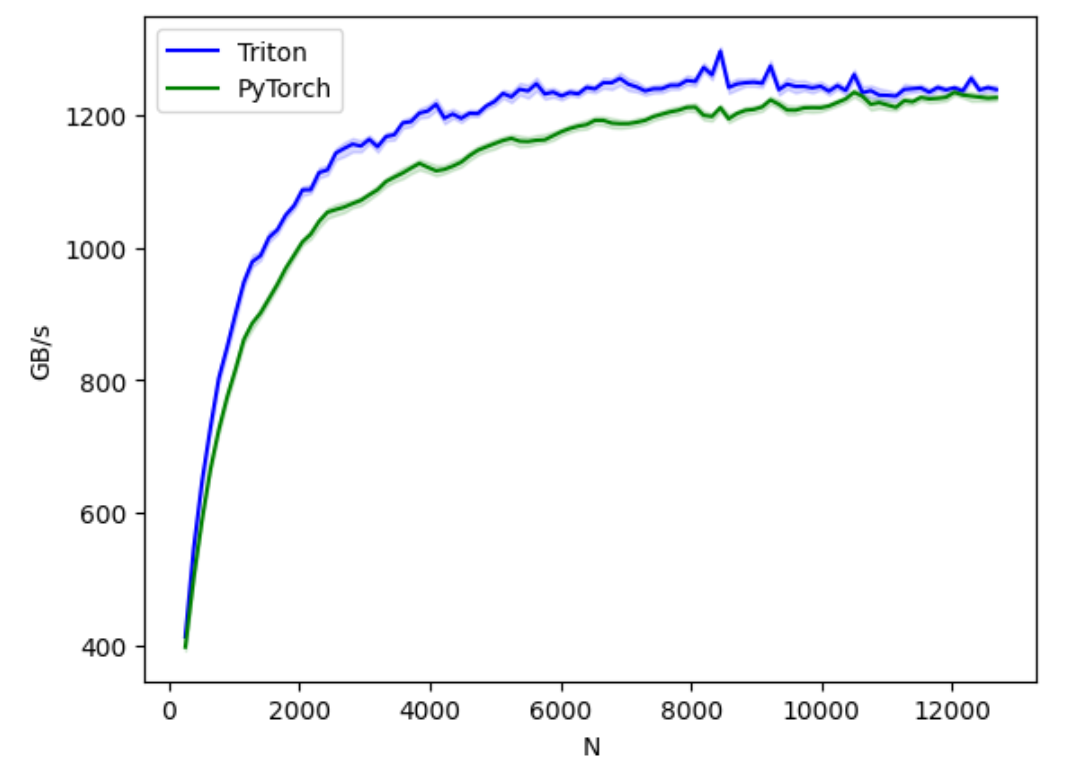
在 AMD GPU 上开发 Triton Kernel_triton amd-CSDN博客

算法 - 不可不知小技巧|CPP Wrapper 完全指南:让你的 Triton 算子性能再提升一步 - 个人文章 - SegmentFault 思否

Triton GPU Programming From Scratch - Tutorial https://t.co/6T7snaSC1V ...

Triton Compilation Stages: Python to GPU | Emilio Andere posted on the ...

Triton GPU Kernels Lesson #9 | Flash attention (part 2 - backward pass ...
Triton vs CUDA: GPU Kernel Optimization for ML Workloads
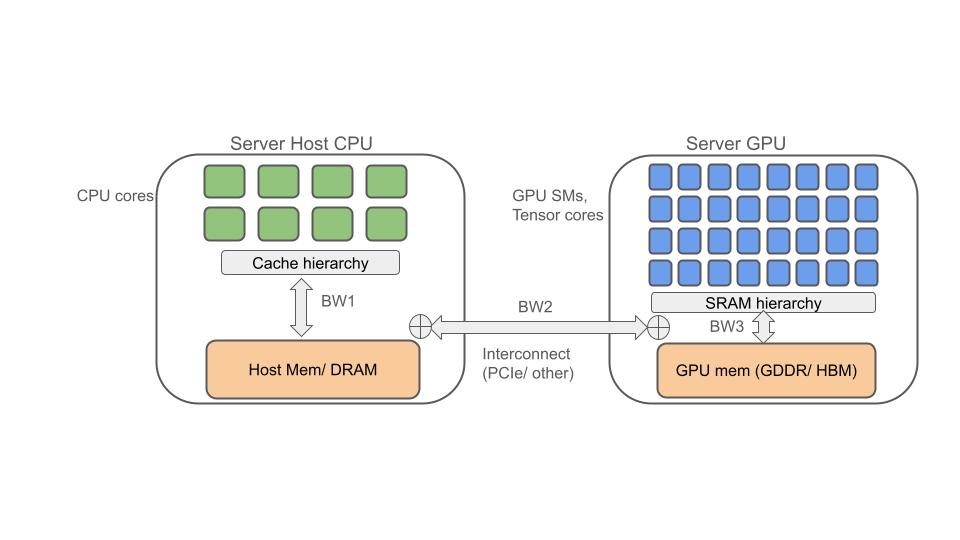
Democratizing AI Accelerators and GPU Kernel Programming using Triton ...
Advertisement Space (336x280)
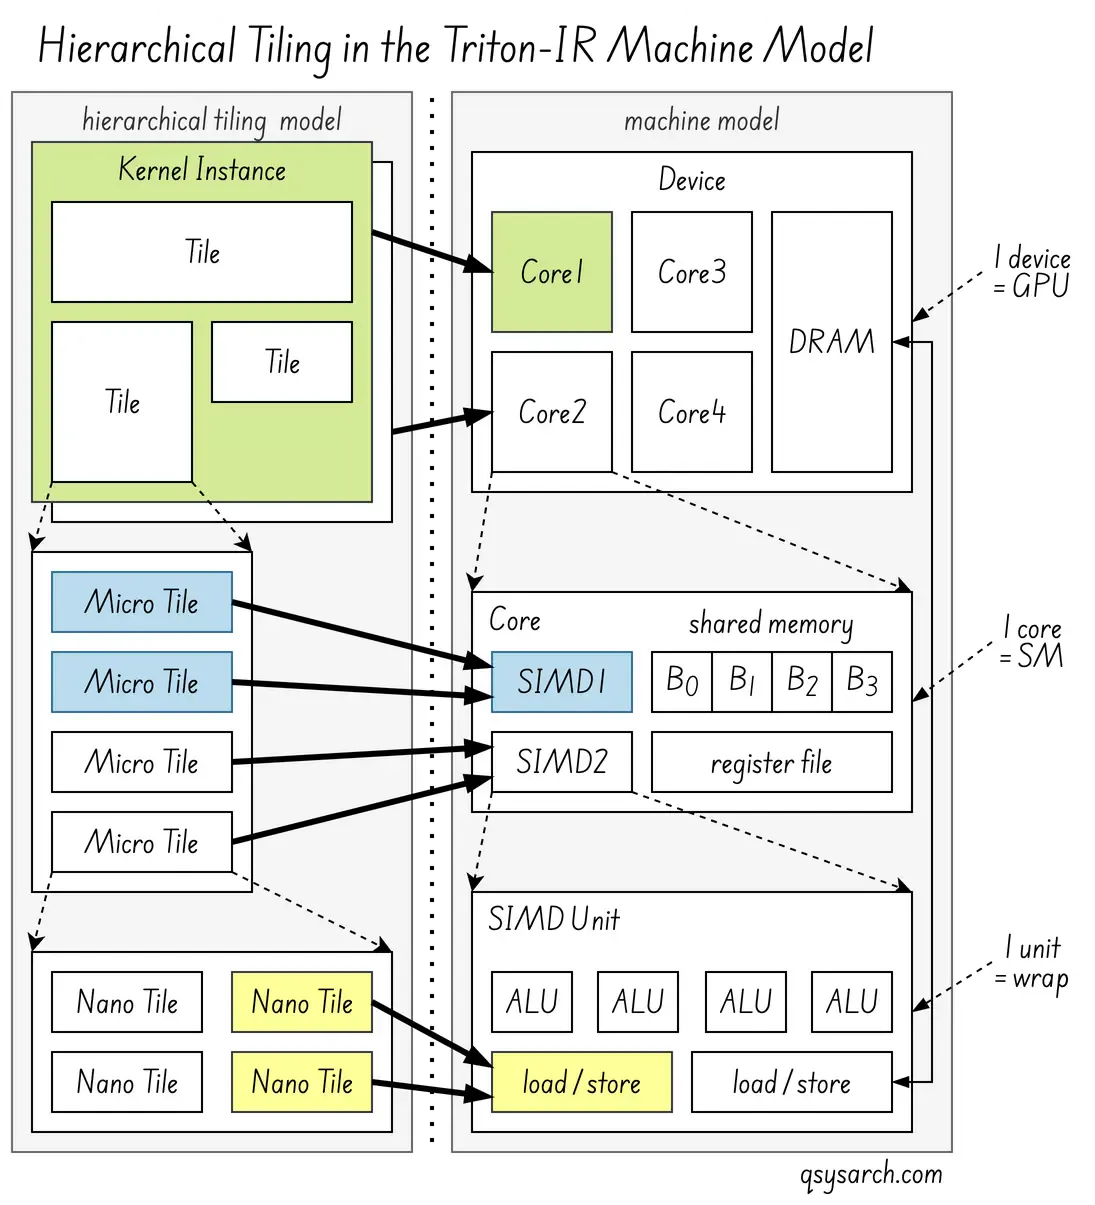
GPU Compiler Architecture: CUDA, Triton & DeepSeek · QSysArch - Quantum ...

I just dropped Part 2 of my Triton GPU programming series! In this part ...

人工智能 - GPU 应该怎么选择?写给 AI 工程师的 GPU 选型指南 - IDP技术干货 - SegmentFault 思否
Triton GPU Kernels Lesson #8 | Layernorm - YouTube
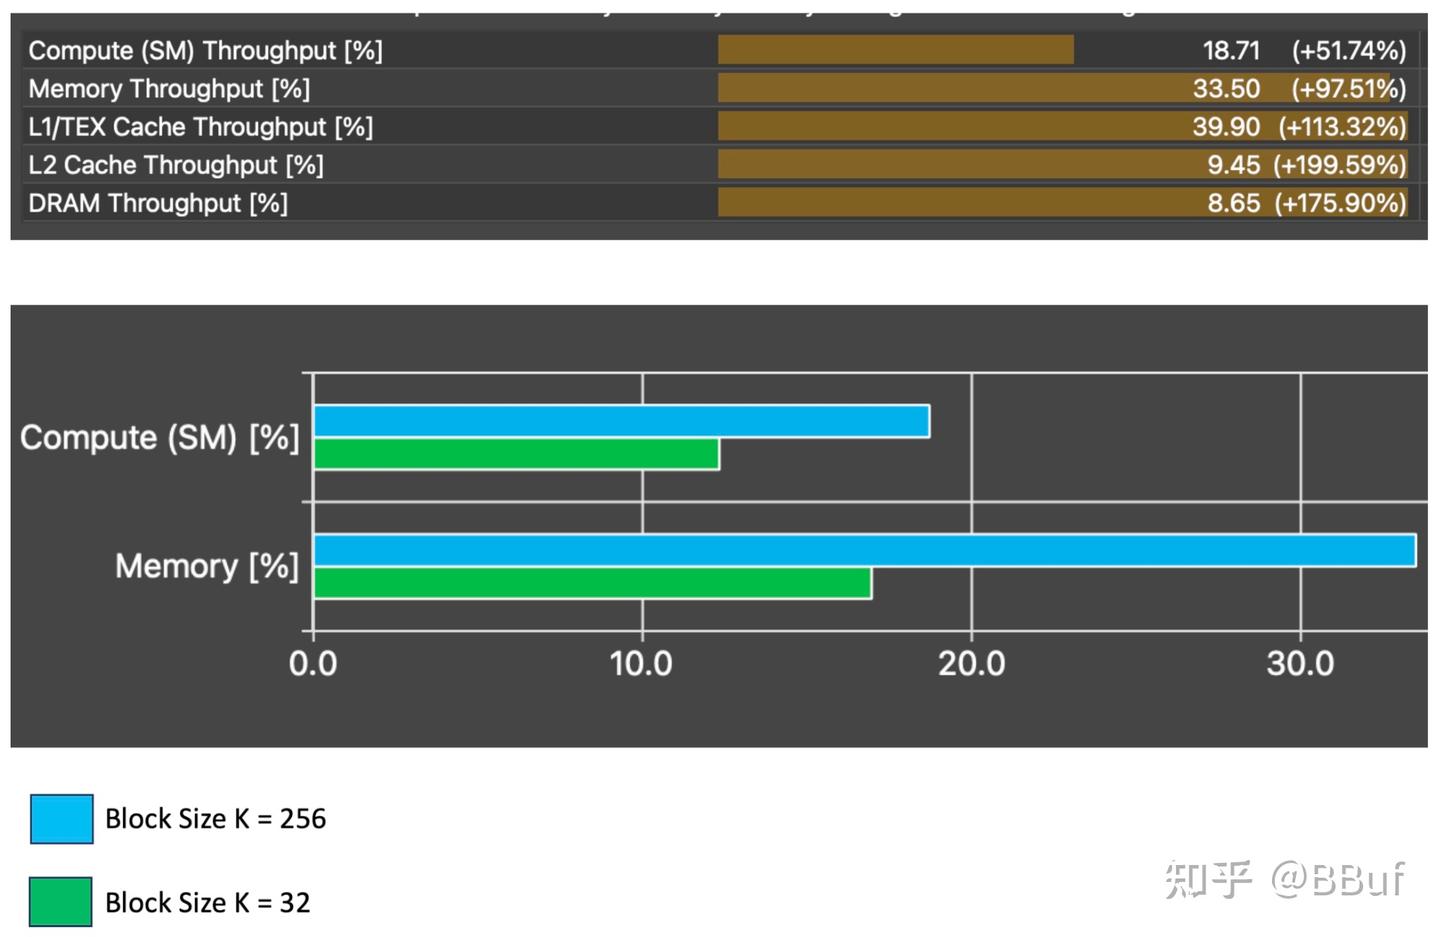
【博客翻译】在 GPU 上如何加速 GPTQ Triton 反量化kernel - 知乎

AMD AI 架构师张宁:多视角解析 AMD Triton 编译器,助力开源生态建设 - 超神经HyperAI - SegmentFault 思否

Triton GPU Kernels Lesson #7 | Dropout - YouTube
Triton Kernels for Mortals. How simple custom GPU kernels can beat ...
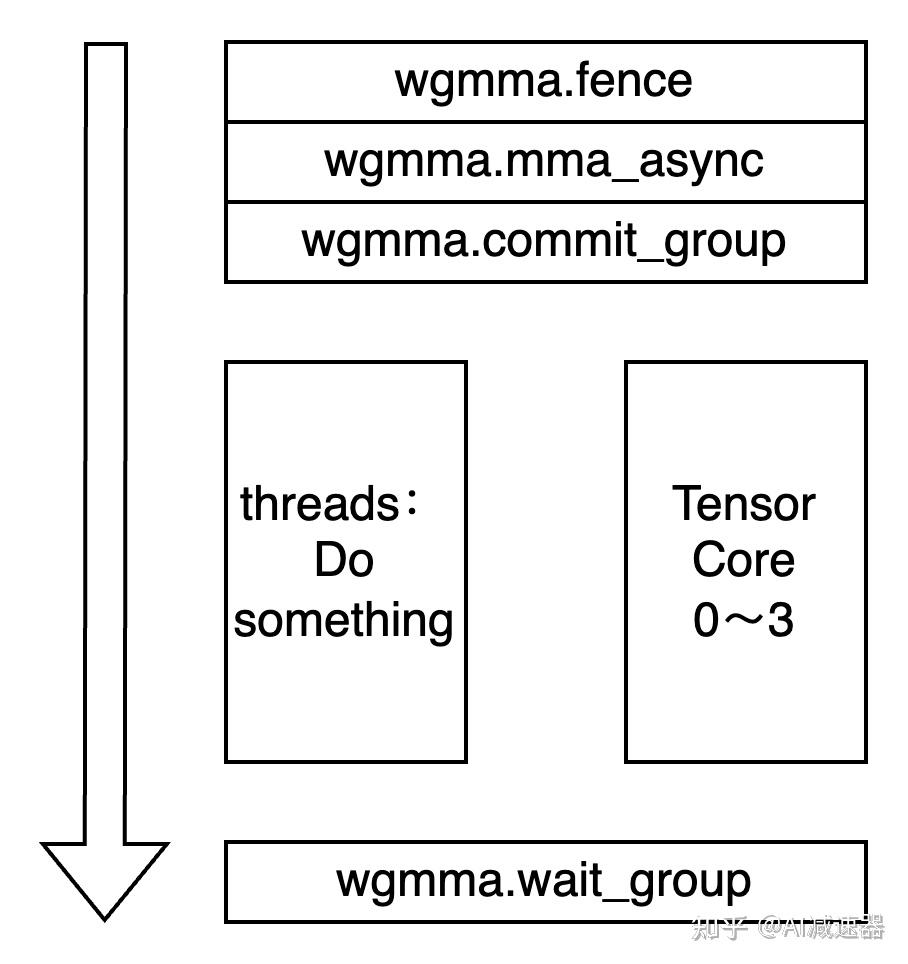
Triton GPU 优化: Pipeline - 知乎

人工智能 - 从零开始用自定义 Triton 内核编写 FlashAttention-2 - deephub - SegmentFault 思否
Advertisement Space (336x280)

人工智能 - 从零开始用自定义 Triton 内核编写 FlashAttention-2 - deephub - SegmentFault 思否
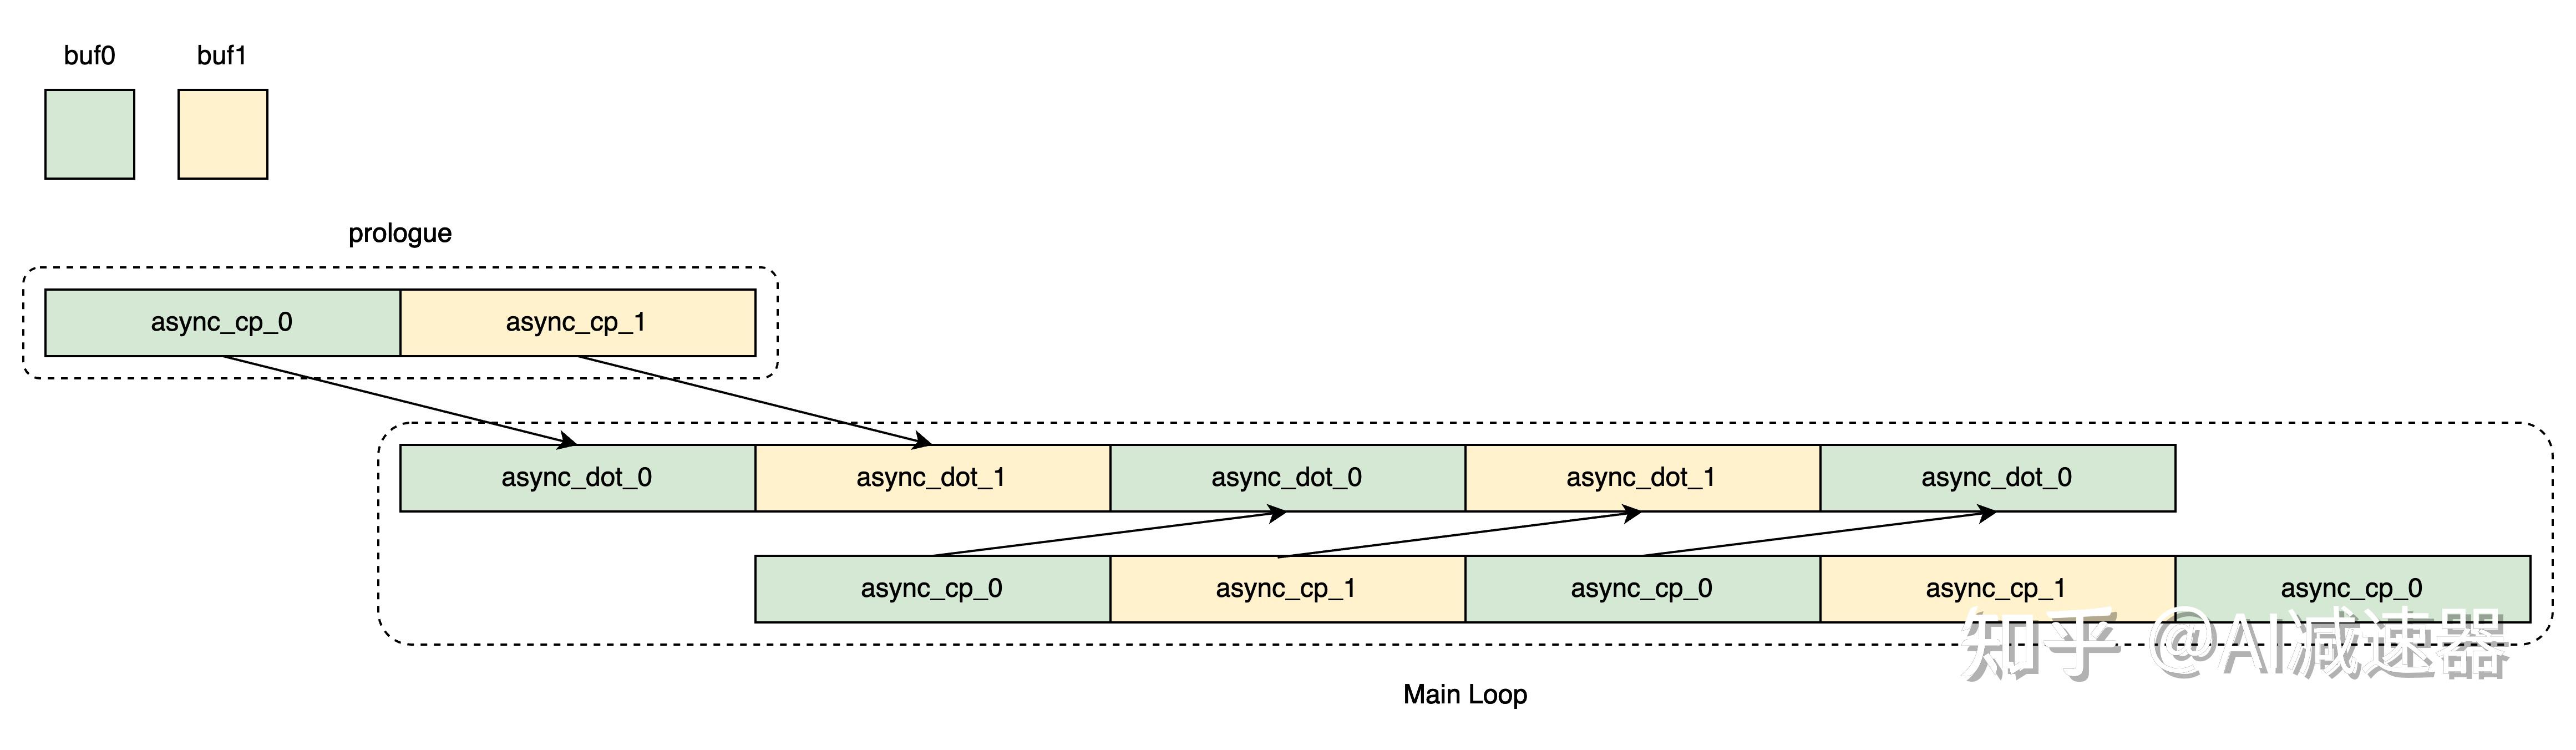
Triton GPU 优化: Pipeline - 知乎

人工智能 - 部署 LLMs 前如何计算与优化 GPU 内存需求? - IDP技术干货 - SegmentFault 思否

人工智能 - GPU 应该怎么选择?写给 AI 工程师的 GPU 选型指南 - IDP技术干货 - SegmentFault 思否

人工智能 - 记录TritonServer部署多模型到多GPU踩坑 | 京东云技术团队 - 京东云技术新知 - SegmentFault 思否

CUDA 初始团队成员锐评 cuTile「专打」Triton,Tile 范式能否重塑 GPU 编程生态竞争格局 - 超神经HyperAI ...