
Understanding Kv Cache In Llm Inference Jingchaos Website
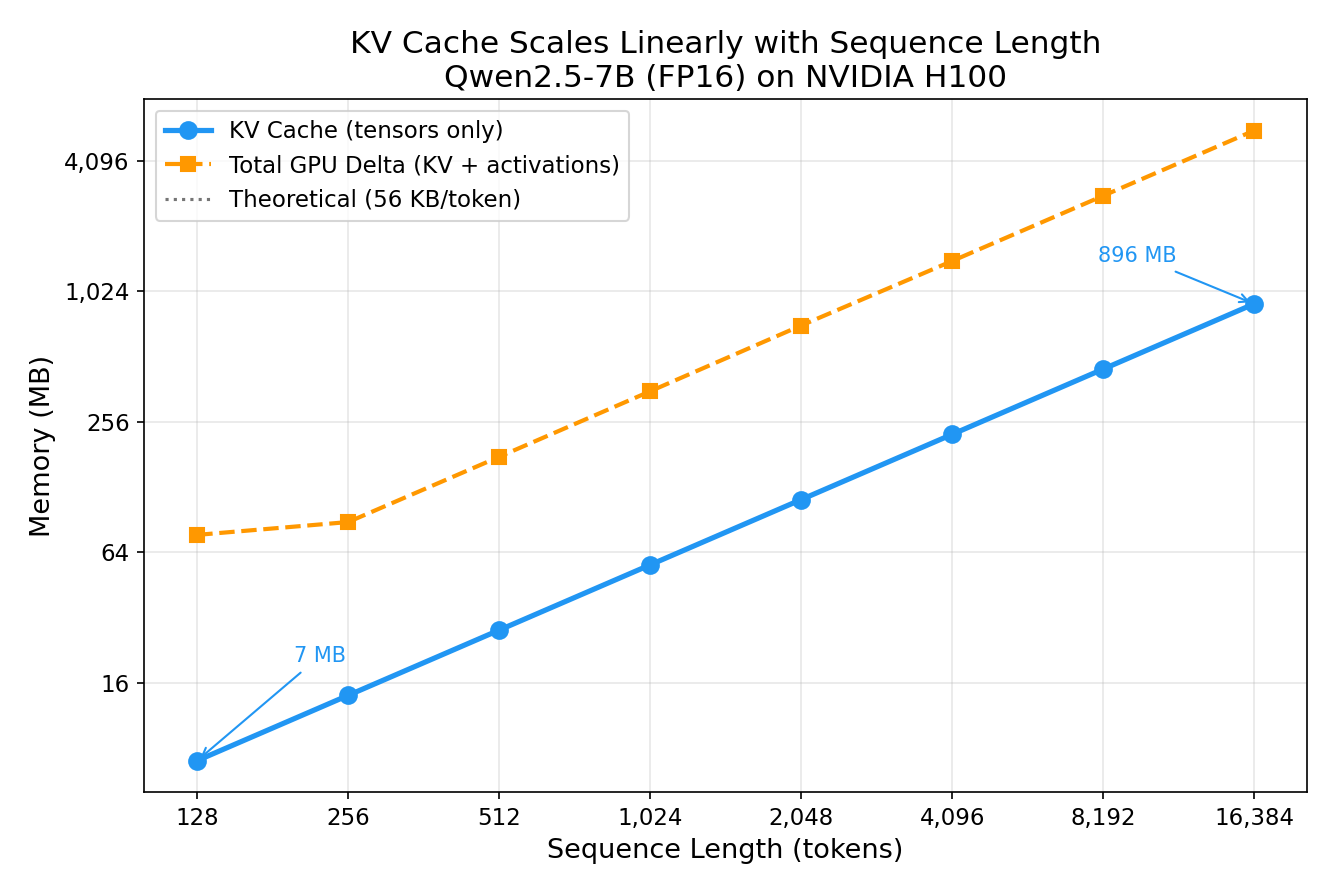
Understanding KV Cache in LLM Inference - Jingchao’s Website
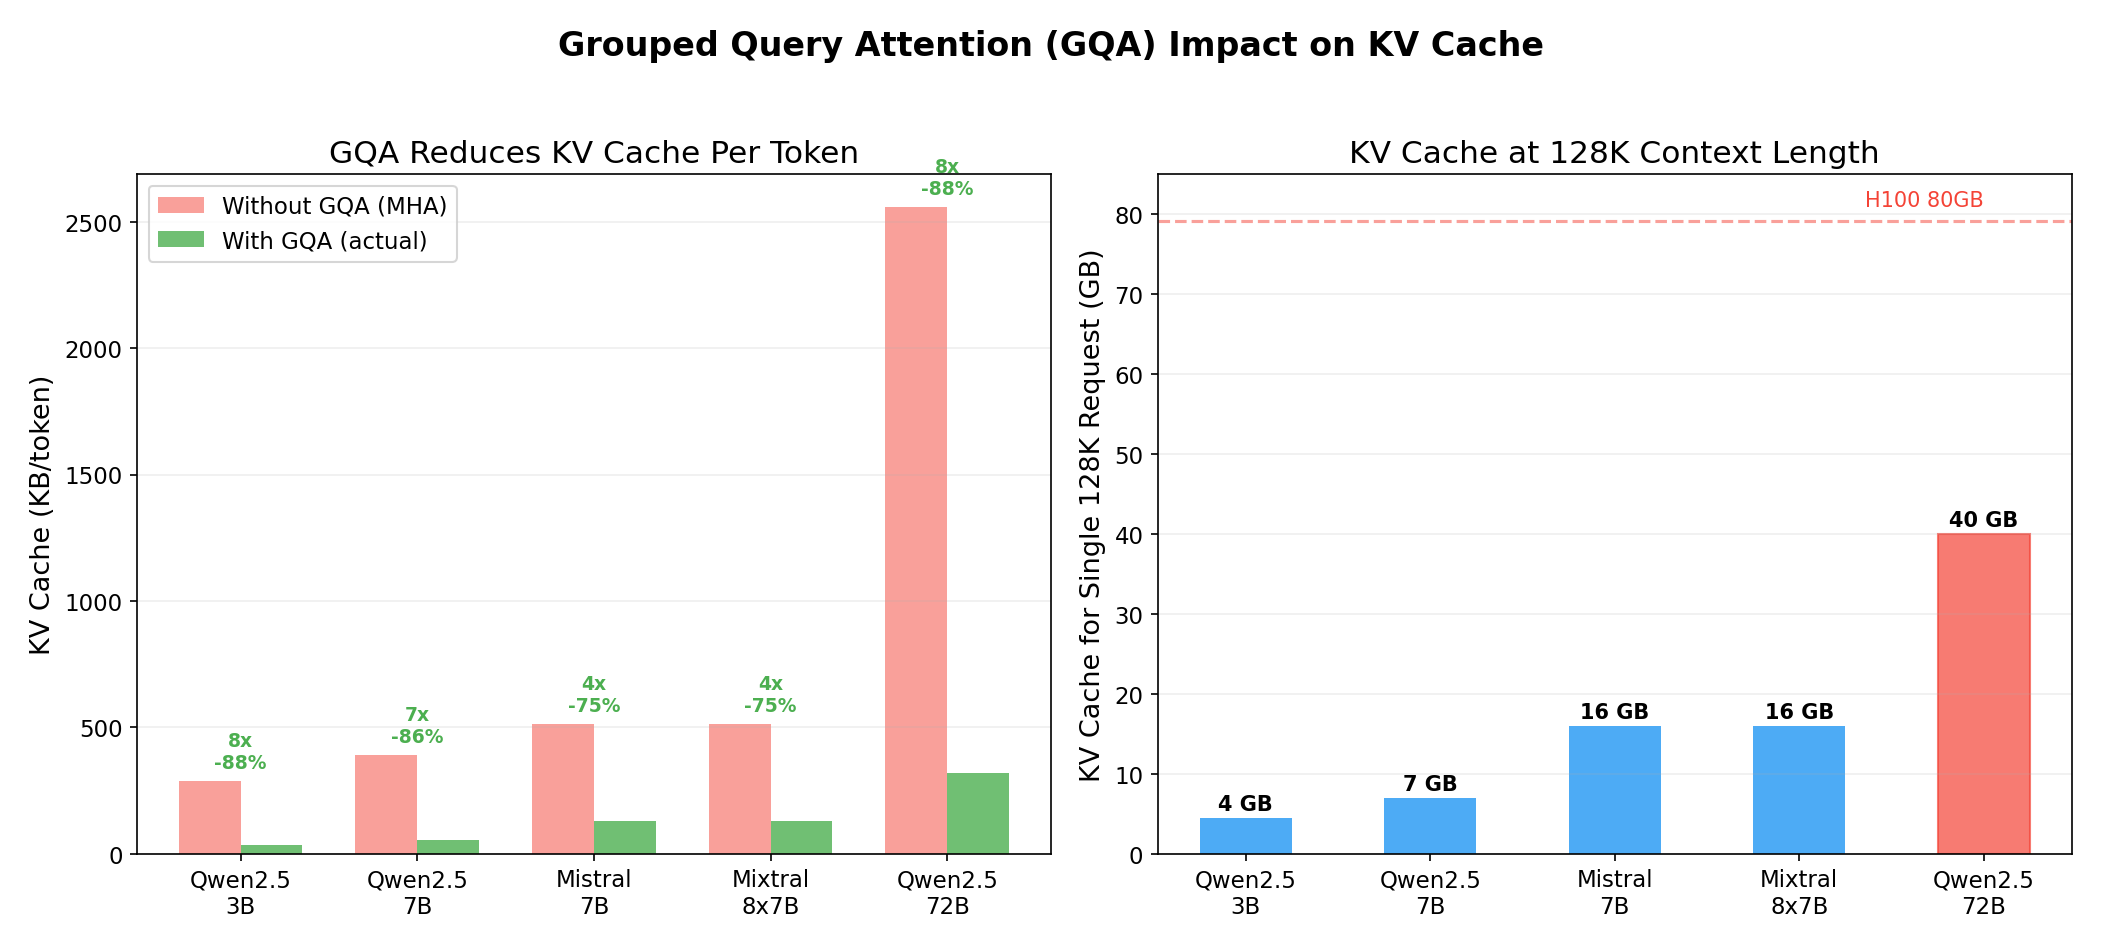
Understanding KV Cache in LLM Inference - Jingchao’s Website
KV Cache State: Definition & Role in LLM Inference | Inference Systems

KV Cache in LLM Inference - Complete Technical Deep Dive - YouTube

Identify Critical KV Cache in LLM Inference from an Output Perturbation ...

KV Cache Transform Coding for Compact Storage in LLM Inference
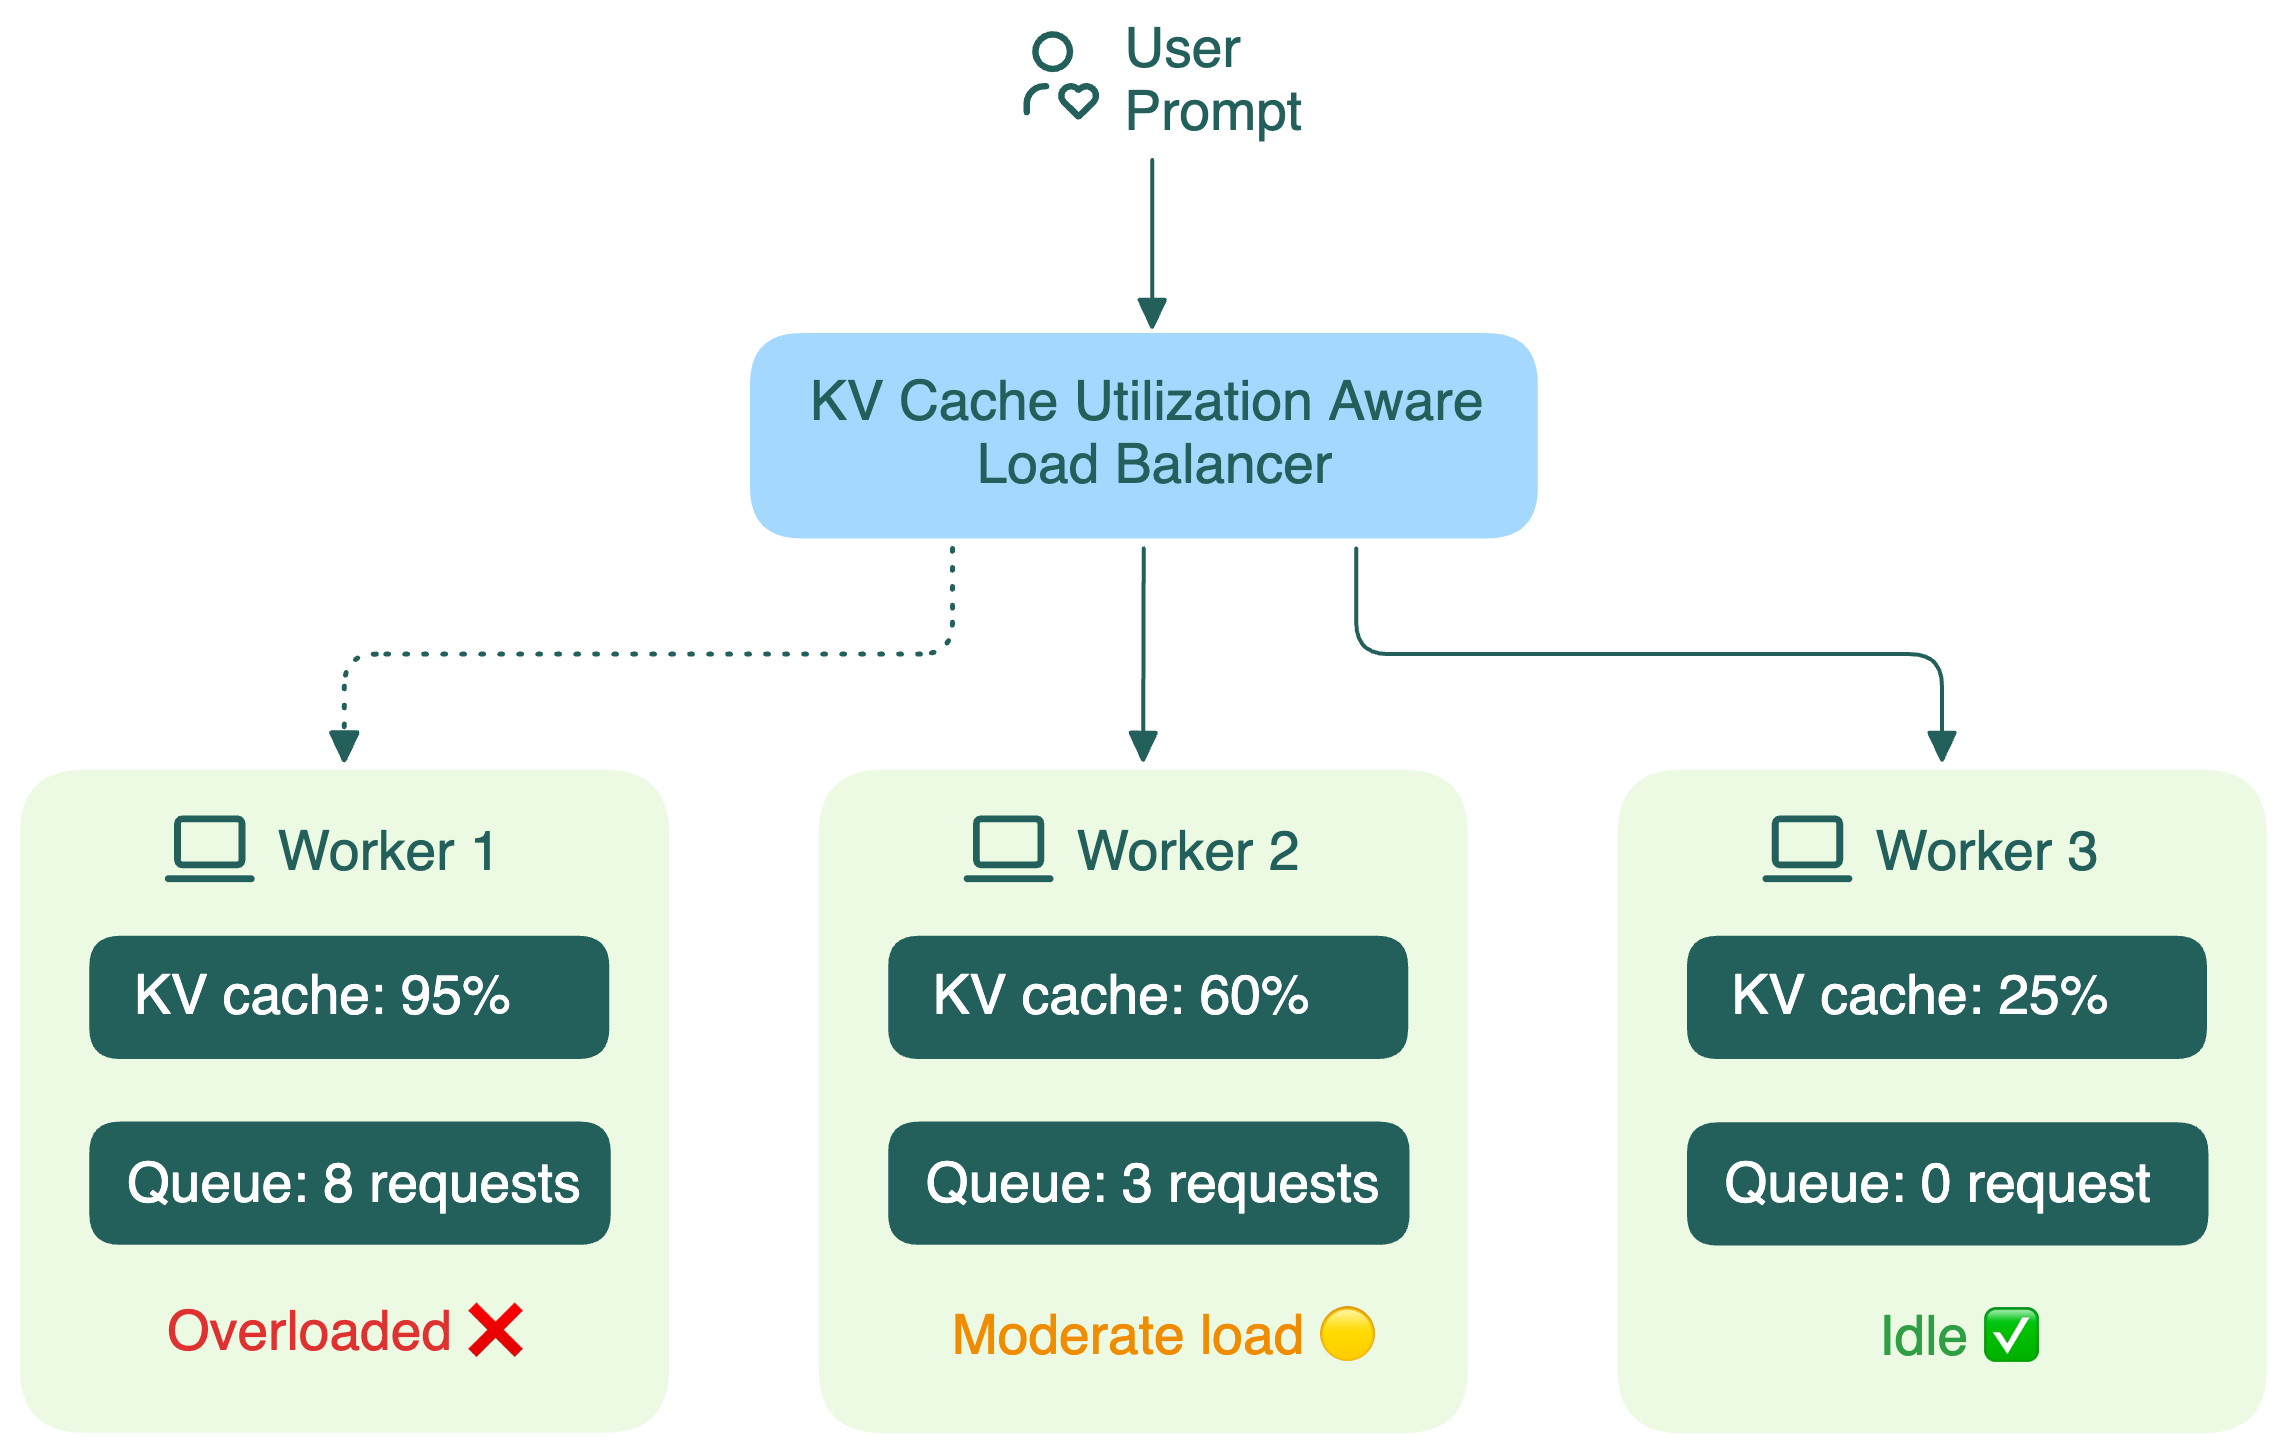
KV cache utilization-aware load balancing | LLM Inference Handbook
基于全局 KV Cache 存储系统的高效 LLM 推理加速方案 Efficient LLM Inference Acceleration ...
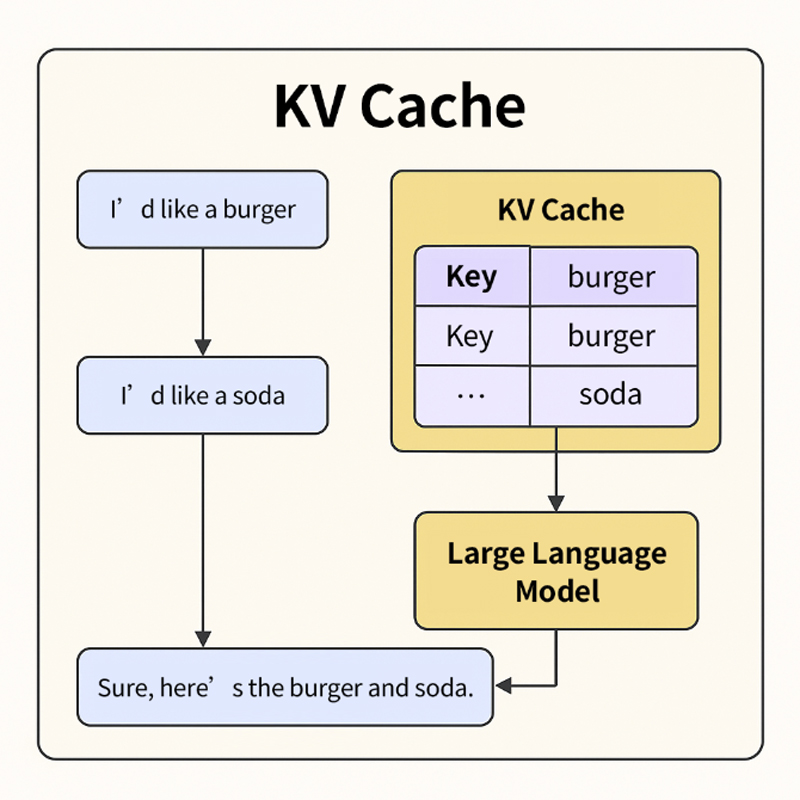
KV Cache Meets NVMe: The Key to Accelerating LLM Inference

KV Cache Offload Accelerates LLM Inference - NADDOD Blog
Advertisement Space (300x250)

KV Cache Reuse Is Quietly Reshaping LLM Inference Architecture | by ...
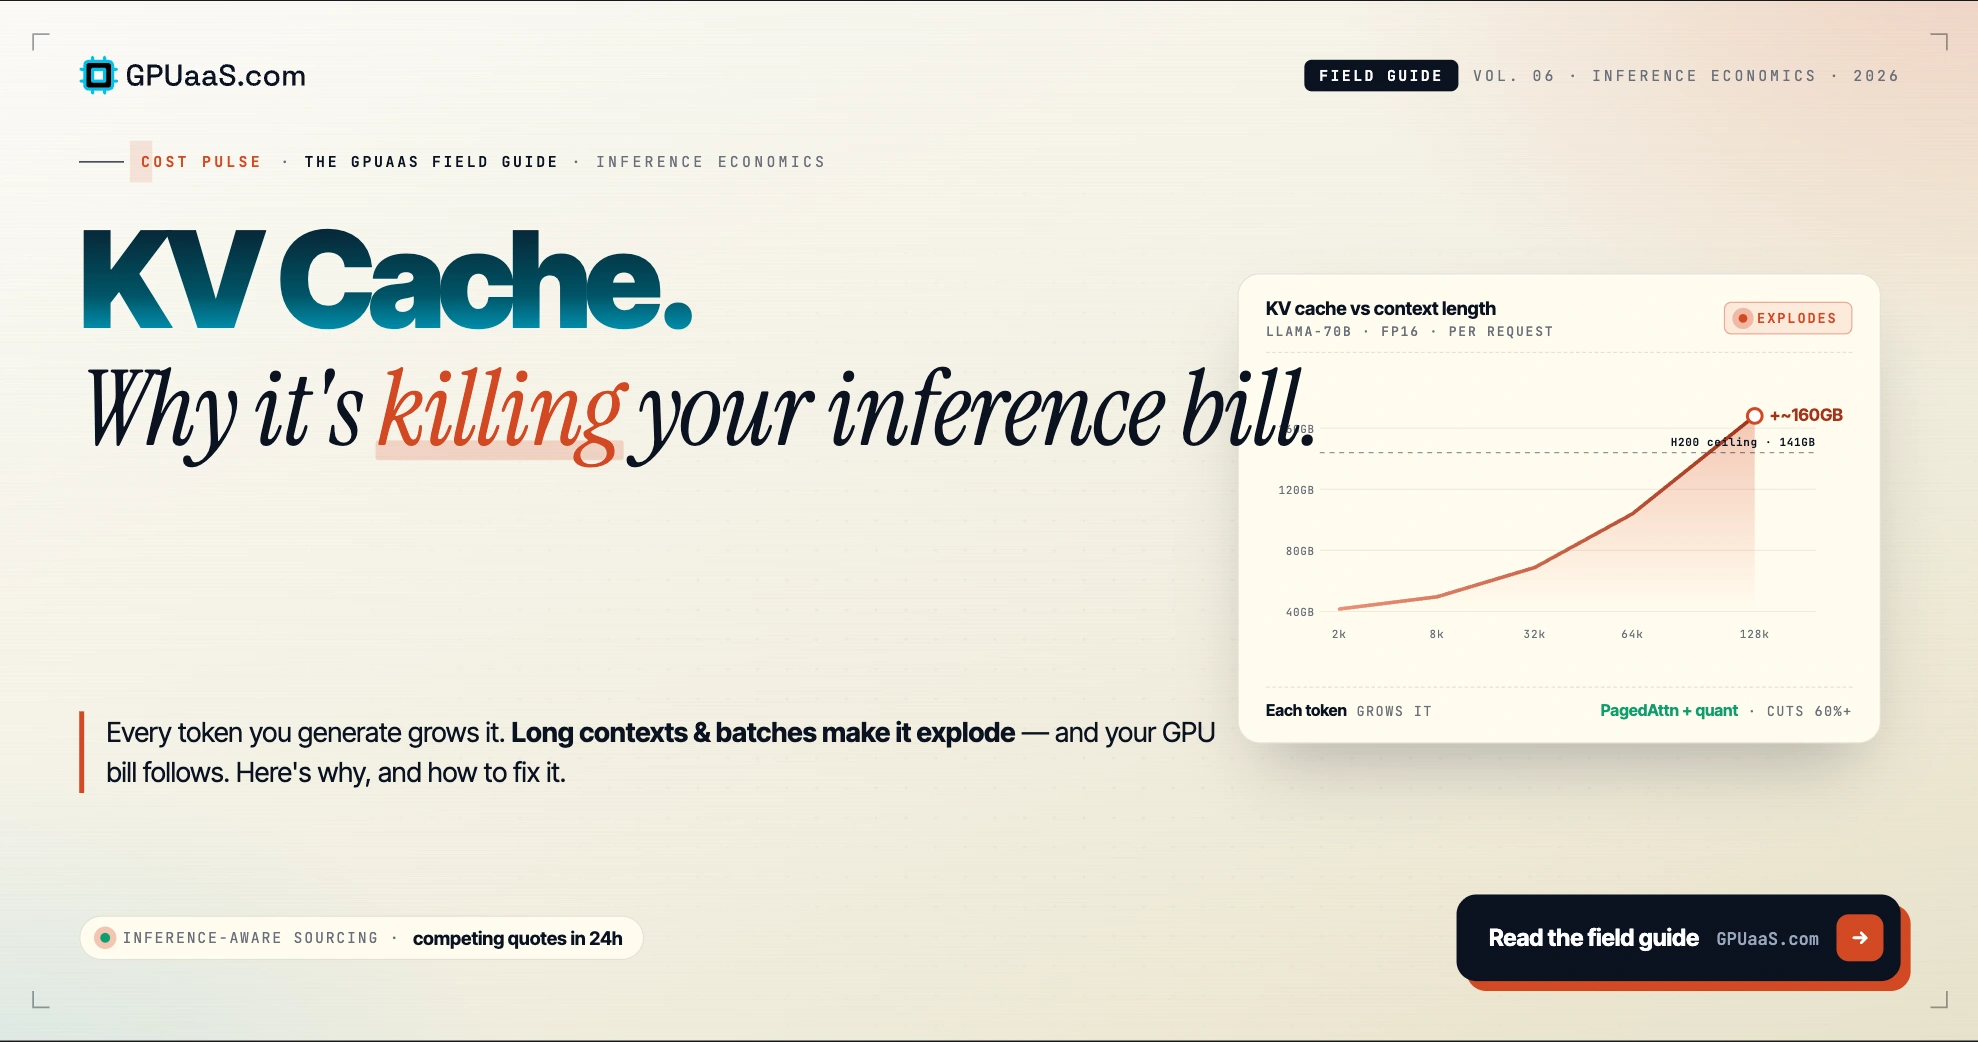
KV Cache Explained: Cut LLM Inference Costs 2026 | GPUaaS.com
KV Cache Explained — Why LLM Inference Is Fast
KV Cache Explained for LLM Inference

LLM inference optimization: Architecture, KV cache and Flash attention ...

LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...
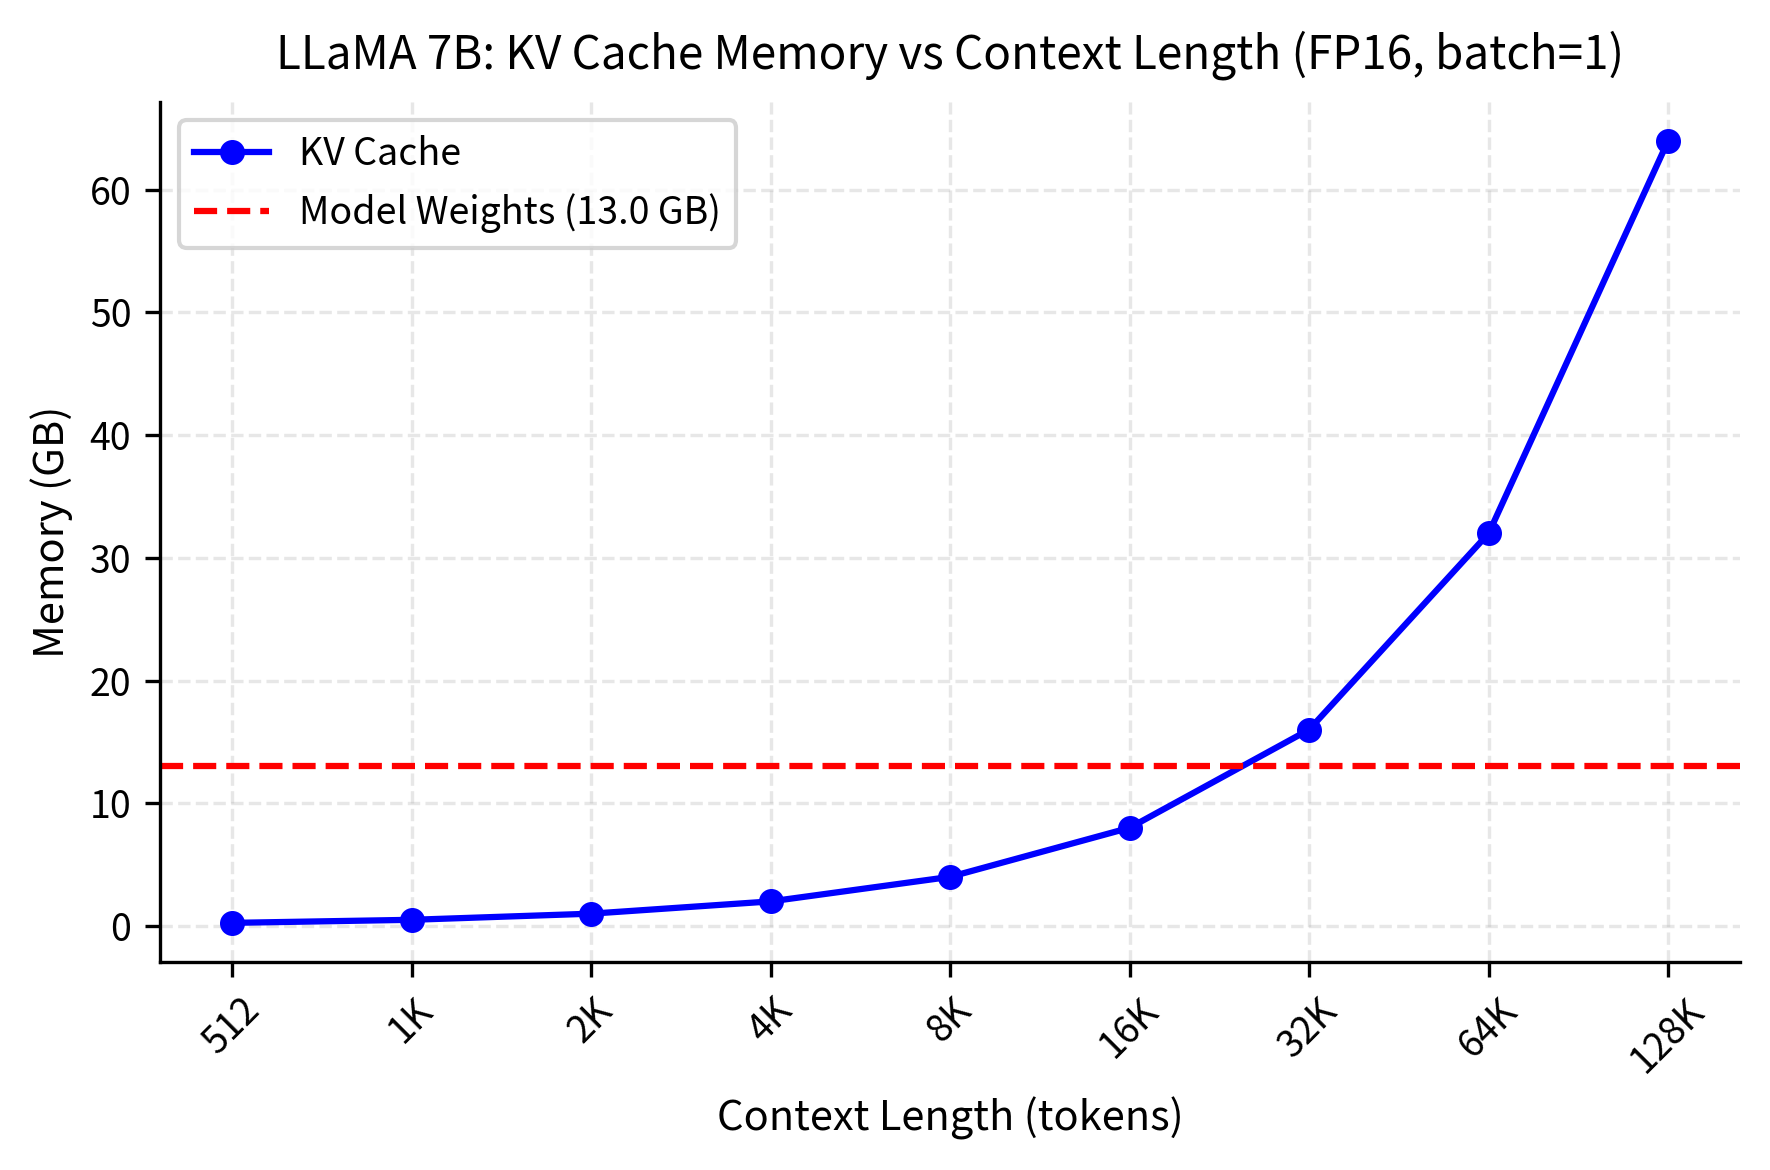
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...

Understanding and Coding the KV Cache in LLMs from Scratch
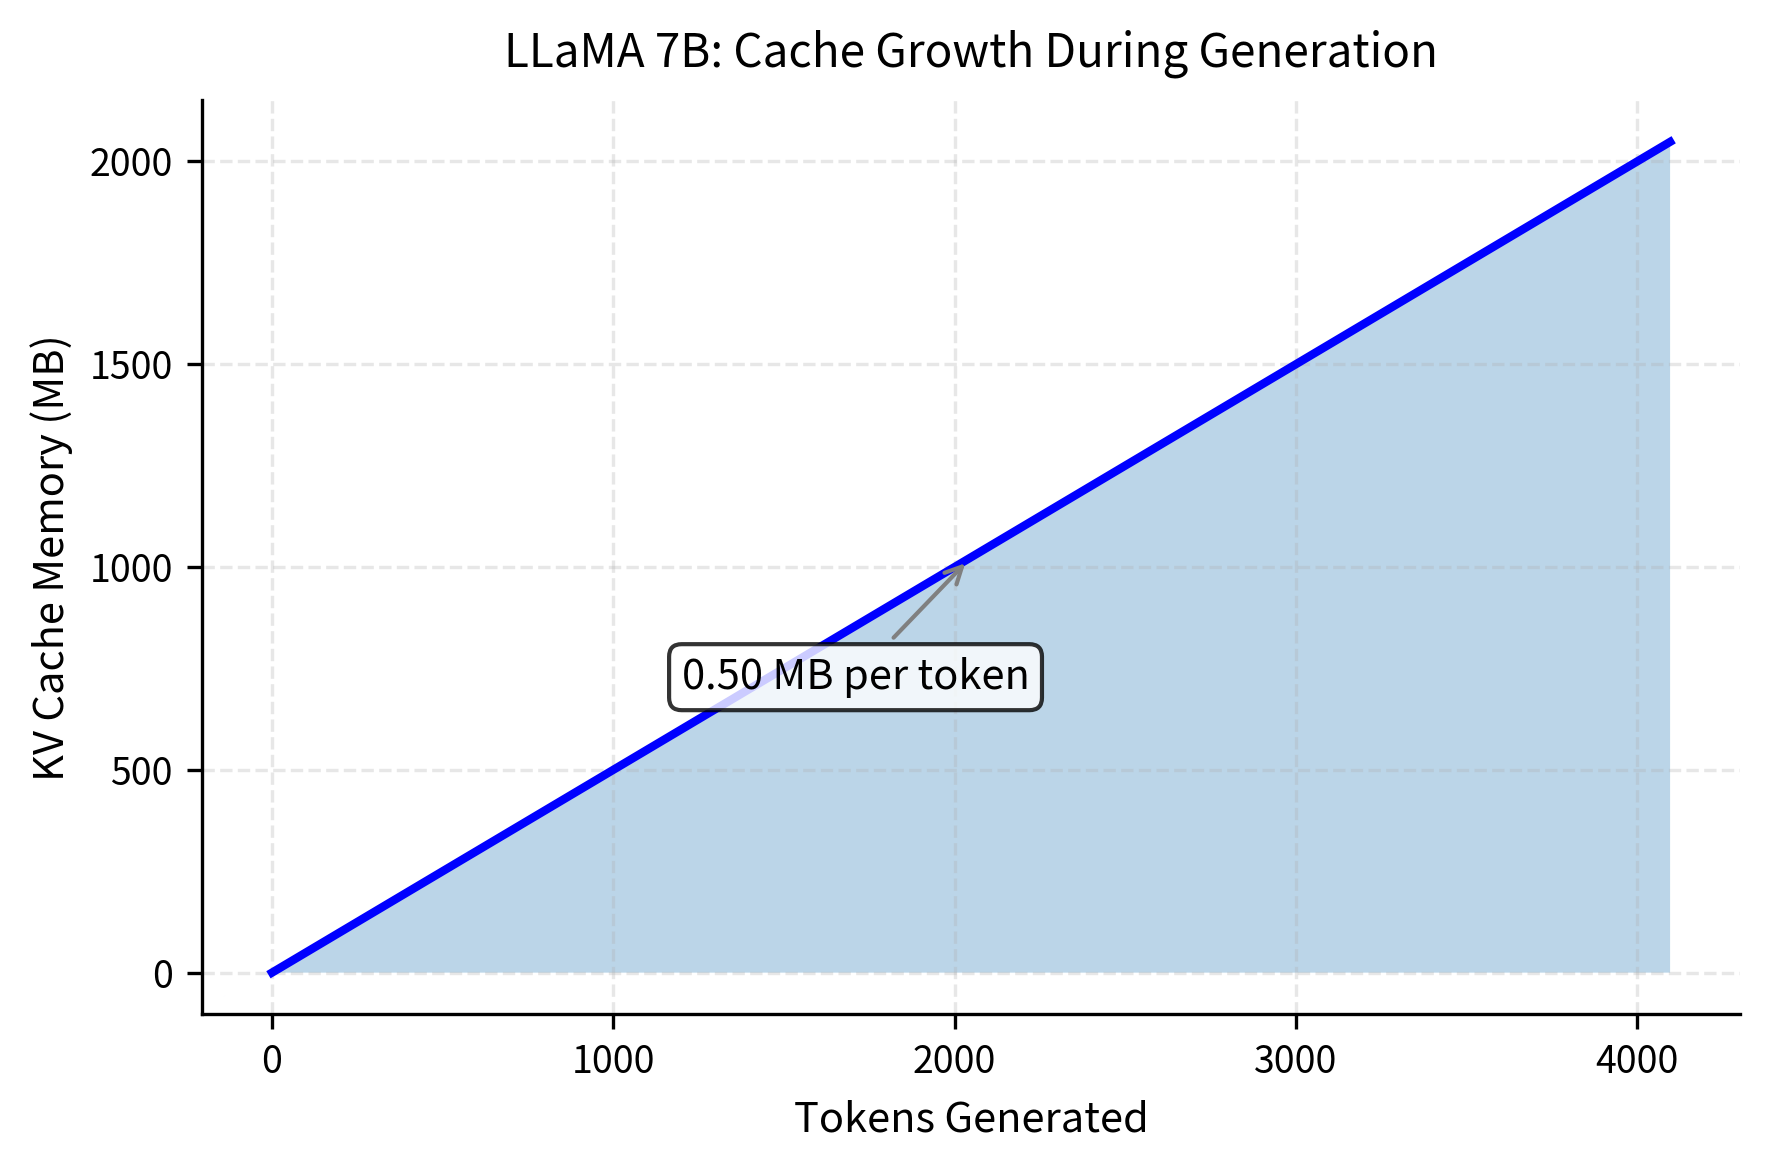
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...

KV Cache Compression for Inference Efficiency in LLMs: A Review | AI ...
Advertisement Space (336x280)

Understanding KV Cache: The Secret to Faster LLM Inference | by Sachin ...
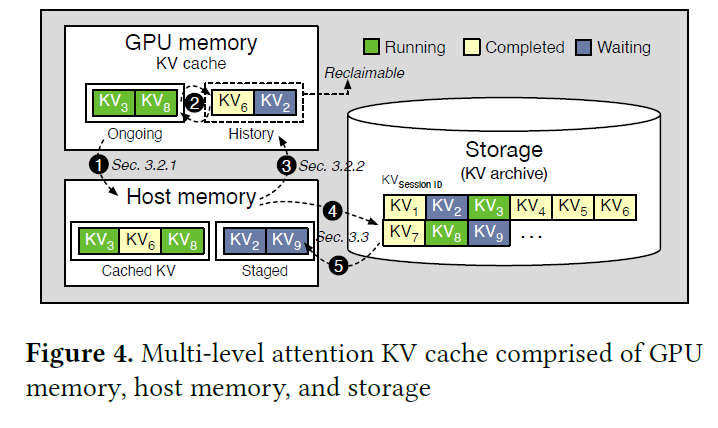
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...

Scaling Multi-Turn LLM Inference with KV Cache Storage Offload and Dell ...
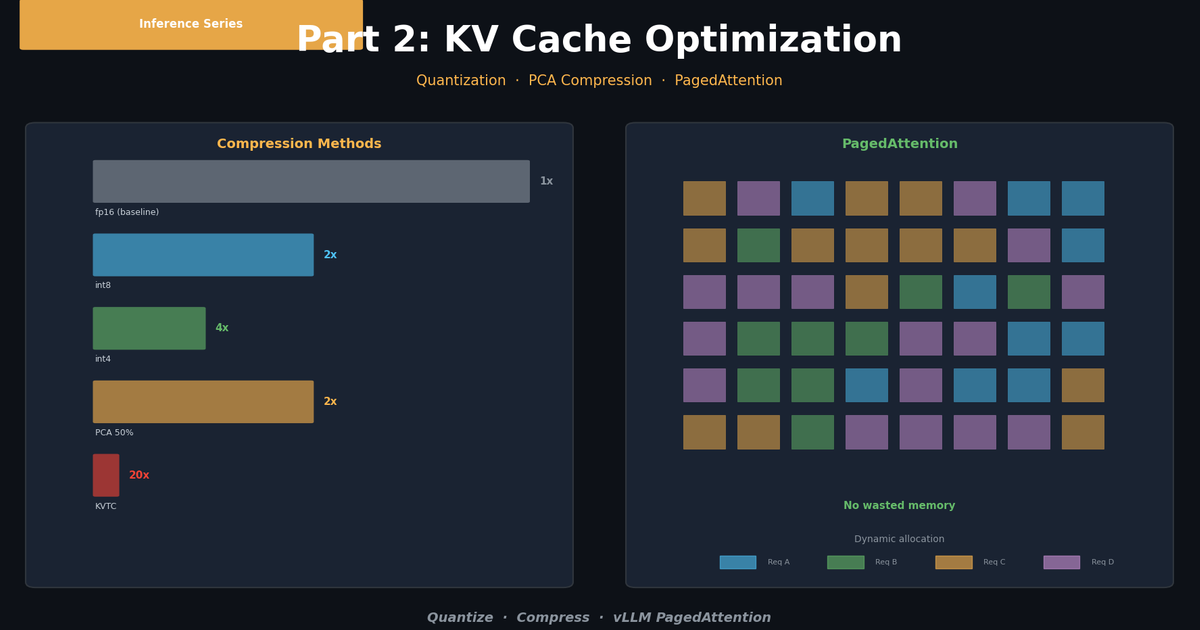
LLM Inference Optimization Part 2 — KV Cache Optimization | SOTAAZ Blog

[论文评述] Accelerating LLM Inference Throughput via Asynchronous KV Cache ...
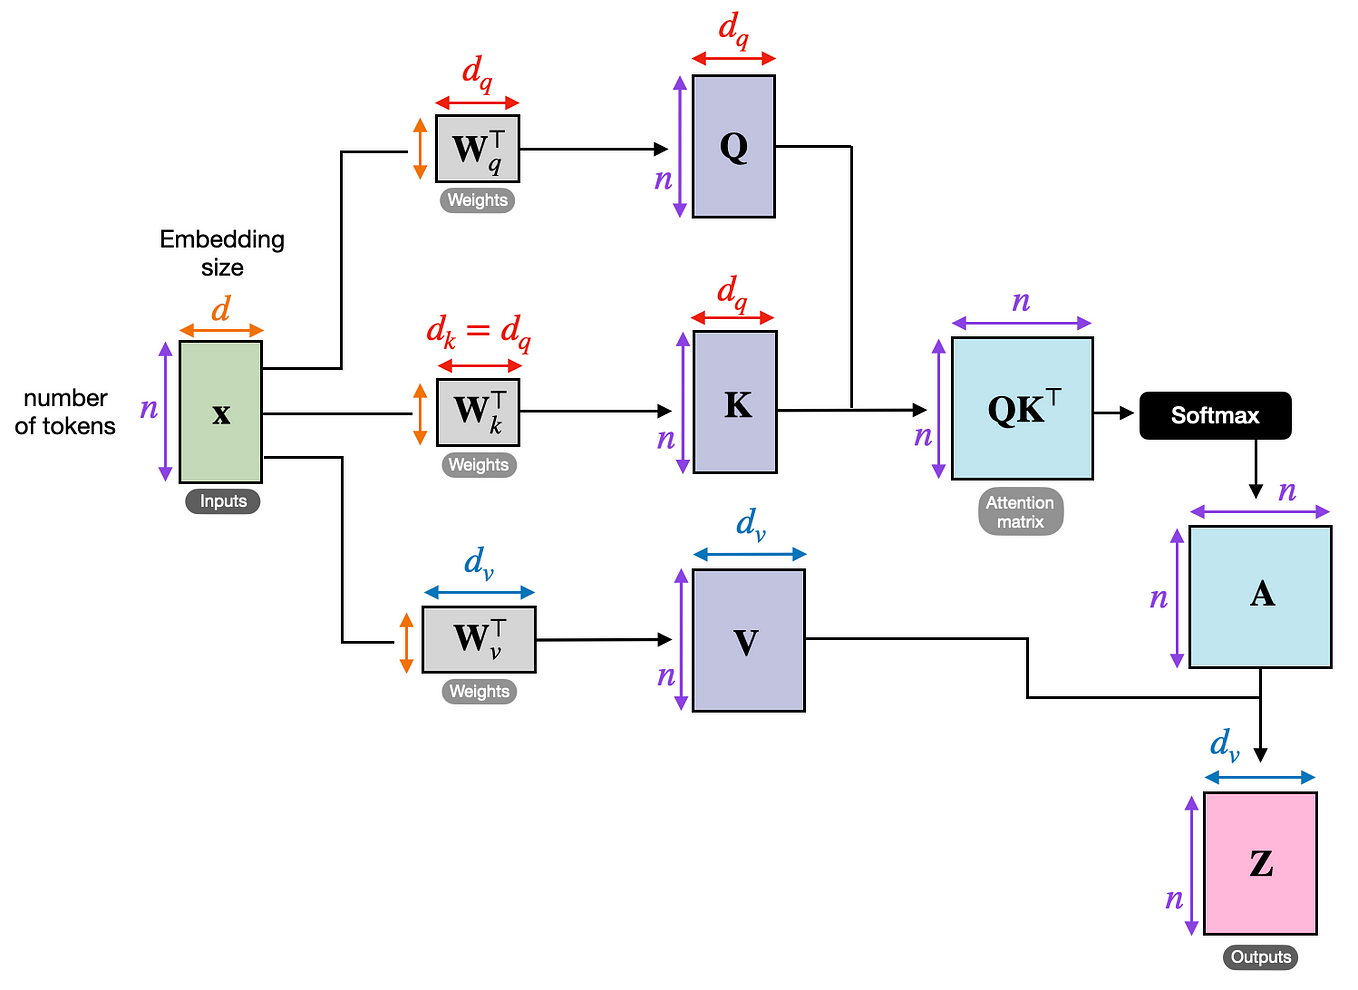
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...

Accelerating LLM Inference Throughput via Asynchronous KV Cache Prefetching

LLM Inference Bottleneck: KV Cache vs GPU Memory | Osama Altaf posted ...
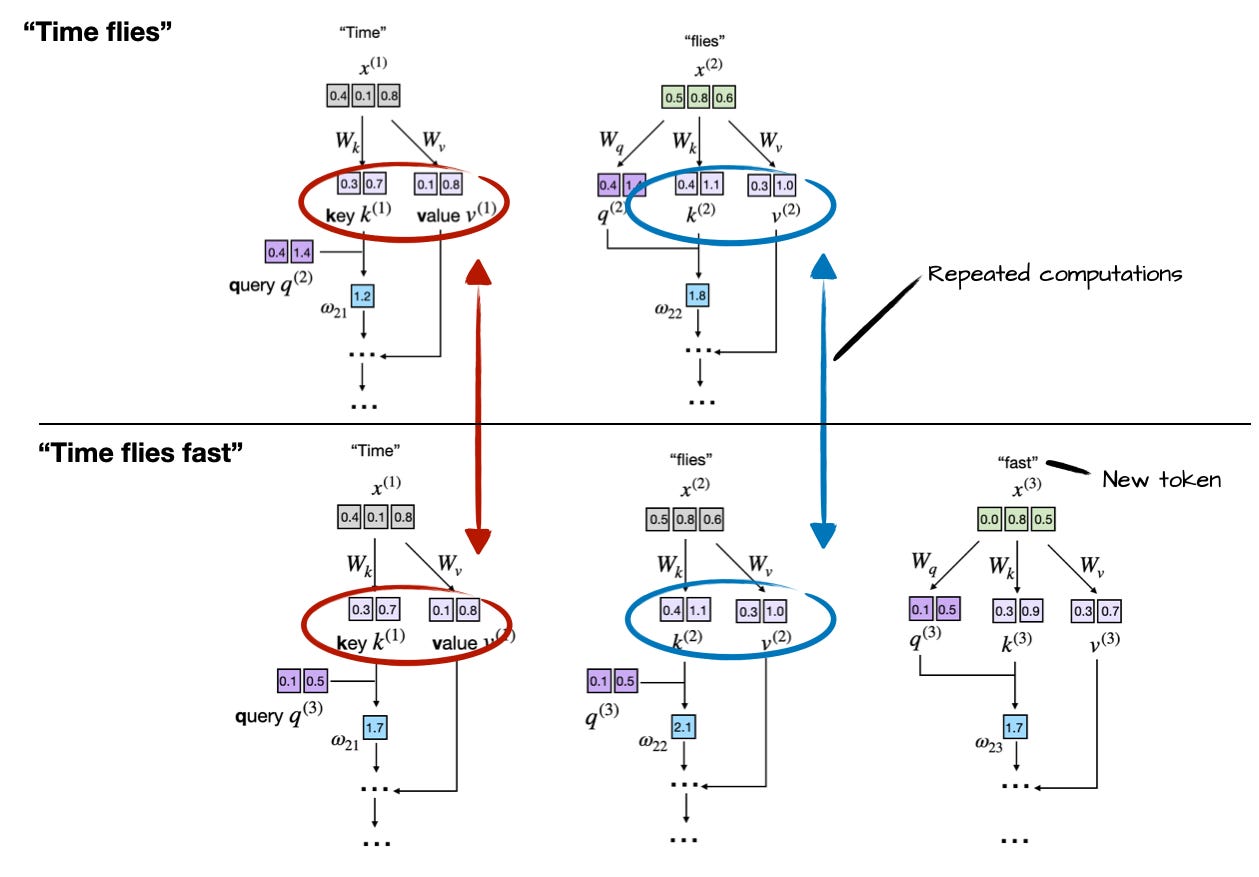
Understanding and Coding the KV Cache in LLMs from Scratch
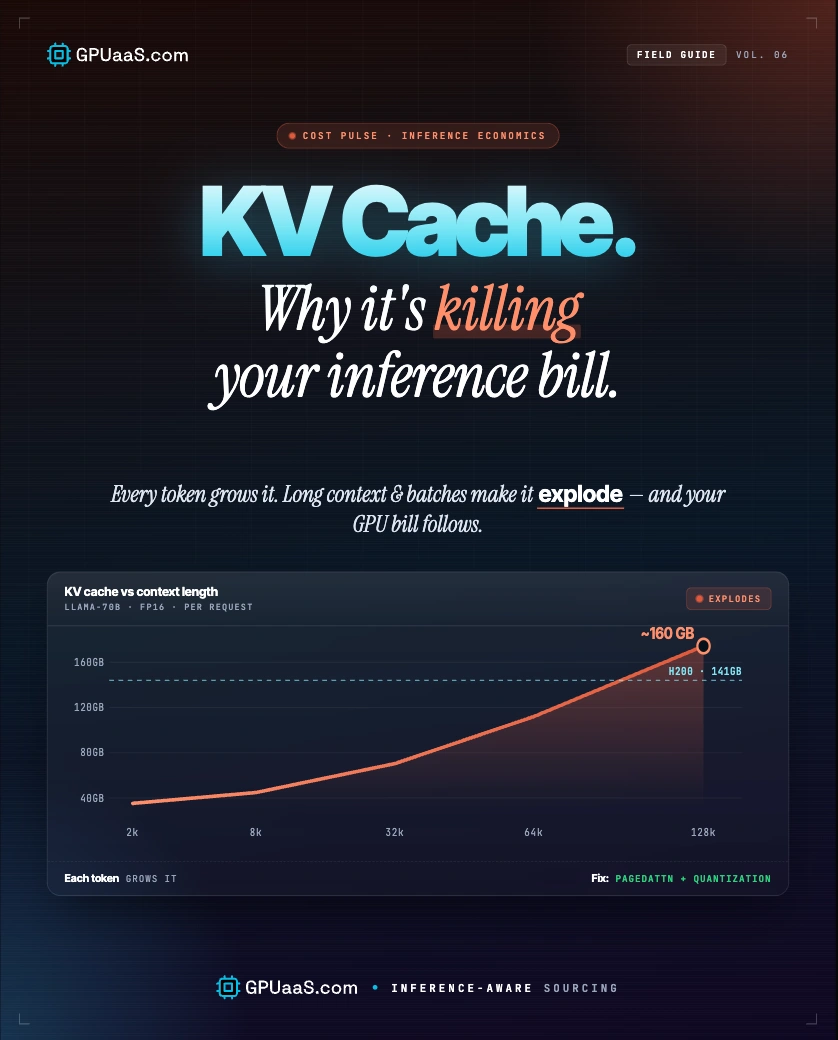
KV Cache Explained: Cut LLM Inference Costs 2026 | GPUaaS.com
Advertisement Space (336x280)
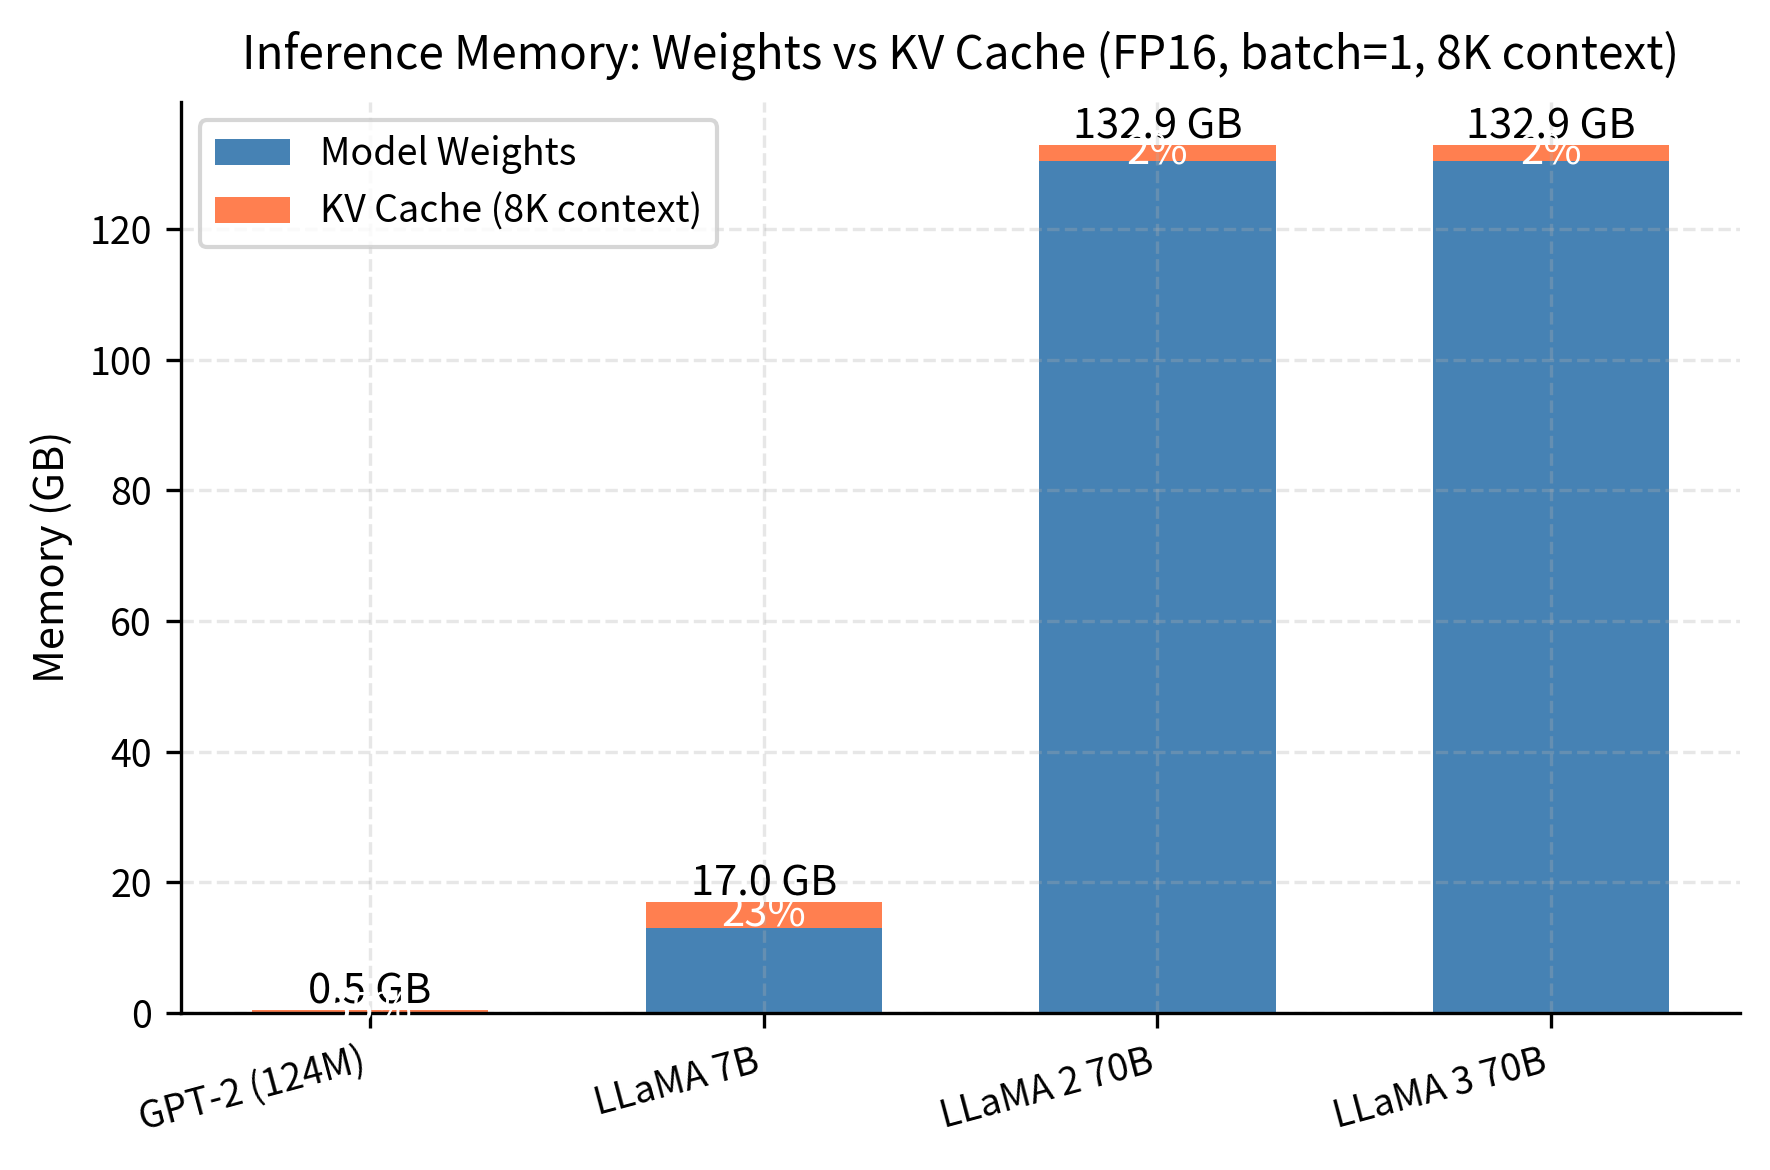
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
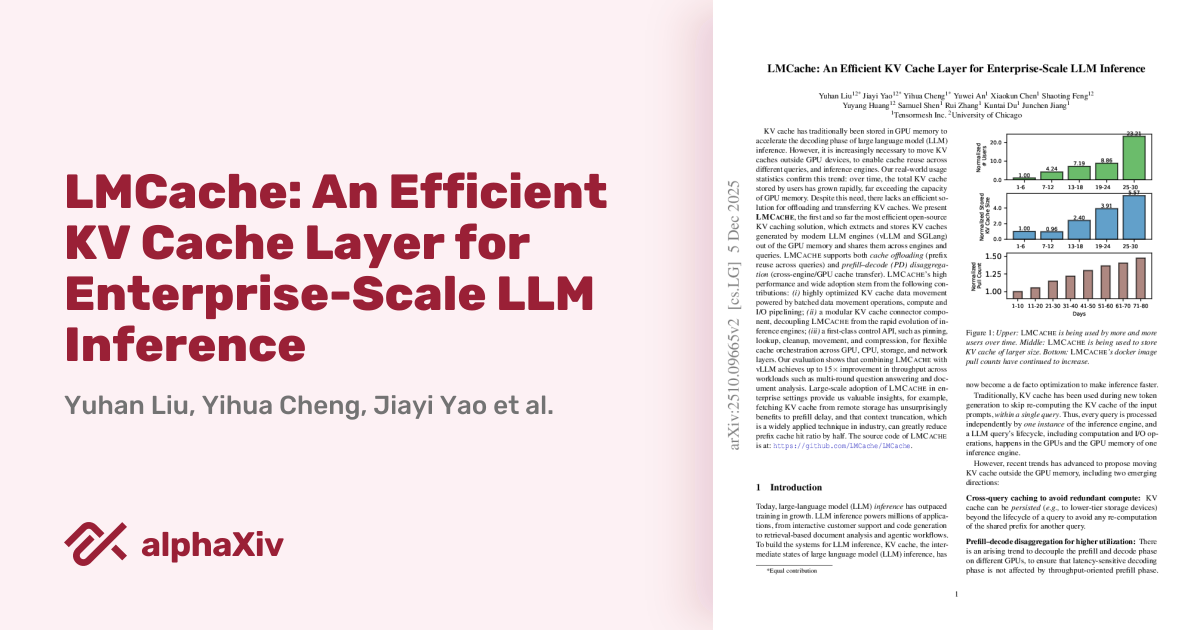
LMCache: An Efficient KV Cache Layer for Enterprise-Scale LLM Inference ...
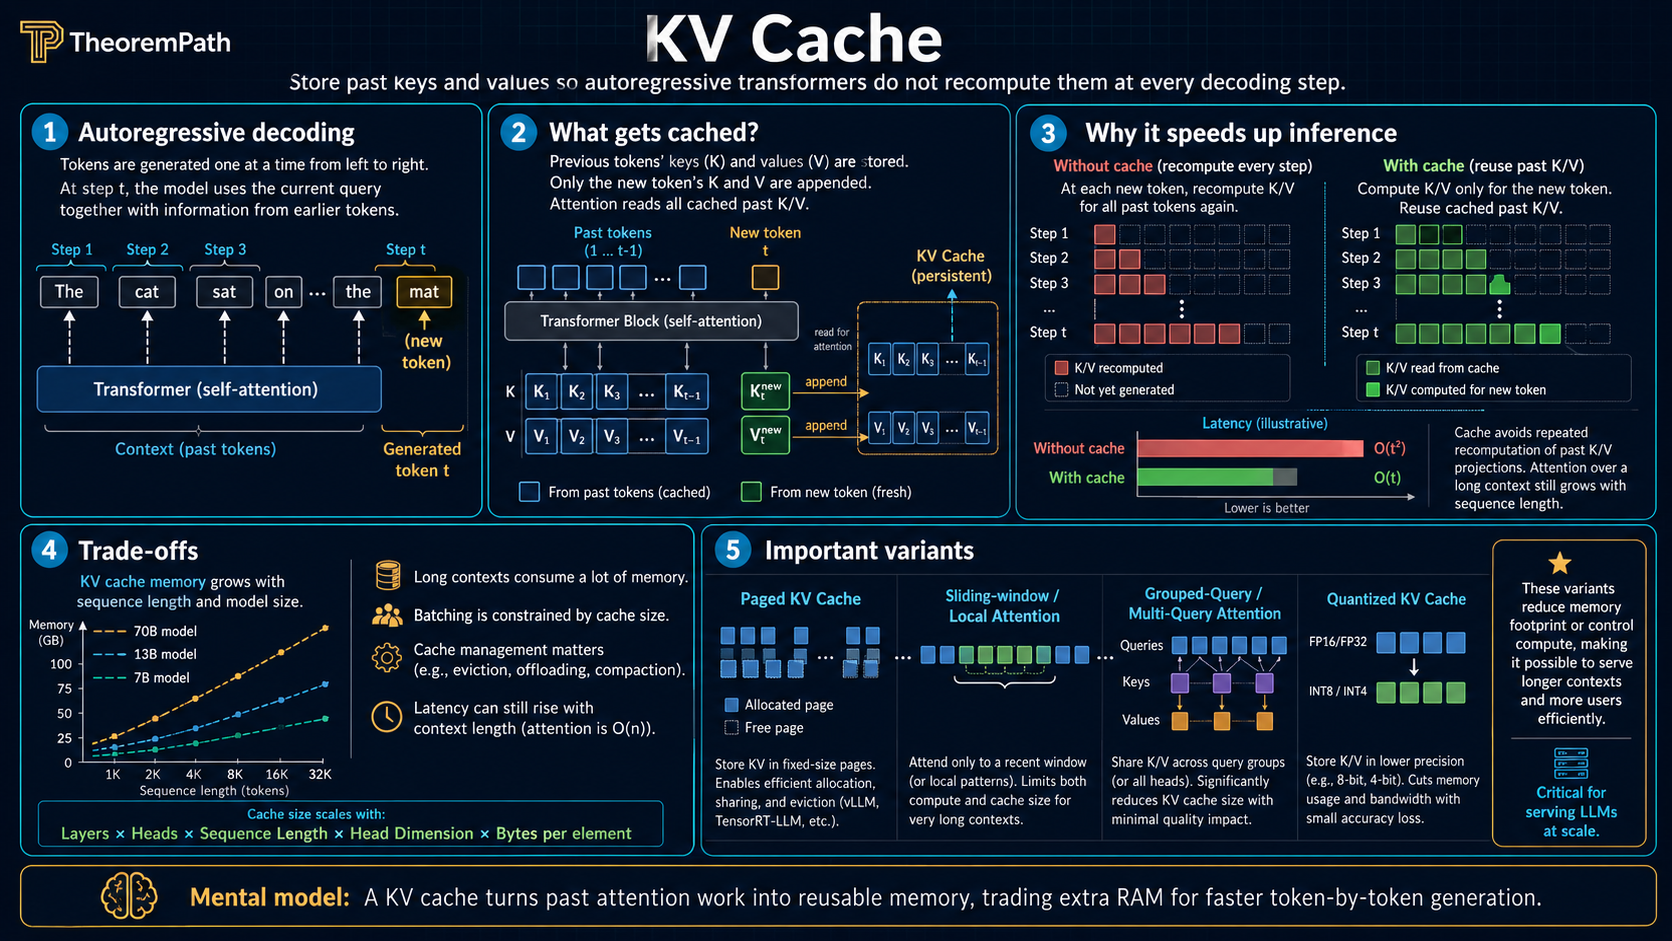
KV Cache. Inference Memory Bottleneck. LLM Construction | TheoremPath

LLM Inference: Accelerating Long Context Generation with KV Cache ...

LMCache: Accelerating LLM Inference with Smart KV Caching (Part 1 of 2 ...
Understanding LLM Batch Inference | Adaline