
Kv Cache Utilization Aware Load Balancing Llm Inference Handbook
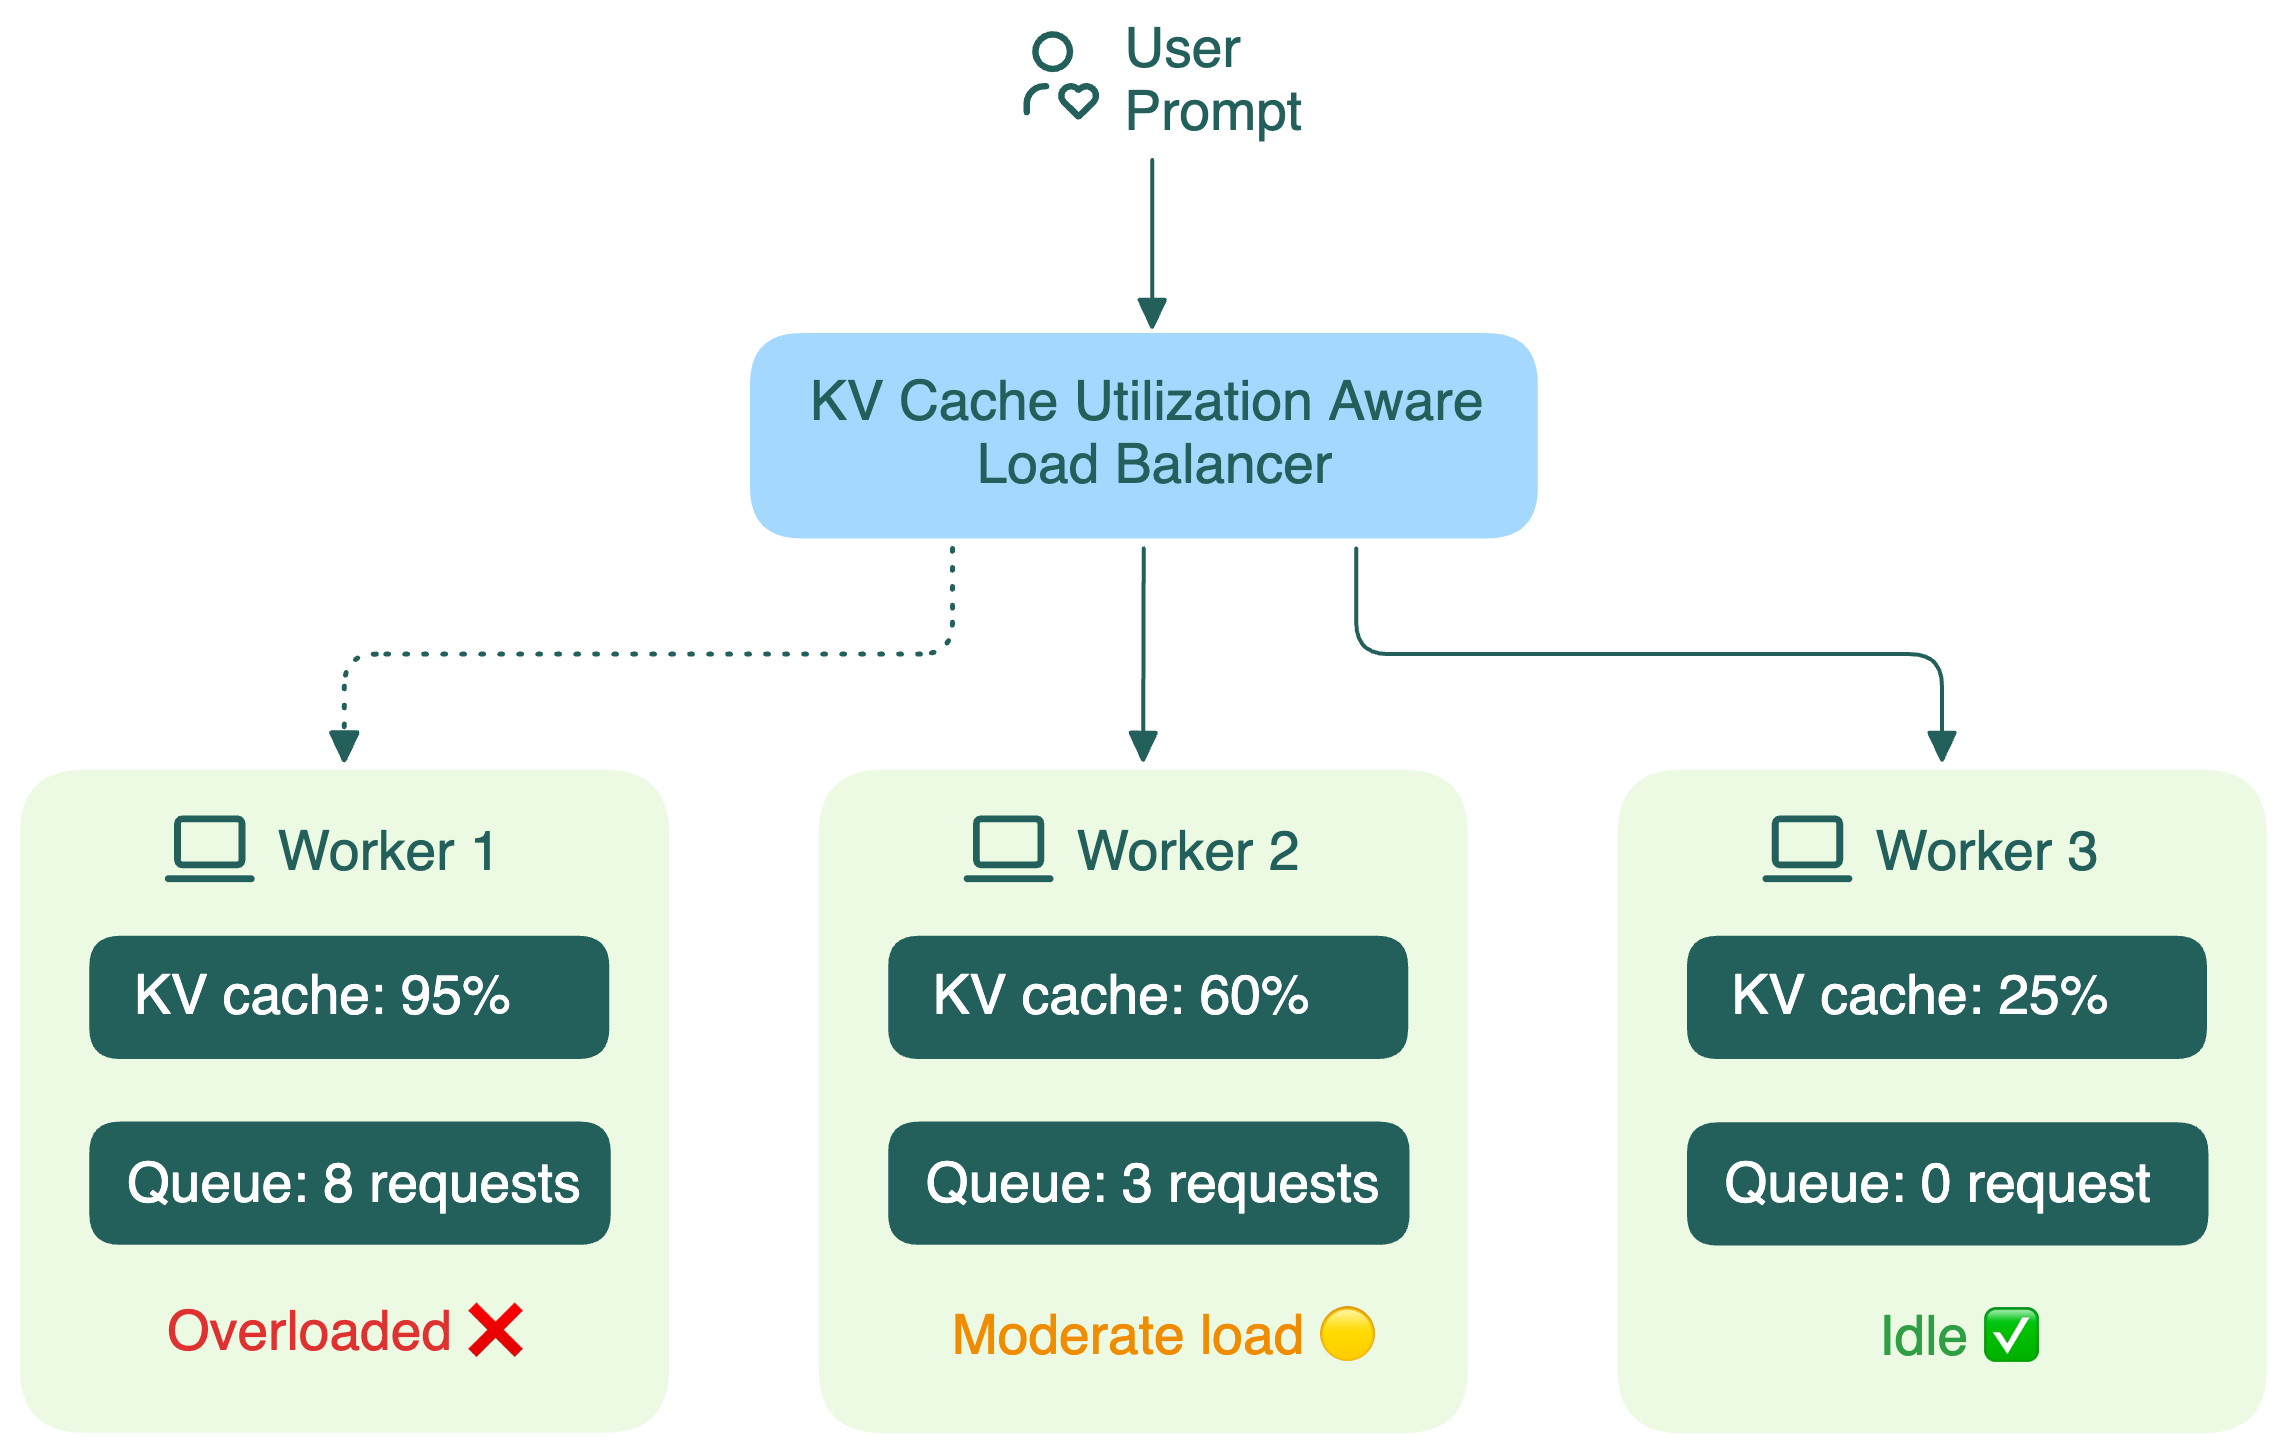
KV cache utilization-aware load balancing | LLM Inference Handbook

KV Cache Utilization-Aware Load Balancing - LLM Inference Handbook | PDF
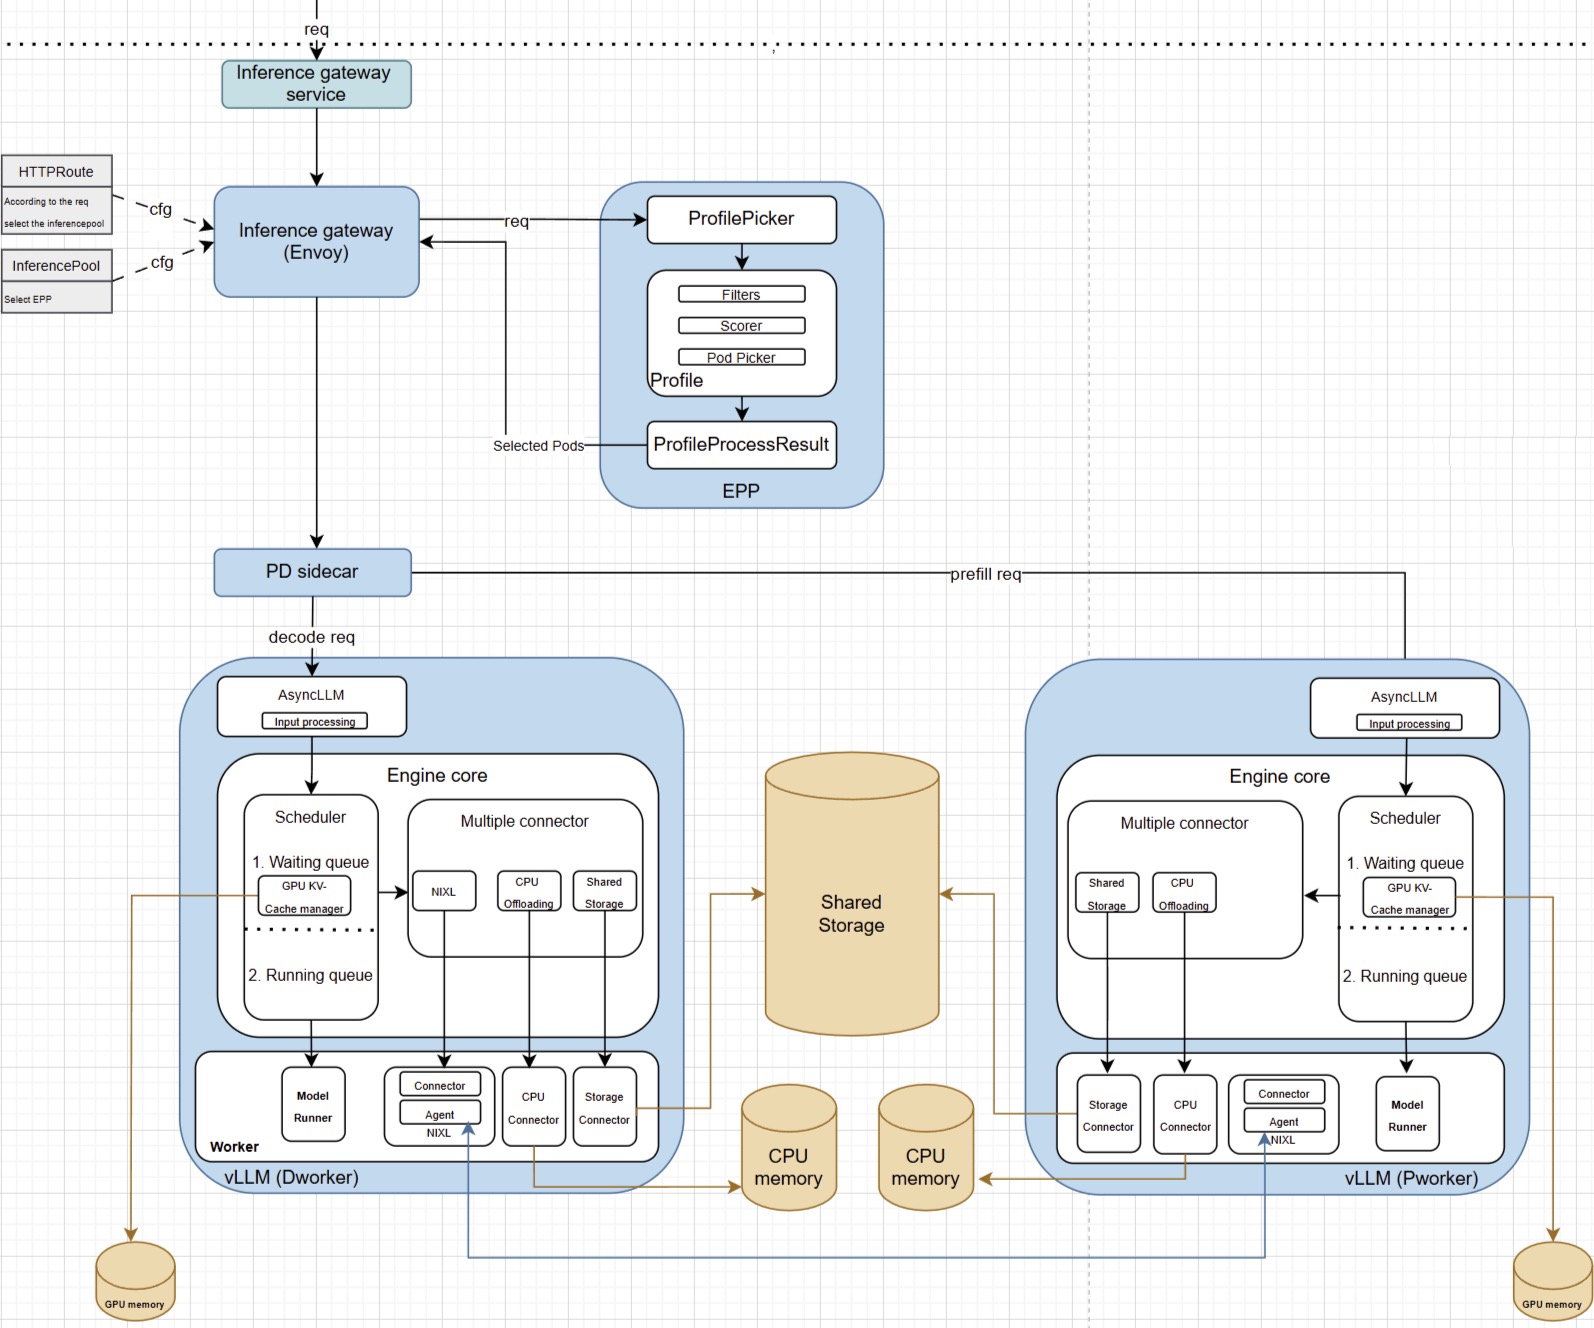
Master KV cache aware routing with llm-d for efficient AI inference ...

KVSharer: method for efficient LLM inference via dissimilar KV Cache ...
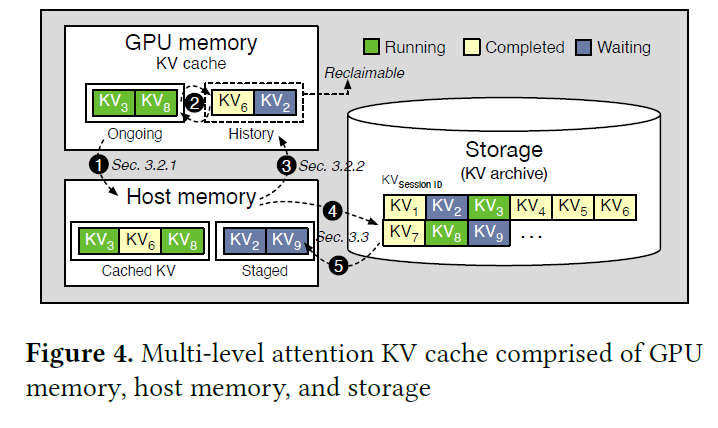
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...

KV Cache Reuse Is Quietly Reshaping LLM Inference Architecture | by ...

Scaling Multi-Turn LLM Inference with KV Cache Storage Offload and Dell ...

KVPR: Efficient LLM Inference with I/O-Aware KV Cache Partial ...
KV Cache State: Definition & Role in LLM Inference | Inference Systems

(PDF) Online Scheduling for LLM Inference with KV Cache Constraints
Advertisement Space (300x250)

Configure LLM Inference Load Balancing with ASM - Alibaba Cloud Service ...
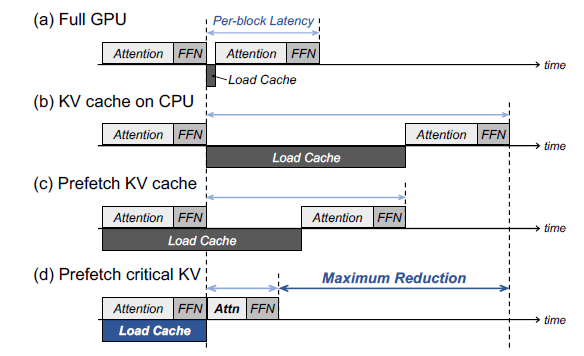
KVSharer: method for efficient LLM inference via dissimilar KV Cache ...
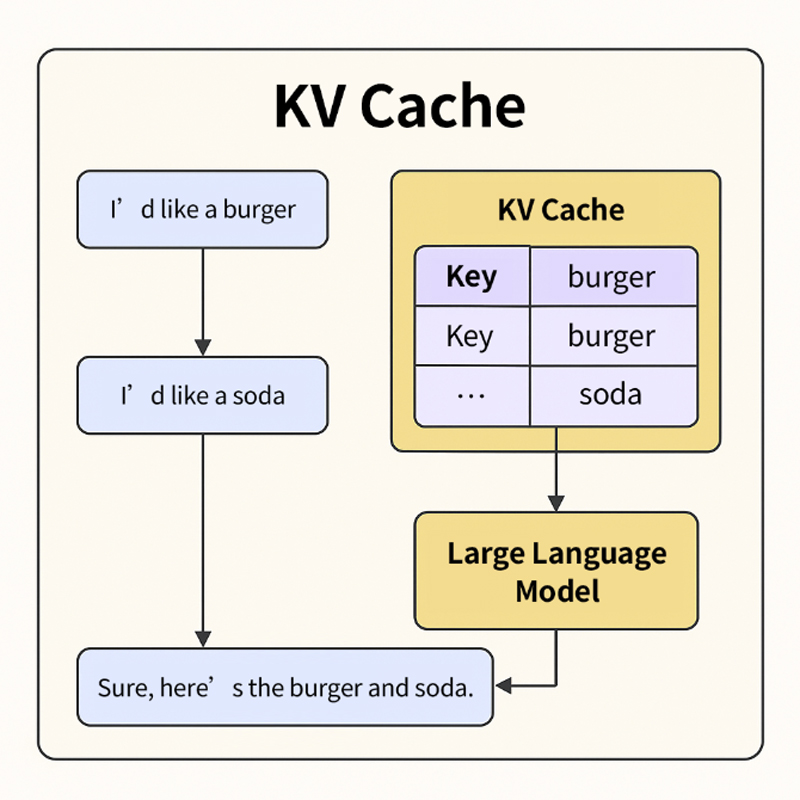
KV Cache Meets NVMe: The Key to Accelerating LLM Inference

[论文评述] Accelerating LLM Inference Throughput via Asynchronous KV Cache ...

(PDF) Efficient Long-Context LLM Inference via KV Cache Clustering

VecInfer: Efficient LLM Inference with Low-Bit KV Cache via Outlier ...

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

LLM Inference Bottleneck: KV Cache vs GPU Memory | Osama Altaf posted ...

Figure 1 from Accelerating LLM Inference via Dynamic KV Cache Placement ...
Advertisement Space (336x280)

KV Cache Transform Coding for Compact Storage in LLM Inference

LLM inference optimization: Architecture, KV cache and Flash attention ...

Accelerating LLM Inference Throughput via Asynchronous KV Cache Prefetching

LMCache: Accelerating LLM Inference with Smart KV Caching (Part 1 of 2 ...
What is KV Cache? | LLM Inference Optimization | Inference Systems
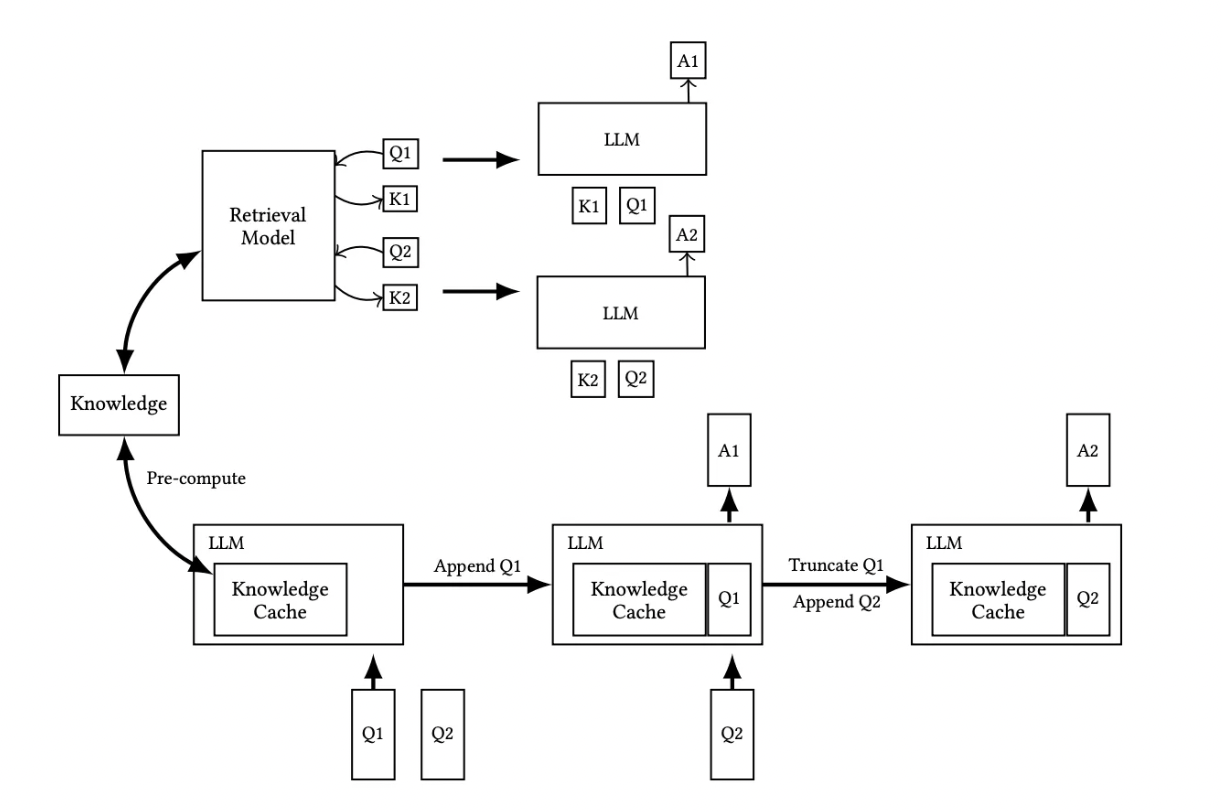
Optimizing LLM Inference: Managing the KV Cache | by Aalok Patwa | Medium

BanaServe: Unified KV Cache and Dynamic Module Migration for Balancing ...
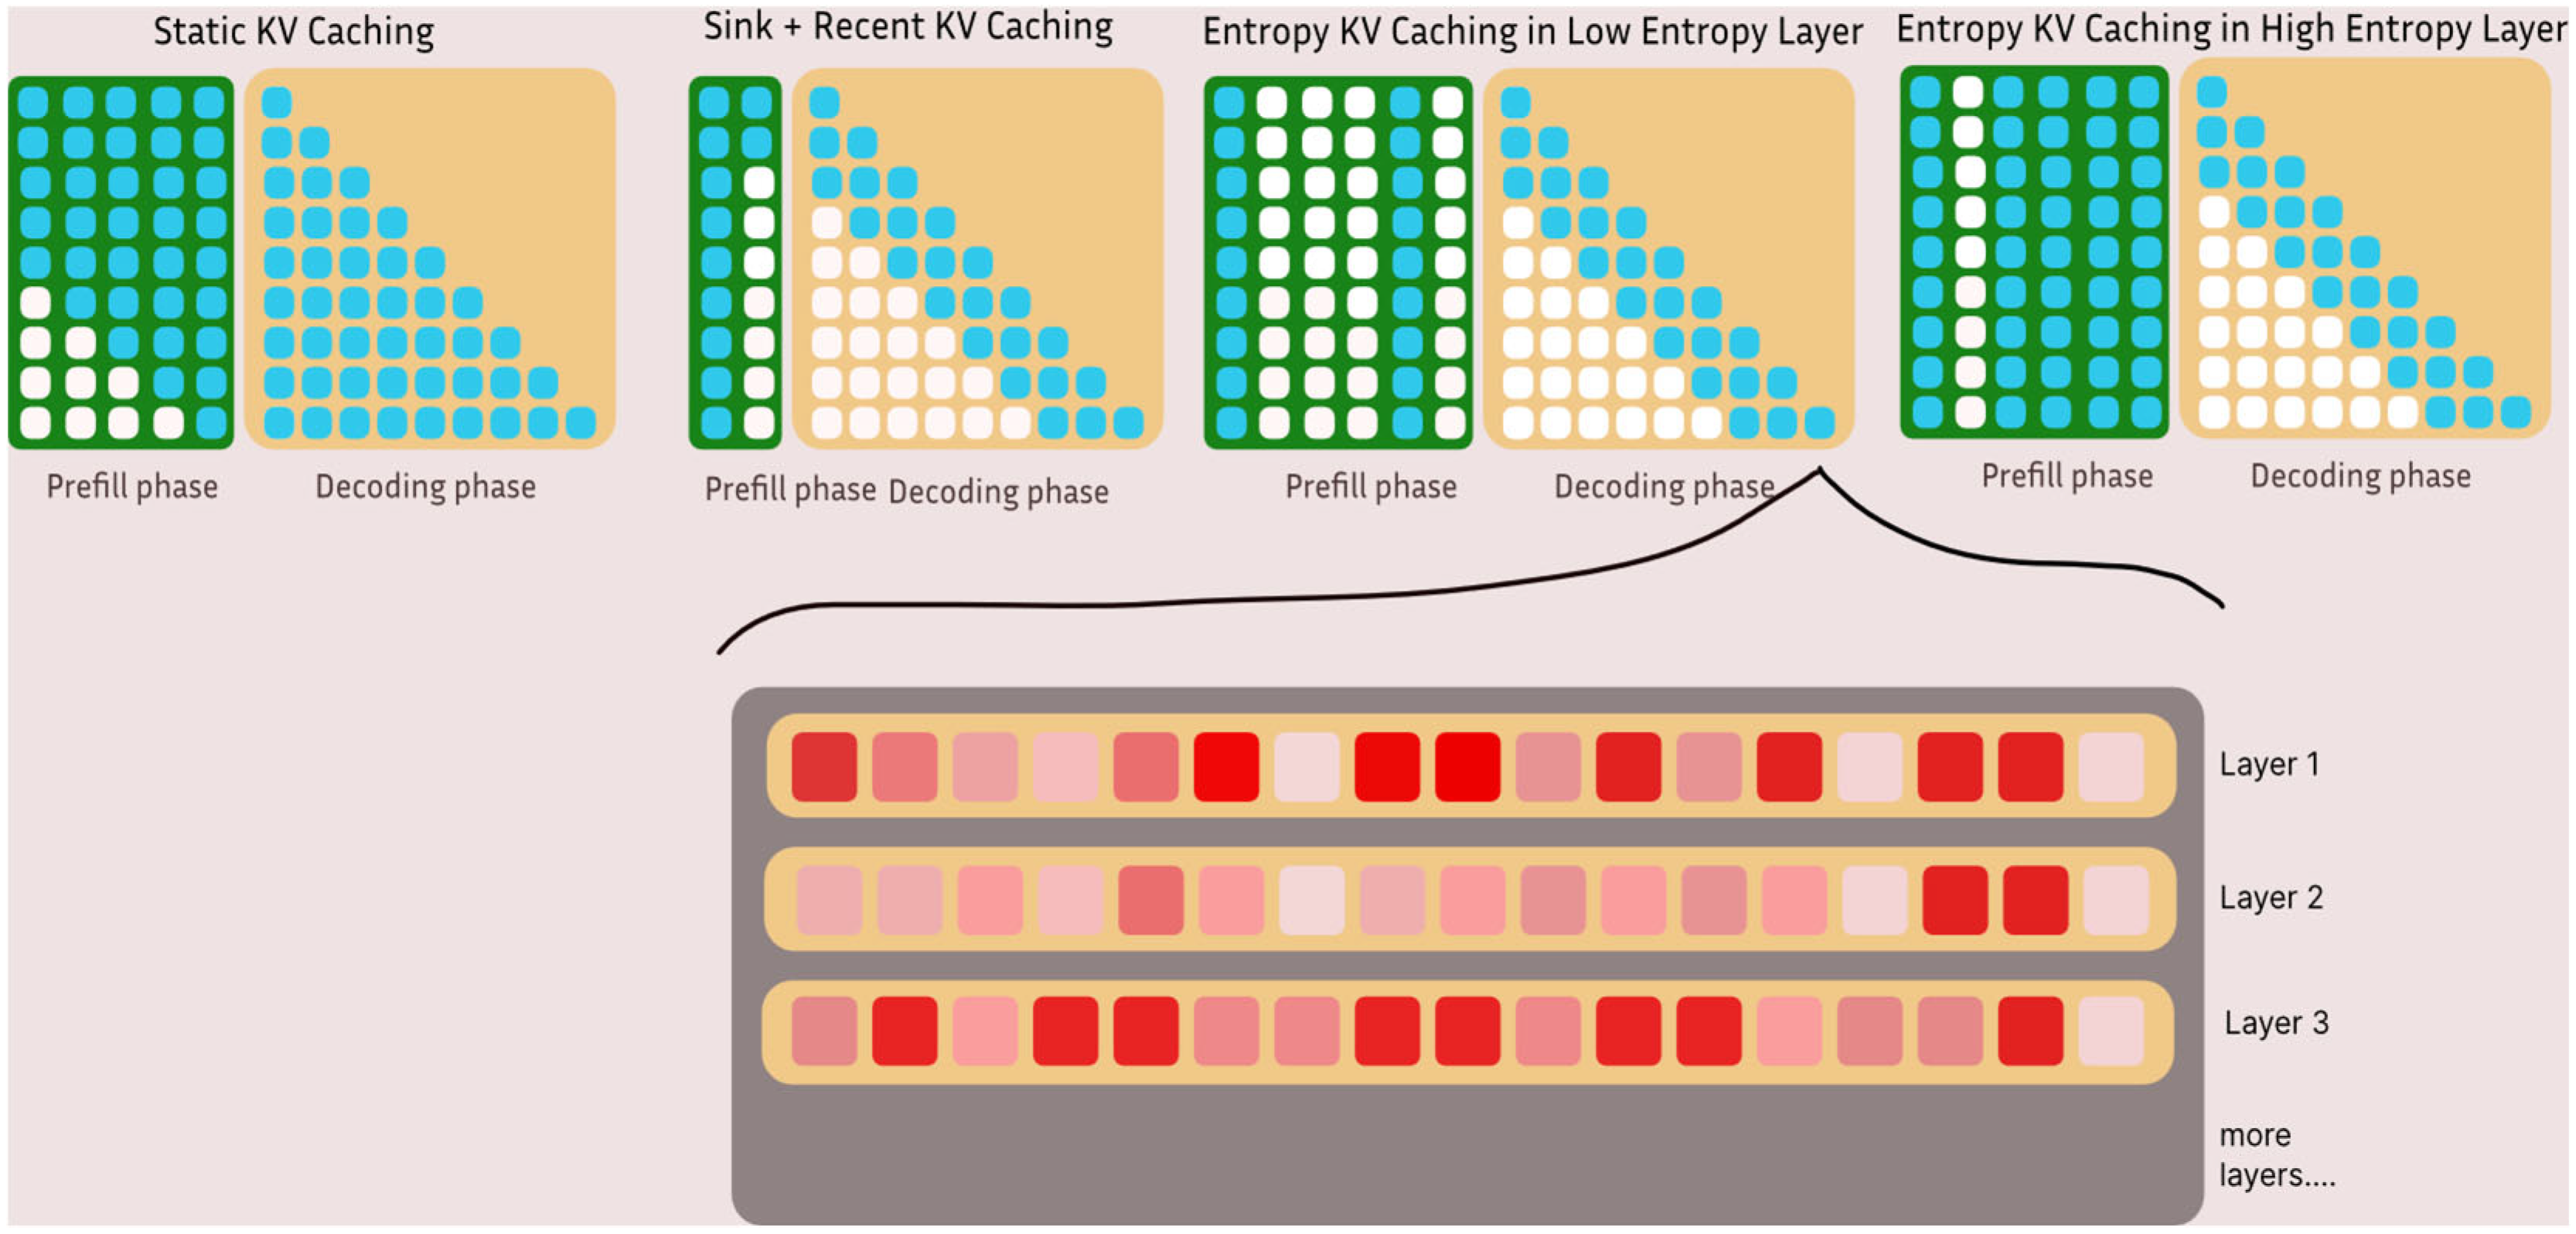
Entropy-Guided KV Caching for Efficient LLM Inference
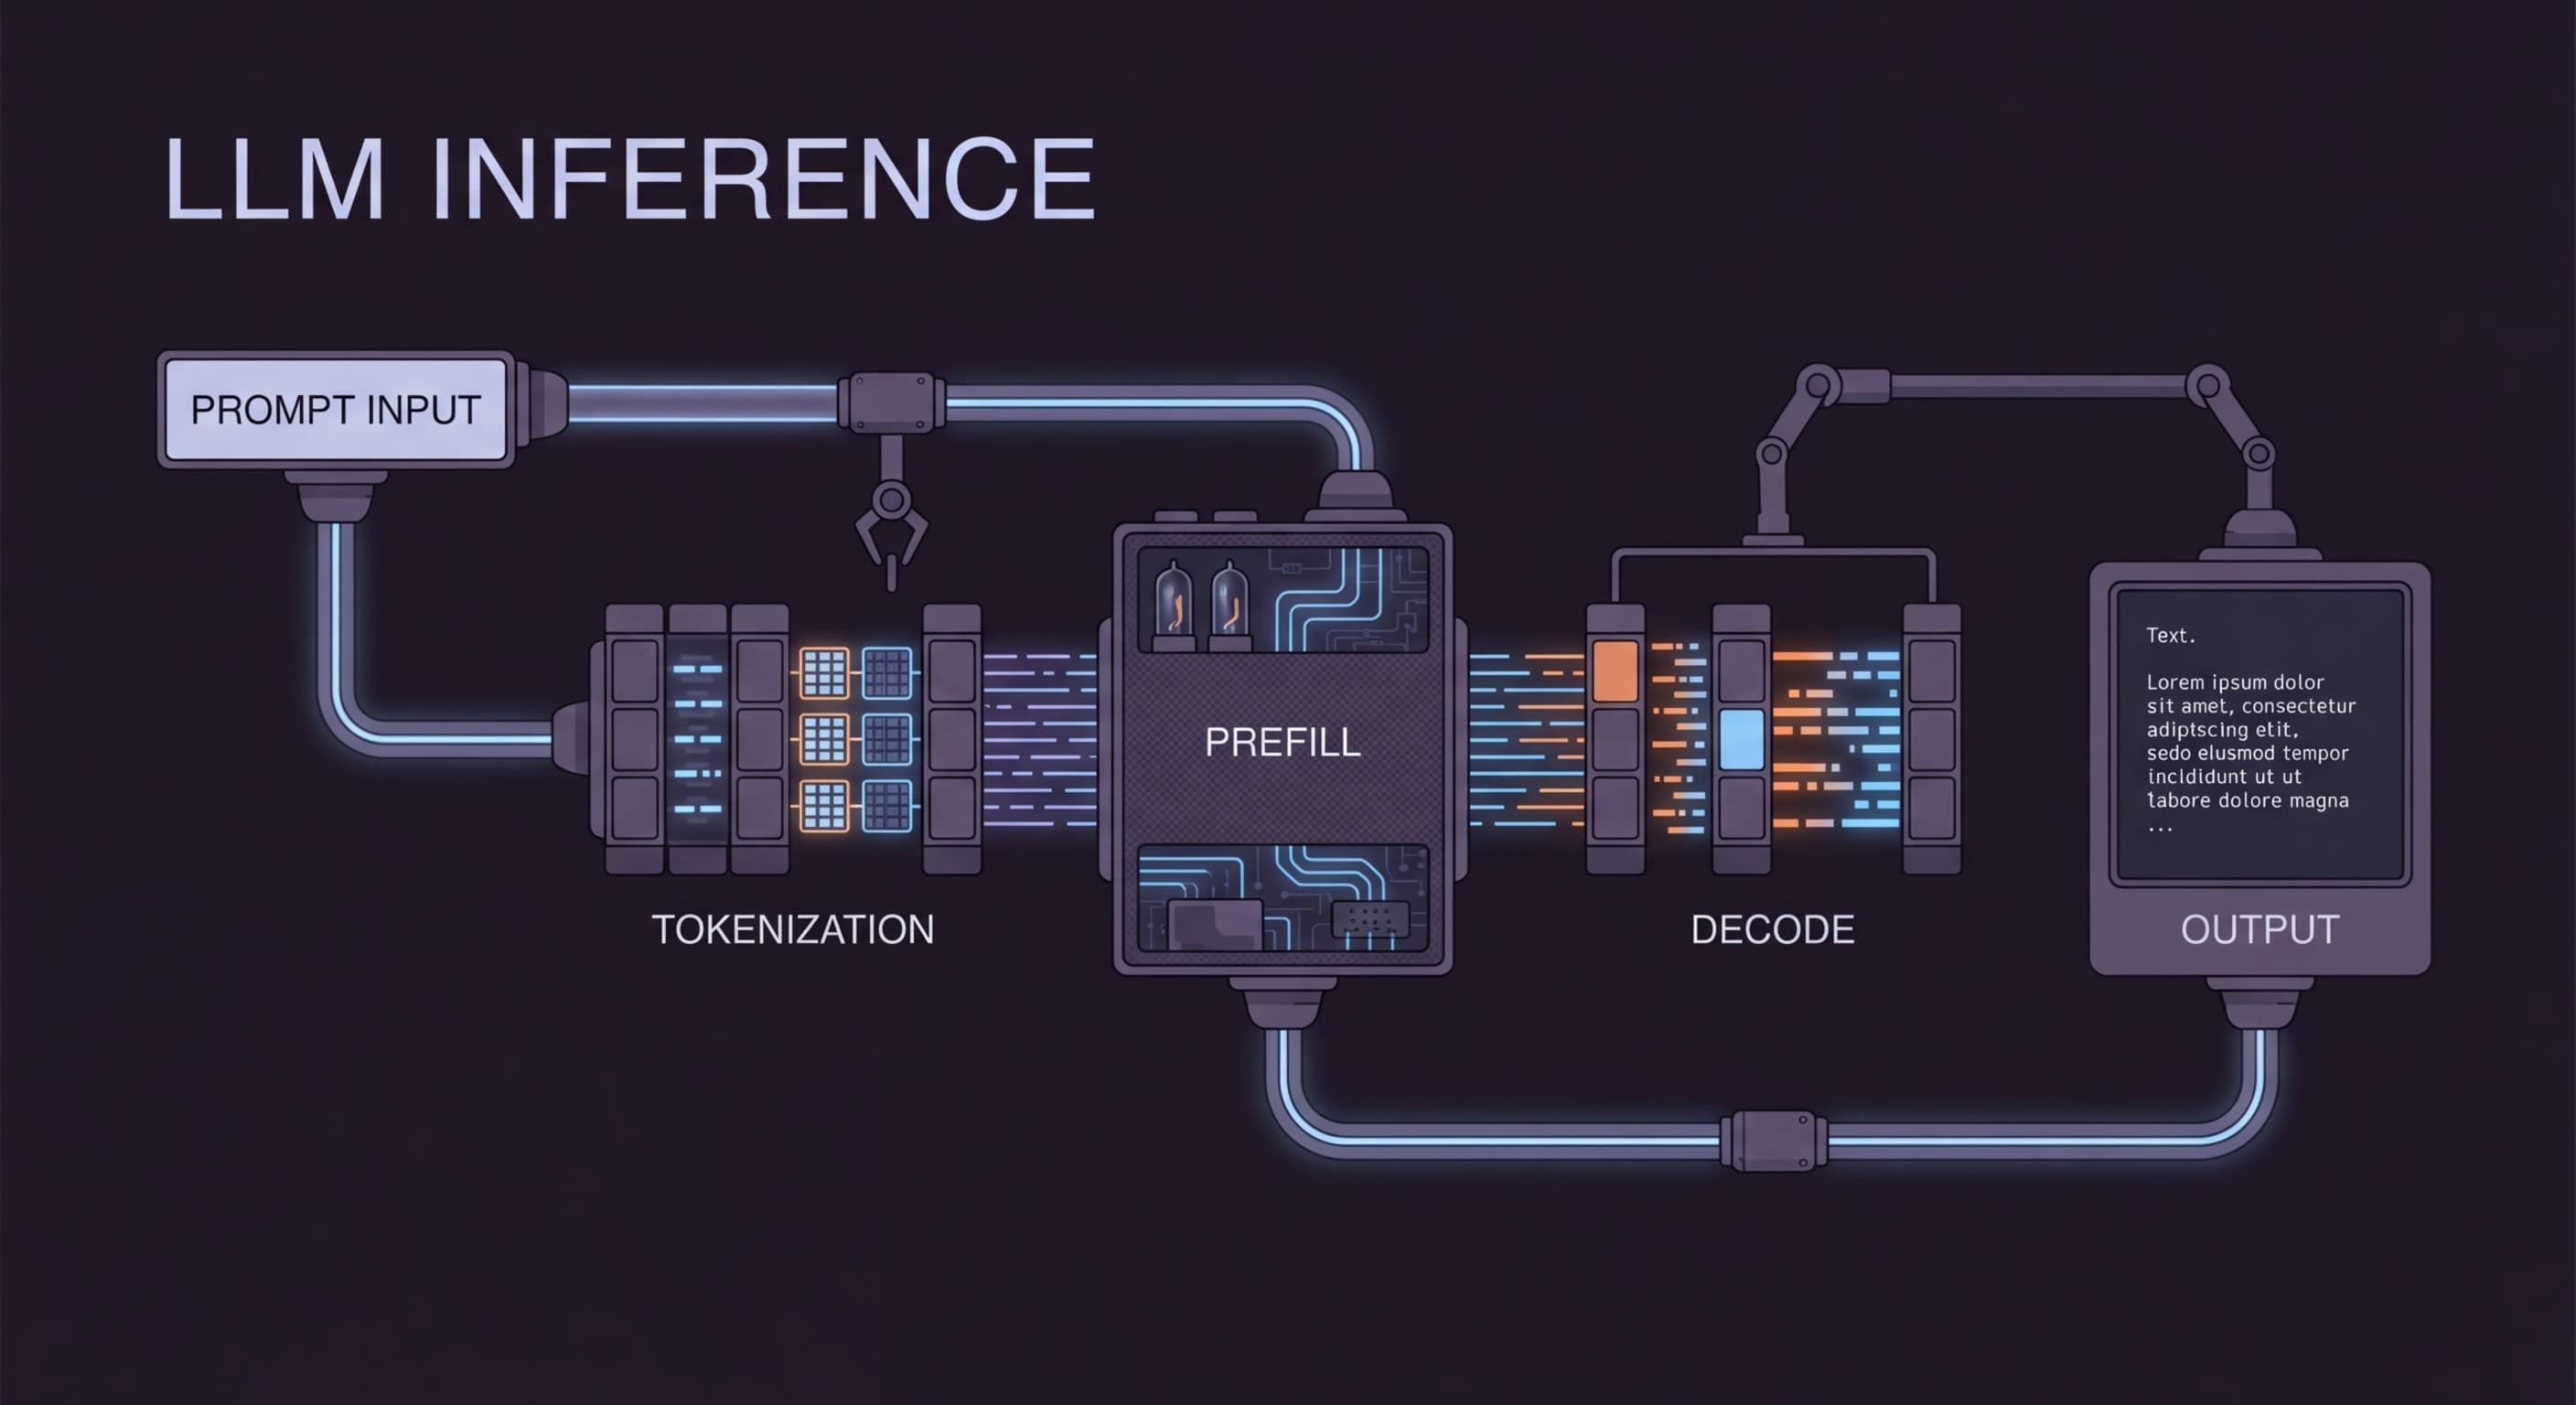
LLM Inference: Prefill, Decode, KV Cache & Cost Guide (2026) | Morph

Optimizing LLM Inference: Managing the KV Cache | by Aalok Patwa | Medium
Advertisement Space (336x280)
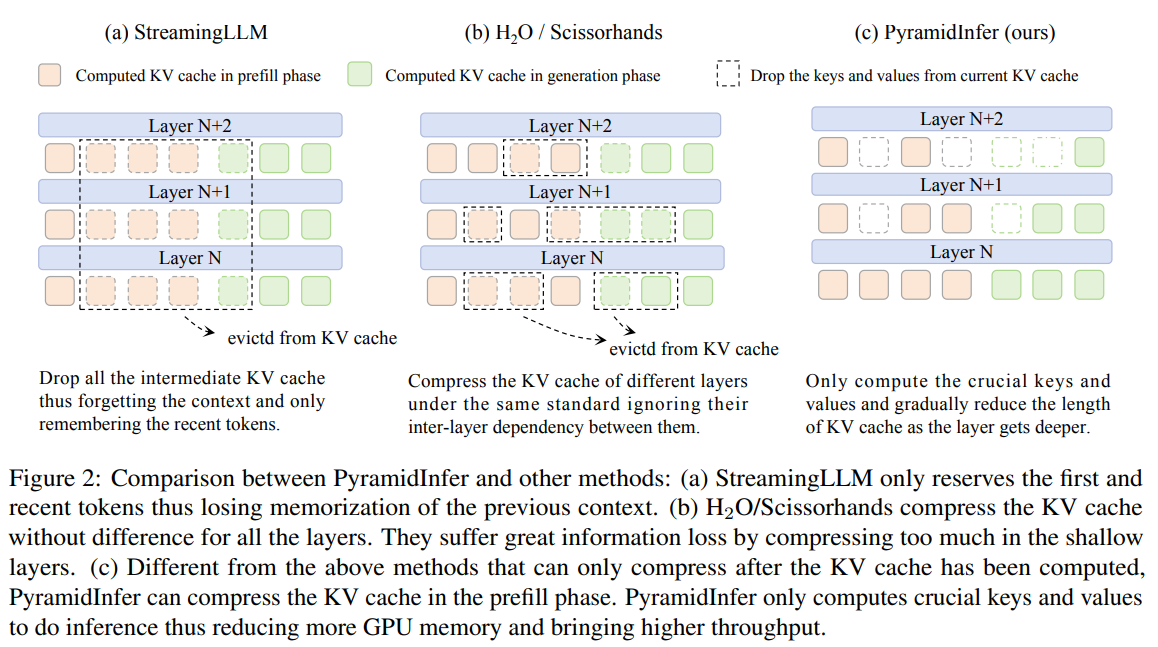
PyramidInfer: Allowing Efficient KV Cache Compression for Scalable LLM ...
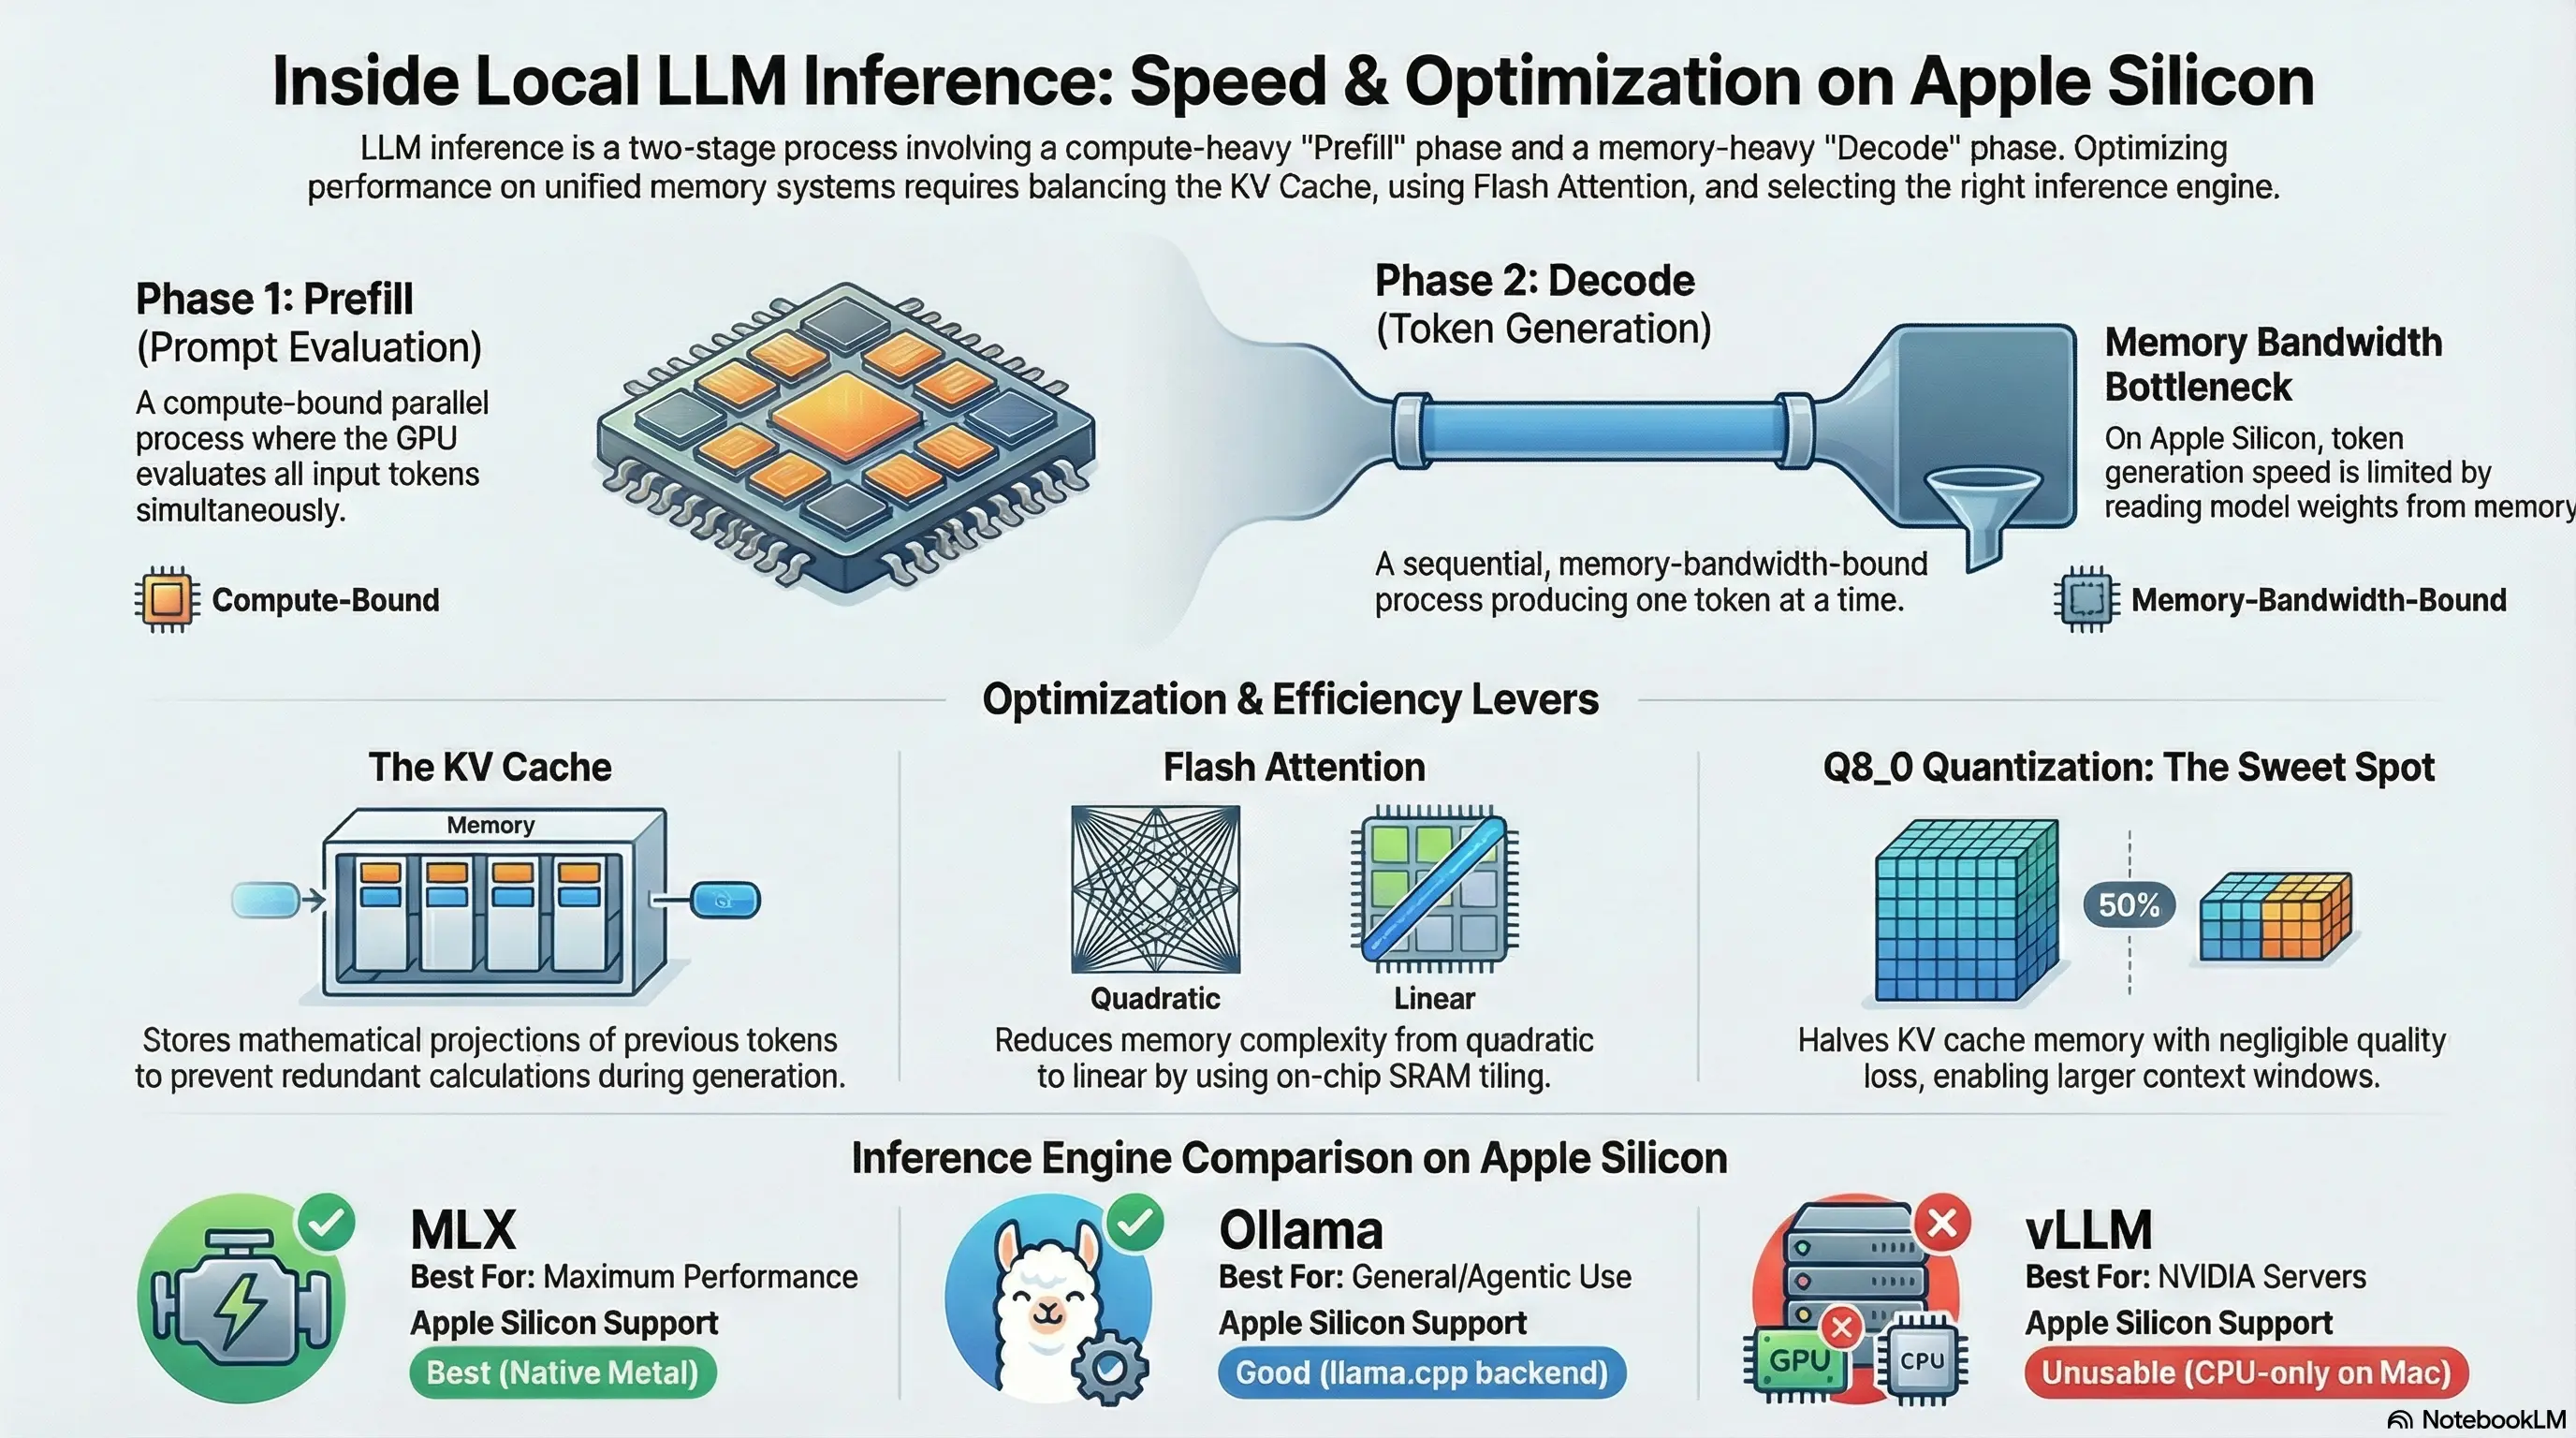
LLM Inference Internals: KV Cache, Flash Attention, and Optimizing for ...

Stateful KV Cache Management for LLMs: Balancing Space, Time, Accuracy ...
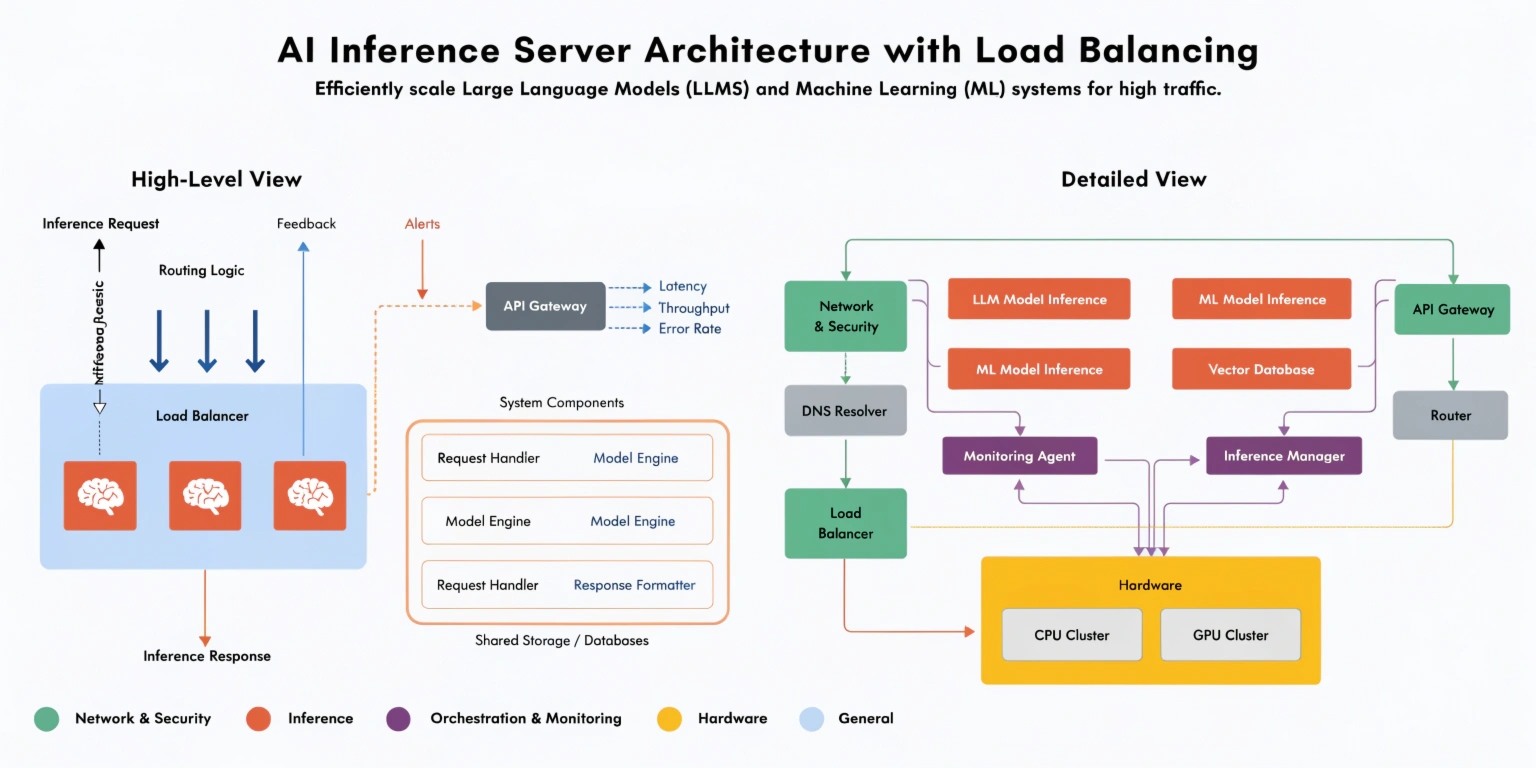
Load Balancing in AI Inference Servers | Scaling LLM, GPU Clusters ...

Comparative Characterization of KV Cache Management Strategies for LLM ...
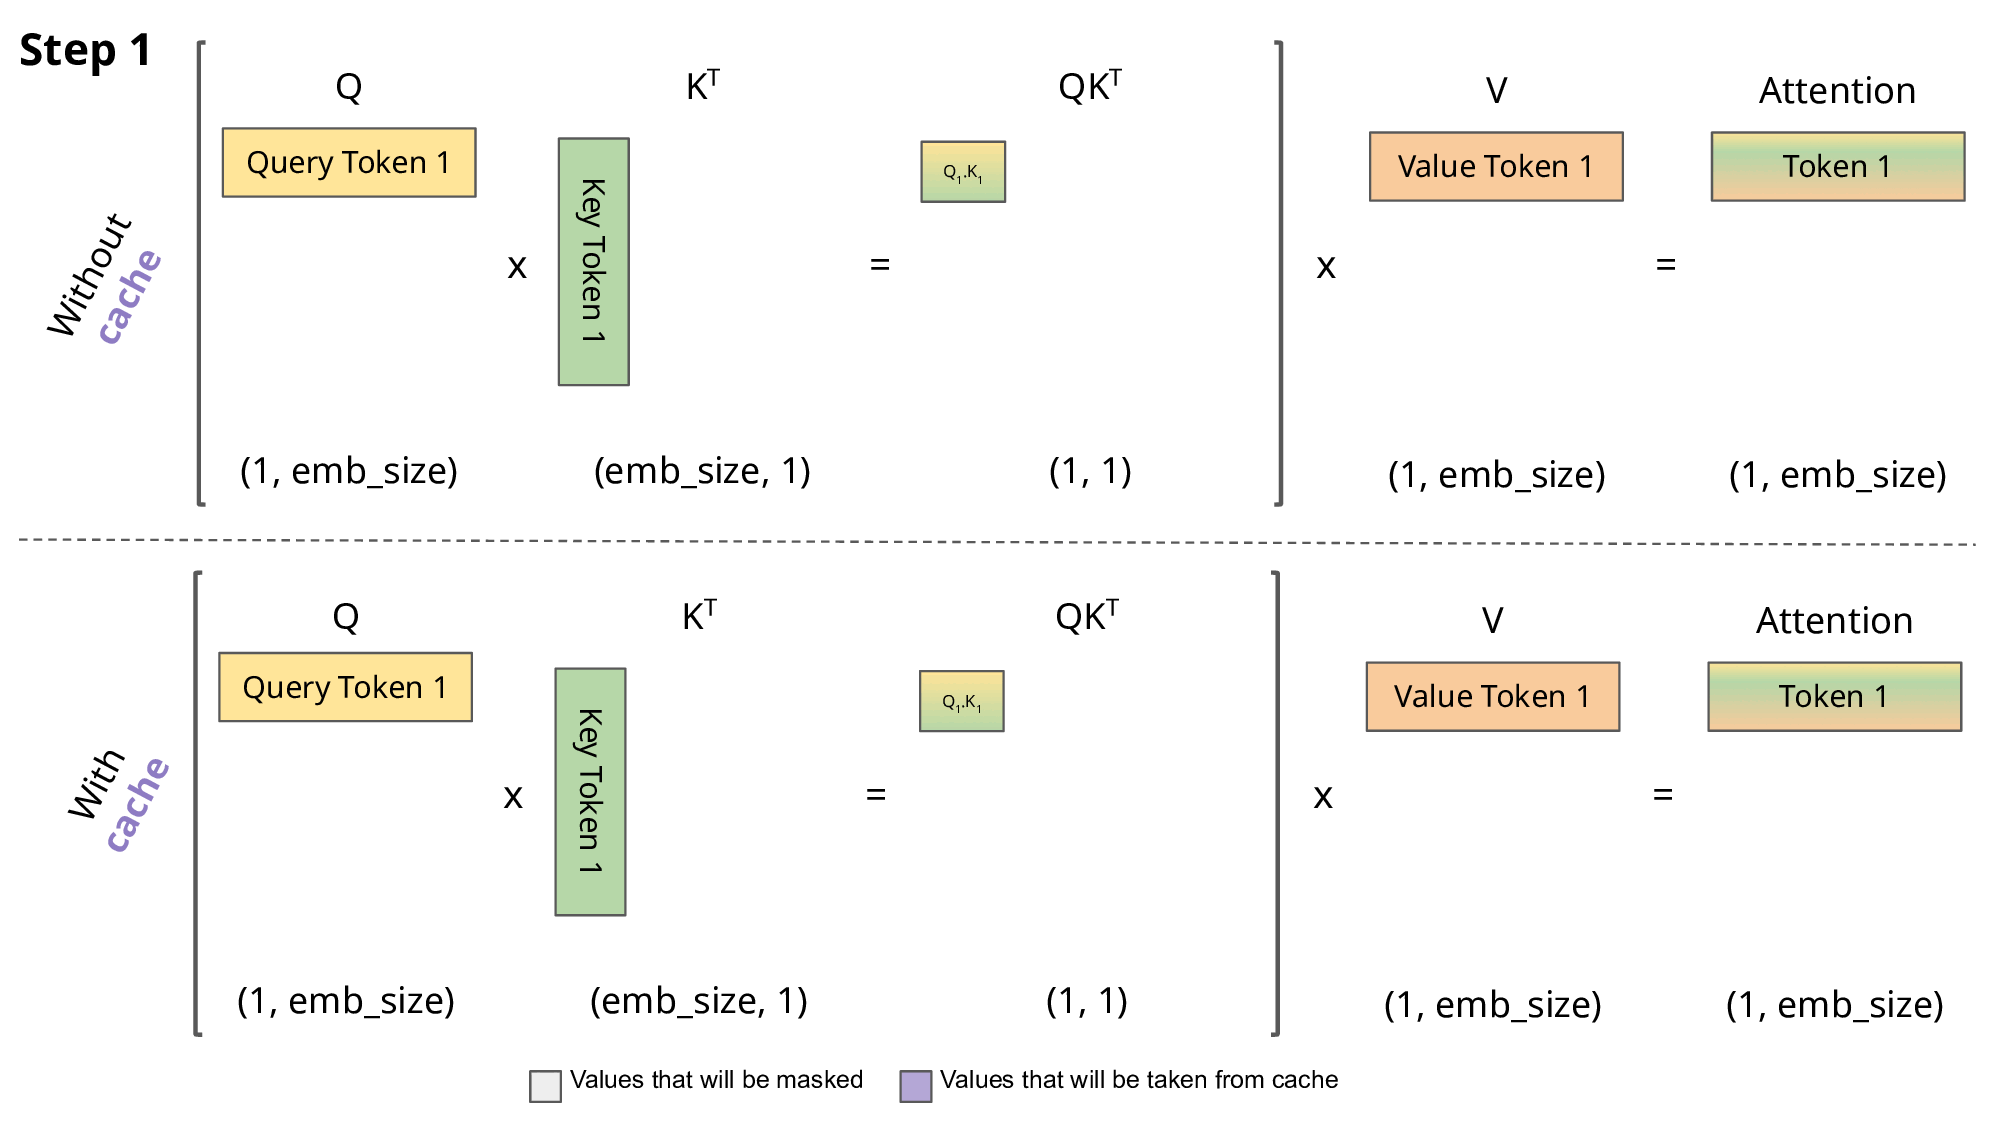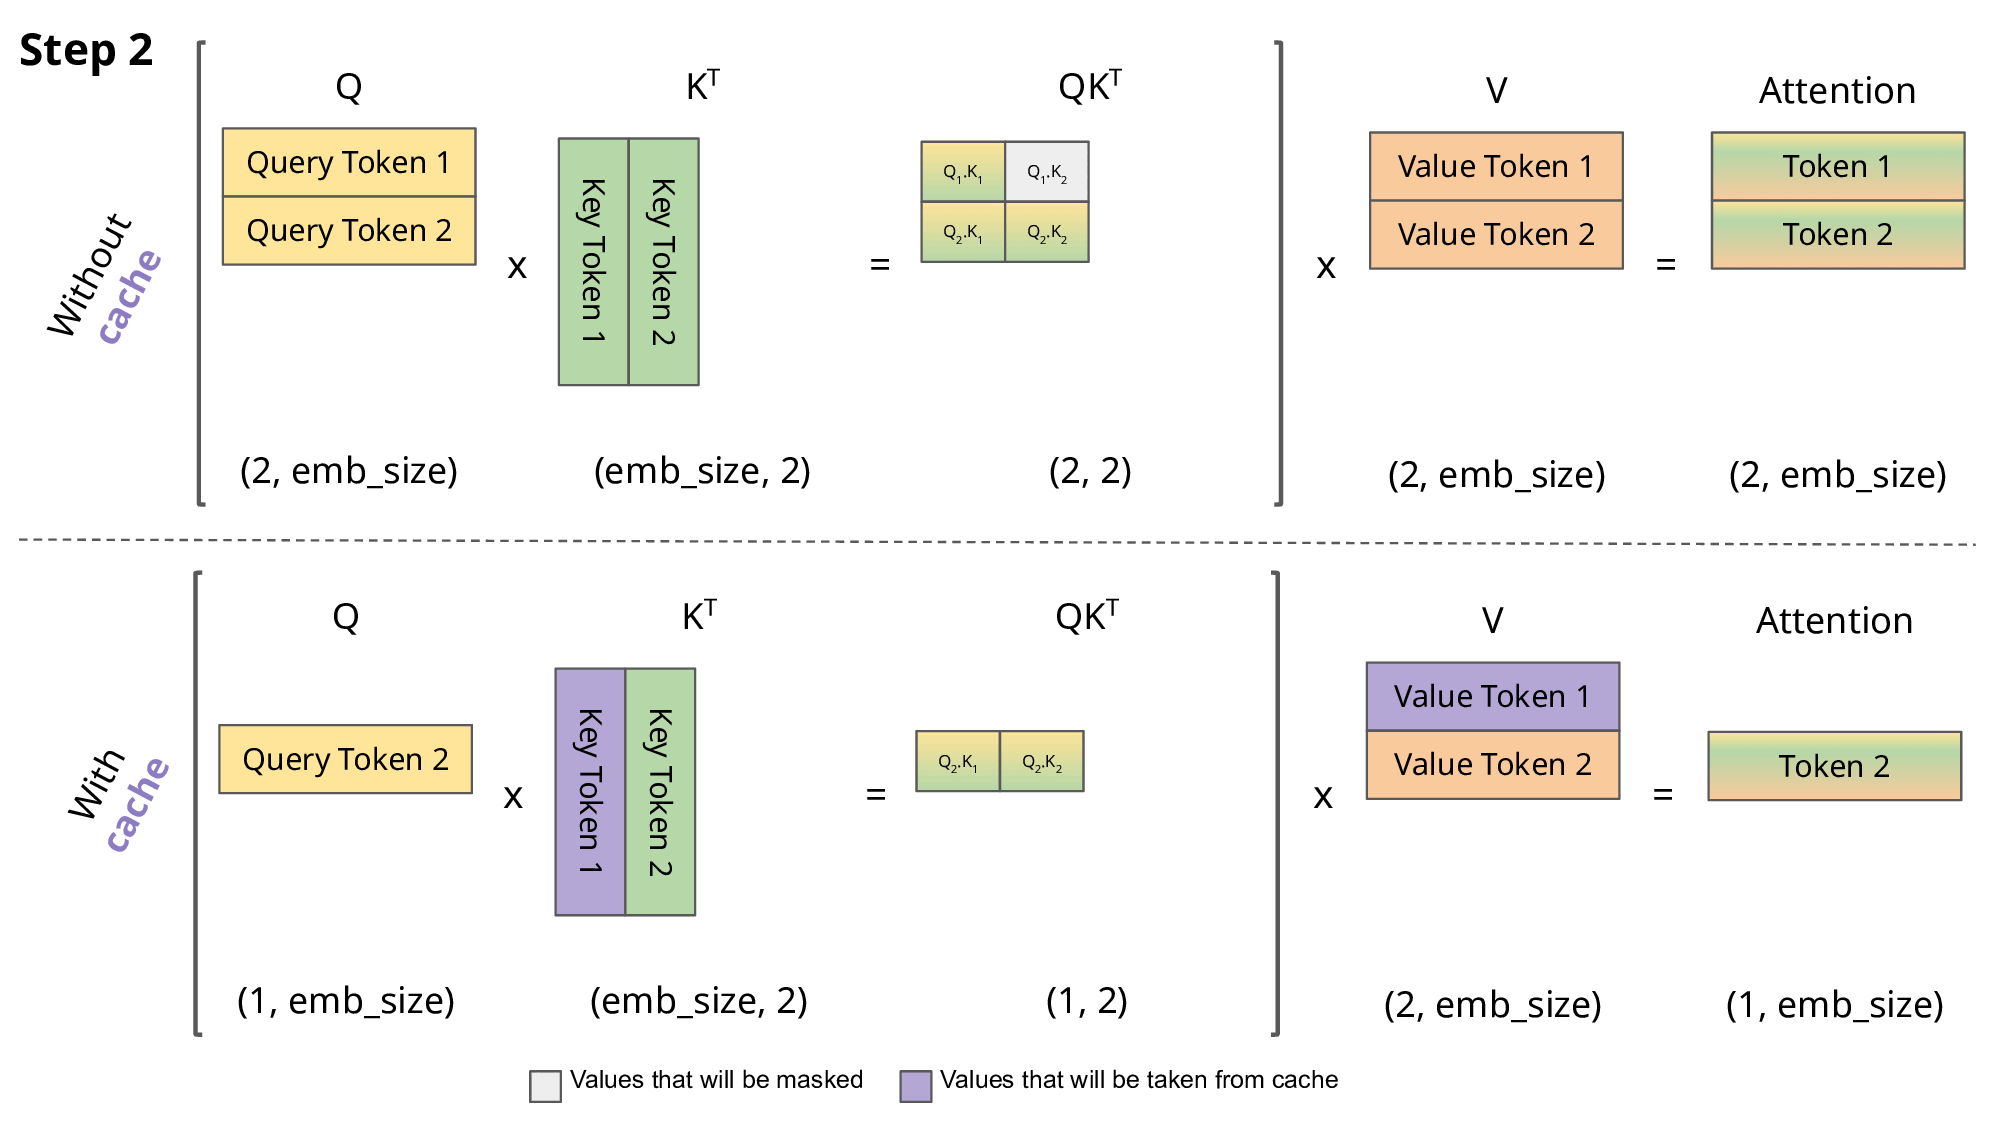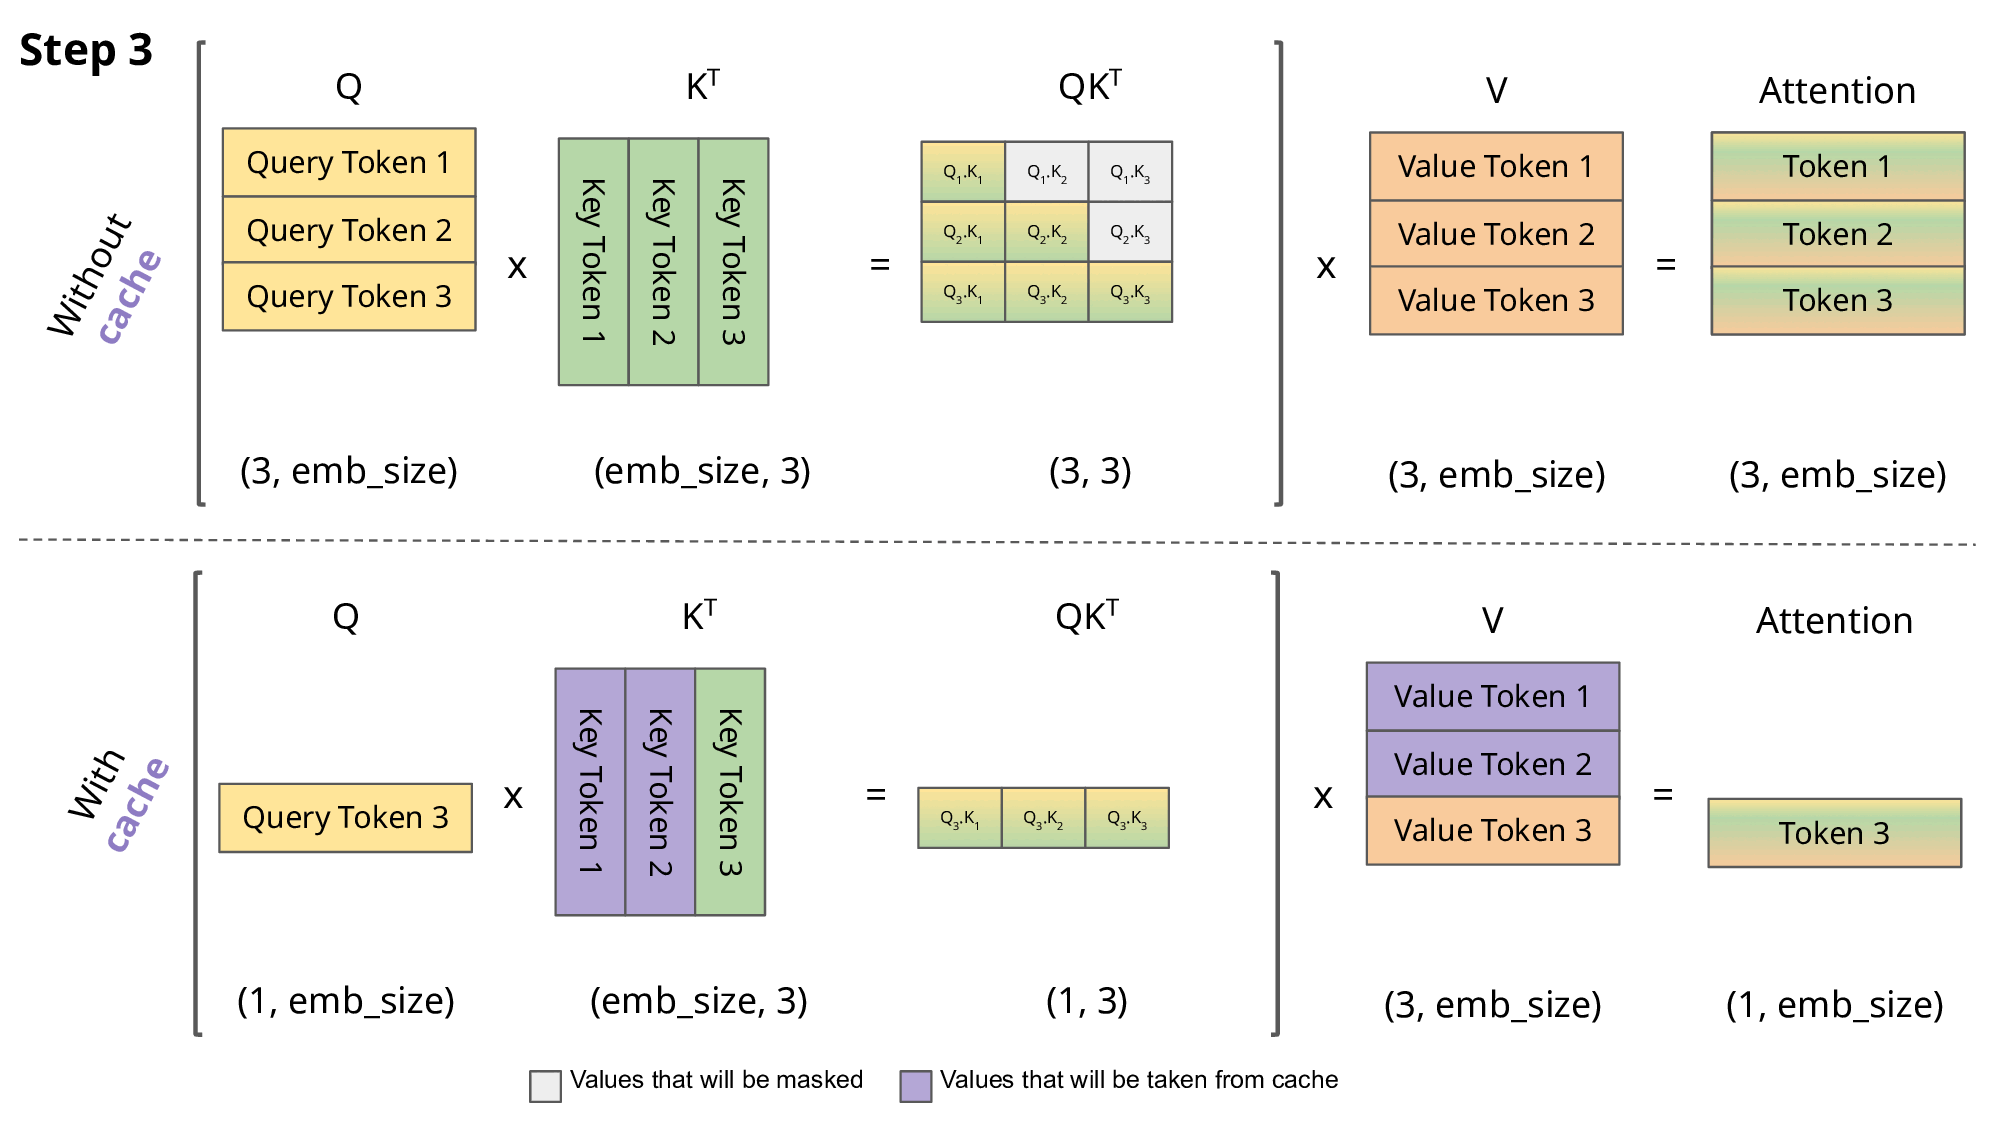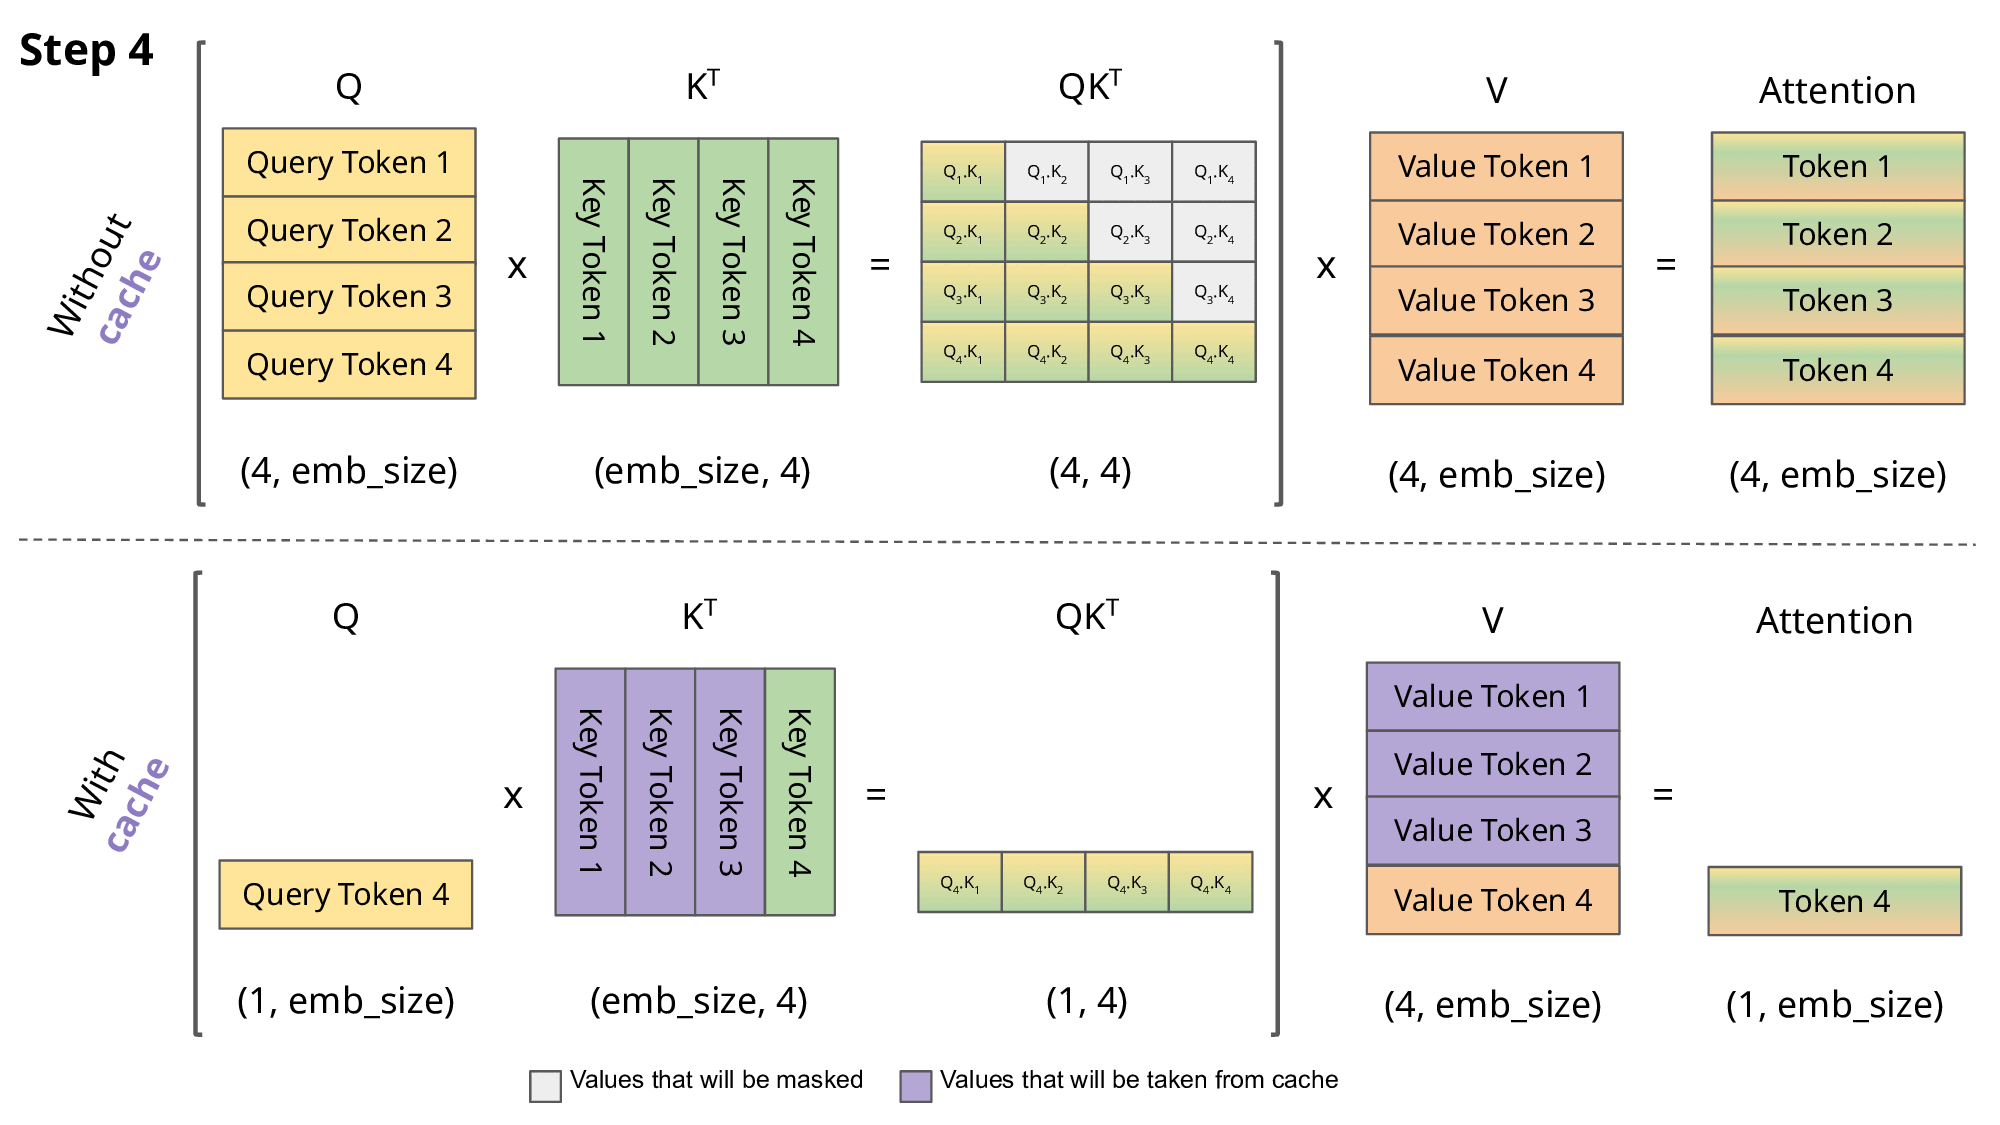
Optimizing LLM Inference: Managing the KV Cache | by Aalok Patwa | Medium