
Vllm Explained How Pagedattention Makes Llms Faster And Cheaper Dev

vLLM Explained: How PagedAttention Makes LLMs Faster and Cheaper - DEV ...

vLLM Explained: How PagedAttention Makes LLMs Faster and Cheaper - DEV ...
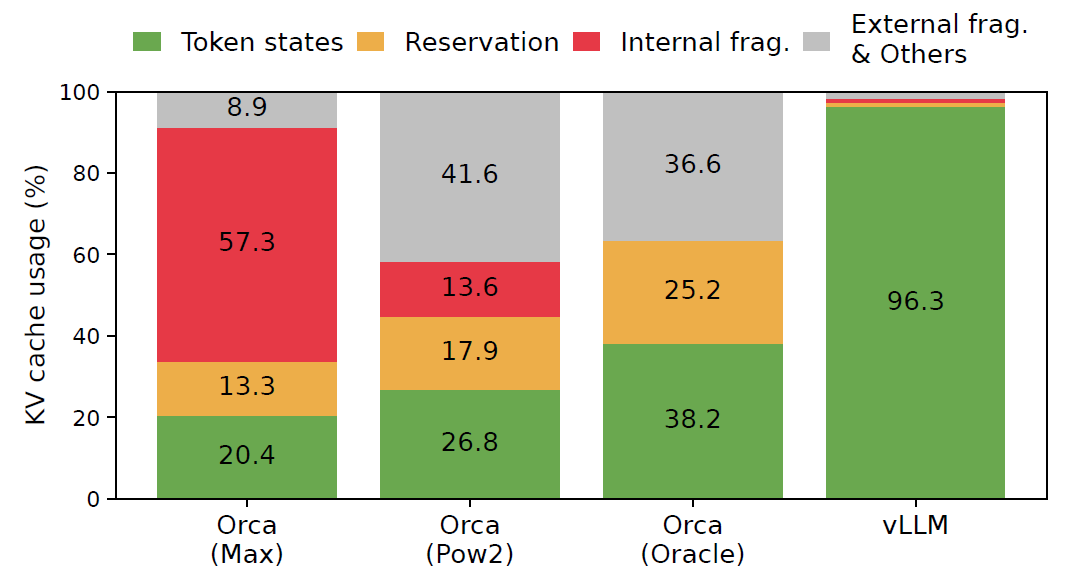
PagedAttention and vLLM serve Large Language Models faster and cheaper ...

PagedAttention and vLLM serve Large Language Models faster and cheaper ...
PagedAttention and vLLM serve Large Language Models faster and cheaper ...

PagedAttention and vLLM serve Large Language Models faster and cheaper ...

PagedAttention and vLLM serve Large Language Models faster and cheaper ...

PagedAttention and vLLM serve Large Language Models faster and cheaper ...

vLLM Throughput Guide - PagedAttention and Batching Tips (2026)

Optimizing LLM Deployment: vLLM PagedAttention and the Future of ...
Advertisement Space (300x250)
Ray Summit 2023 - Fast LLM Serving with vLLM and PagedAttention

Introduction to vLLM and PagedAttention | Runpod Blog

Free Video: Fast LLM Serving with vLLM and PagedAttention from Anyscale ...

vLLM and PagedAttention is the best for fast Large Language Models ...
vLLM Python 2026 : servir des LLMs en production — PagedAttention ...

vLLM Explained in 10 Minutes: Faster LLM Serving - YouTube
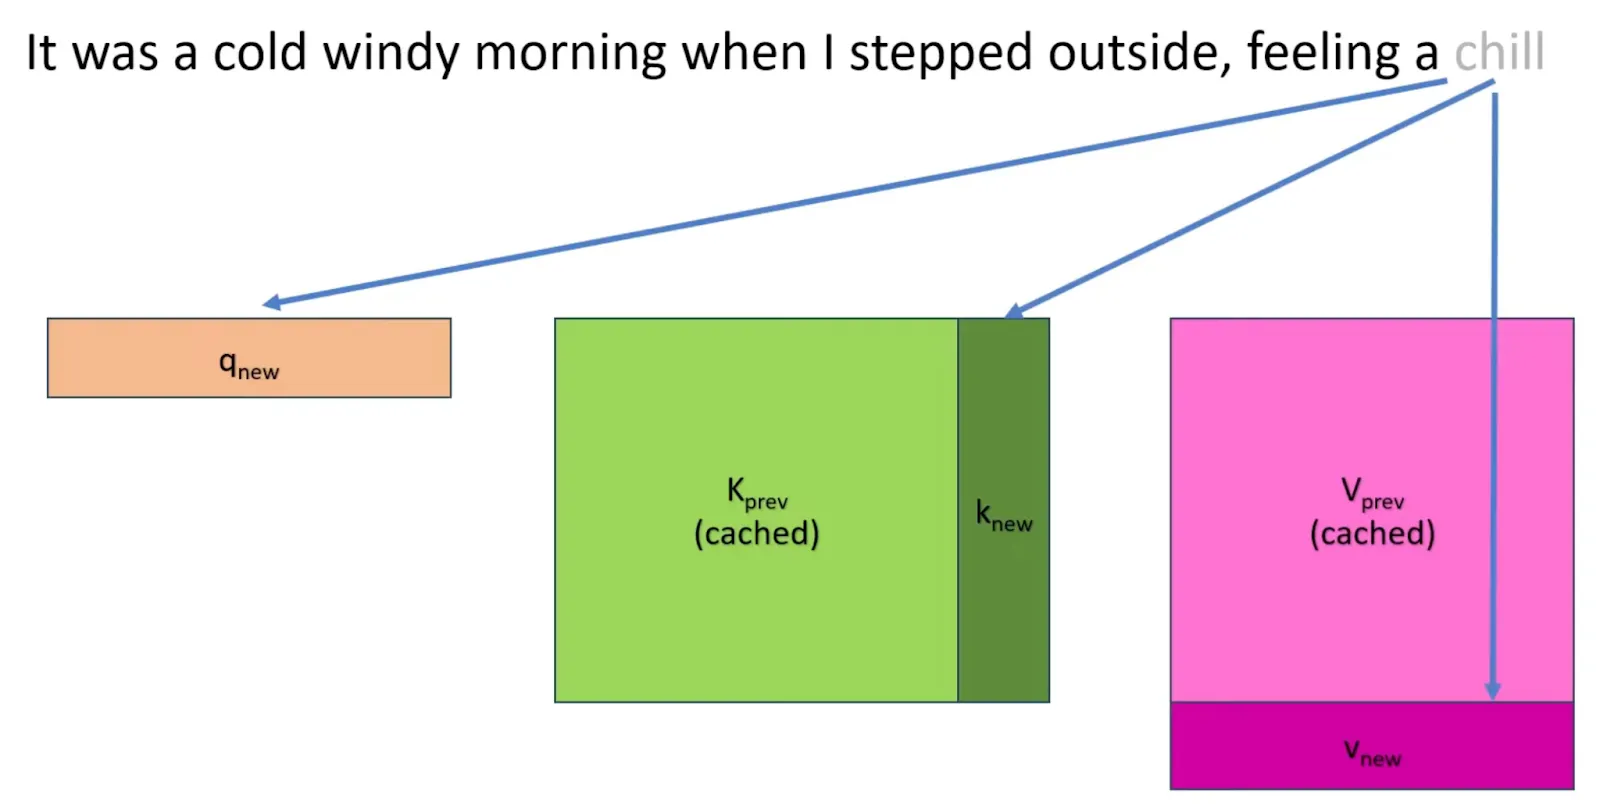
Introduction to vLLM and PagedAttention | Runpod Blog

Introduction to vLLM and PagedAttention | Runpod Blog

GraphRAG local setup via vLLM and Ollama : A detailed integration guide ...
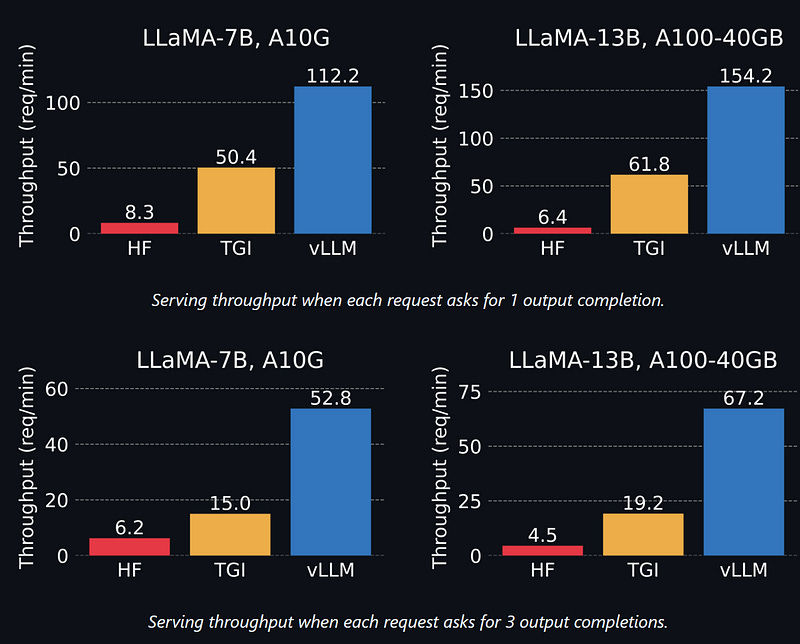
vLLM: PagedAttention for 24x Faster LLM Inference
Advertisement Space (336x280)
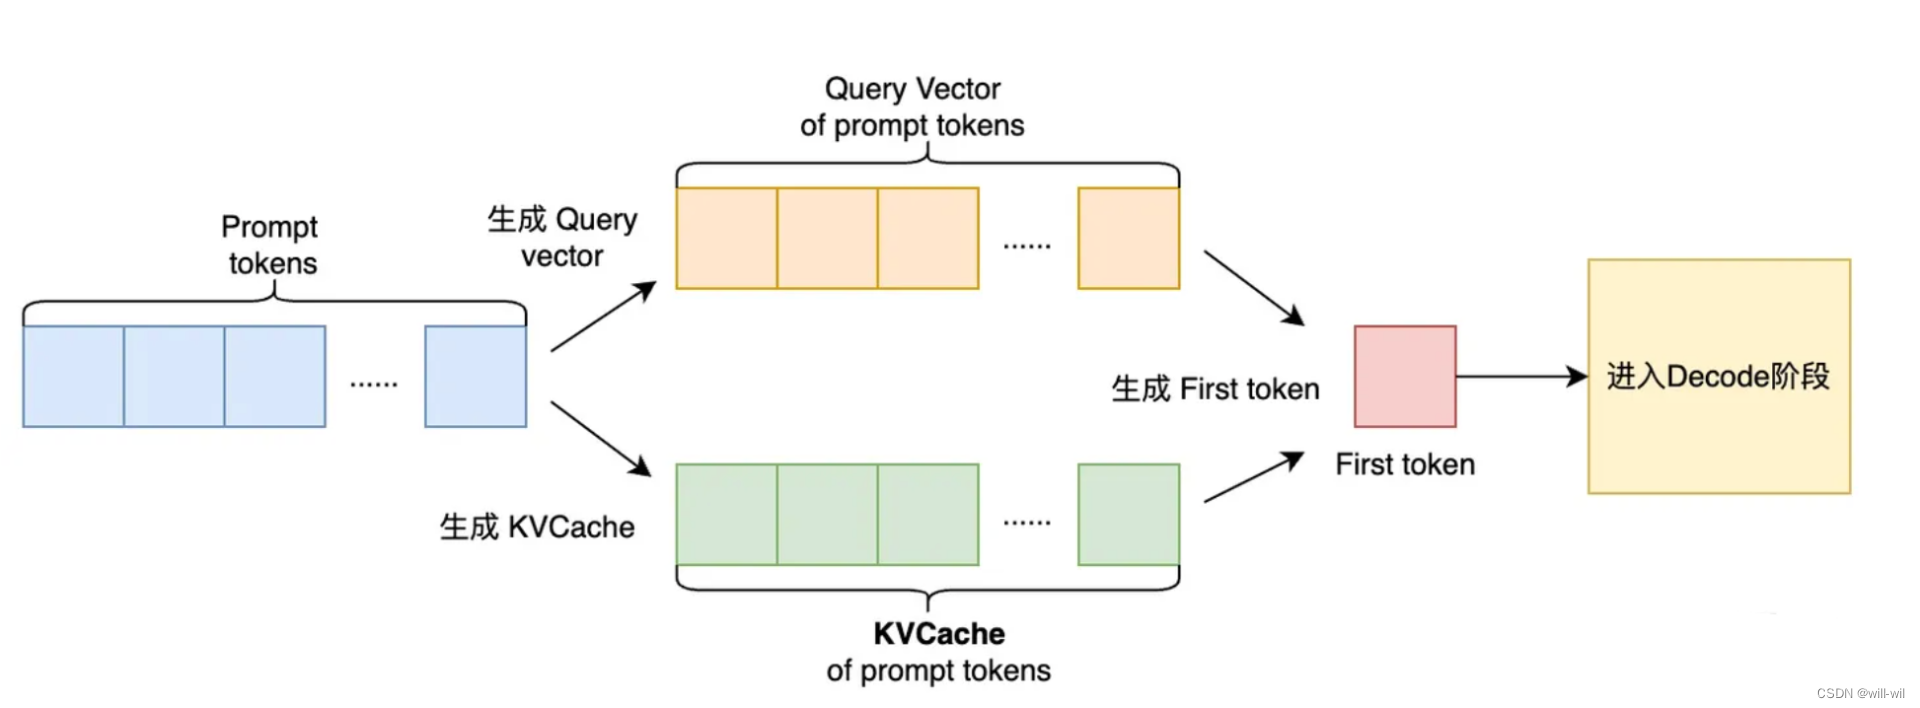
vLLM: Easy, Fast, and Memory-Efficient LLM Serving with PagedAttention ...
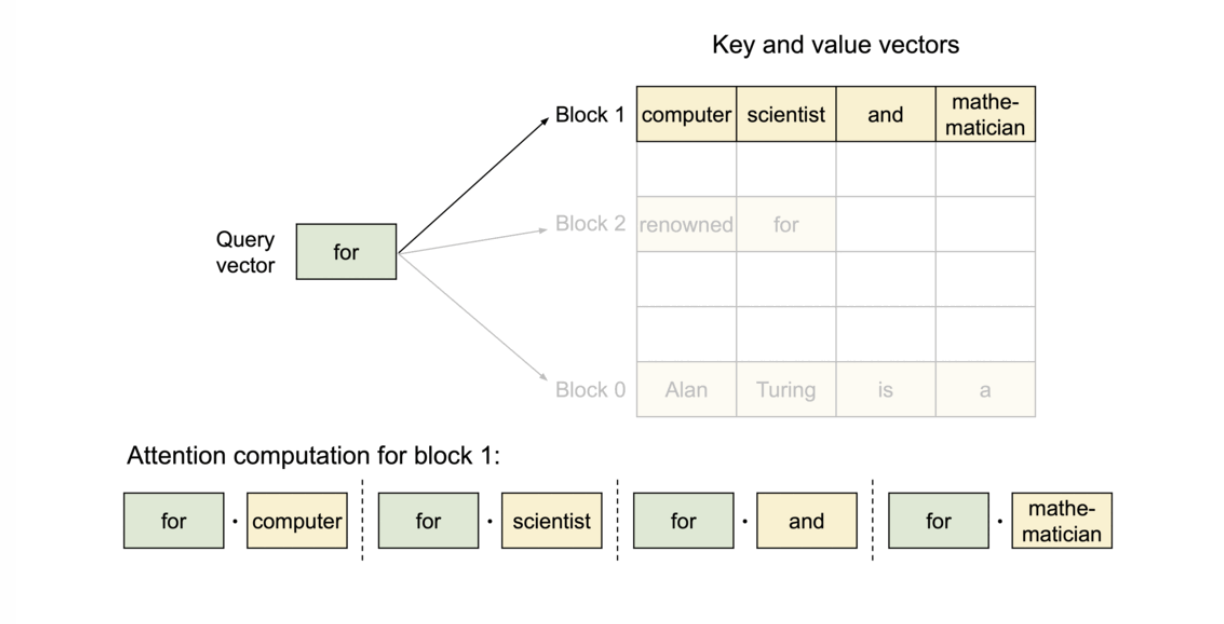
vLLM: Easy, Fast, and Cheap LLM Serving with PagedAttention | Unknown ...
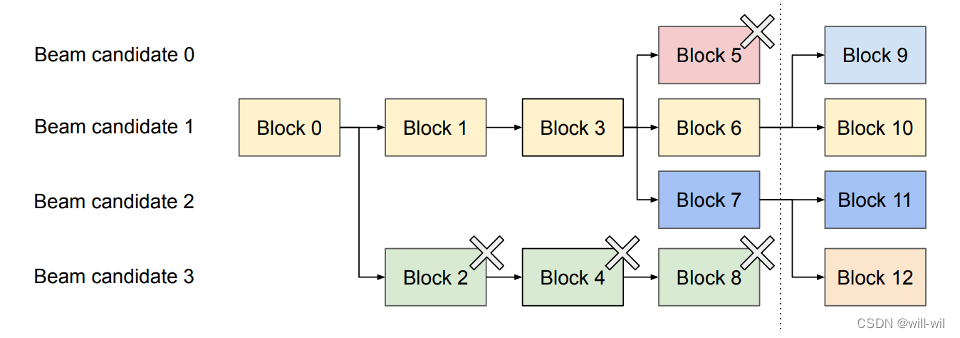
vLLM: Easy, Fast, and Memory-Efficient LLM Serving with PagedAttention ...
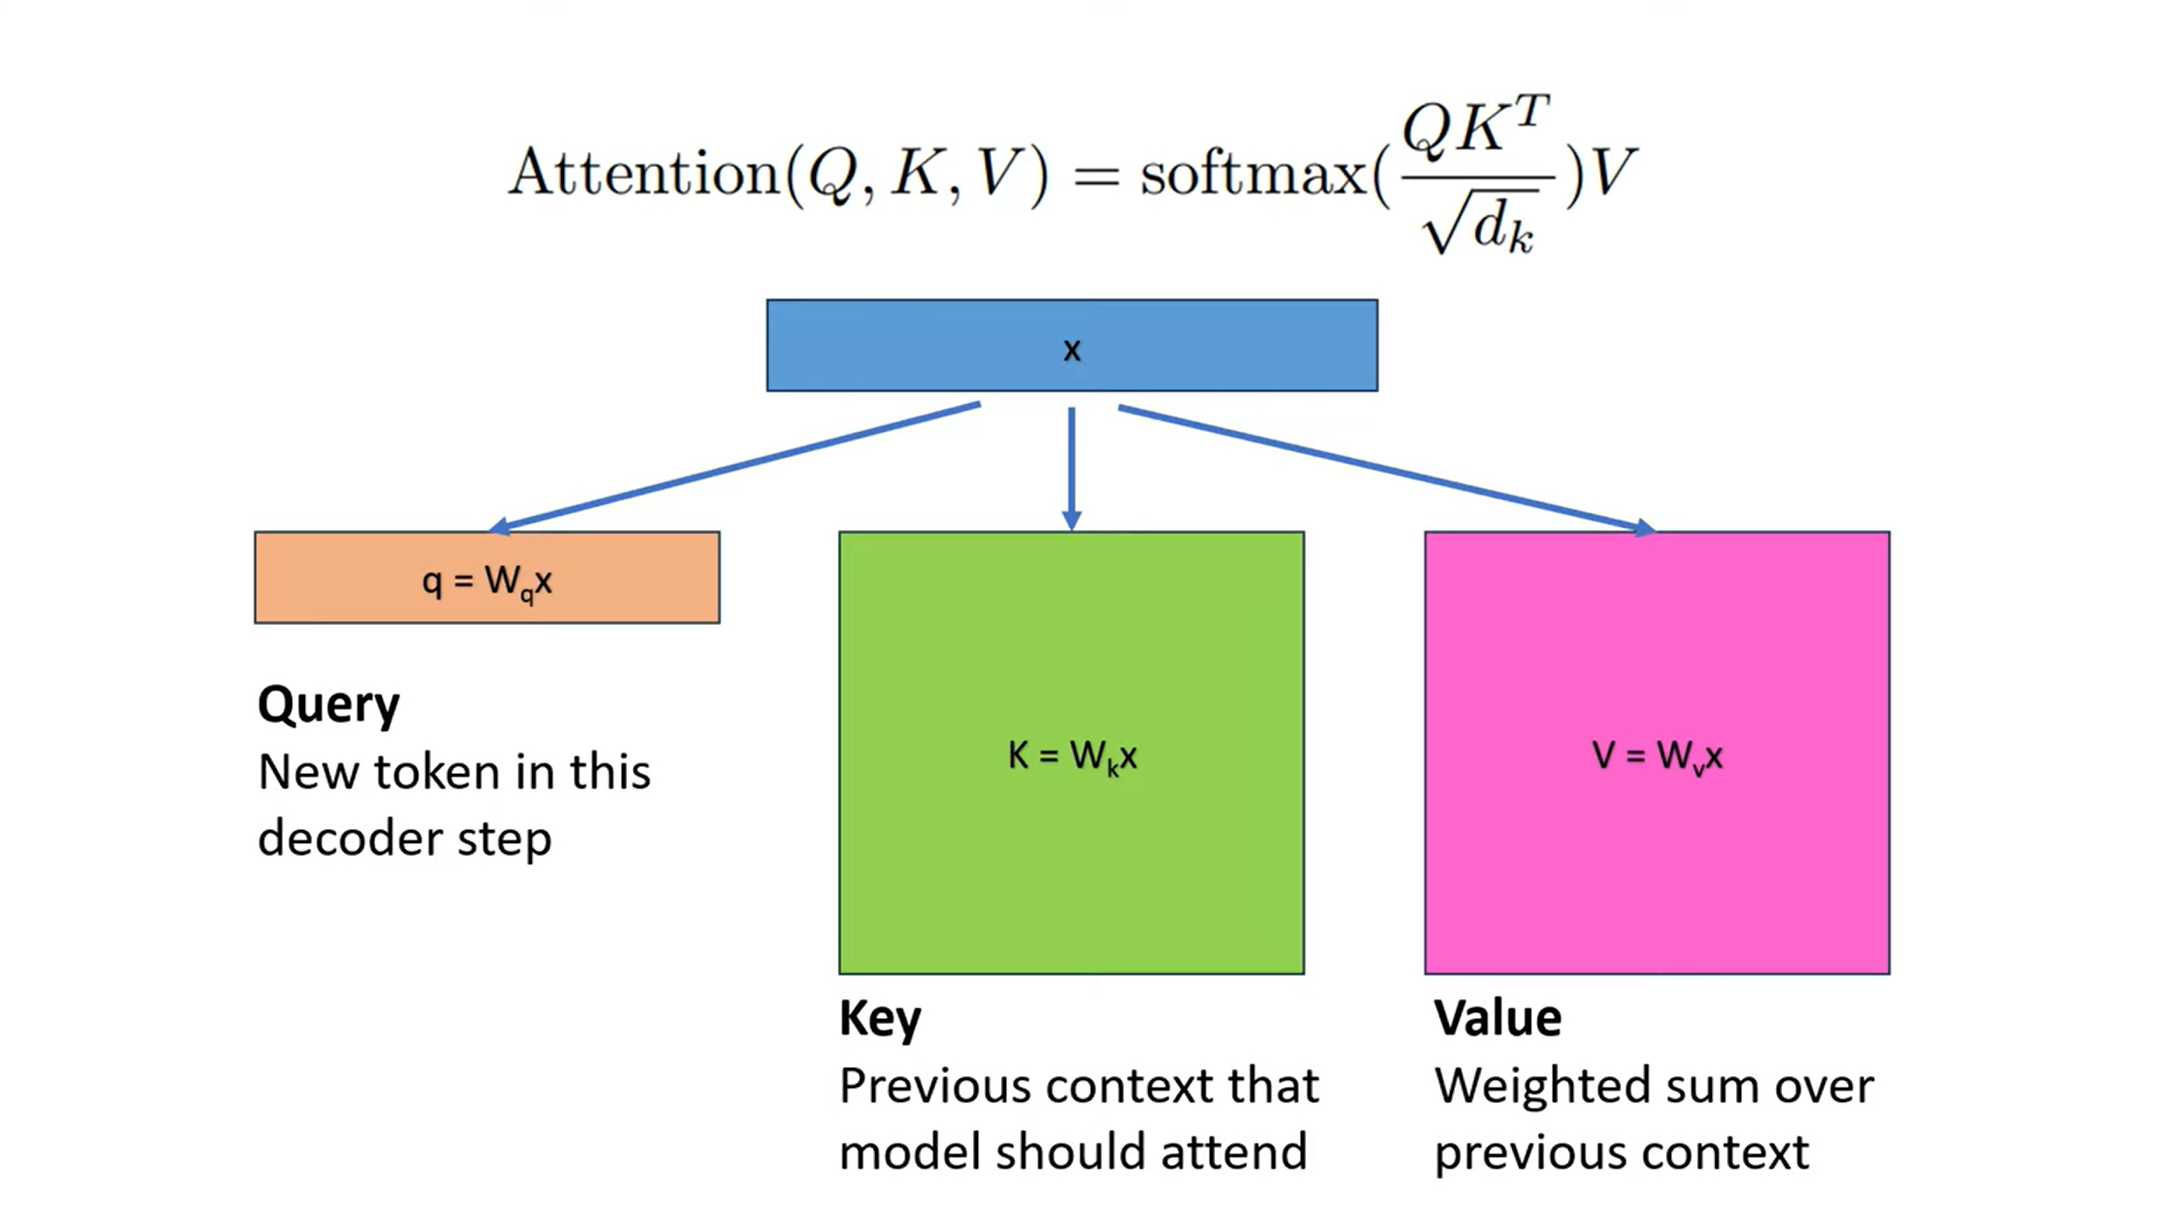
vLLM 核心技术 PagedAttention 原理详解-CSDN博客
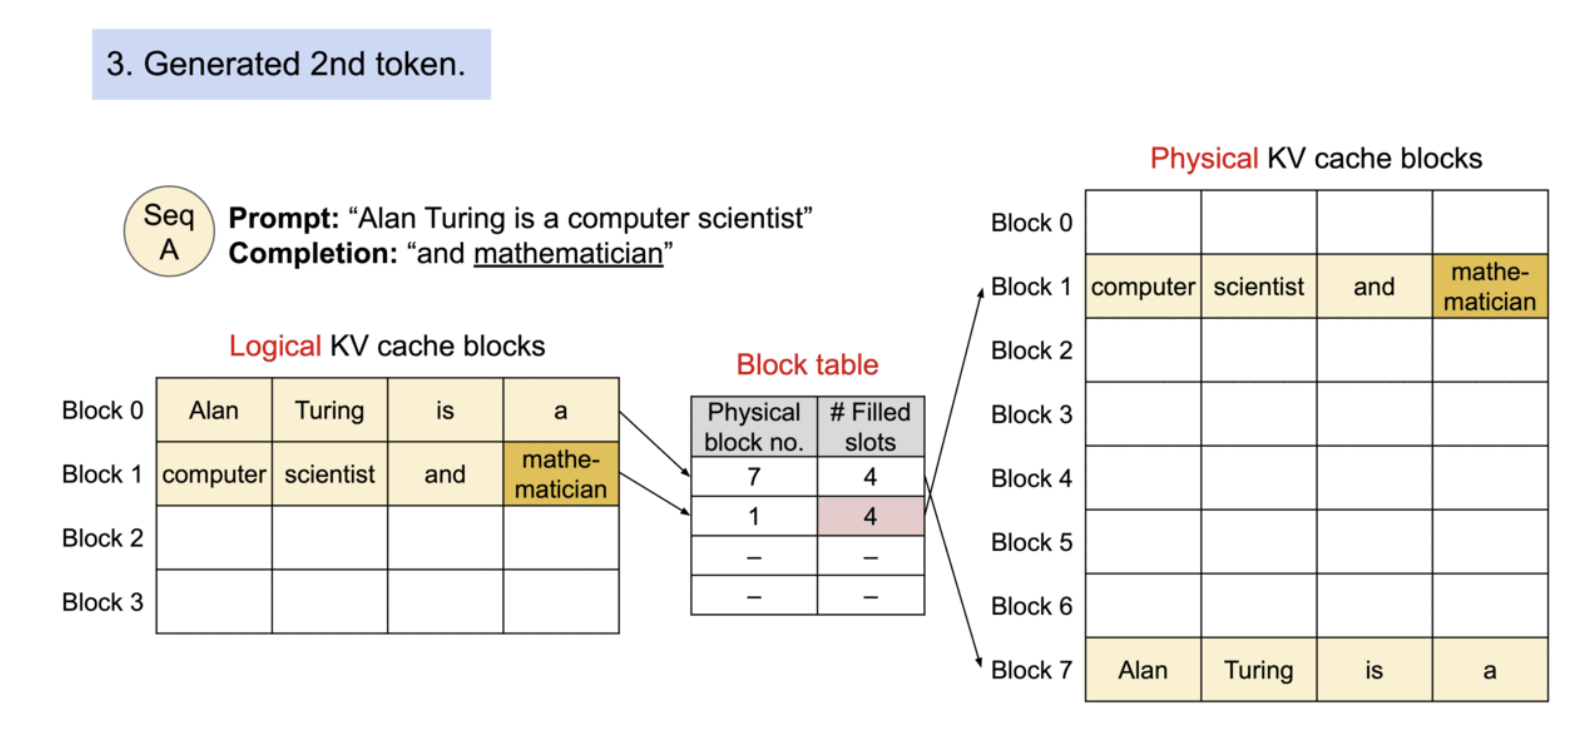
vLLM: Easy, Fast, and Cheap LLM Serving with PagedAttention | Unknown ...
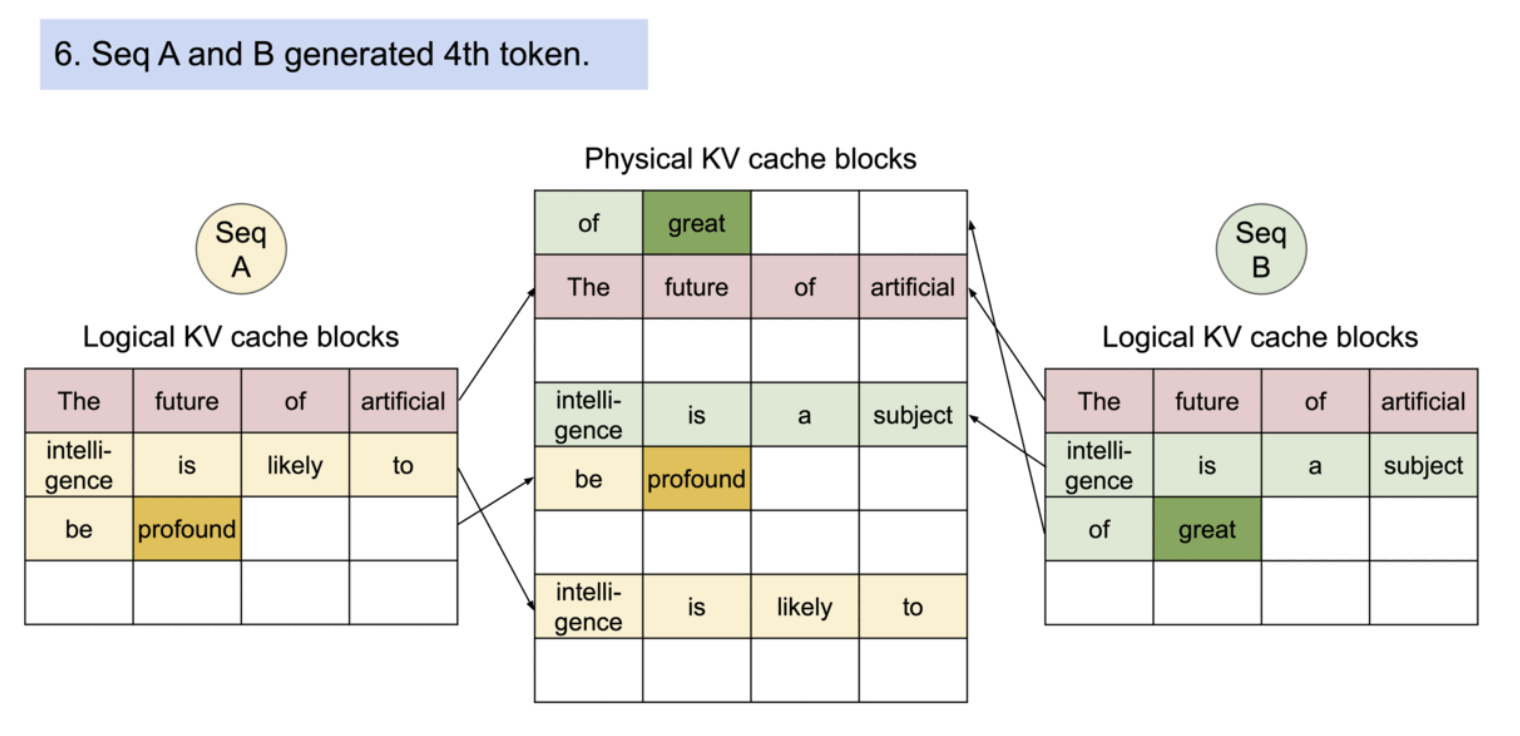
vLLM: Easy, Fast, and Cheap LLM Serving with PagedAttention | Unknown ...
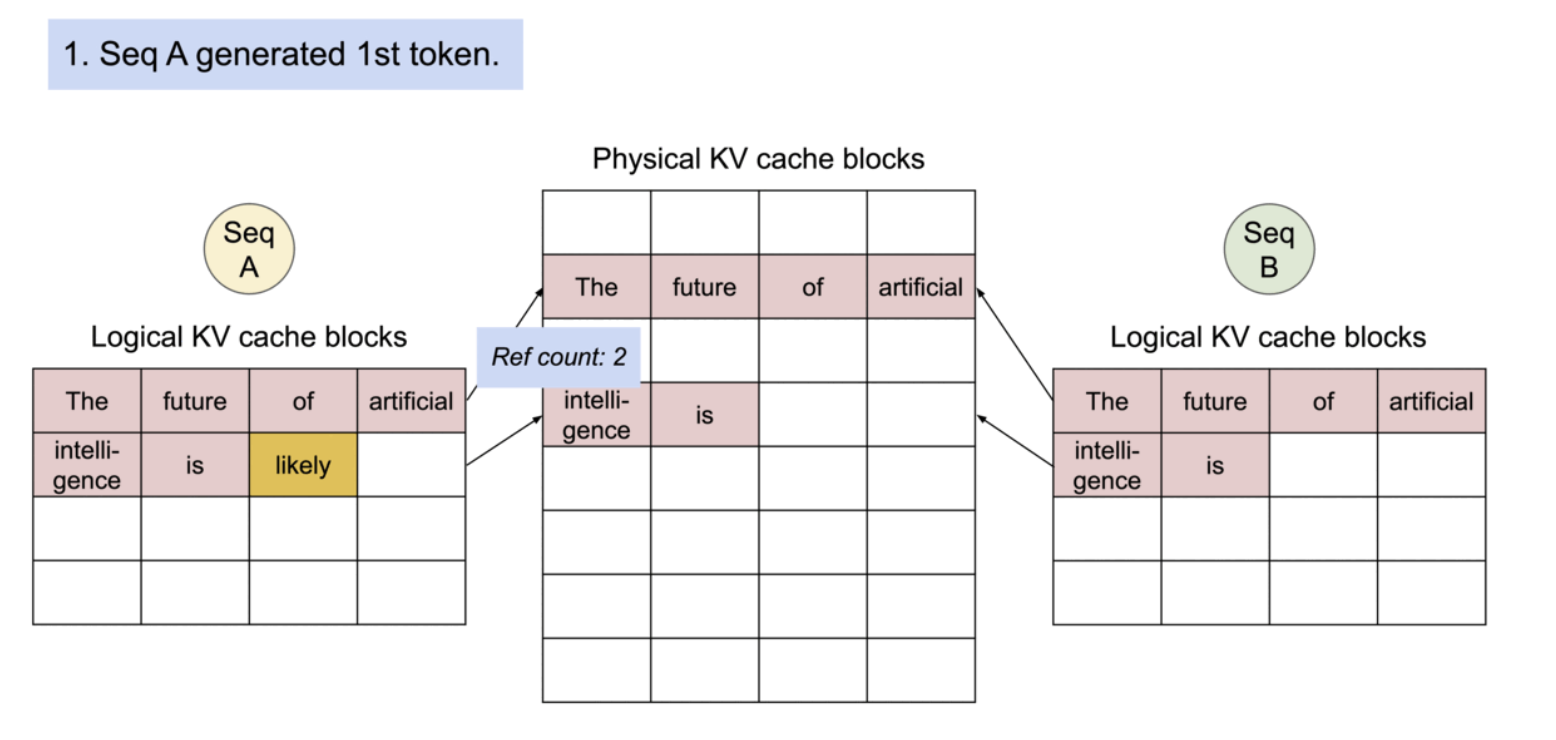
vLLM: Easy, Fast, and Cheap LLM Serving with PagedAttention | Unknown ...
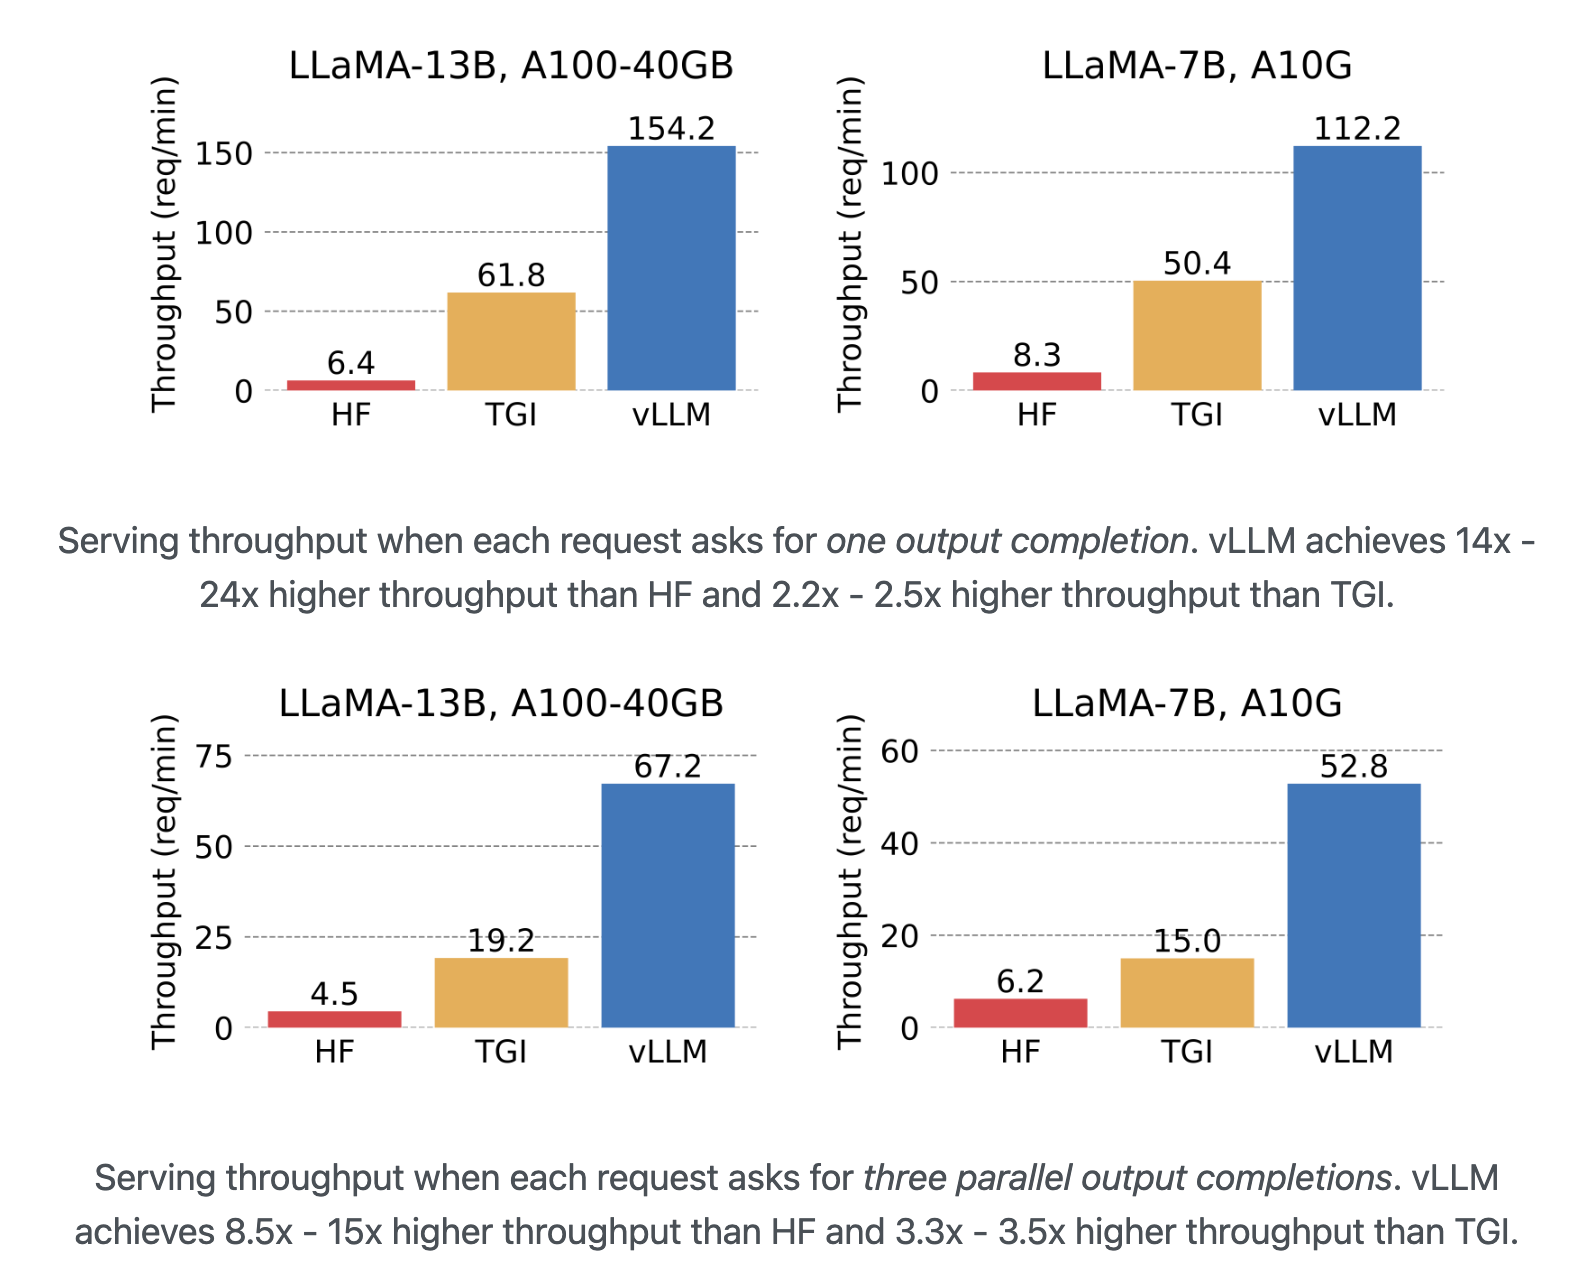
vLLM: Easy, Fast, and Cheap LLM Serving with PagedAttention | Unknown ...

vLLM 核心技术 PagedAttention 原理详解 - 知乎
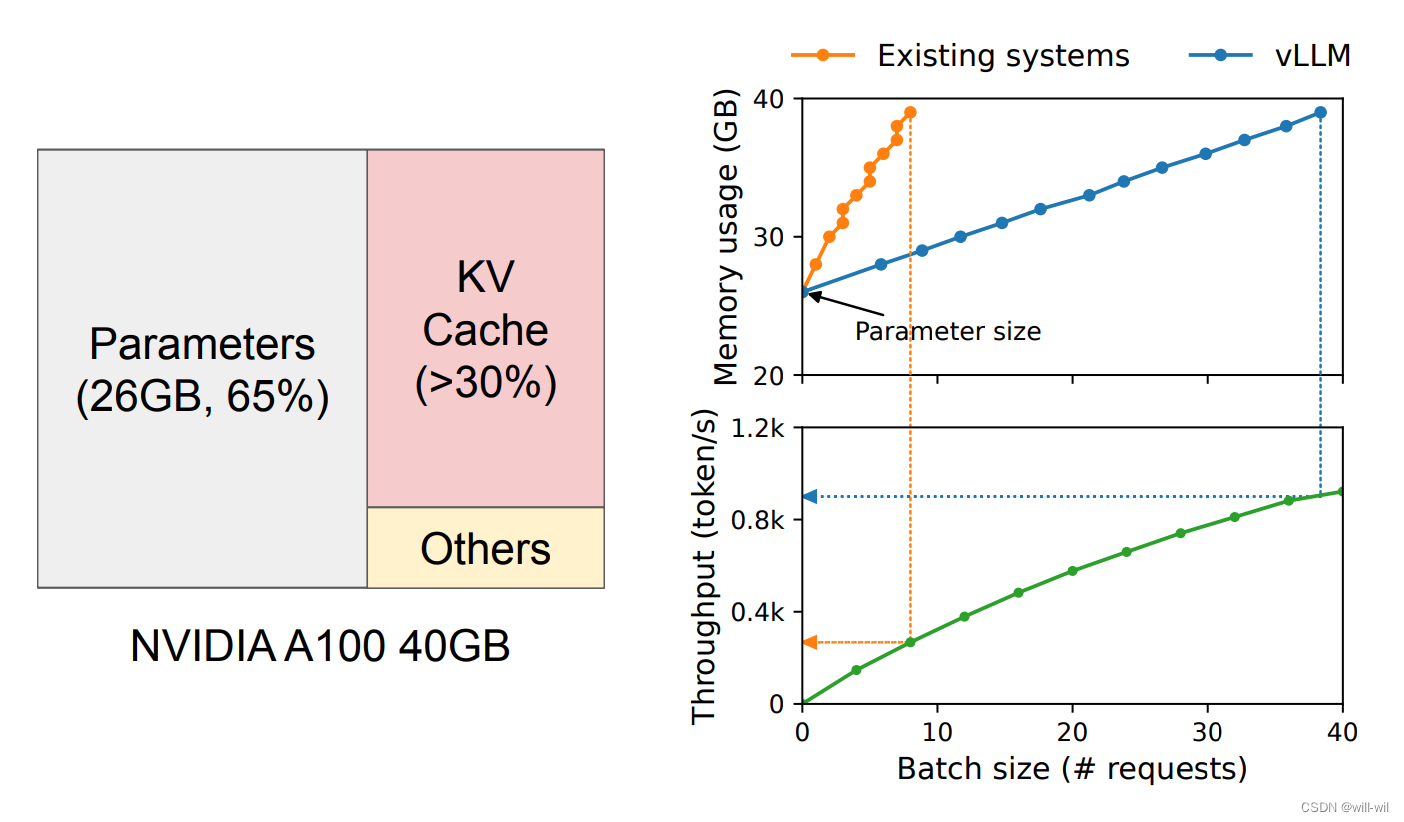
vLLM: Easy, Fast, and Memory-Efficient LLM Serving with PagedAttention ...
Advertisement Space (336x280)
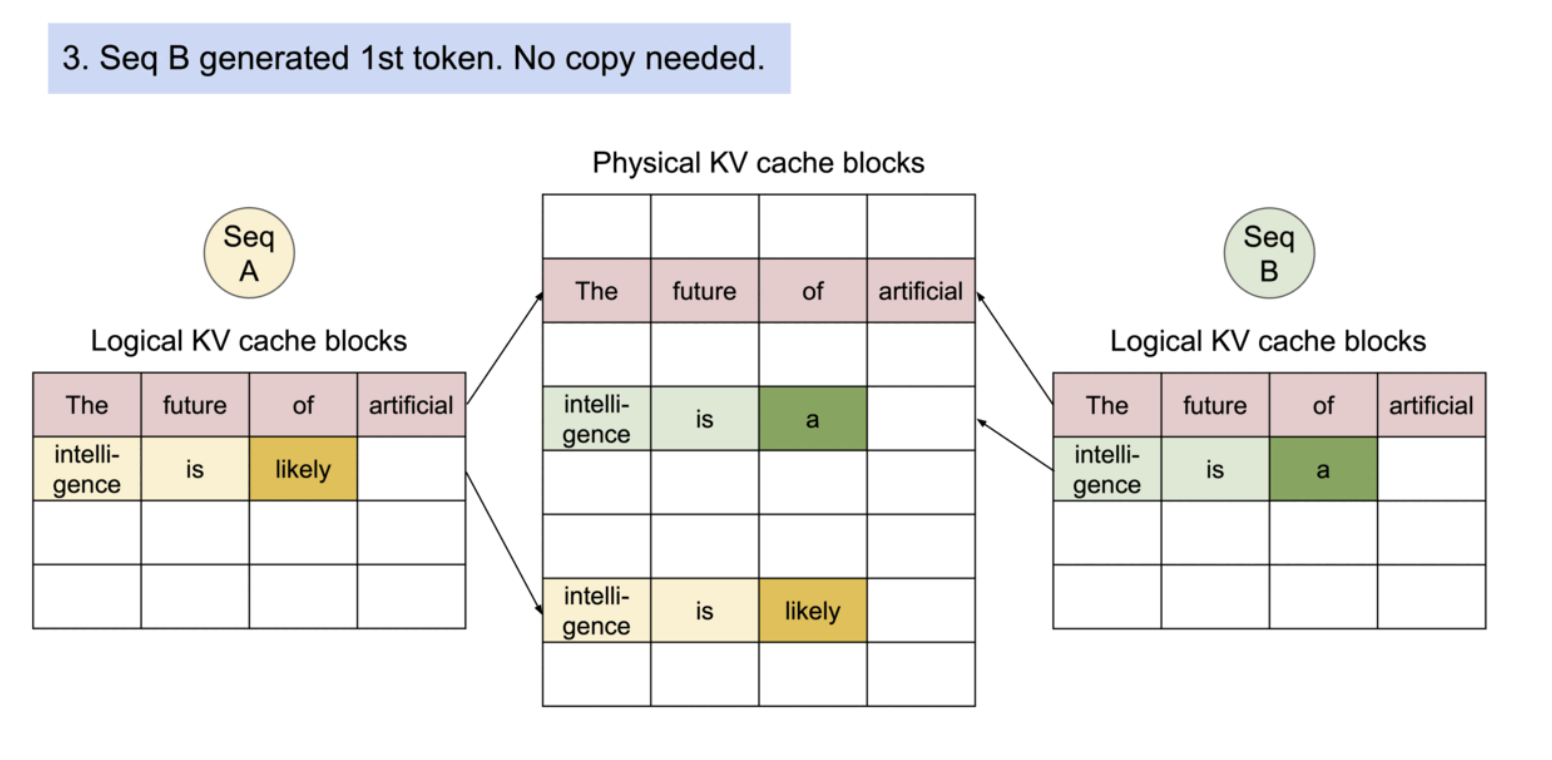
vLLM: Easy, Fast, and Cheap LLM Serving with PagedAttention | Unknown ...

PagedAttention | PagedAttention Architecture Explained | LLM ...

vLLM: Easy, Fast, and Memory-Efficient LLM Serving with PagedAttention ...
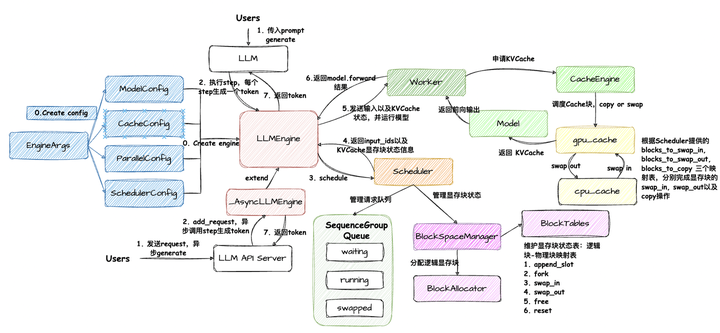
vLLM & PagedAttention 论文深度解读(二)—— vLLM 服务架构及源码实现 - 知乎
vLLM - High-throughput LLM inference engine with PagedAttention ... at ...
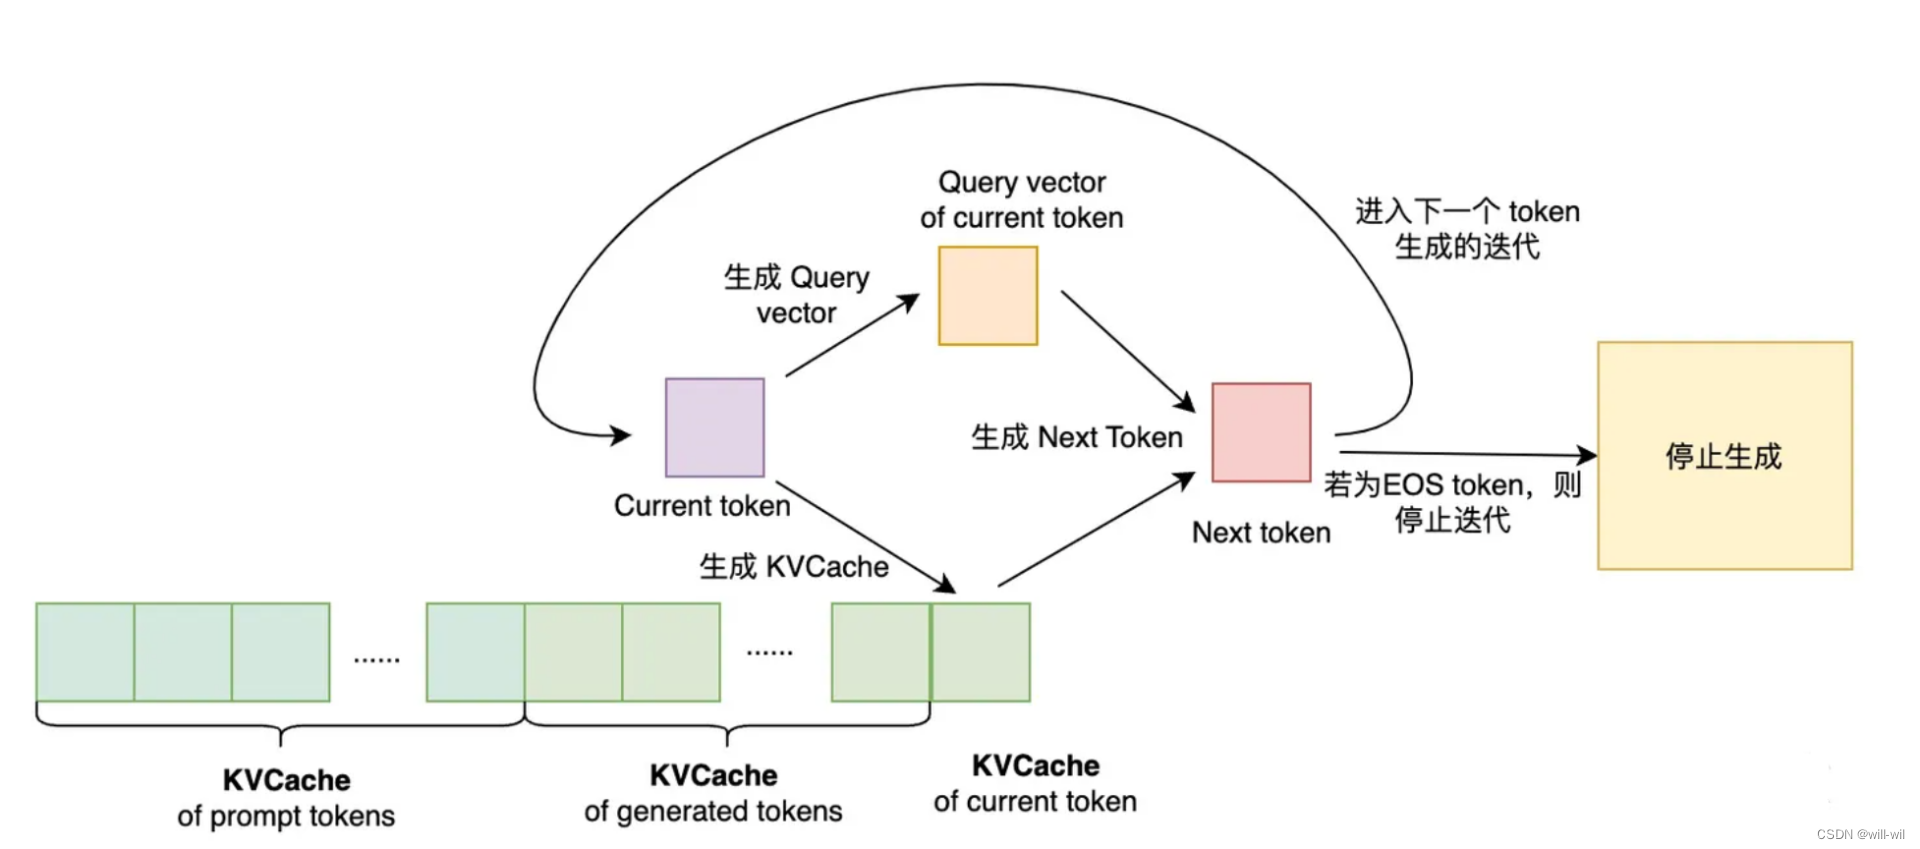
vLLM: Easy, Fast, and Memory-Efficient LLM Serving with PagedAttention ...