
Vllm Throughput Guide Pagedattention And Batching Tips 2026

vLLM Throughput Guide - PagedAttention and Batching Tips (2026)
vLLM Throughput Guide - PagedAttention and Batching Tips (2026)

vLLM Throughput Guide - PagedAttention and Batching Tips (2026)

vLLM Interview Questions: 2026 PagedAttention + Production Guide
vLLM Optimization — Batching, Quantization, and Throughput Tuning 2026 ...
vLLM Explained: PagedAttention and Continuous Batching

vLLM Tutorial 2026: PagedAttention LLM Inference Guide - WeavAI Blog
vLLM Guide 2026 | High-Throughput LLM Serving
vLLM Python 2026 : servir des LLMs en production — PagedAttention ...

vLLM Deep Dive: PagedAttention, Continuous Batching & 24x Throughput ...
Advertisement Space (300x250)

vLLM Tutorial 2026: PagedAttention LLM Inference Guide - WeavAI Blog
vLLM Continuous Batching & PagedAttention: Maximizing Throughput — AI ...
vLLM PagedAttention Production Serving Optimization and Inference ...
Ray Summit 2023 - Fast LLM Serving with vLLM and PagedAttention
vLLM en production : le guide du développeur 2026

vLLM Explained: How PagedAttention Makes LLMs Faster and Cheaper - DEV ...
PagedAttention and vLLM serve Large Language Models faster and cheaper ...

Optimizing LLM Deployment: vLLM PagedAttention and the Future of ...

vLLM Explained: How PagedAttention Makes LLMs Faster and Cheaper - DEV ...

Fast LLM Serving with vLLM and PagedAttention - YouTube
Advertisement Space (336x280)

vLLM Installation Guide for Proxmox Server Solutions LXC with GPU ...

How continuous batching enables 23x throughput in LLM inference ...
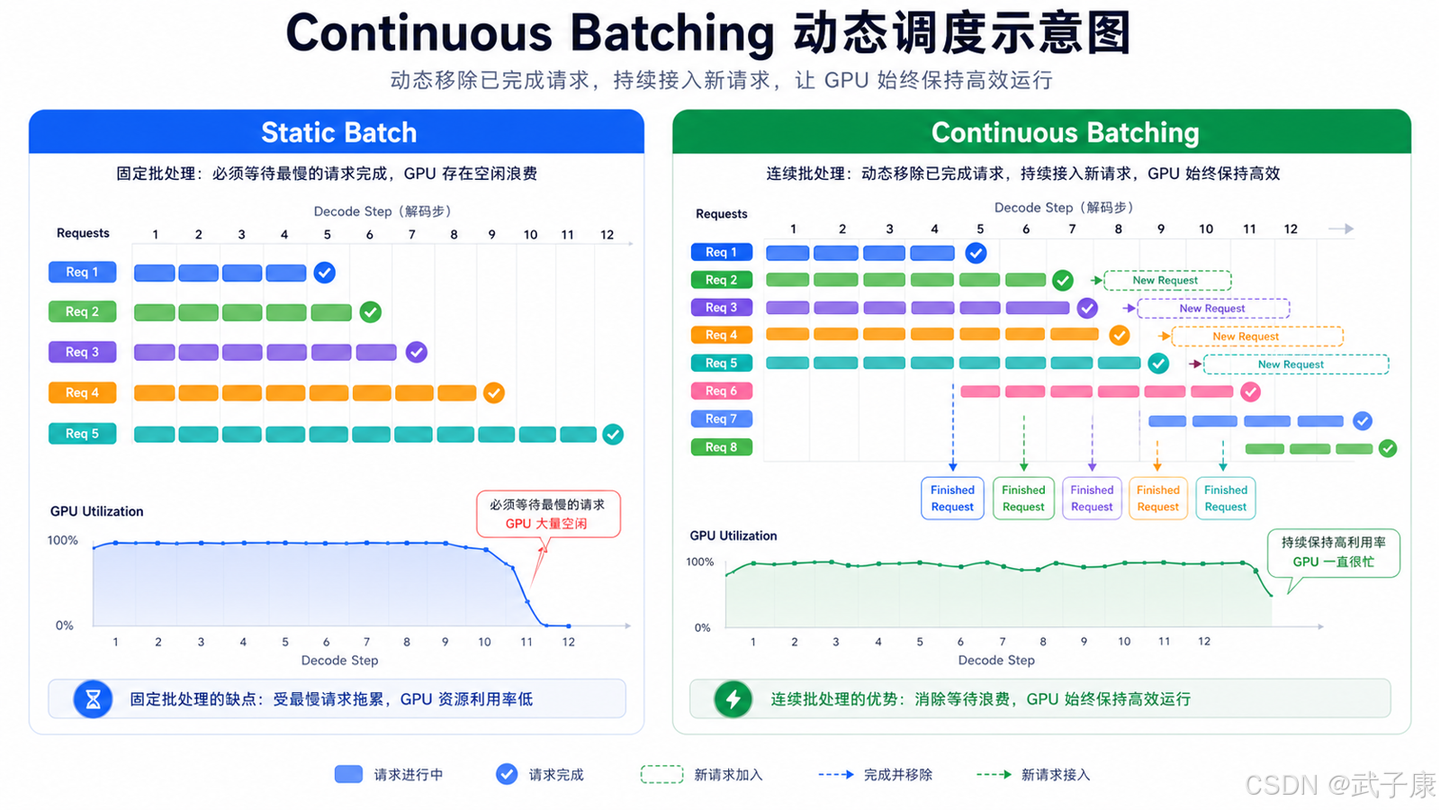
vLLM 深入浅出:从 PagedAttention 到生产级大模型推理服务 - 知乎

vLLM Efficiency Boosts Throughput with Paged Attention | Ayesha Javaid ...

How continuous batching enables 23x throughput in LLM inference ...

LLM Batch Inference Cut Costs 50% Production Guide 2026 | Iterathon
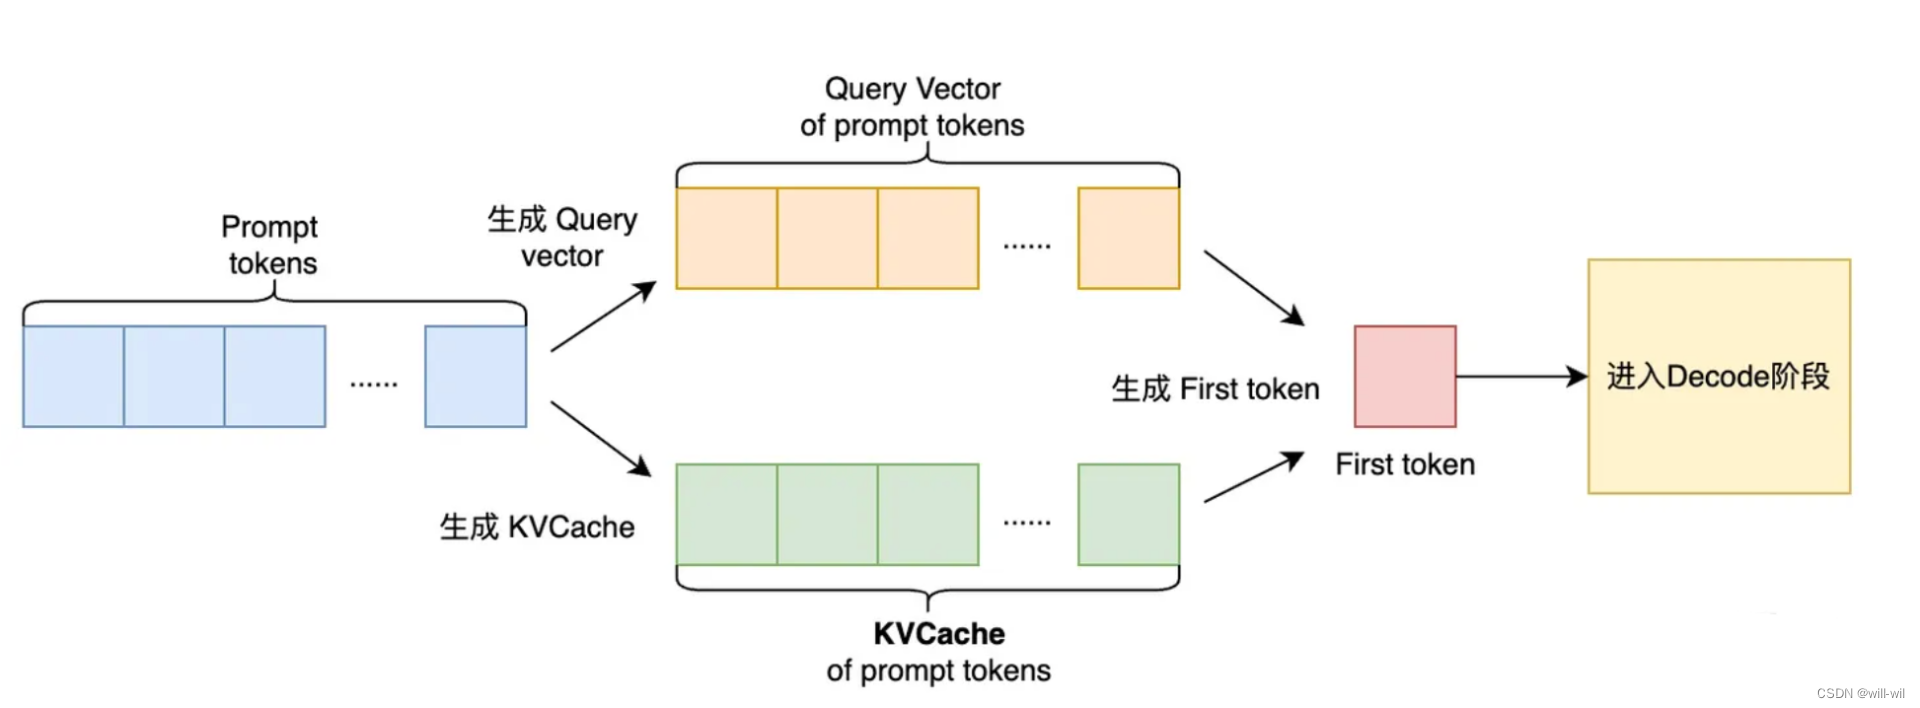
vLLM: Easy, Fast, and Memory-Efficient LLM Serving with PagedAttention ...

vLLM 核心技术 PagedAttention 原理详解 - 知乎

vLLM Fully explained page attention & continuous batching in simple way ...

vLLM: Using PagedAttention to Optimize LLM Inference and Serving
Advertisement Space (336x280)
vLLM - High-throughput LLM inference engine with PagedAttention ... at ...

VLLM: Using PagedAttention To Optimize LLM Inference and Serving ...

How vLLM Achieves 2-4× Better Throughput: The PagedAttention Breakthrough
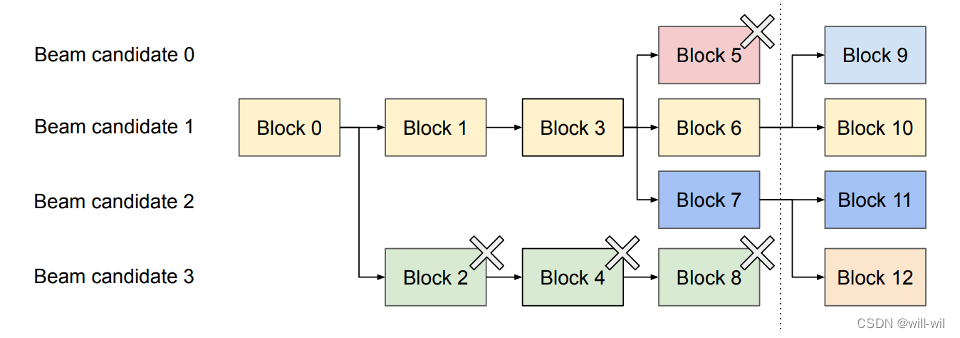
vLLM: Easy, Fast, and Memory-Efficient LLM Serving with PagedAttention ...
Optimizing Large Language Models with vLLM and Related Tools.pdf

How to Speed up AI Inference with vLLM Continuous Batching - Voice.ai