
Vllm In Production Running Llms At Scale With Gpus High Performance

vLLM in Production: Running LLMs at Scale with GPUs, High-Performance ...

Scale Open LLMs with vLLM Production Stack | by Shahrukh khan | Medium

Scale Open LLMs with vLLM Production Stack | by Shahrukh khan | Medium
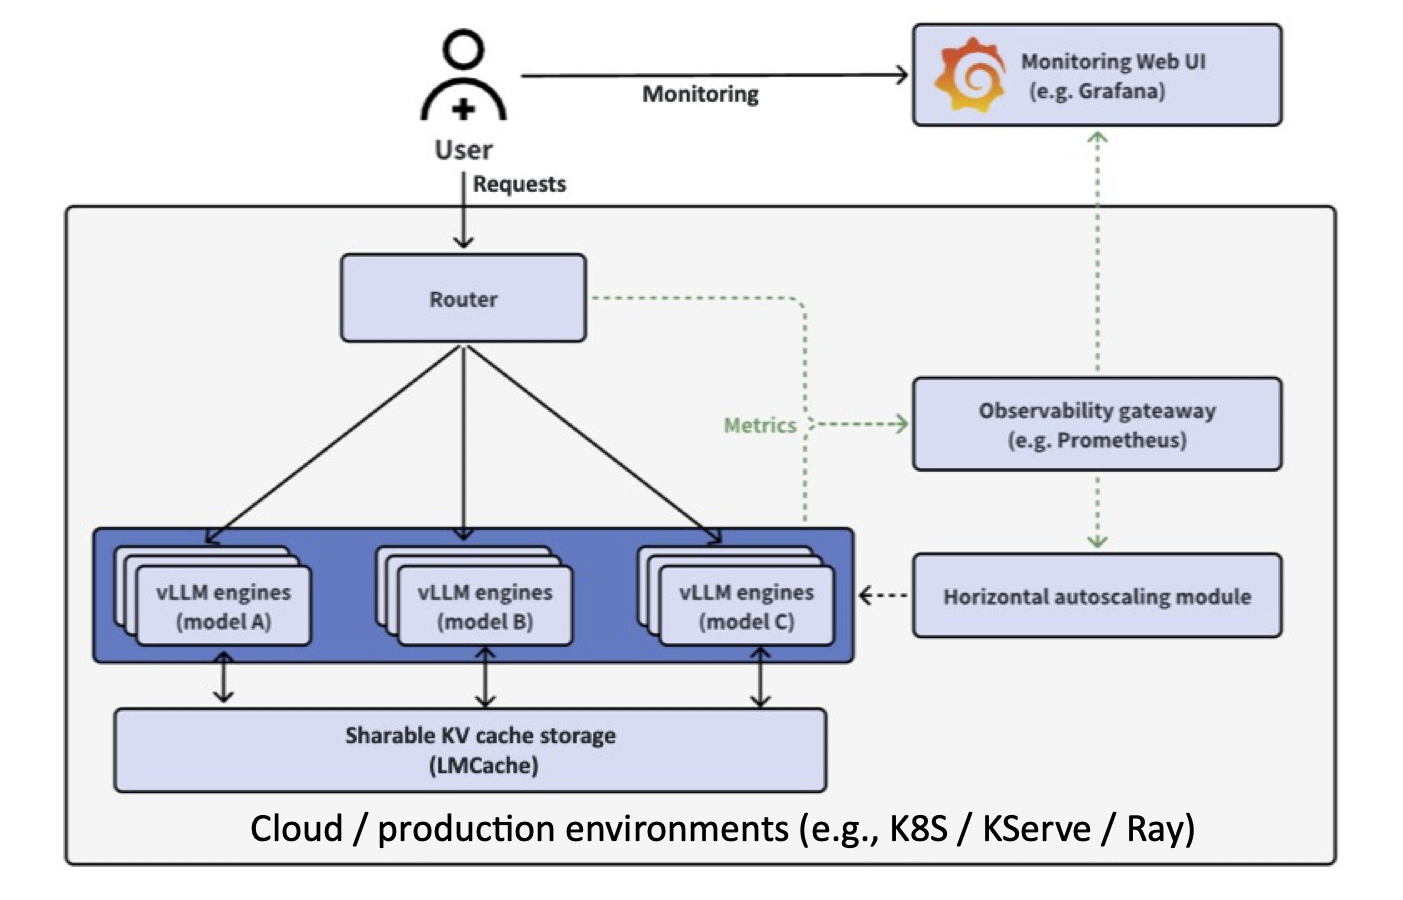
High Performance and Easy Deployment of vLLM in K8S with “vLLM ...
High Performance and Easy Deployment of vLLM in K8S with vLLM ...
Scale Open LLMs with vLLM Production Stack | by Shahrukh khan | Medium
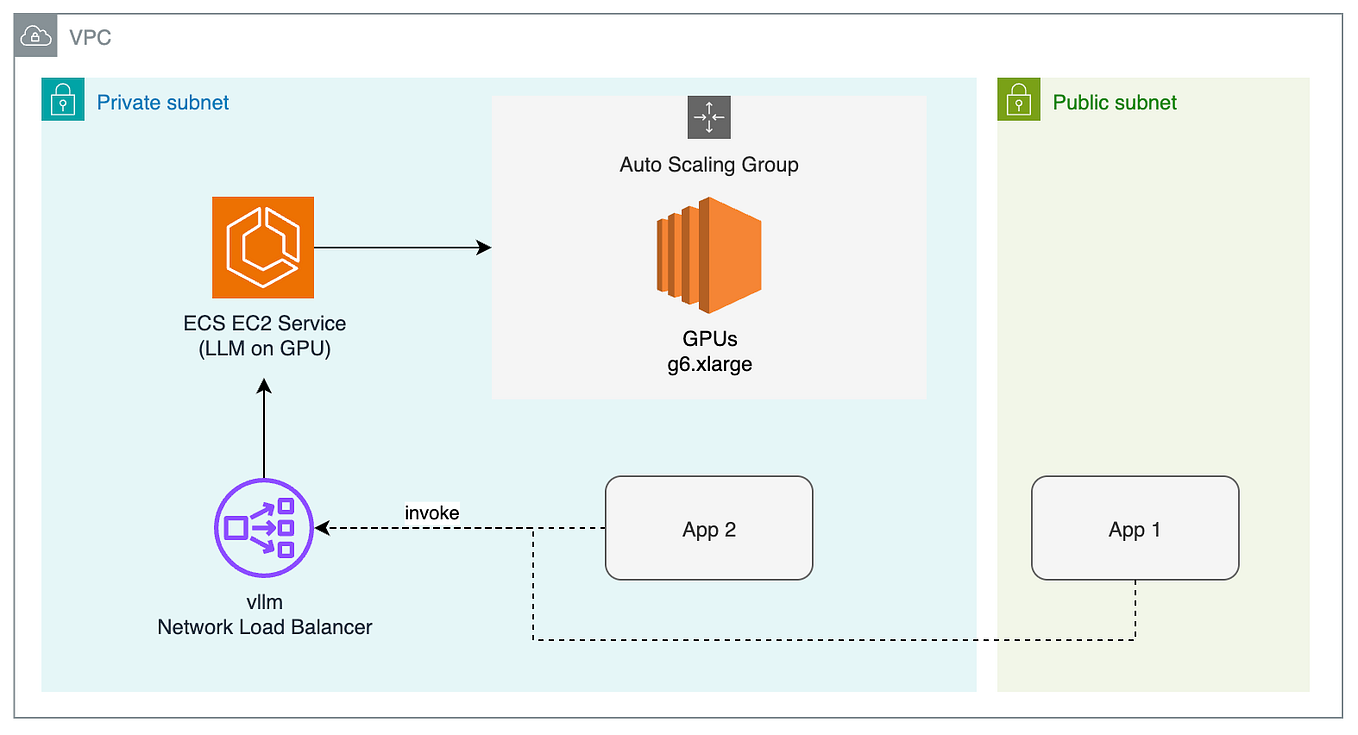
Scale Open LLMs with vLLM Production Stack | by Shahrukh khan | Medium

Inferencing LLMs at Scale with Kubernetes and vLLM | by Welzin ...

Serving LLMs with vLLM + FastAPI at Scale · Technical news about AI ...
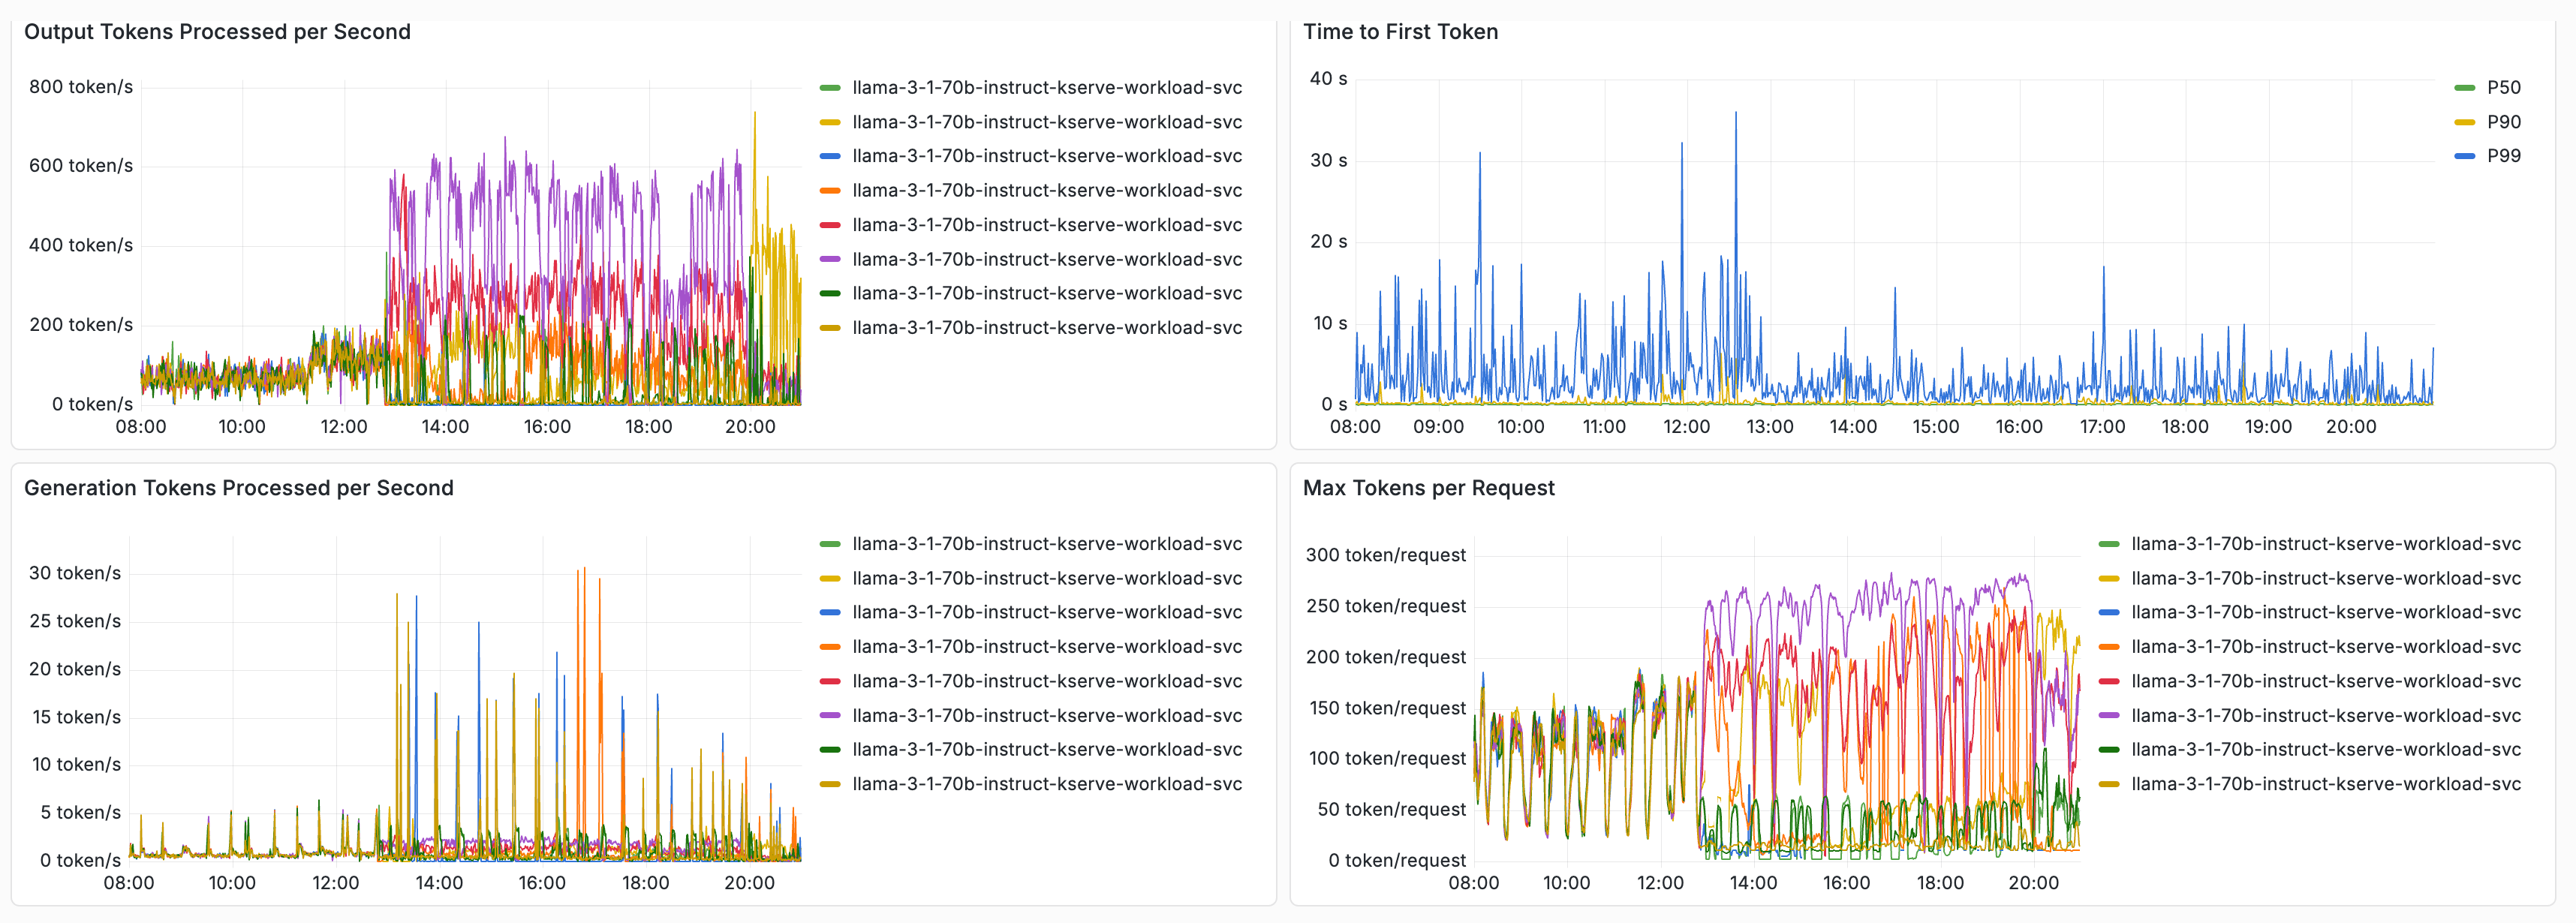
Production-Grade LLM Inference at Scale with KServe, llm-d, and vLLM ...
Advertisement Space (300x250)
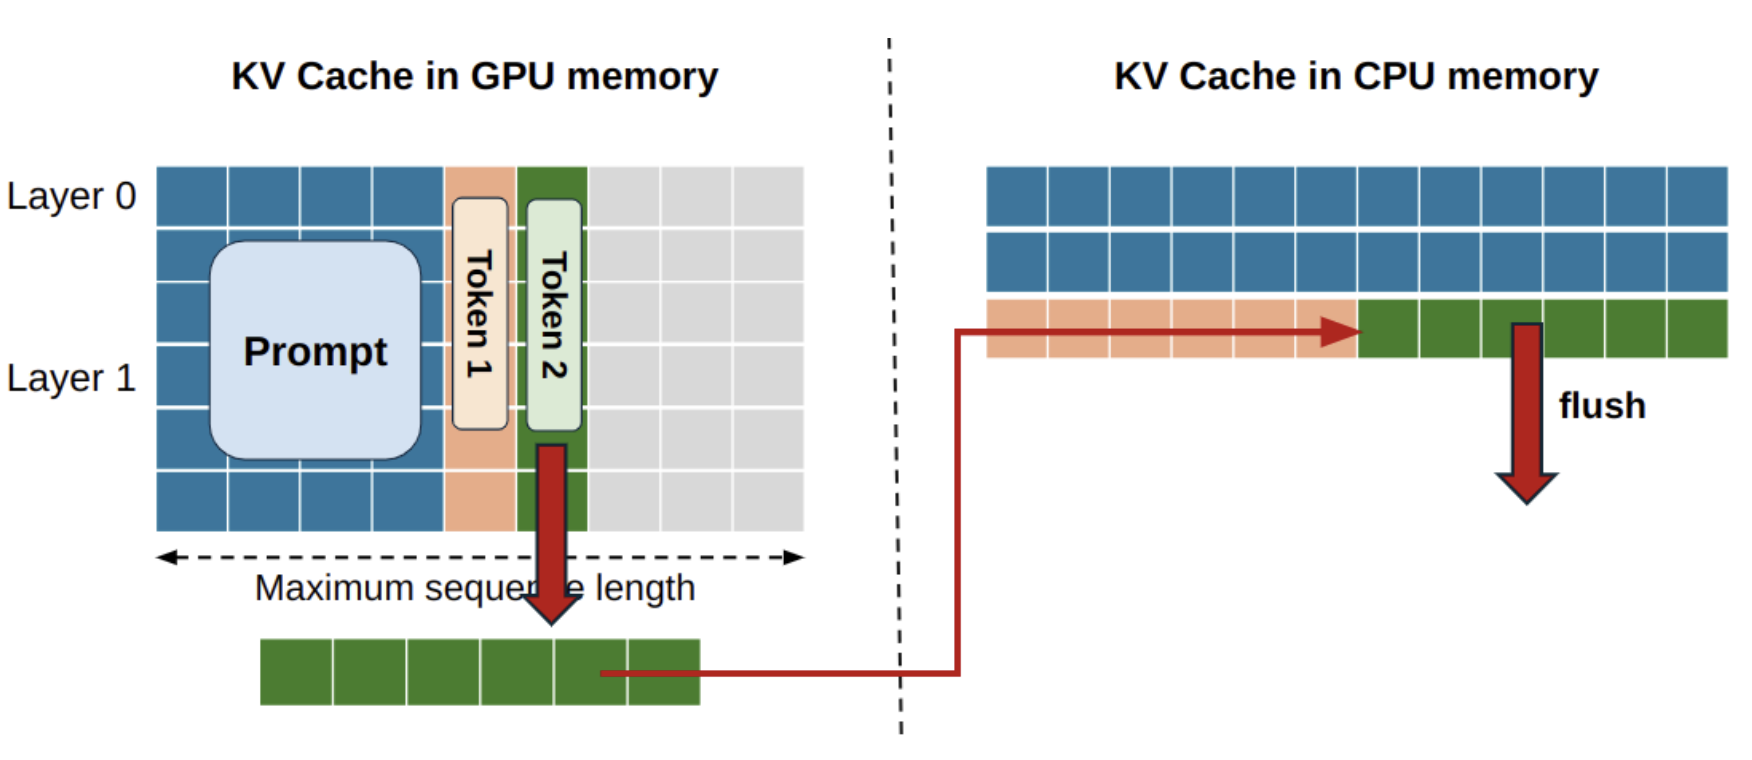
5 Lessons from Deploying LLMs in Production using vLLM - Floating Bytes
Running vLLM with Qwen3.5-35B GPTQ on 4× Nvidia T4 GPUs | 67 AI Lab

Boosting LLMs performance in production

Enterprise-Ready LLM Inferencing with the vLLM Production Stack on Dell ...

Core Components | Open‑Source LLM Inferencing at Scale: vLLM Production ...

Run LLMs Locally on Your GPU with vLLM (No APIs) | Top Python Libraries
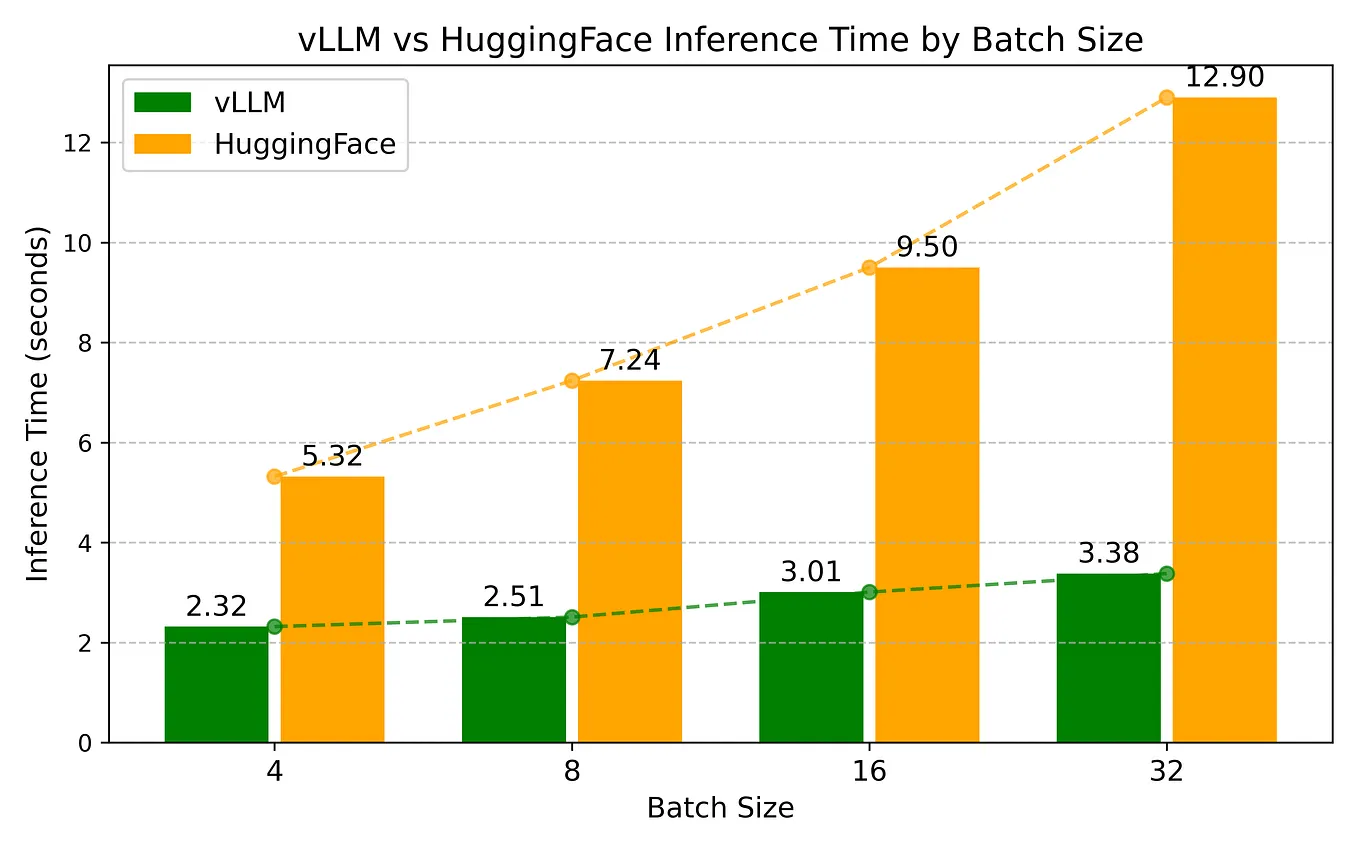
Serving Large Language Models with vLLM on AMD ROCm GPUs | by Trade ...

vLLM: Deploying LLMs at Scale - Fractal Analytics

Serving Large Language Models with vLLM on AMD ROCm GPUs | by Trade ...

vLLM: Deploying LLMs at Scale Like OpenAI
Advertisement Space (336x280)
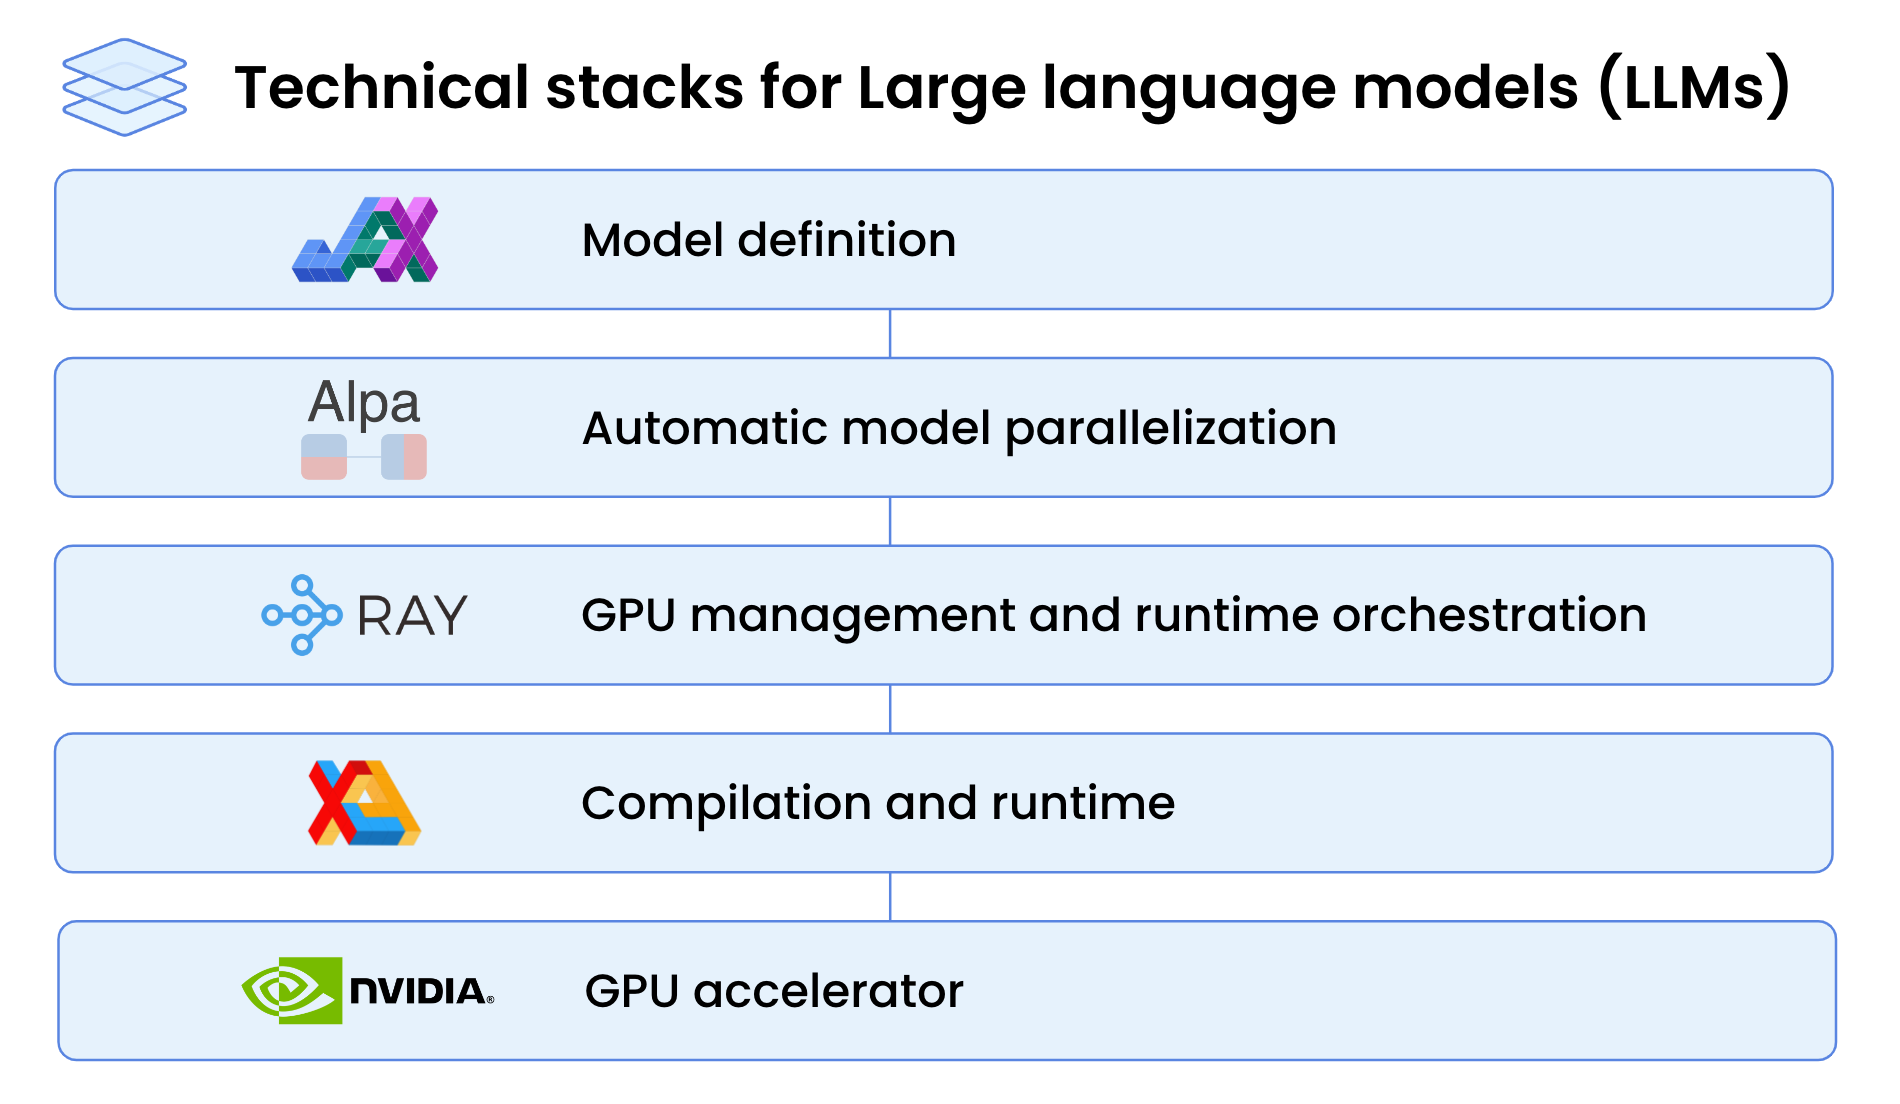
High-Performance LLM Training at 1000 GPU Scale With Alpa & Ray

Serving LLMs in Production: Performance, Cost & Scale - Event | MLOps ...

Optimize LLM serving with vLLM on Intel® GPUs - Intel Community

Optimizing NVIDIA GPUs for Production vLLM Deployments: A tool created ...
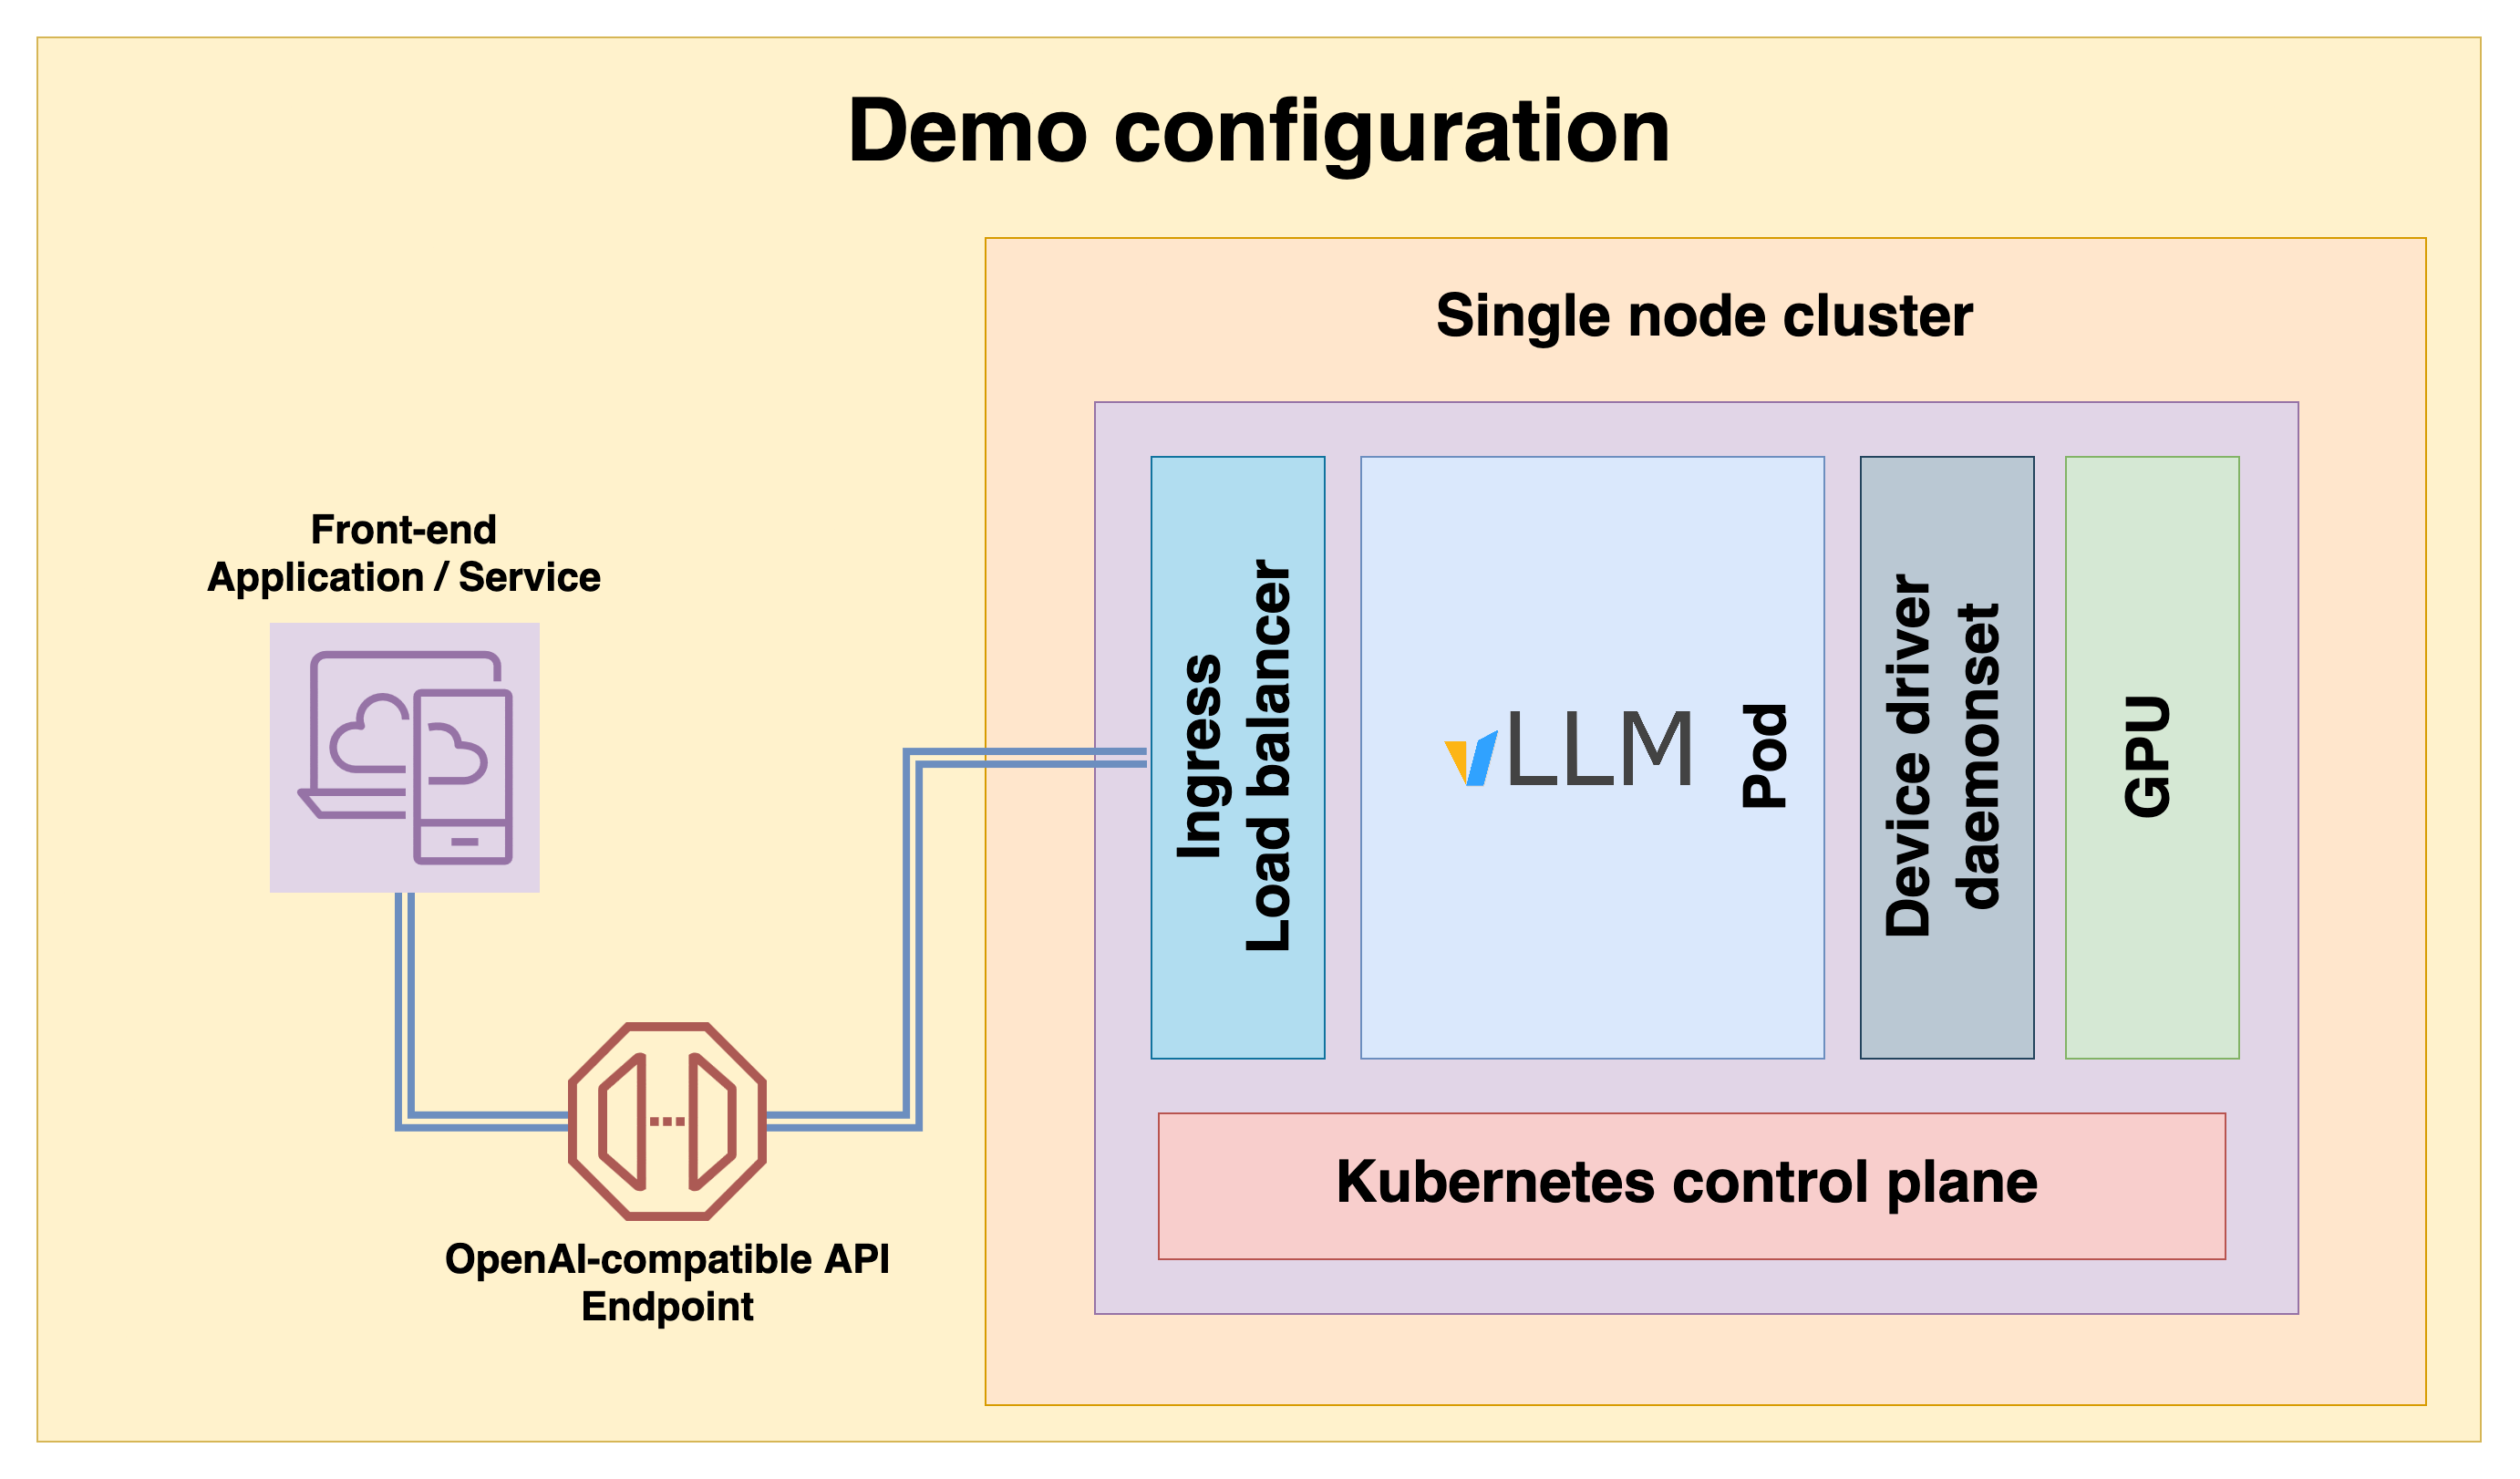
How to deploy LLMs in production • The Register

Run LLMs at Scale - Self-Hosted AI Infrastructure - Cast AI
Pliops Announces Collaboration with vLLM Production Stack to Enhance ...

Open‑Source LLM Inferencing at Scale: vLLM Production Stack on Dell AI ...

Performance Impact | Open‑Source LLM Inferencing at Scale: vLLM ...

Deploying LLMs in Production: From Transformers to vLLM and Ollama | by ...
Advertisement Space (336x280)

Deploying LLMs at Scale | TrueFoundry

Performance Optimization | Open‑Source LLM Inferencing at Scale: vLLM ...

How to Benchmark An LLM with vLLM in 10 Minutes

Run vLLM on Kubernetes with NVIDIA GPUs (EKS Guide)

LLM Semantic Router Production Implementation vLLM SR 2026 | Iterathon
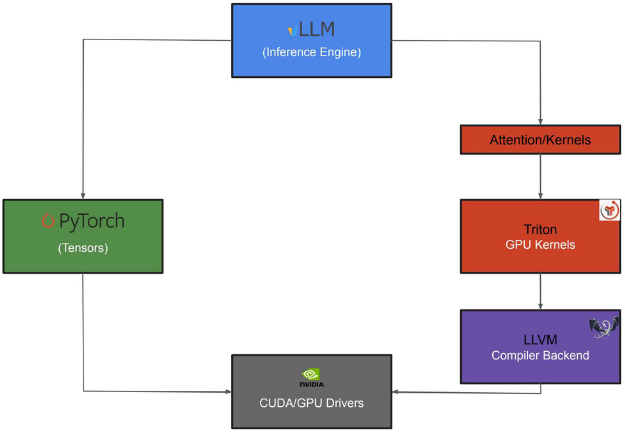
LLM Inference with vLLM Using GPU on Power9