
Vllm Production Ai Inference On Gke With Openwebui Gateway Api And

vLLM: Production AI Inference on GKE with OpenWebUI, Gateway API, and TLS

vLLM: Production AI Inference on GKE with OpenWebUI, Gateway API, and ...

vLLM: Production AI Inference on GKE with OpenWebUI, Gateway API, and ...

vLLM: Production AI Inference on GKE with OpenWebUI, Gateway API, and ...

Experimenting with GPUs: GKE managed DRANET and Inference Gateway AI ...

An End‑to‑End View of AI Inference Stacks with vLLM and Alternatives

Why We Migrated from Ingress to Gateway API on GKE — A Production ...

Guardrails at the gateway: Securing AI inference on GKE with Model ...

Unifying real-time and async inference with GKE Inference Gateway ...

The Future of AI Inference on Kubernetes: Gateway API Inference ...
Advertisement Space (300x250)

Serving Online Inference with vLLM API on Vast.ai - YouTube
Local AI inference with GPT-OSS, vLLM and OpenShift - ConSol Blog

Scaling LLM Inference on GKE: Serving with vLLM or llm-d | by Don ...
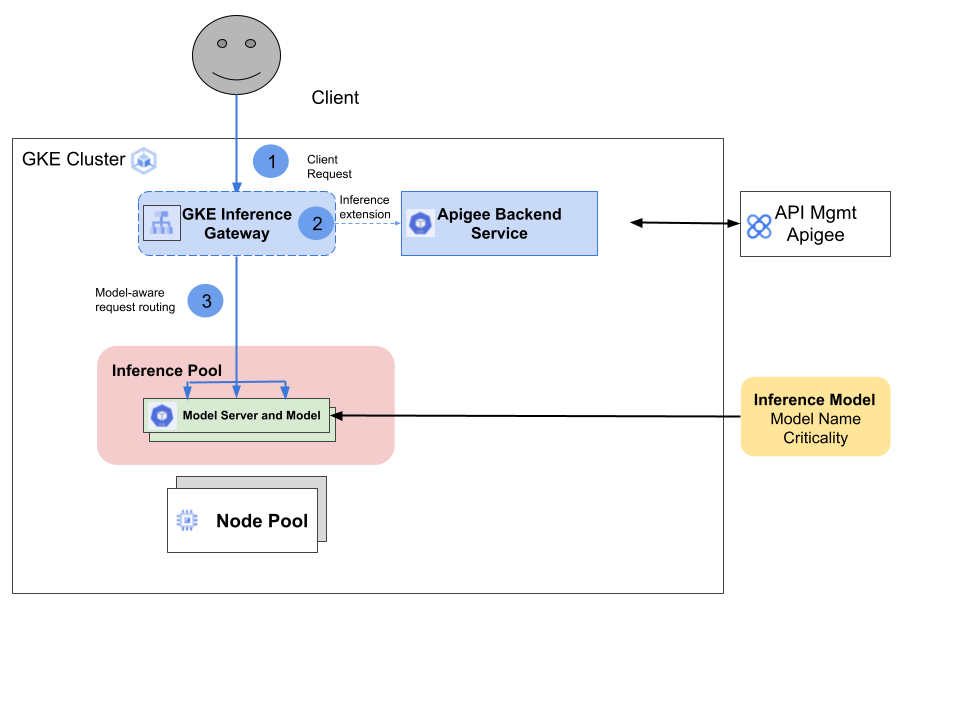
Apigee Operator for Kubernetes and GKE Inference Gateway integration ...
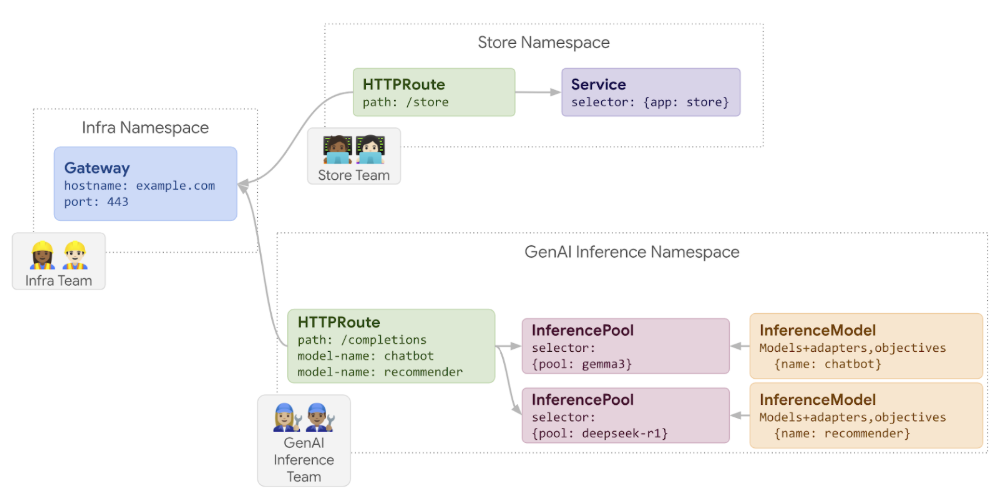
AI / LLM 서비스를 위한 클라우드 인프라 최적화 - GKE Inference Gateway - | Google Cloud 블로그

AI / LLM 서비스를 위한 클라우드 인프라 최적화 - GKE Inference Gateway - | Google Cloud 블로그

GKE Inference Gateway and Quickstart are GA | Google Cloud Blog

AI / LLM 서비스를 위한 클라우드 인프라 최적화 - GKE Inference Gateway - | Google Cloud 블로그

Multi-cluster GKE Inference Gateway helps scale AI workloads | Google ...
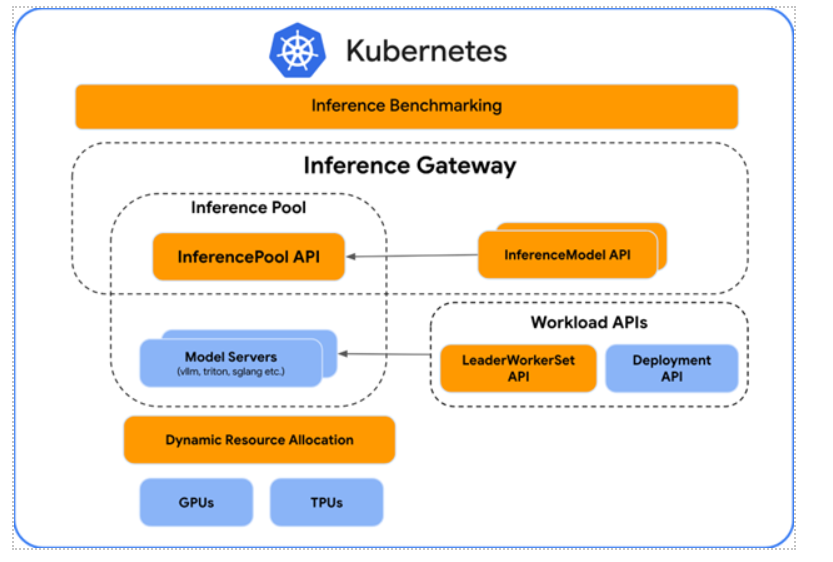
Evolving Kubernetes and GKE for Gen AI Inference - Cloud Native Now
Advertisement Space (336x280)
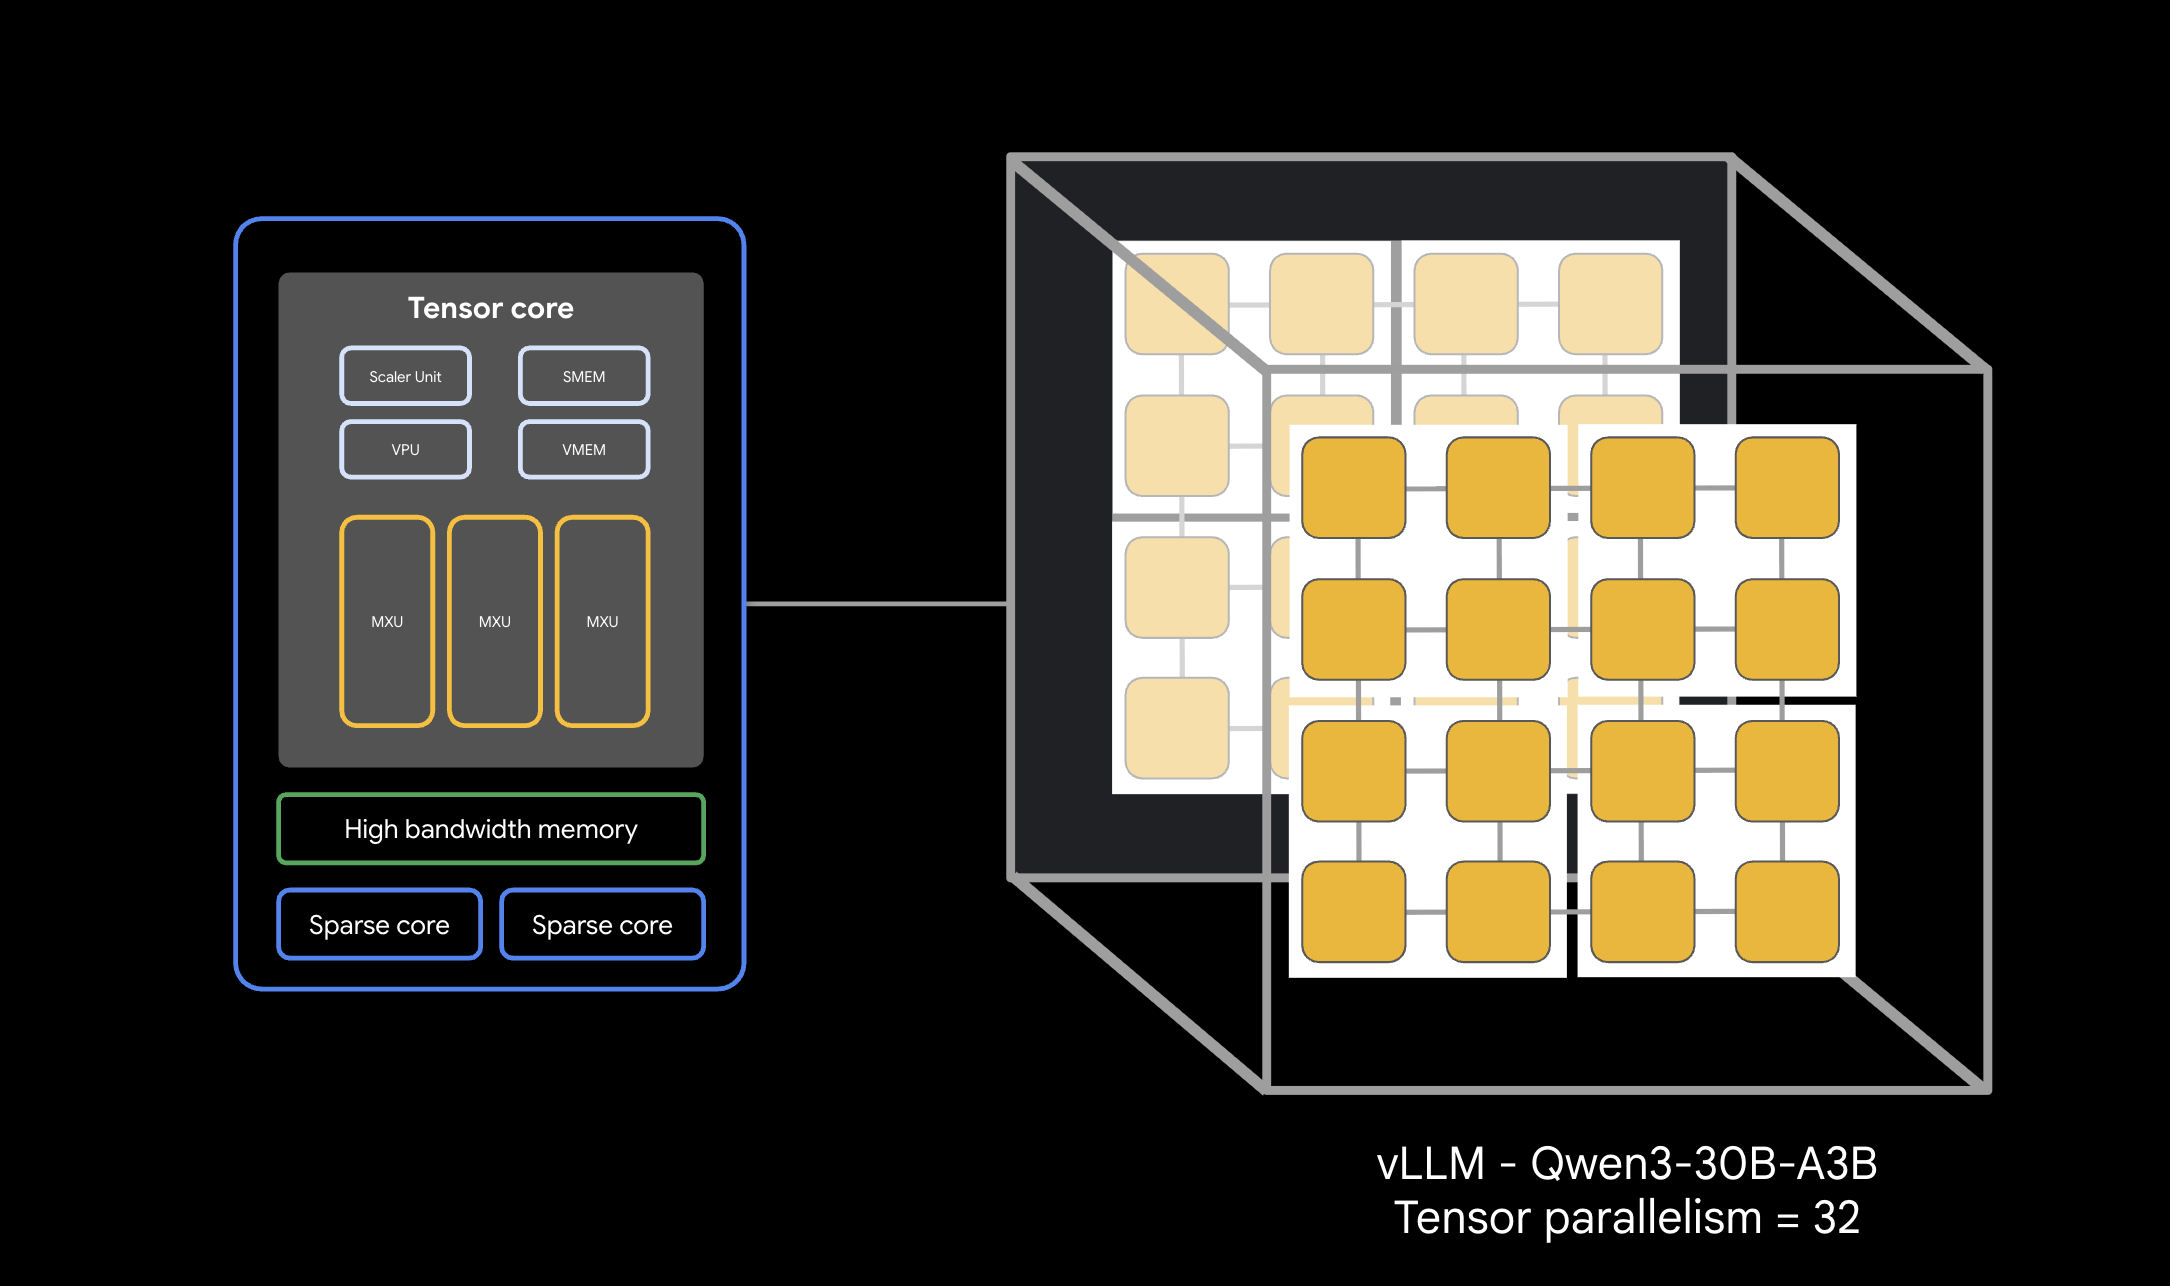
Deploy Multihost TPU vLLM Inferencing with Ray on GKE | Google Codelabs

Quickstart: High-throughput LLM inference with vLLM on Amazon EKS ...

Multi-cluster GKE Inference Gateway helps scale AI workloads | Google ...
Multi-cluster GKE Inference Gateway helps scale AI workloads
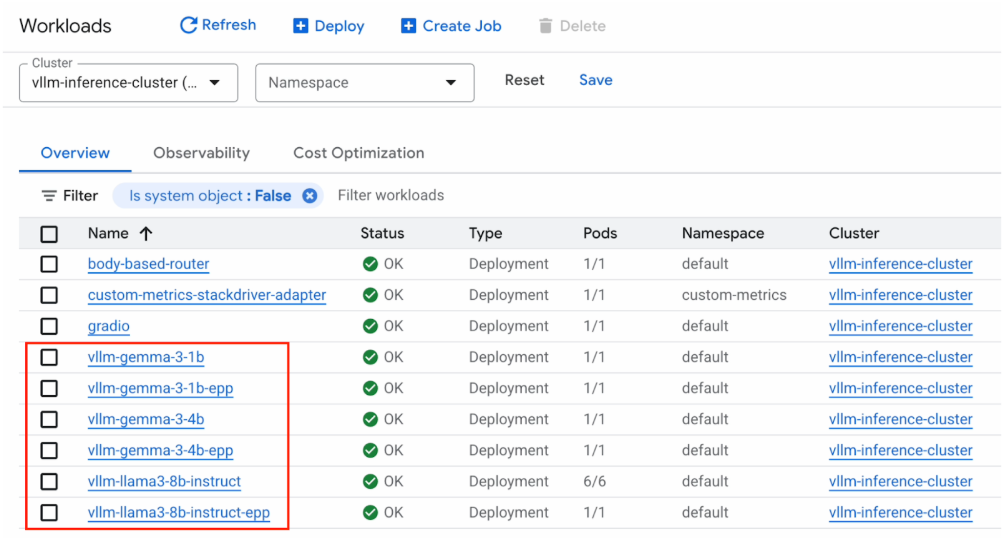
AI / LLM 서비스를 위한 클라우드 인프라 최적화 - GKE Inference Gateway - | Google Cloud 블로그

Deploy an agentic AI application on GKE with the Agent Development Kit ...

Performance of Llama 3.1 8B AI Inference using vLLM on ND-H100-v5 ...

Run OpenAI-compatible LLM inference with Gemma and vLLM | Modal Docs
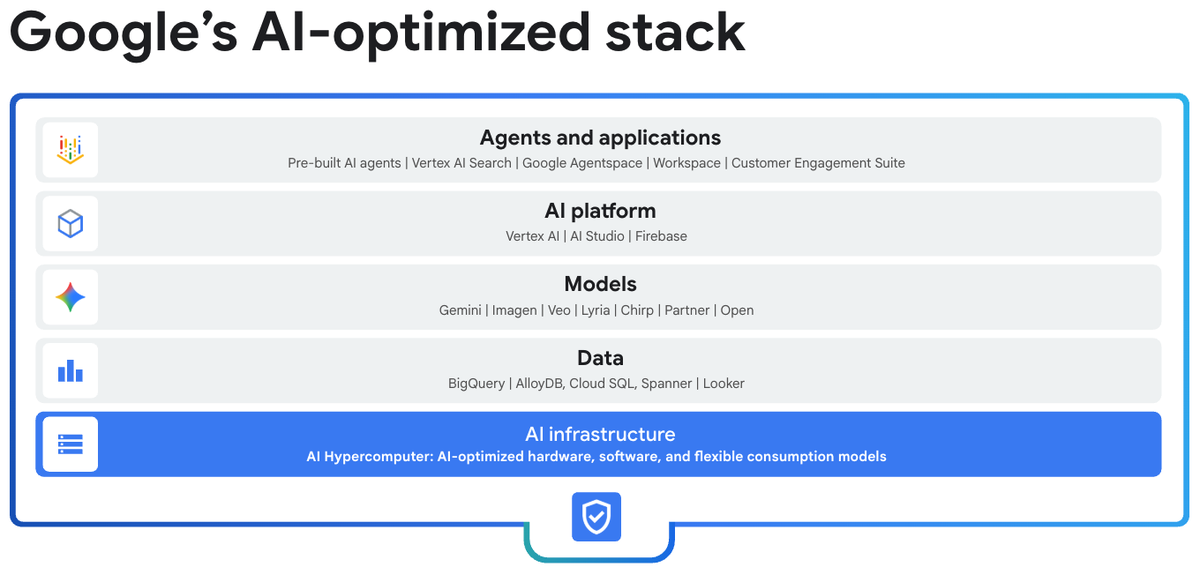
GKE Inference Gateway and Quickstart are GA | Google Cloud Blog

Open‑Source LLM Inferencing at Scale: vLLM Production Stack on Dell AI ...
Advertisement Space (336x280)
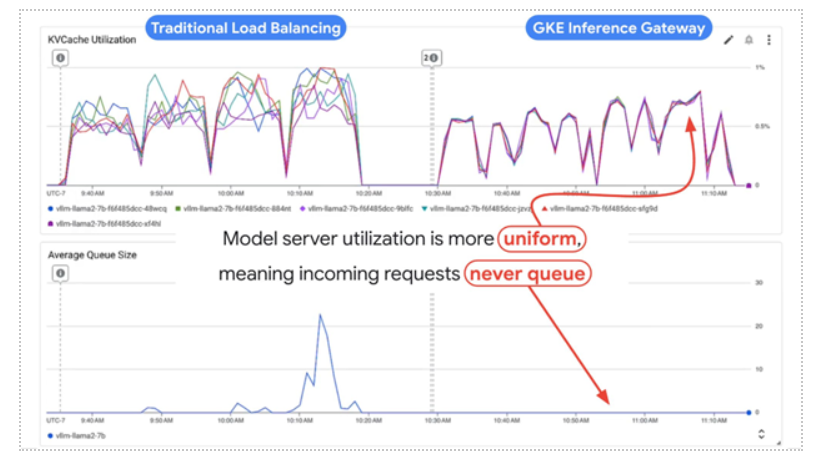
Evolving Kubernetes and GKE for Gen AI Inference - Cloud Native Now

Optimizing vLLM Inference with Run:AI and Fracture GPU | by Ardavan ...

AI Factories: LLM Inference with vLLM

關於由 llm-d 支援的 GKE Inference Gateway | GKE networking | Google Cloud ...
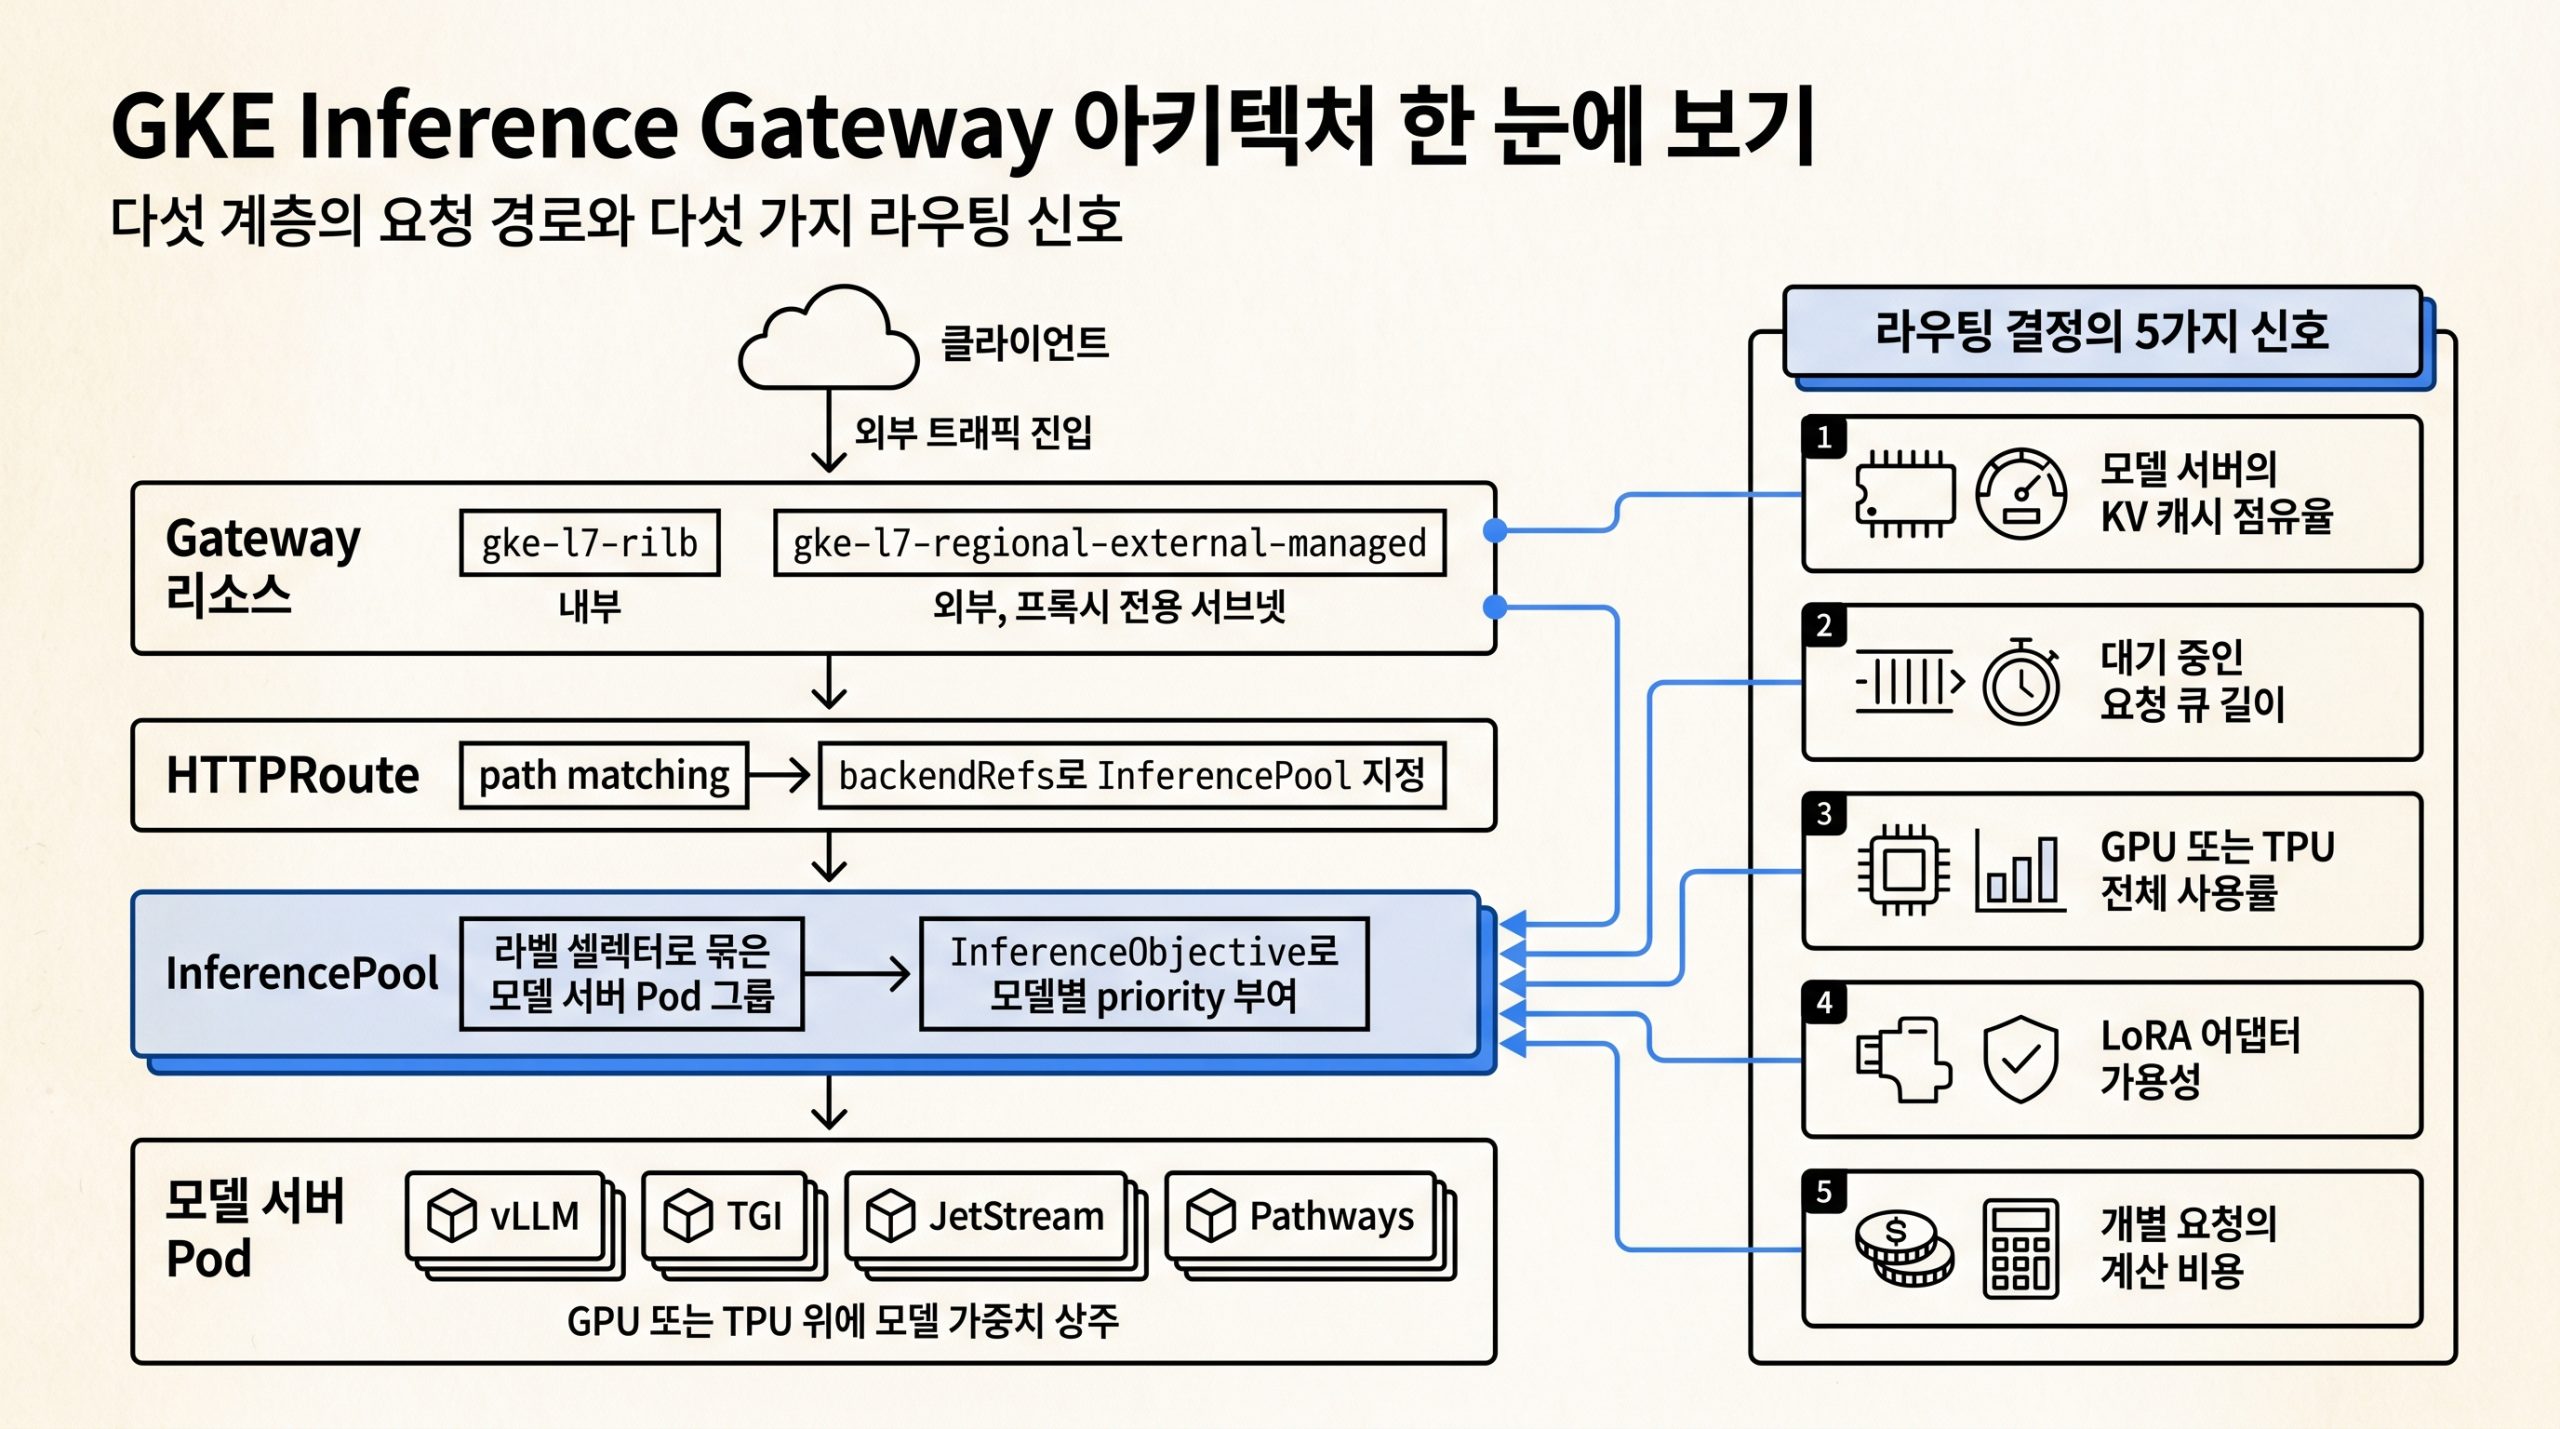
Google Next 2026 GKE - 02 Standardizing LLM Serving with Inference ...
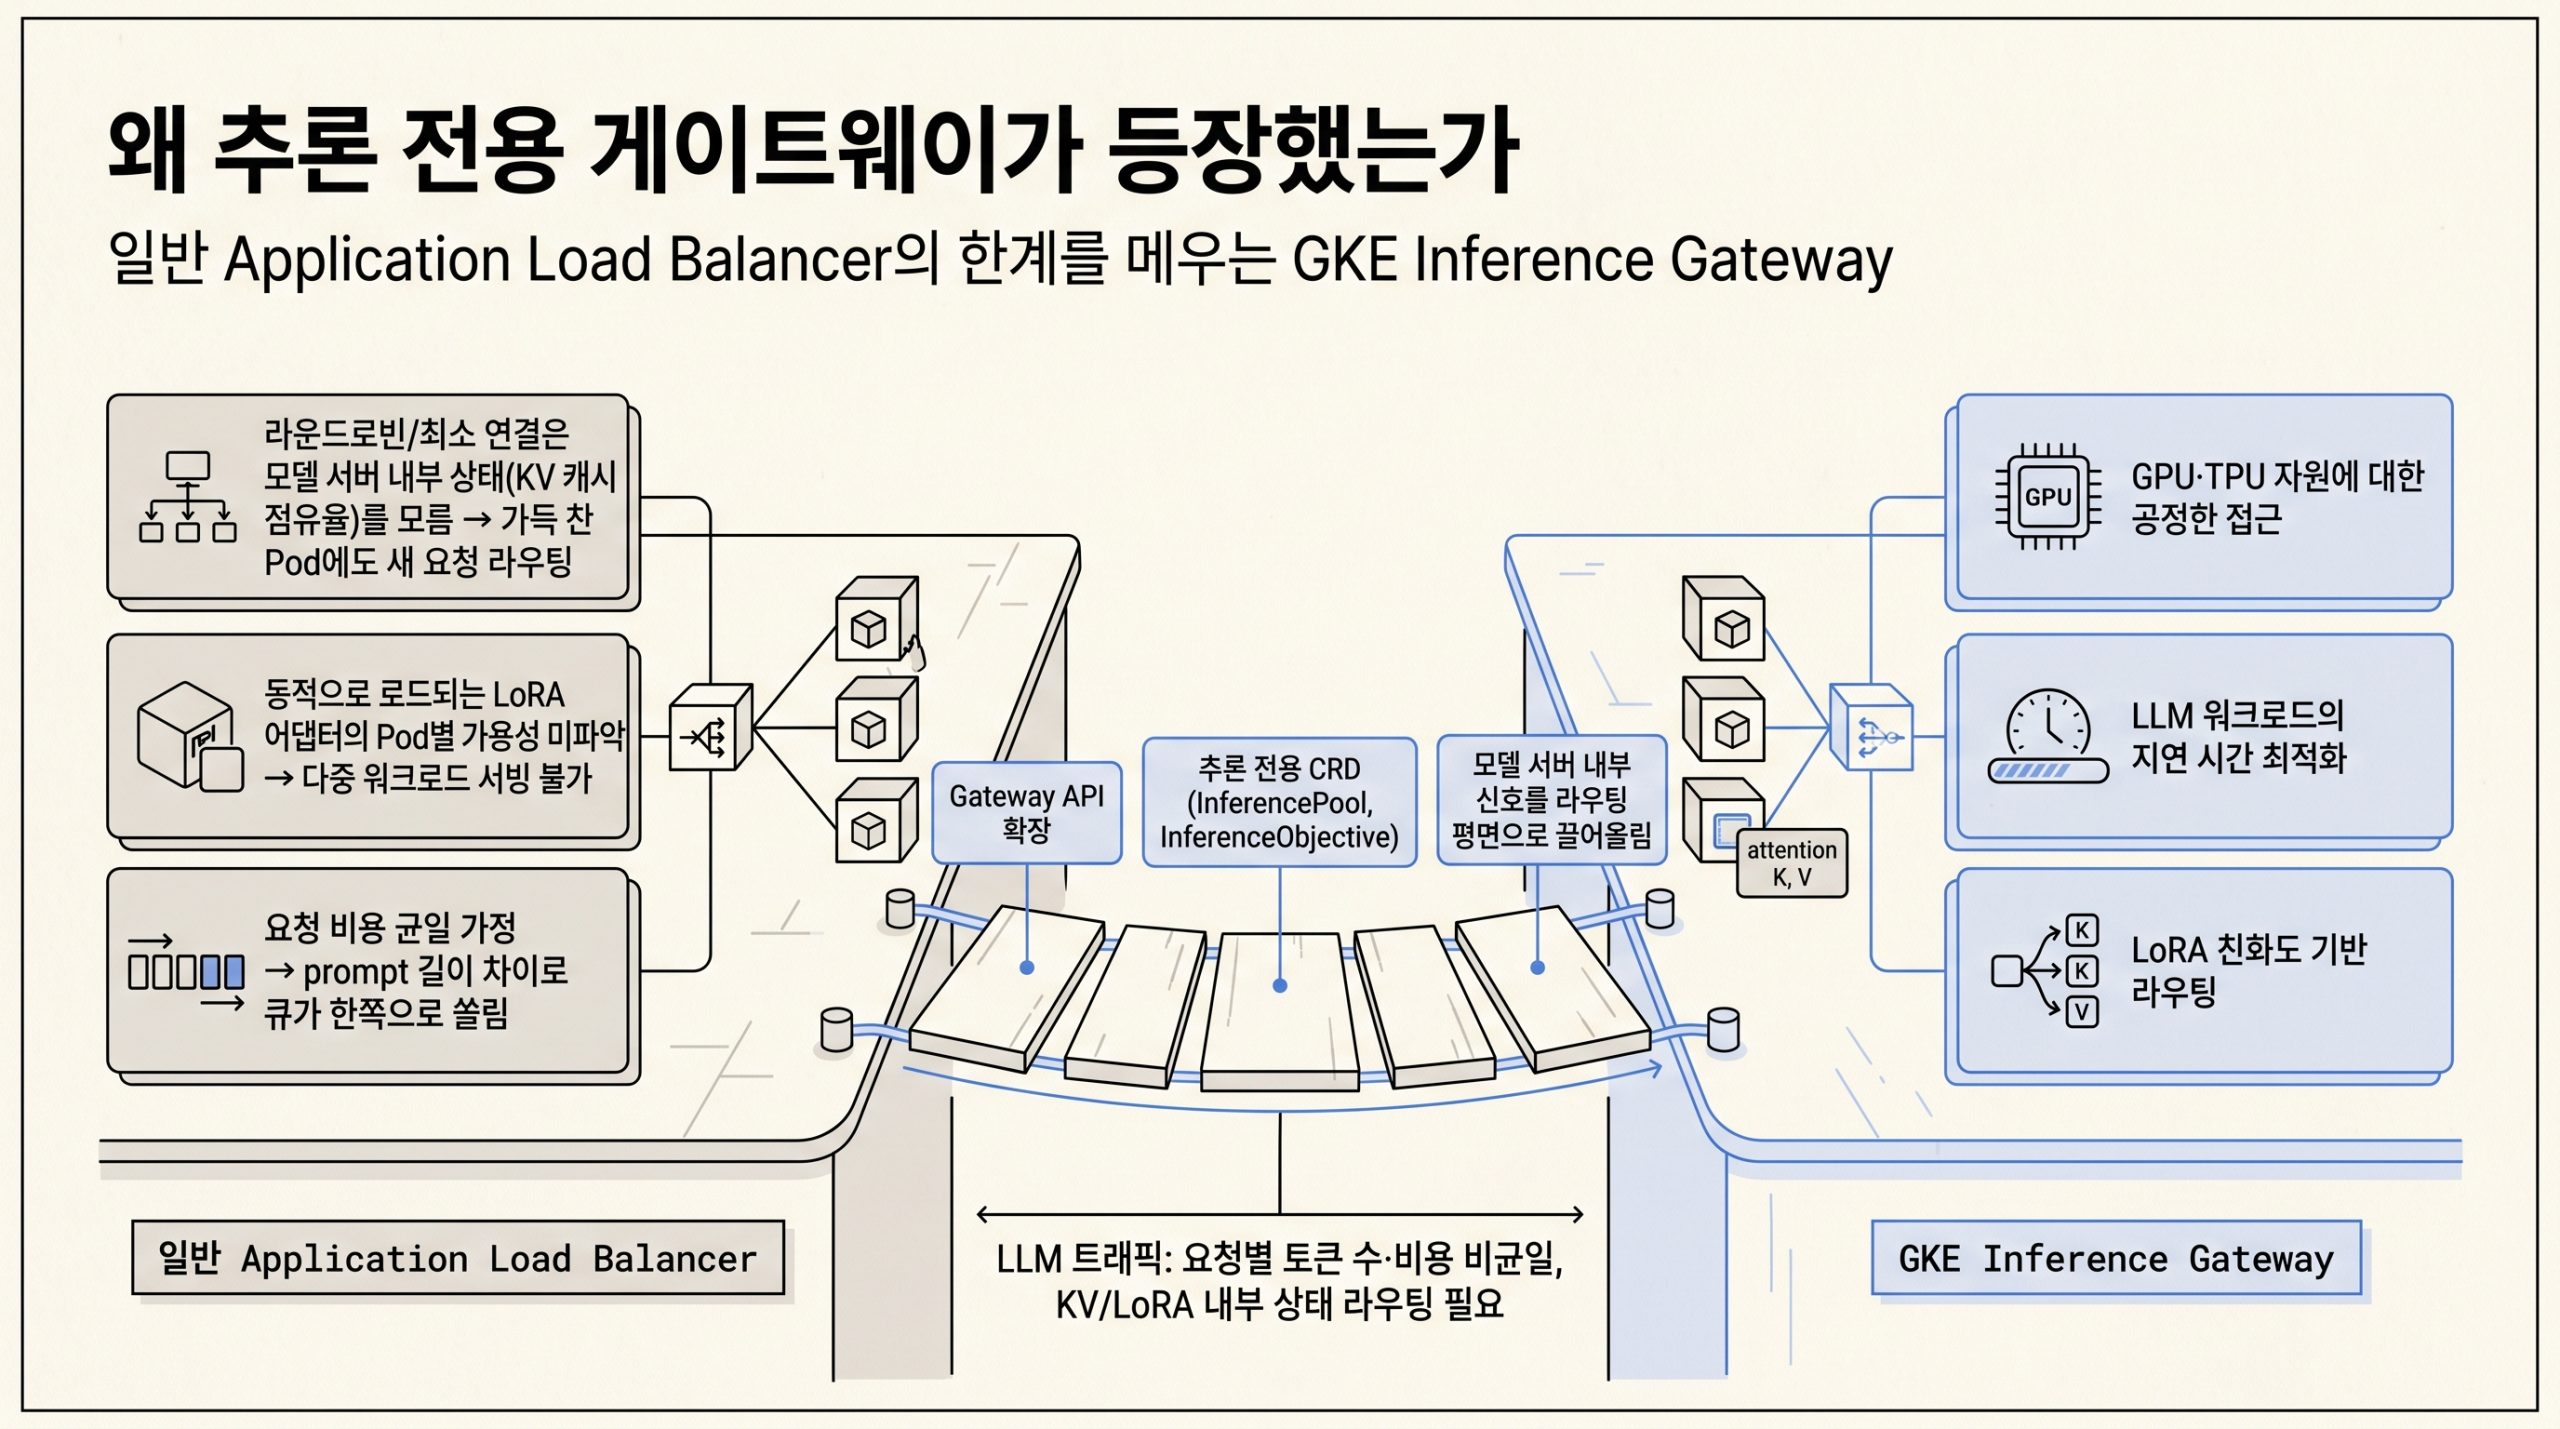
Google Next 2026 GKE - 02 Standardizing LLM Serving with Inference ...