
An Endtoend View Of Ai Inference Stacks With Vllm And Alternatives
Free Video: Improve AI Inference - Serving Models With KServe and VLLM ...

vLLM: Production AI Inference on GKE with OpenWebUI, Gateway API, and ...

12 vLLM Alternatives for Efficient and Scalable LLM Inference ...
12 vLLM Alternatives for Efficient and Scalable LLM Inference ...
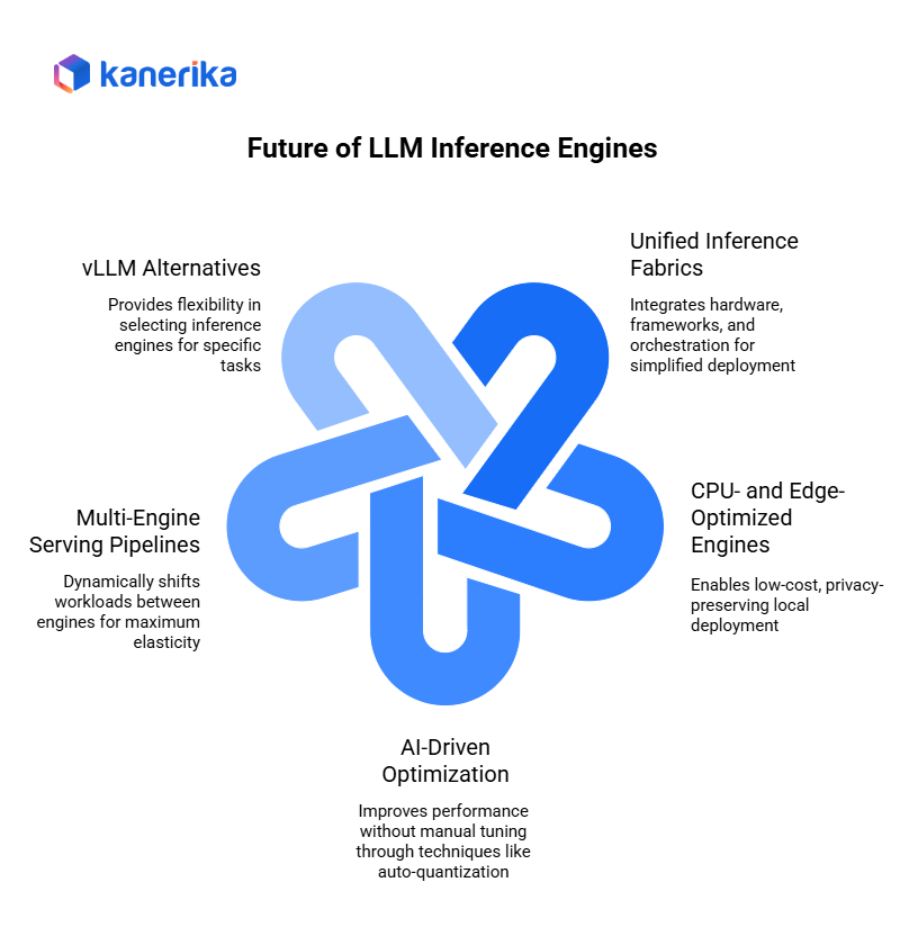
Top 10 vLLM Alternatives for Faster AI Inference in 2026
12 vLLM Alternatives for Efficient and Scalable LLM Inference ...
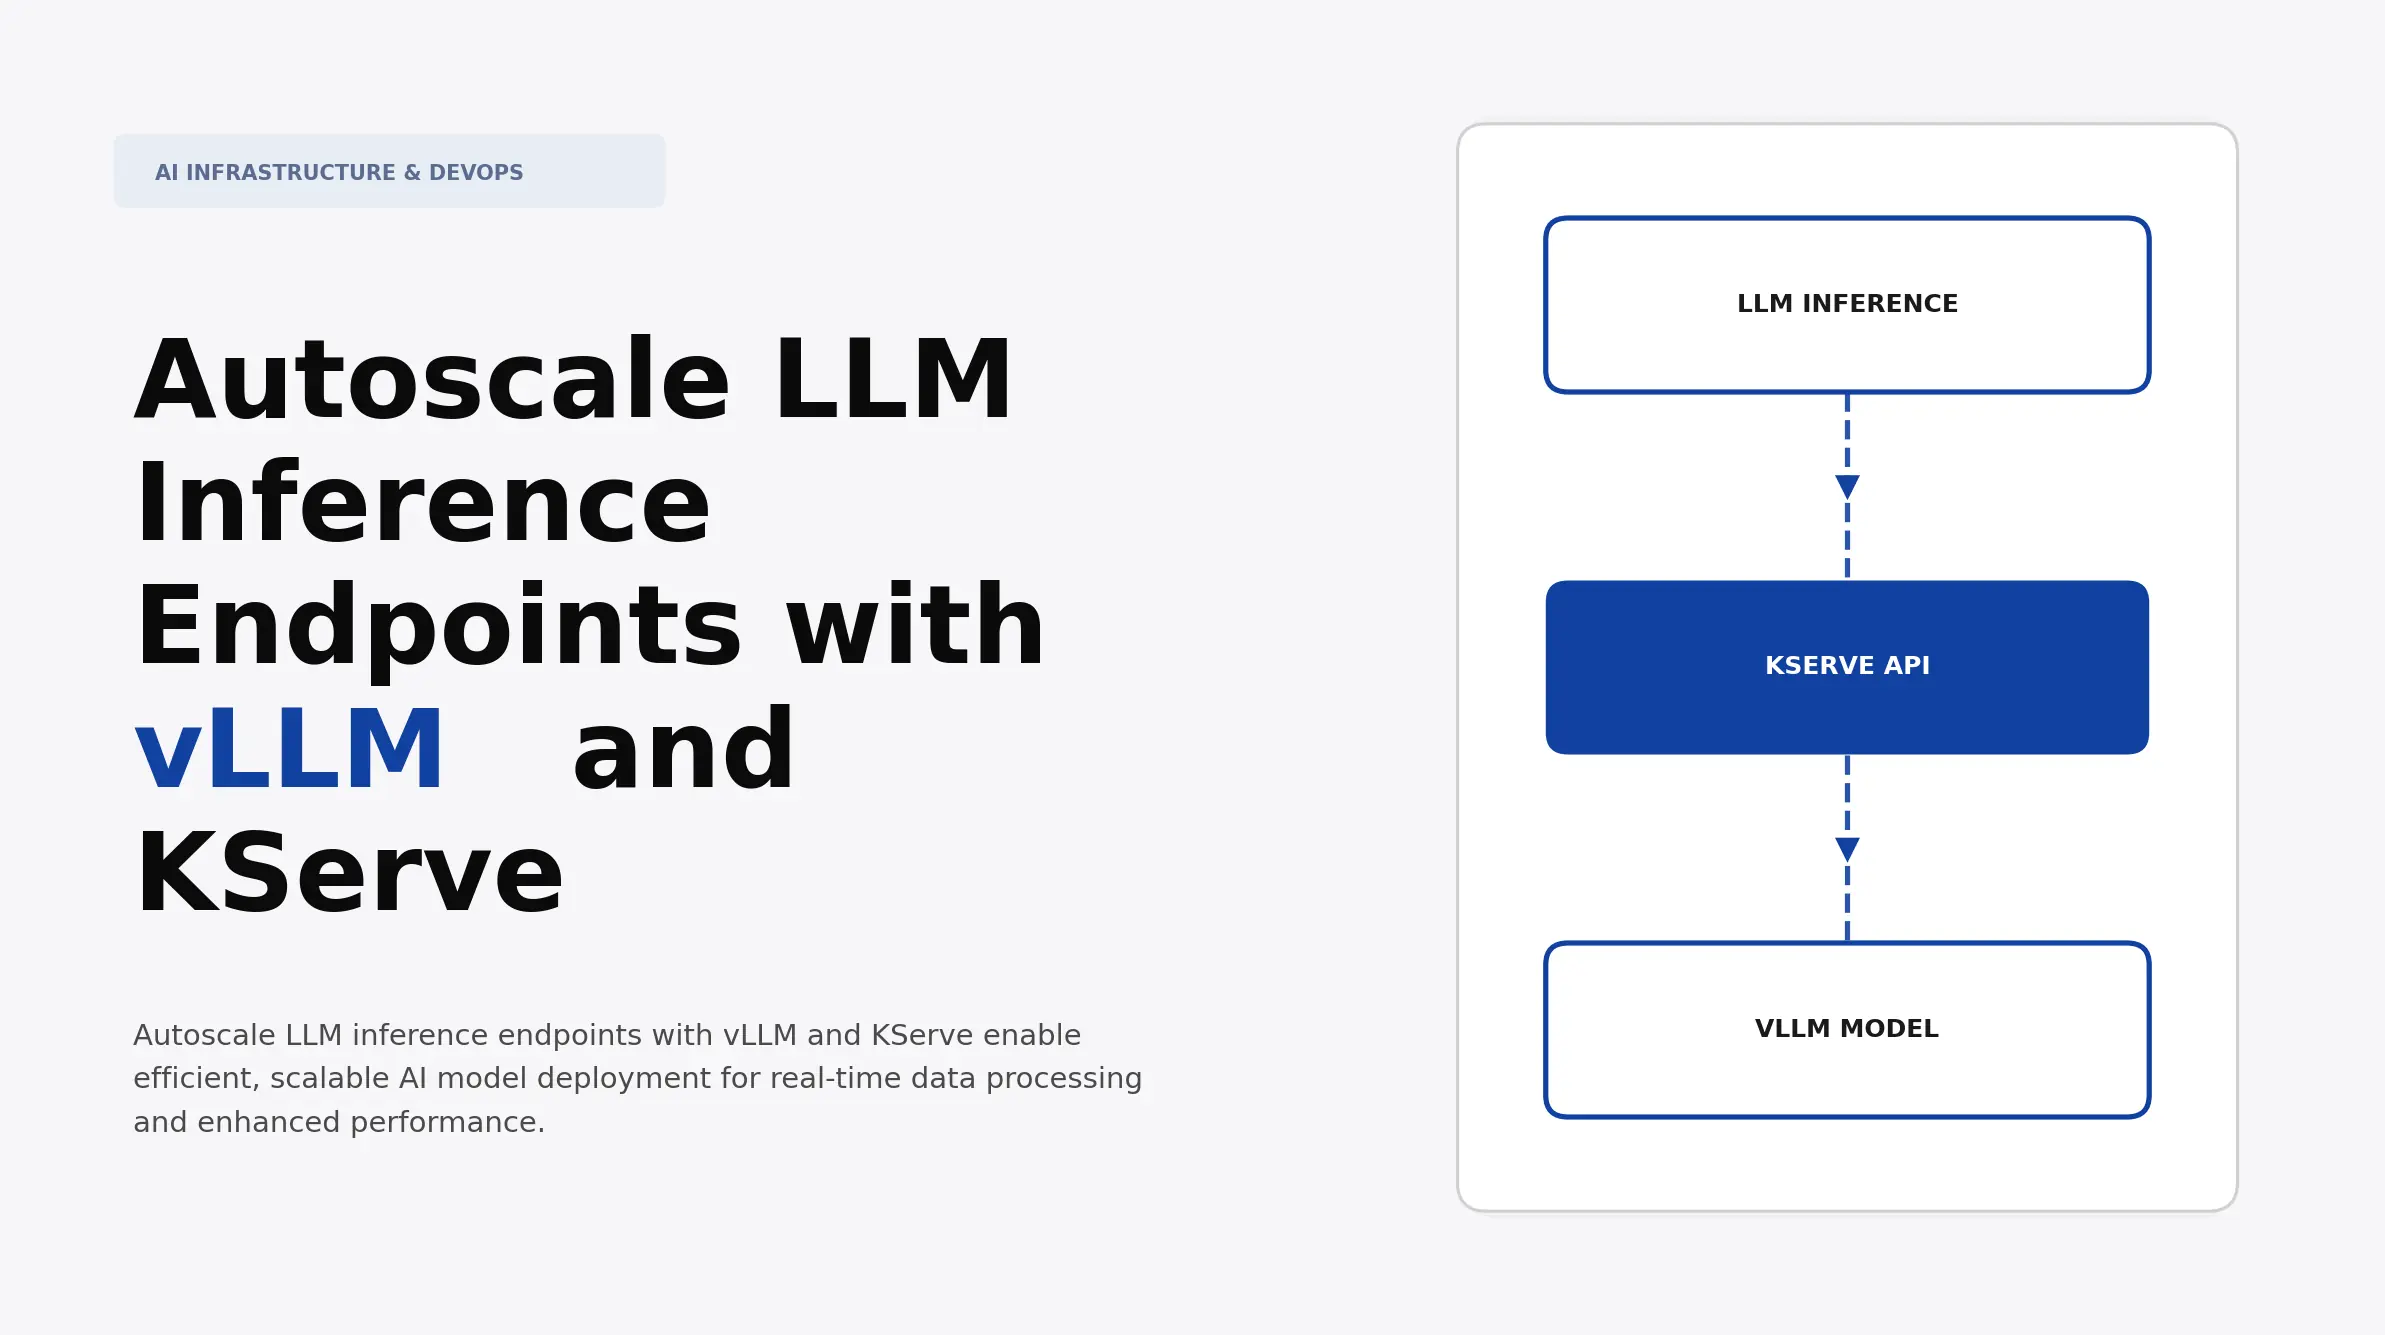
Autoscale LLM Inference Endpoints with vLLM and KServe | Atomic Loops

12 vLLM Alternatives for Efficient and Scalable LLM Inference ...

Components of an AI inference stack - AWS Prescriptive Guidance
High Performance and Easy Deployment of vLLM in K8S with vLLM ...
Advertisement Space (300x250)

Performance of Llama 3.1 8B AI Inference using vLLM on ND-H100-v5 ...
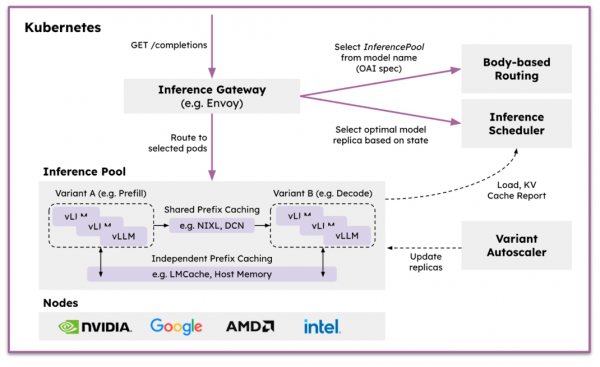
Why vLLM is the best choice for AI inference today | Red Hat Developer
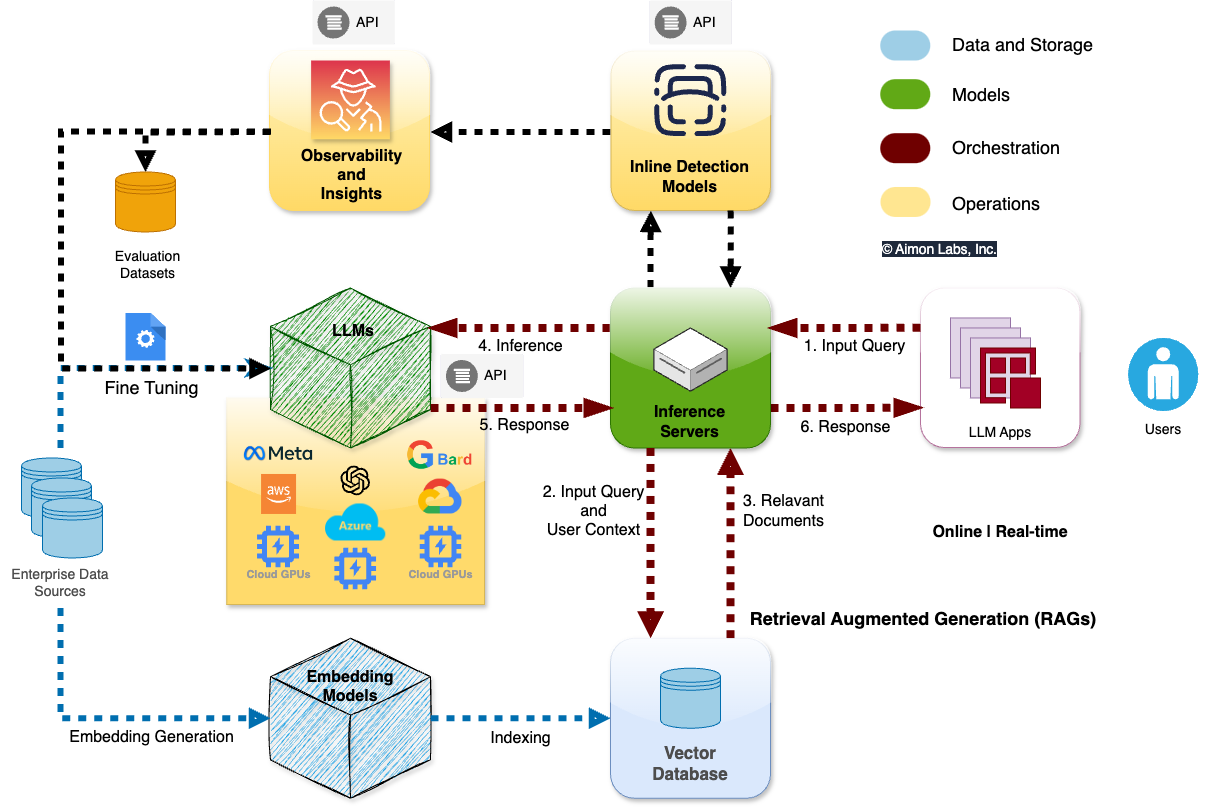
Popular LLM Inference Stacks and Setups
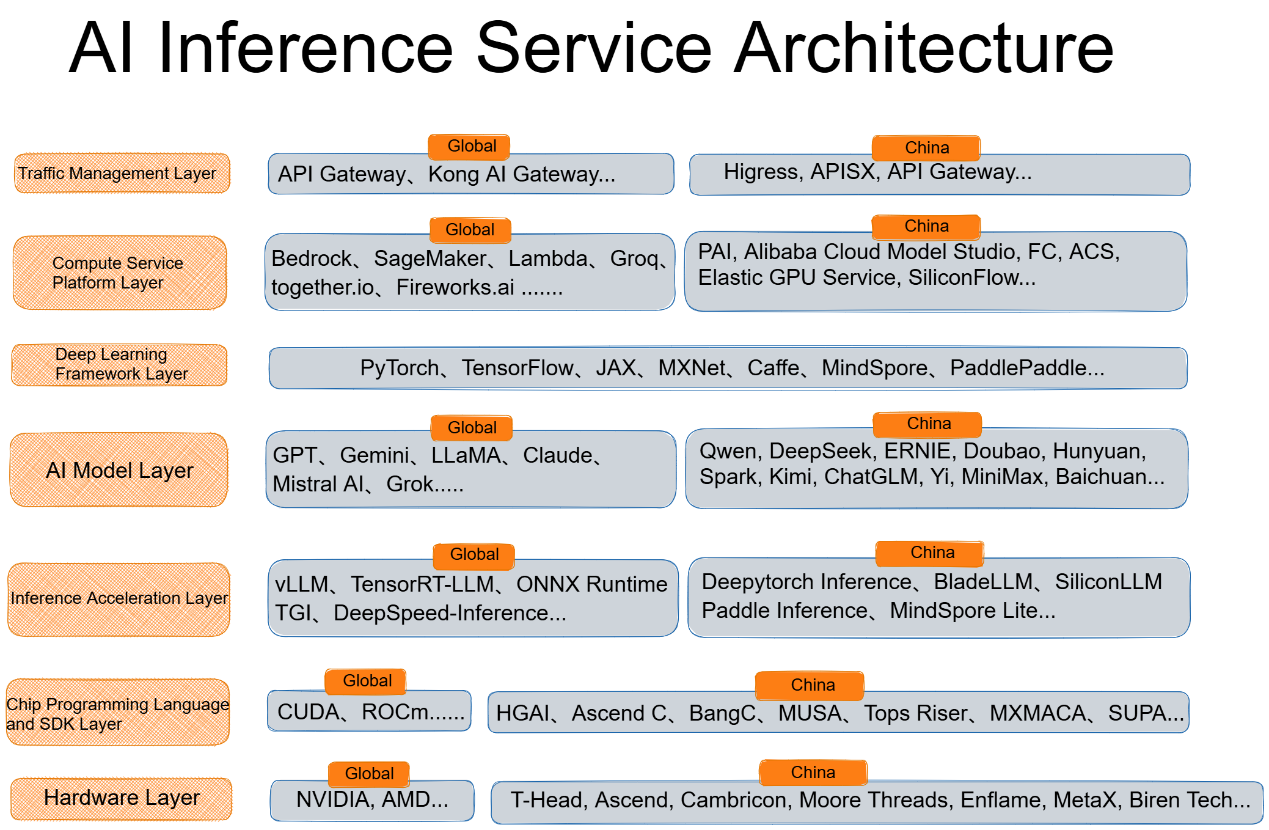
AI Model Inference Service: An Overview - Alibaba Cloud Community

Alluxio & vLLM Partner to Optimize AI Inference Performance
vLLM - High-throughput LLM inference engine with PagedAttention ... at ...
Best 5 vLLM Alternatives for Self-Hosted Inference in 2026
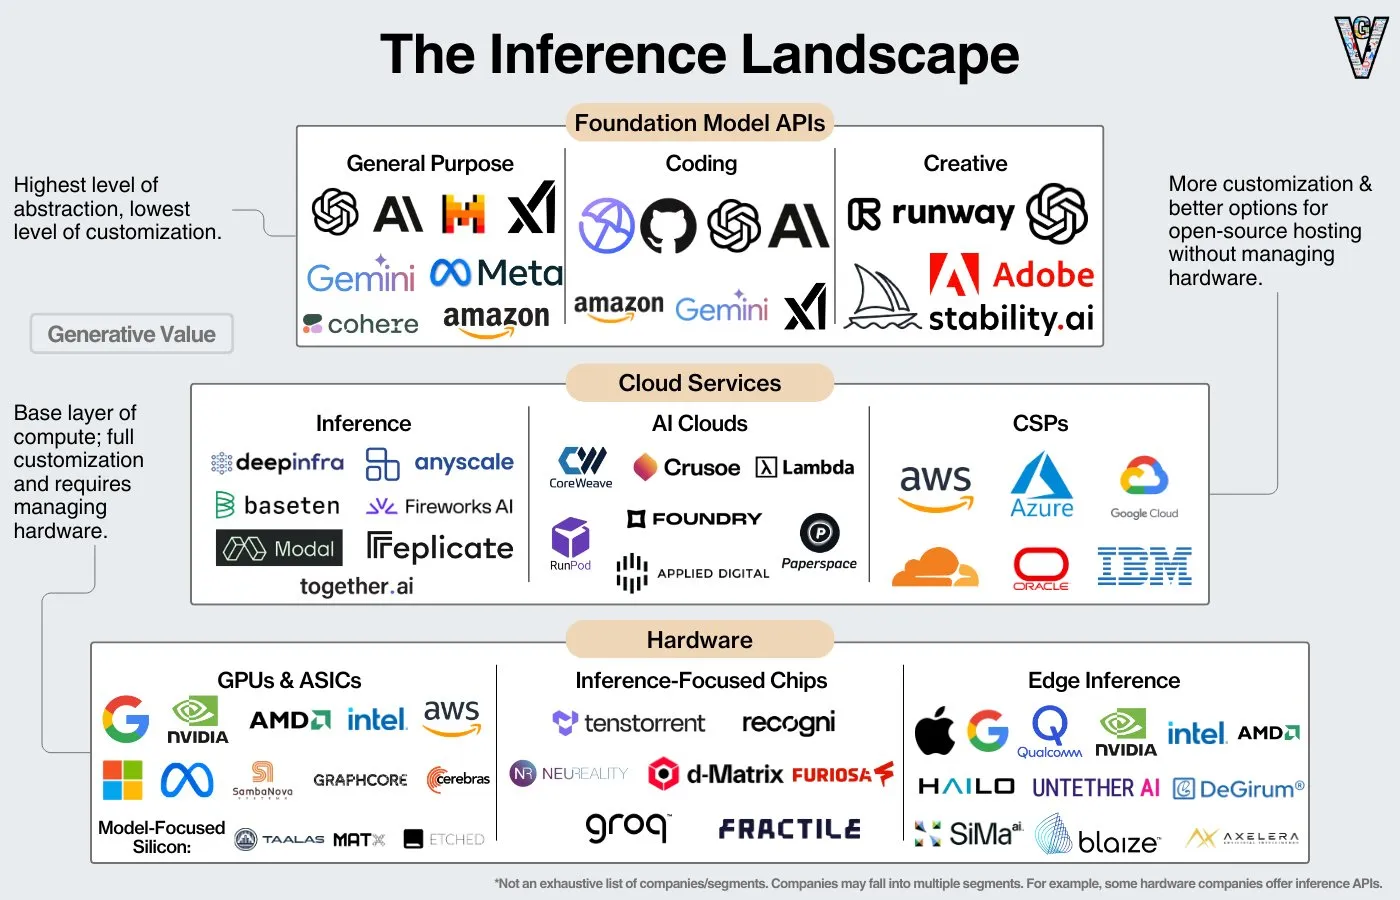
AI Model Inference Service: An Overview - Alibaba Cloud Community

An Open Source Stack for AI Compute: Kubernetes + Ray + PyTorch + vLLM ...
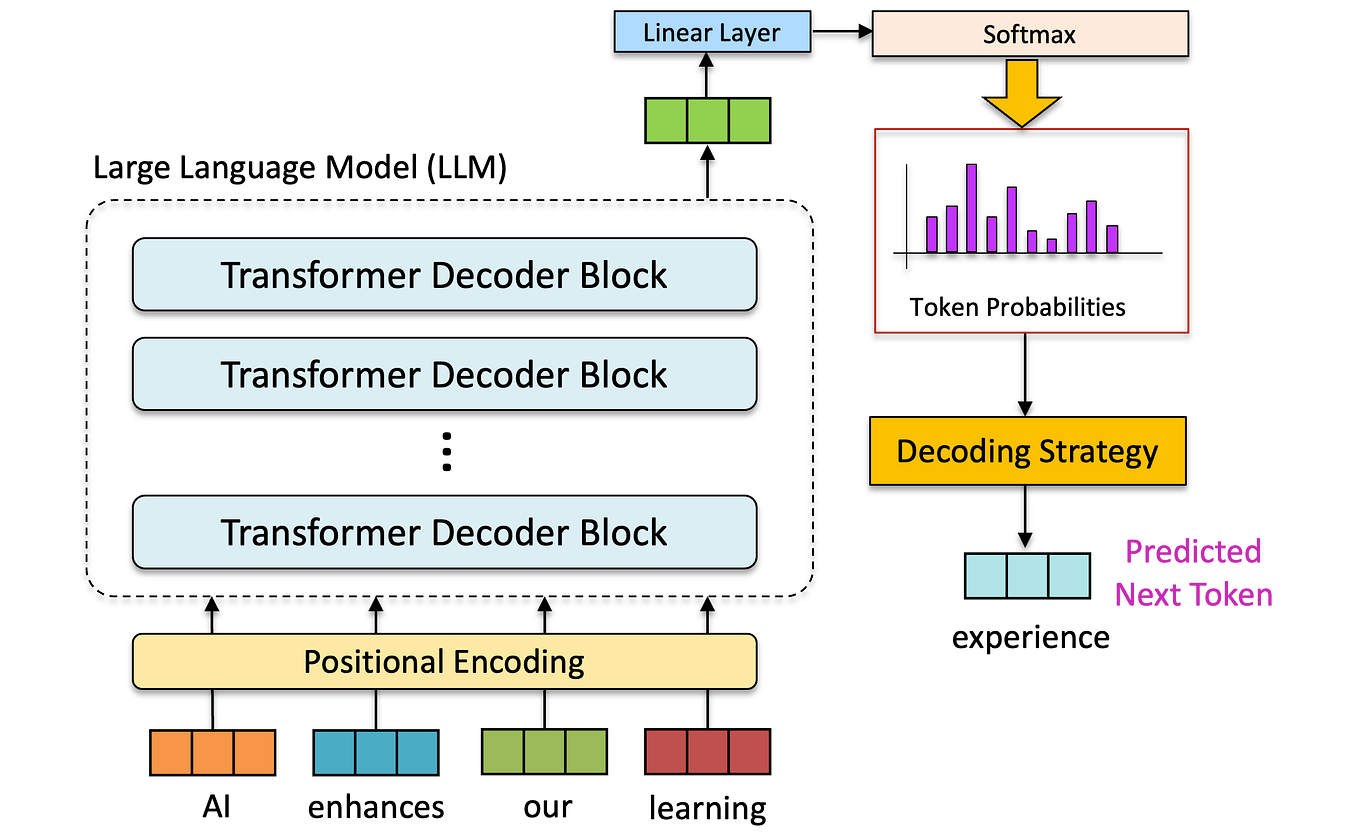
LLM Inference — A Detailed Breakdown of Transformer Architecture and ...
Advertisement Space (336x280)

Understanding and Optimizing Multi-Stage AI Inference Pipelines | AI ...
Distributed Inference with vLLM | vLLM Blog

Evaluation of Generative AI Models and Search Use Case
vLLM Inference Optimization on RHEL AI | Luca Berton
Optimize AI Inference Performance with NVIDIA Full-Stack Solutions ...

Getting Started with vLLM Docker: GPU-Powered Inference Using the ...

10 Best vLLM Alternatives for LLM Inference in Production (2026) - DEV ...
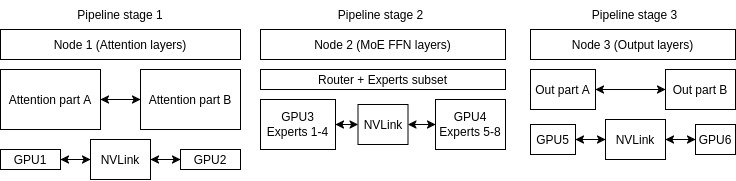
Why vLLM is the best choice for AI inference today | Red Hat Developer
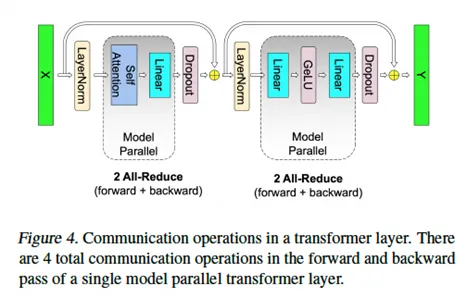
Analyzing the Distributed Inference Process Using vLLM and Ray from the ...
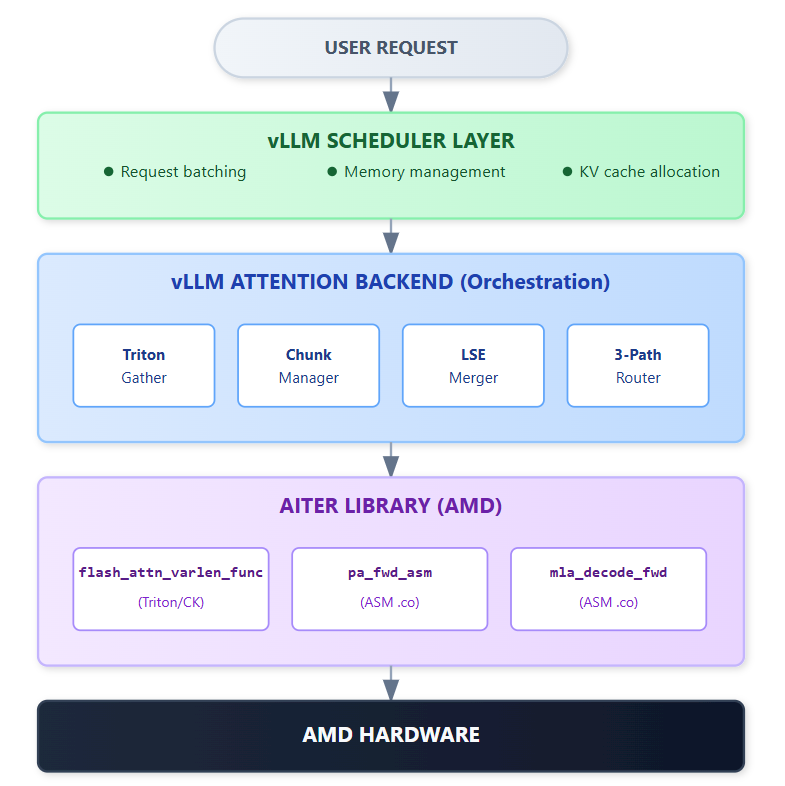
Beyond Porting: How vLLM Orchestrates High-Performance Inference on AMD ...
Advertisement Space (336x280)
Pliops Announces Collaboration with vLLM Production Stack to Enhance ...
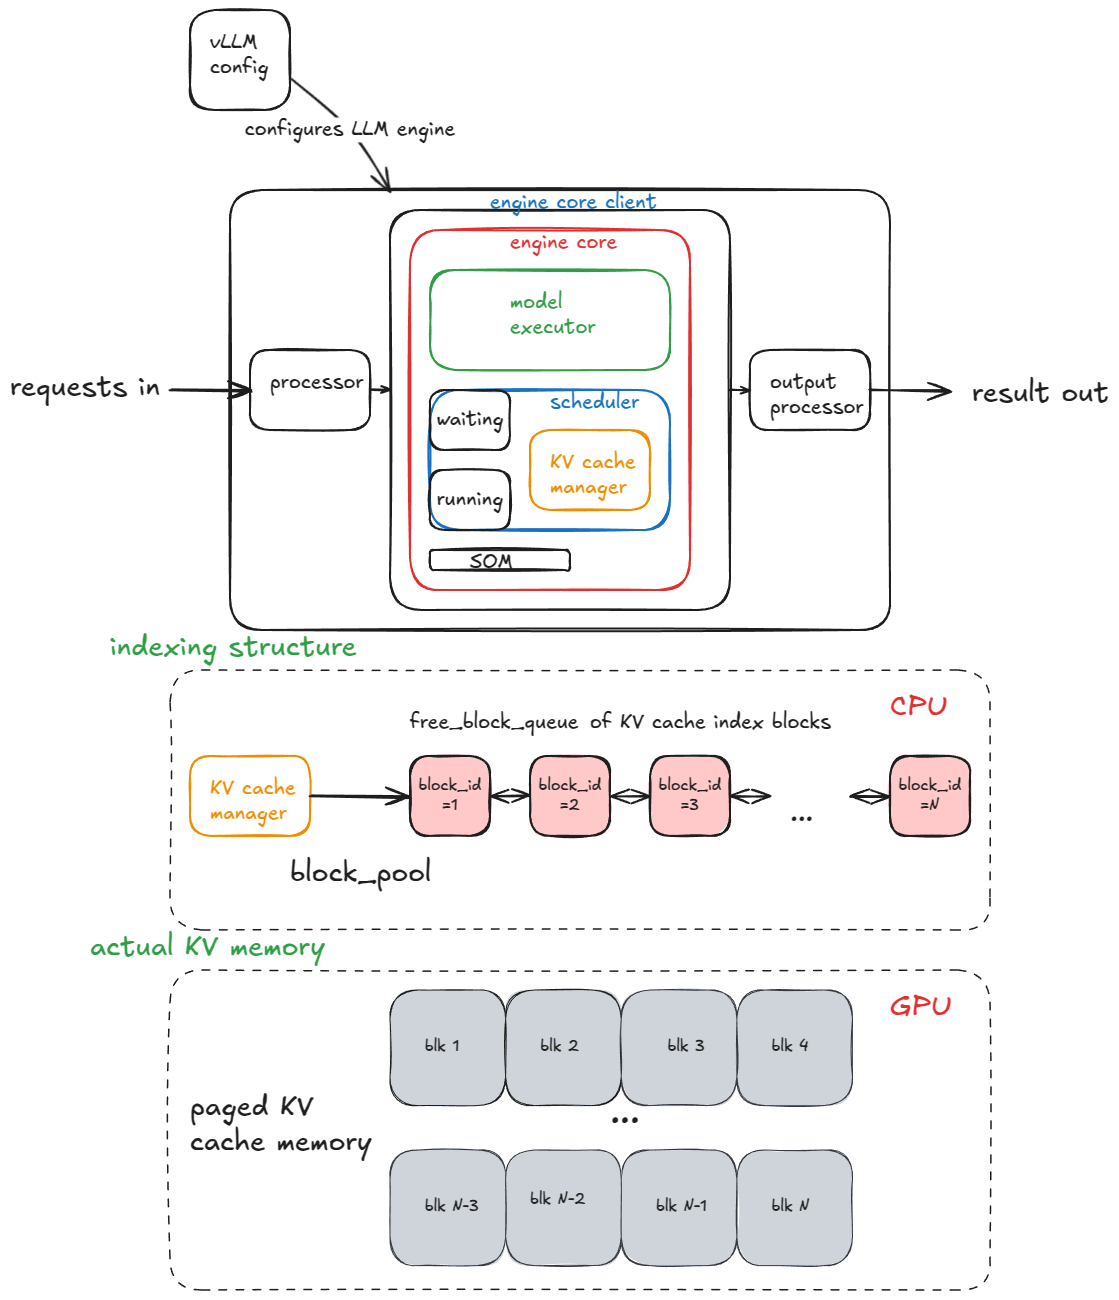
Inside vLLM: Anatomy of a High-Throughput LLM Inference System ...

vLLM production-stack: LLM inference for Enterprises (part1) - Cloudthrill
AI/ML Infra Meetup | A Faster and More Cost Efficient LLM Inference ...

vLLM Production Stack now has an end-to-end deployment guide on ...

vLLM Advanced: Building Custom Inference Pipelines at Scale (2026 Guide ...