
Vllm Session 2 The Engine Layer Request Management Dev Community

vLLM — Session 2: The Engine Layer — Request Management - DEV Community

Session 1: vLLM Overview and the User API - DEV Community

Memory Management and Scheduling in the vLLM Engine | by Priyadarshini ...
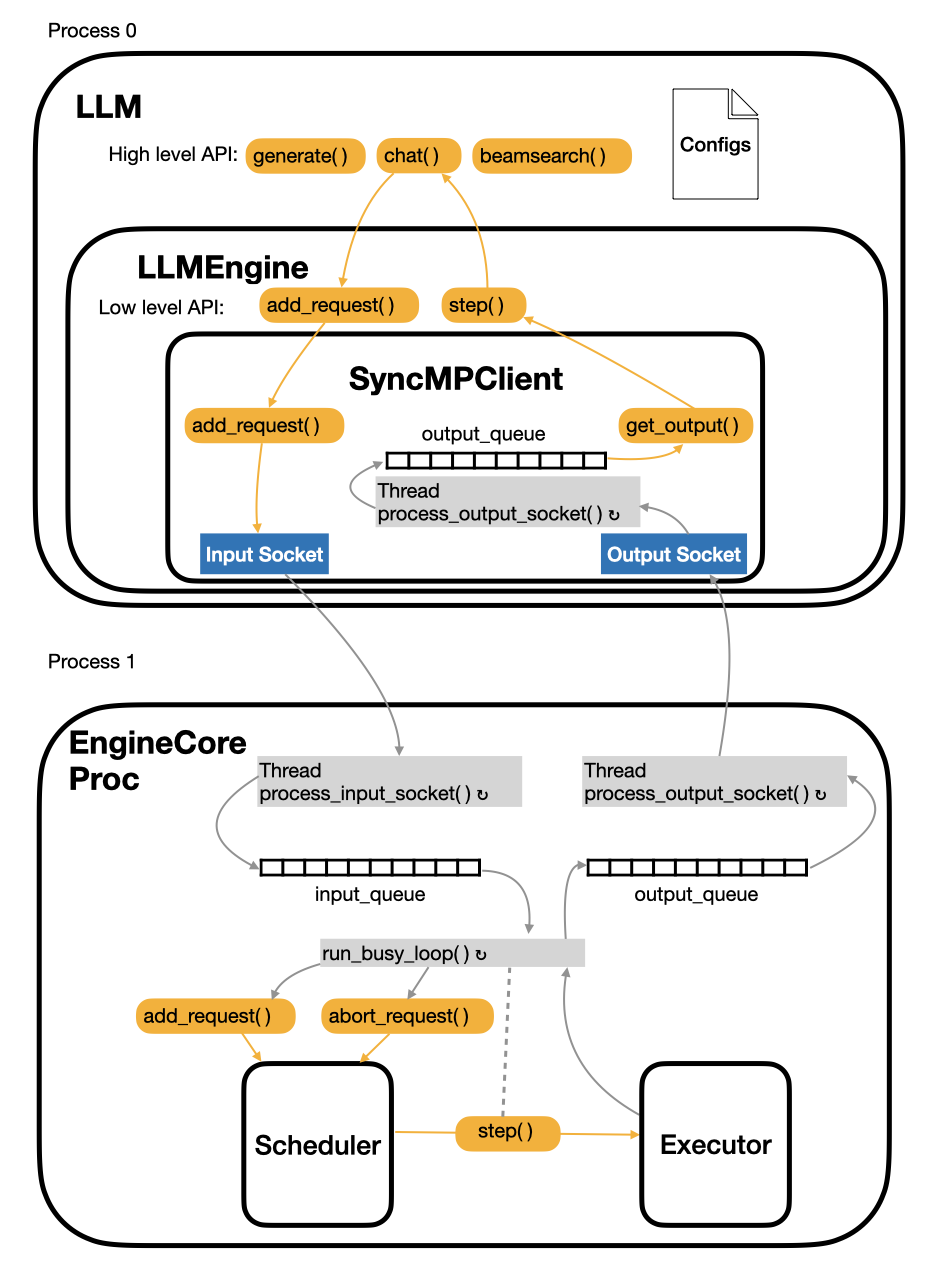
vLLM V1 Engine Design Ⅰ: The Excution Loop - Haisheng's Note Zoo

Deploy the vLLM Inference Engine to Run Large Language Models (LLM) on ...
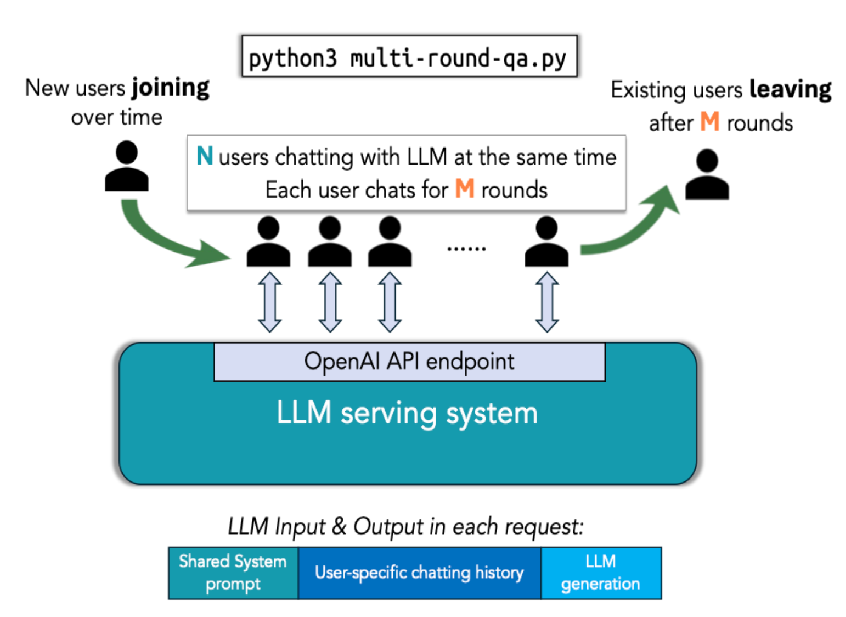
Deploy DeepSeek-R1 with the vLLM V1 engine and build an AI-powered ...

How the VLLM inference engine works? - YouTube
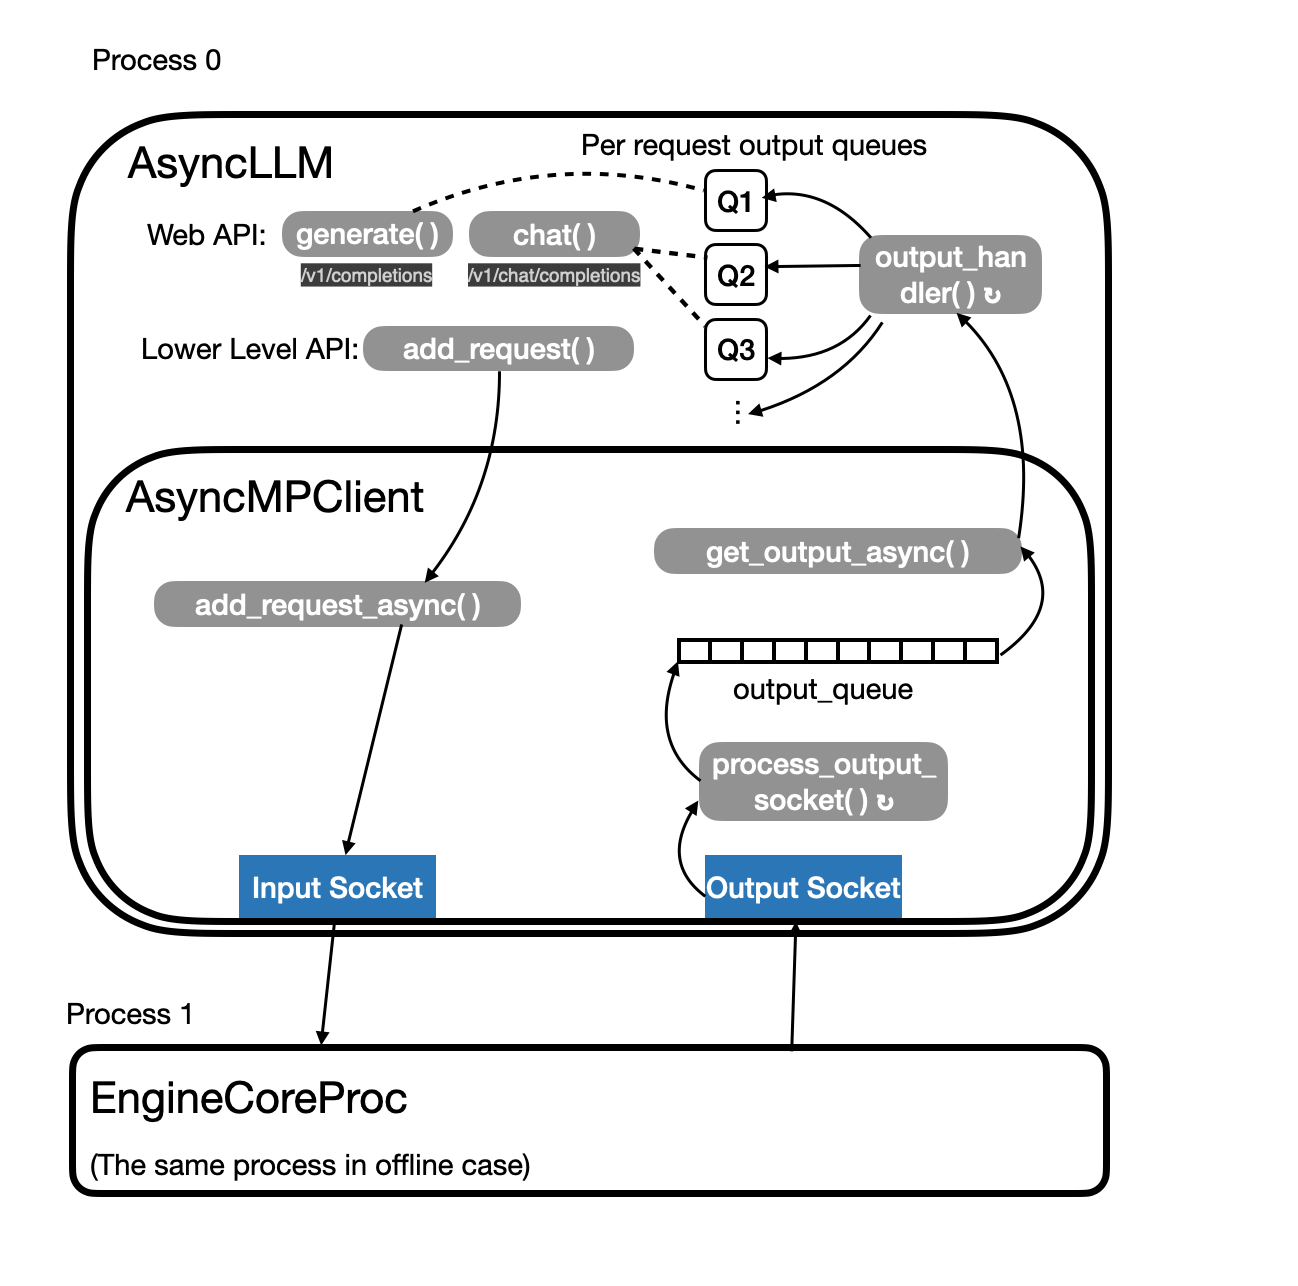
vLLM V1 Engine Design Ⅰ: The Excution Loop - Haisheng's Note Zoo

vLLM Website Launch: Community Resources and Tools | vLLM posted on the ...
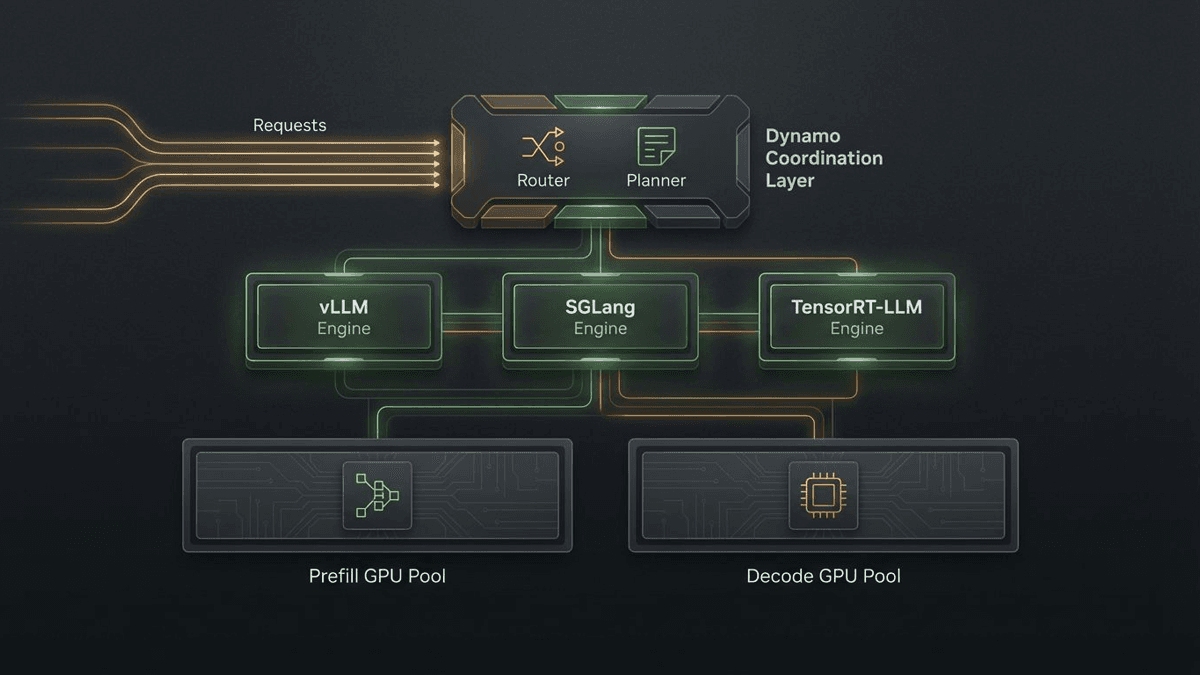
NVIDIA Dynamo is the orchestration layer above vLLM | AI News Silo
Advertisement Space (300x250)
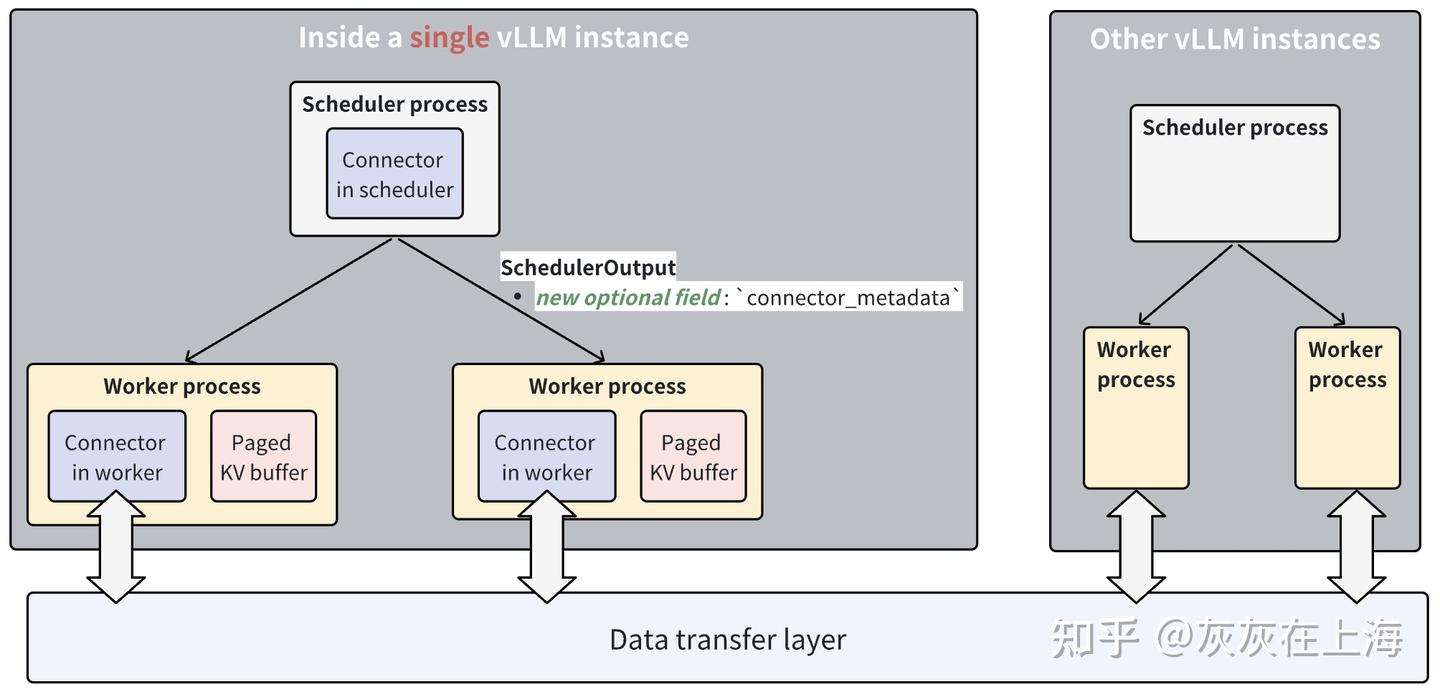
vLLM PD 分离系列(二)- Engine V1 PD 分离 - 知乎

vLLM Explained: How PagedAttention Makes LLMs Faster and Cheaper - DEV ...
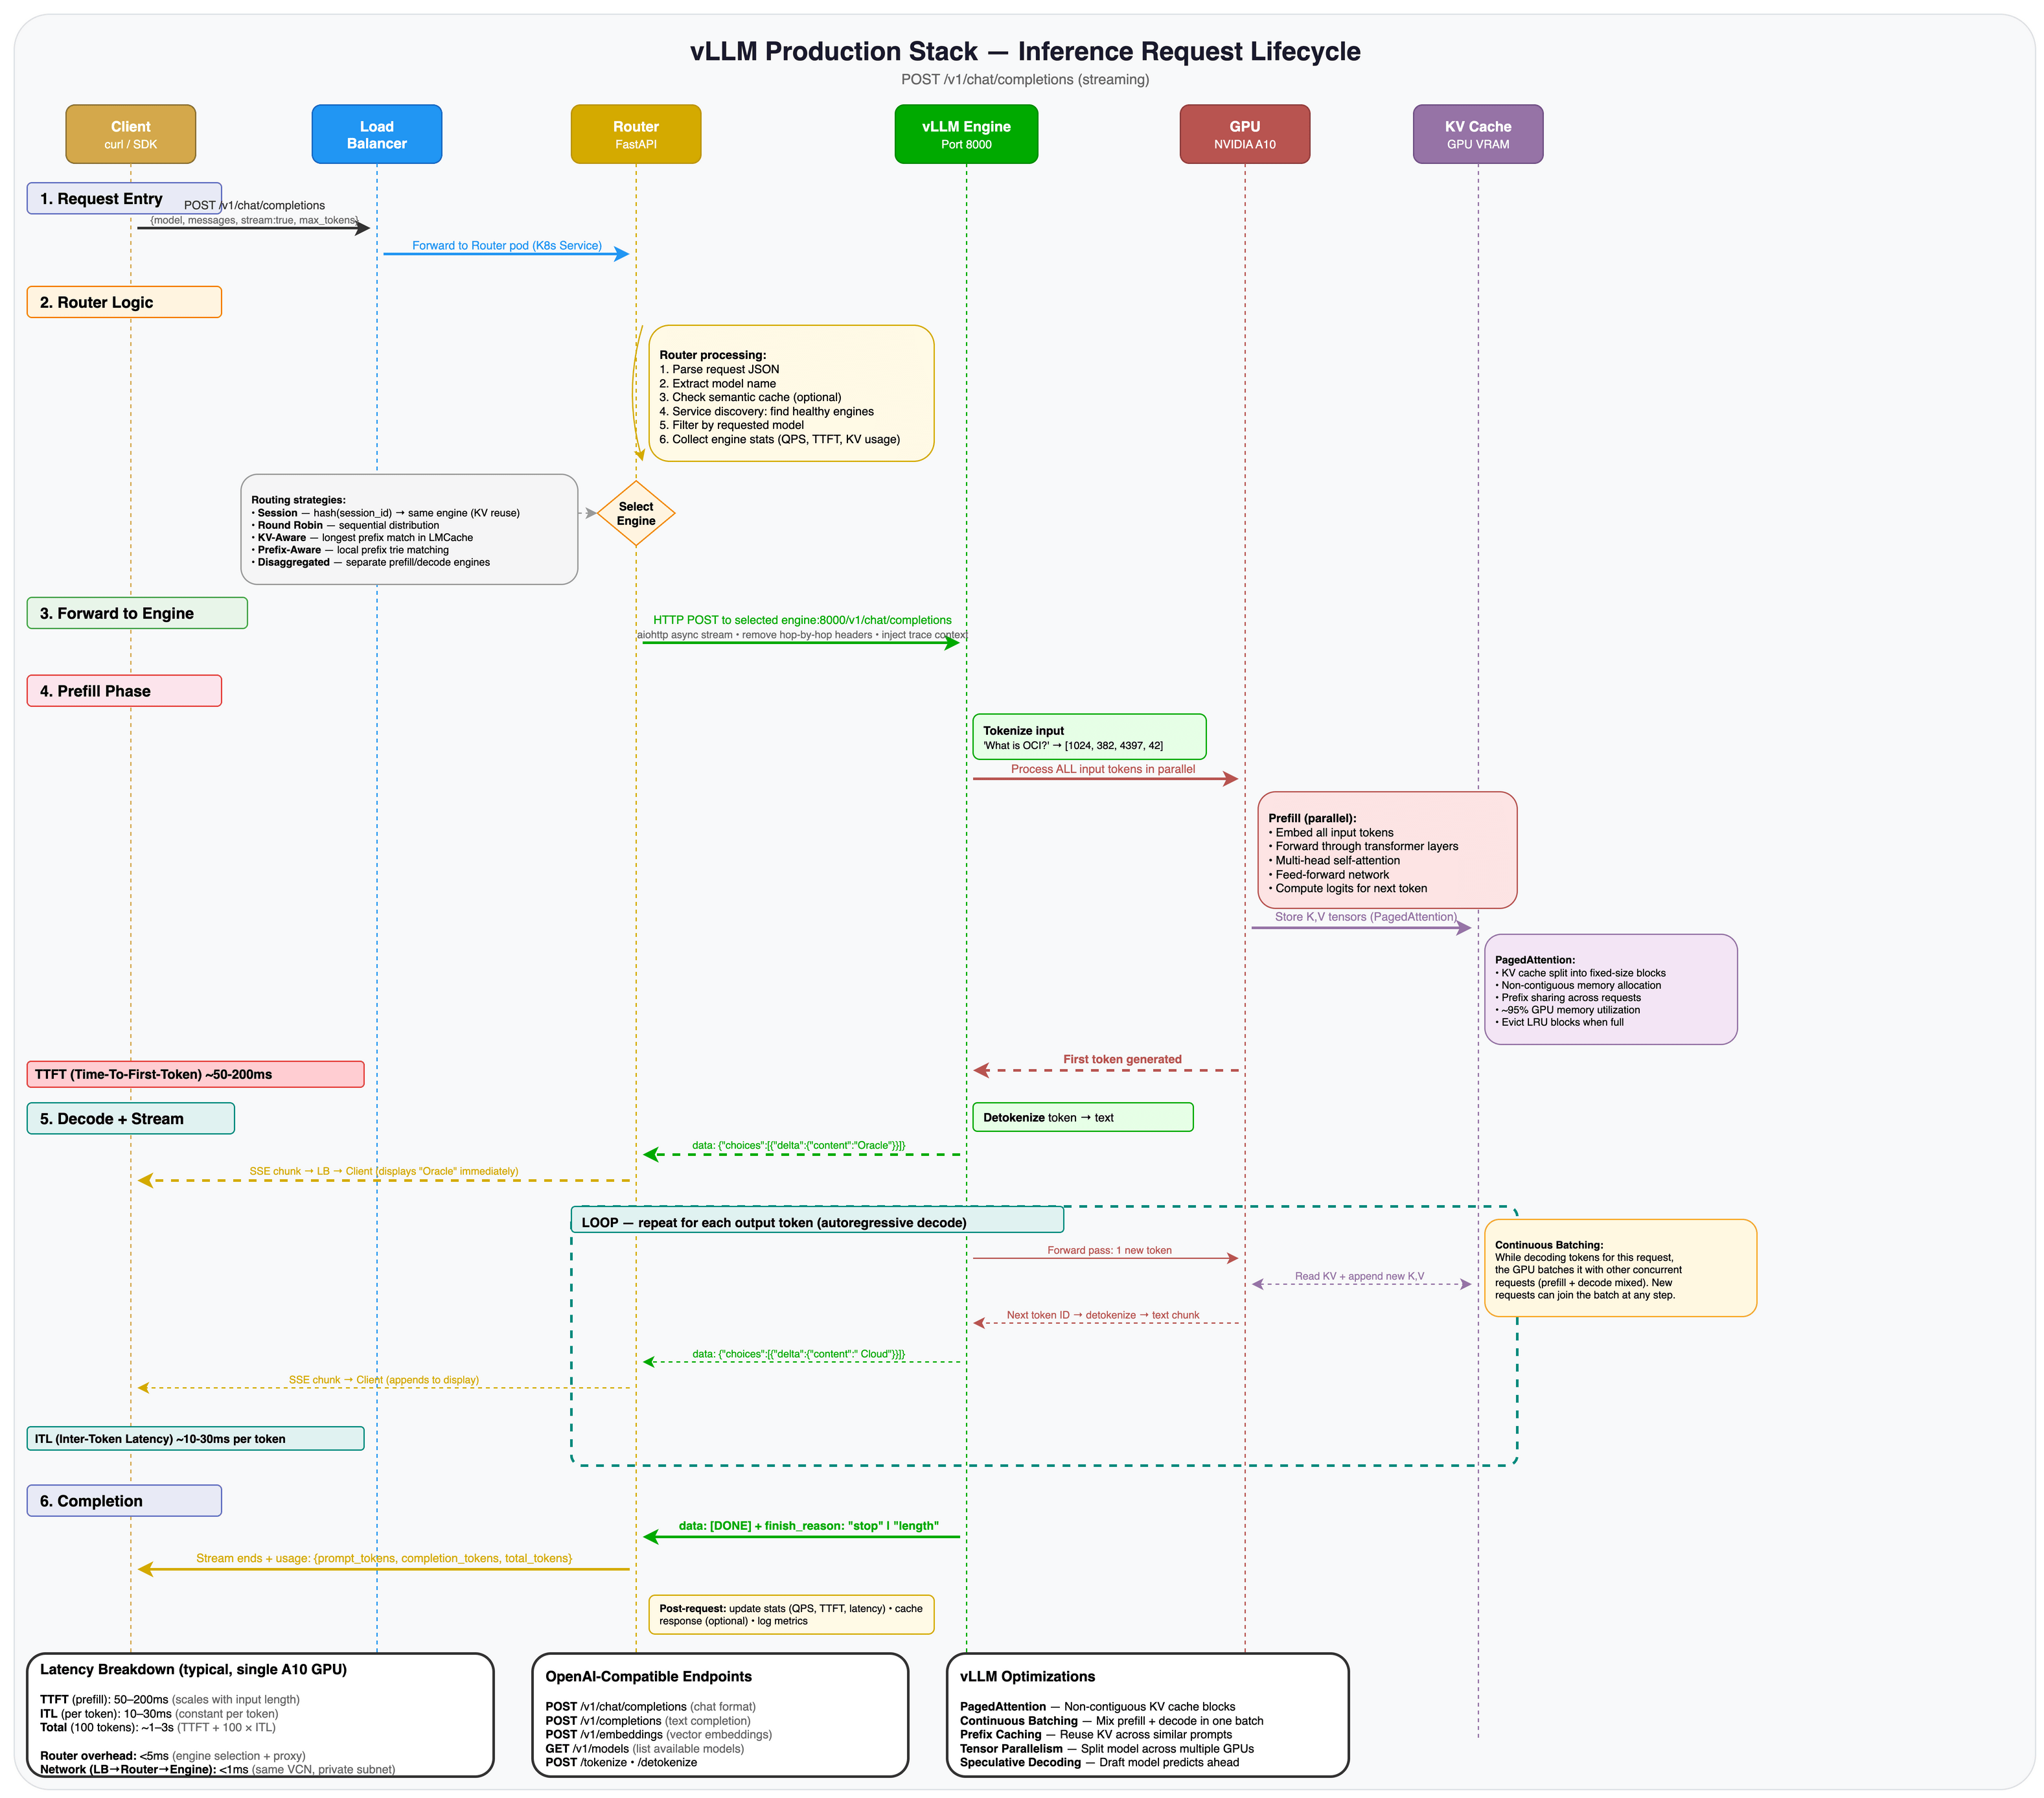
Deploy OpenAI vLLM Production Stack on Oracle Kubernetes Engine (OKE)
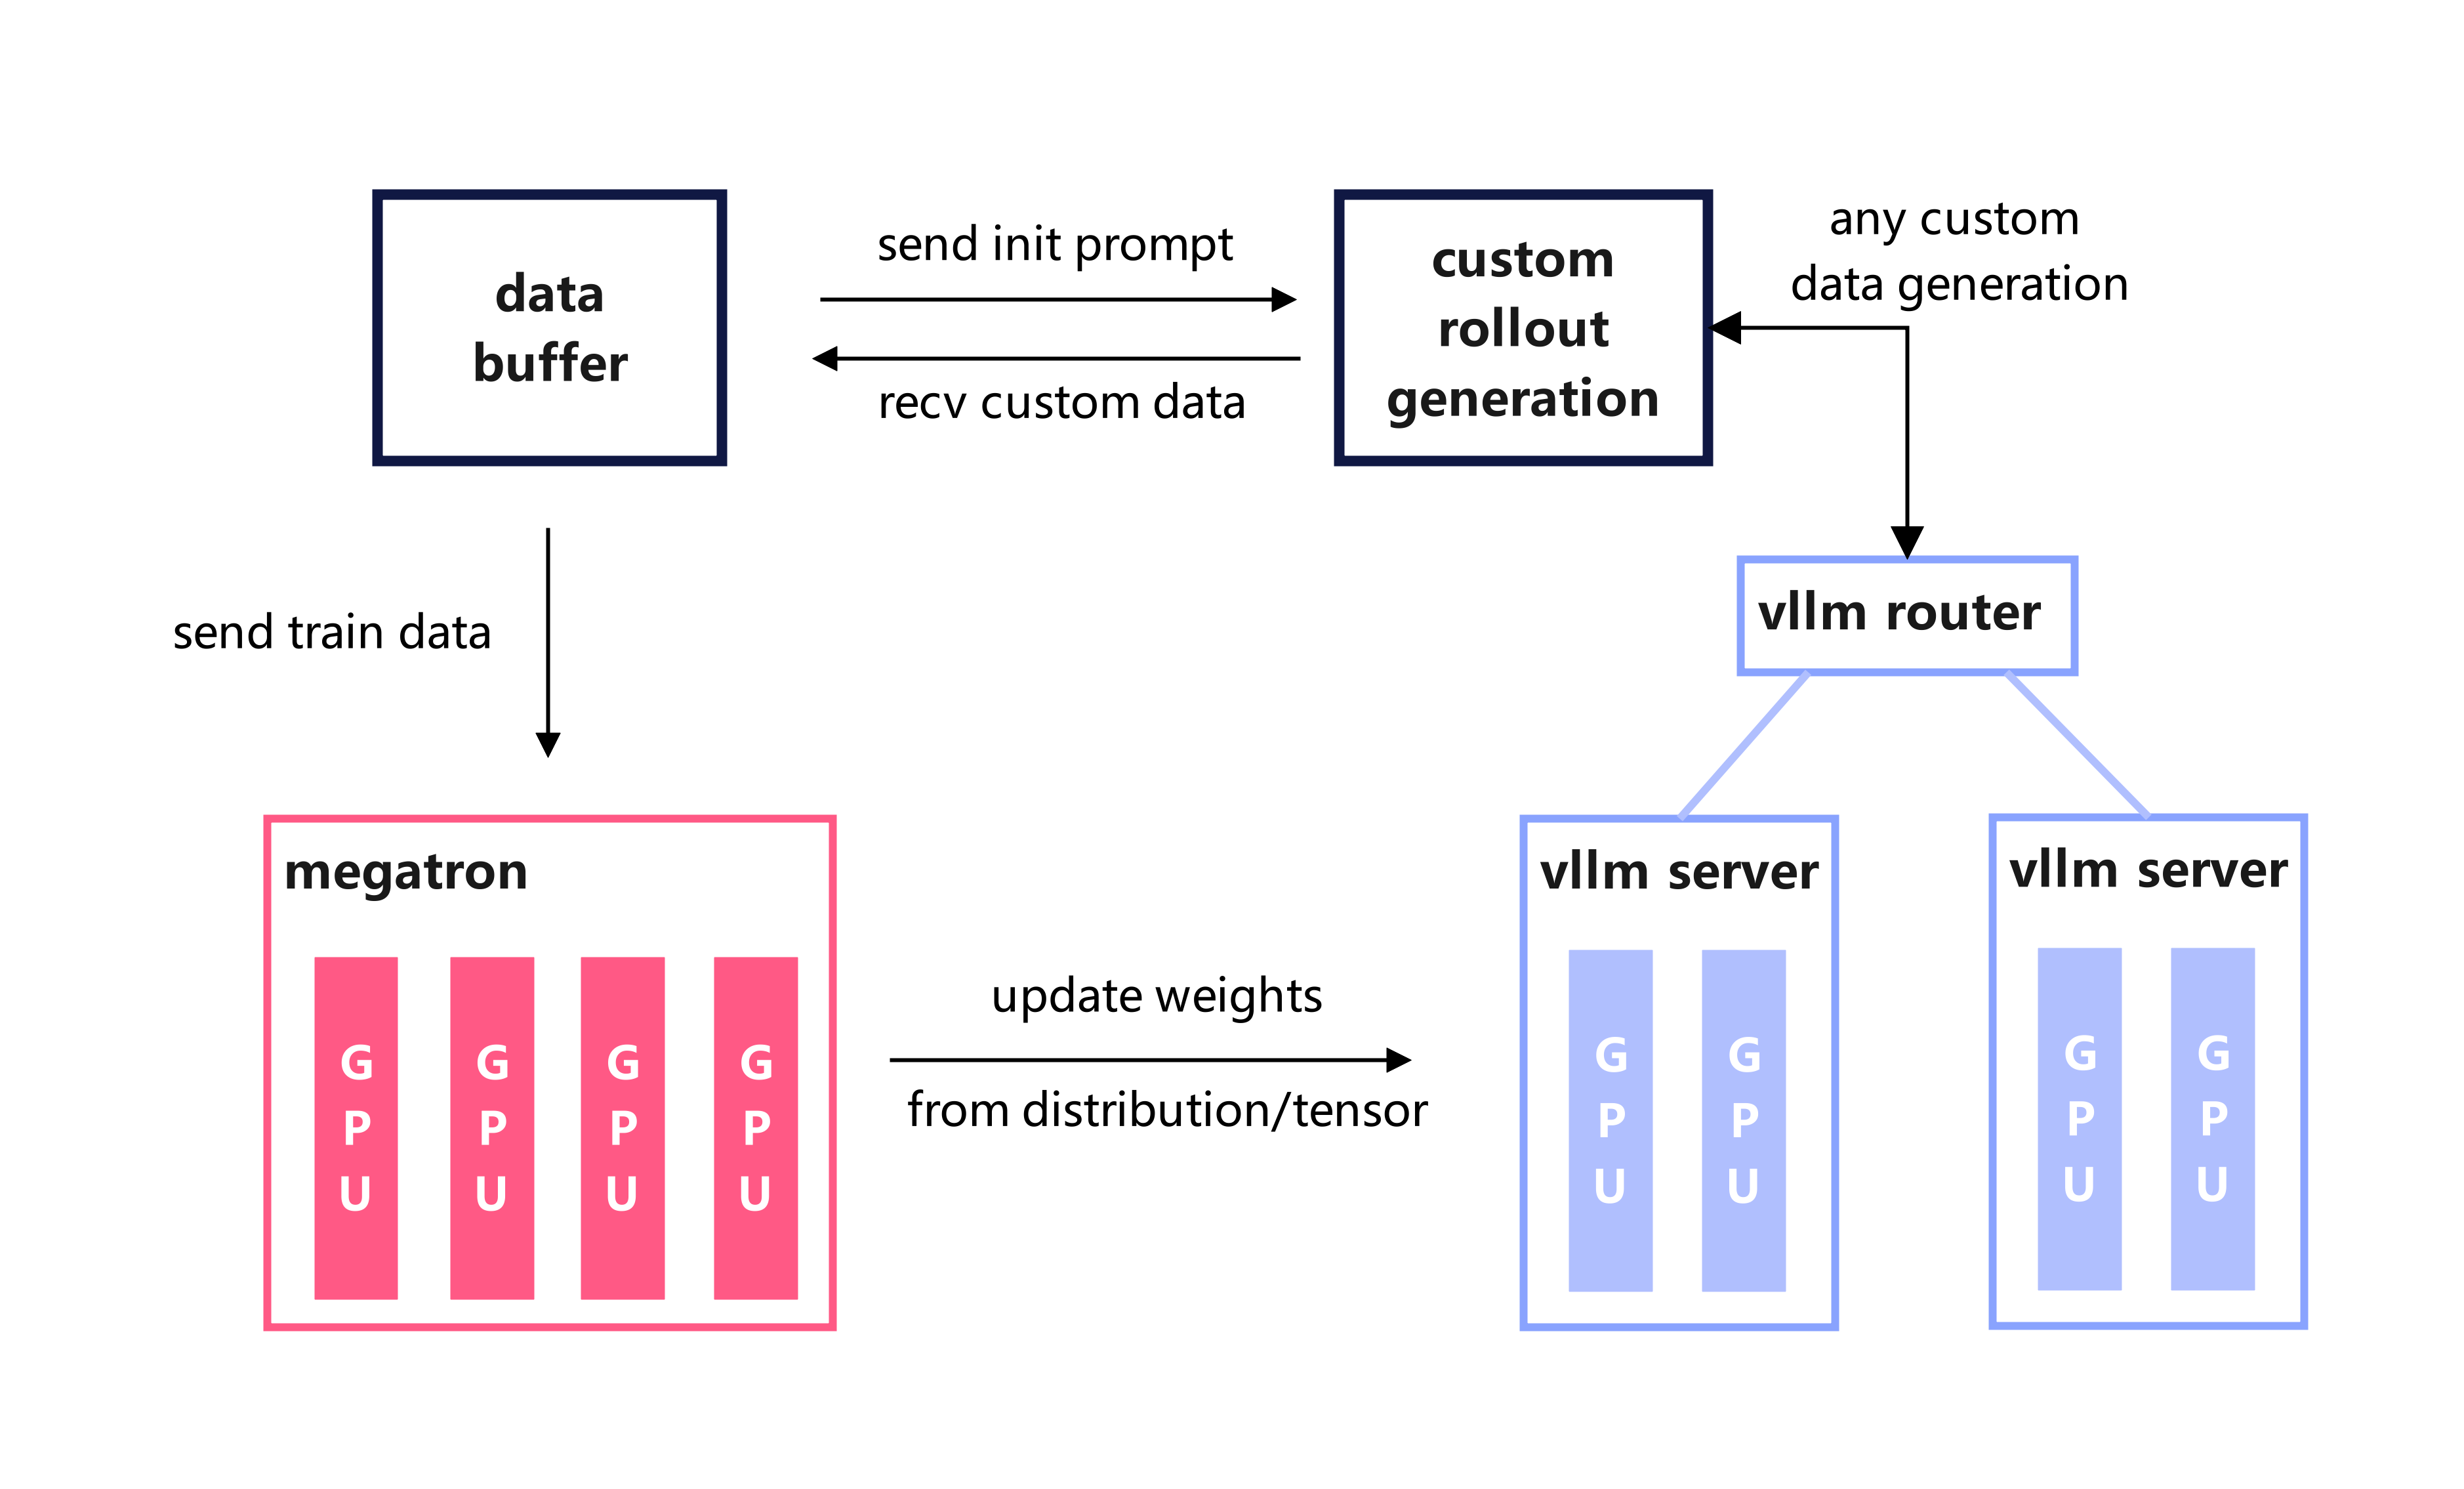
vLLM Config: Advanced Engine Deployment — Vime
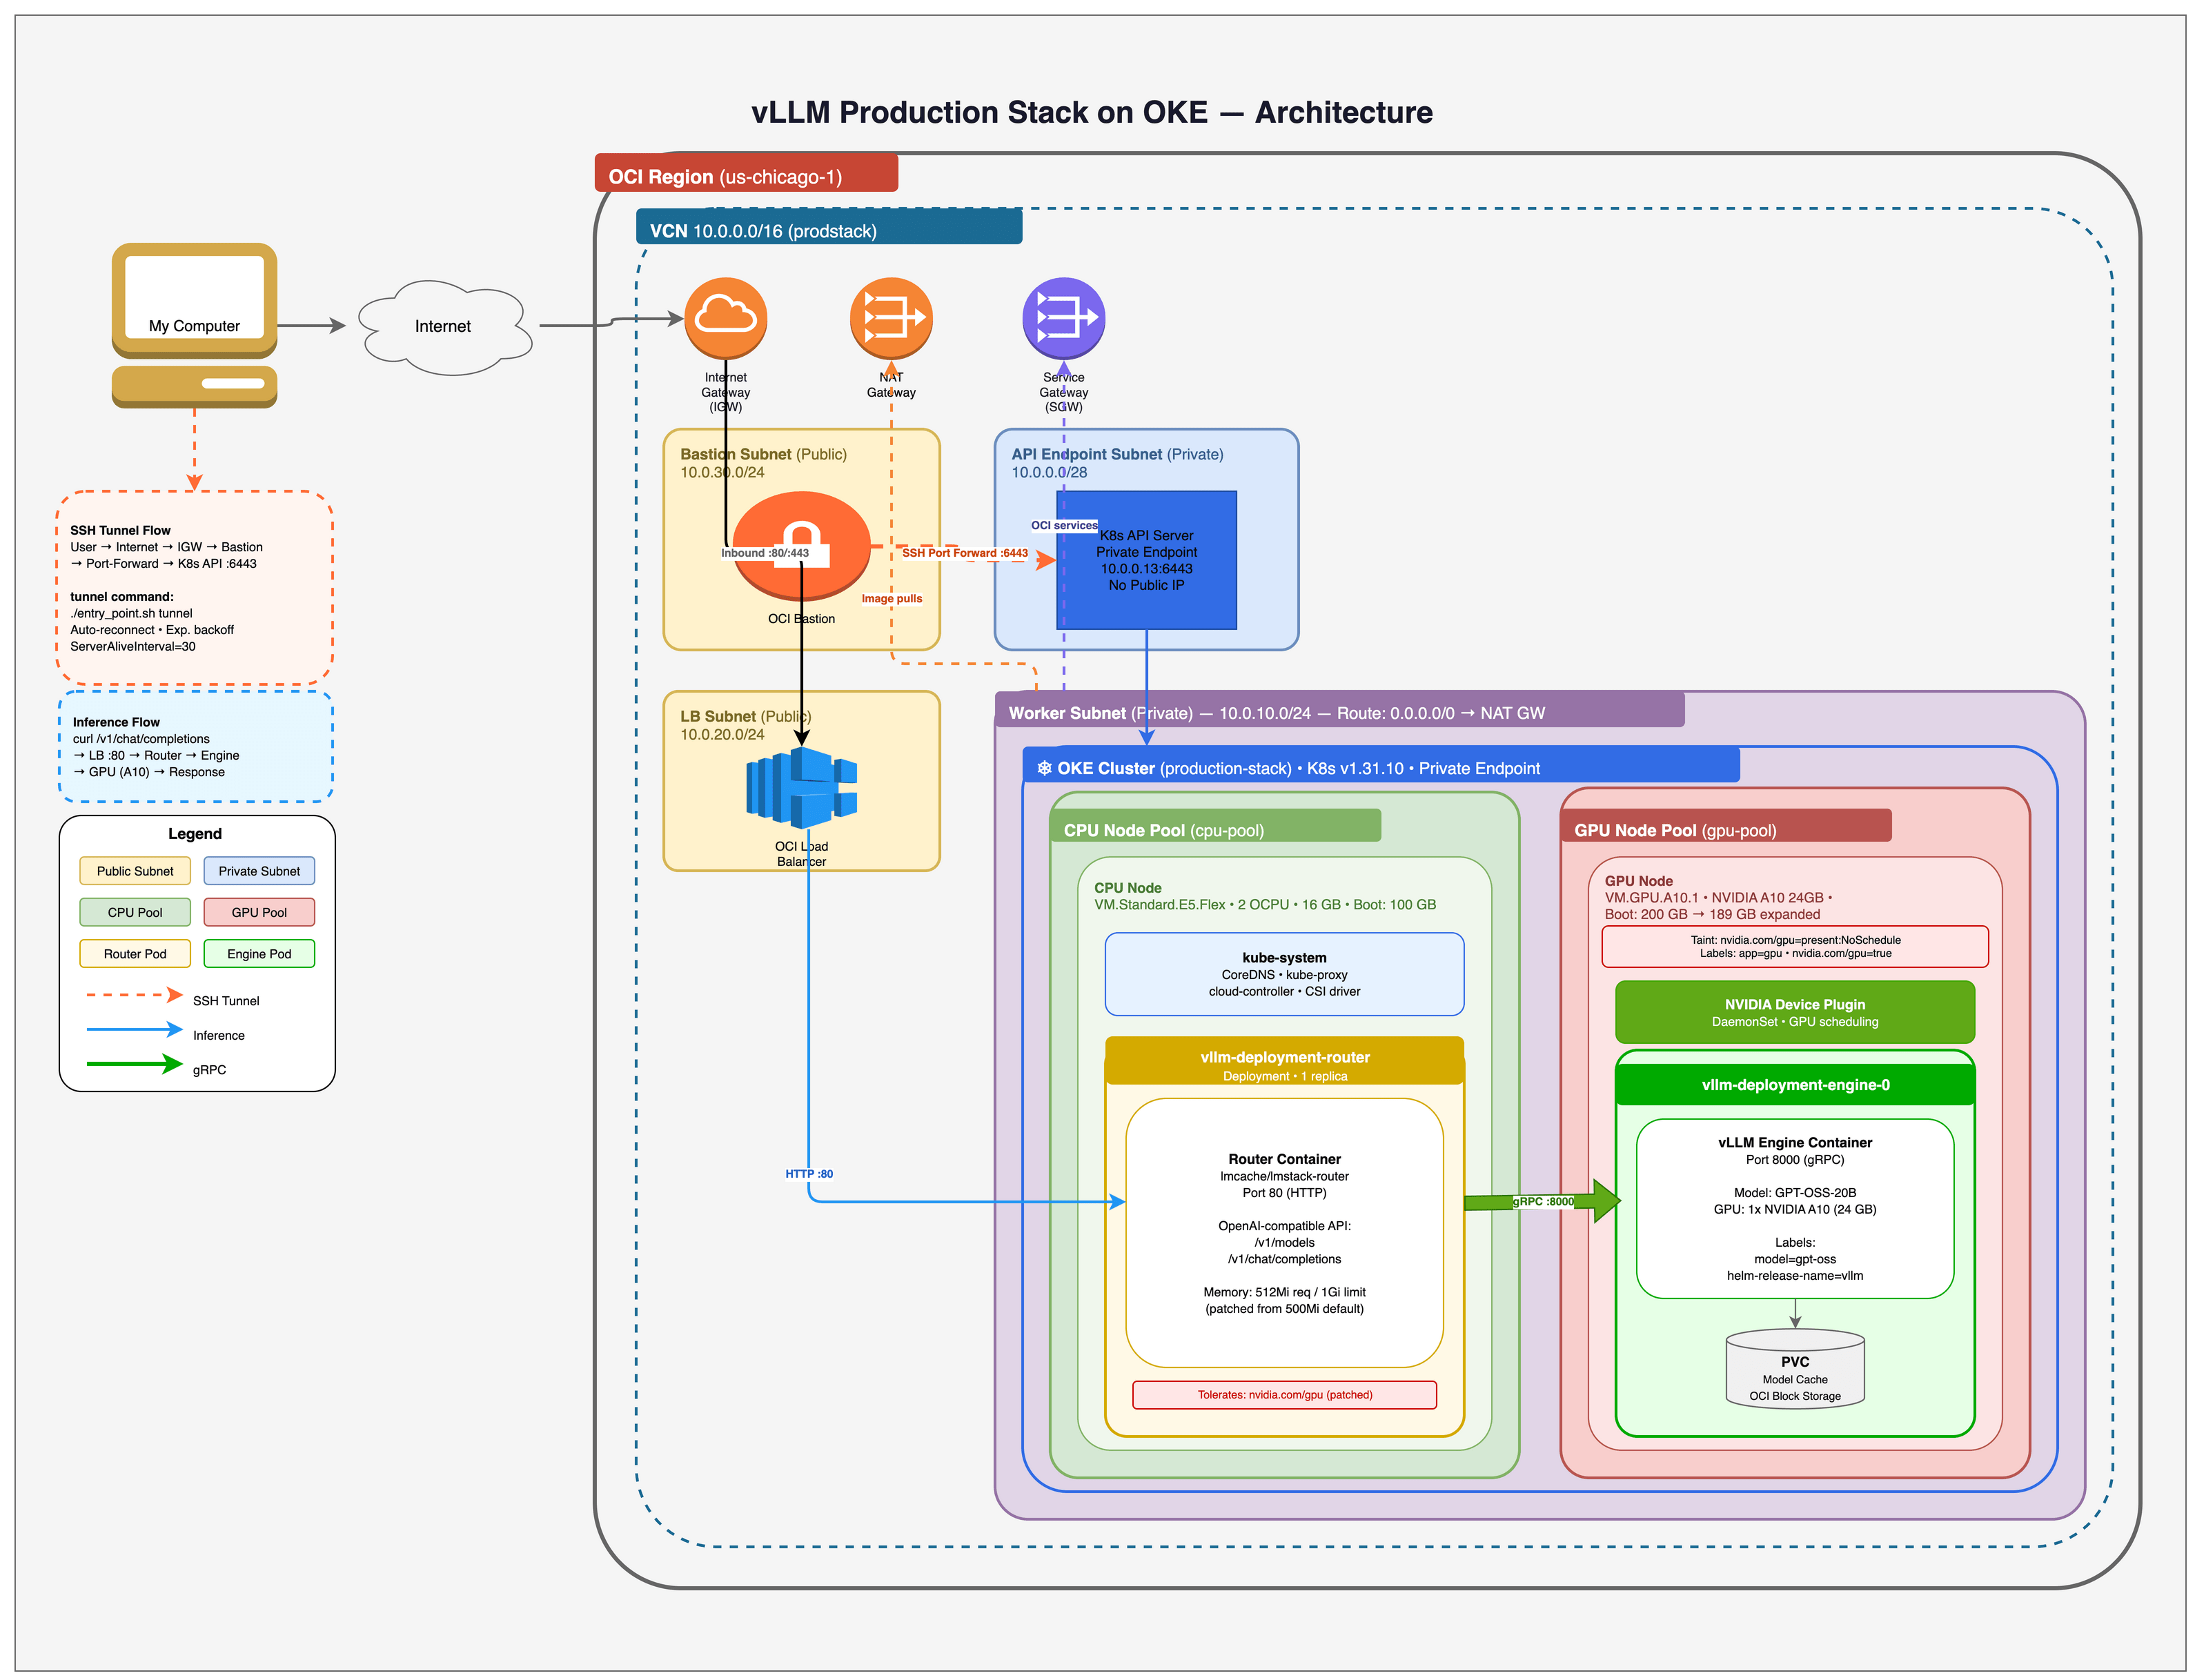
Deploy OpenAI vLLM Production Stack on Oracle Kubernetes Engine (OKE)

Optimizing LLM Throughput with vLLM: Understanding the Engine Behind ...

Free Video: vLLM Inference and LLM Server Engine for Machine Learning ...
Engine Core and Request Lifecycle | npuichigo/vllm | DeepWiki
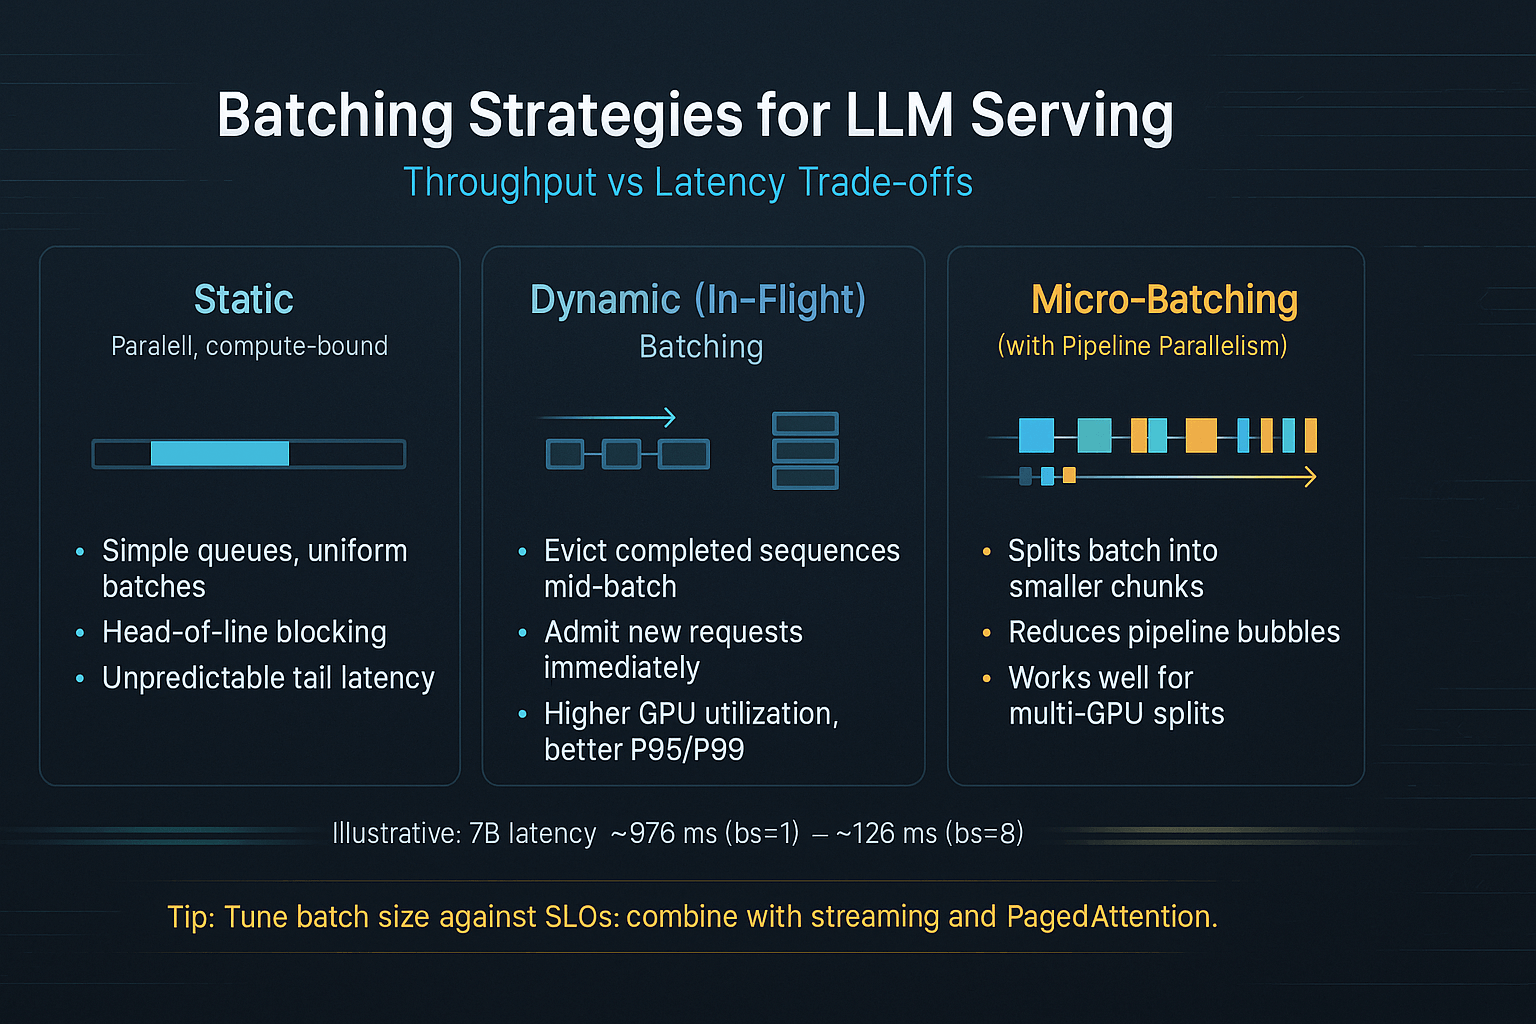
Nano vLLM: A Tiny Inference Engine that Teaches you the Big Ideas ...

VLM Pipeline with Docling - DEV Community
Advertisement Space (336x280)
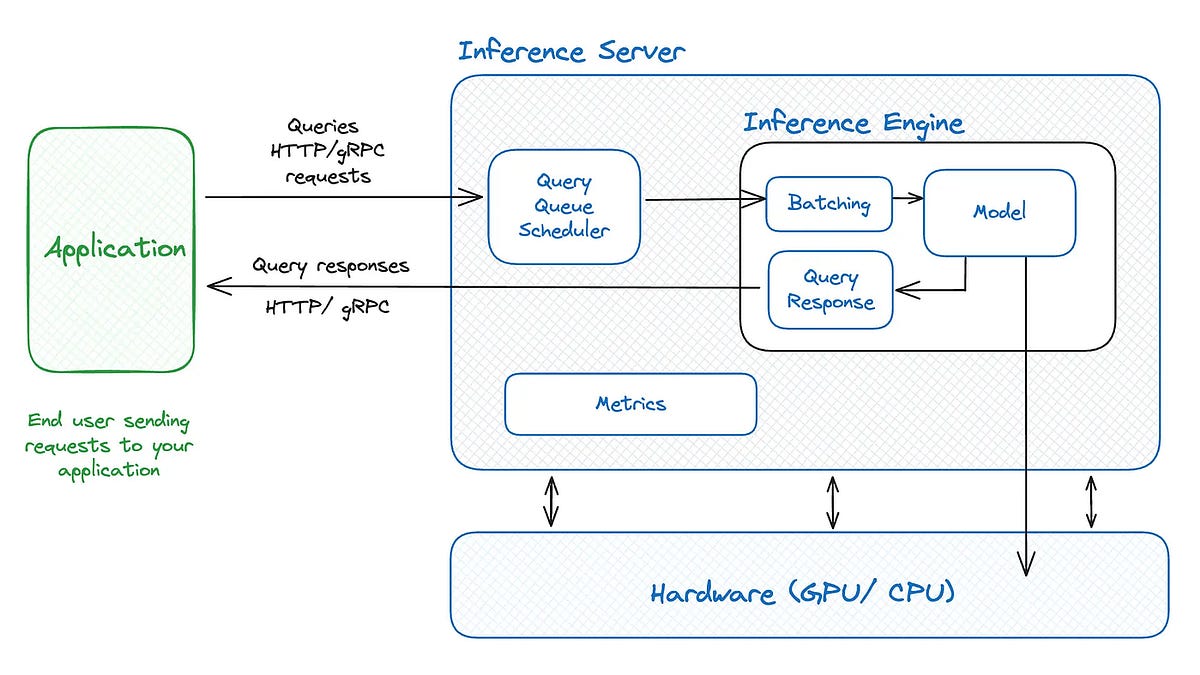
Nano vLLM: A Tiny Inference Engine that Teaches you the Big Ideas ...
vLLM Review: High-Performance LLM Inference Engine for GPU ...
Building Clean, Maintainable vLLM Modifications Using the Plugin System ...

vLLM Inference Engine Boosts AI App Performance | SwathiLakshmi B ...

Want to deploy open models using vLLM as the inference engine? We just ...

Beyond the Model: How vLLM Powers Enterprise-Scale LLM Serving | by ...
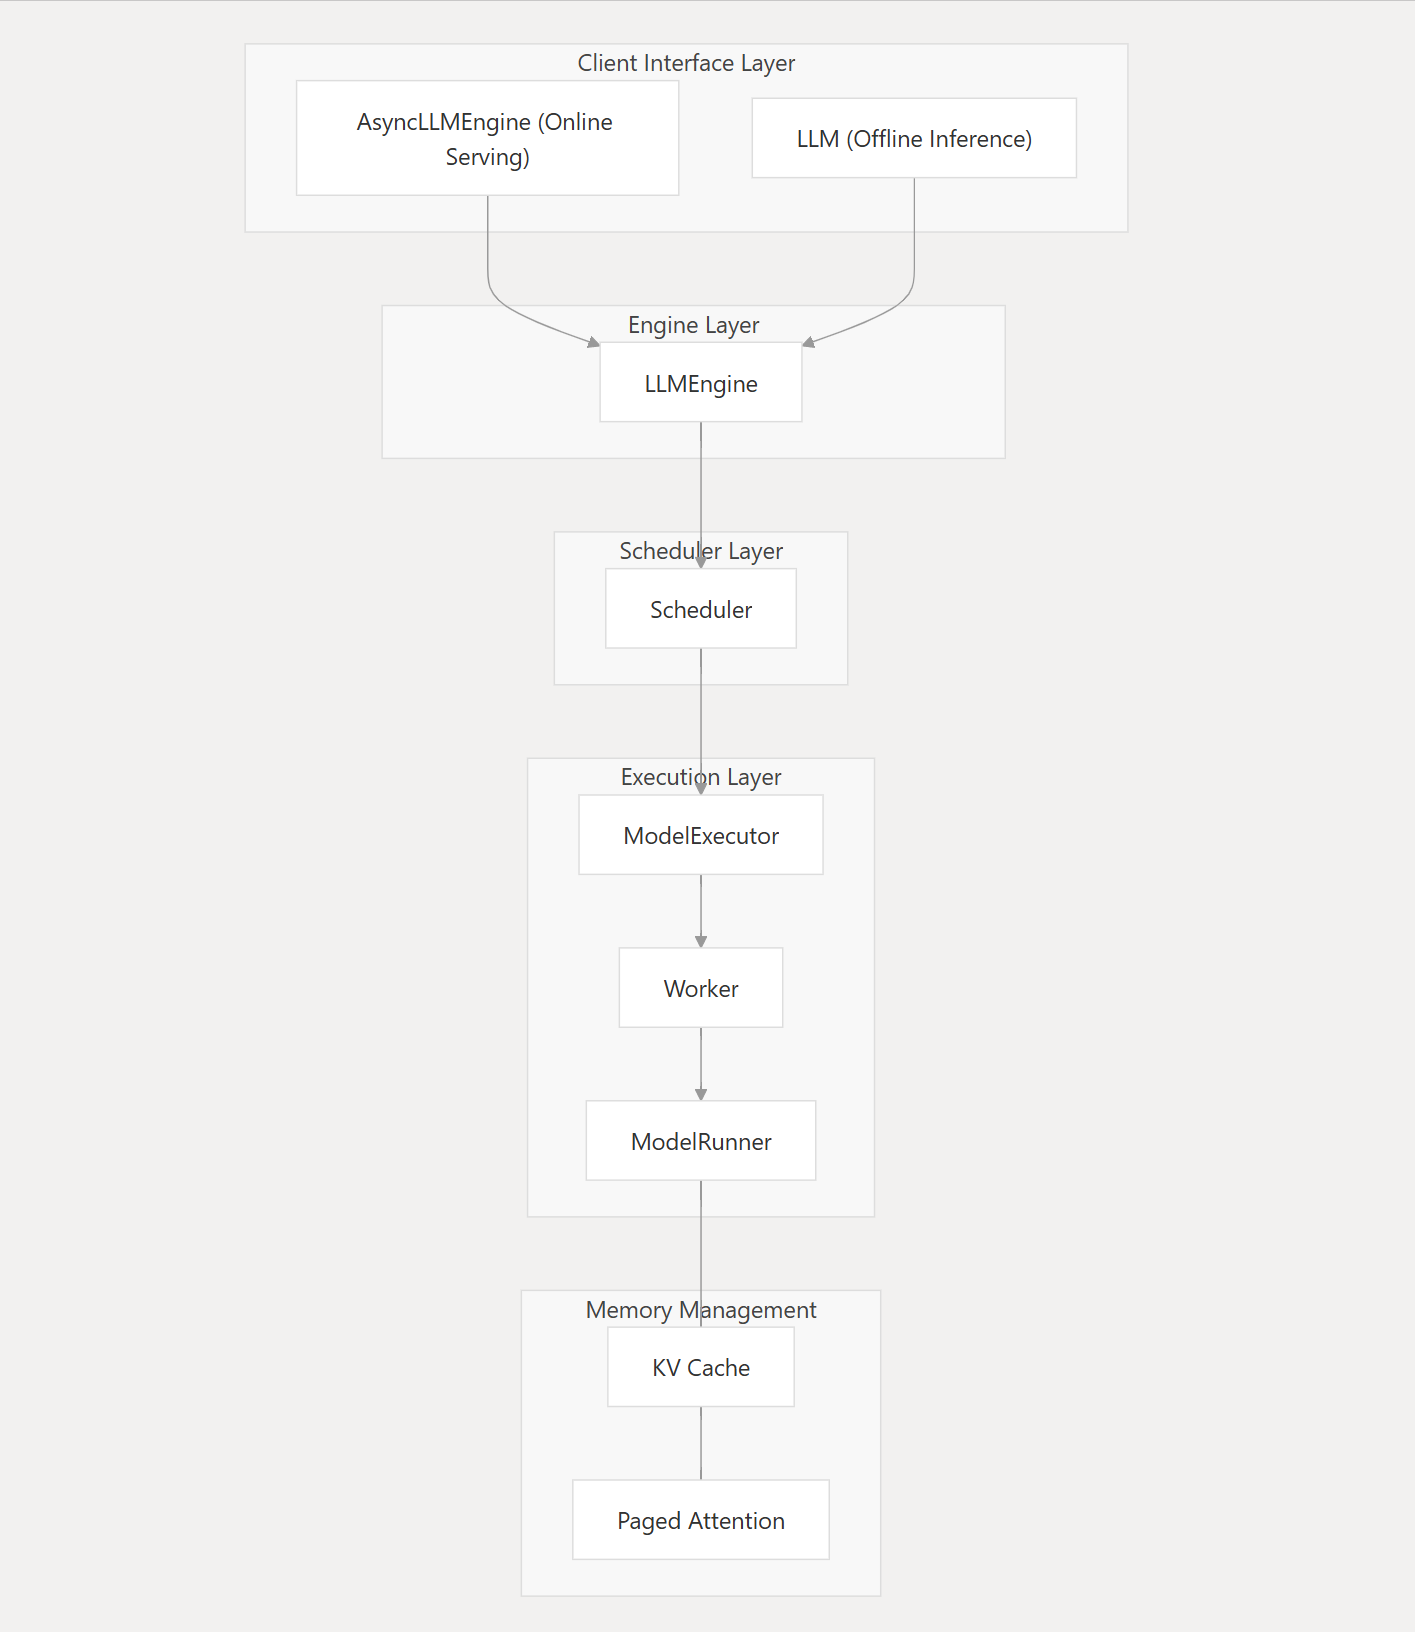
vLLM for beginners: The Fundamentals - Cloudthrill

⚡️ What’s vLLM and why should you care? It’s a turbo engine for ...
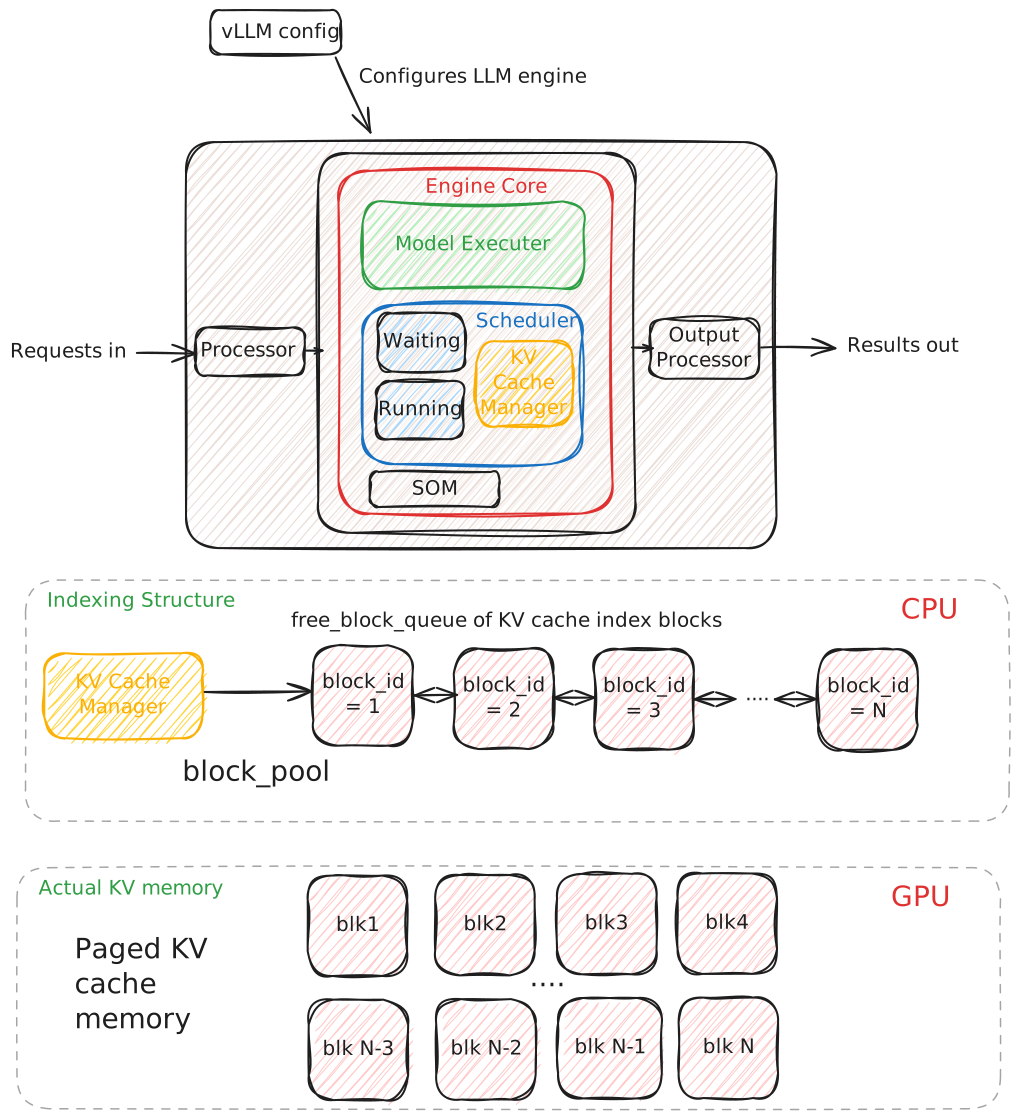
Paged Attention from First Principles: A View Inside vLLM | Hamza's Blog

vLLM V1 | OpenLM.ai
Advertisement Space (336x280)
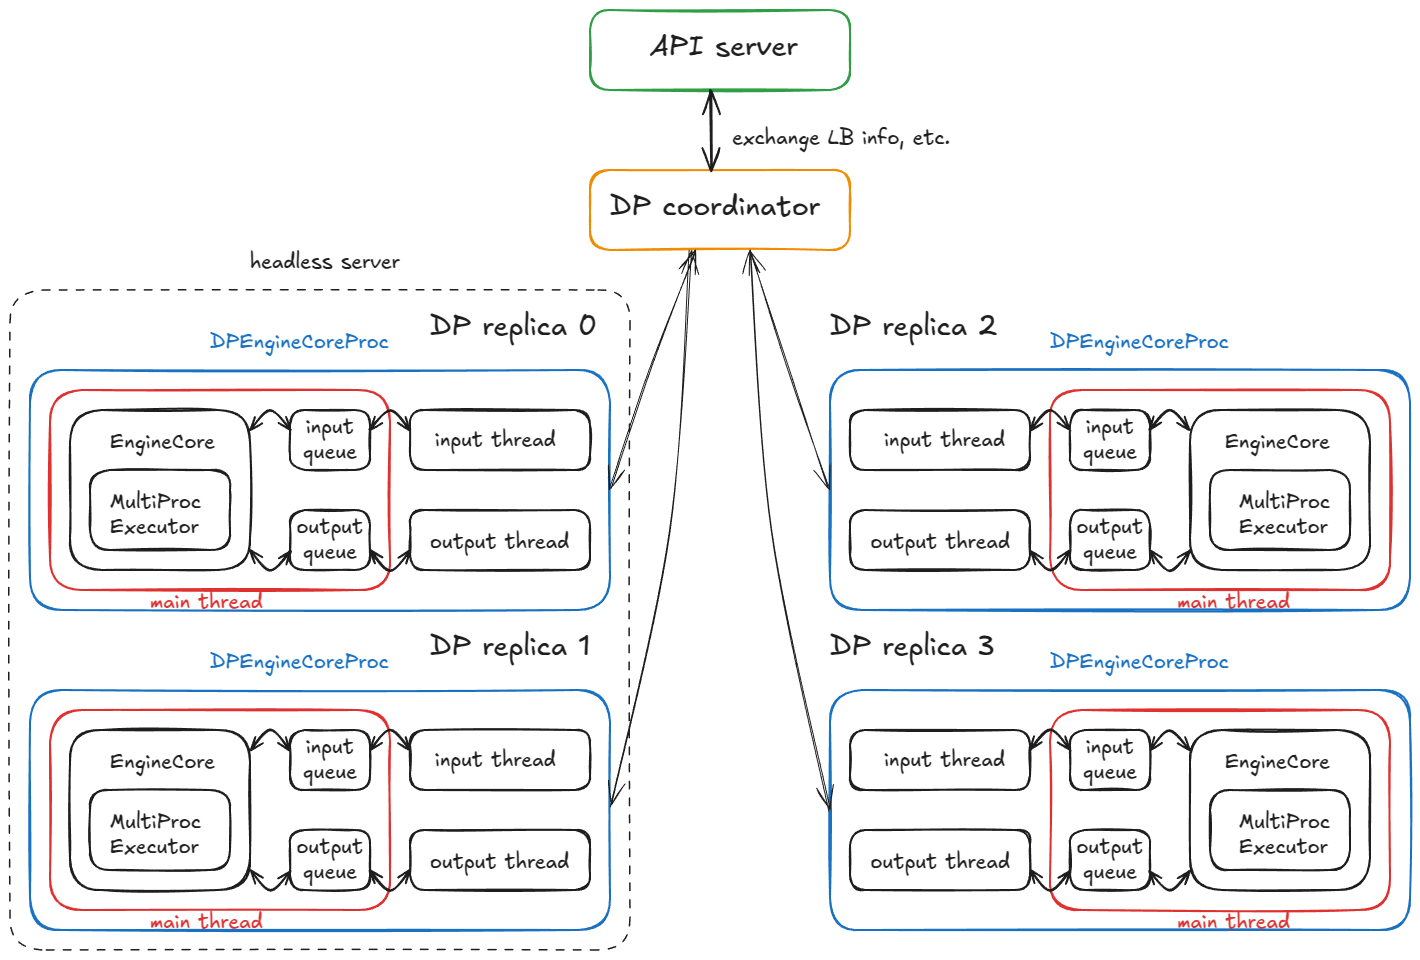
Inside vLLM: Anatomy of a High-Throughput LLM Inference System | vLLM Blog
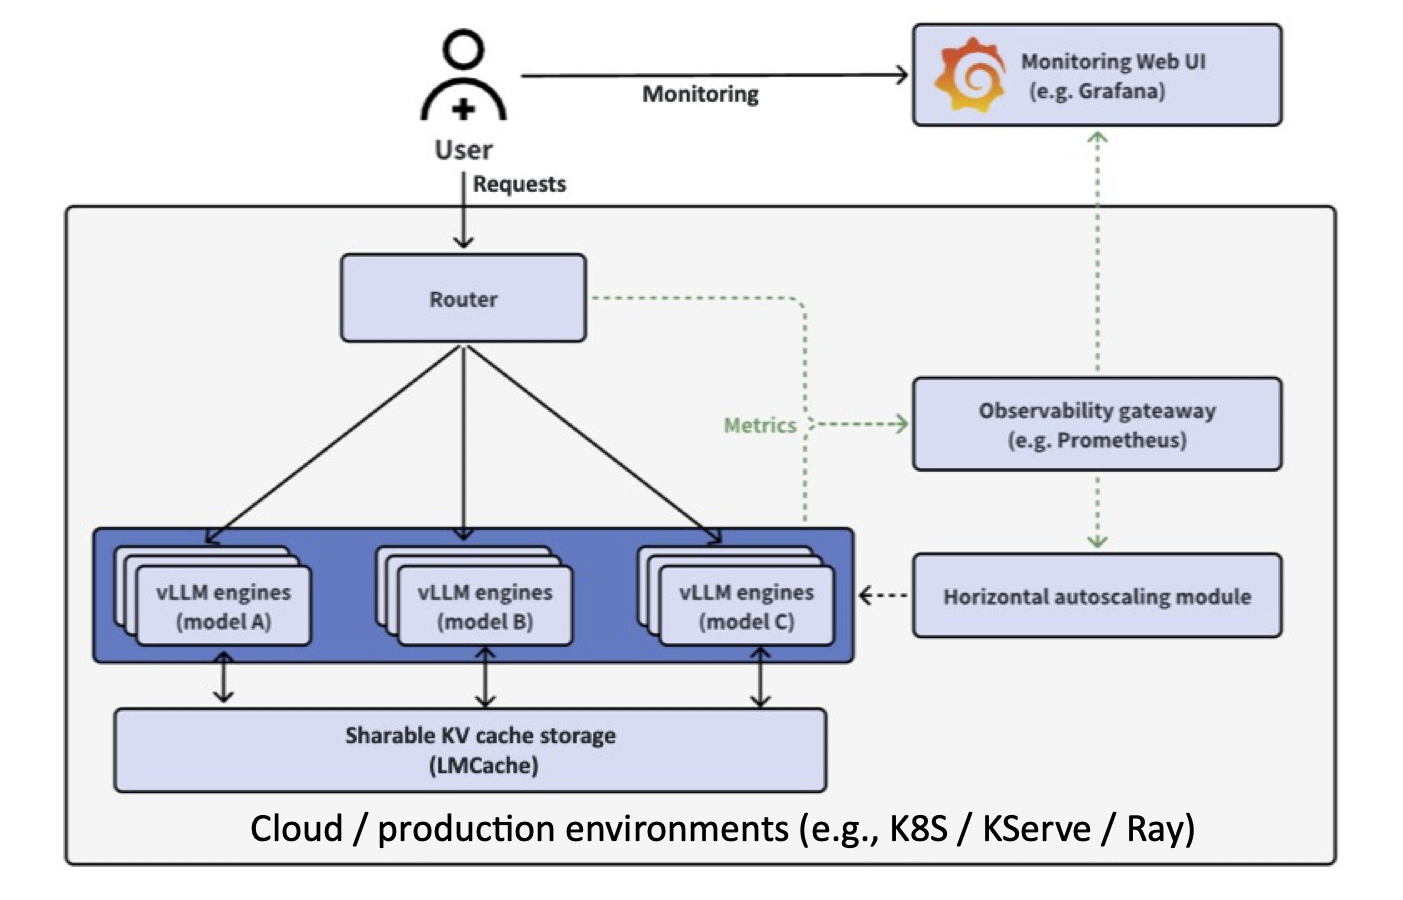
High Performance and Easy Deployment of vLLM in K8S with “vLLM ...
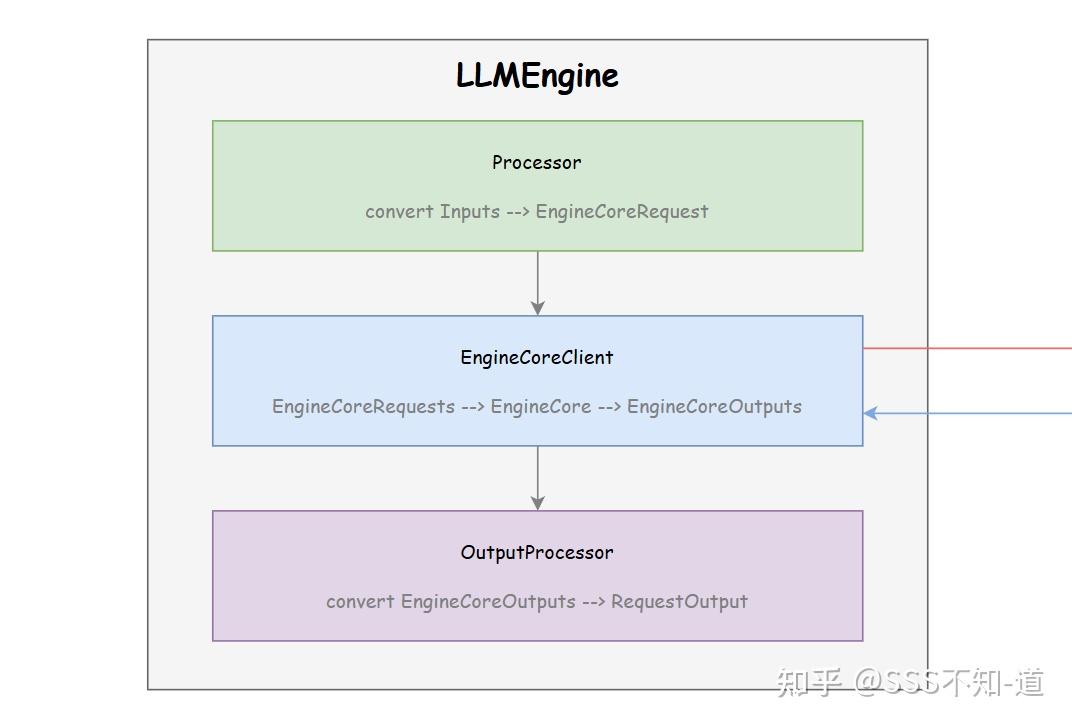
vLLM 结构化输出|Guided Decoding (V1) - 知乎

vLLM: Open-Source LLM Inference Engine for Multi-Tenant Serving ...
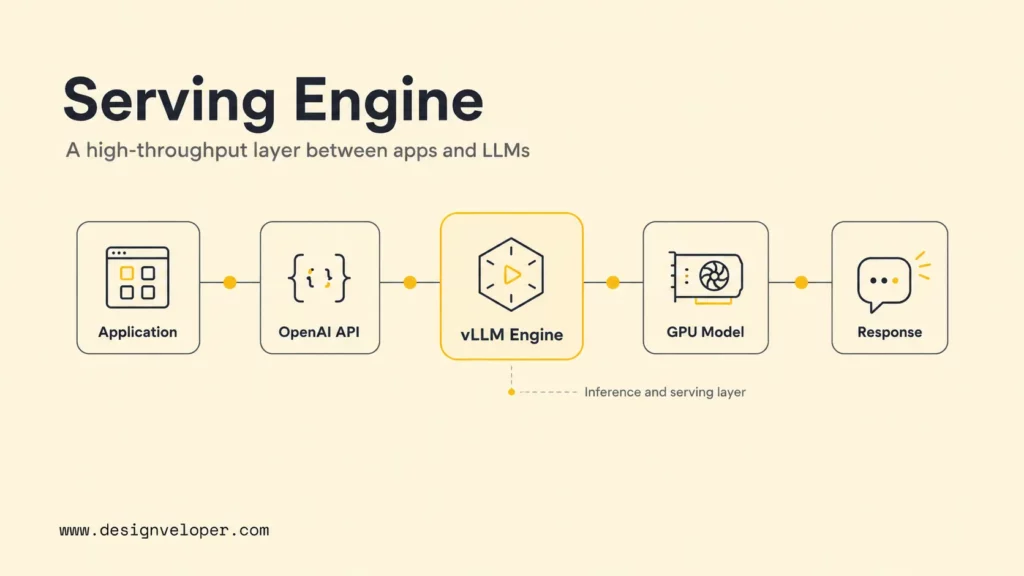
vLLM Tutorial: A Step-By-Step Guide To Deploying And Serving LLMs ...
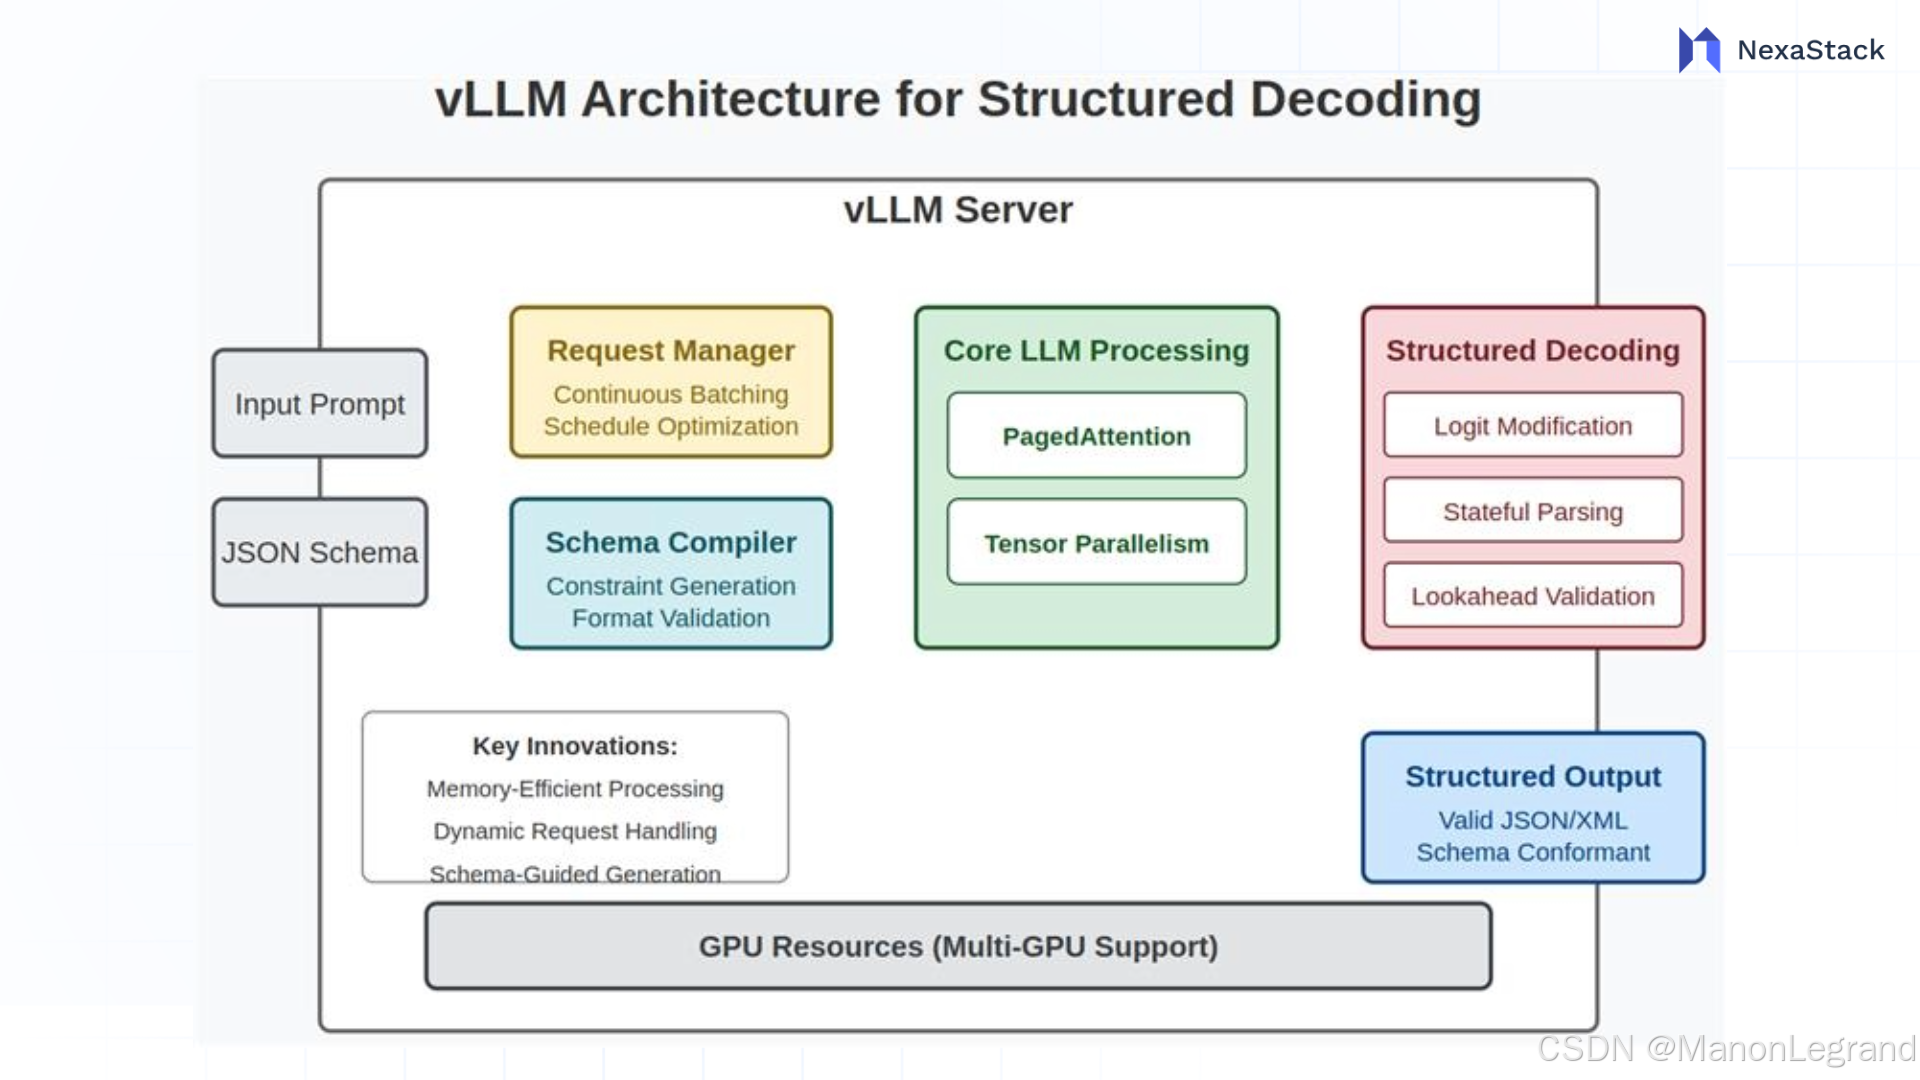
LLM - 使用 vLLM 部署 Qwen2.5-VL-32B 模型 (4卡x4090-49G) (3)_qwen2.5-vl 怎么vllm ...