
Vllms Continuous Batching And Memory Management Drive Performance
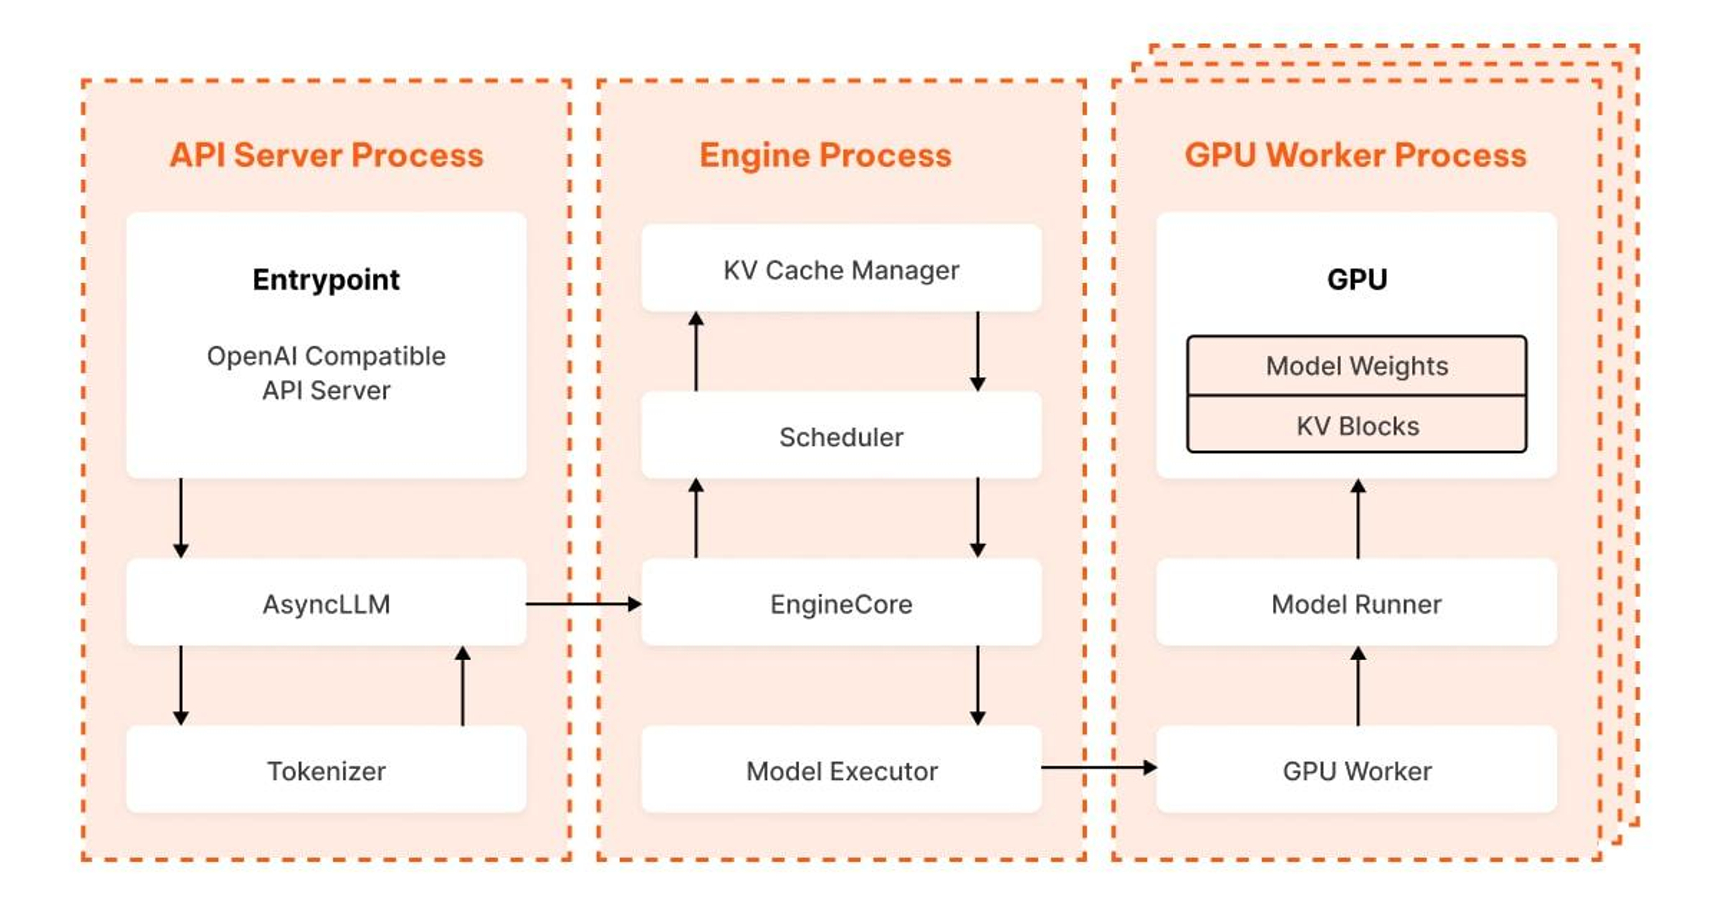
vLLM's Continuous Batching and Memory Management Drive Performance ...

vLLM's Continuous Batching and Memory Management Drive Performance ...

vLLM's Continuous Batching and Memory Management Drive Performance ...

Memory Management and Scheduling in the vLLM Engine | by Priyadarshini ...

How Continuous Batching Boosts LLM Performance with TorchWeave | Sri ...
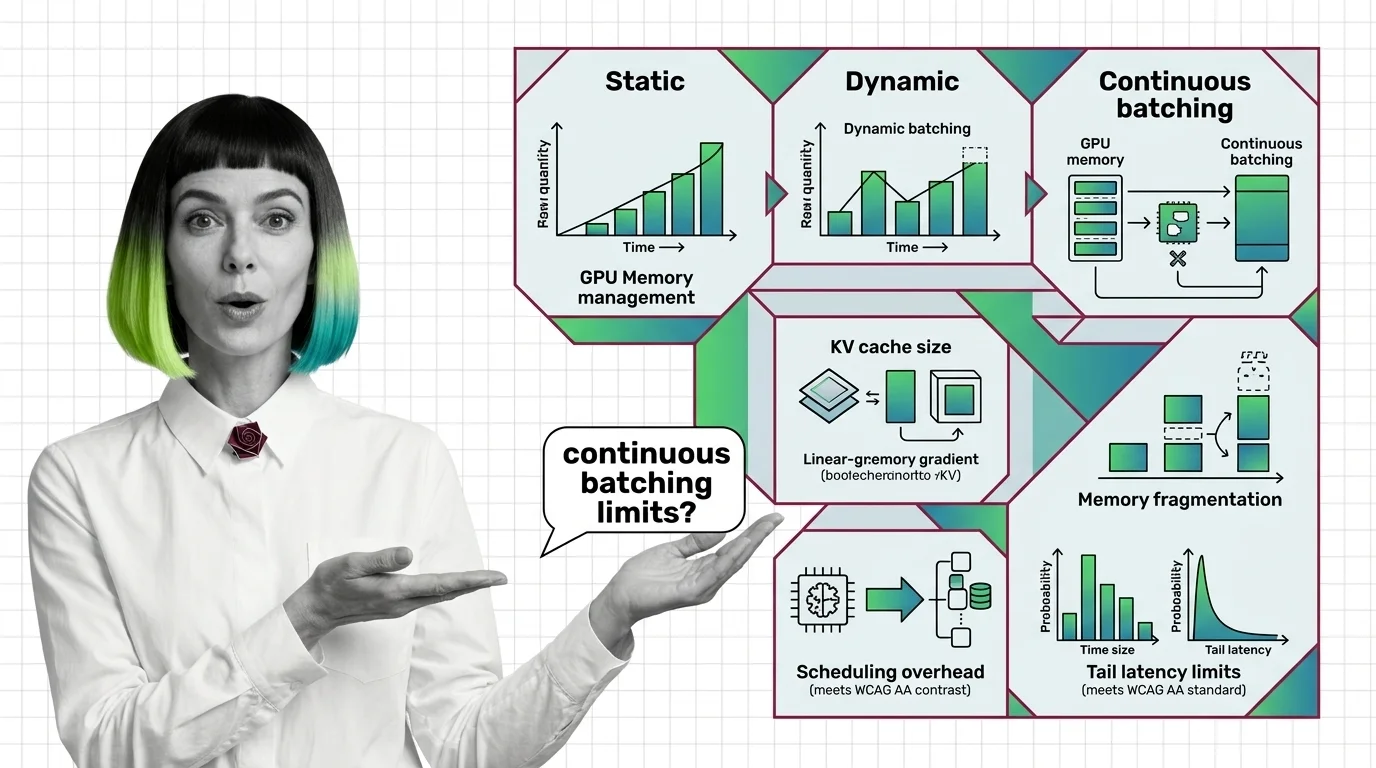
What Is Continuous Batching and How Iteration-Level Scheduling ...
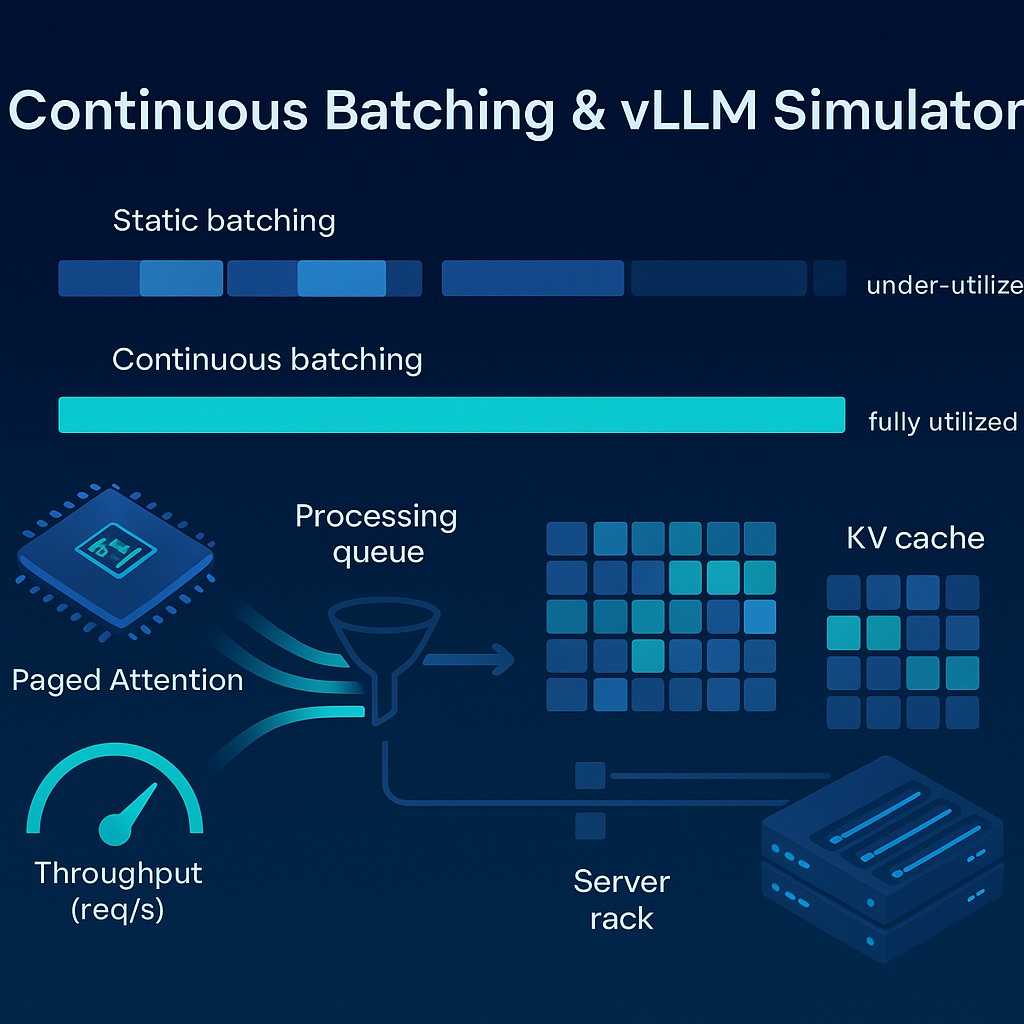
Free Continuous Batching & vLLM Simulator | Simulations4All

How continuous batching enables 23x throughput in LLM inference ...
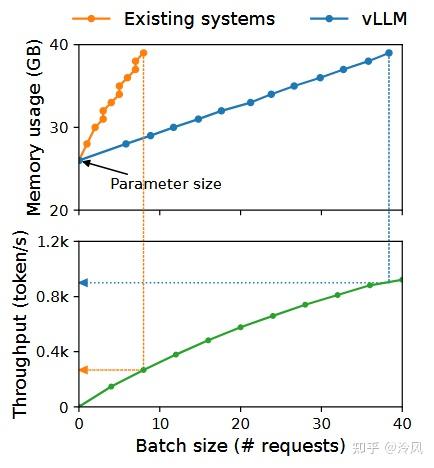
经典论文分享:Efficient Memory Management for Large Language Model Serving ...
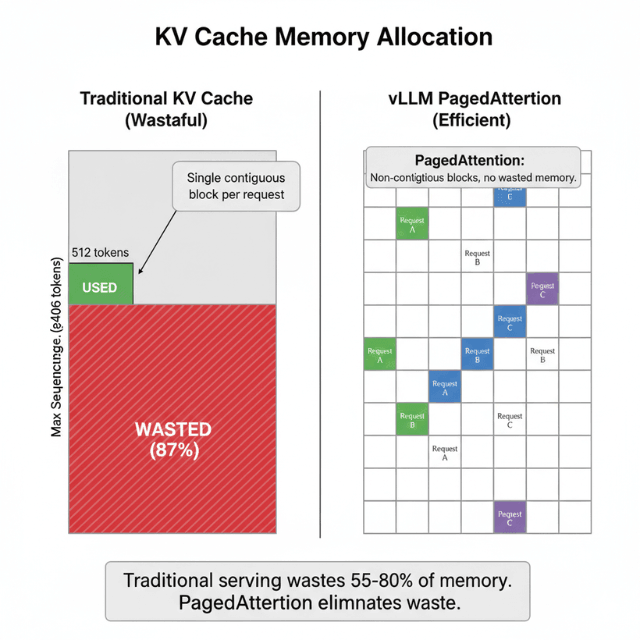
vLLM Throughput Guide - PagedAttention and Batching Tips (2026)
Advertisement Space (300x250)
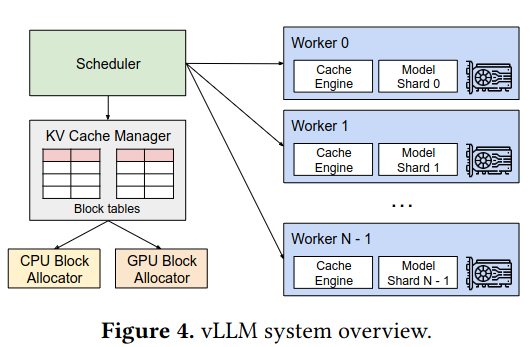
Efficient Memory Management for Large Language Model Serving with ...
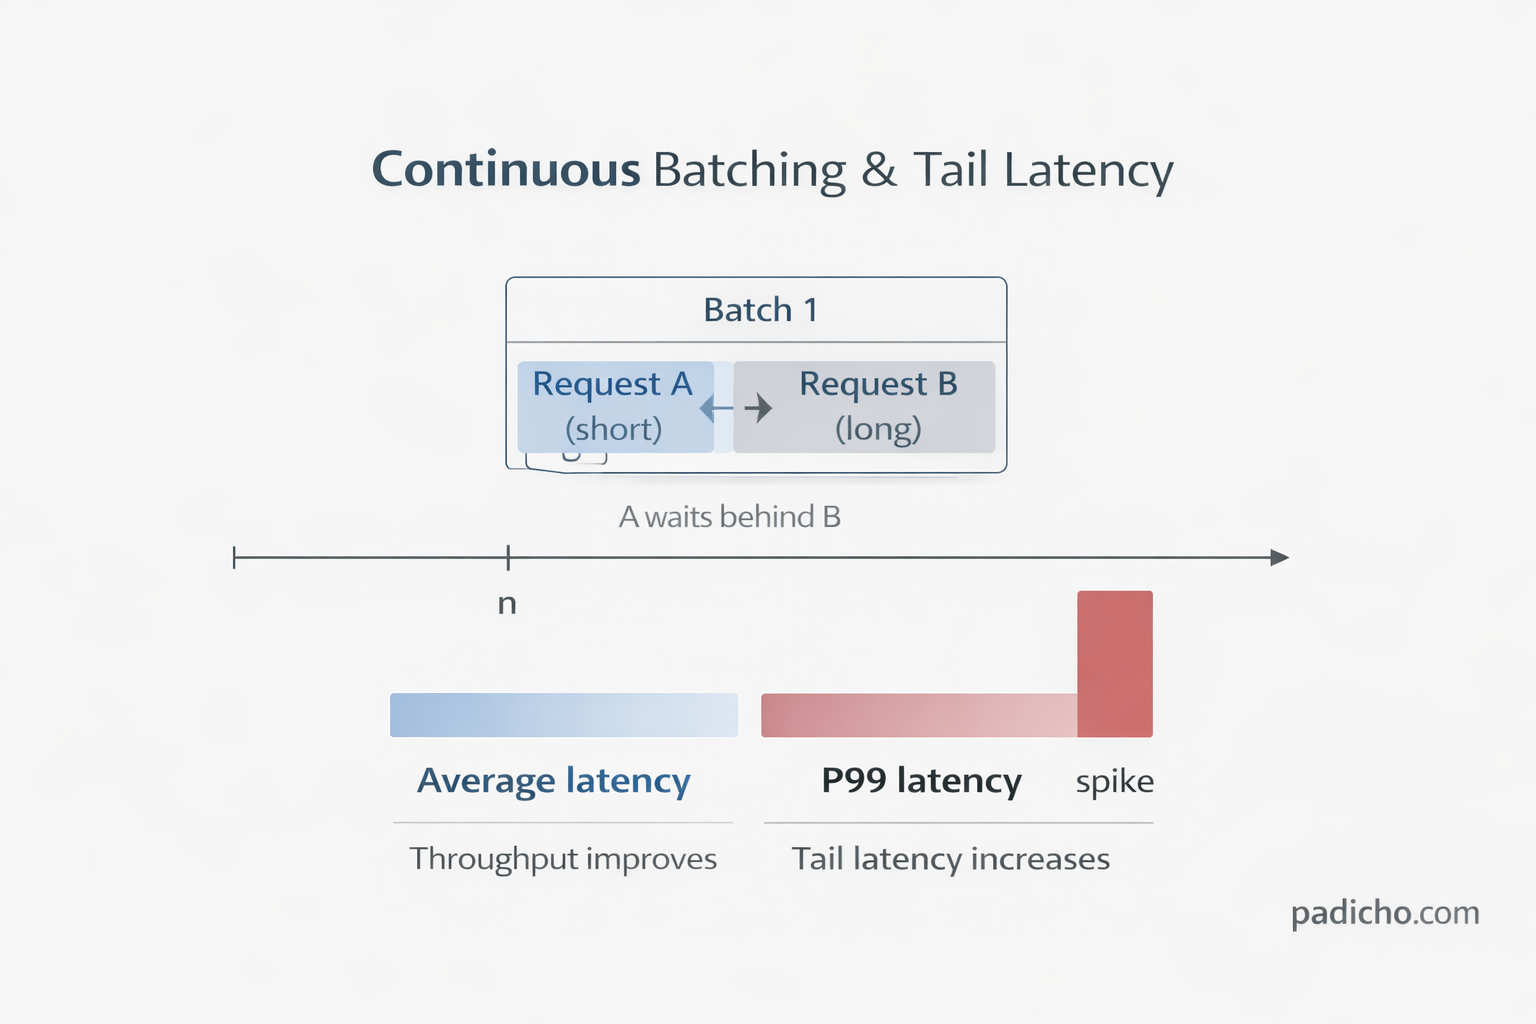
Scaling and Performance in AI Systems — Interview Guide
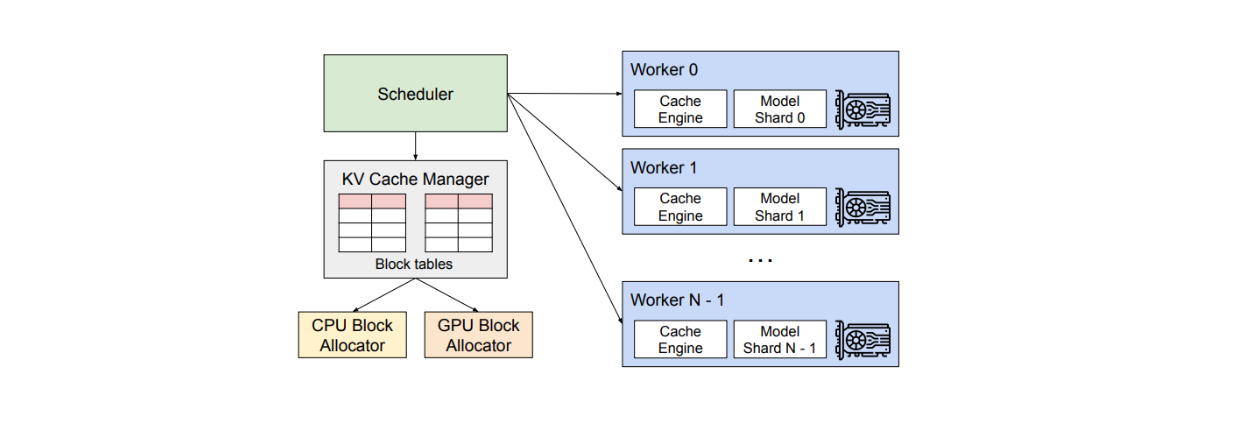
Efficient Memory Management for Large Language Model Serving with ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...
Continuous Batching — Maximizing GPU Utilization for LLM Serving ...

vLLM Fully explained page attention & continuous batching in simple way ...

Nano-vLLM 源码解读 - 7. Continuous Batching - 大模型推理 - 博客园

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...
Advertisement Space (336x280)
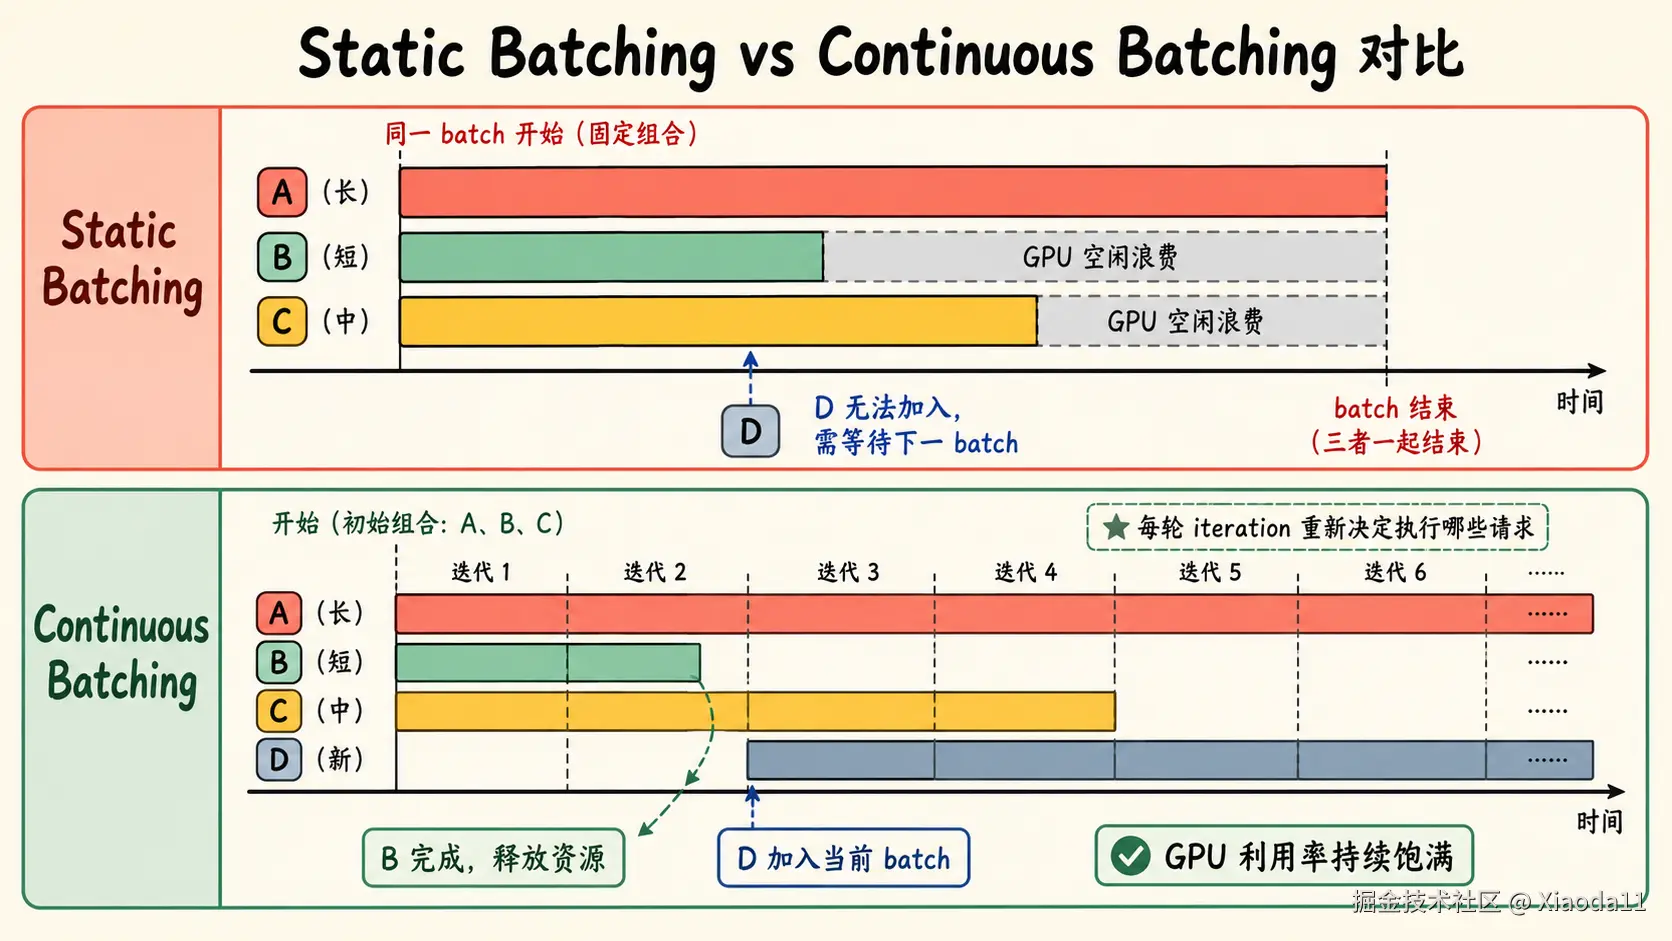
vLLM Scheduler:为什么 Continuous Batching 是 LLM Serving 的核心? - 技术栈
How to Speed up AI Inference with vLLM Continuous Batching - Voice.ai
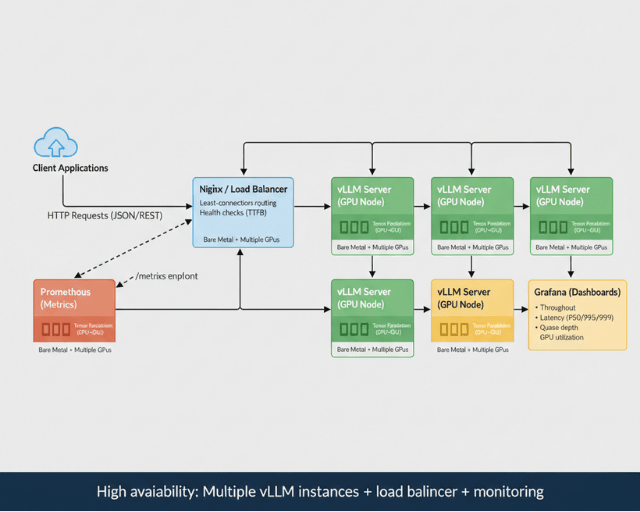
vLLM Throughput Guide - PagedAttention and Batching Tips (2026)
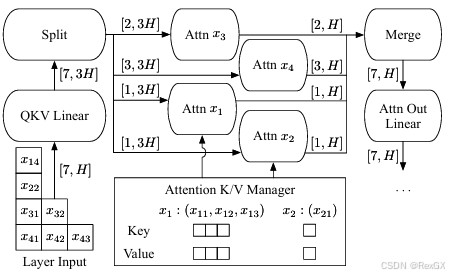
【模型推理篇】vLLM核心思想 - ② 动态批处理 continuous batching_vllm continuous batching ...
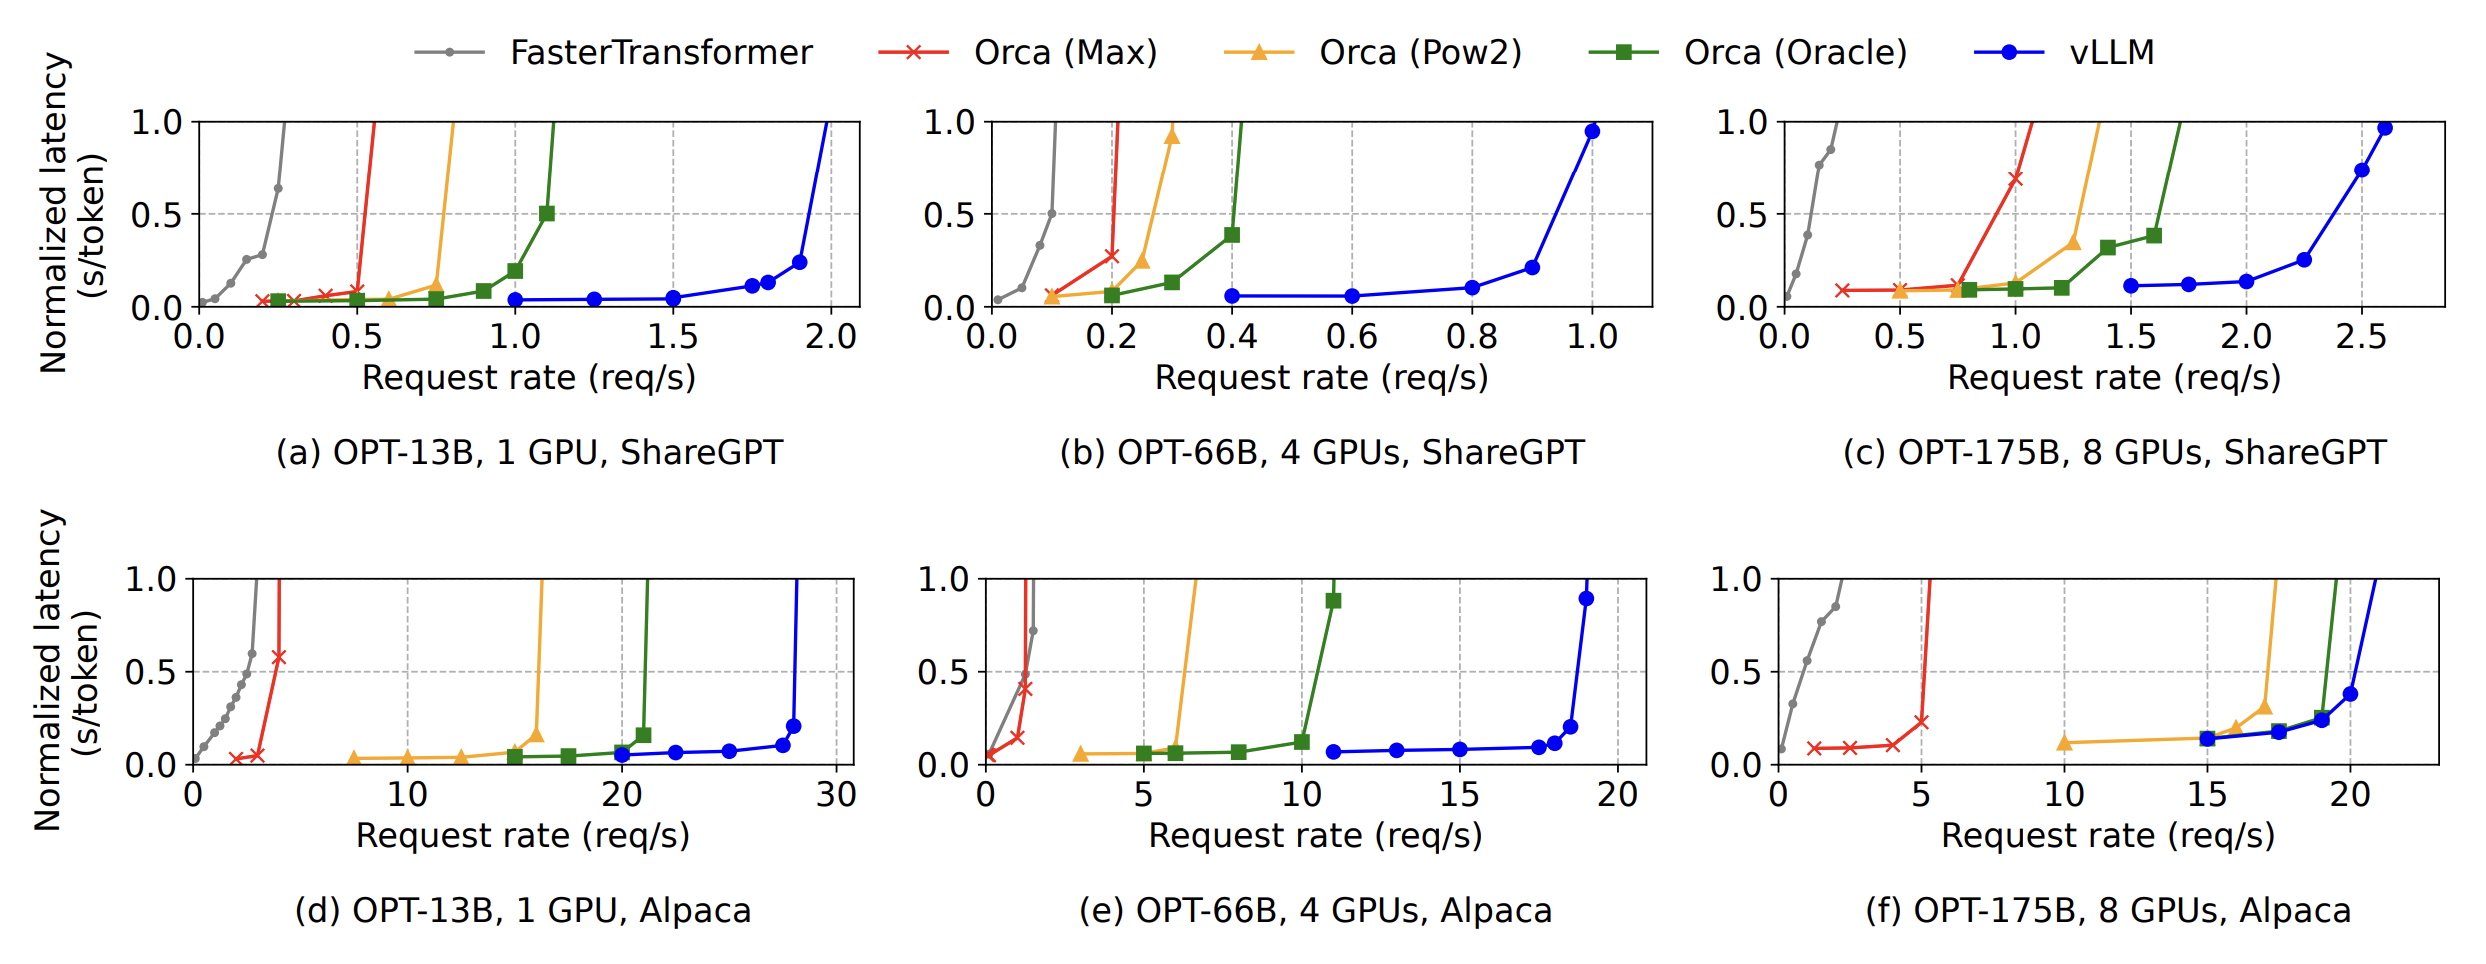
vLLM and PagedAttention: Why KV Cache Management Matters - Minseo’s Dev ...
How to Speed up AI Inference with vLLM Continuous Batching - Voice.ai
vLLM memory management analysis
[Feature]: continuous batching for vllm.LLM · Issue #7353 · vllm ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...
Advertisement Space (336x280)

How continuous batching enables 23x throughput in LLM inference ...
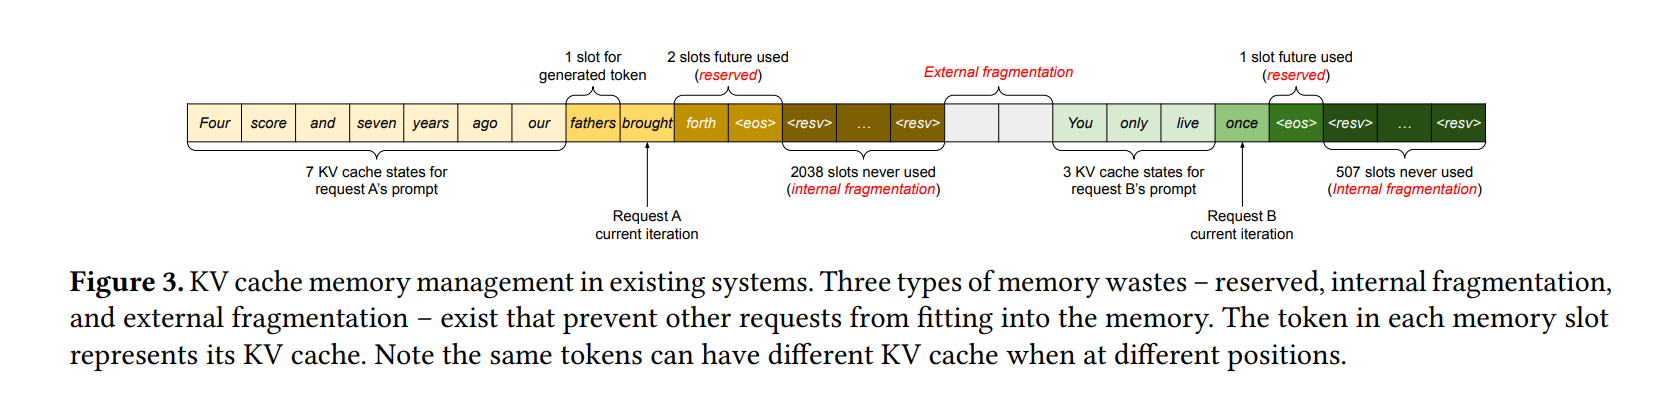
[论文笔记]vLLM: Efficient Memory Management for Large Language Model ...
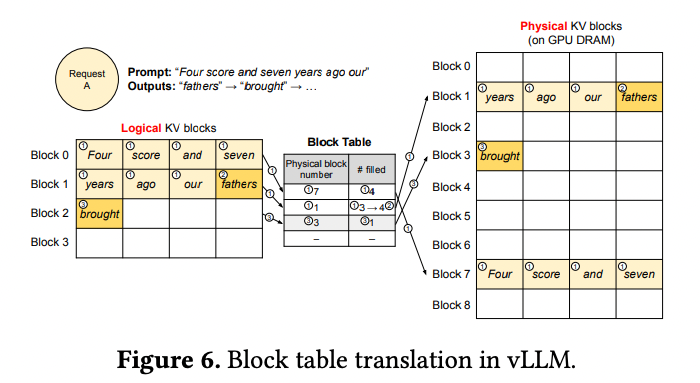
[논문 리뷰] Efficient Memory Management for Large Language Model Serving ...
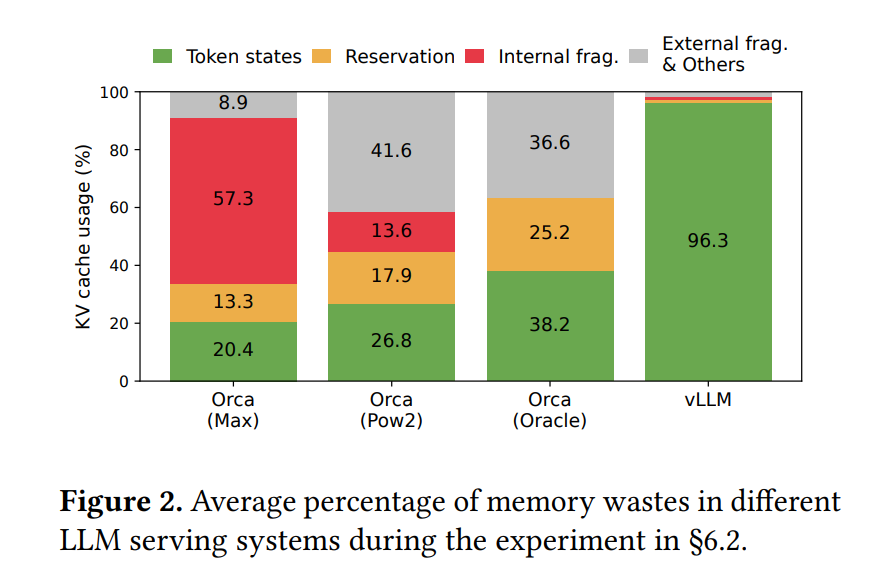
[论文笔记]vLLM: Efficient Memory Management for Large Language Model ...
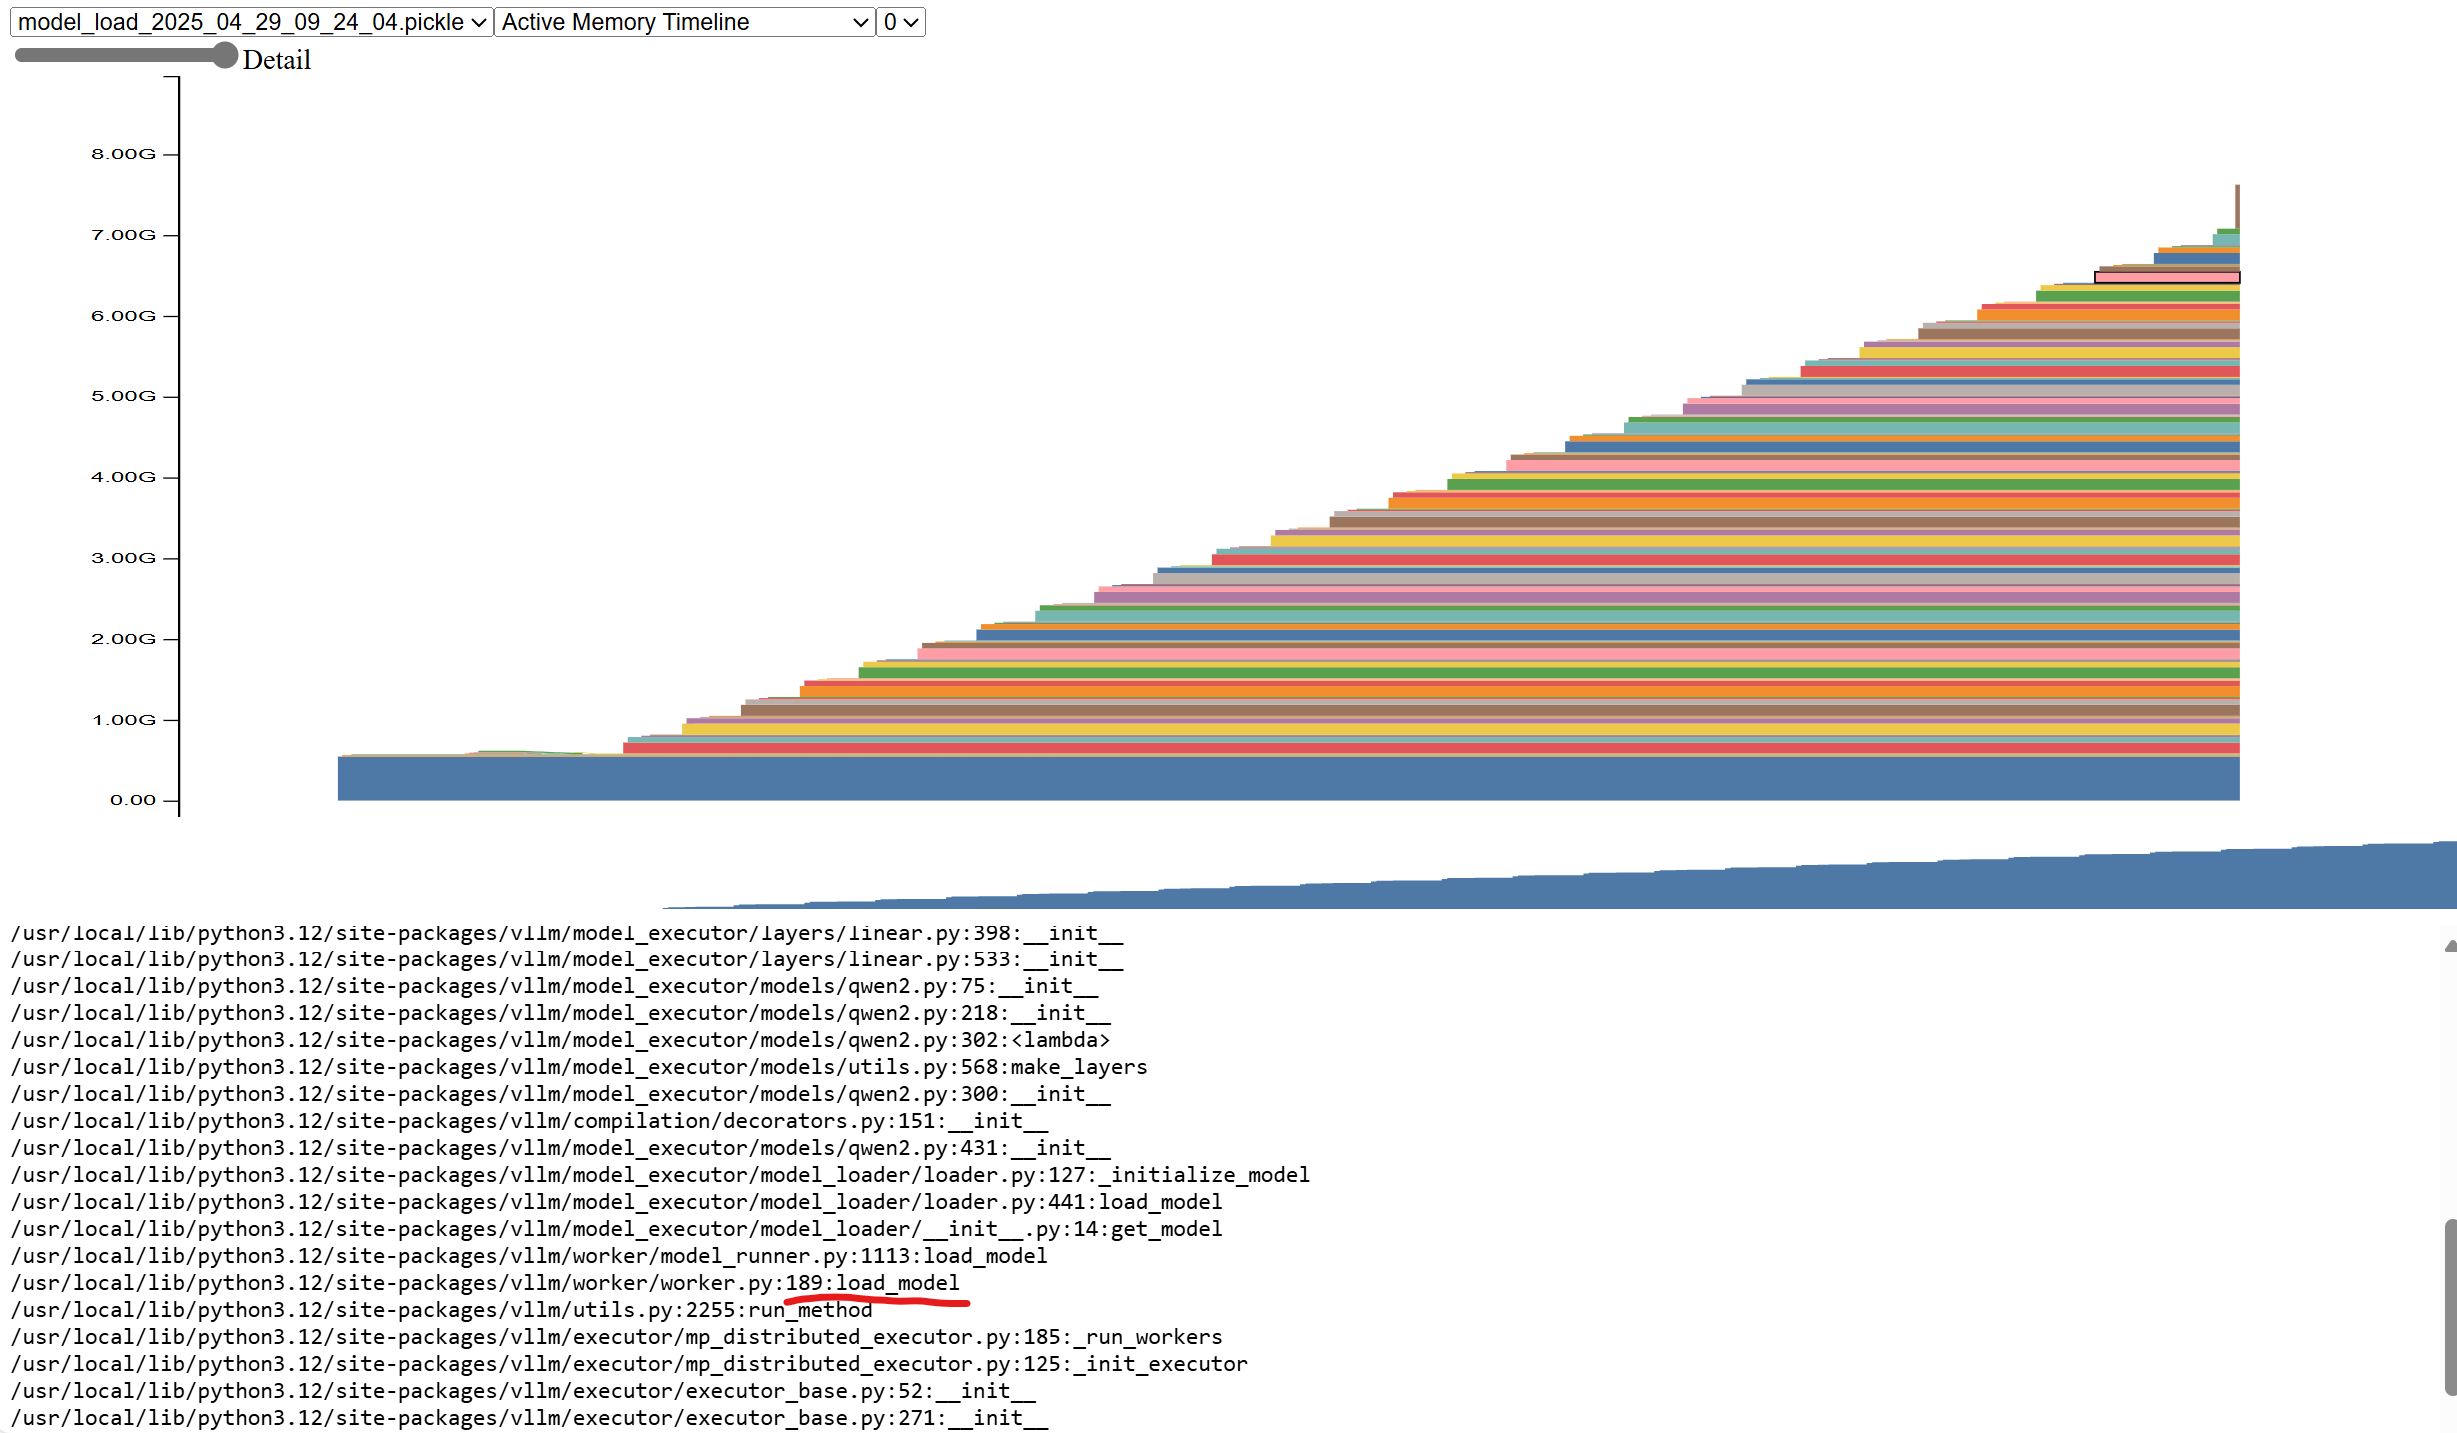
vLLM memory management analysis
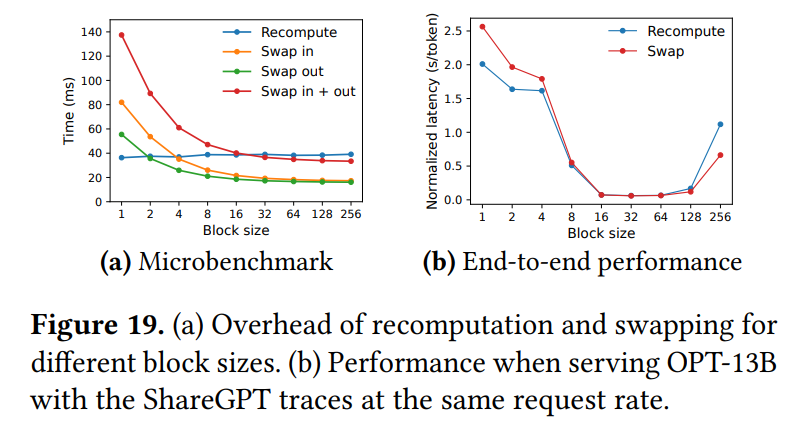
[论文笔记]vLLM: Efficient Memory Management for Large Language Model ...