
What Is Llm Inference Process Latency Examples Explained 2026
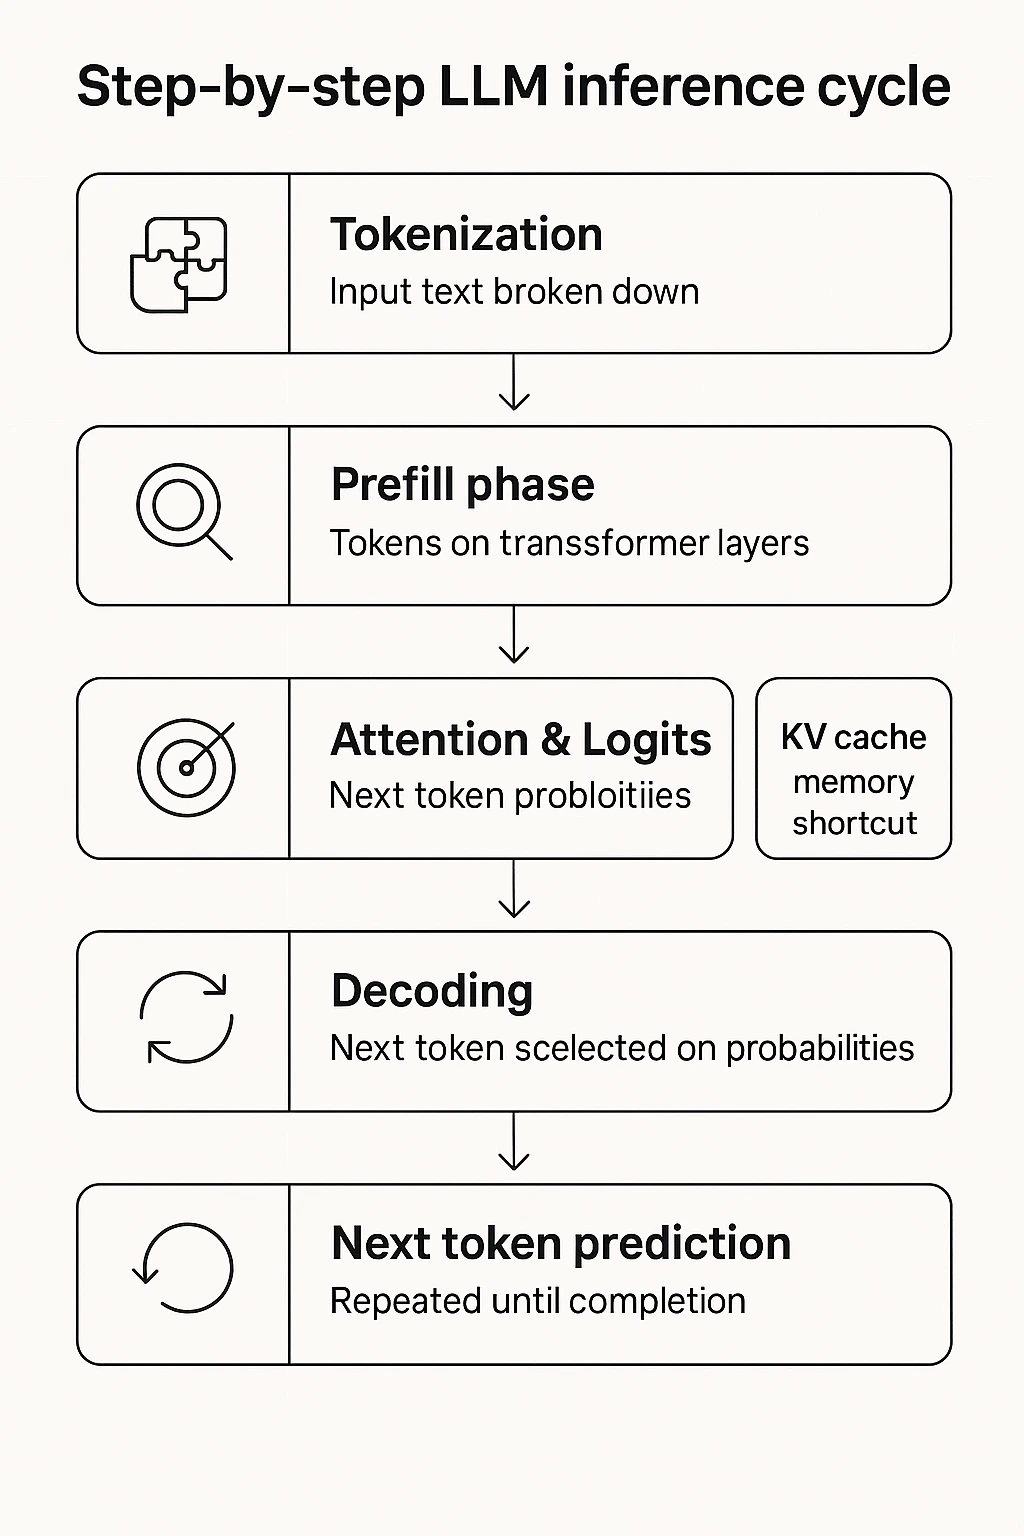
What Is LLM Inference? Process, Latency & Examples Explained (2026)
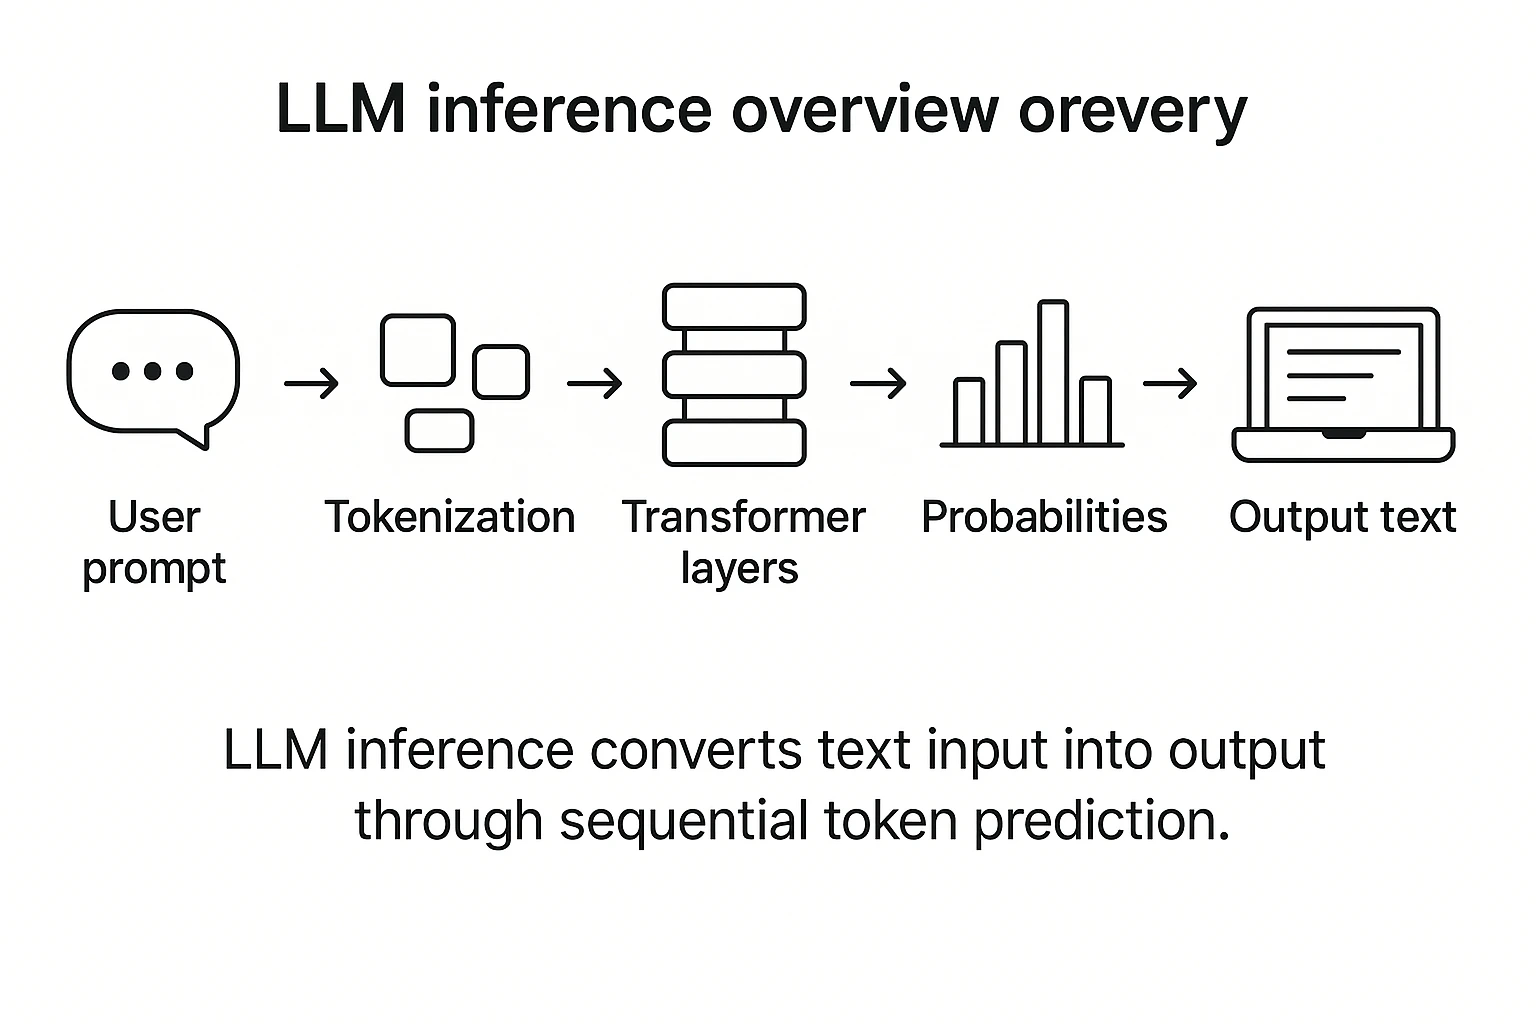
What Is LLM Inference? Process, Latency & Examples Explained (2026)
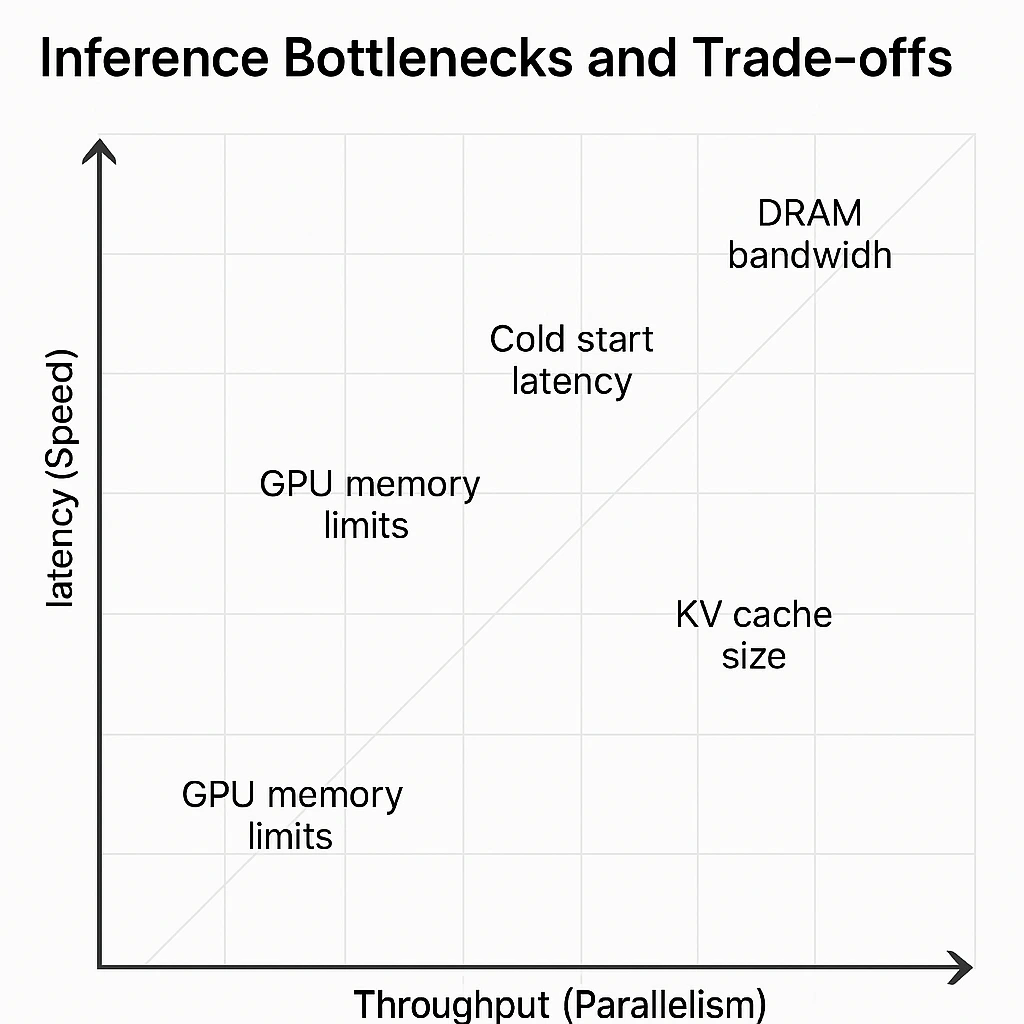
What Is LLM Inference? Process, Latency & Examples Explained (2026)
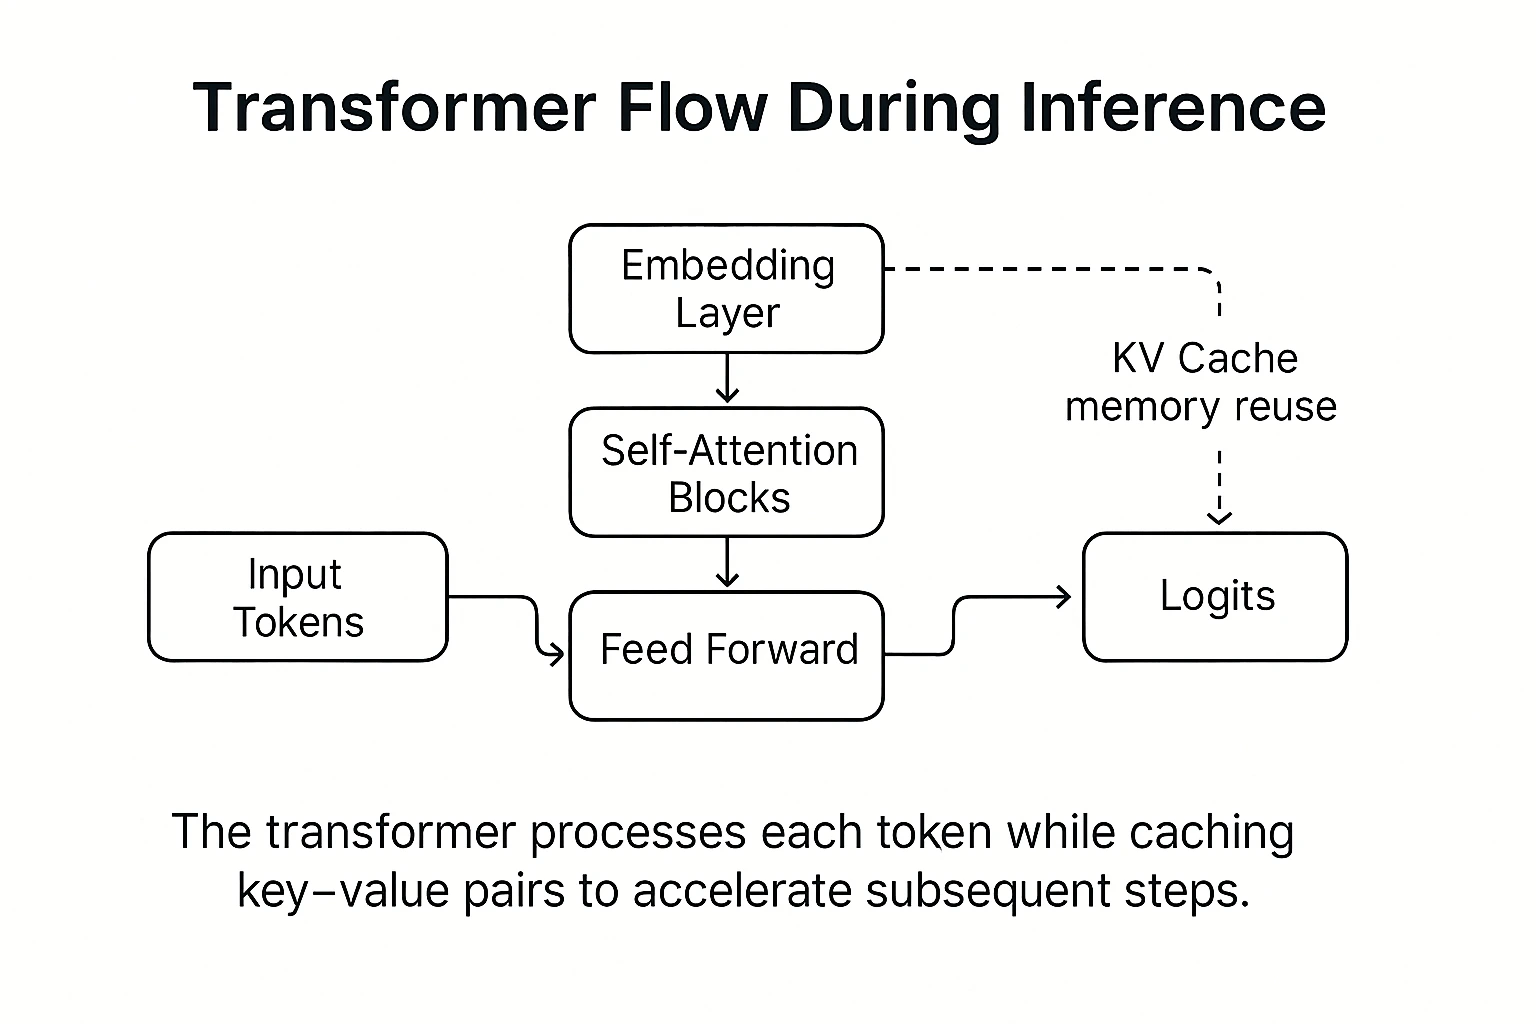
What Is LLM Inference? Process, Latency & Examples Explained (2026)
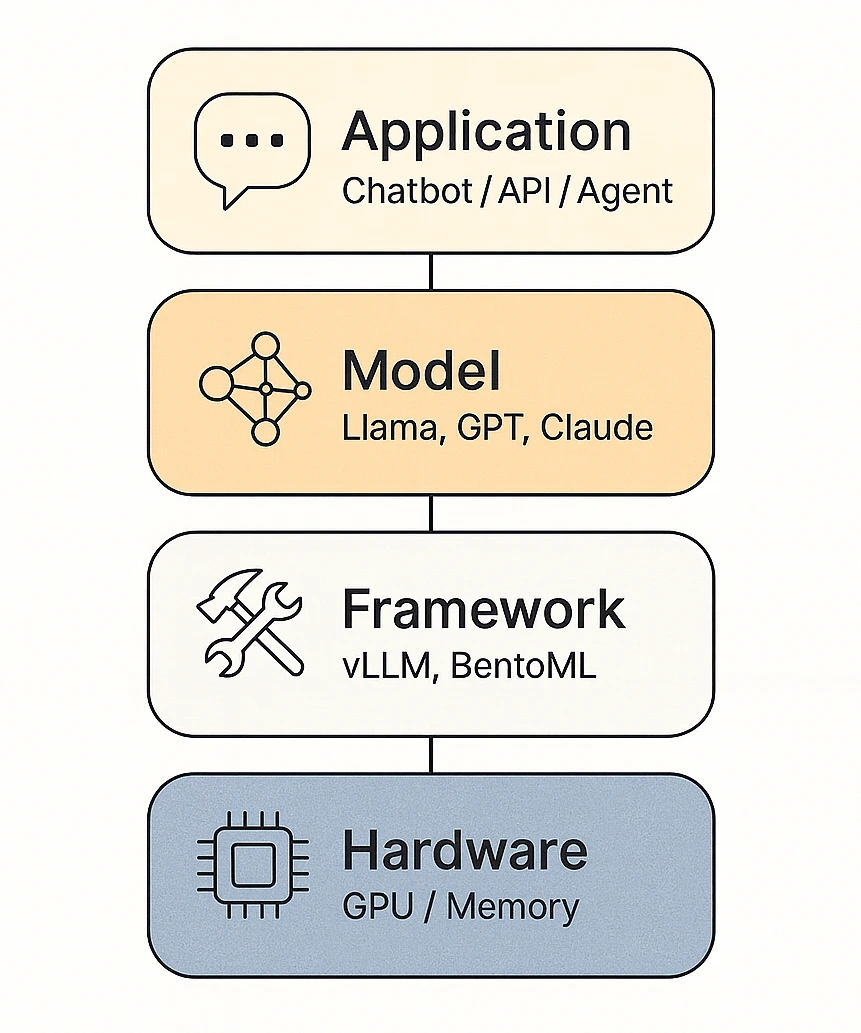
What Is LLM Inference? Process, Latency & Examples Explained (2026)
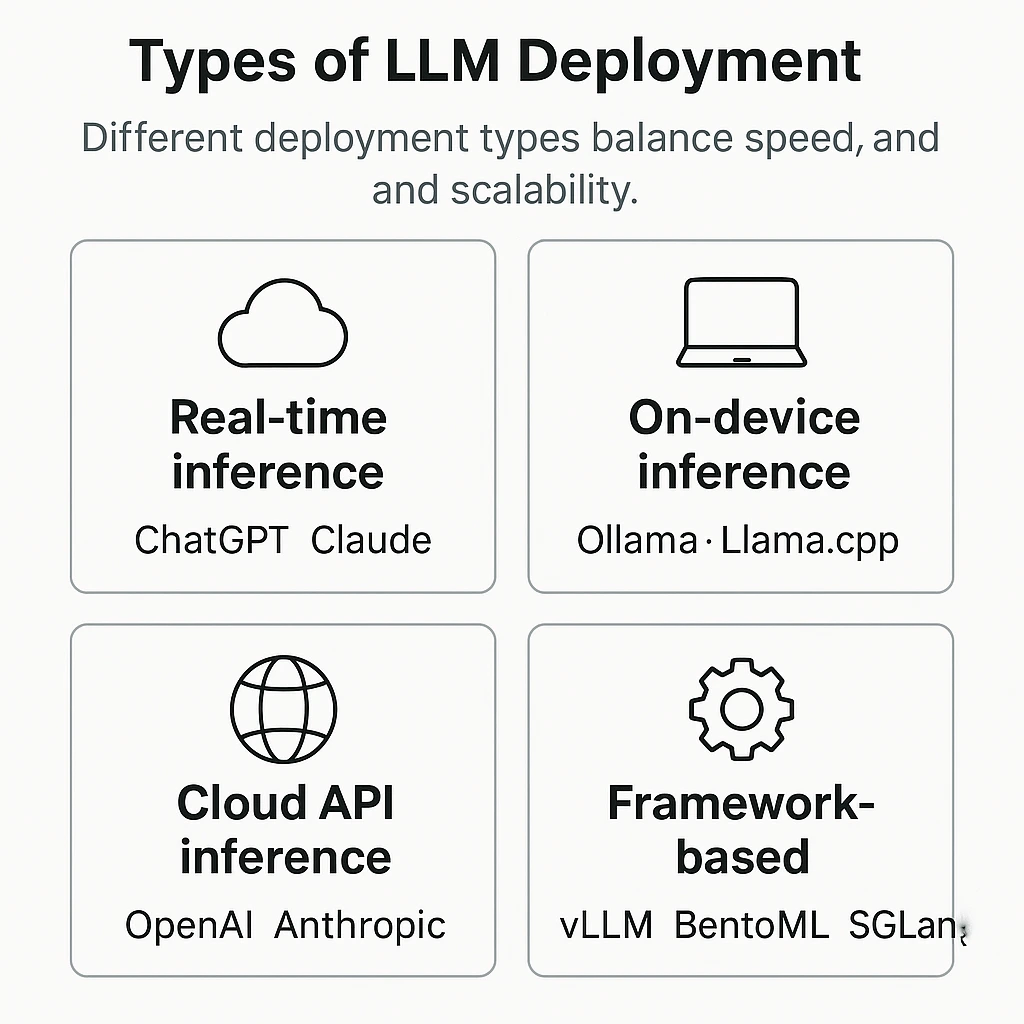
What Is LLM Inference? Process, Latency & Examples Explained (2026)
What Is LLM Inference? Process, Latency & Examples Explained (2026)
What Is LLM Inference? Process, Latency & Examples Explained (2026)

LLM Inference Latency Metrics Explained | PDF | Mean | Latency ...

LLM Inference latency is highly prompt dependent. Understanding the ...
Advertisement Space (300x250)

Real-Time Streaming LLM Inference Guide 2026 | Iterathon

LLM Inference Scaling, Latency Collapse Simulation | Kaggle

LLM Inference Optimization Production Guide 2026 | Iterathon

Improving LLM Inference Latency on CPUs with Model Quantization ...
LLM Inference Explained: Prefill vs Decode and Why Latency Matters ...
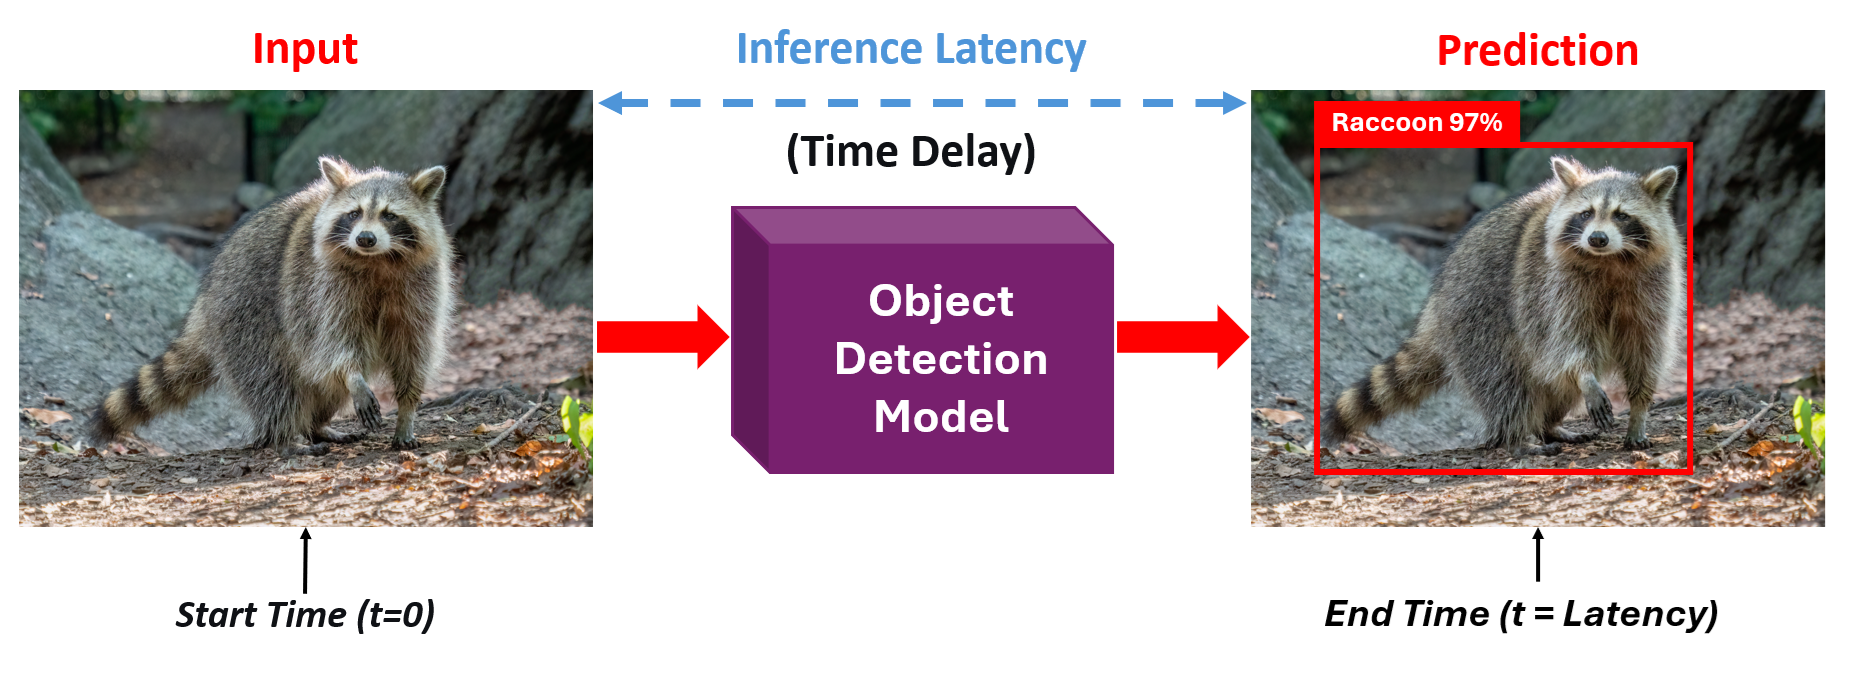
What Is Inference Latency? Real-Time Computer Vision
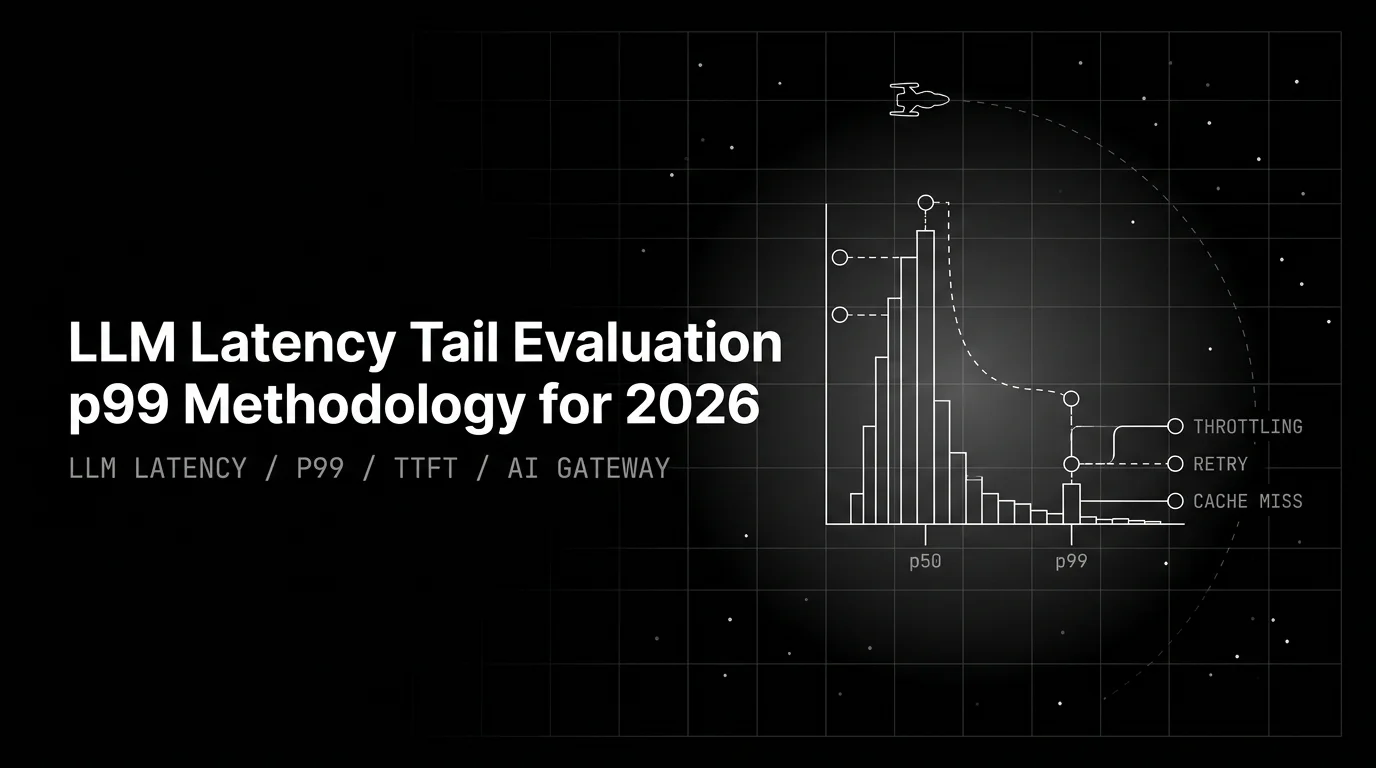
LLM Latency Tail Evaluation: p99 Methodology 2026

Understanding LLM Inference Process | PDF | Applied Mathematics ...
LLM Inference Explained for Developers — How AI Models Generate Text

GenAI – How To Optimize LLM Inference Process ? – Praudyog
Advertisement Space (336x280)
LLM Inference SLO Engineering: TTFT, ITL, and P99 Latency Budgets for ...
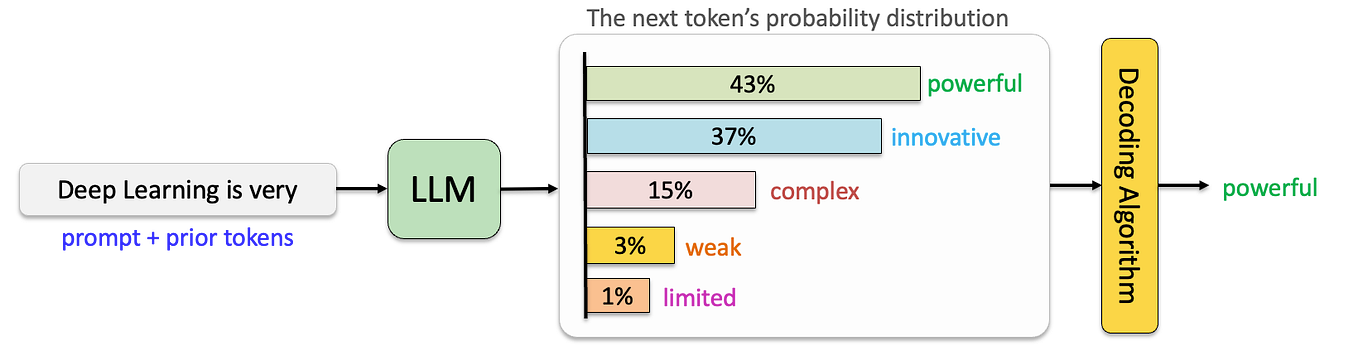
LLM Inference Series: 2. The two-phase process behind LLMs’ responses ...
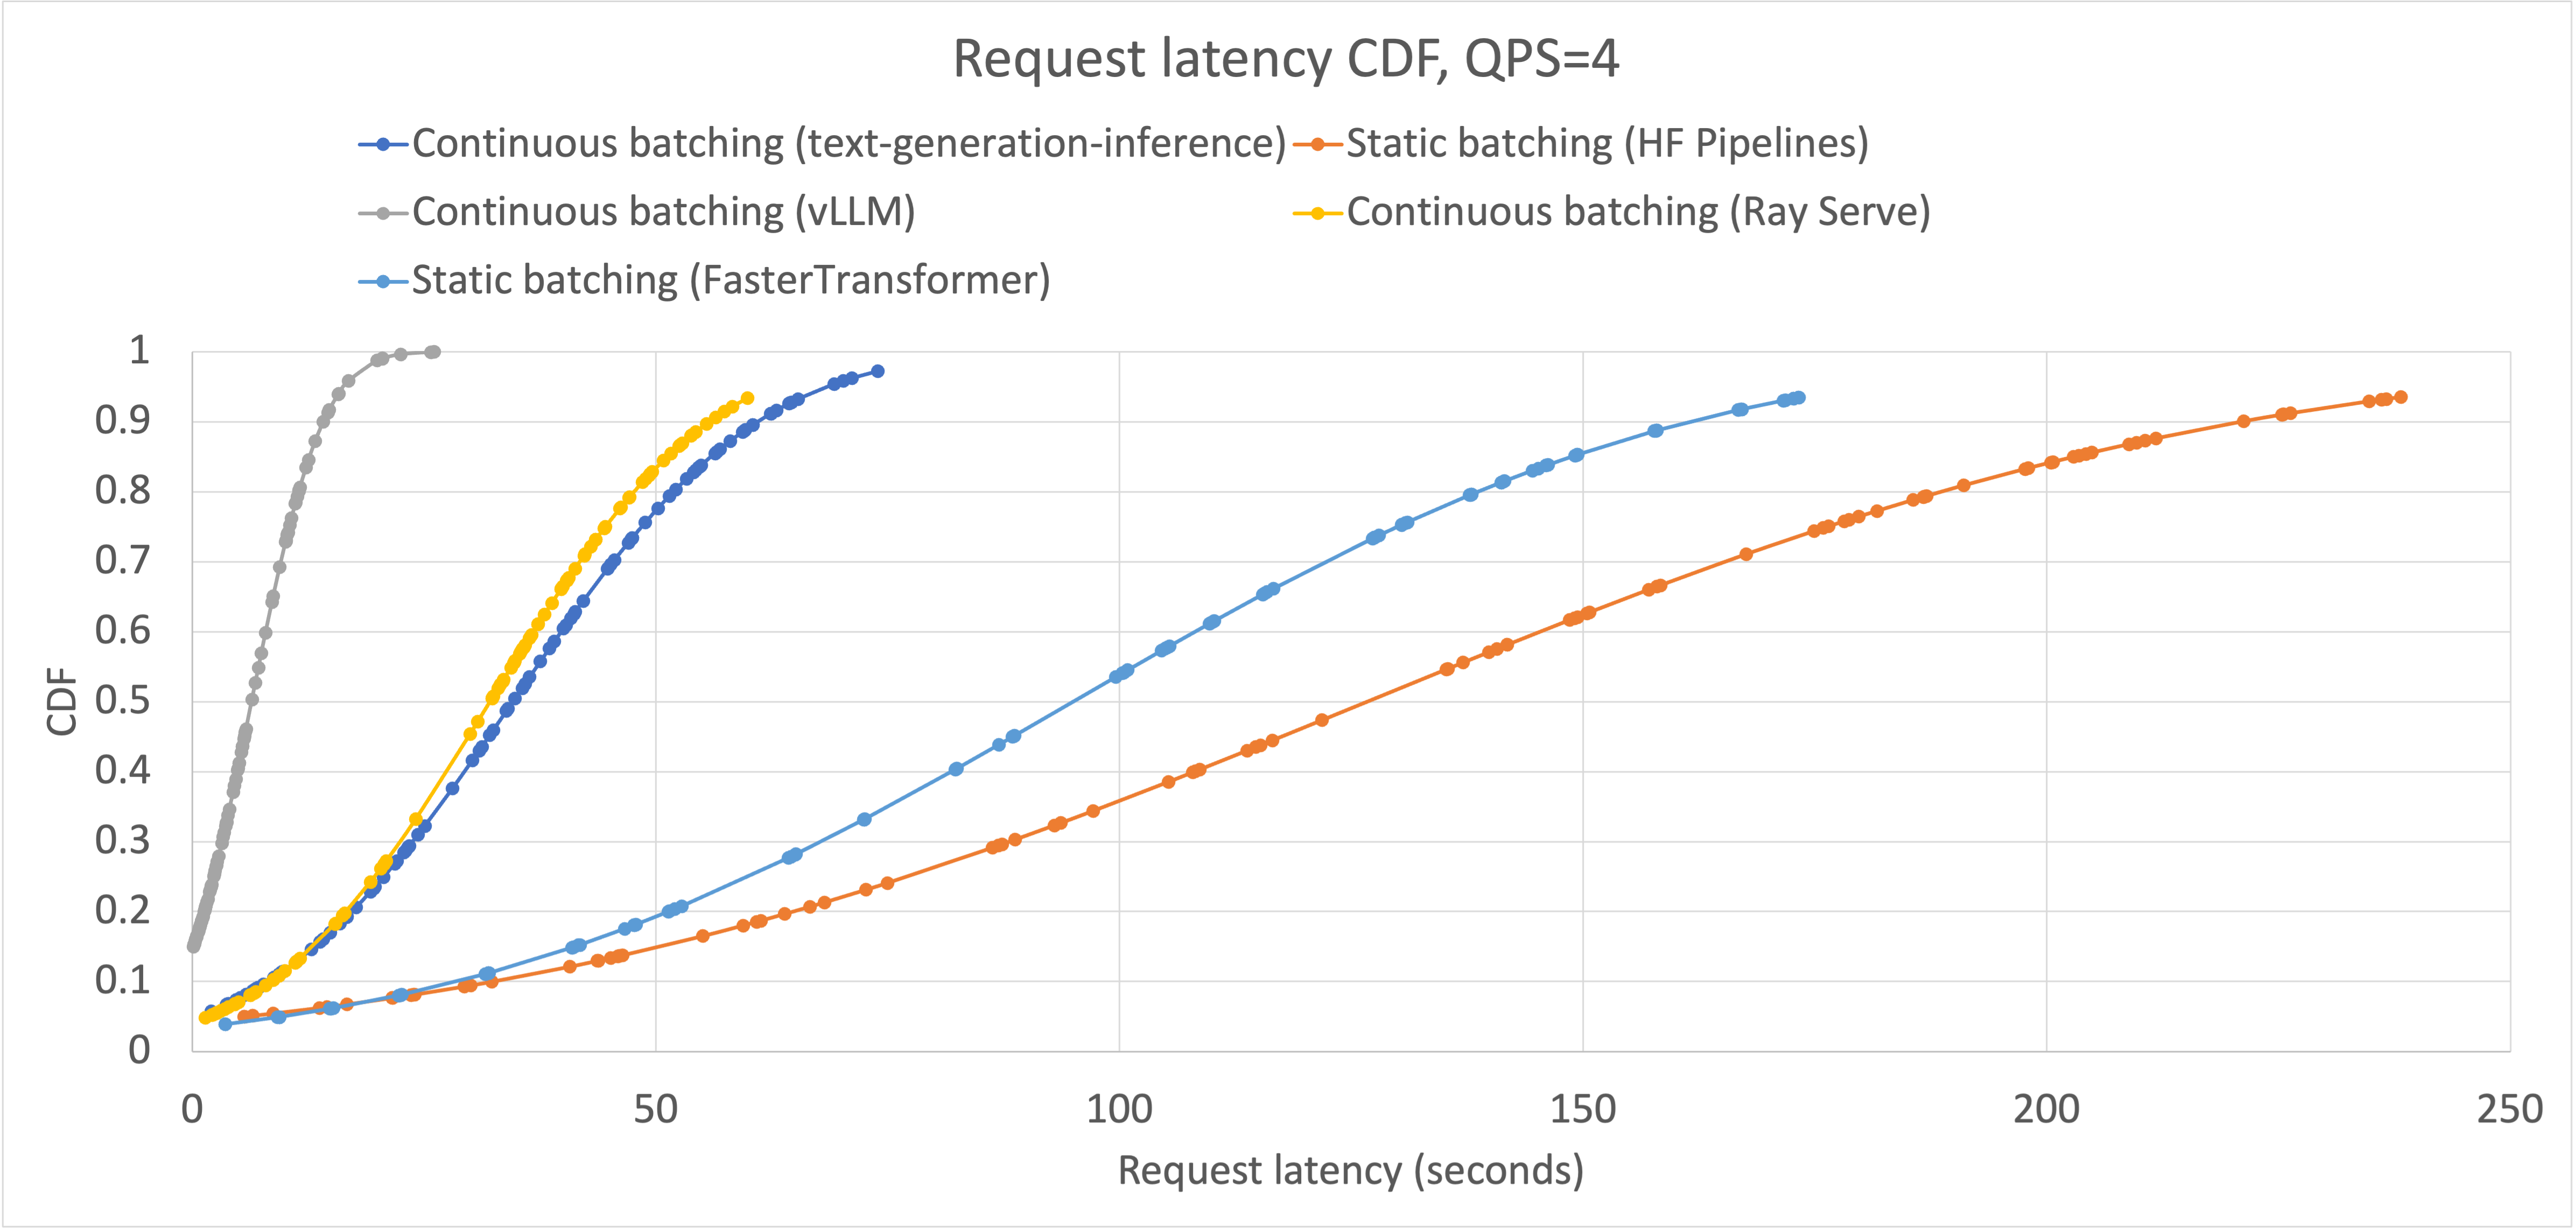
Achieve 23x LLM Inference Throughput & Reduce p50 Latency
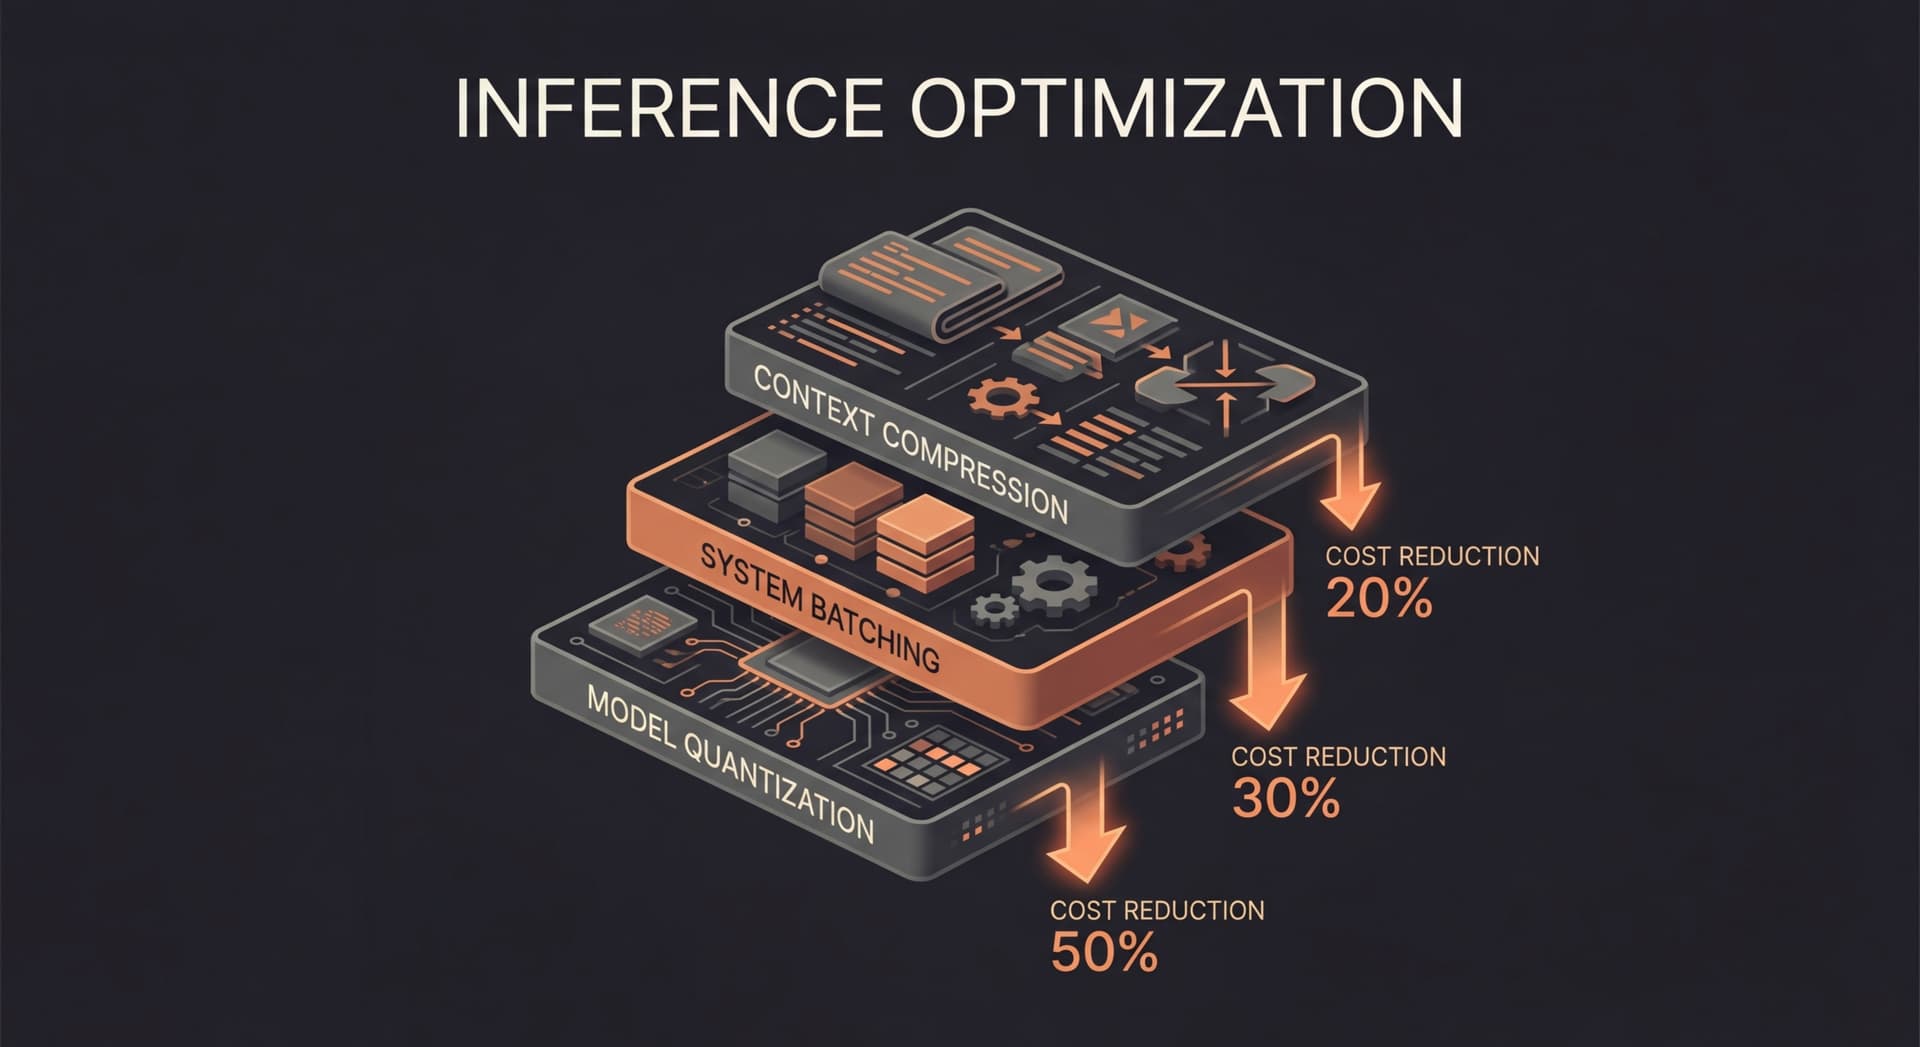
LLM Inference Optimization: Cut Cost & Latency at Every Layer (2026 ...

Cut LLM Inference Latency With NVIDIA L4 & TensorRT

LLM Inference Series: 2. The two-phase process behind LLMs’ responses ...
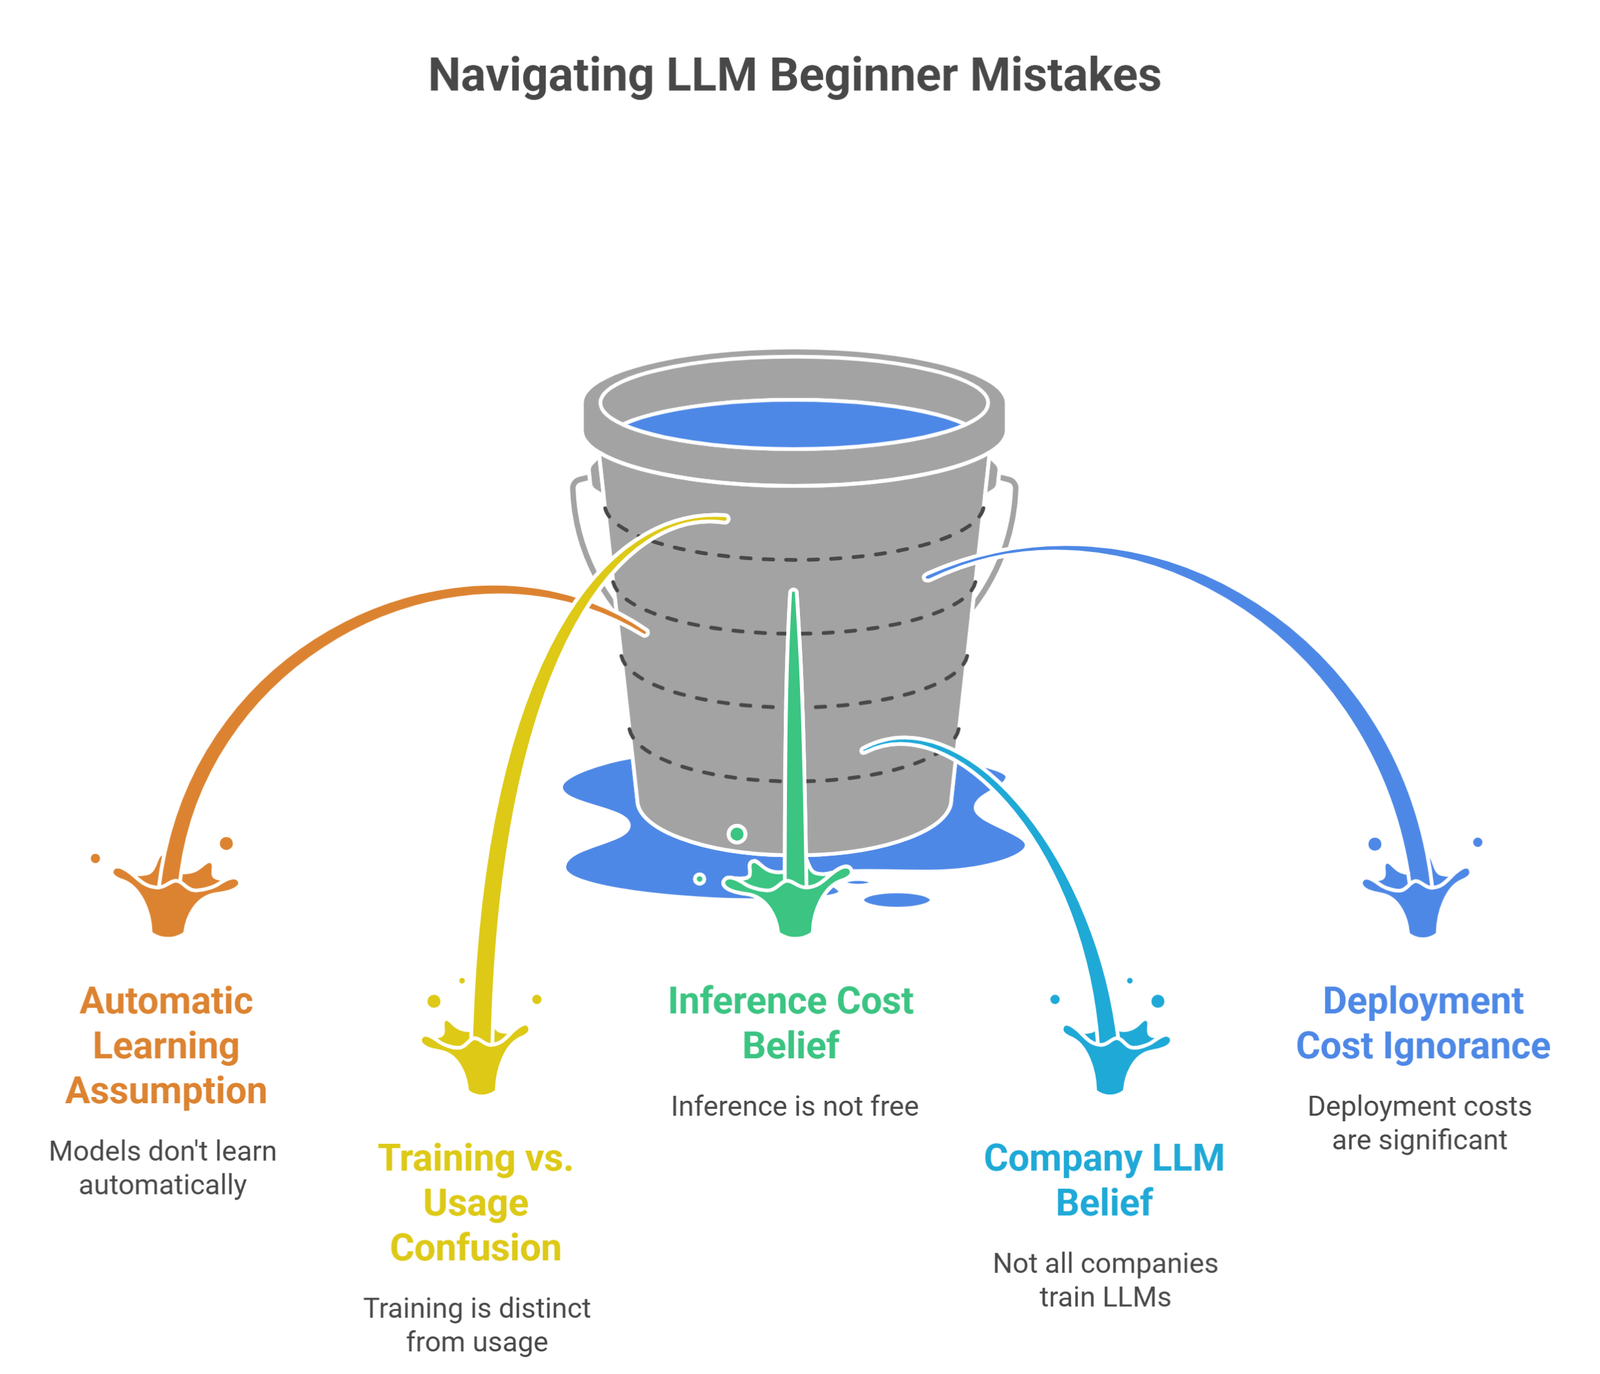
Ultimate Guide to LLM Training vs Inference in 2026 (Easy, Fast ...
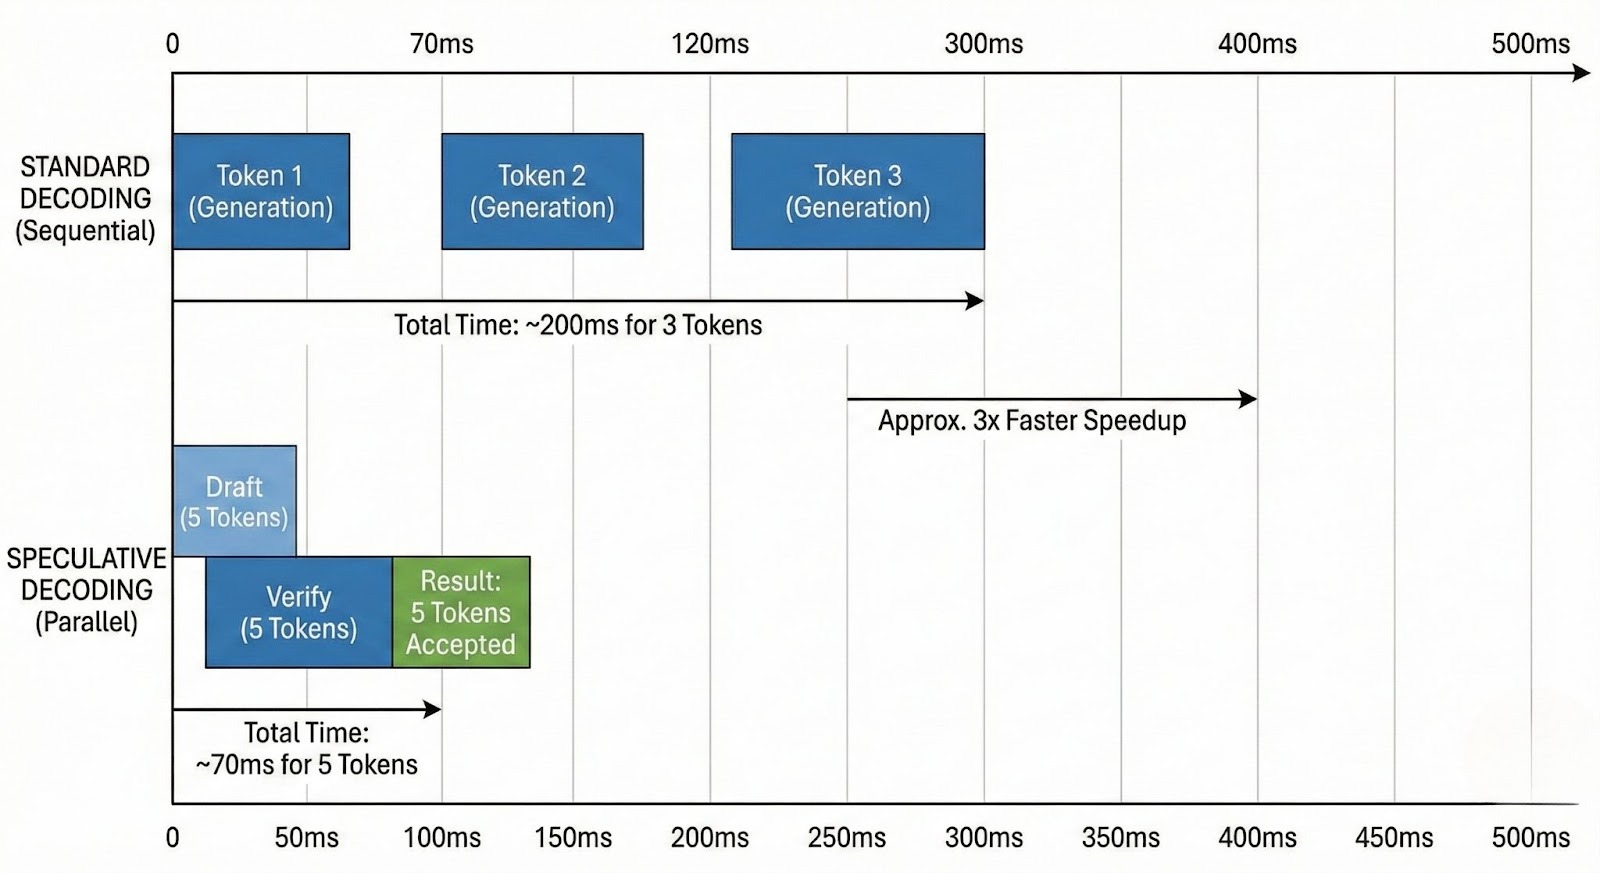
How to Achieve Ultra-Low Latency LLM Inference in the Cloud
Why is LLM Inference Optimization Important in 2026?
LLM API Latency Compared: Speed Benchmarks 2026 — APIpulse
Advertisement Space (336x280)

LLM Inference Series: 2. The two-phase process behind LLMs’ responses ...
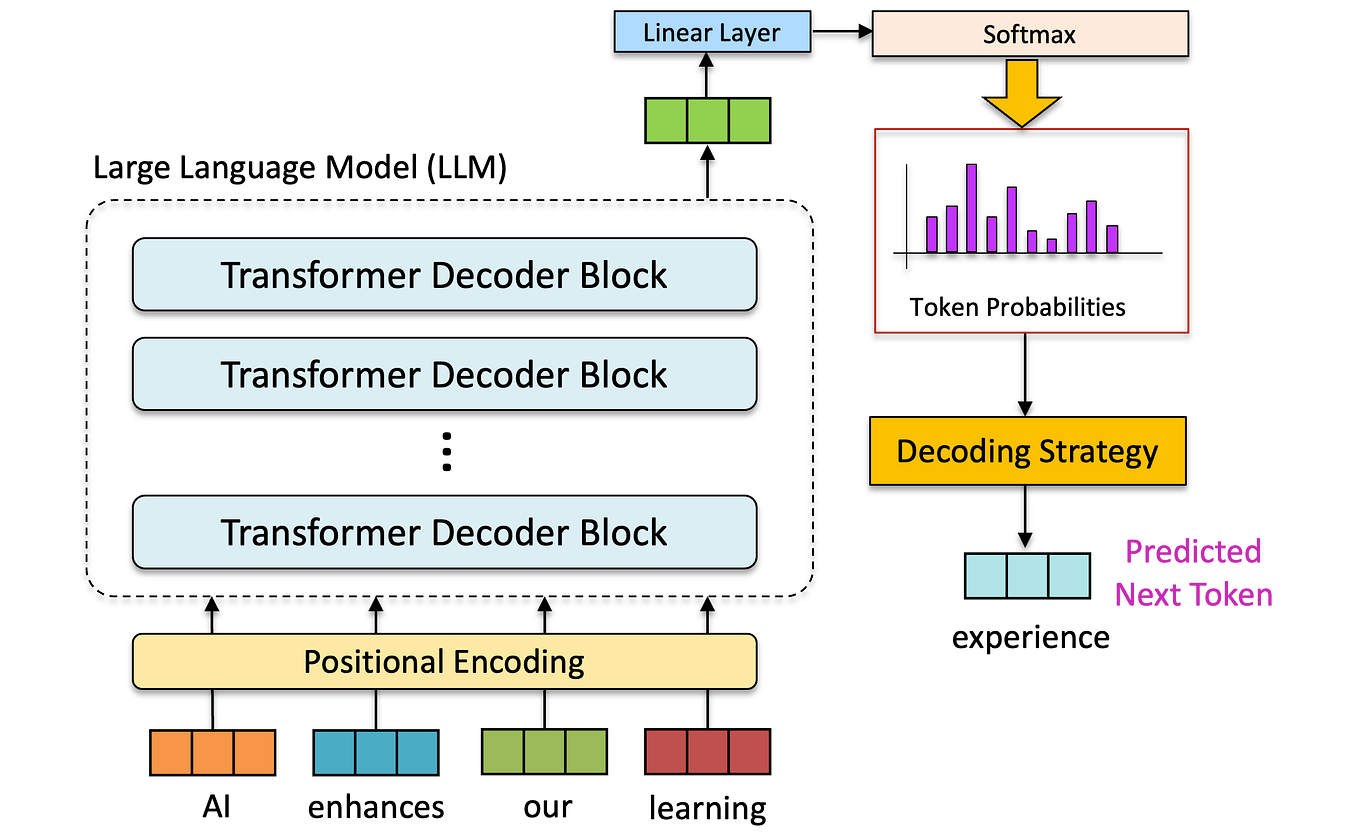
LLM Inference Series: 2. The two-phase process behind LLMs’ responses ...
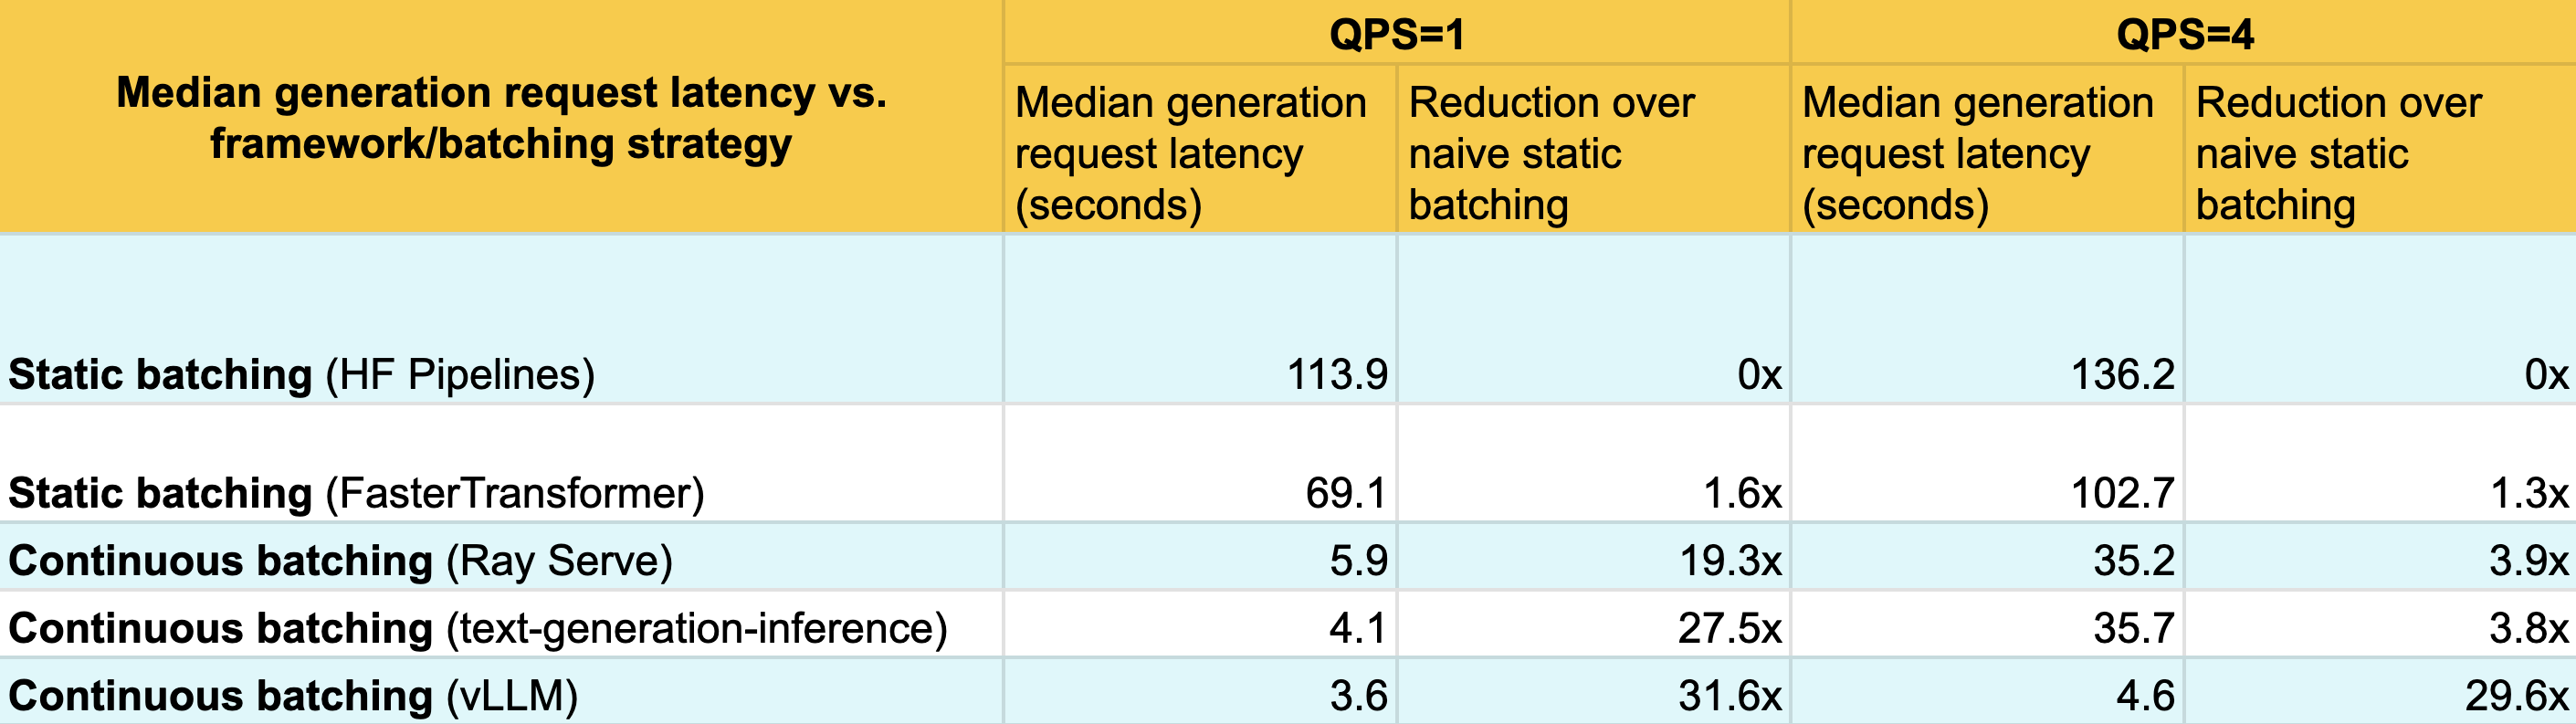
Achieve 23x LLM Inference Throughput & Reduce p50 Latency
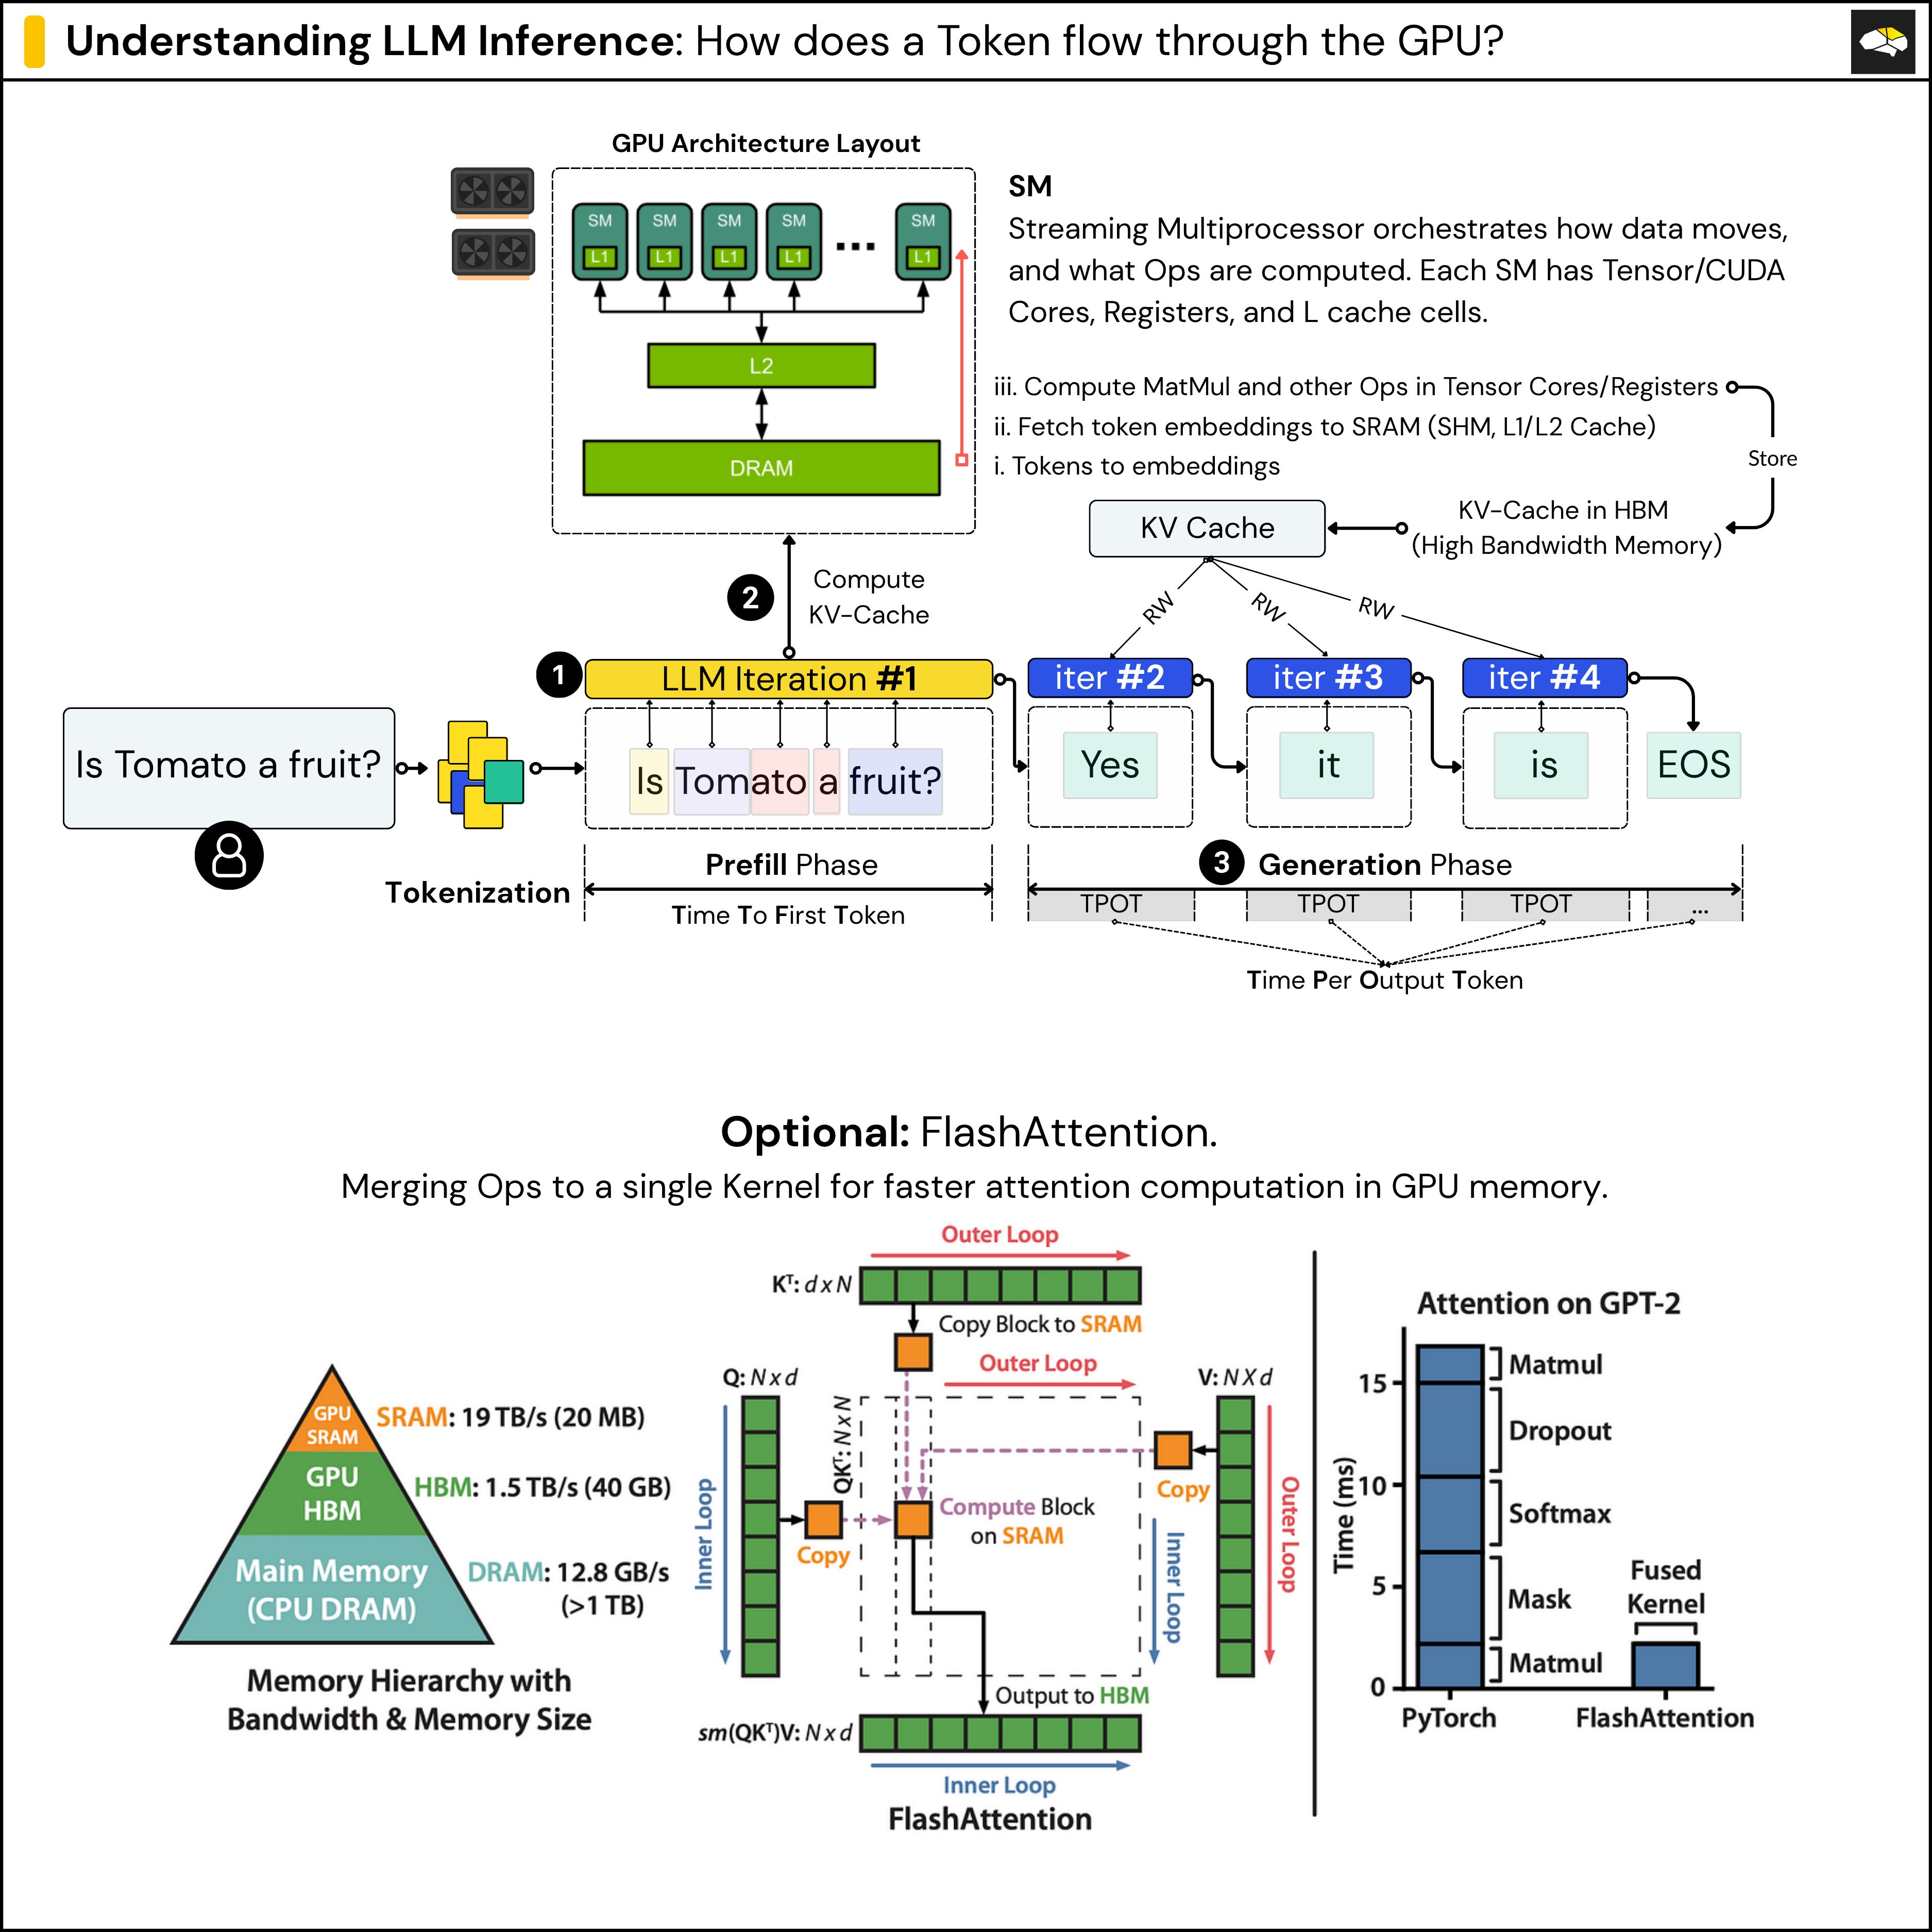
Understanding LLM Inference - by Alex Razvant
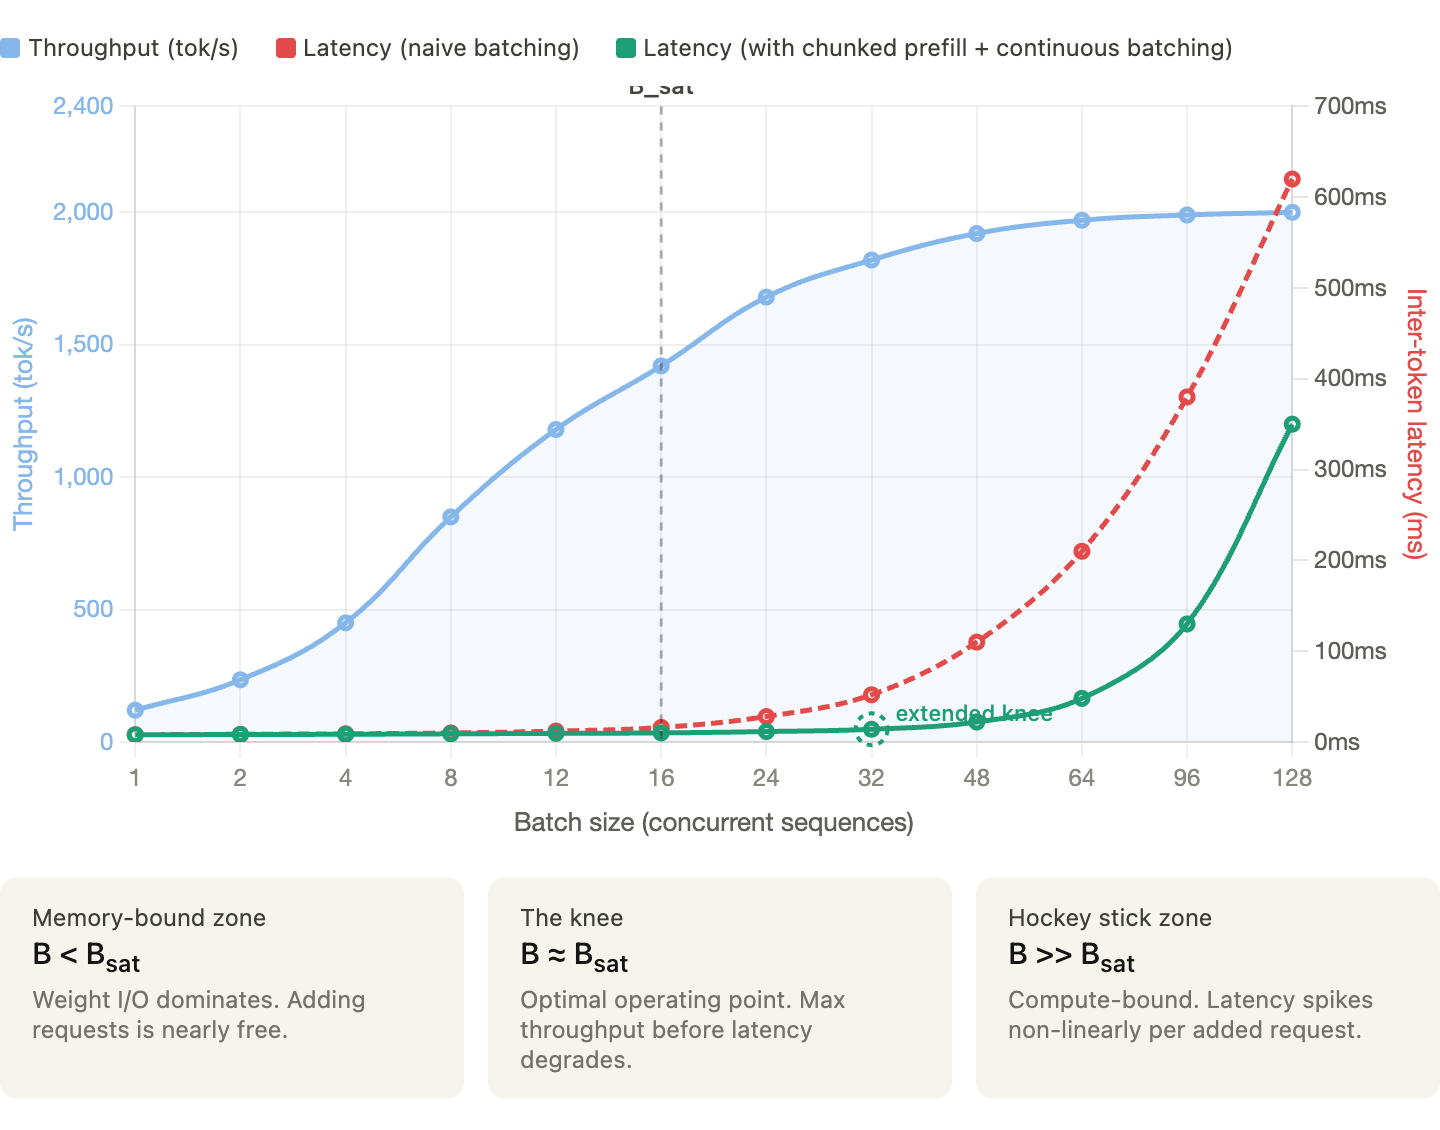
The LLM Inference Trilemma: Throughput, Latency, Cost | DigitalOcean

3-Part Series: LLM Latency in Production (Part 1)