
Whats The Multi Head Latent Attention Mla Operation Used In Deepseek

Three Interpretations of DeepSeek V2's Multi-headed Latent Attention Layer

Three Interpretations of DeepSeek V2's Multi-headed Latent Attention Layer
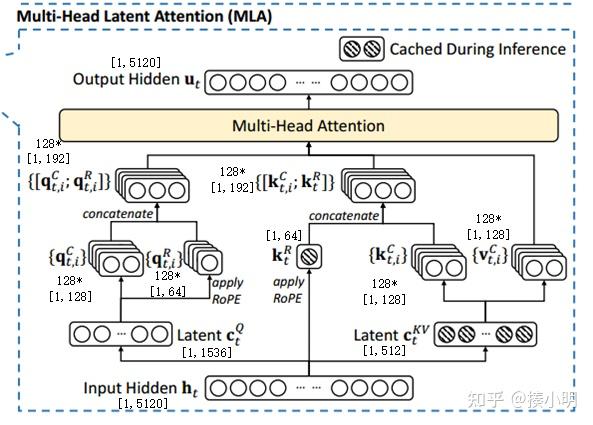
DeepSeek MLA (Multi-head latent attention)的attention流程 - 知乎

DeepSeek + SGLang: Multi-Head Latent Attention

Inside DeepSeek V3: Breaking Down Multi-Head Latent Attention (MLA ...

DeepSeek Multihead Latent Attention - YouTube

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

Multi-Head Latent Attention (MLA) | Sebastian Raschka, PhD
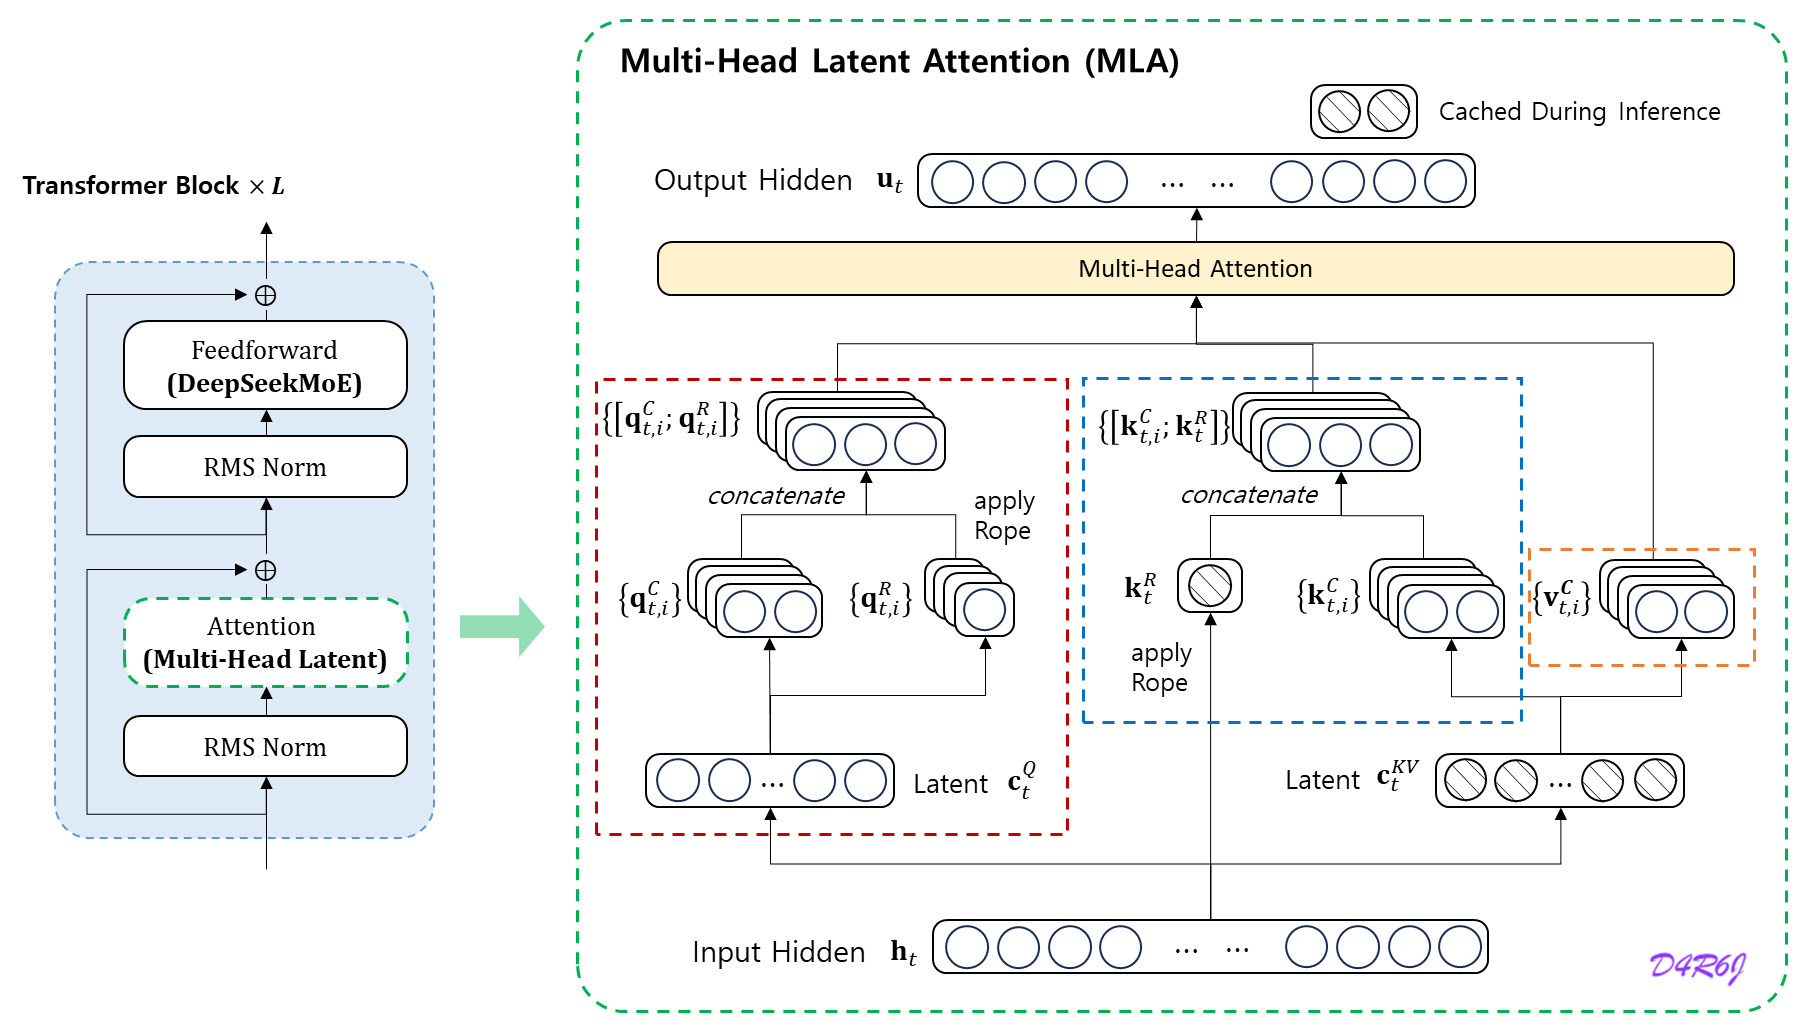
[ DeepSeek ] 1. code review [ MLA ]

A Technical Tour of the DeepSeek Models from V3 to V3.2
Advertisement Space (300x250)

[论文评述] Hardware-Centric Analysis of DeepSeek's Multi-Head Latent Attention

Multi-Head Latent Attention (MLA) 详细介绍(来自Deepseek V3的回答) - 知乎

Multi-Head Latent Attention (MLA) is a newly proposed technique for ...

DeepSeek 注意力之 MLA(Multi-Head Latent Attention) - 知乎
Build DeepSeek-V3: Multi-Head Latent Attention (MLA) Architecture ...

Exploring Transformed Multi-Head Latent Attention for Cost-Effective ...

Implementing DeepSeek-V2’s Multi-Head Latent Attention (MLA) from ...

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science
Build DeepSeek-V3: Multi-Head Latent Attention (MLA) Architecture ...

Multi-Head Latent Attention – Latent KV-Cache (DeepSeek v3) – Lechuck Park
Advertisement Space (336x280)

Advancements in Machine Learning with DeepSeek v3

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

Multilingual Capabilities of DeepSeek v3 in AI Applications
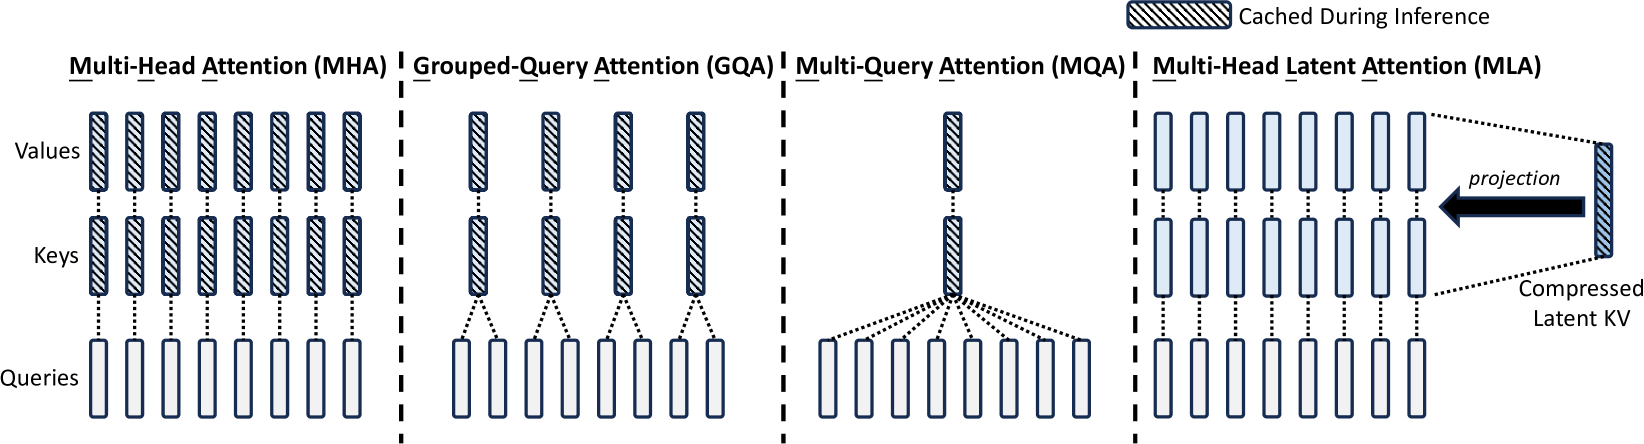
DeepSeek-V2: Multi-Head Latent Attention (MLA)
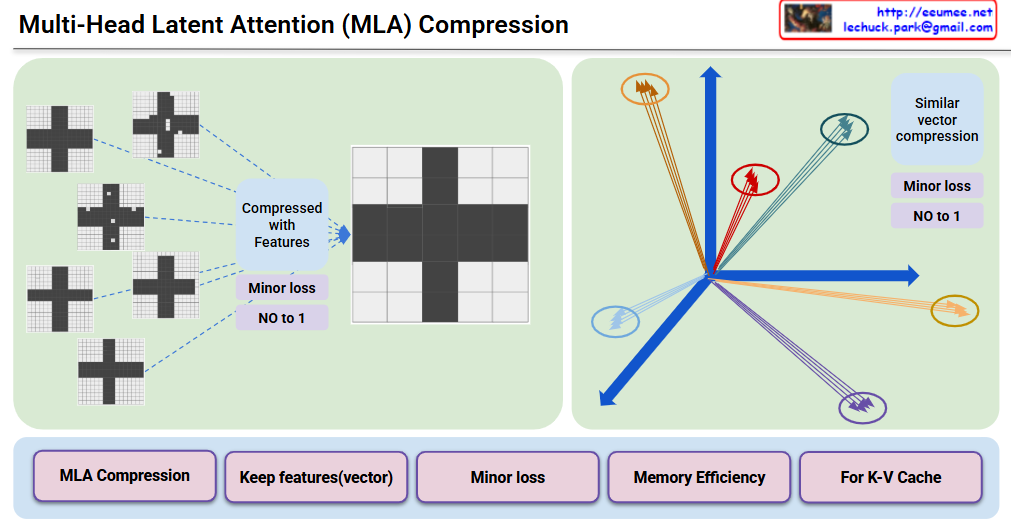
Multi-Head Latent Attention (MLA) Compression – Lechuck Park

Multi-Head Latent Attention Explained Simply - YouTube

Multi-Head Latent Attention — 토큰당 shared latent로 KV 캐시를 줄이는 원리 - Zero ...

DeepSeek Series: A Comprehensive Deep Dive into Multi-Head Latent ...

The Multi-head Attention Mechanism Explained!

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science
Advertisement Space (336x280)

DeepSeek Launches FlashMLA

How to Reduce Memory Use in Reasoning Models

资讯 | Deepseek-V2多头潜在注意力(Multi-head Latent Attention)原理及PyTorch实现 - 智源社区

【大模型】DeepSeek核心技术之MLA (Multi-head Latent Attention)_deepseek mla-CSDN博客
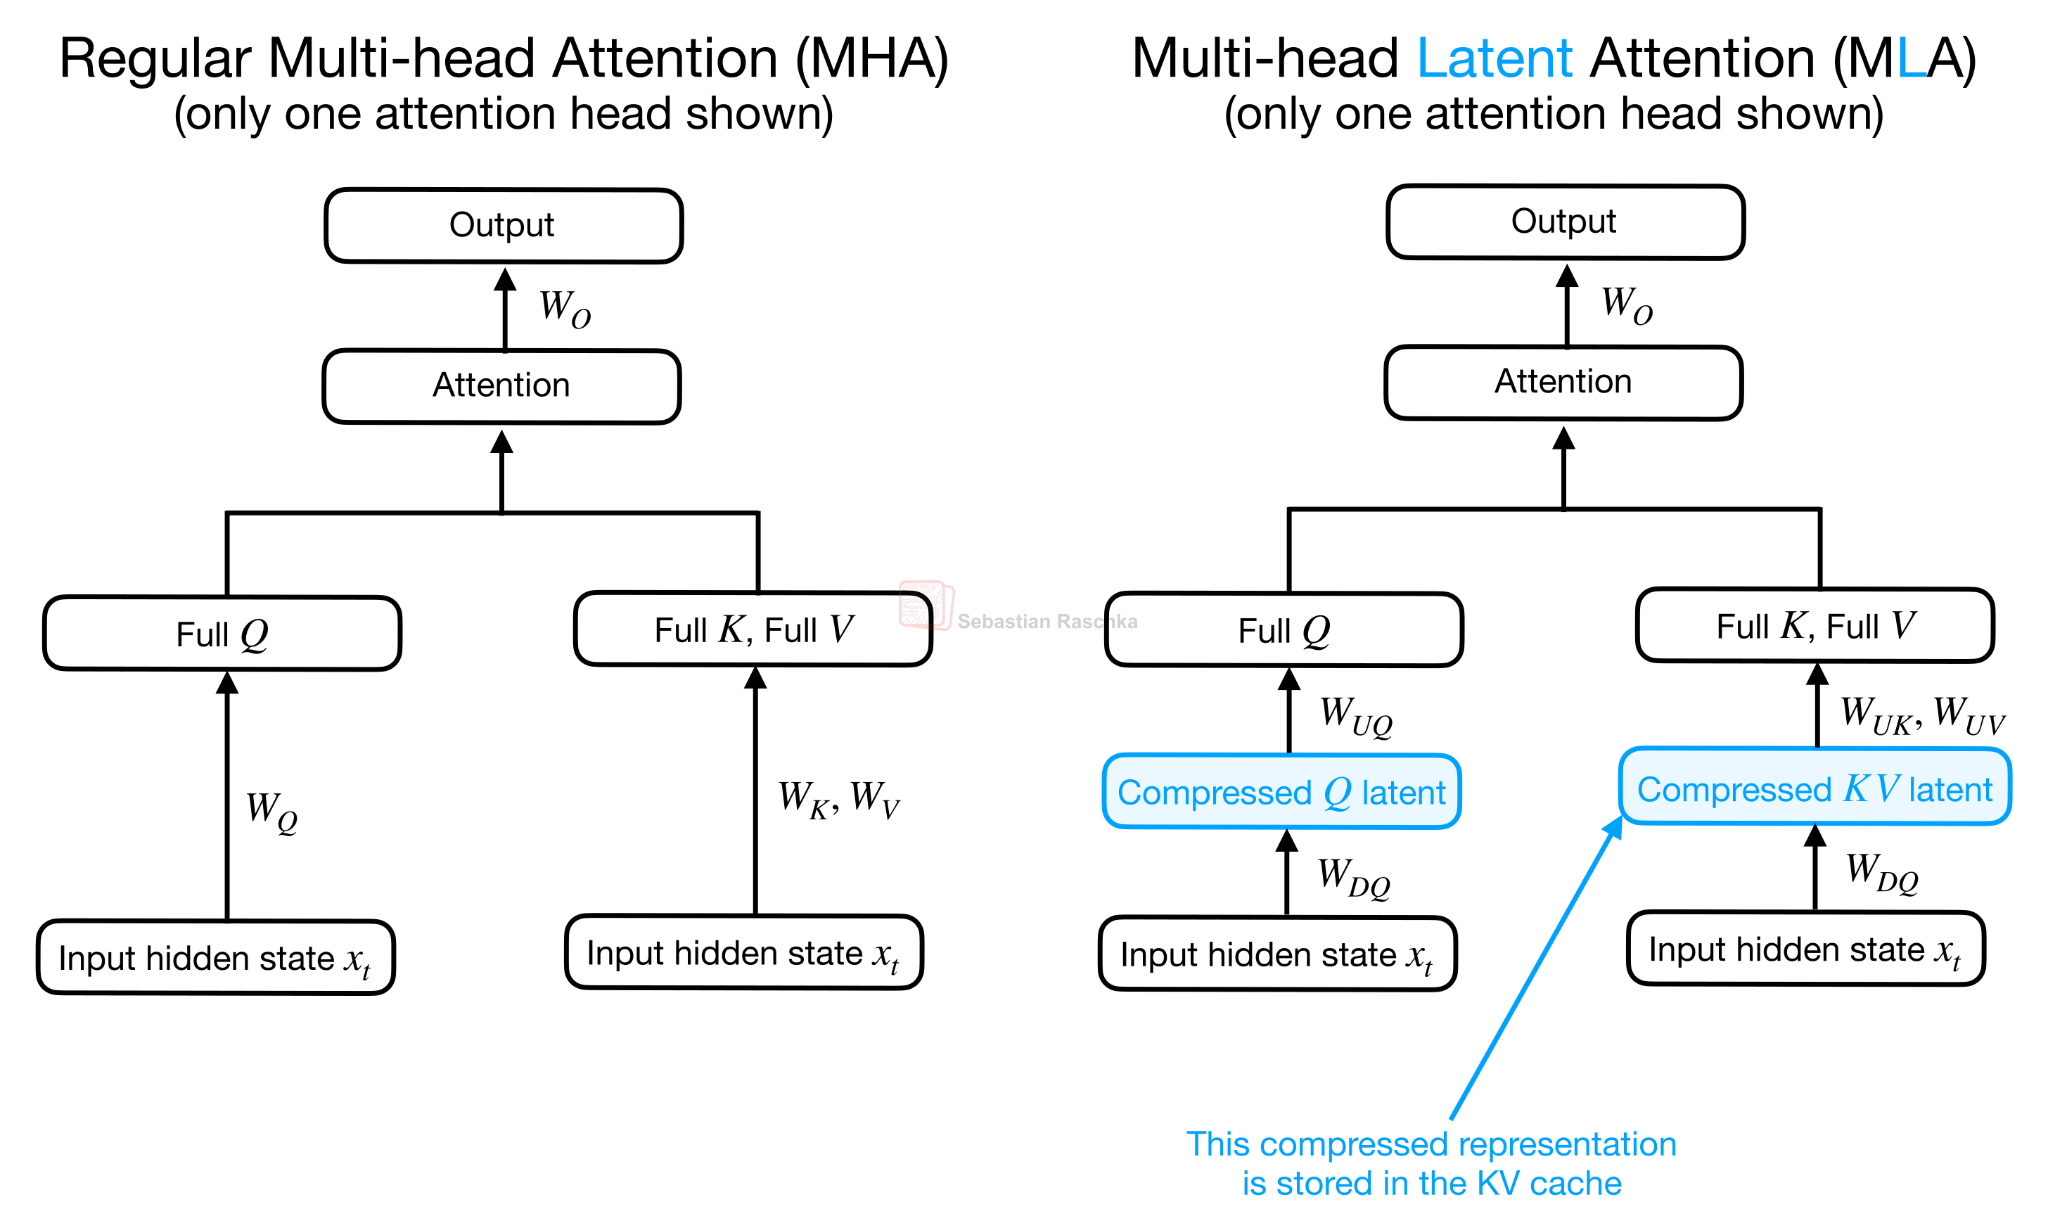
Recent Developments in LLM Architectures: KV Sharing, mHC, and ...
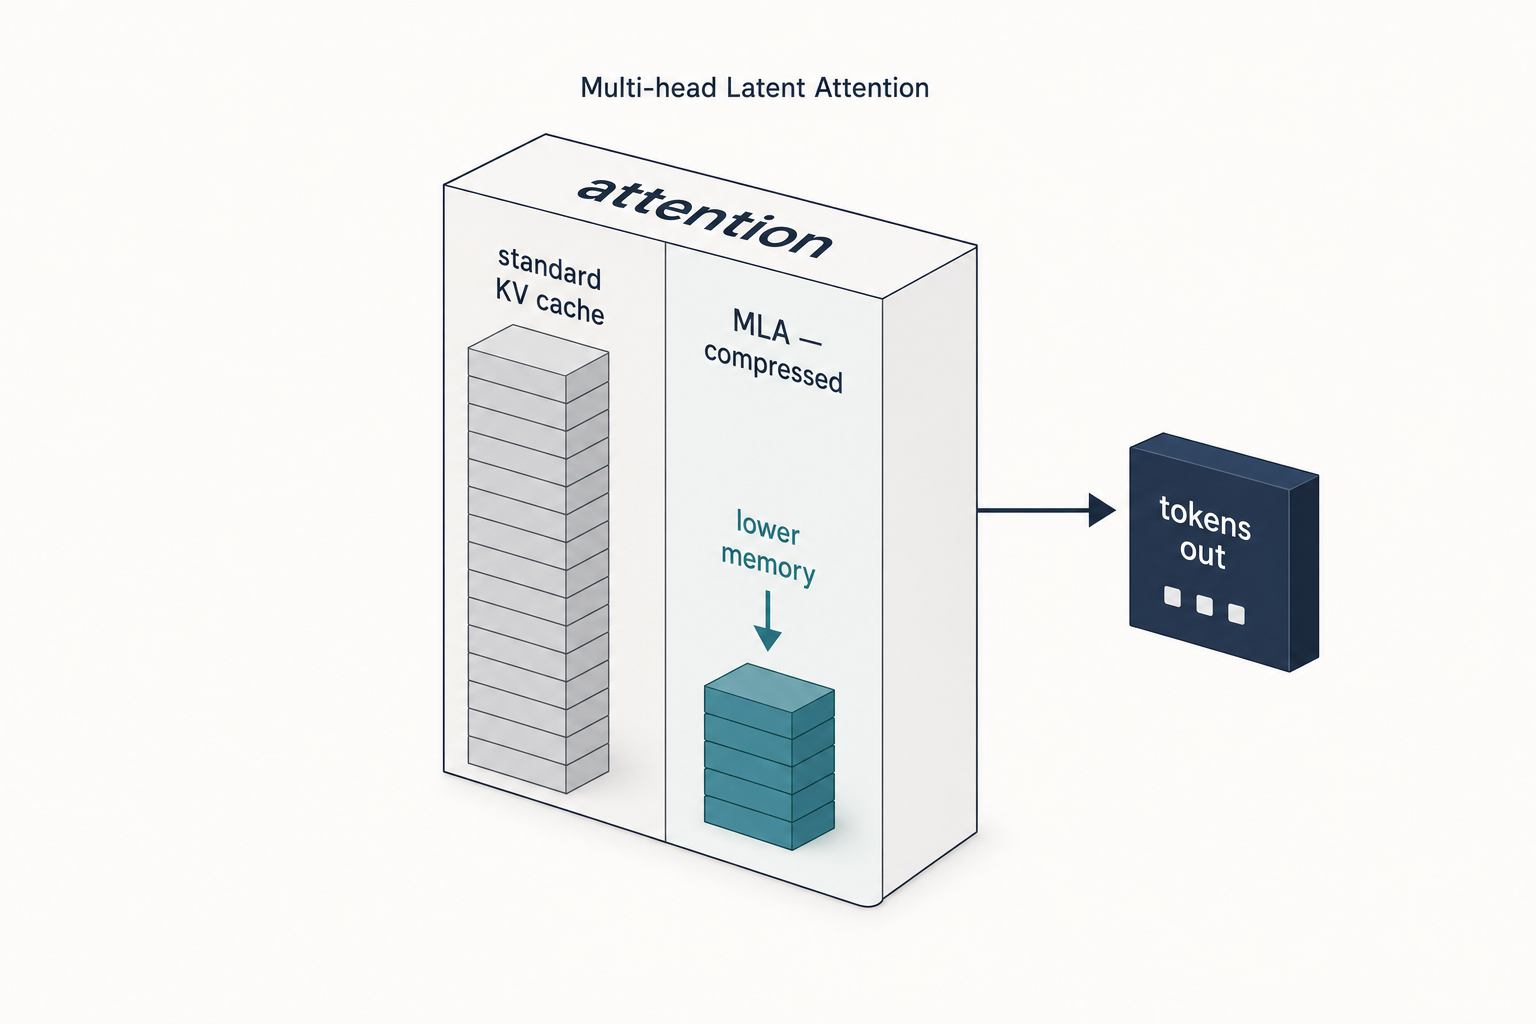
DeepSeek V2: Architecture, Benchmarks & Legacy