
Three Interpretations Of Deepseek V2s Multi Headed Latent Attention Layer

Three Interpretations of DeepSeek V2's Multi-headed Latent Attention Layer

Three Interpretations of DeepSeek V2's Multi-headed Latent Attention Layer

Under the Hood of DeepSeek V2: How Multihead Latent Attention is ...

[论文评述] Hardware-Centric Analysis of DeepSeek's Multi-Head Latent Attention

DeepSeek Multihead Latent Attention - YouTube

DeepSeek + SGLang: Multi-Head Latent Attention

Multi-Head Latent Attention and Multi-token Prediction in Deepseek v3 ...

DeepSeek + SGLang: Multi-Head Latent Attention

(PDF) Hardware-Centric Analysis of DeepSeek's Multi-Head Latent Attention

DeepSeek + SGLang: Multi-Head Latent Attention
Advertisement Space (300x250)

DeepSeek + SGLang: Multi-Head Latent Attention

Inside DeepSeek V3: Breaking Down Multi-Head Latent Attention (MLA ...
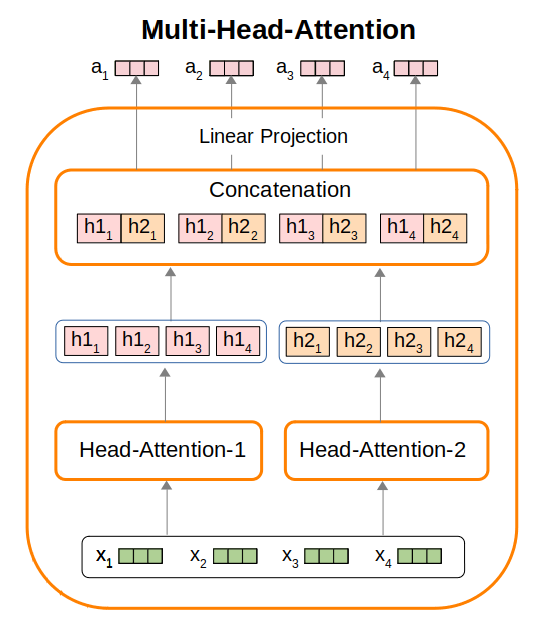
Multi Head Attention Layer | Keras Multihead Attention Mask – NDBD

Implementing DeepSeek-V2’s Multi-Head Latent Attention (MLA) from ...

DeepSeek Series: A Comprehensive Deep Dive into Multi-Head Latent ...

[논문 리뷰] Multi-head Temporal Latent Attention

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

Multi-Head Latent Attention (MLA) is a newly proposed technique for ...
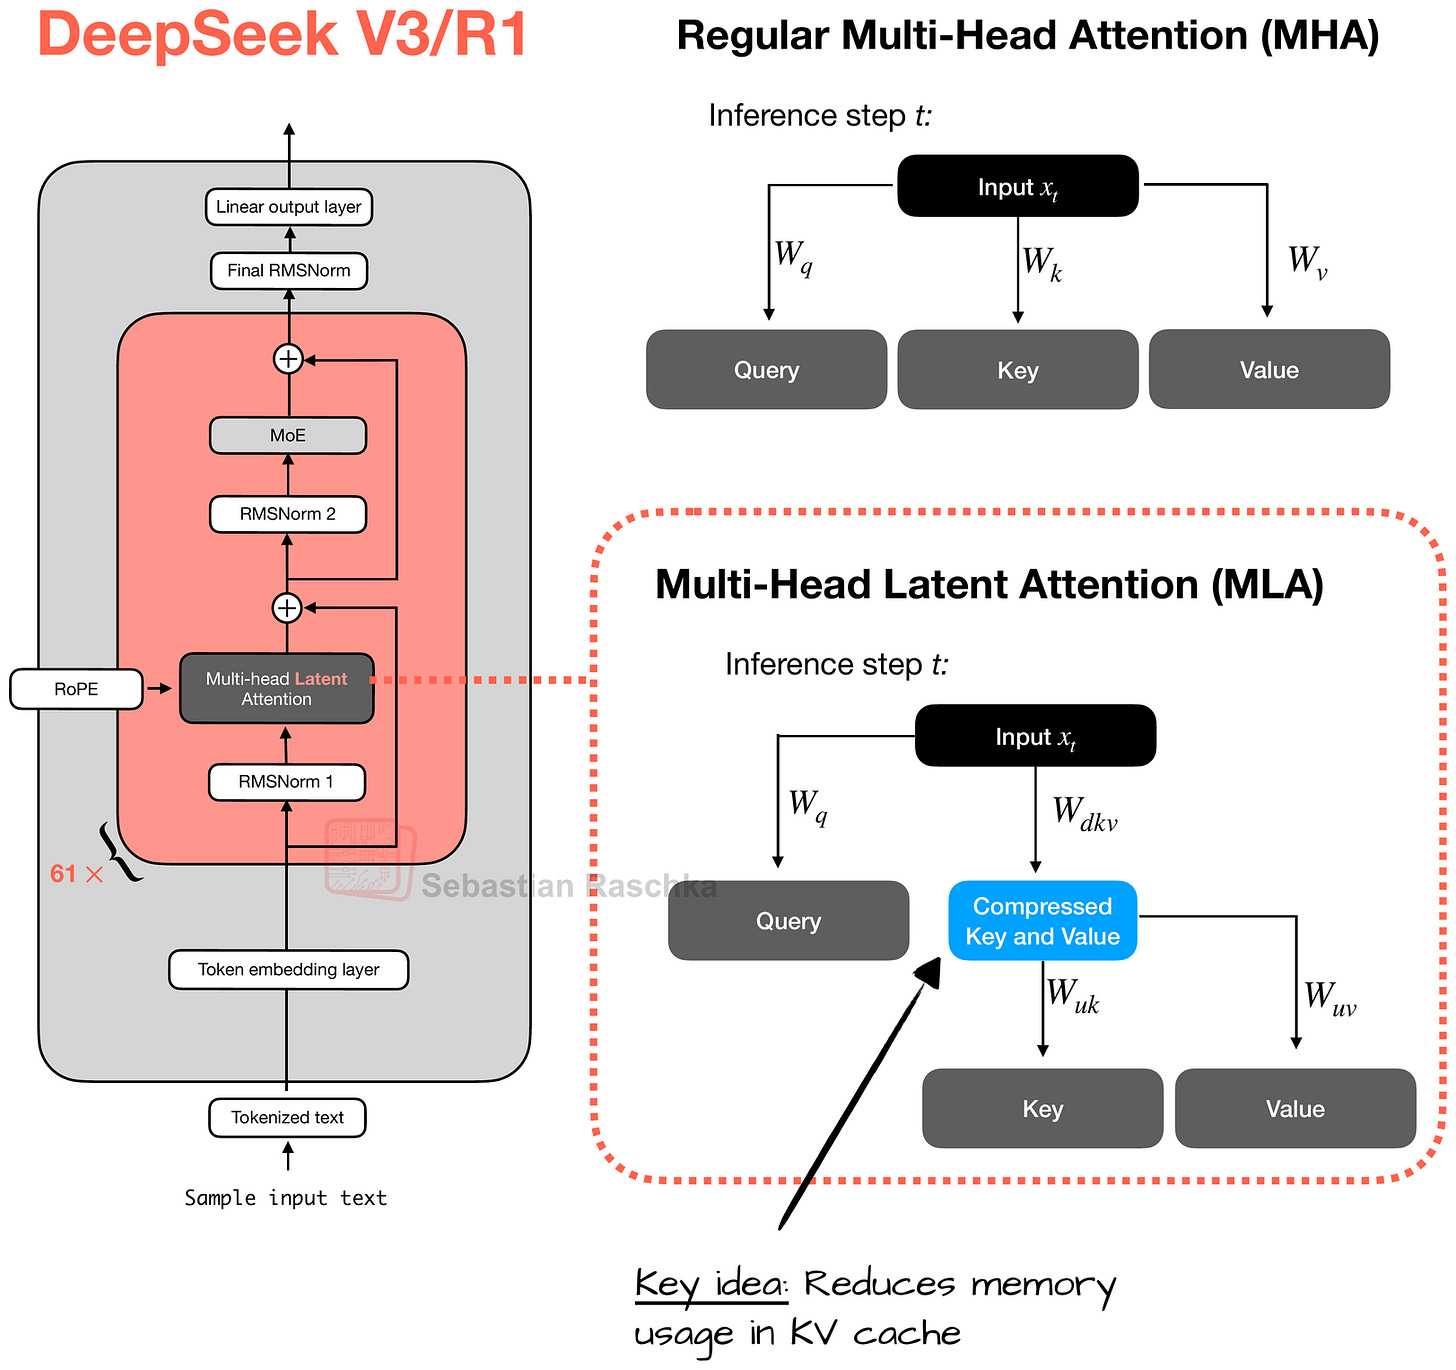
A Technical Tour of the DeepSeek Models from V3 to V3.2
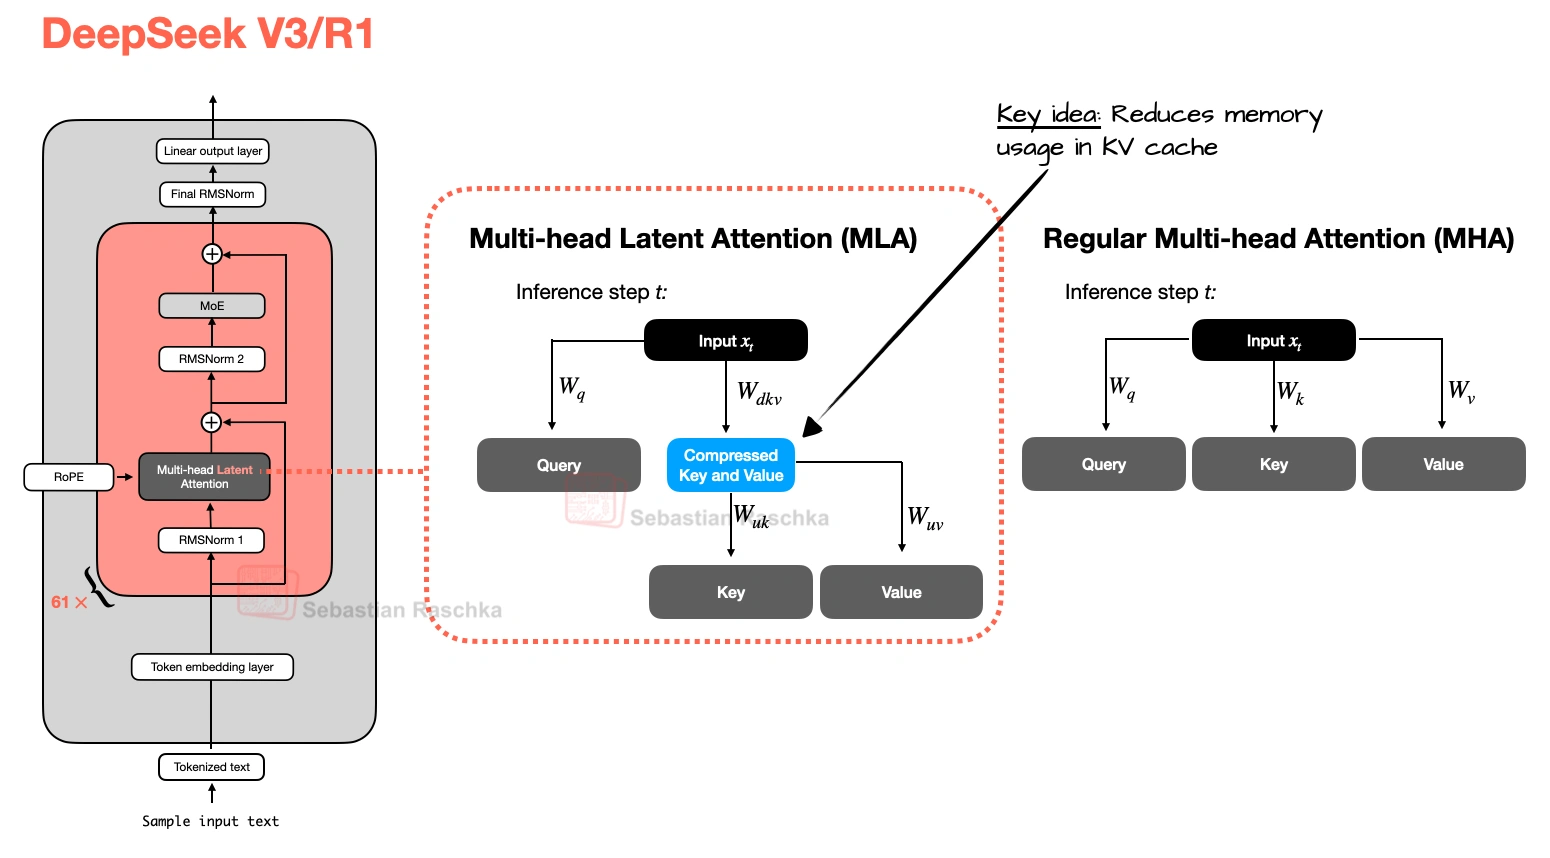
Multi-Head Latent Attention (MLA) | Sebastian Raschka, PhD
Advertisement Space (336x280)

DeepSeek Multi-Head Attention Explained - Part 1 - YouTube

Multi-Head Latent Attention – Latent KV-Cache (DeepSeek v3) – Lechuck Park

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science
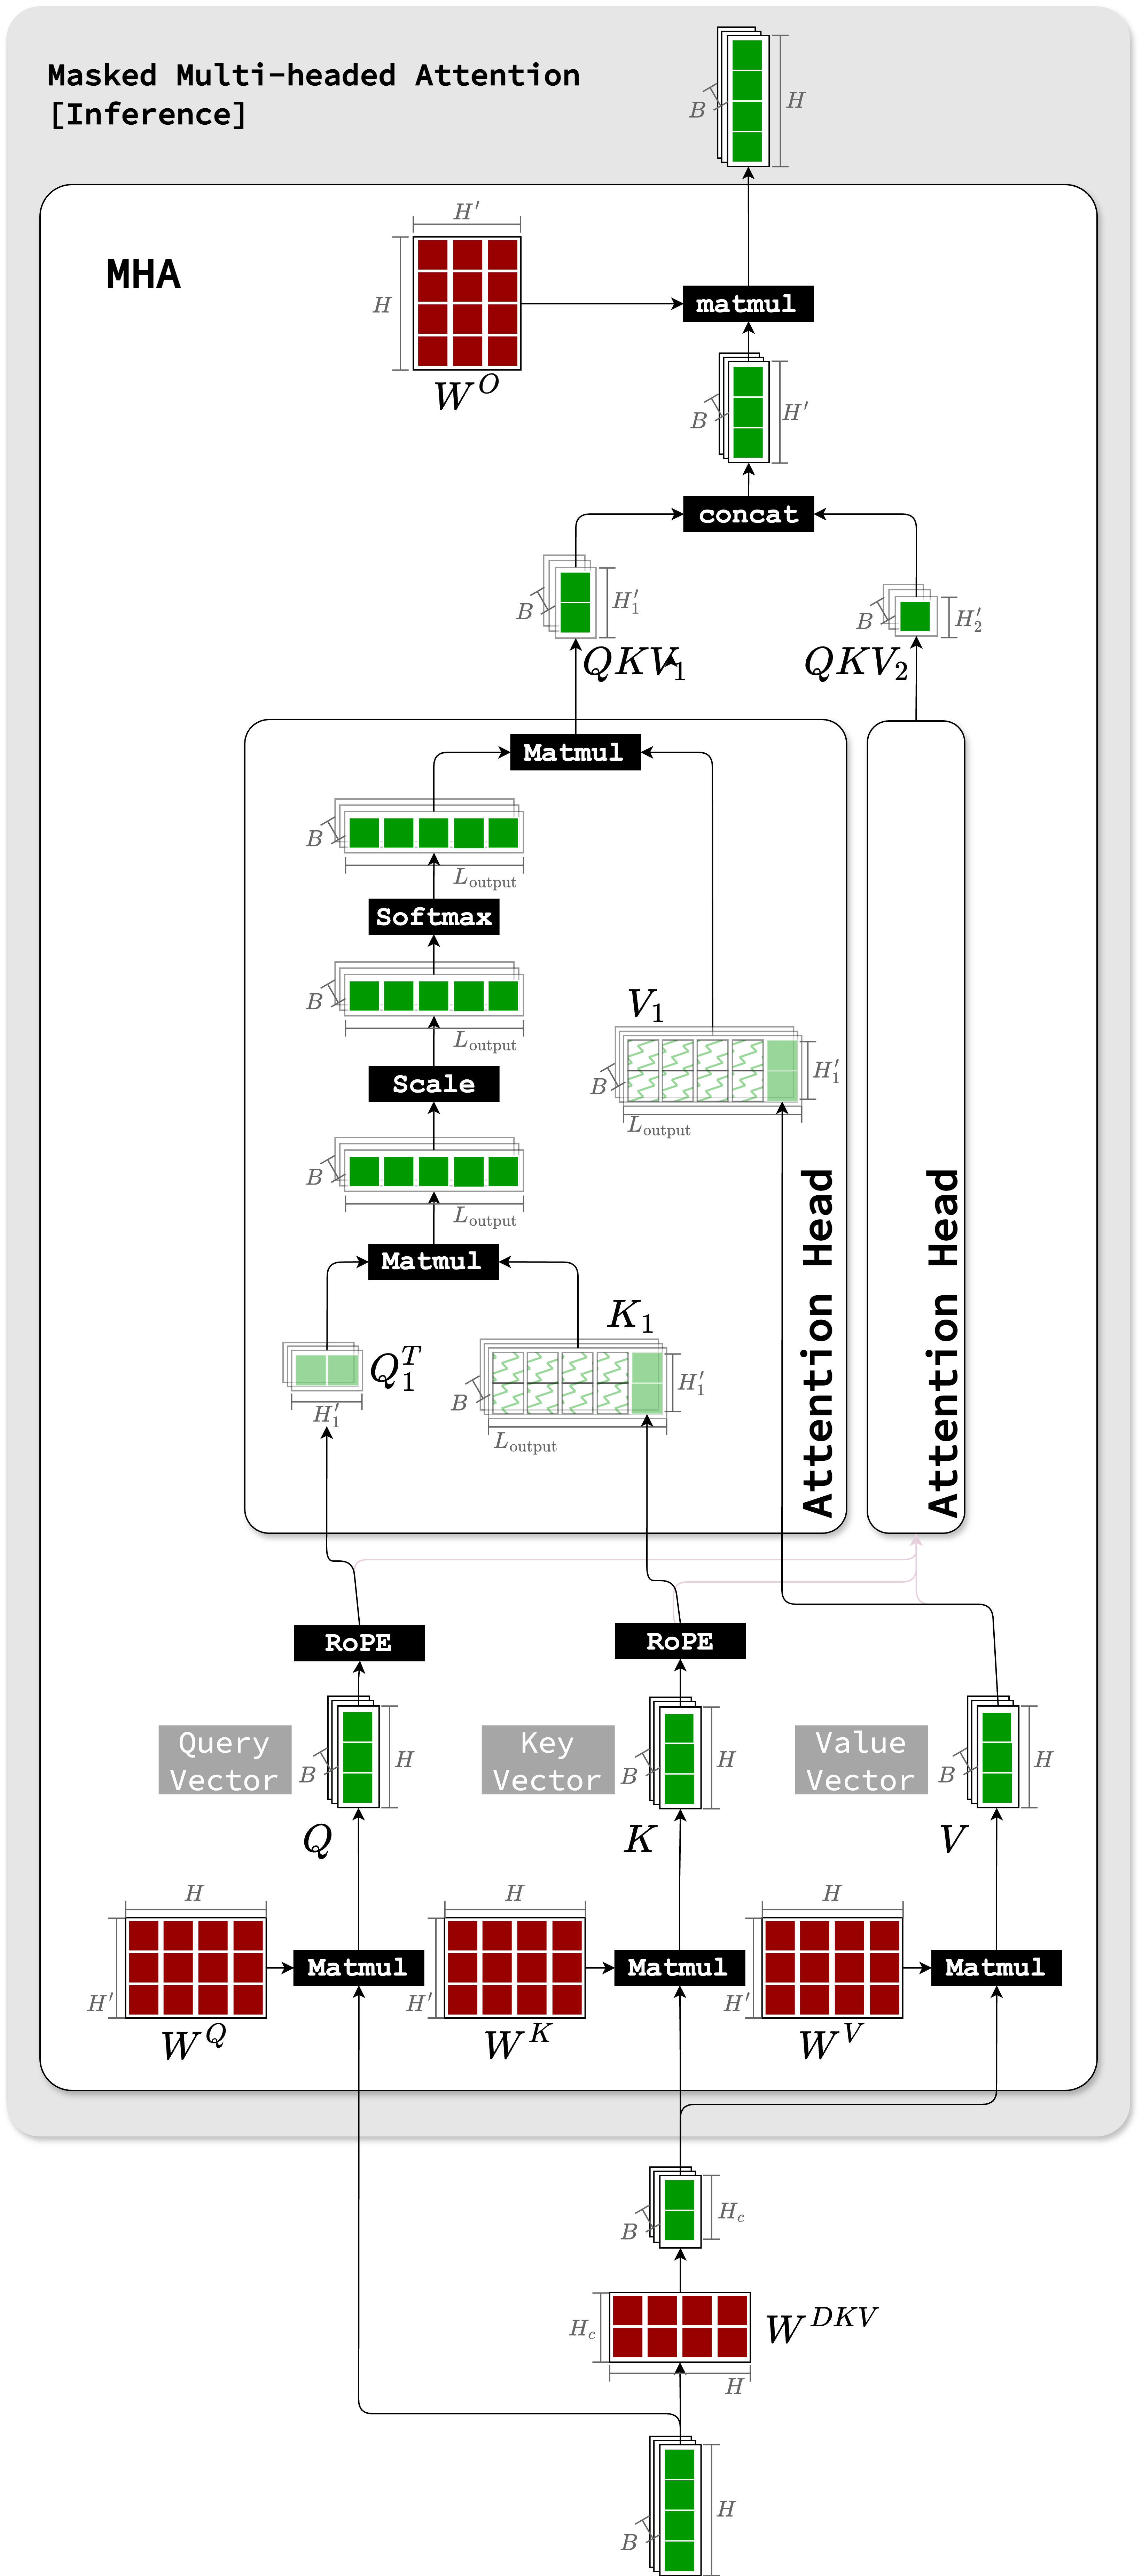
DeepSeek-v2 - Multi-head Latent Attention
Build DeepSeek-V3: Multi-Head Latent Attention (MLA) Architecture ...

Multi-Head Latent Attention: DeepSeek V2/V3 Engineering View | Xu'Blog

Implementing DeepSeek-V2’s Multi-Head Latent Attention (MLA) from ...

Multi-Head Latent Attention Explained Simply - YouTube

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

Paper Review: Multi-Headed Latent Attention (MLA) in DeepSeek-V2 – The ...
Advertisement Space (336x280)

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

How DeepSeek's Multi-Head Latent Attention Changed the Game - YouTube

DeepSeek 注意力之 MLA(Multi-Head Latent Attention) - 知乎

Attention Evolved: How Multi-Head Latent Attention Works | by Karl ...
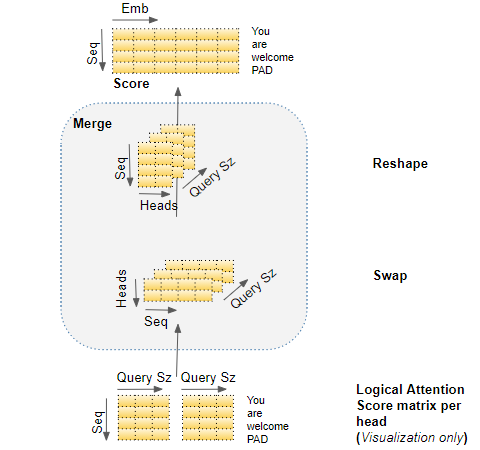
Deepseek 이해하기 (1) - MLA (Multi-Head Latent Attention)
提升推理效率的新突破:Multi-Head Latent Attention (MLA) 在 DeepSeek-V2 中的應用