
Deepseek Sglang Multi Head Latent Attention

Three Interpretations of DeepSeek V2's Multi-headed Latent Attention Layer

DeepSeek + SGLang: Multi-Head Latent Attention

Three Interpretations of DeepSeek V2's Multi-headed Latent Attention Layer

DeepSeek Multihead Latent Attention - YouTube
DeepSeek + SGLang: Multi-Head Latent Attention — Blog — Verda (formerly ...

DeepSeek + SGLang: Multi-Head Latent Attention

DeepSeek + SGLang: Multi-Head Latent Attention

Inside DeepSeek V3: Breaking Down Multi-Head Latent Attention (MLA ...
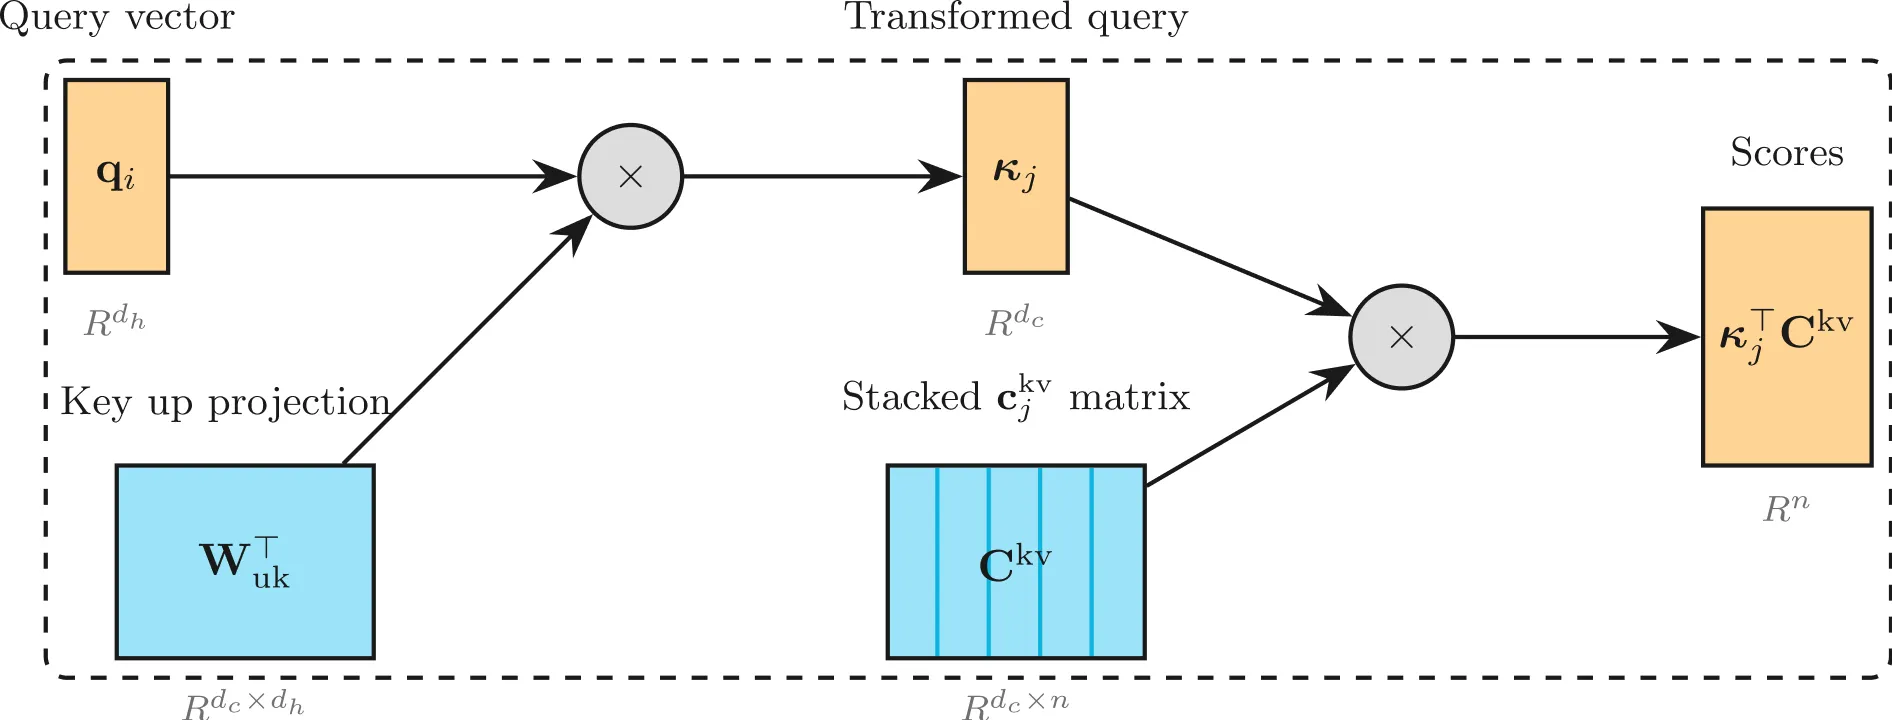
DeepSeek + SGLang: Multi-Head Latent Attention

DeepSeek + SGLang: Multi-Head Latent Attention
Advertisement Space (300x250)

Multi-Head Latent Attention and Multi-token Prediction in Deepseek v3 ...

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

[论文评述] Hardware-Centric Analysis of DeepSeek's Multi-Head Latent Attention

Multi-Head Latent Attention (MLA) 详细介绍(来自Deepseek V3的回答) - 知乎

DeepSeek Series: A Comprehensive Deep Dive into Multi-Head Latent ...

Implementing DeepSeek-V2’s Multi-Head Latent Attention (MLA) from ...

DeepSeek Multi-Head Attention Explained - Part 1 - YouTube
Build DeepSeek-V3: Multi-Head Latent Attention (MLA) Architecture ...

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

How DeepSeek's Multi-Head Latent Attention Changed the Game - YouTube
Advertisement Space (336x280)

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

SGLang v0.3 Release: 7x Faster DeepSeek MLA, 1.5x Faster torch.compile ...

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

Multi-Head Latent Attention – Latent KV-Cache (DeepSeek v3) – Lechuck Park
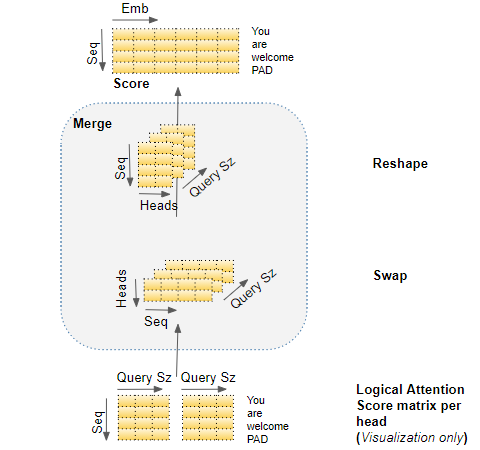
Deepseek 이해하기 (1) - MLA (Multi-Head Latent Attention)
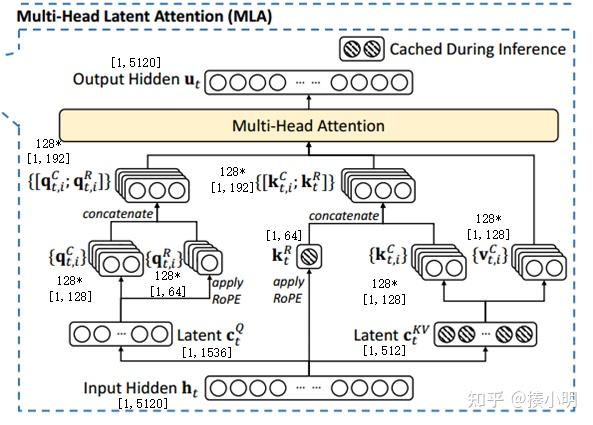
DeepSeek MLA (Multi-head latent attention)的attention流程 - 知乎

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

DeepSeek 注意力之 MLA(Multi-Head Latent Attention) - 知乎

Multi-Head Latent Attention Explained Simply - YouTube
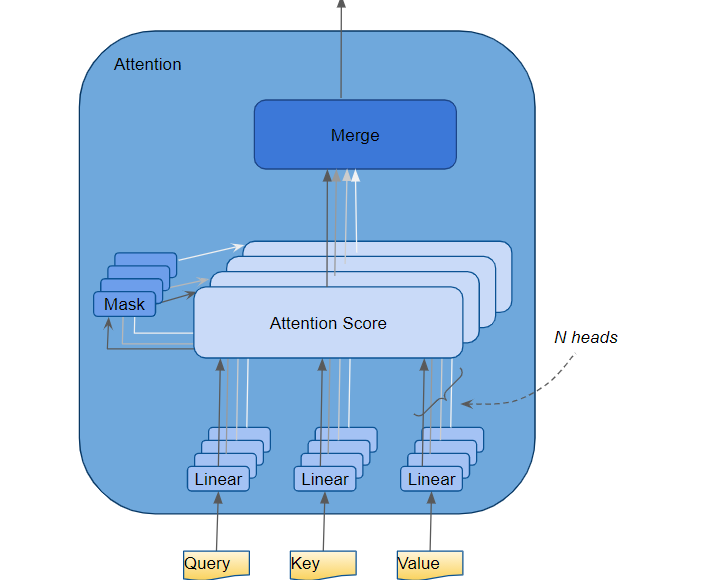
Deepseek 이해하기 (1) - MLA (Multi-Head Latent Attention)
Advertisement Space (336x280)

Multi-Head Latent Attention (MLA) is a newly proposed technique for ...

Implementing DeepSeek-V2’s Multi-Head Latent Attention (MLA) from ...

DeepSeek Launches FlashMLA

A Technical Tour of the DeepSeek Models from V3 to V3.2

资讯 | Deepseek-V2多头潜在注意力(Multi-head Latent Attention)原理及PyTorch实现 - 智源社区
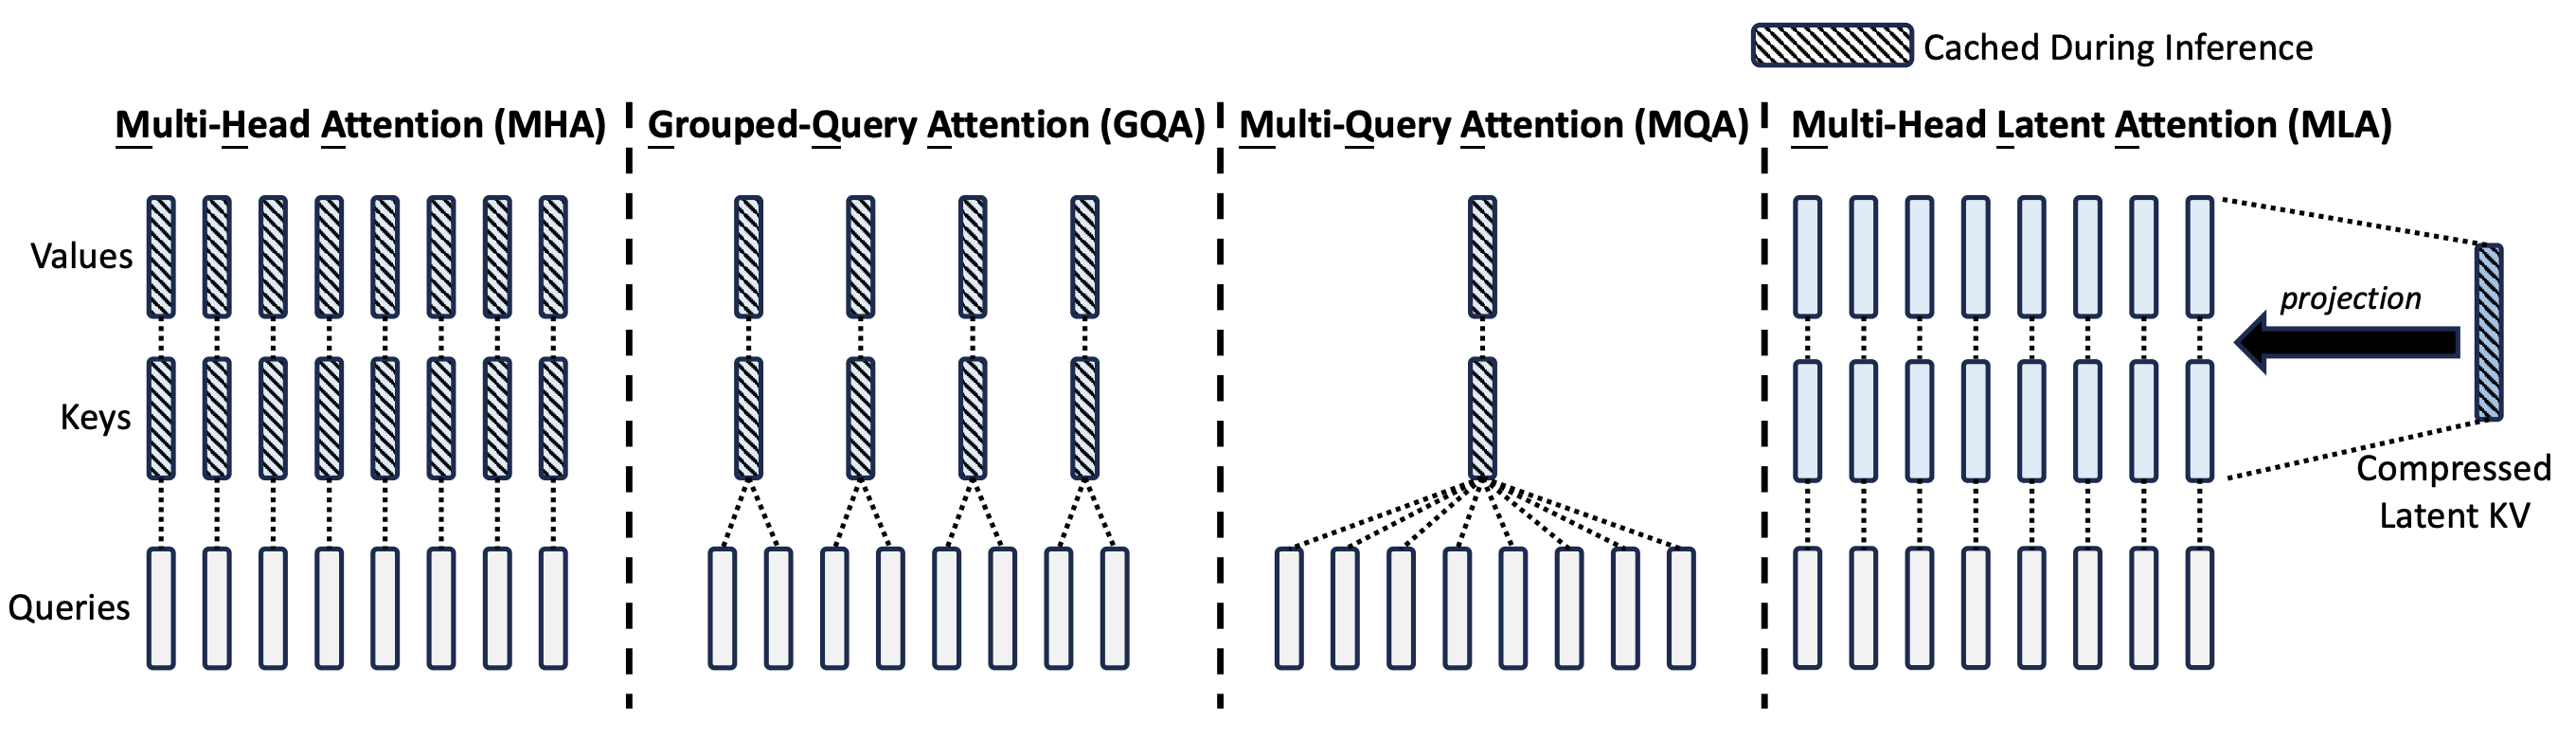
How has DeepSeek improved the Transformer architecture? | Epoch AI