
When Benchmarks Talk Re Evaluating Code Llms With Interactive

When Benchmarks Talk: Re-Evaluating Code LLMs with Interactive Feedback ...

[논문 리뷰] When Benchmarks Talk: Re-Evaluating Code LLMs with Interactive ...
When Benchmarks Talk: Re-Evaluating Code LLMs with Interactive Feedback ...

Evaluating LLMs with Benchmarks | AI Tutorial | Next Electronics

tinyBenchmarks: evaluating LLMs with fewer examples | AI Research Paper ...
Evaluating LLMs for Production Beyond Benchmarks

Ada-LEval: Evaluating long-context LLMs with length-adaptable ...

AI Code Generation: New DevQualityEval Benchmark Reveals Which LLMs ...

ToolSandbox: Realistic Interactive Benchmark for Evaluating LLM Tool ...

GBQA: A Game Benchmark for Evaluating LLMs as Quality Assurance ...
Advertisement Space (300x250)
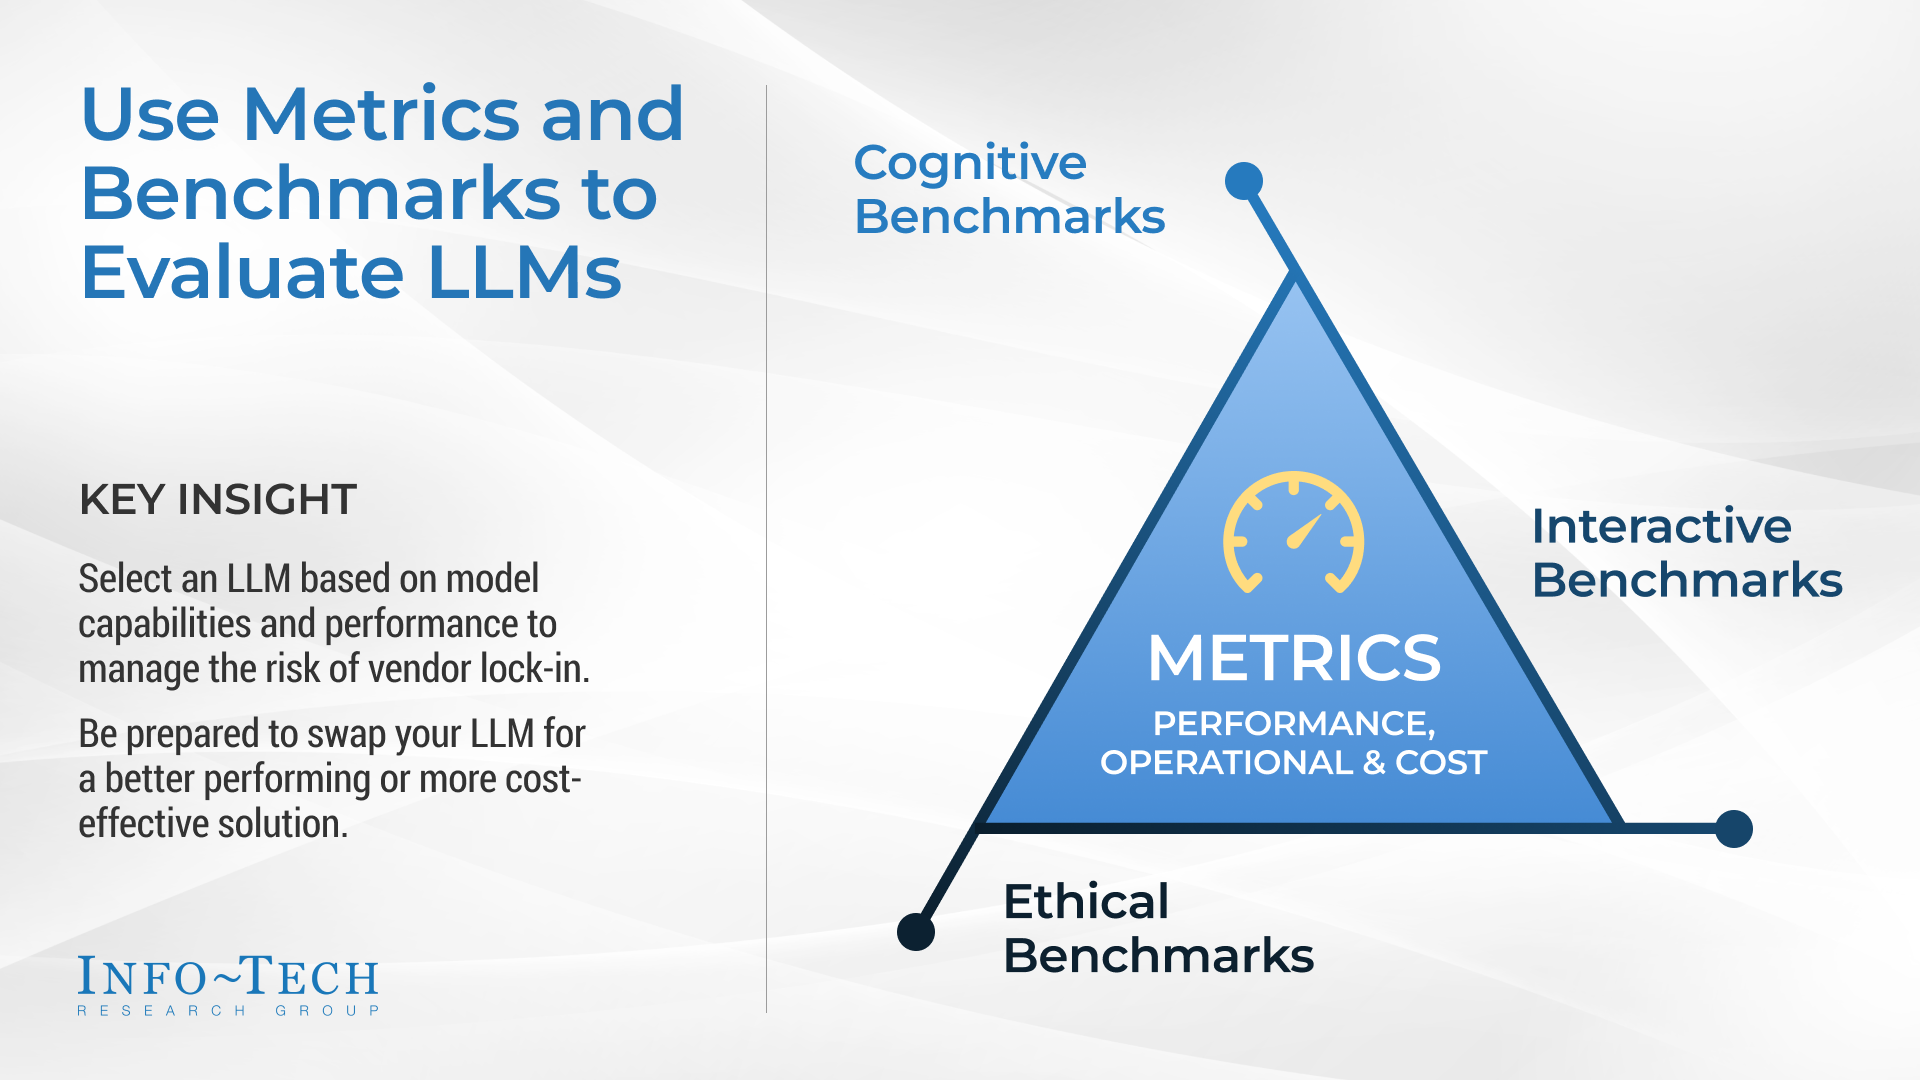
Leverage Metrics and Benchmarks to Evaluate LLMs | Info-Tech Research Group
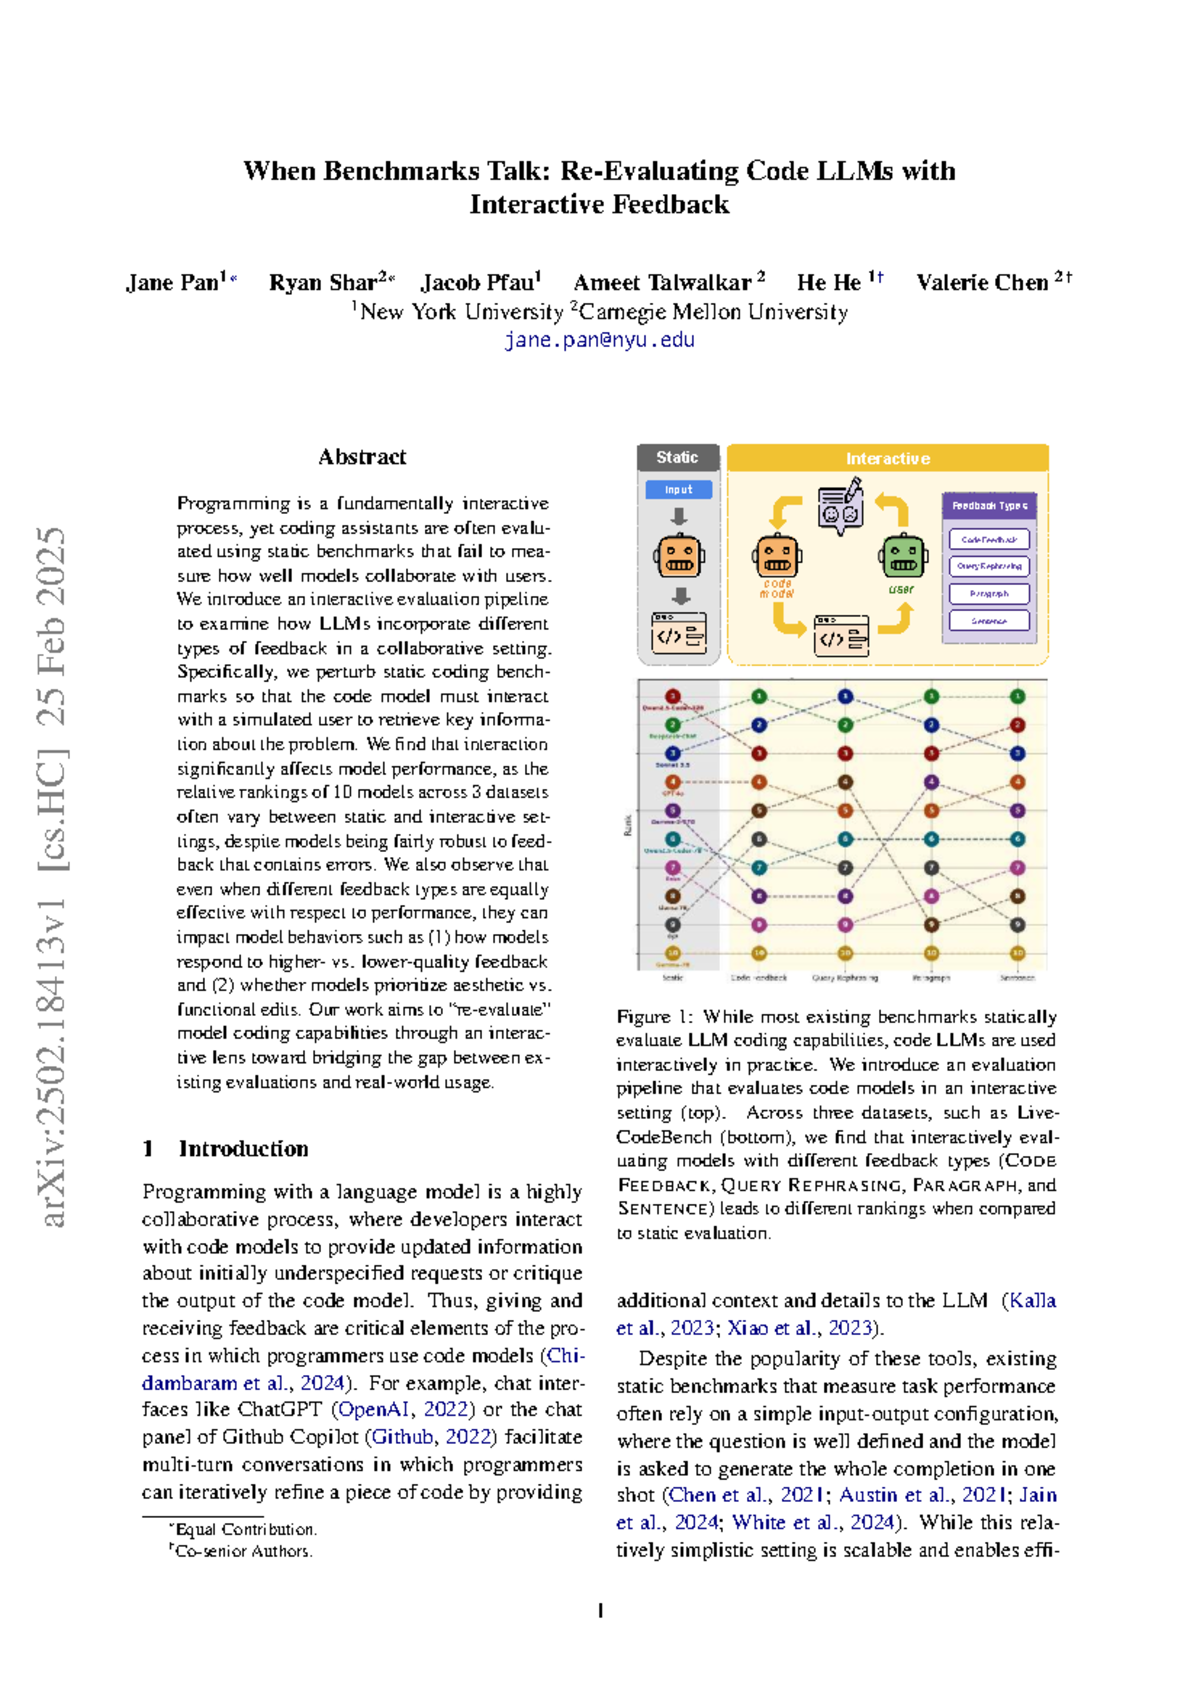
Interactive Evaluation of Code LLMs: Feedback Types and Performance (CS ...
AQA-Bench: An Interactive Benchmark for Evaluating LLMs' Sequential ...
How to Test and Benchmark Multiple LLMs Without Rewriting Your Code ...

(PDF) Re-Evaluating Code LLM Benchmarks Under Semantic Mutation
Evaluating LLM Systems: Metrics & Benchmarks 2026
HumanEval Benchmark: Evaluating LLM Code Generation Capability

Evaluating LLM Capabilities: Benchmarks Guide | PDF | Applied ...

[论文评述] HLS-Eval: A Benchmark and Framework for Evaluating LLMs on High ...

CTIBench - A Benchmark For Evaluating LLMs in Cyber Threat ...
Advertisement Space (336x280)

Announcing UA-Code-Bench: a New Benchmark for Evaluating LLMs on ...

Evaluating and Achieving Controllable Code Completion in Code LLM | AI ...
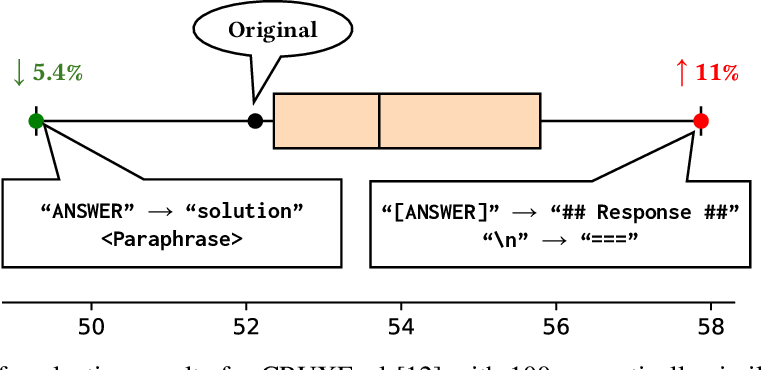
Figure 1 from Re-Evaluating Code LLM Benchmarks Under Semantic Mutation ...
How to Evaluate LLMs for Enterprise Use: Beyond Benchmarks | MeshWorld
GBQA: A Game Benchmark for Evaluating LLMs as Quality Assurance ...
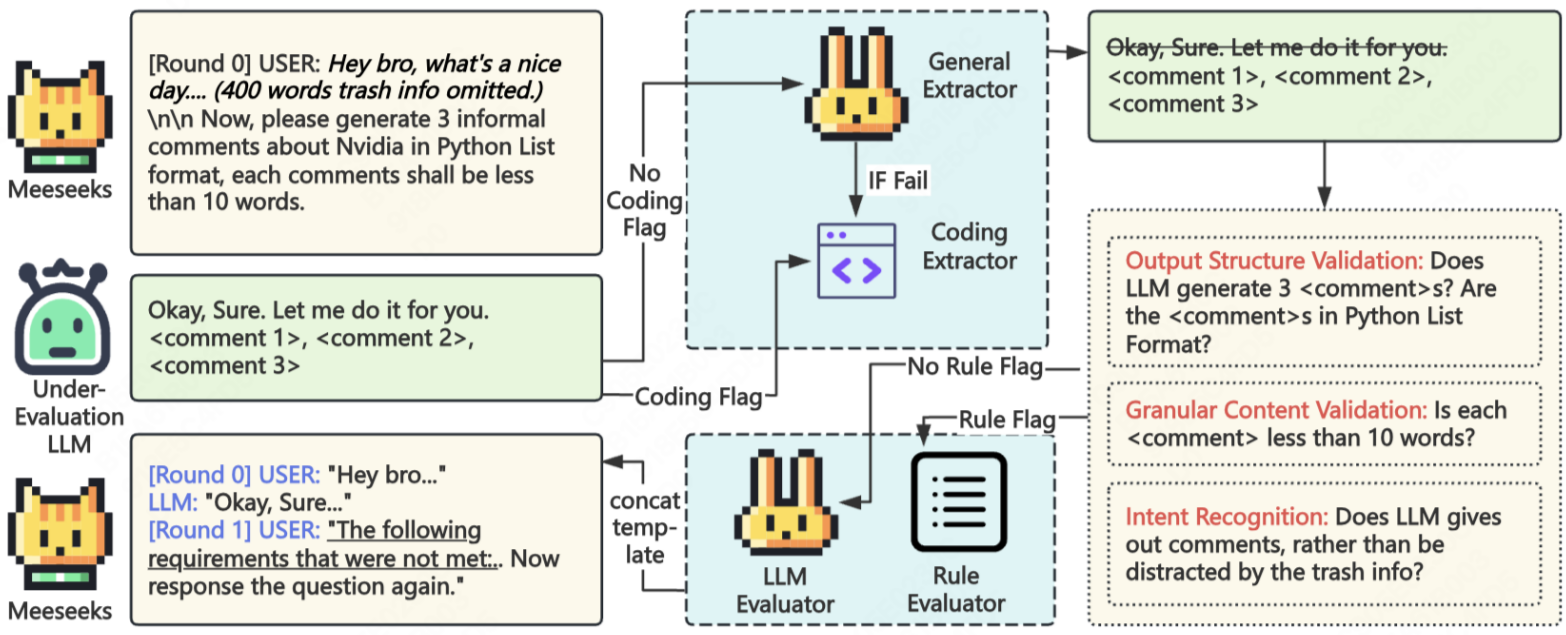
[论文评述] Meeseeks: An Iterative Benchmark Evaluating LLMs Multi-Turn ...

Evaluating Modern LLMs for General Reasoning, Coding, and Math
LLM Code Review Leaderboard - Benchmarks and Rankings | Awesome Agents

From Tools to Teammates: Evaluating LLMs in Multi-Session Coding ...

Paper page - CTIBench: A Benchmark for Evaluating LLMs in Cyber Threat ...
Advertisement Space (336x280)

An introduction to code LLM benchmarks for software engineers ...

(PDF) FrontendBench: A Benchmark for Evaluating LLMs on Front-End ...

Paper page - GBQA: A Game Benchmark for Evaluating LLMs as Quality ...

Meet 'BALROG': A Novel AI Benchmark Evaluating Agentic LLM and VLM ...
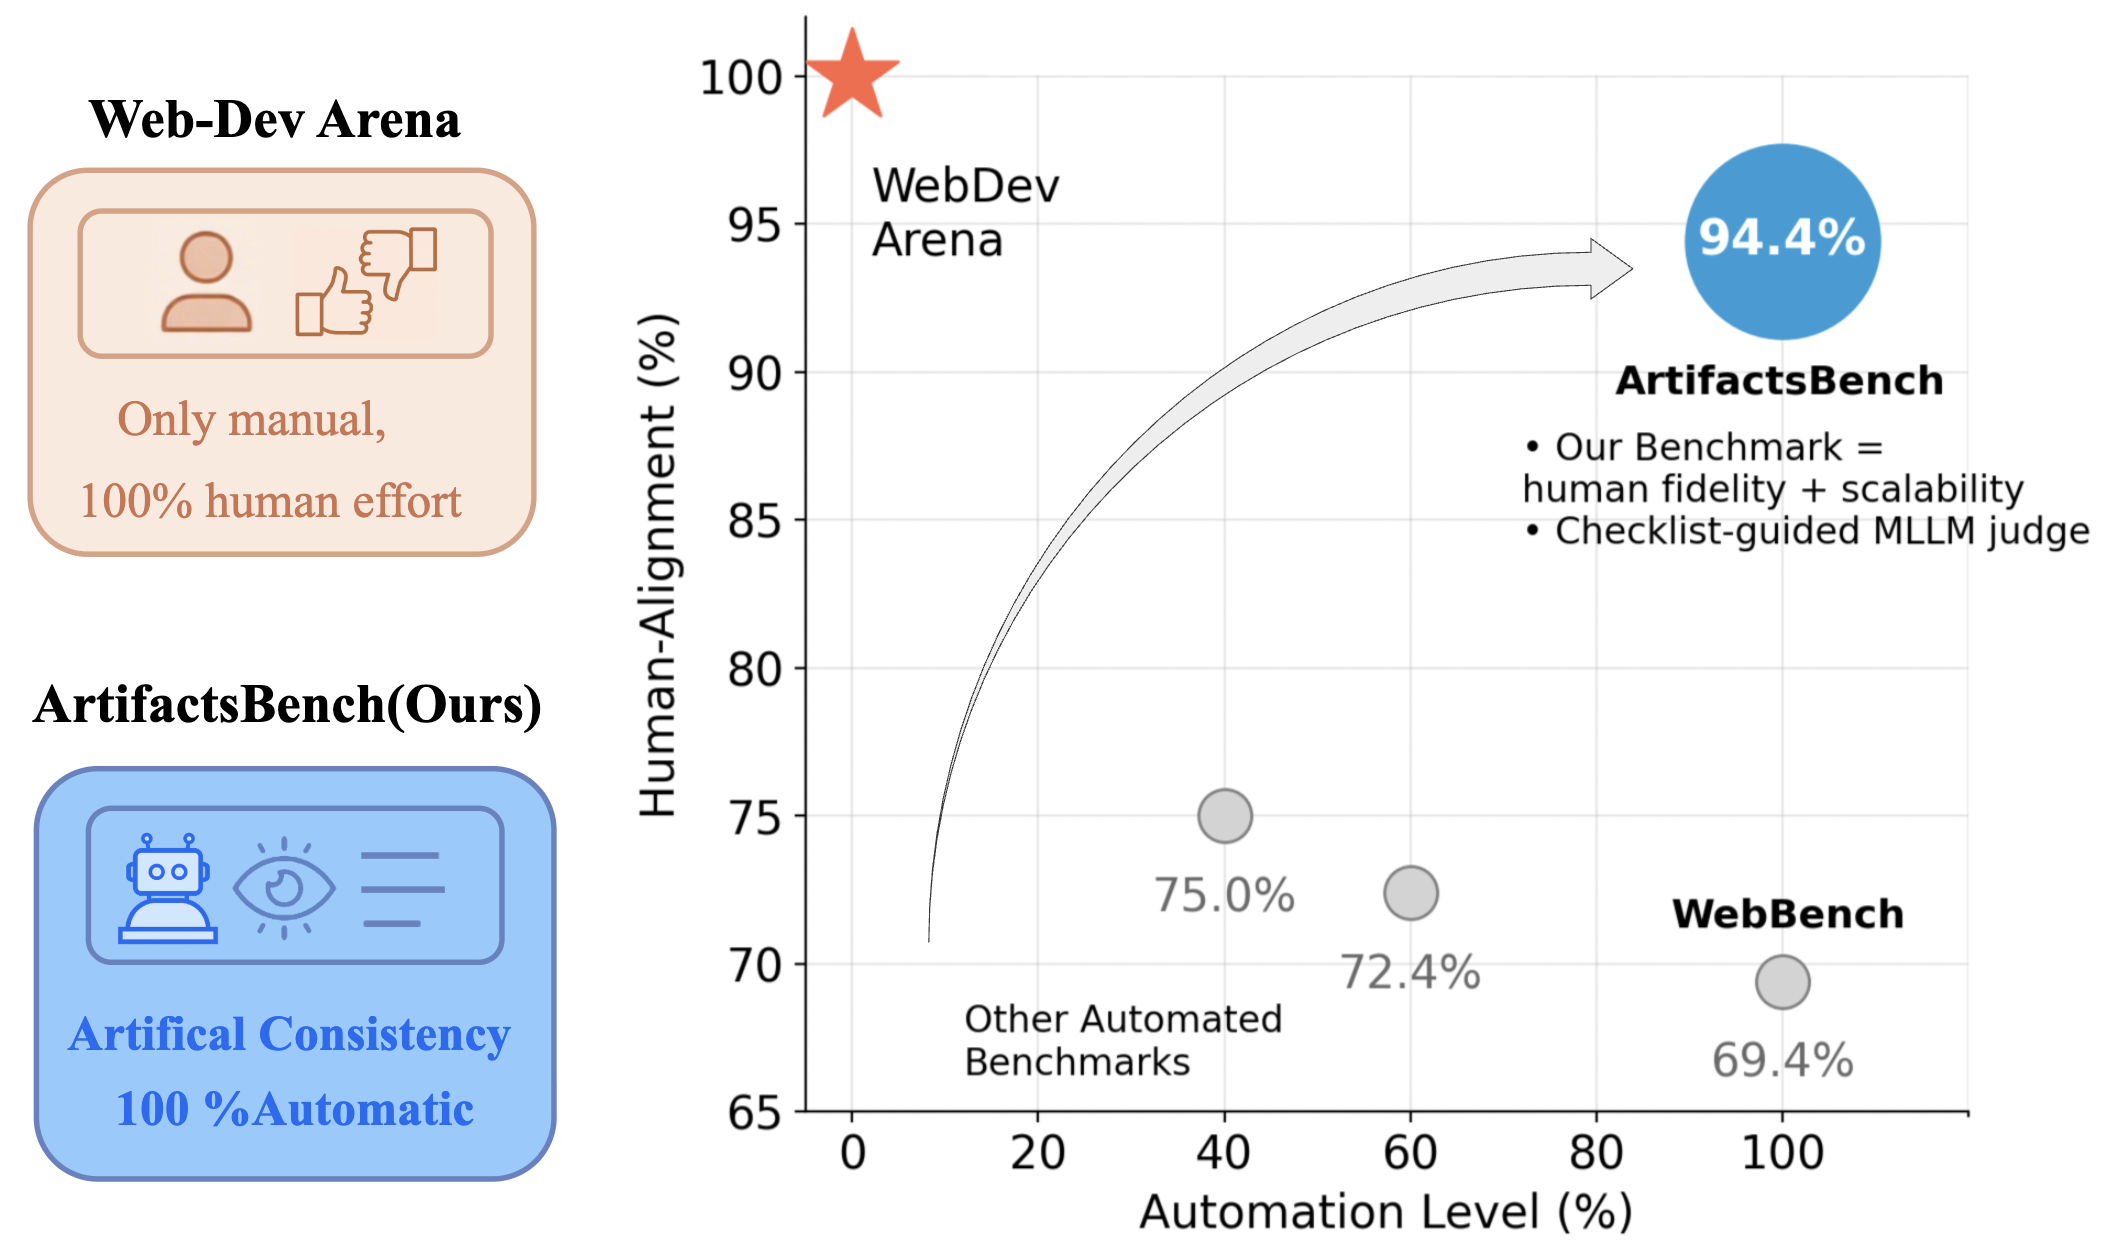
ArtifactsBench: Bridging the Visual-Interactive Gap in LLM Code ...

Dynamic Benchmark Construction for Evaluating Large Language Models on ...