
13 Llm Alignment And Preference Learning Llm Foundations
13. LLM Alignment and Preference Learning — LLM Foundations
13. LLM Alignment and Preference Learning — LLM Foundations
13. LLM Alignment and Preference Learning — LLM Foundations
13. LLM Alignment and Preference Learning — LLM Foundations
13. LLM Alignment and Preference Learning — LLM Foundations
13. LLM Alignment and Preference Learning — LLM Foundations
13. LLM Alignment and Preference Learning — LLM Foundations
13. LLM Alignment and Preference Learning — LLM Foundations
Reinforcement Learning for LLM Alignment and Reasoning [Video]

Learning to Paraphrase for Alignment with LLM Preference - ACL Anthology
Advertisement Space (300x250)

(PDF) Adversarial Preference Learning for Robust LLM Alignment
Nearly Optimal Active Preference Learning and Its Application to LLM ...
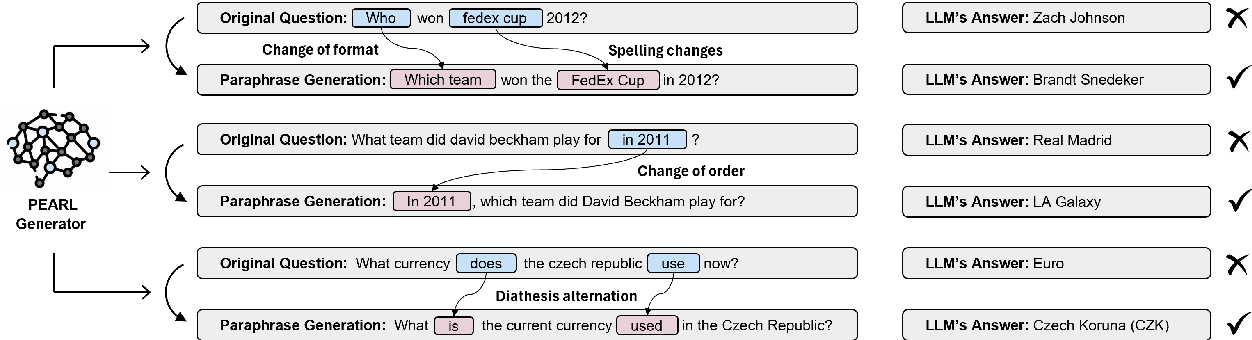
Figure 1 from Learning to Paraphrase for Alignment with LLM Preference ...

Adversarial Preference Learning for Robust LLM Alignment - ACL Anthology
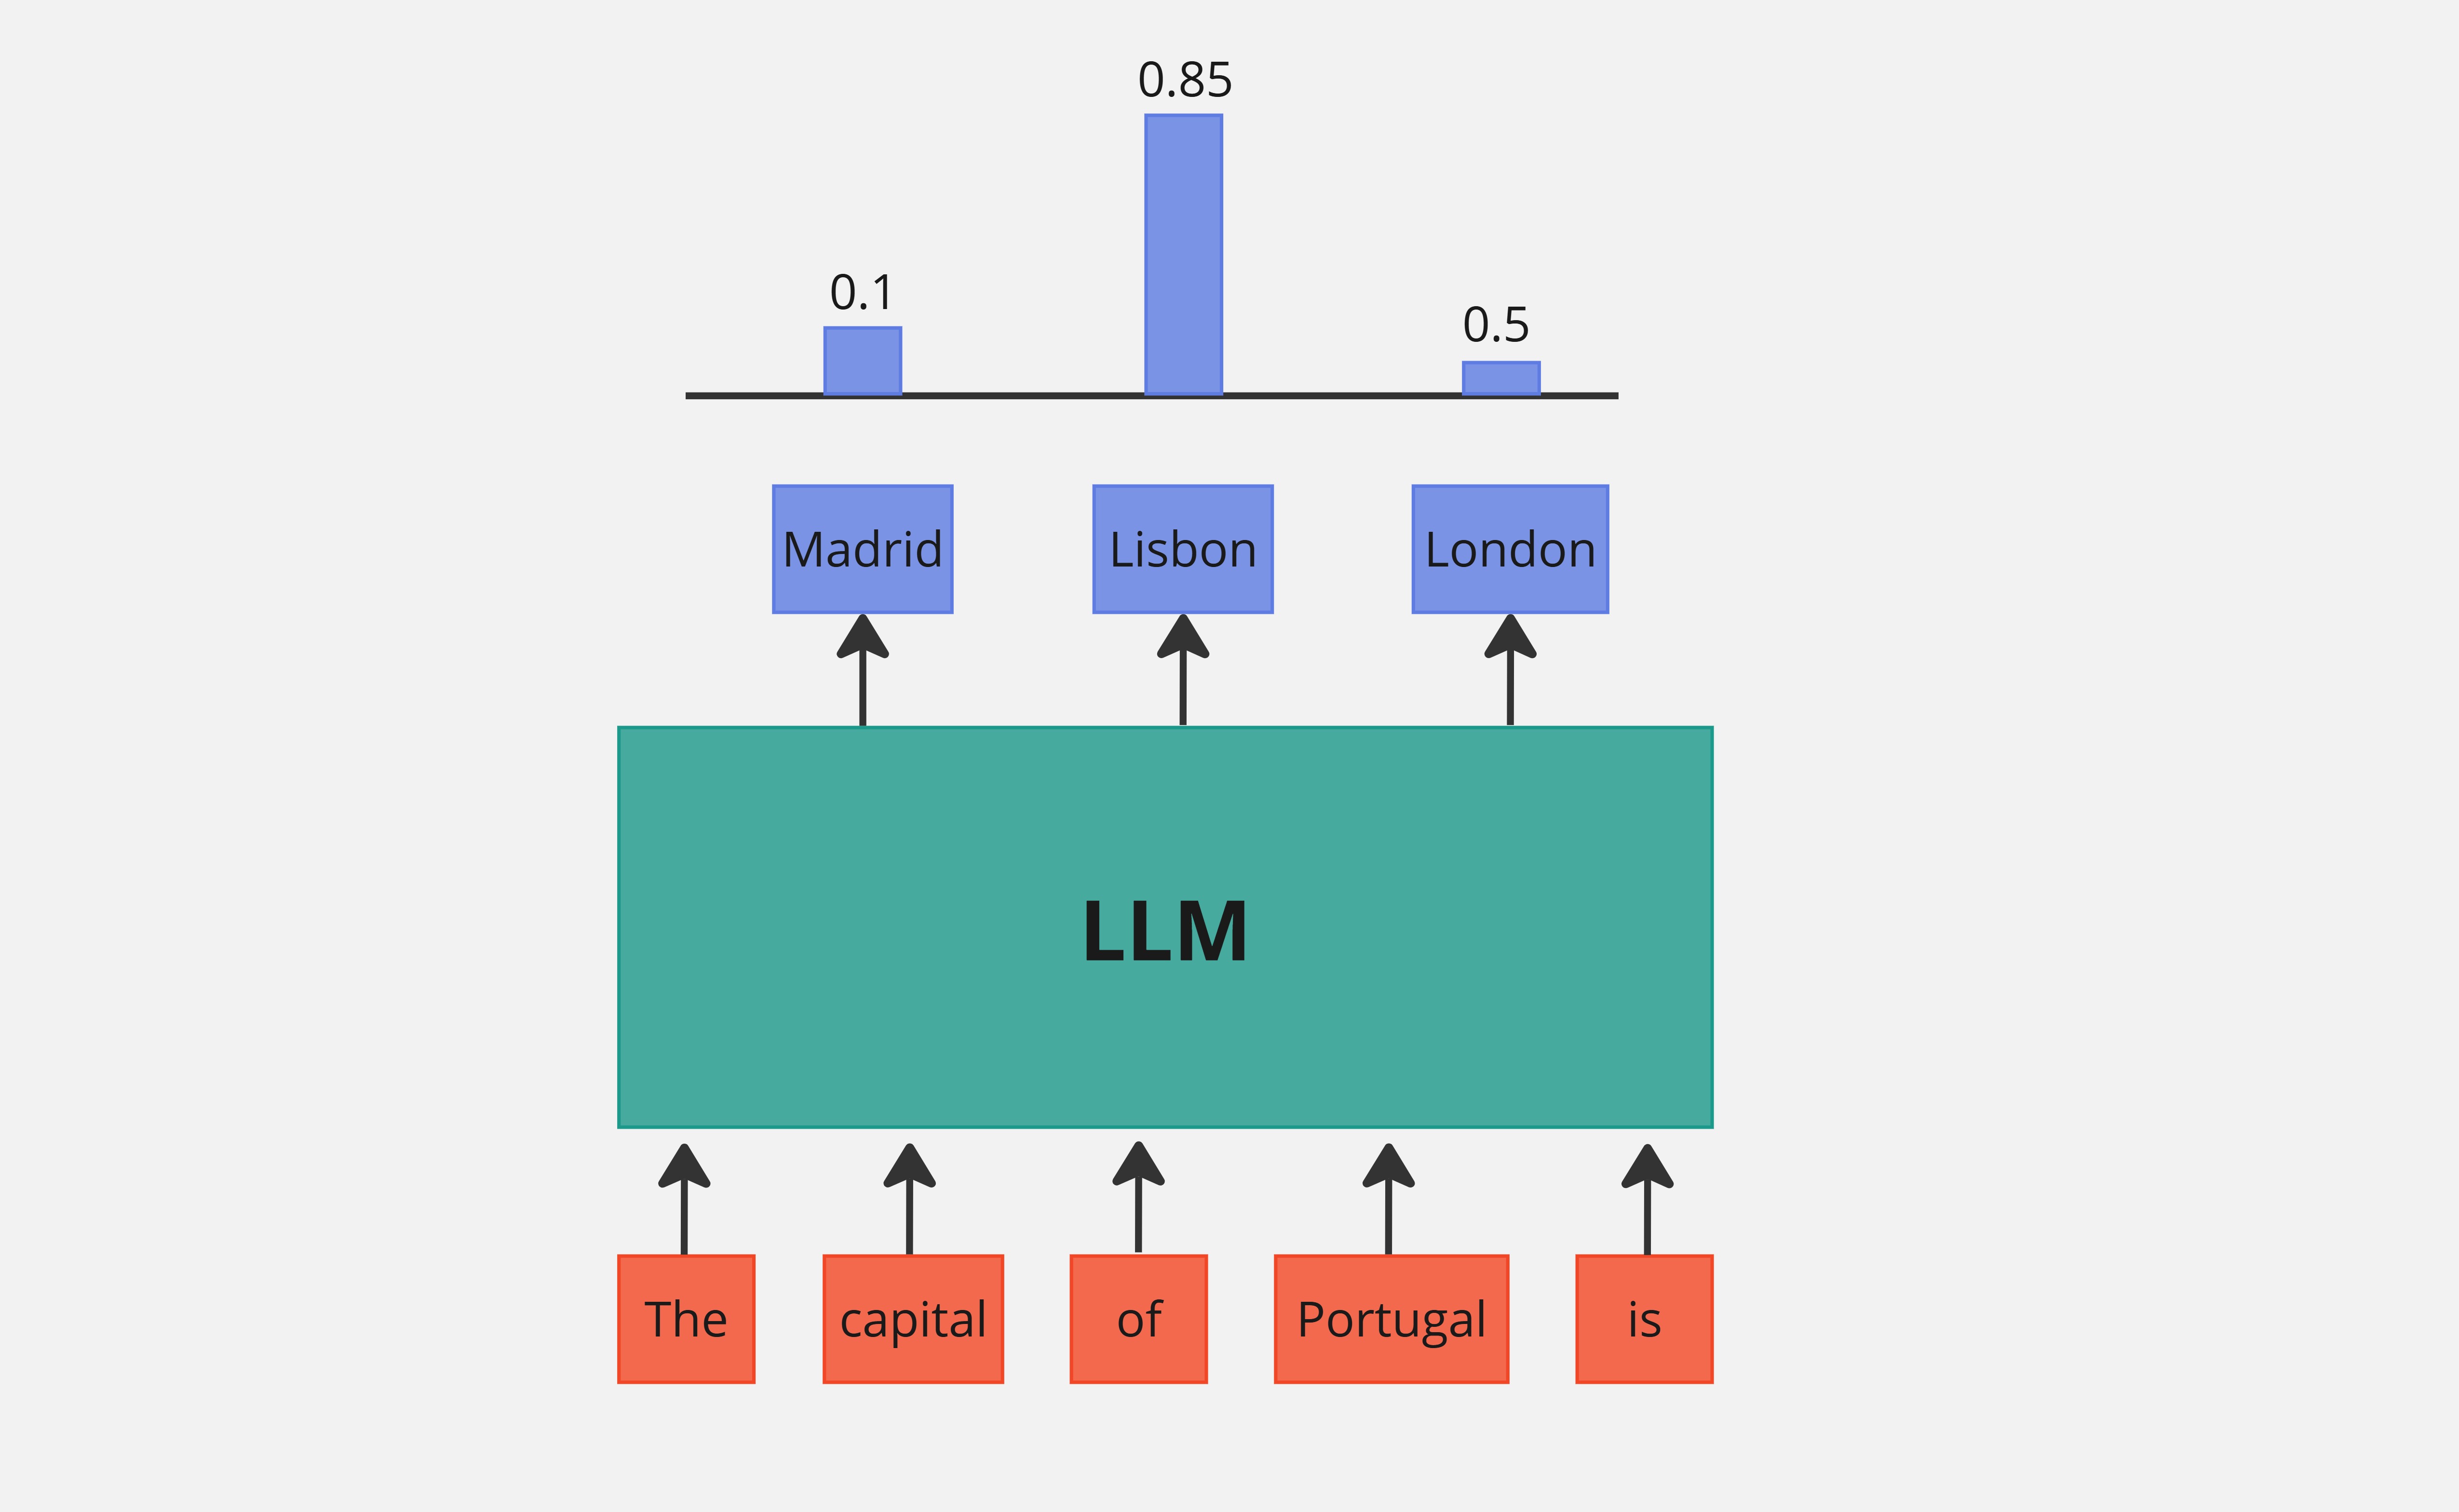
LLM Preference Alignment

Alignment with Preference Optimization Is All You Need for LLM Safety ...
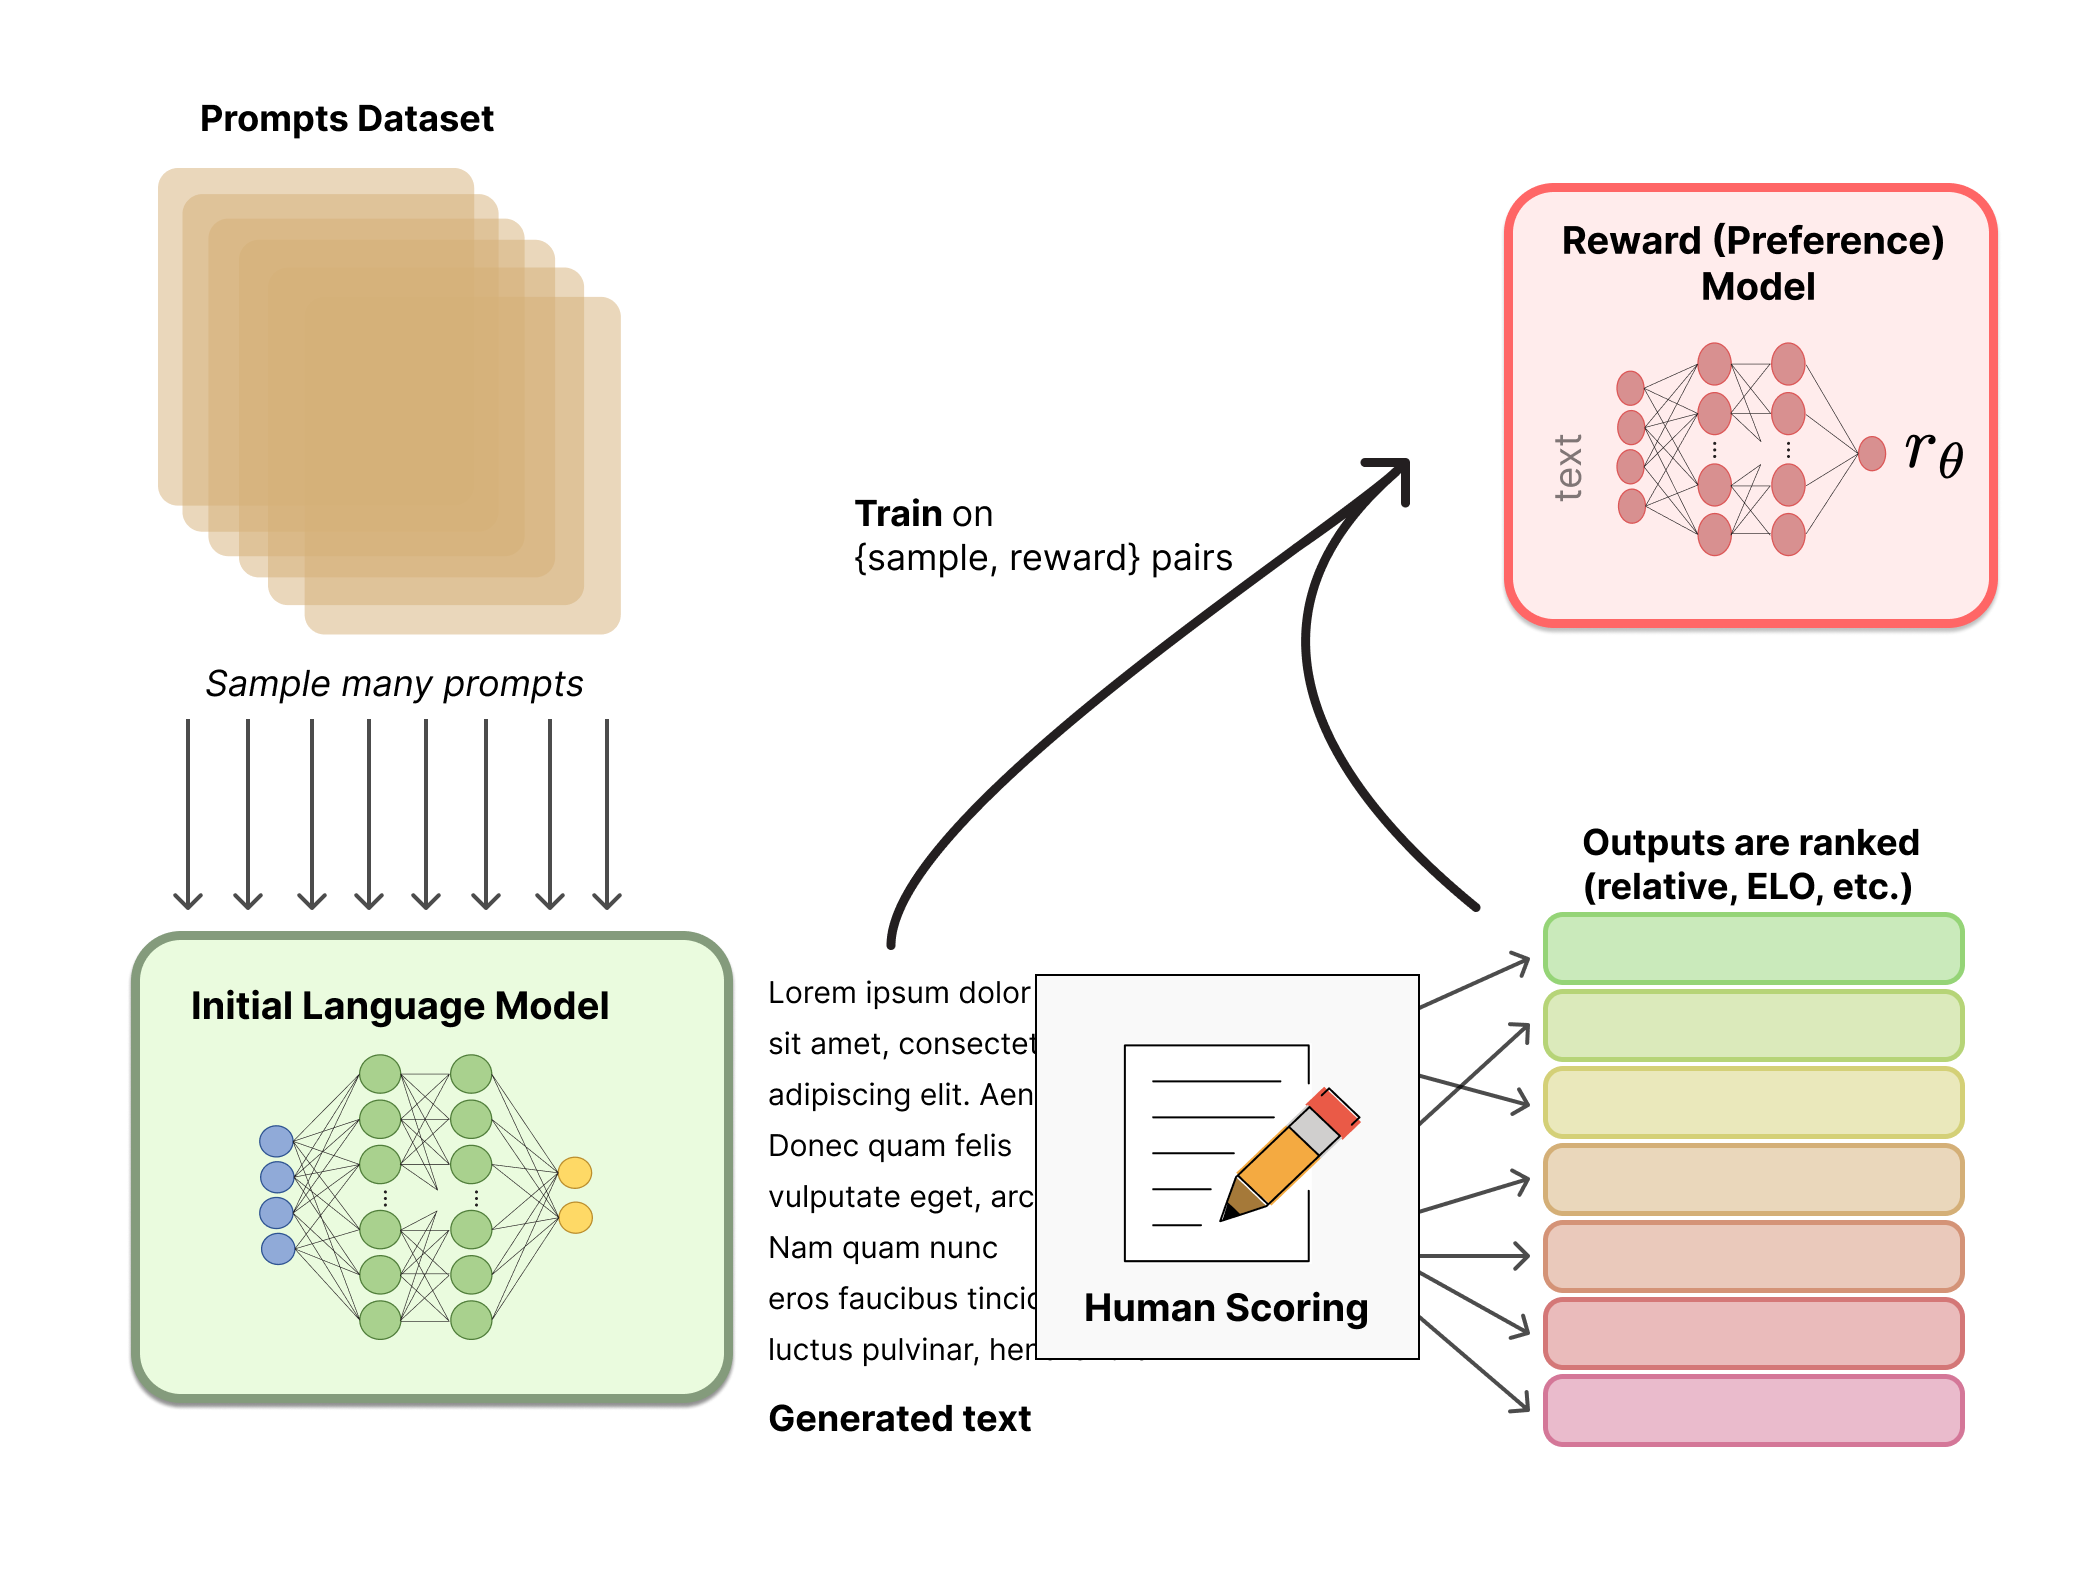
LLM Preference Alignment

The Paradox of Preference: A Study on LLM Alignment Algorithms and Data ...

Aligning LLM Agents by Learning Latent Preference from User Edits

Visualizing Llm Alignment and Misalignment | PDF
Advertisement Space (336x280)

Preference Alignment in LLM - a armodeniz Collection

LLM Alignment Techniques - Best Generative AI & Machine Learning ...

New AI Method From Meta and NYU Boosts LLM Alignment Using Semi-Online ...

A Grounded Preference Model for LLM Alignment - ACL Anthology

Direct Preference Optimization For LLM Alignment | HackerNoon - World ...

Aligning Llm Agents By Learning Latent Preference From User Edits – STLUZ

Figure 1 from Inference time LLM alignment in single and multidomain ...

[논문 리뷰] Pref-CTRL: Preference Driven LLM Alignment using Representation ...

Figure 1 from Relative Preference Optimization: Enhancing LLM Alignment ...

Users as Annotators: LLM Preference Learning from Comparison Mode | AI ...
Advertisement Space (336x280)
The Paradox of Preference: A Study on LLM Alignment Algorithms and Data ...

[논문 리뷰] Learning LLM Preference over Intra-Dialogue Pairs: A Framework ...

Efficient LLM Alignment with Direct Preference Optimization a book by ...
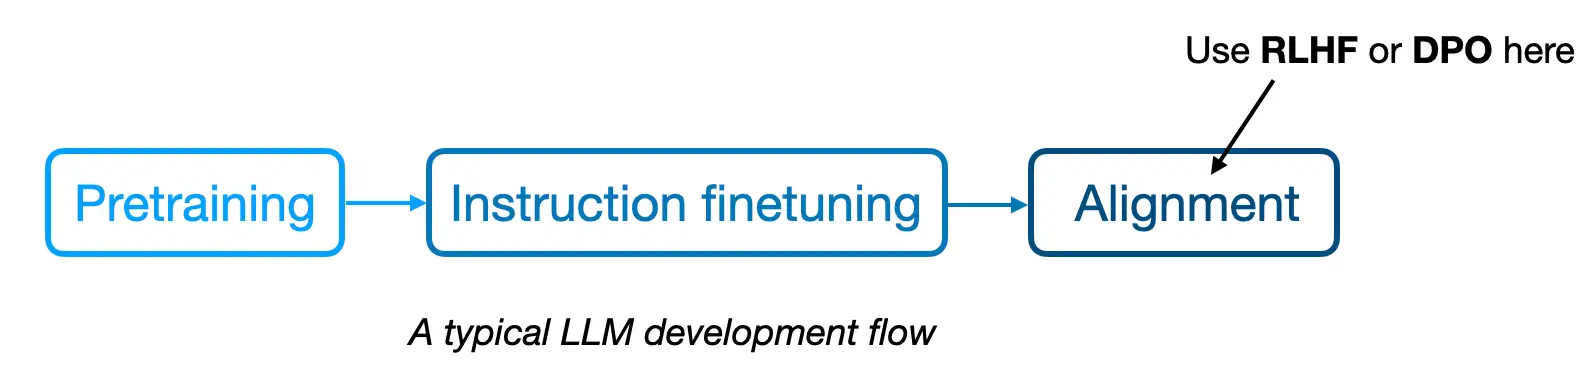
Direct Preference Optimization (DPO) for LLM Alignment (From Scratch ...

Figure 2 from Understand What LLM Needs: Dual Preference Alignment for ...

Paper page - Improving LLM General Preference Alignment via Optimistic ...