
250608373 Draft Based Approximate Inference For Llms
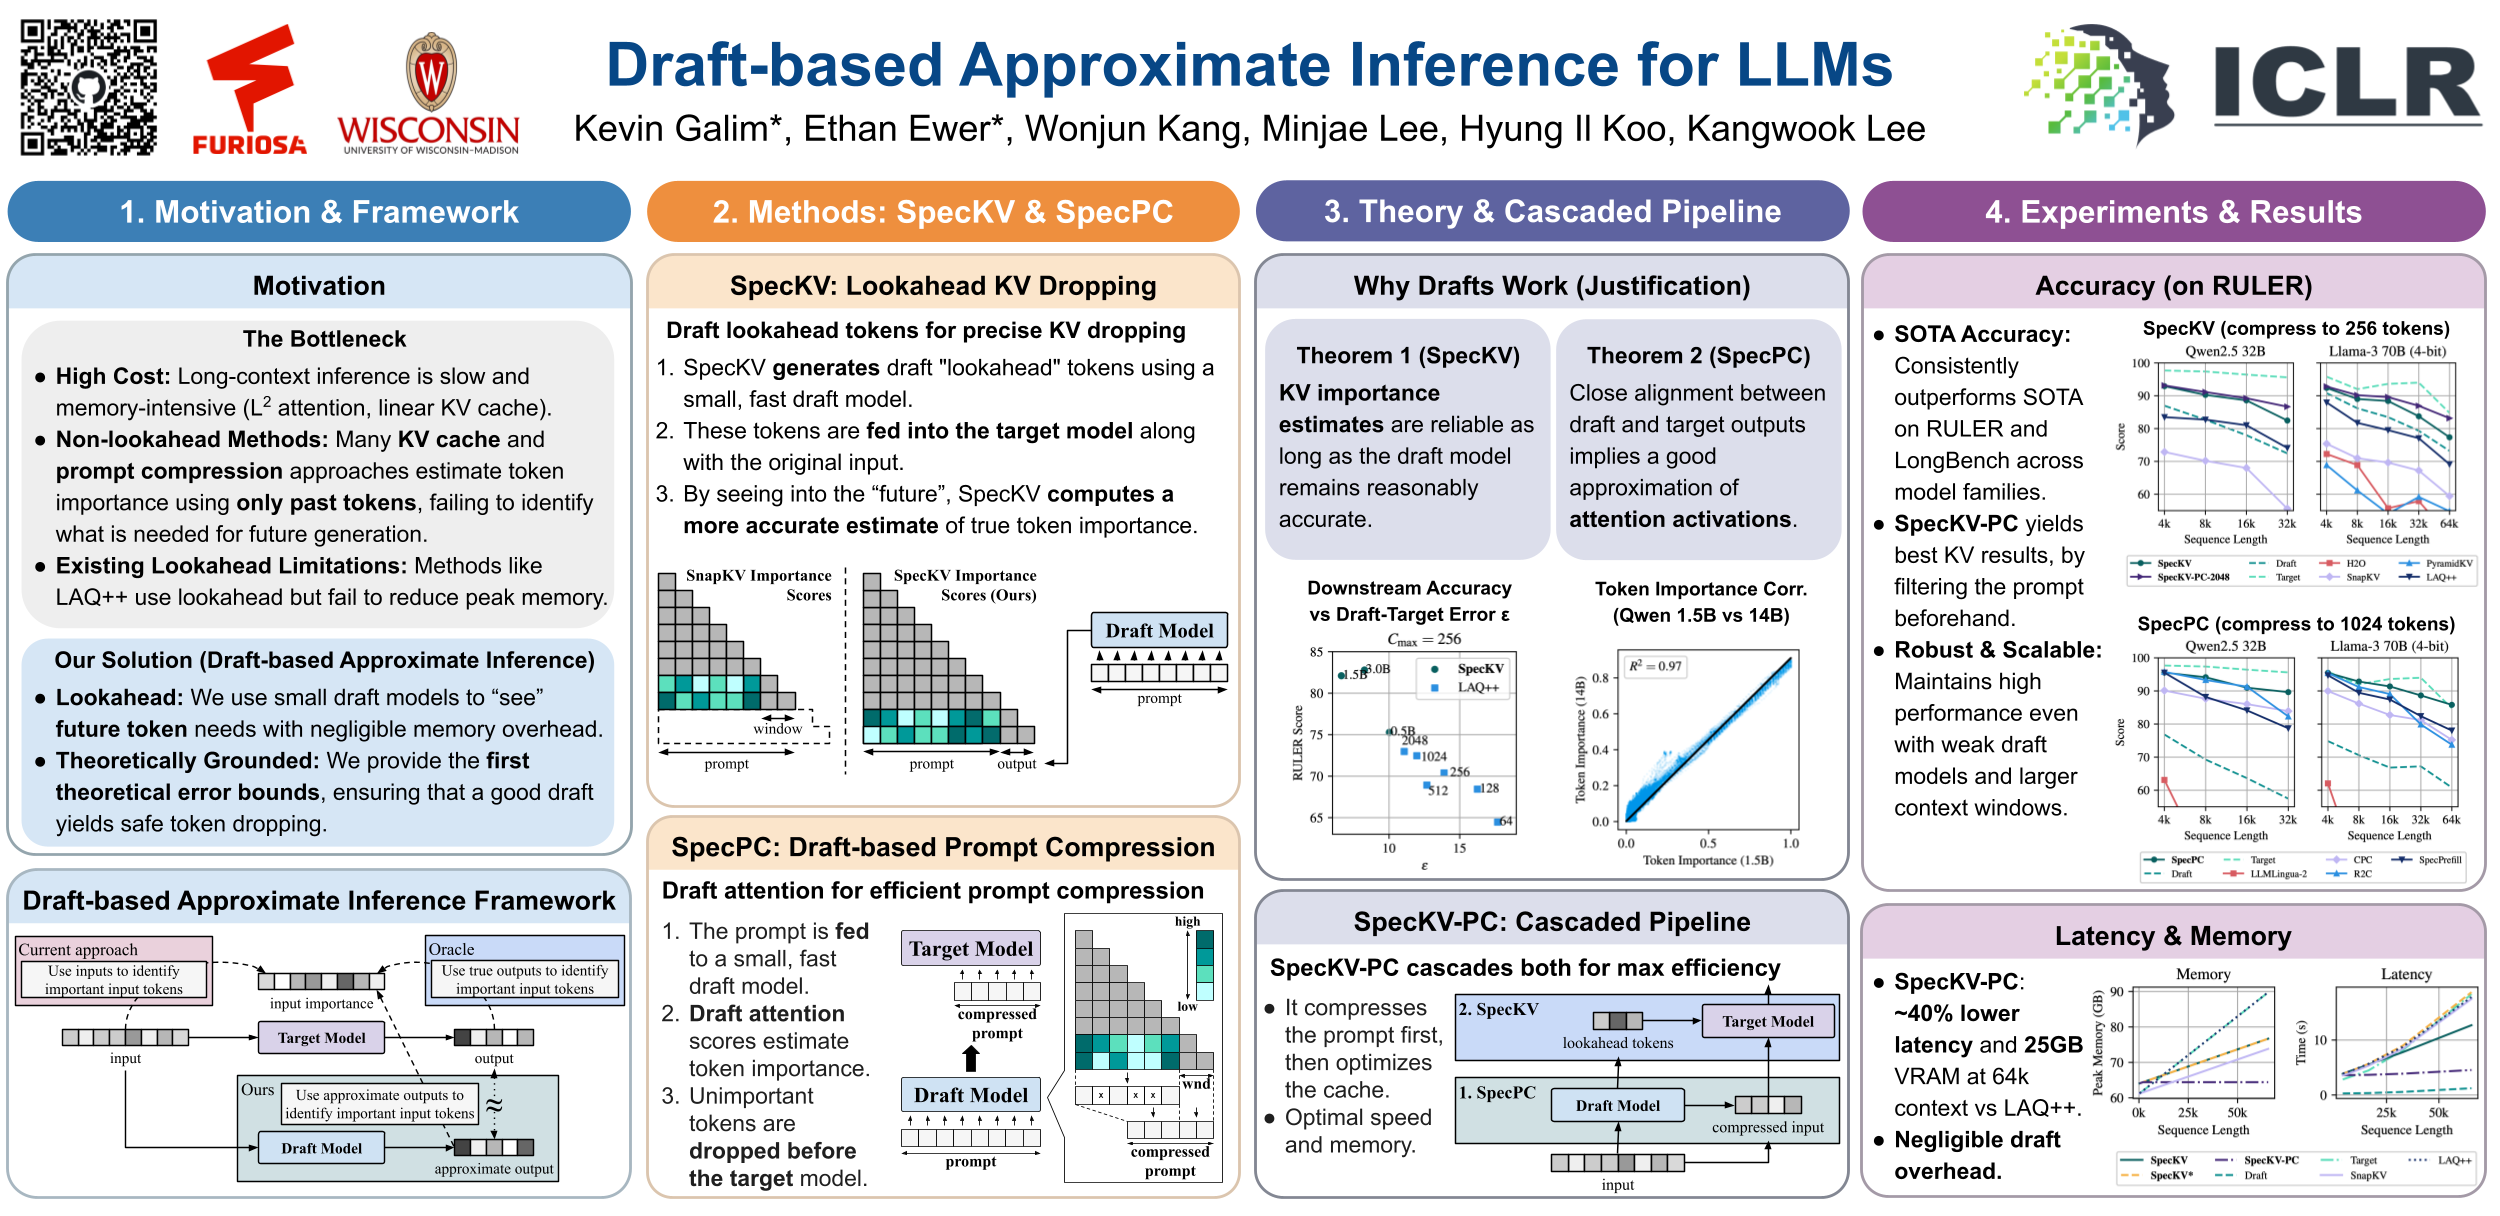
ICLR Poster Draft-based Approximate Inference for LLMs

Paper page - Draft-based Approximate Inference for LLMs

[论文评述] Draft-based Approximate Inference for LLMs
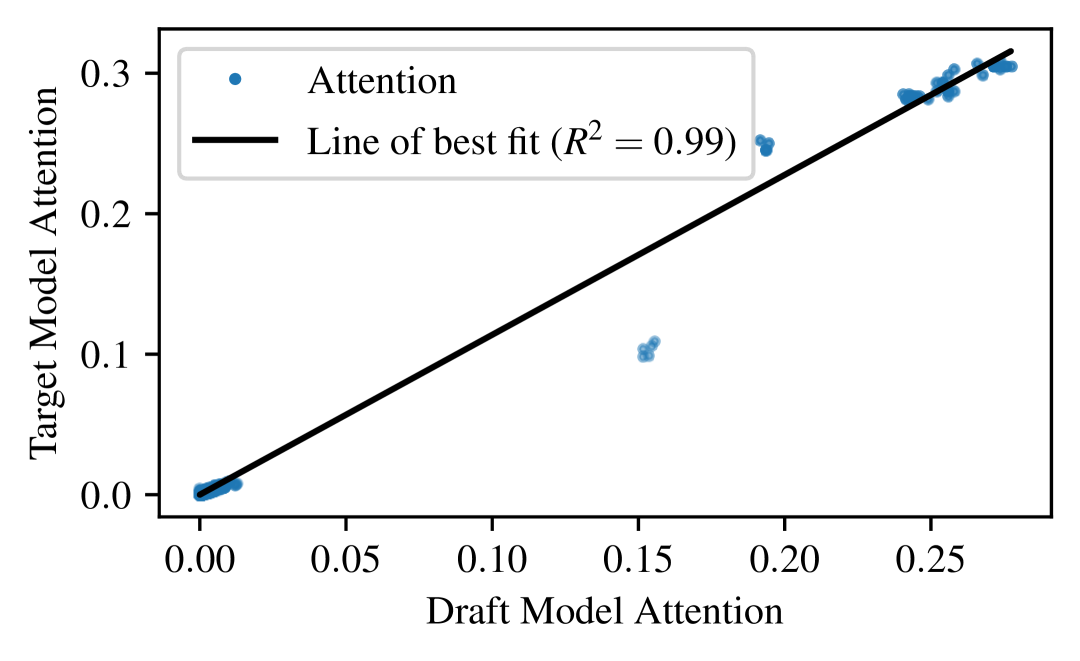
[2506.08373] Draft-based Approximate Inference for LLMs

(PDF) SplitLLM: Collaborative Inference of LLMs for Model Placement and ...

(PDF) Variational inference for approximate reference priors using ...

Variational Sampling for Approximate Inference | PDF | Normal ...

SplitLLM: Collaborative Inference of LLMs for Model Placement and ...
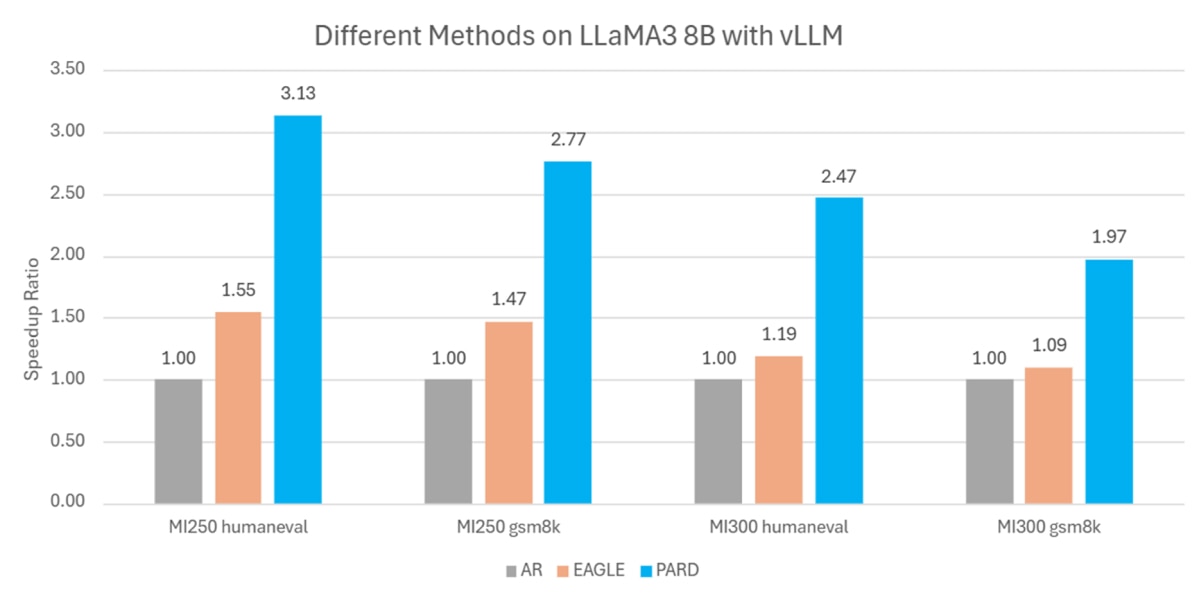
Accelerating Generative LLMs Inference with Parallel Draft Models (PARD)

Estimate memory consumption of llms for inference and fine tuning - YouTube
Advertisement Space (300x250)
[PPT] - Incremental and Approximate Inference for Faster Occlusion ...

Fast Distributed Inference Serving for LLMs - YouTube
INT8 Quantization — Practical 8-Bit Inference for LLMs | tutorialQ
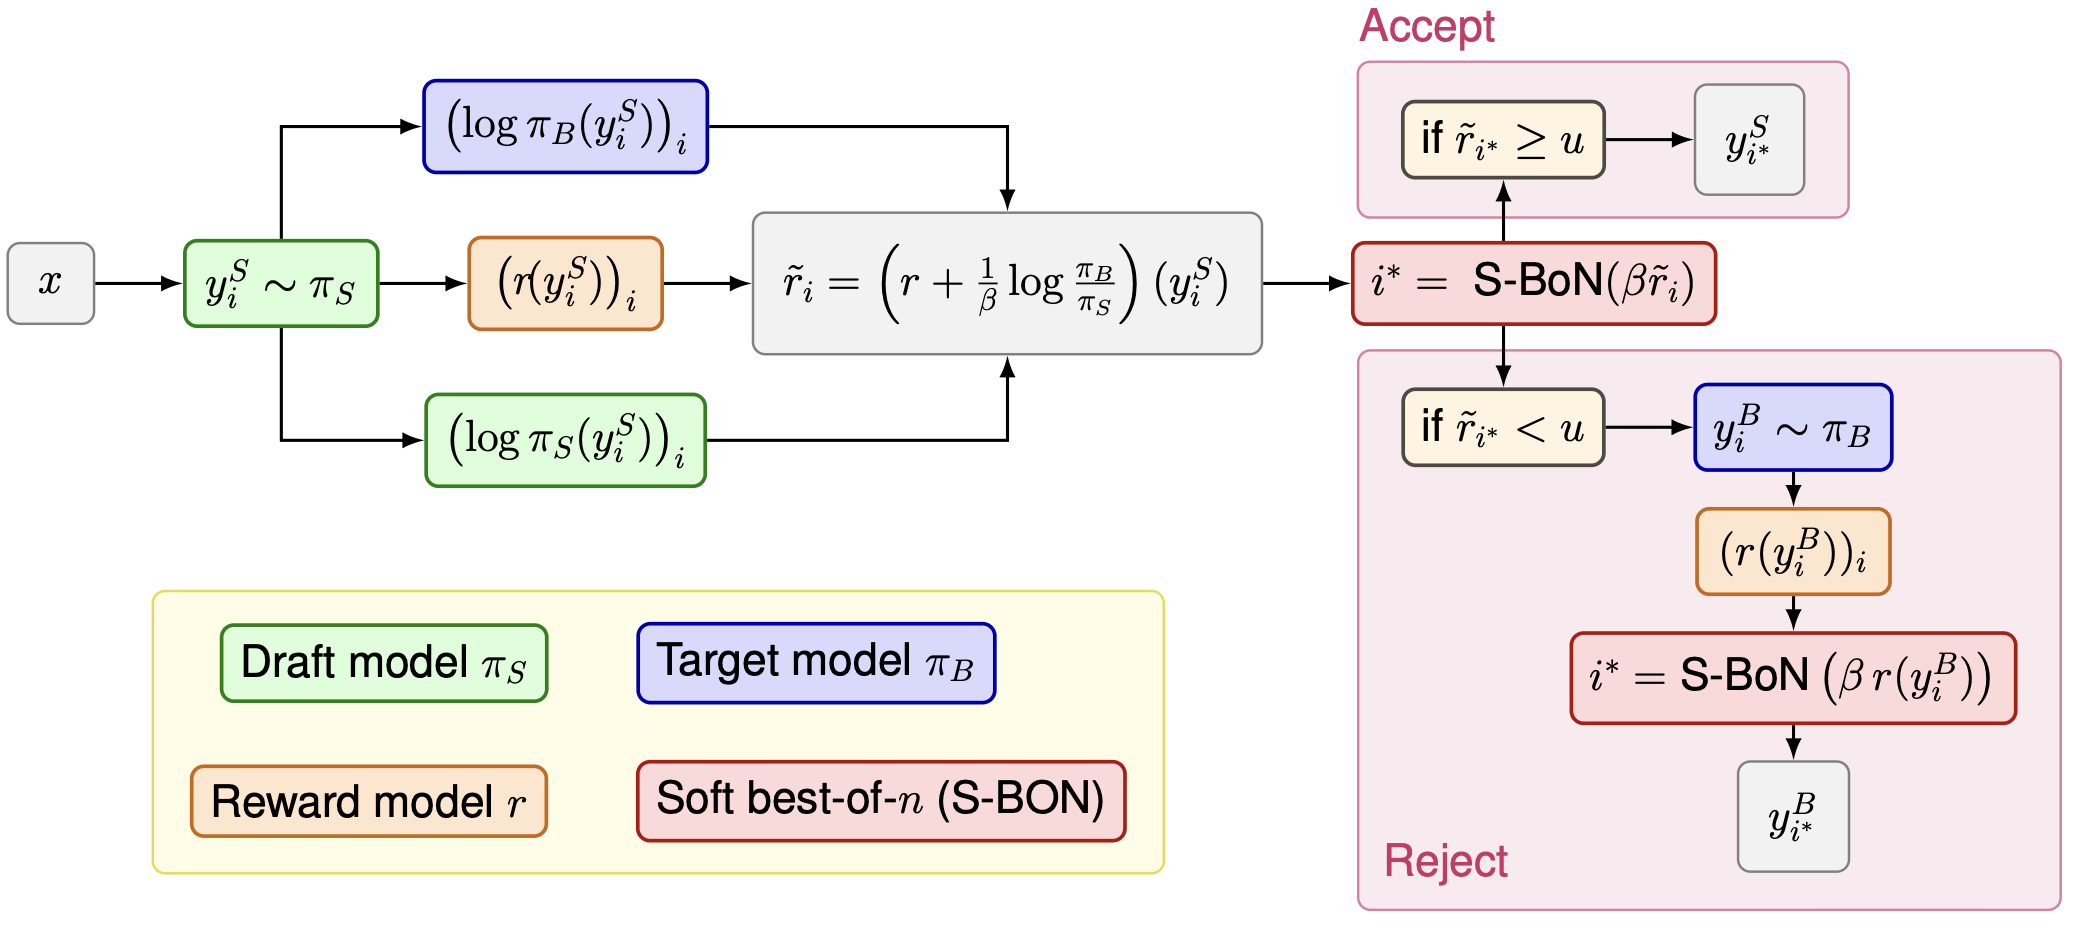
Guided Speculative Inference for Efficient Test-Time Alignment of LLMs ...
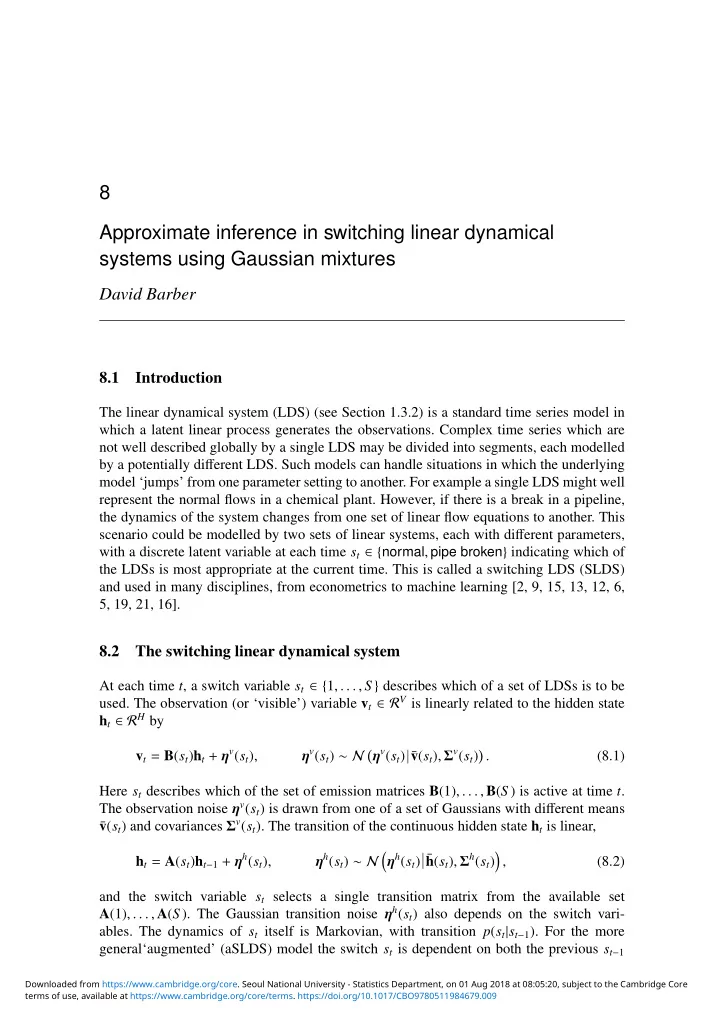
[PDF] - 8 Approximate inference in switching linear dynamical systems ...
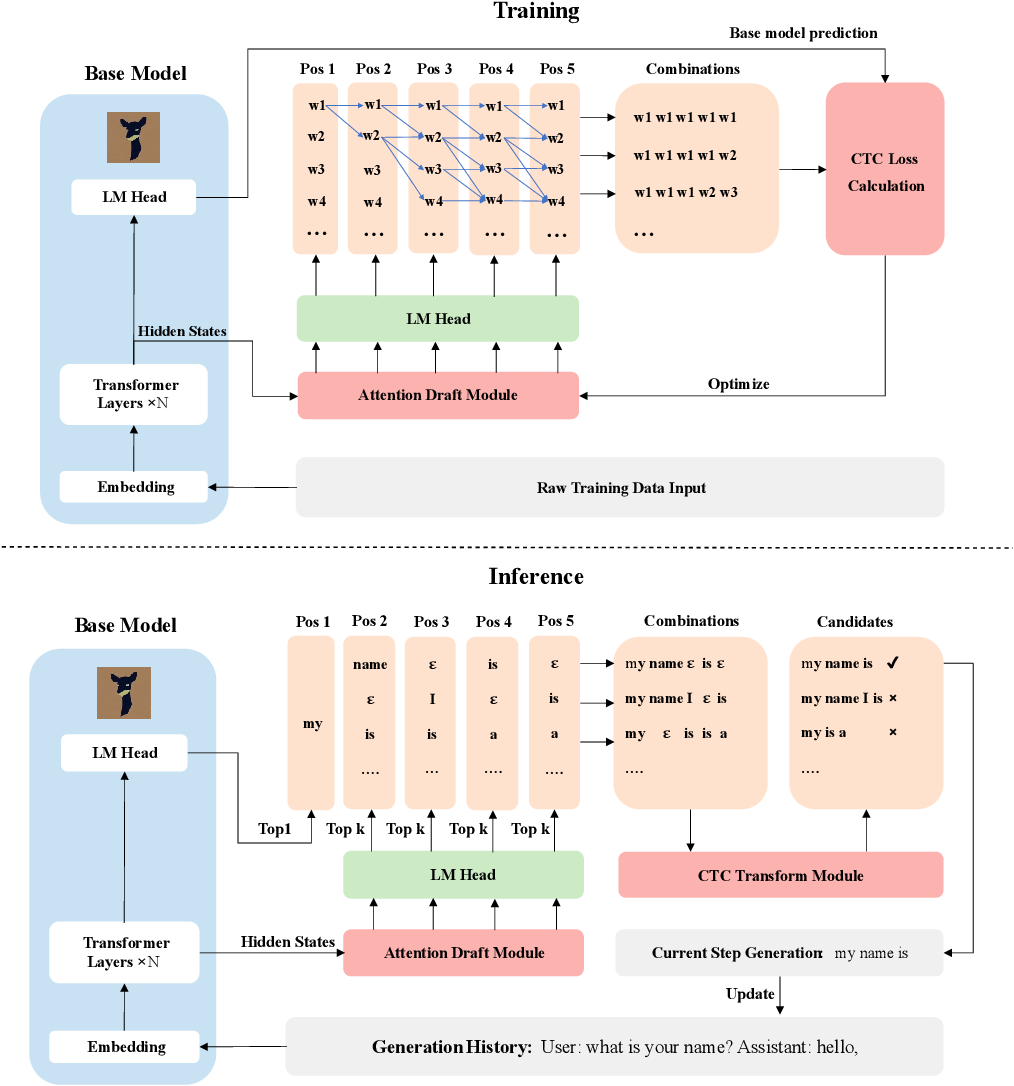
Figure 1 from Speculative Decoding with CTC-based Draft Model for LLM ...

(PDF) Elevating the Inference Performance of LLMs with Reverse ...

Approximate Inference | PDF

EAGLE-2: Faster Inference of Language Models with Dynamic Draft Trees ...
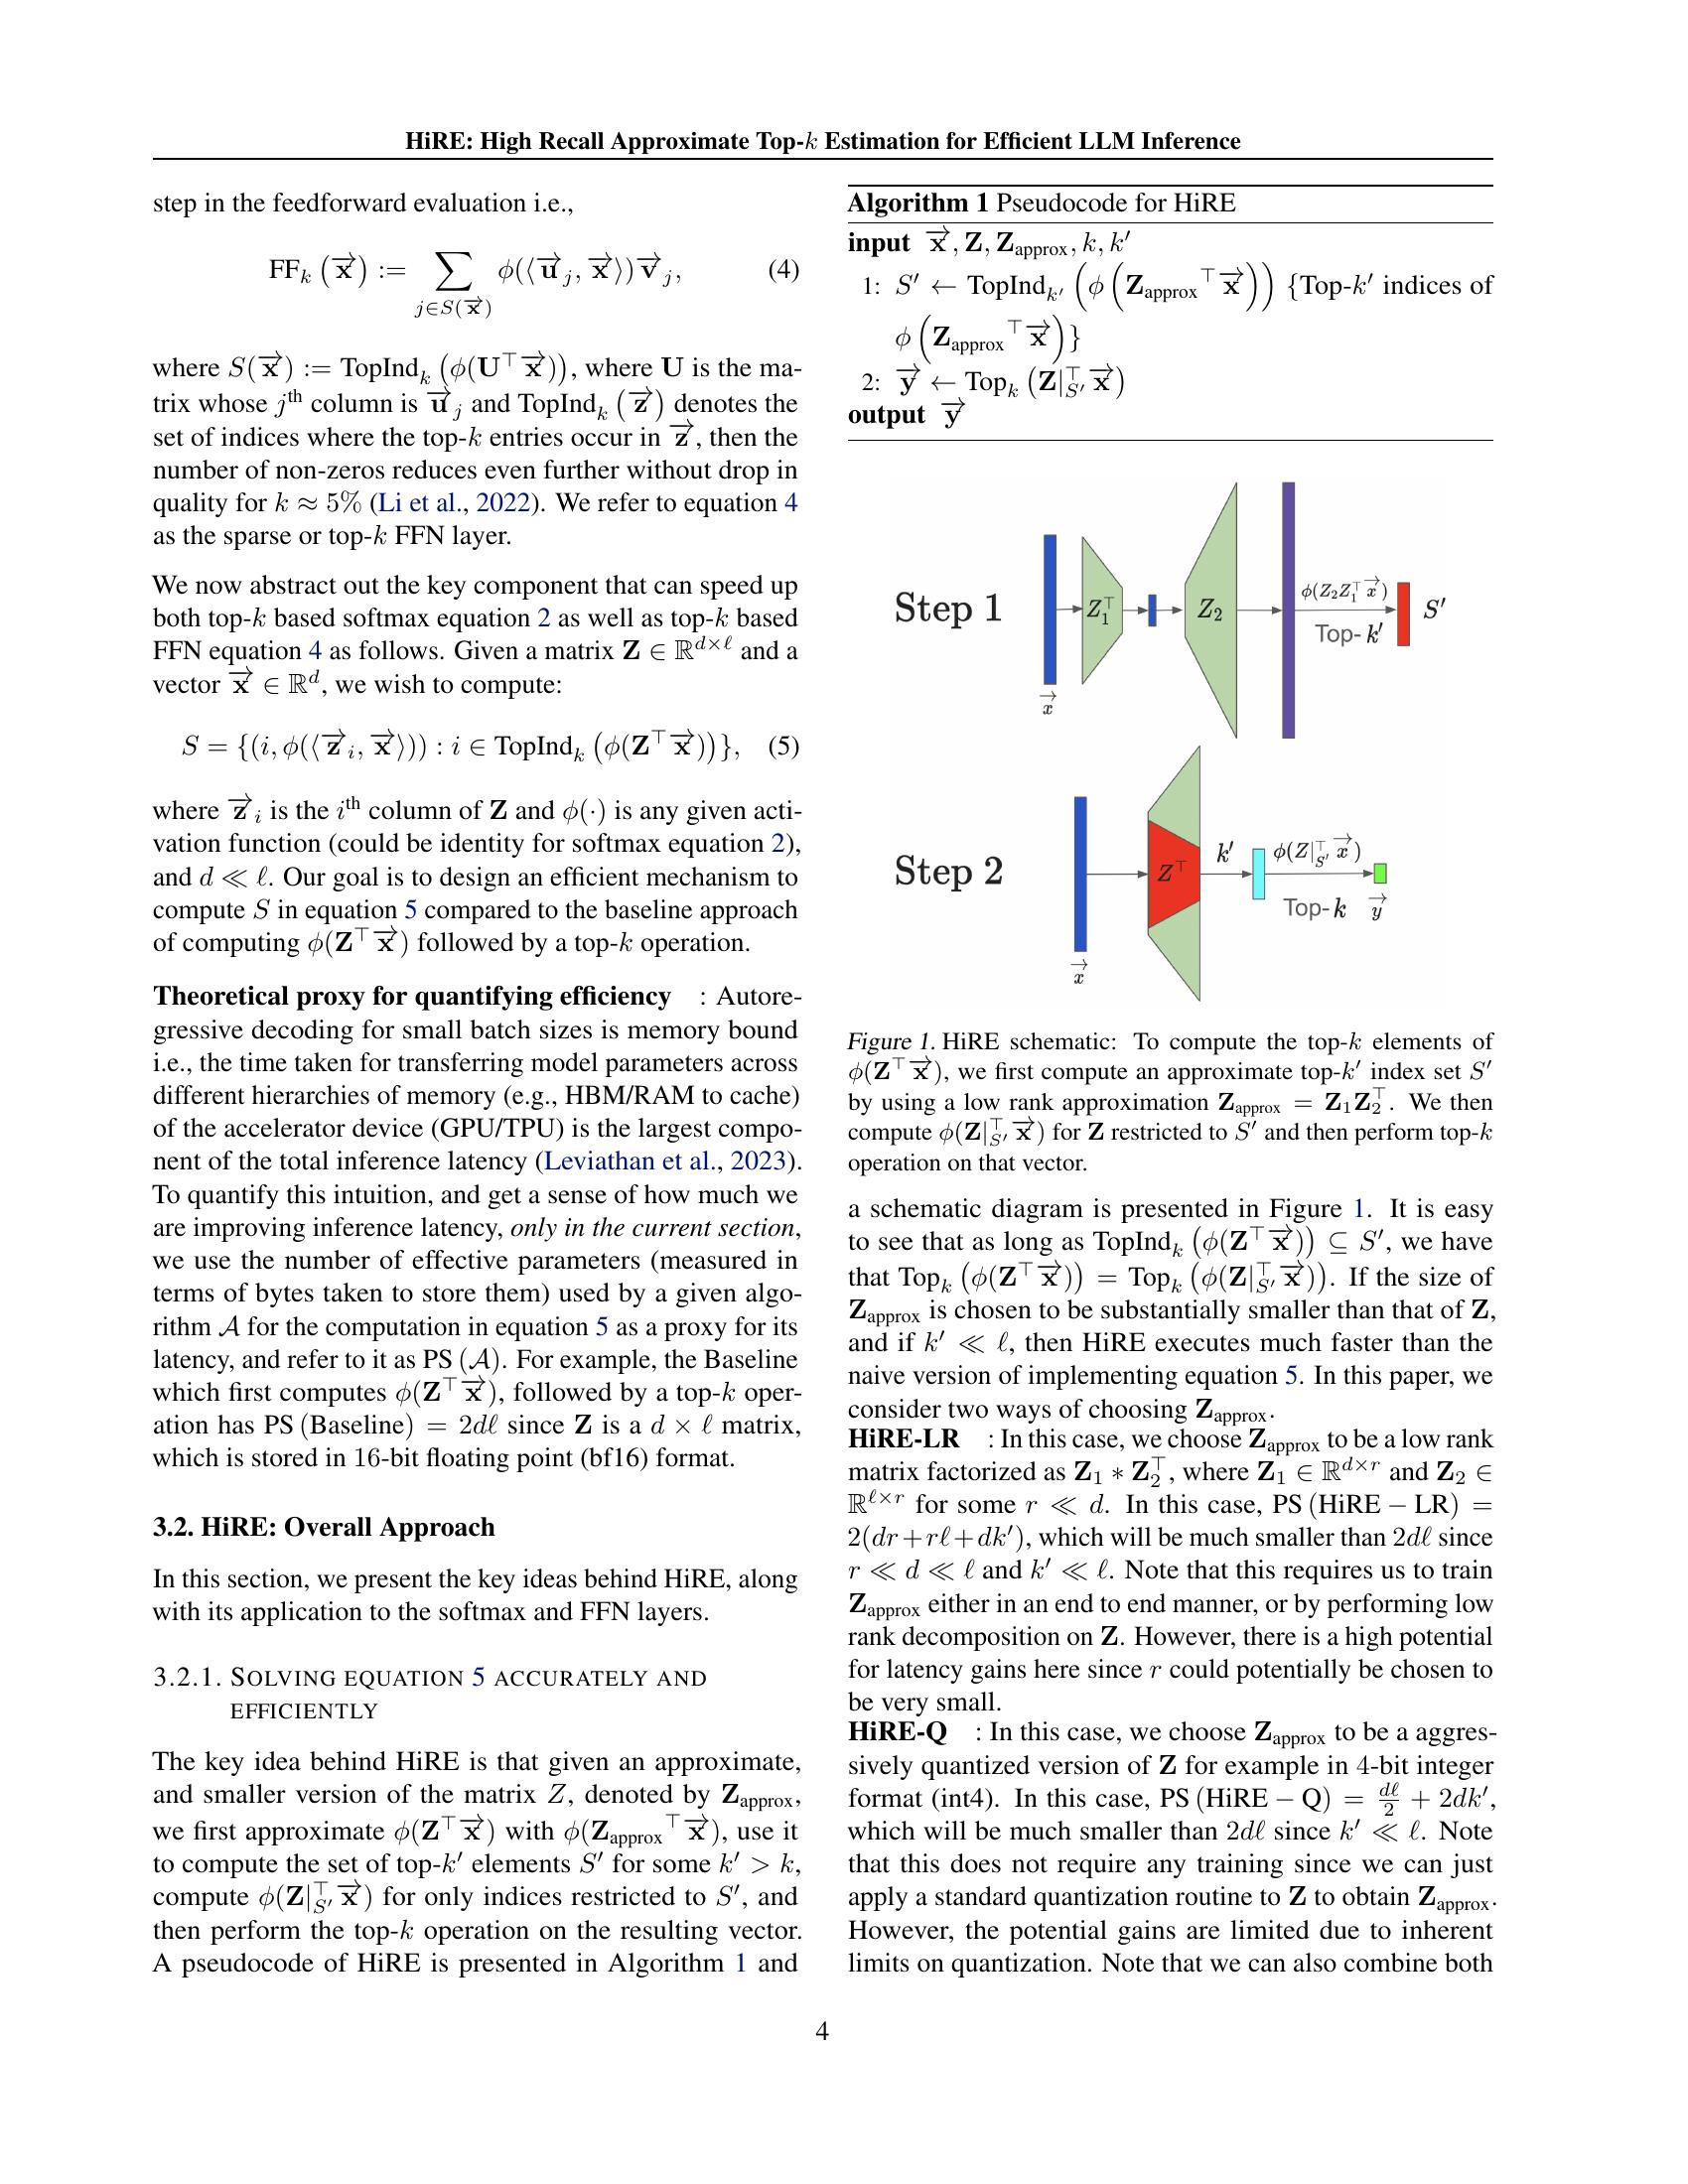
HiRE: High Recall Approximate Top-$k$ Estimation for Efficient LLM ...
Advertisement Space (336x280)

PARD: Accelerating LLM Inference with Low-Cost PARallel Draft Model ...
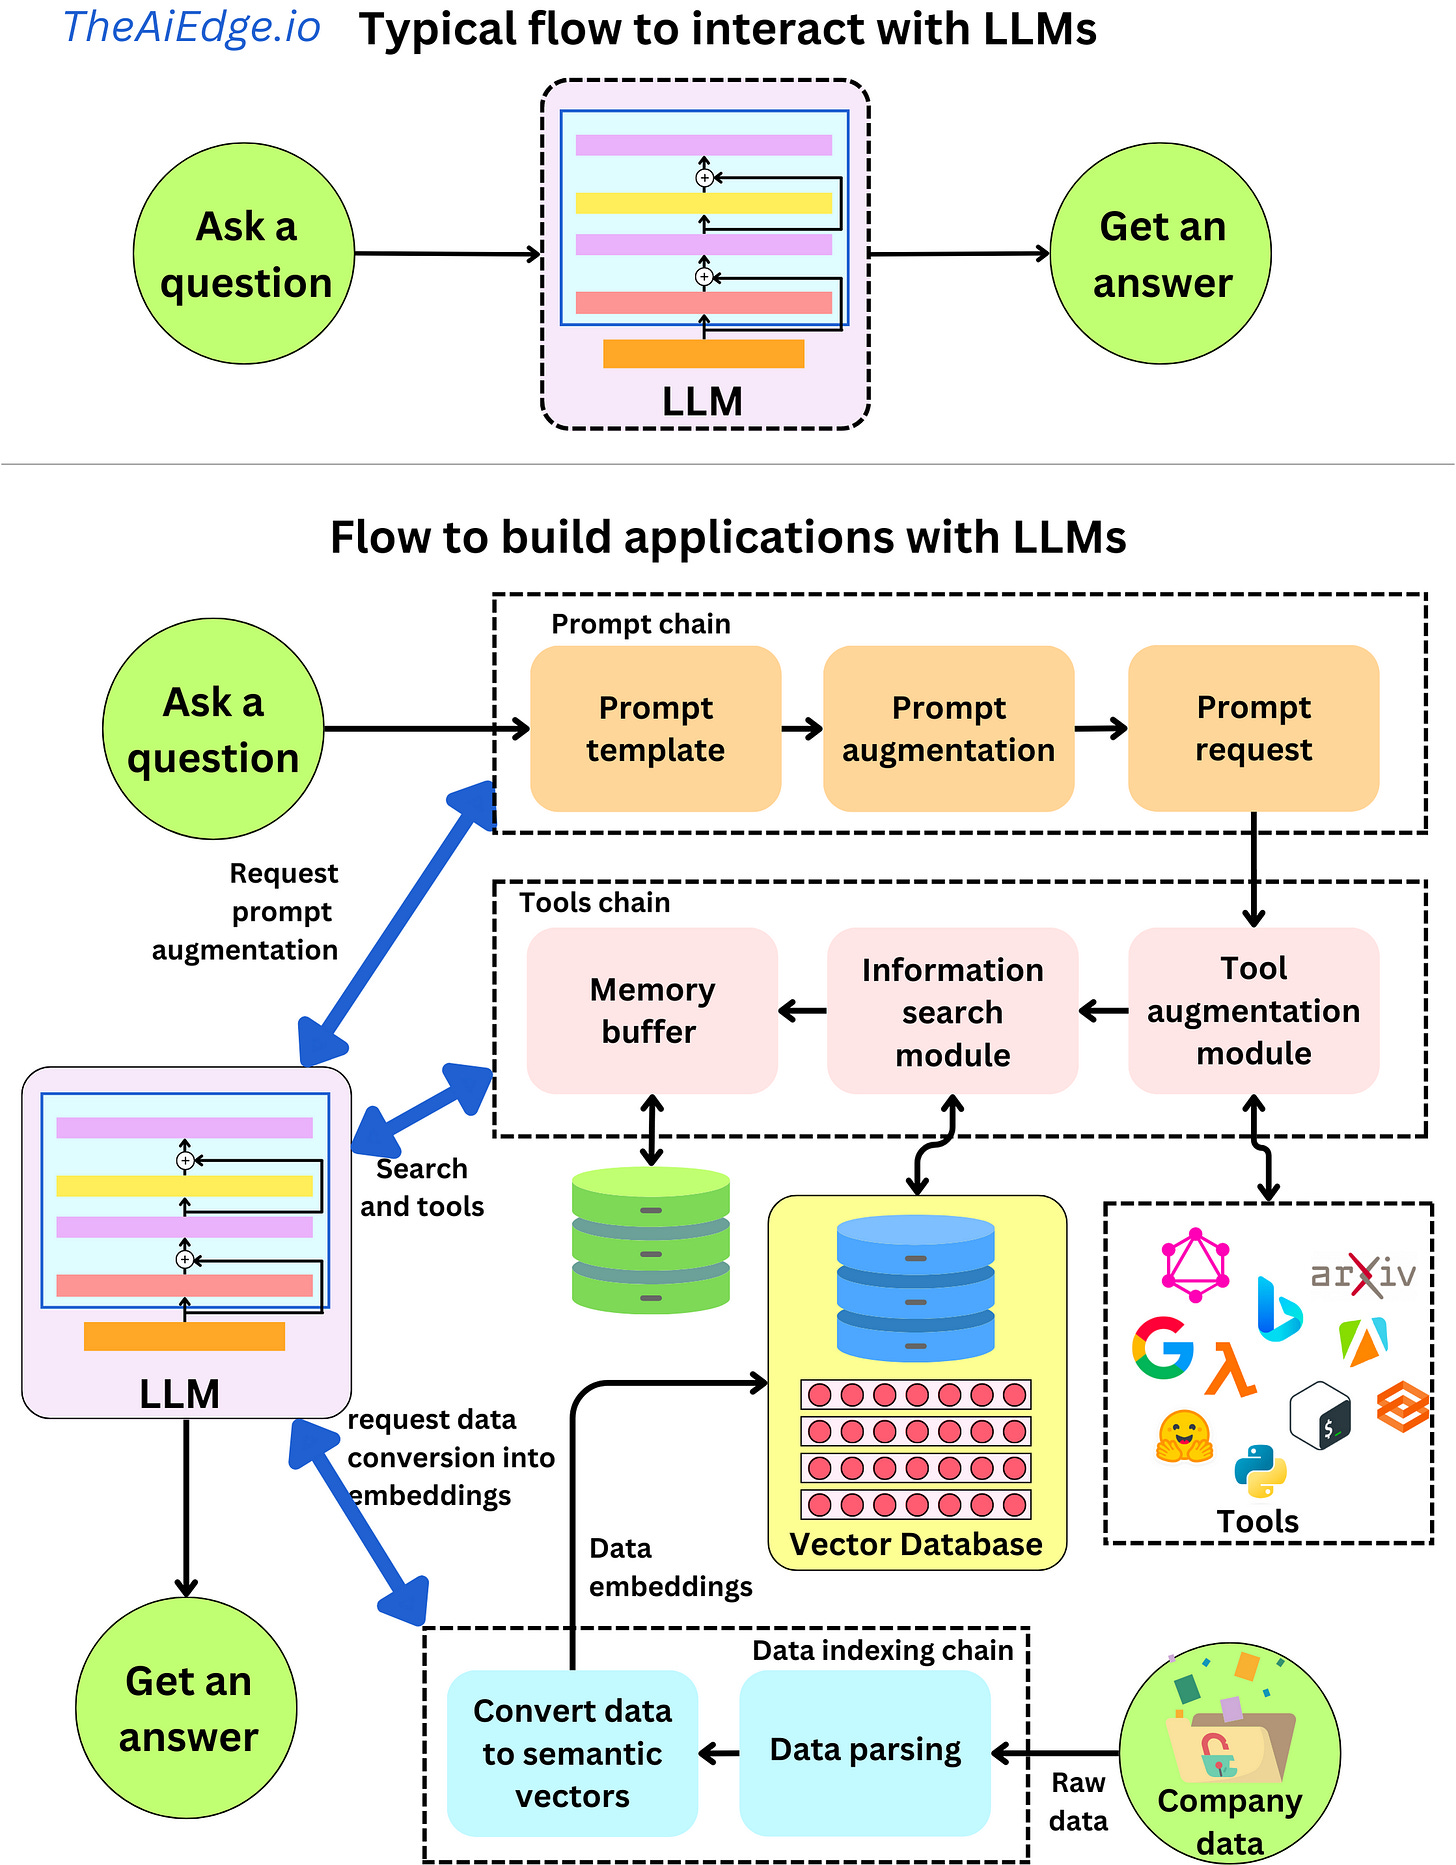
A10, A16, Or 4090 For Llm Inference For Prompt Engineers? – QVWC

(PDF) Gradient-Based Approximate Bayesian Inference with Entropy ...

Serving Inference for LLMs: A Case Study | CoreWeave
Inference of instruction tuned LLMs using edit operations. LLMs take ...

Optimizing Inference Performance for “On-Prem” LLMs. | Wallaroo.AI
LLM Inference Explained for Developers — How AI Models Generate Text

A Probabilistic Inference Approach to Inference-Time Scaling of LLMs ...
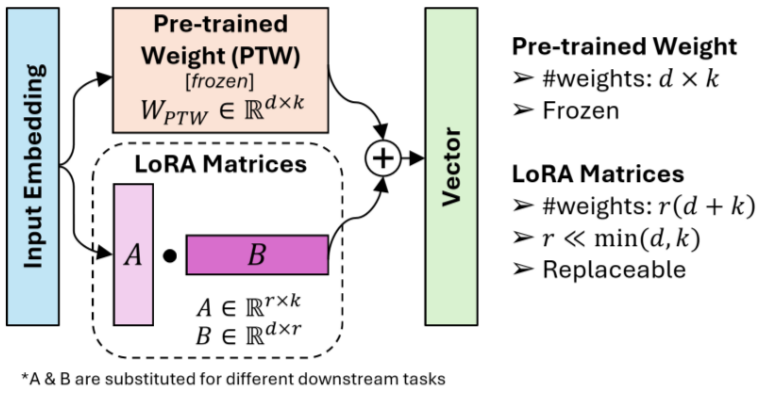
[논문 리뷰] PRIMAL: Processing-In-Memory Based Low-Rank Adaptation for LLM ...

How to Build LLM Inference Pipelines for Enterprise Apps
Advertisement Space (336x280)
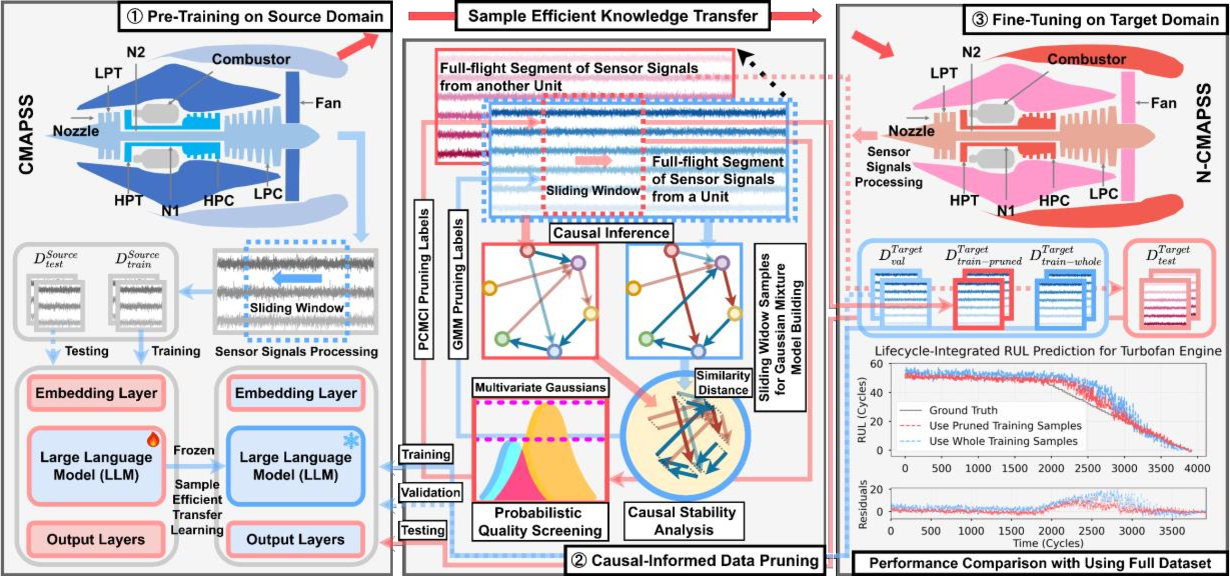
Figure 1 from Causal Inference based Transfer Learning with LLMs: An ...
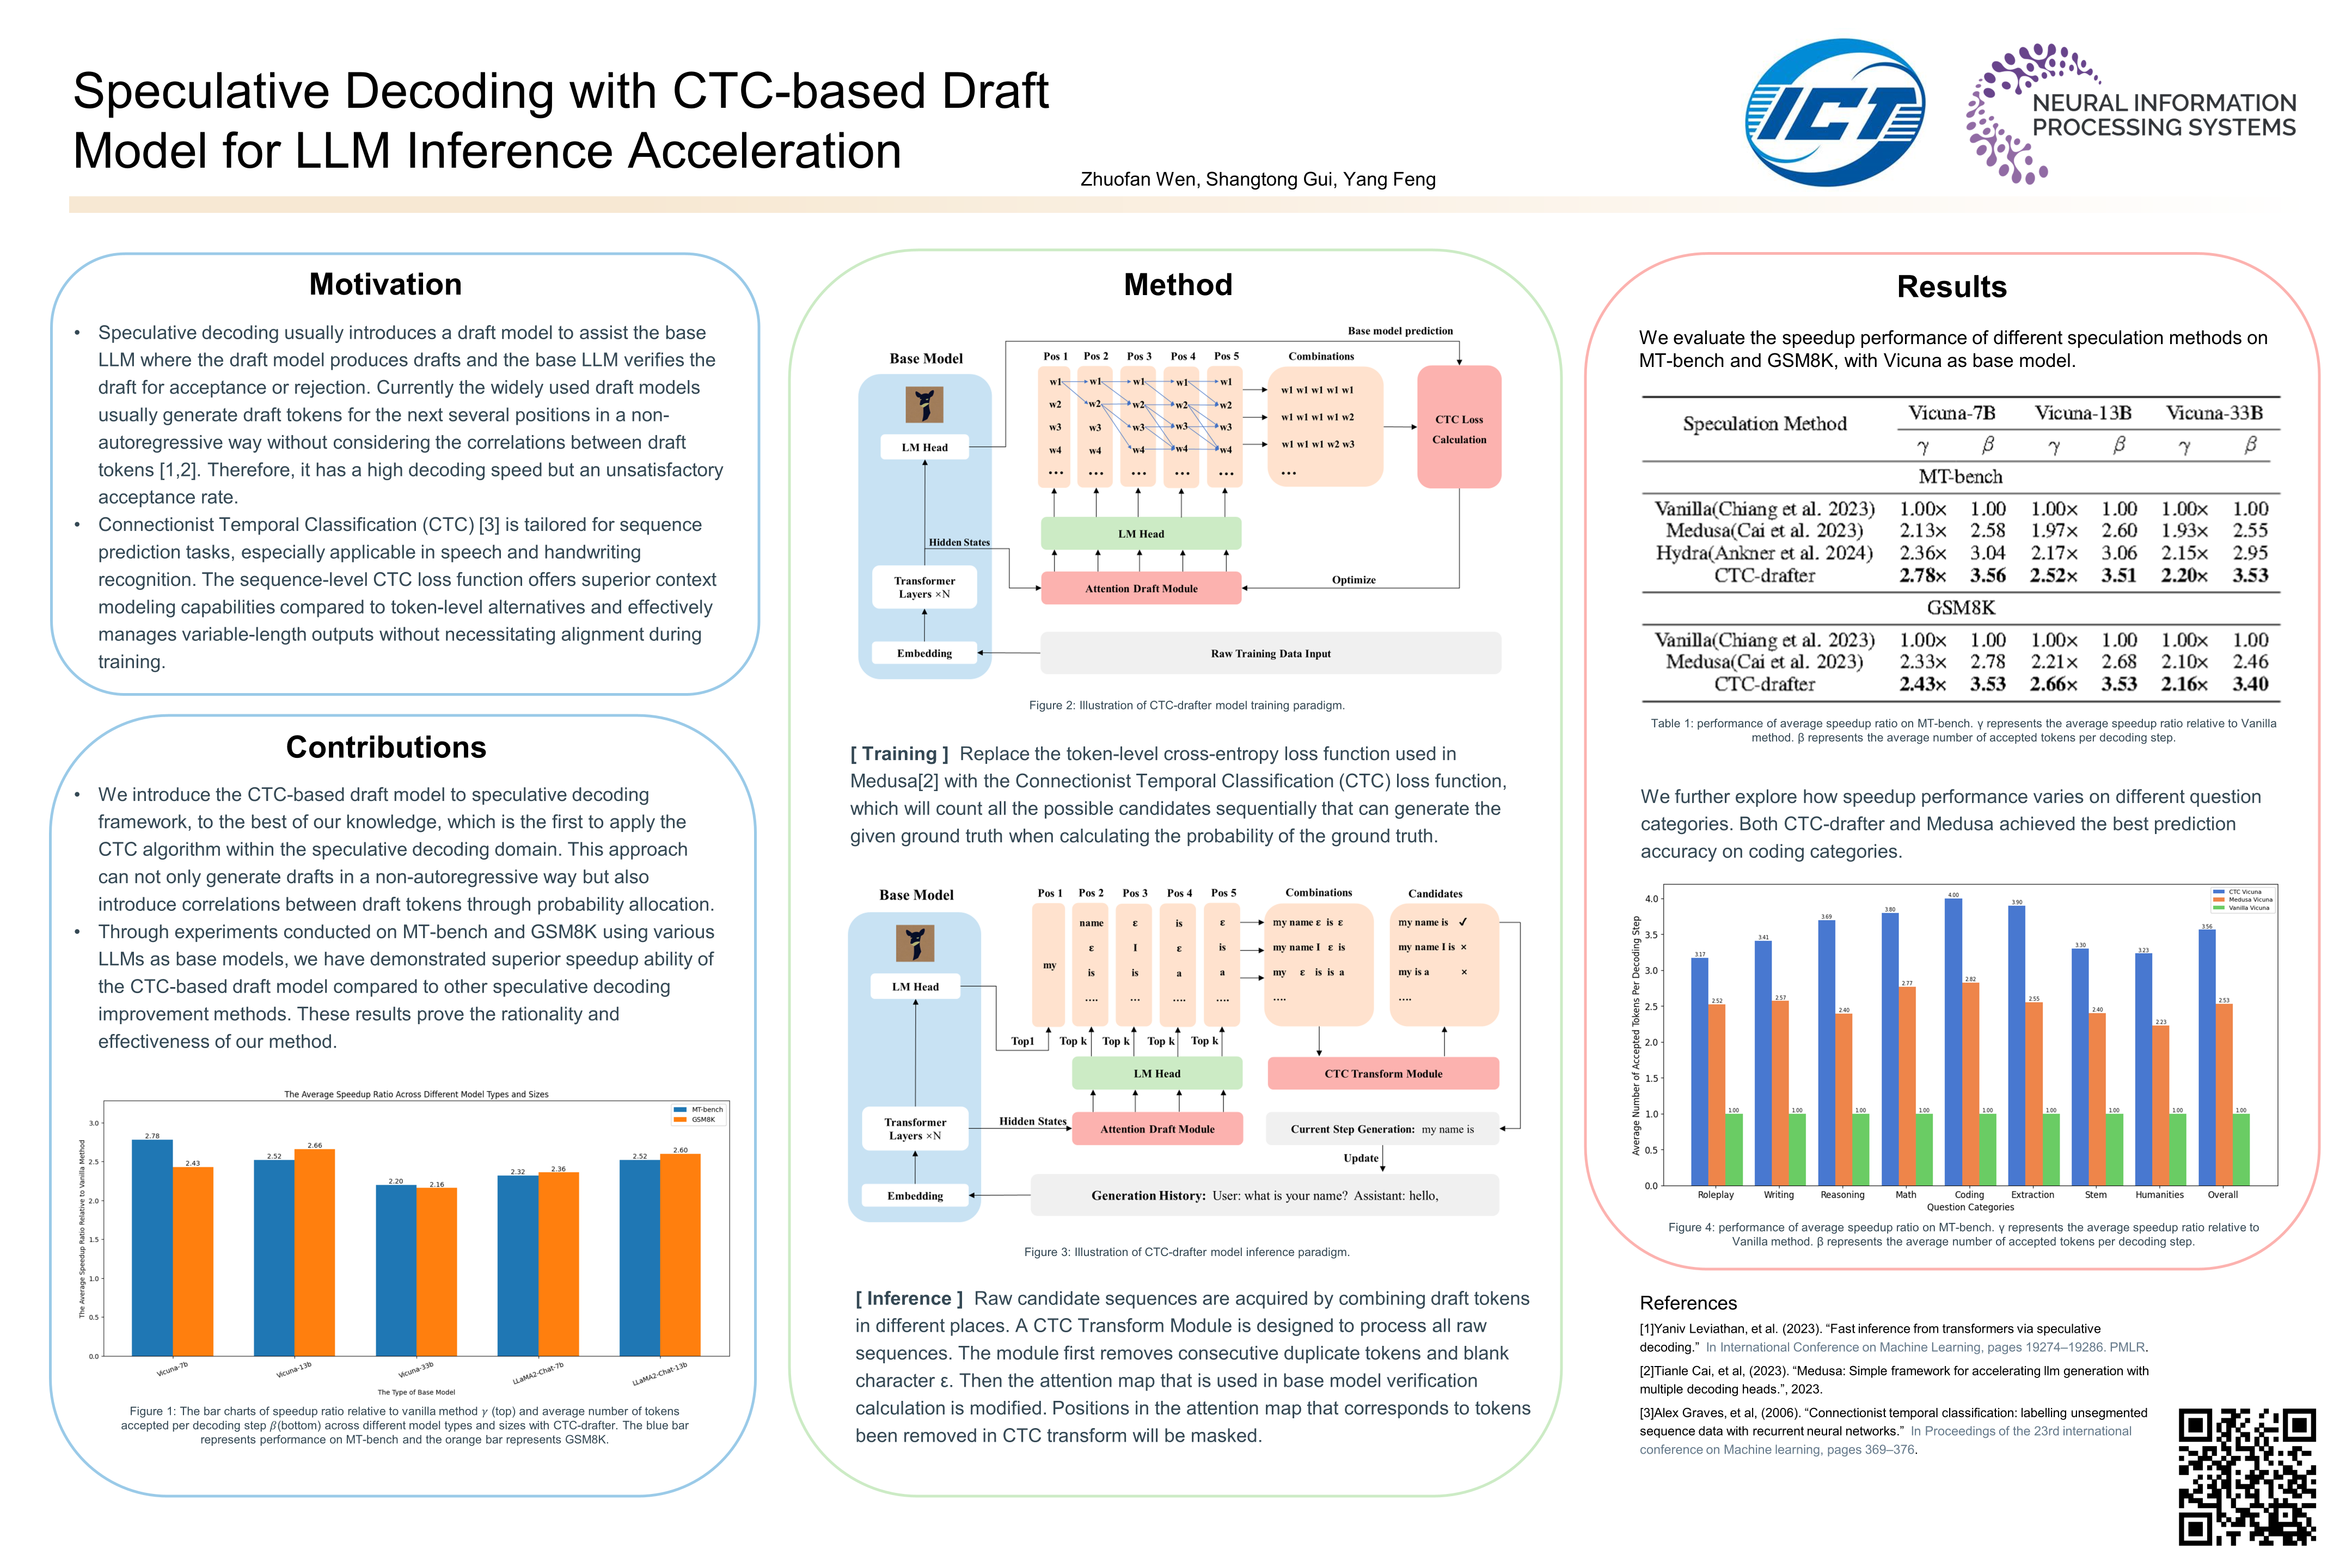
NeurIPS Poster Speculative Decoding with CTC-based Draft Model for LLM ...

Character Predictions for AAC Using LLMs | PDF | Computing
MLPerf Inference 5.1: Benchmarking Small LLMs with Llama3.1-8B - MLCommons

Diffusion LLMs and Faster-Than-Autoregressive Inference
Understanding LLMs from Training to Inference