
Draft Based Approximate Inference For Llms
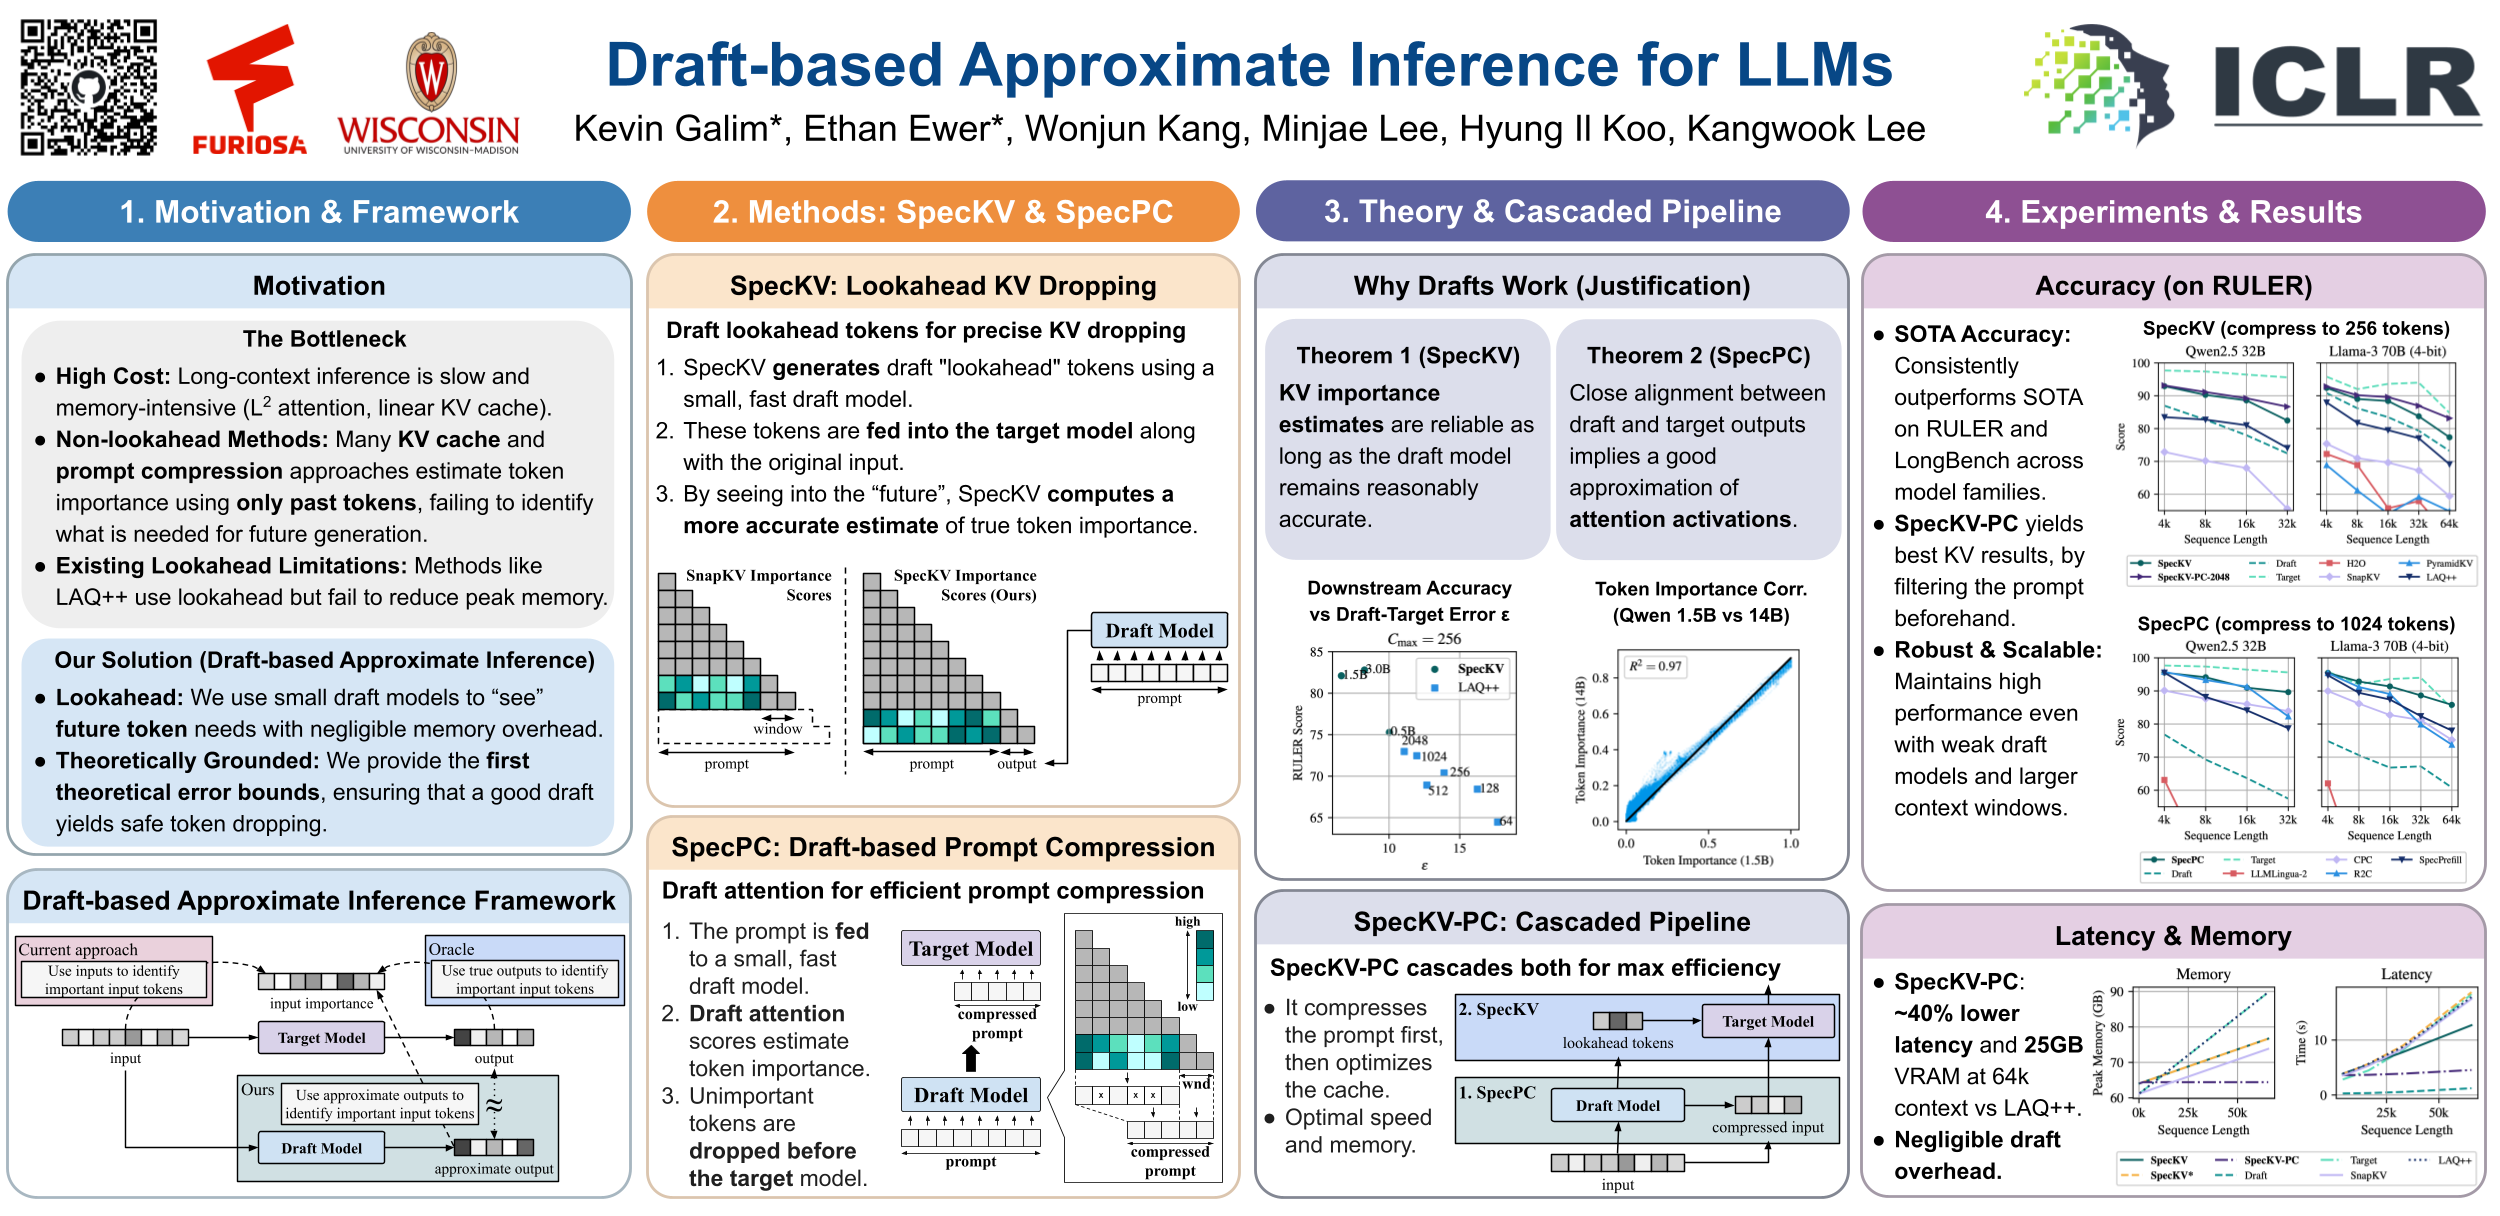
ICLR Poster Draft-based Approximate Inference for LLMs

[论文评述] Draft-based Approximate Inference for LLMs

Paper page - Draft-based Approximate Inference for LLMs
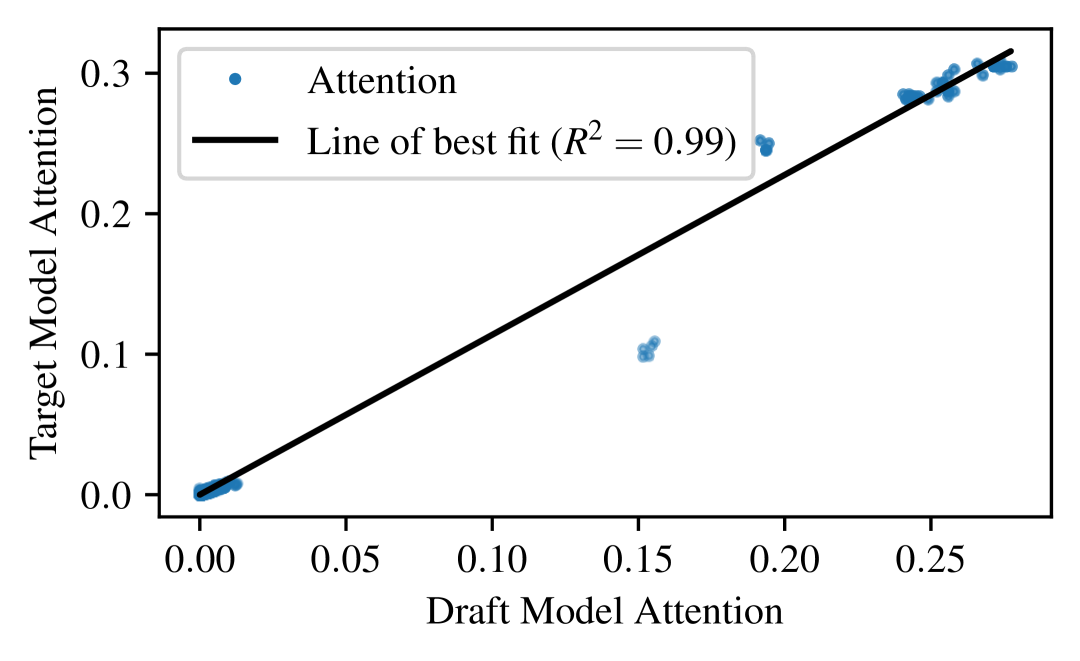
[2506.08373] Draft-based Approximate Inference for LLMs
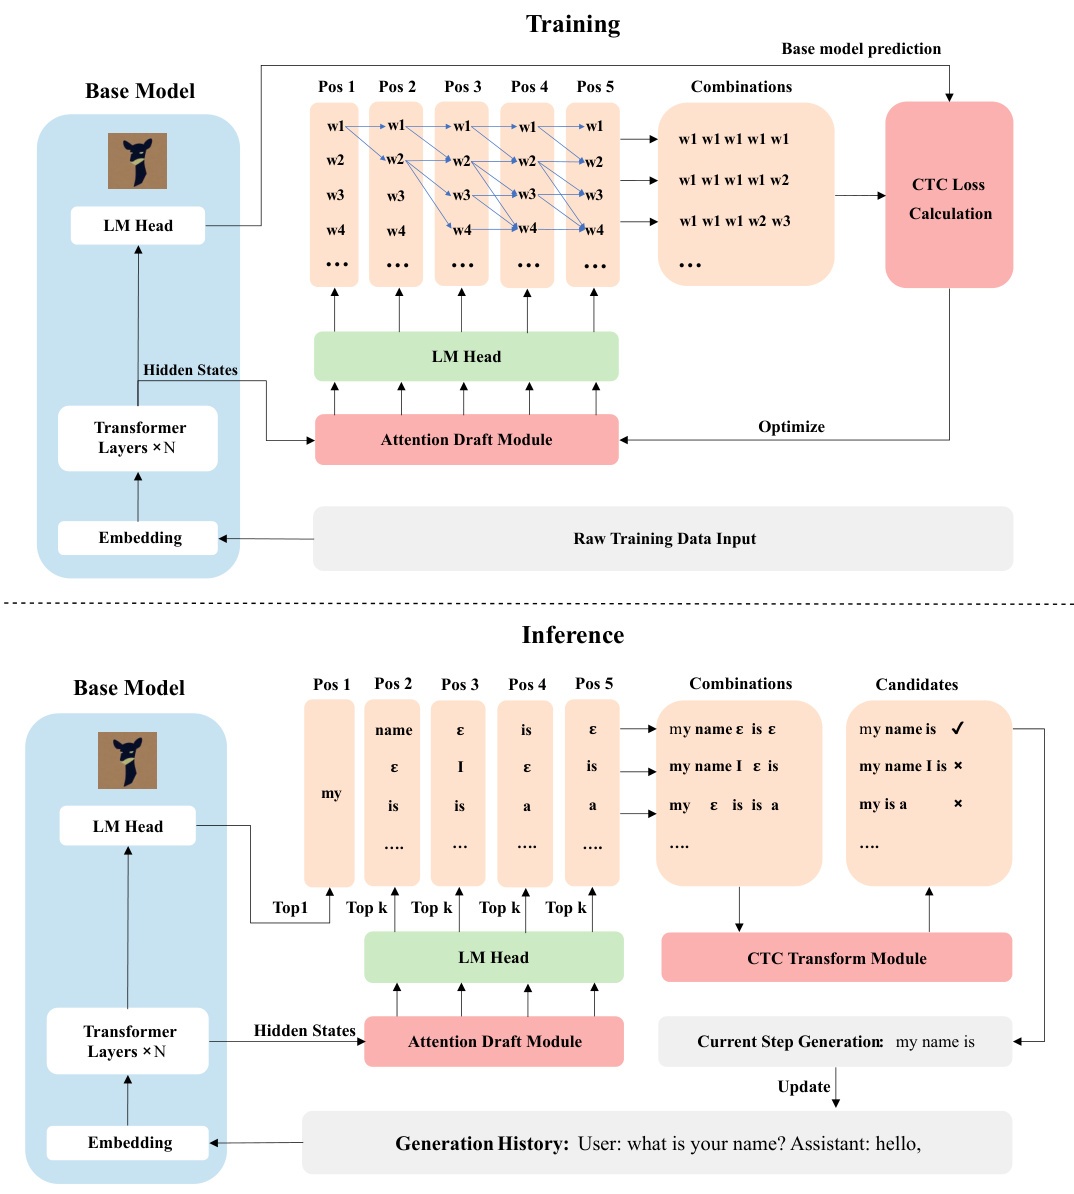
Speculative Decoding with CTC-based Draft Model for LLM Inference ...
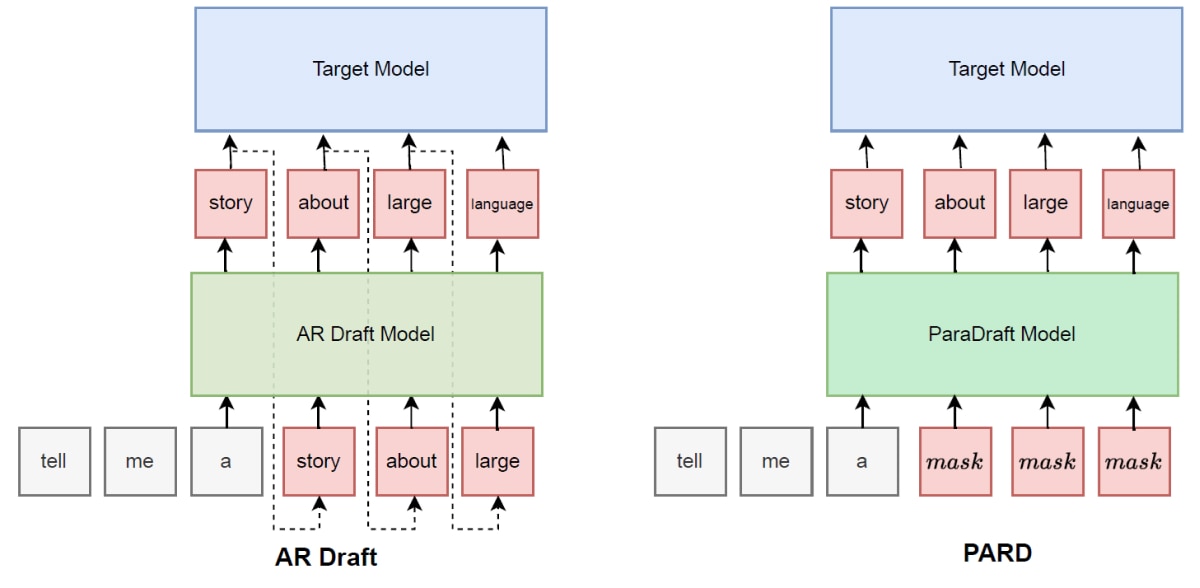
Accelerating Generative LLMs Inference with Parallel Draft Models (PARD)
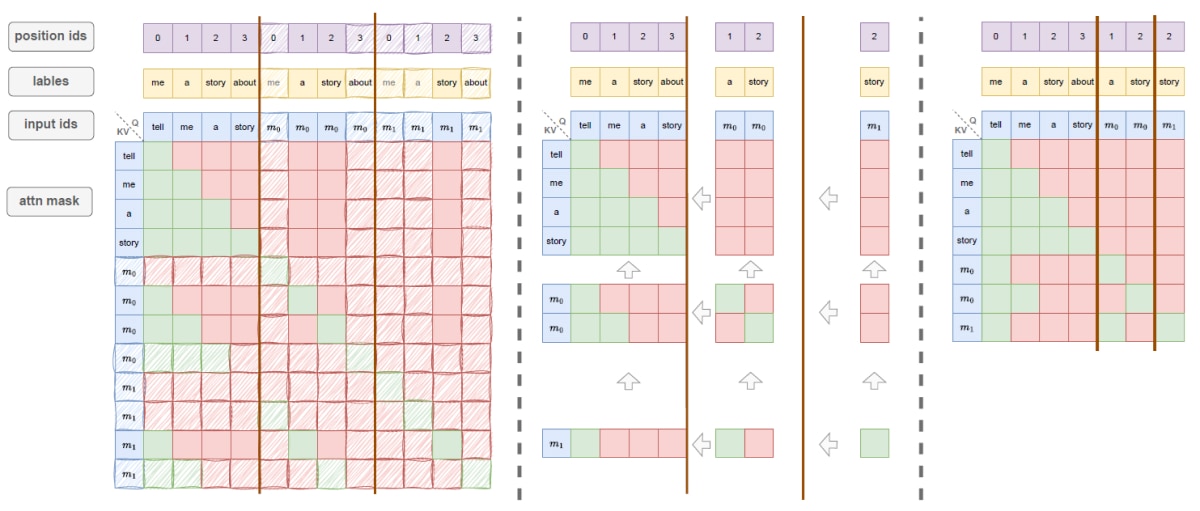
Accelerating Generative LLMs Inference with Parallel Draft Models (PARD)

Inference pipeline for LLMs - YouTube

SplitLLM: Collaborative Inference of LLMs for Model Placement and ...
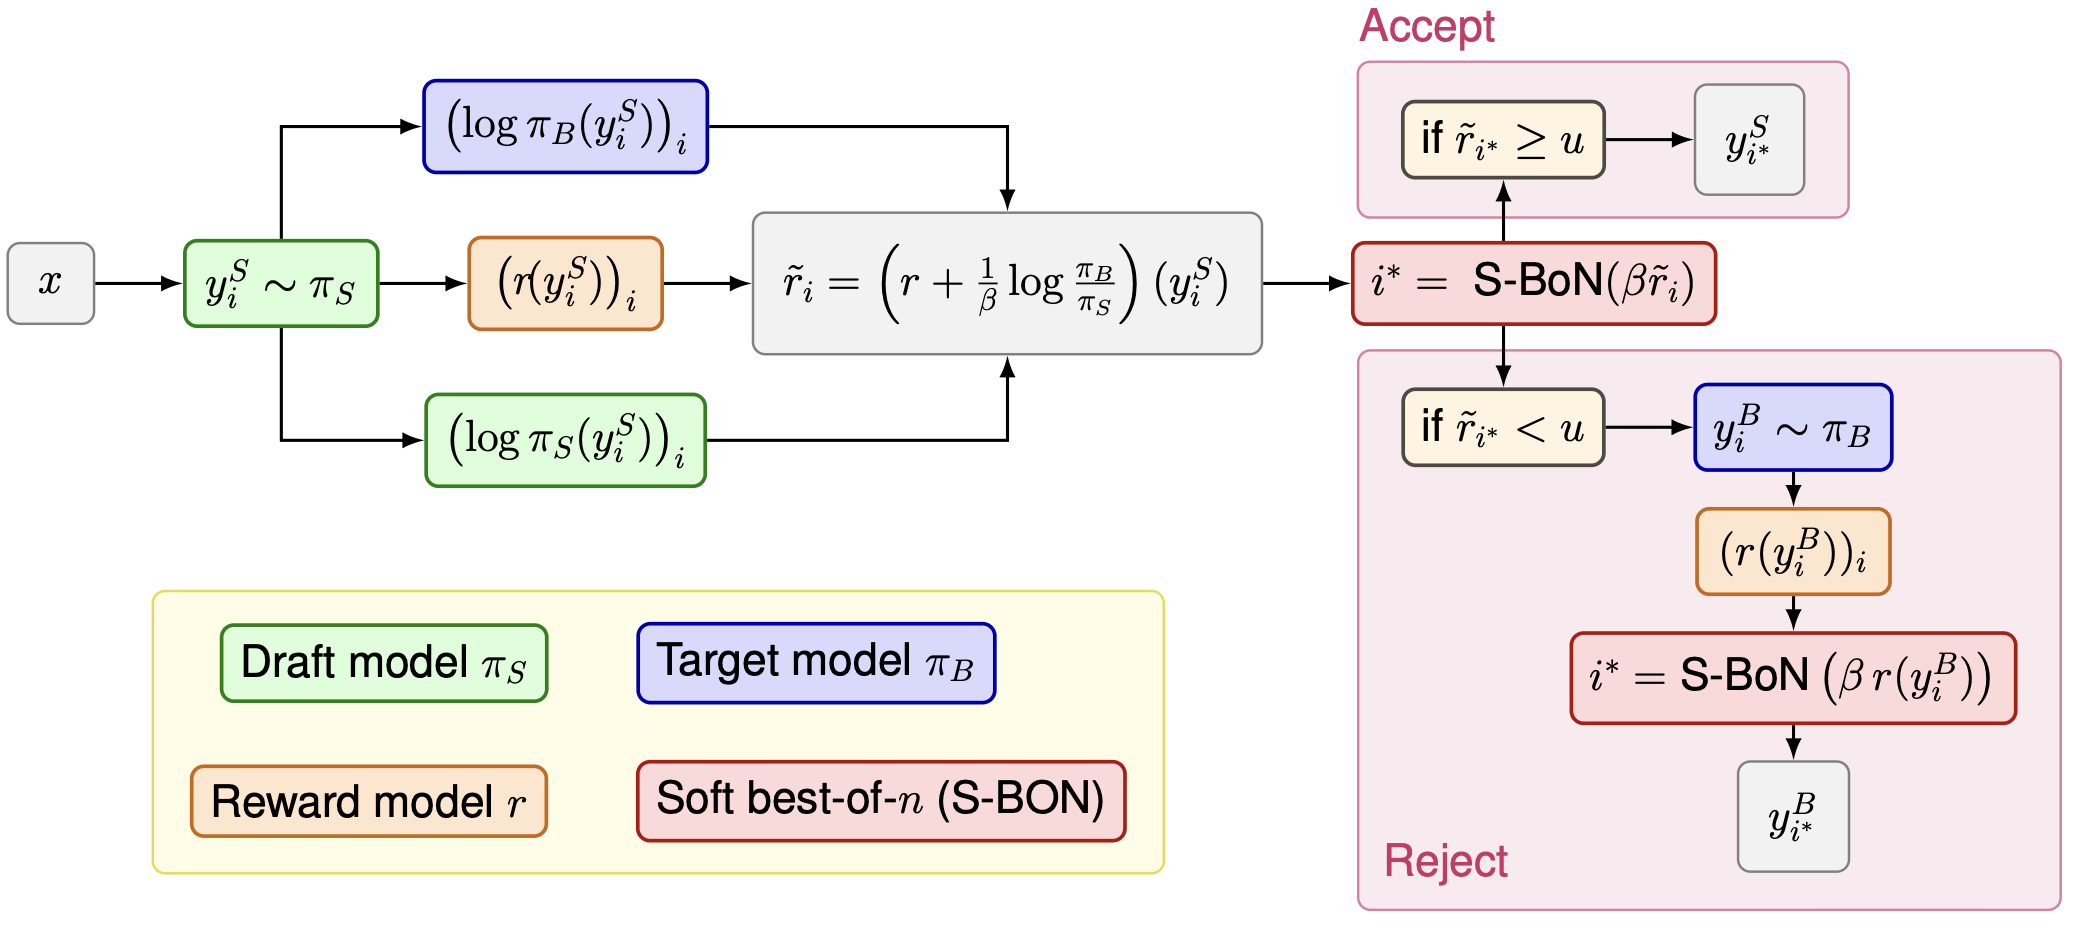
Guided Speculative Inference for Efficient Test-Time Alignment of LLMs ...
Advertisement Space (300x250)
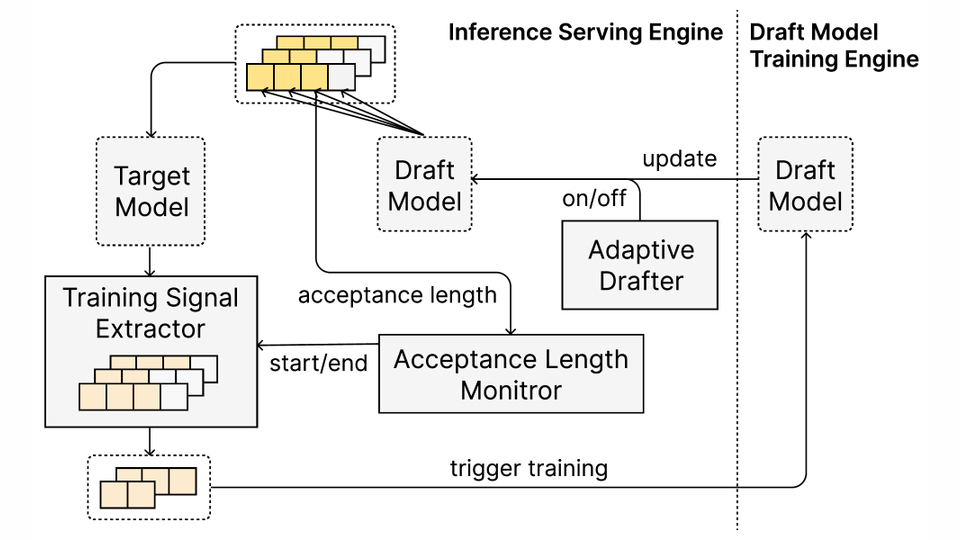
TIDE: Temporal Incremental Draft Engine for Self-Improving LLM ...

Position-Aware Drafting for Inference Acceleration in LLM-Based ...
A10, A16, Or 4090 For Llm Inference For Prompt Engineers? – QVWC
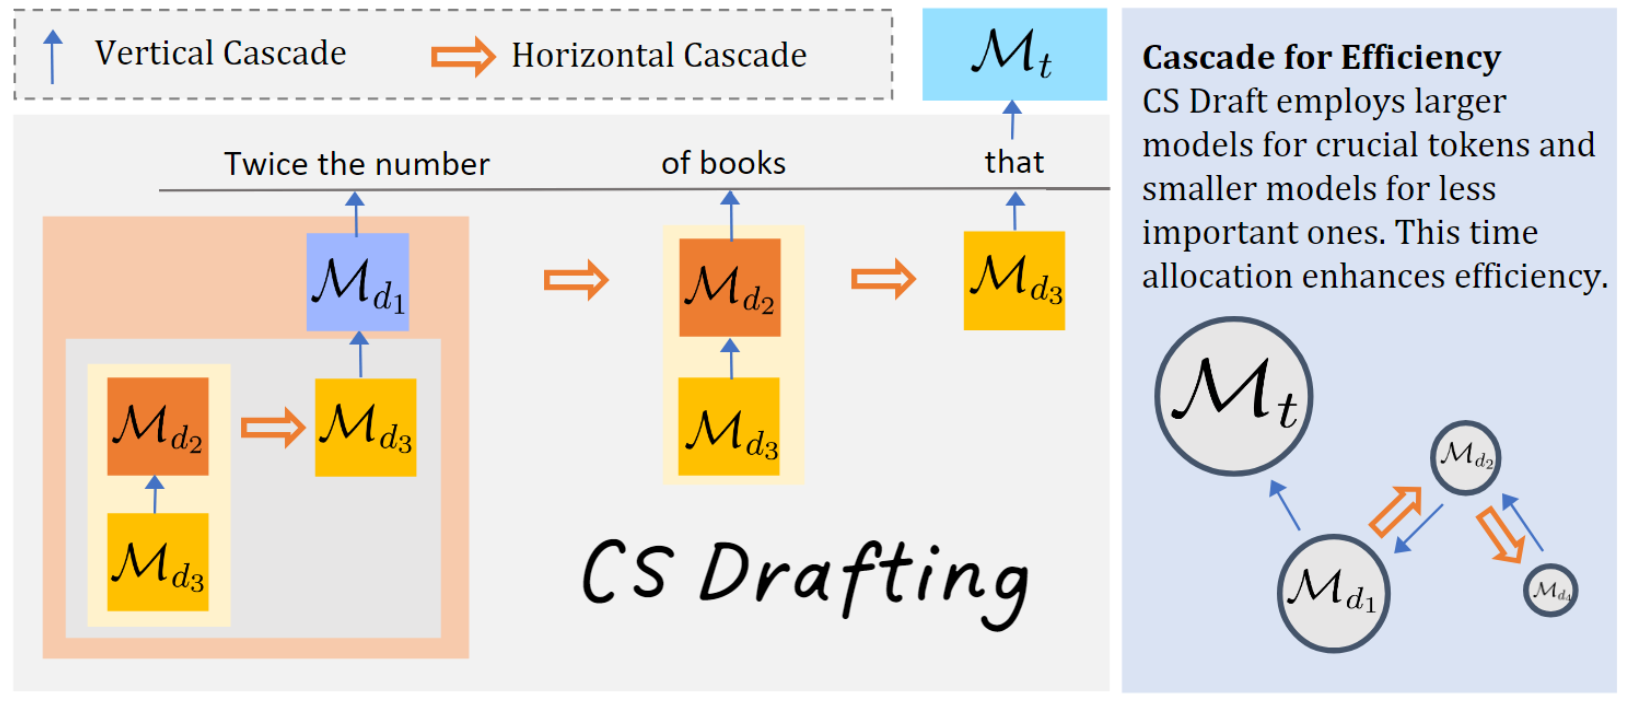
Cascade Speculative Drafting for Even Faster LLM Inference - 知乎
Inference of instruction tuned LLMs using edit operations. LLMs take ...
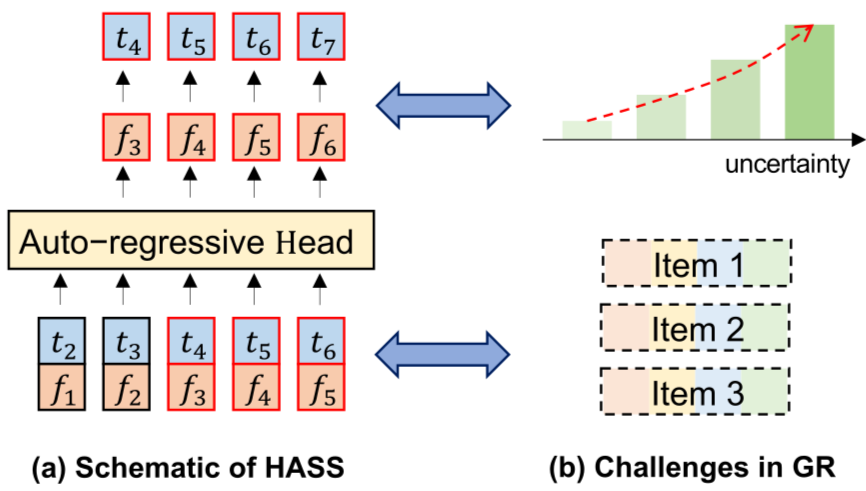
[Revisión de artículo] Position-Aware Drafting for Inference ...

Serving Inference for LLMs: A Case Study with NVIDIA Triton Inference ...

Vidur: A Large-Scale Simulation Framework for LLM Inference Performance ...

Paper page - Cascade Speculative Drafting for Even Faster LLM Inference

Combining Large and Small LLMs to Boost Inference Time and Quality ...
Advertisement Space (336x280)
Vidur: A Large-Scale Simulation Framework for LLM Inference Performance ...

Position-Aware Drafting for Inference Acceleration in LLM-Based ...

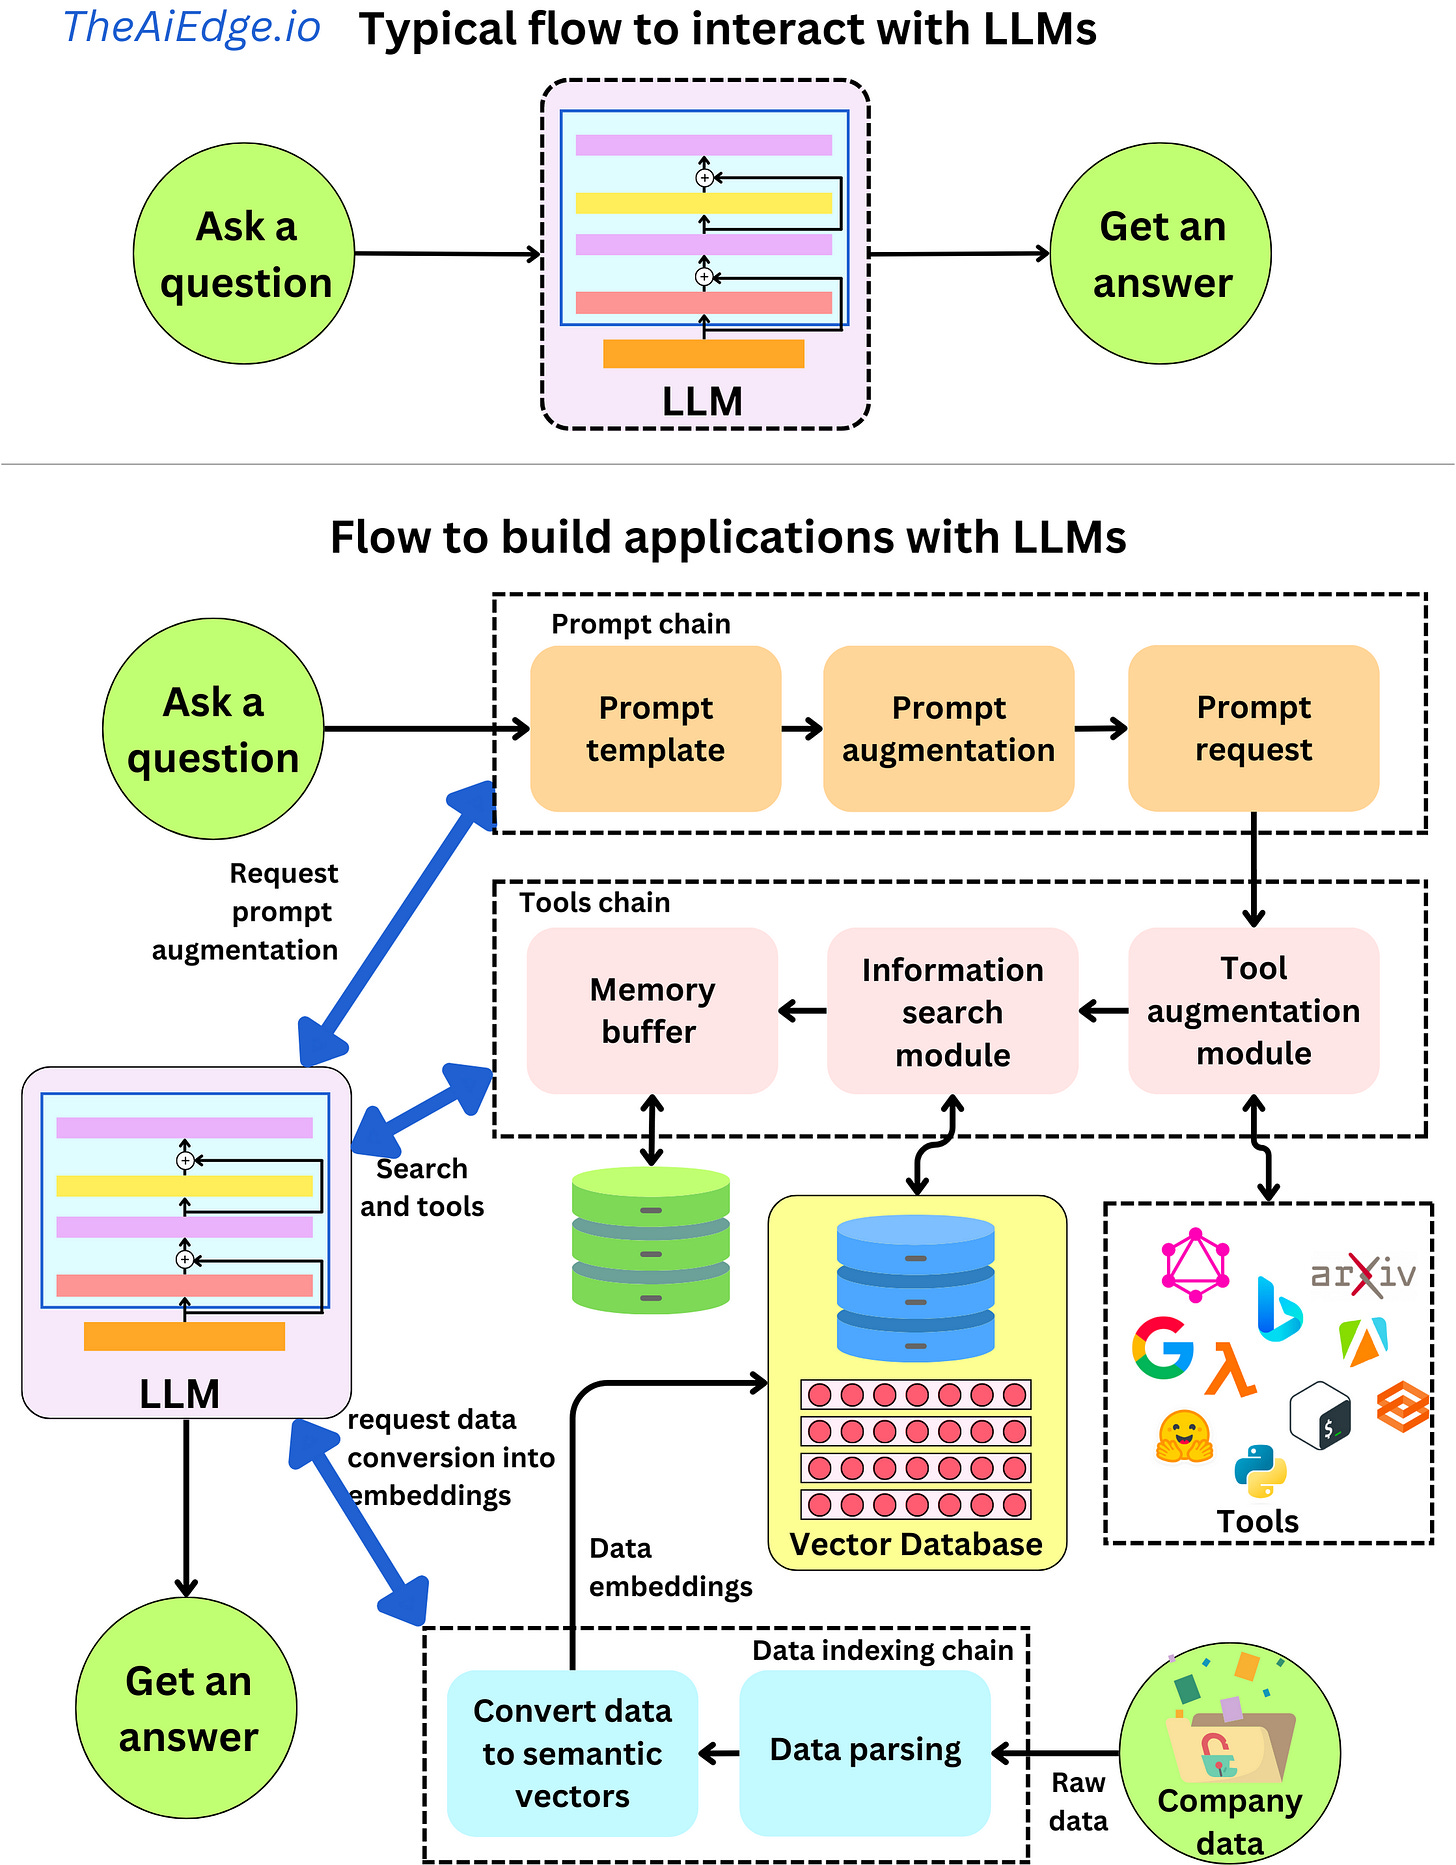
How to Build LLM Inference Pipelines for Enterprise Apps

Approximate Inference Algorithms | PDF
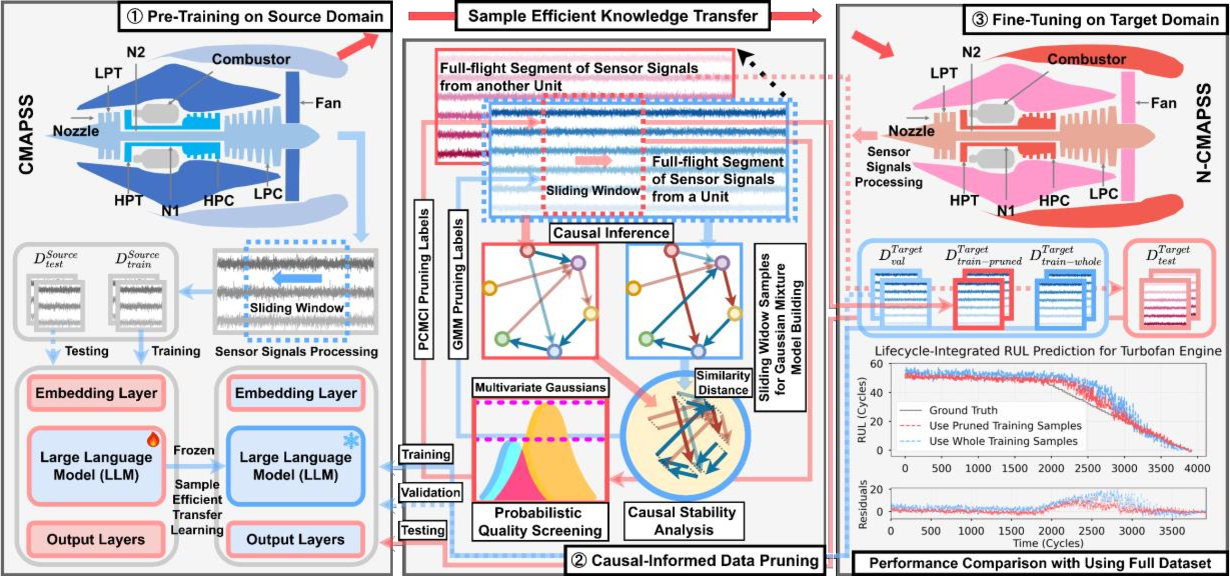
Figure 1 from Causal Inference based Transfer Learning with LLMs: An ...
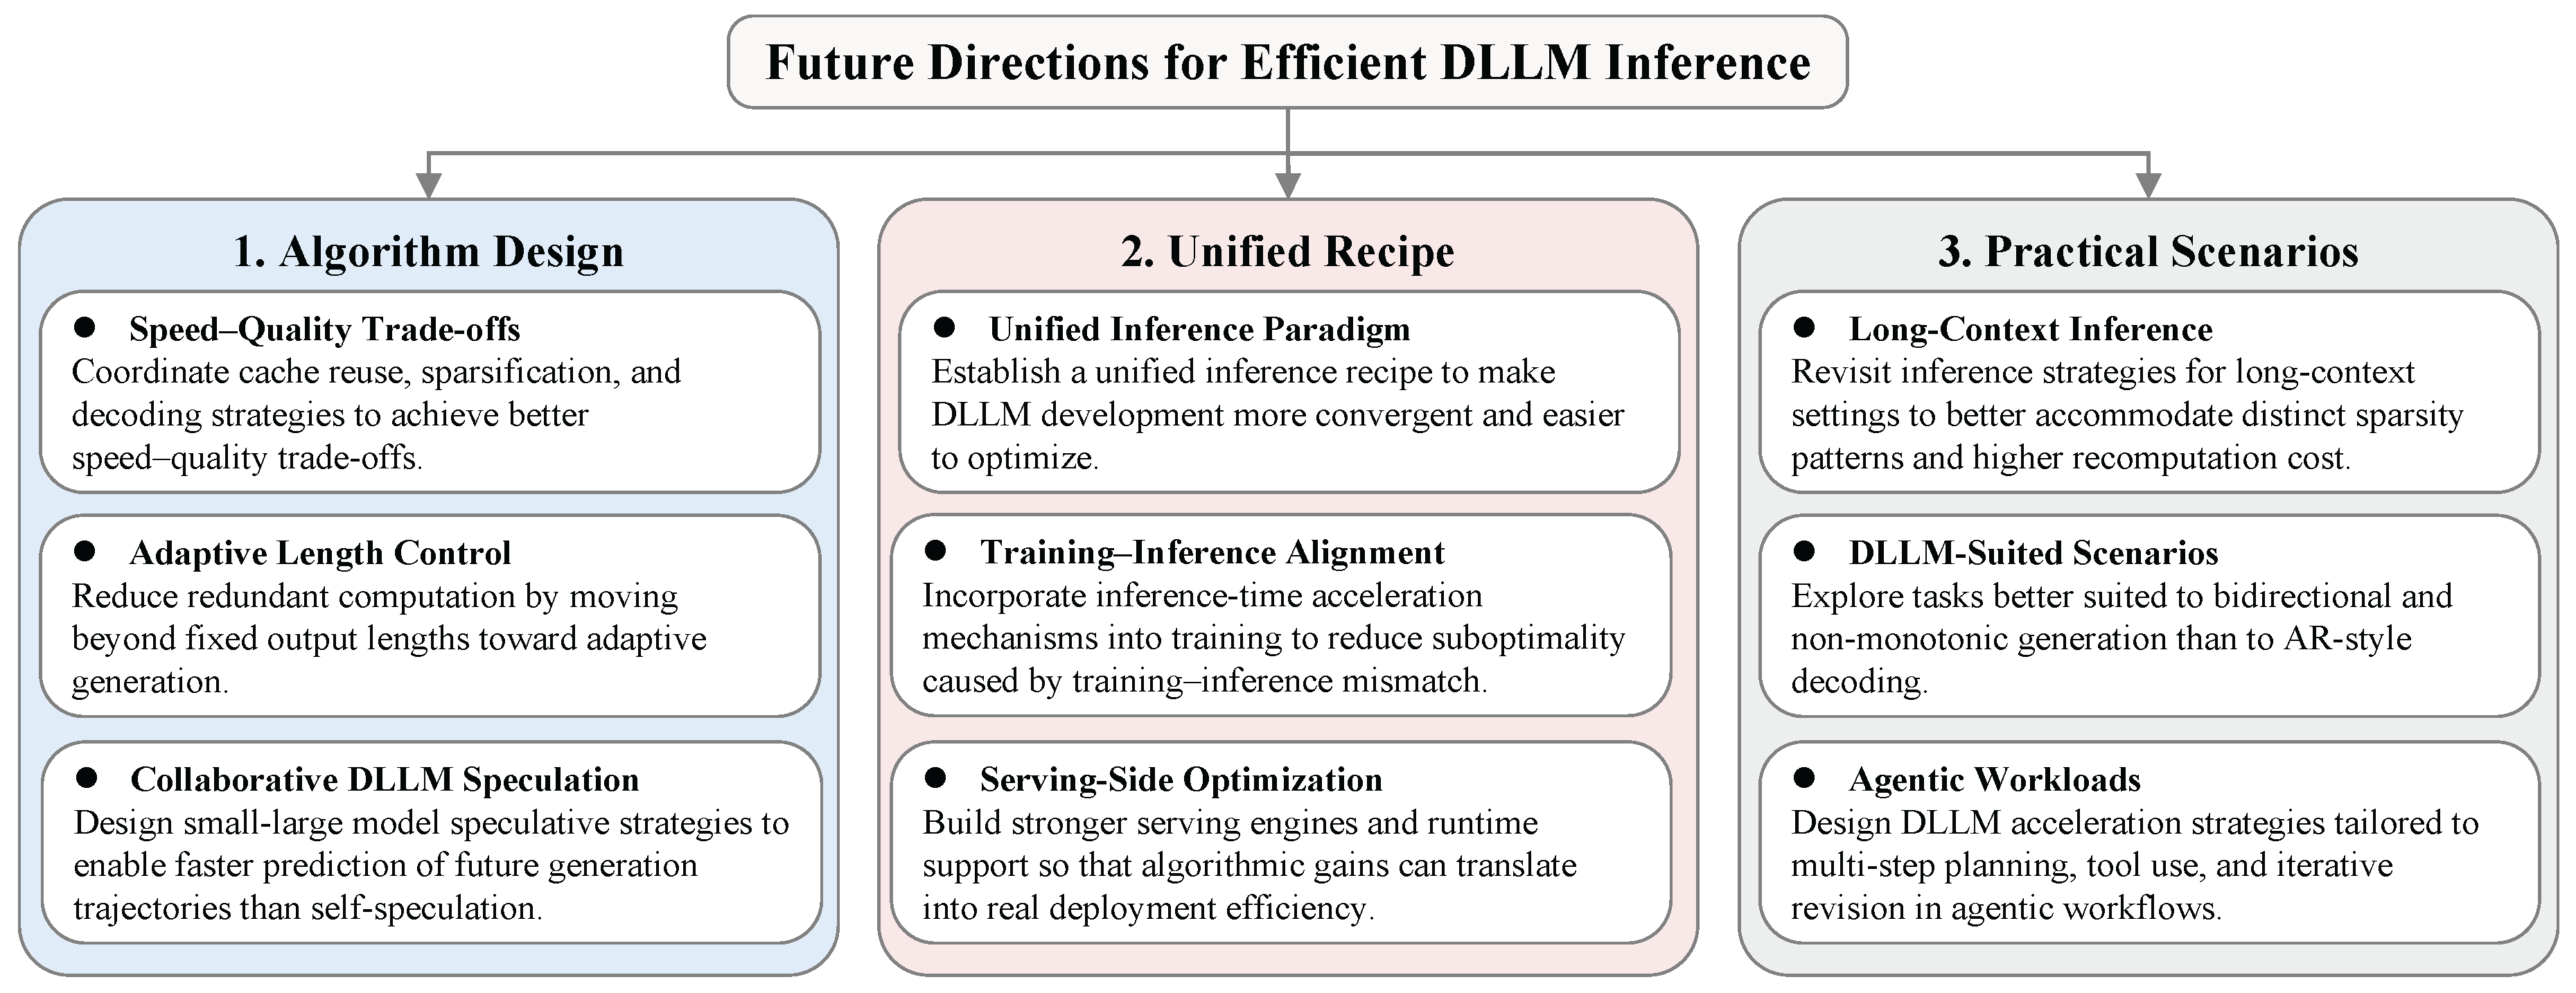
A Comparative Survey of Inference Acceleration for DLLMs against AR ...
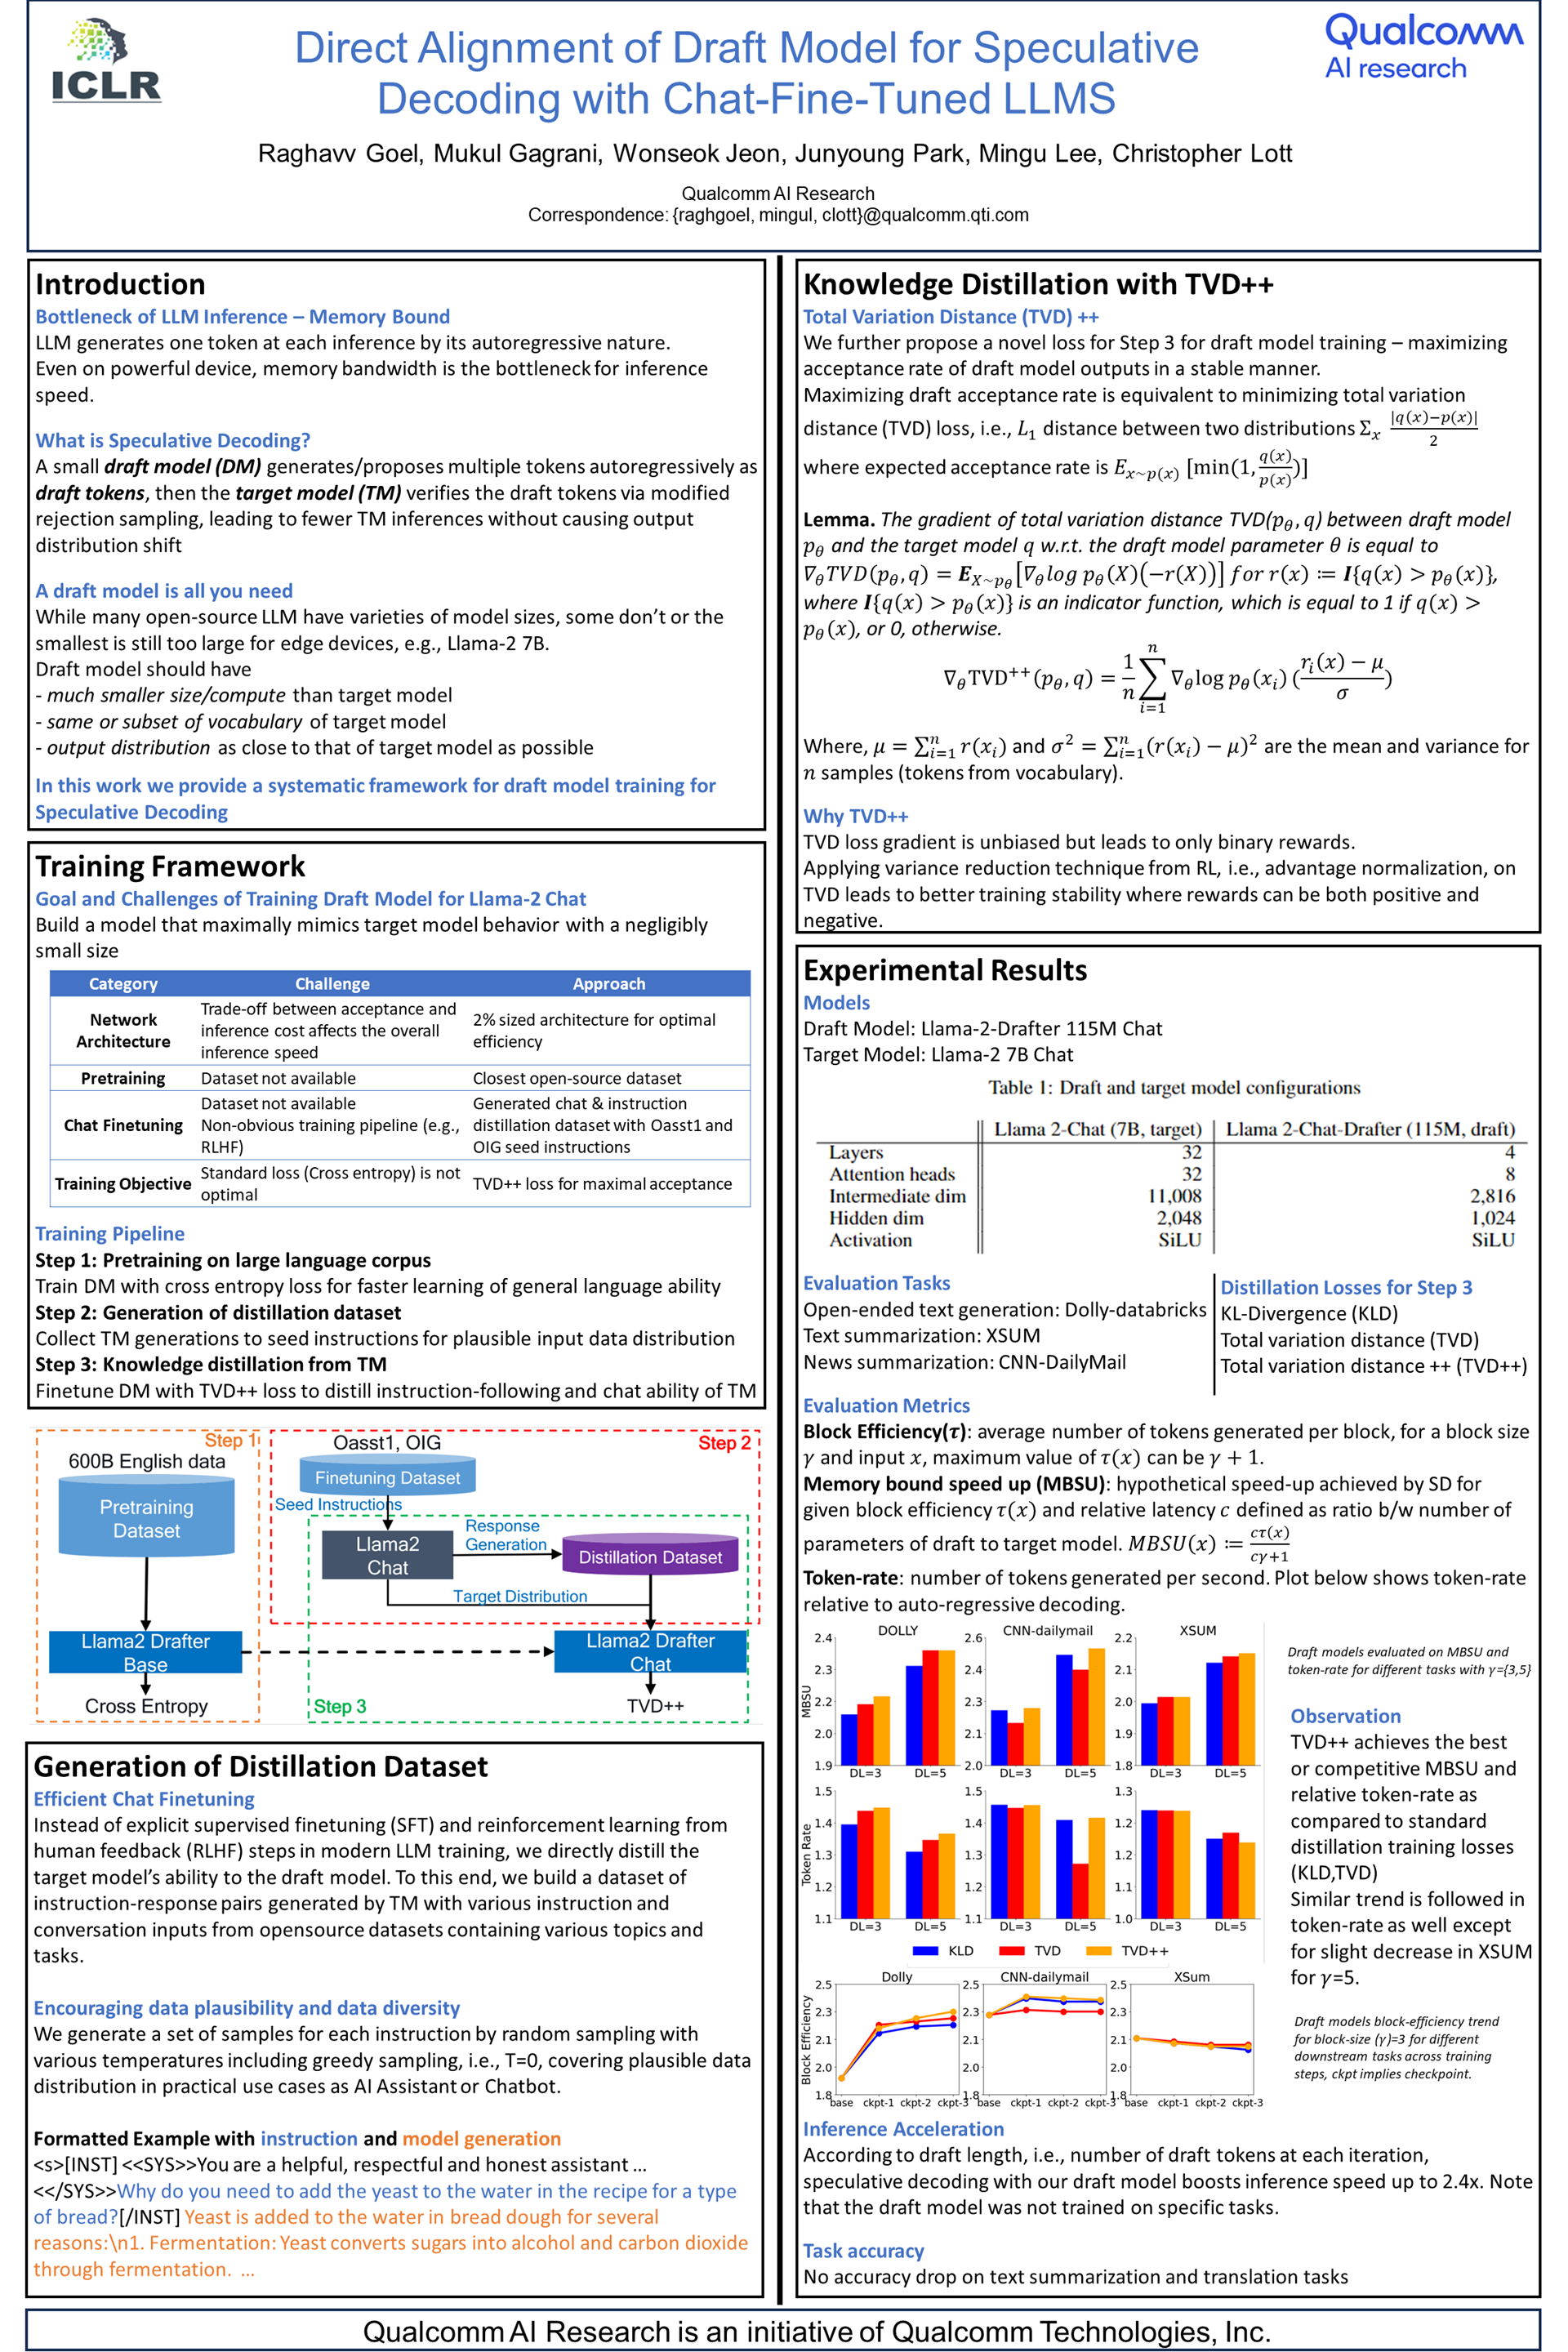
ICLR Direct Alignment of Draft Model for Speculative Decoding with Chat ...
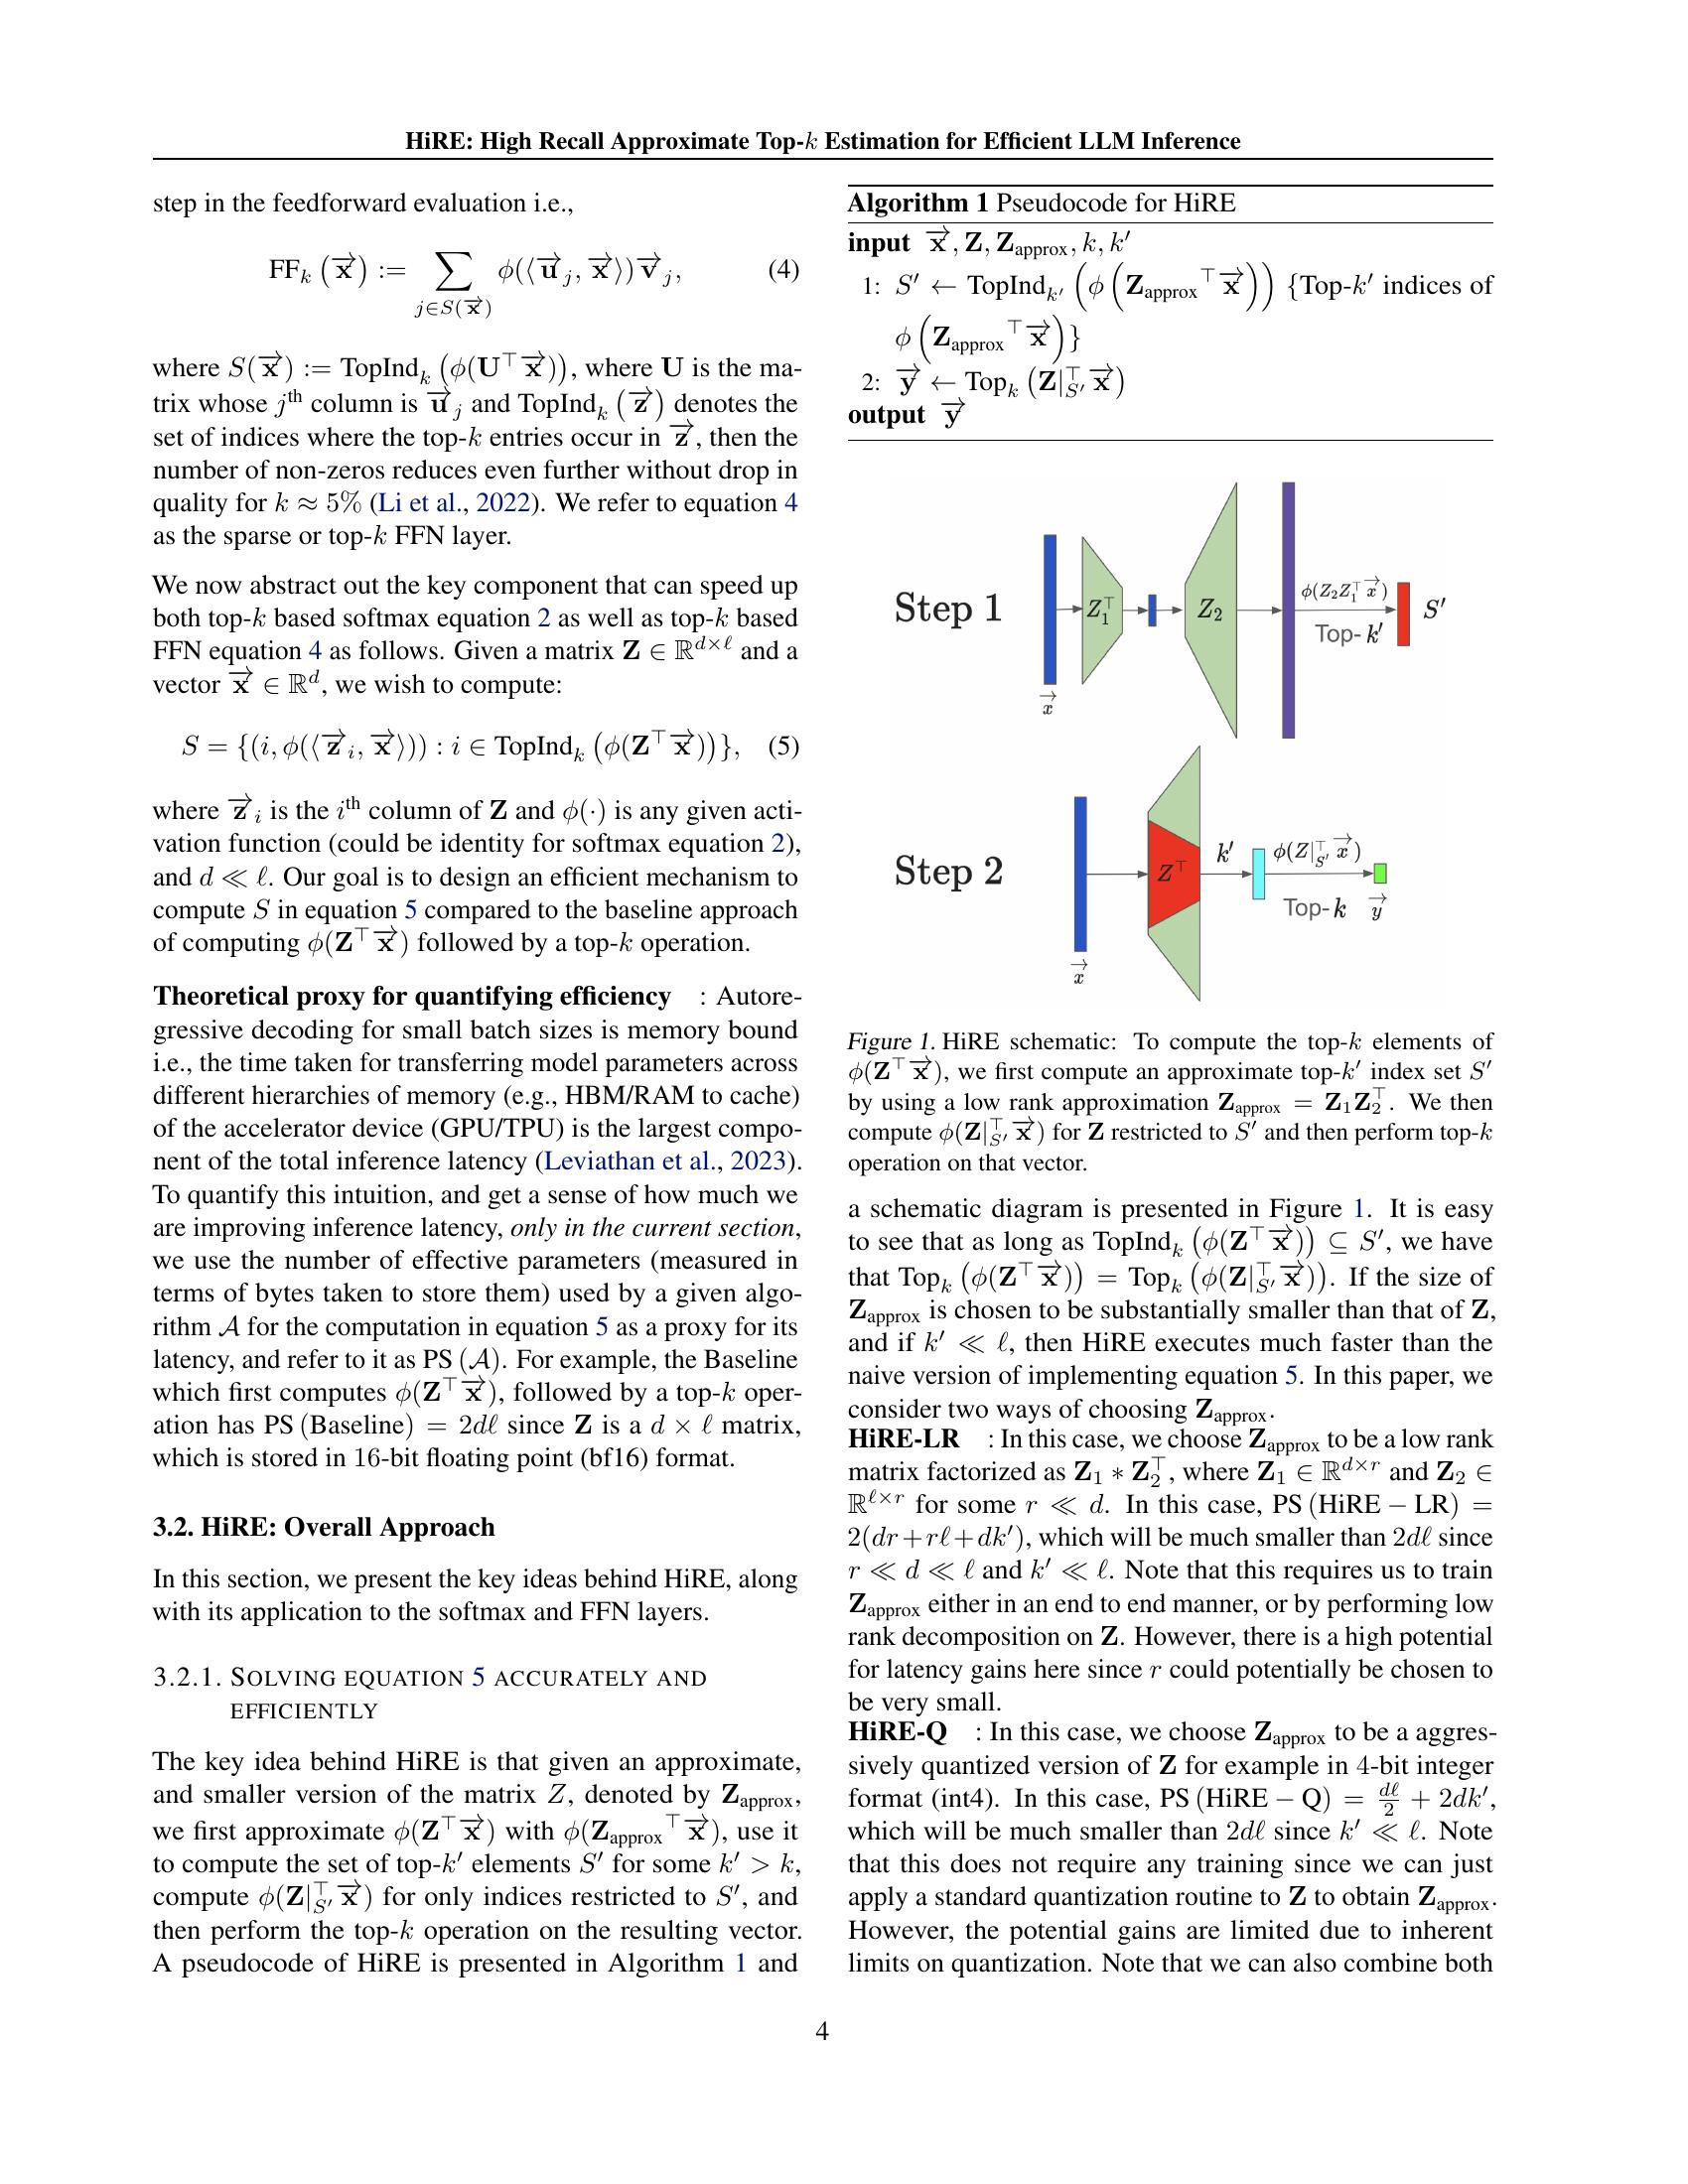
HiRE: High Recall Approximate Top-$k$ Estimation for Efficient LLM ...
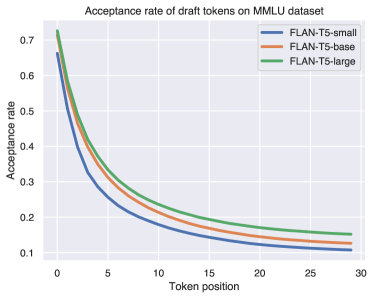
[2312.11462] Cascade Speculative Drafting for Even Faster LLM Inference

A Probabilistic Inference Approach to Inference-Time Scaling of LLMs ...
Advertisement Space (336x280)

The Ongoing Case For Open Source LLMs Custom LLMs, long context, and ...
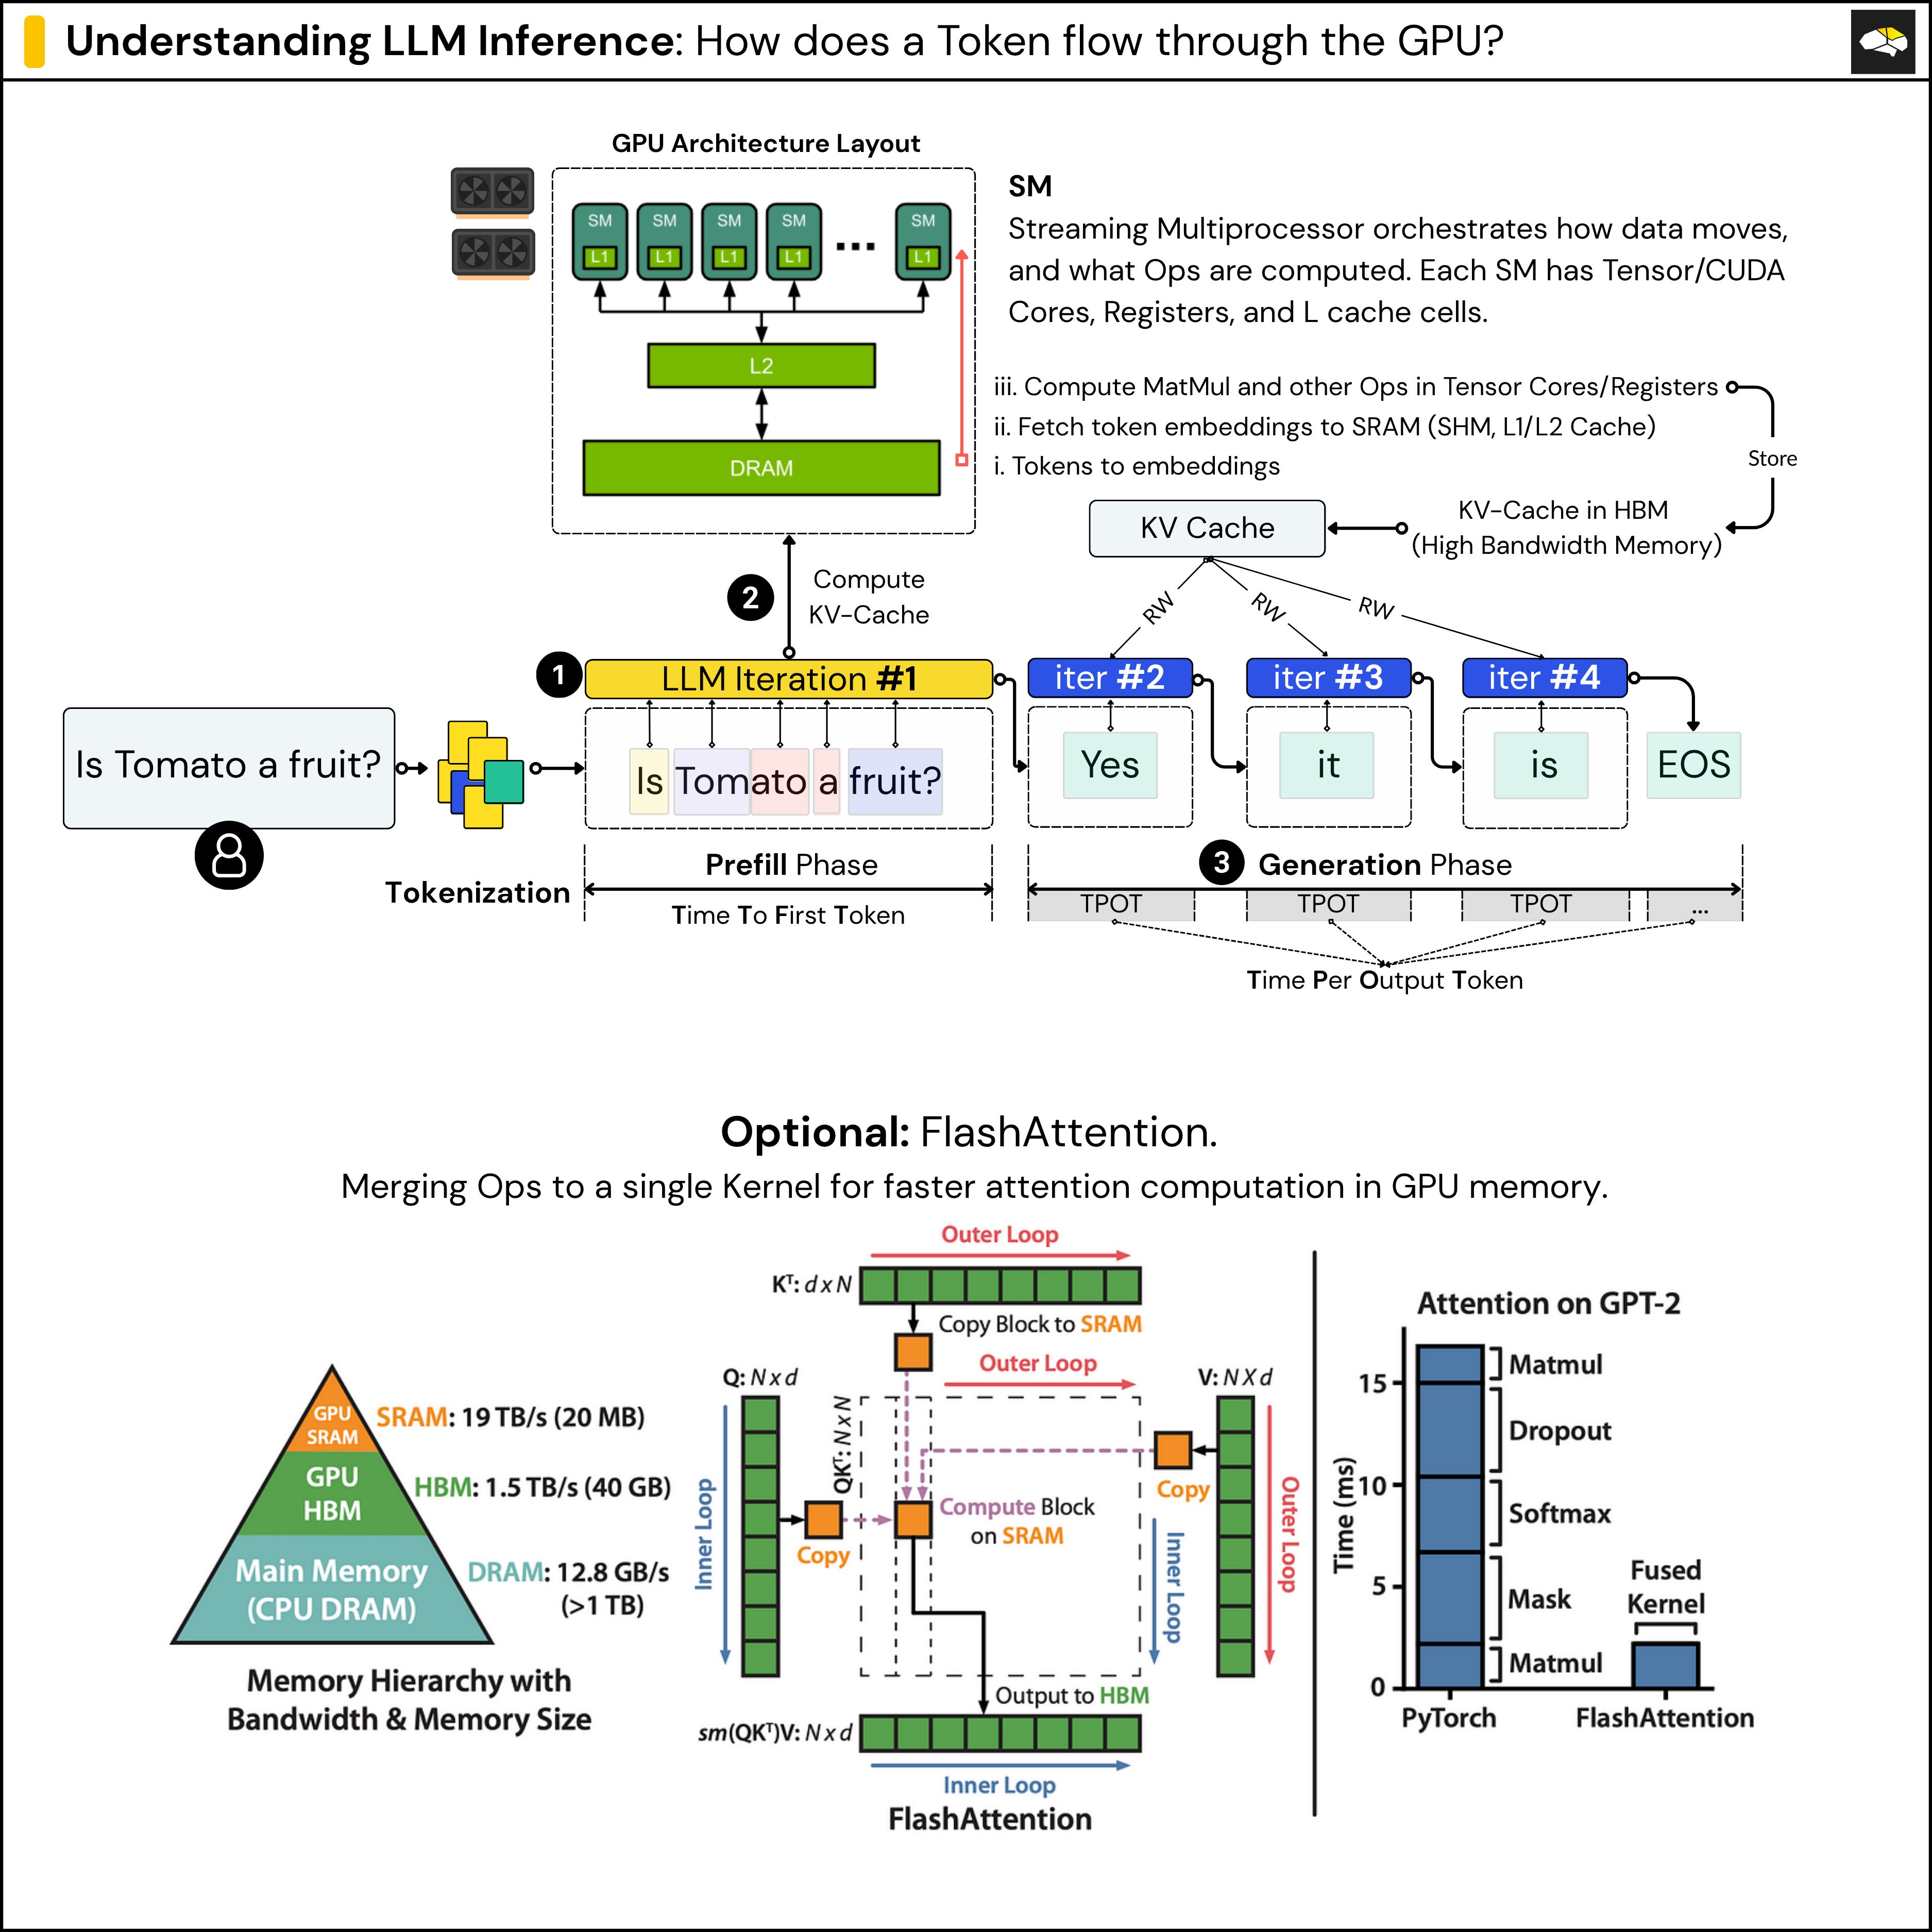
Understanding LLM Inference - by Alex Razvant
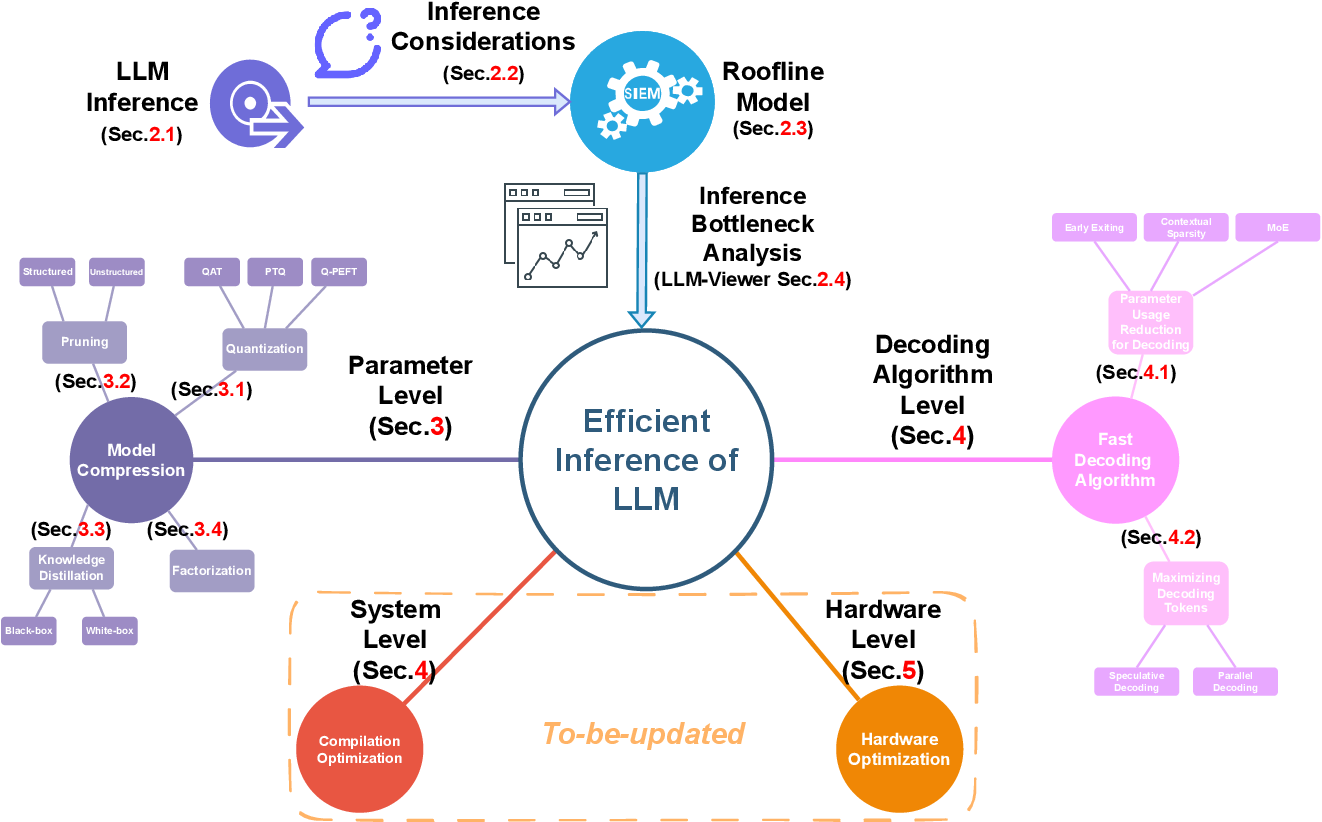
LLM Inference Unveiled: Survey and Roofline Model Insights
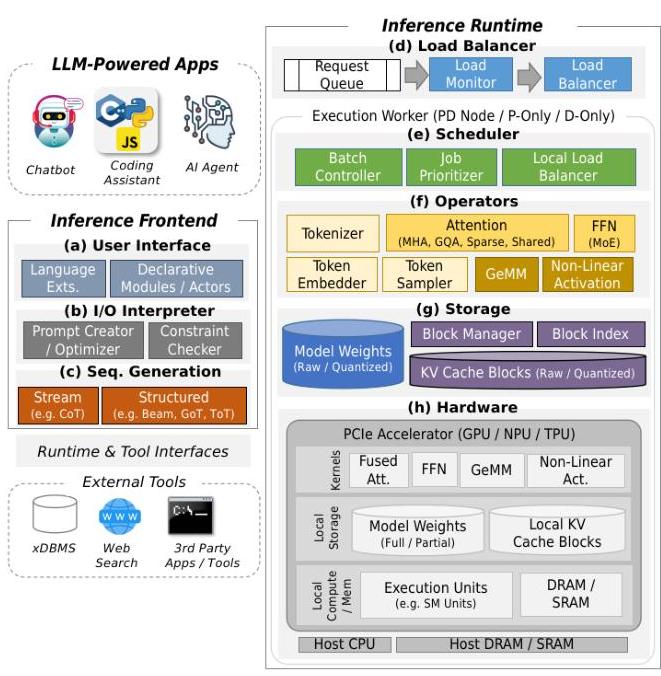
A Survey of LLM Inference Systems | alphaXiv
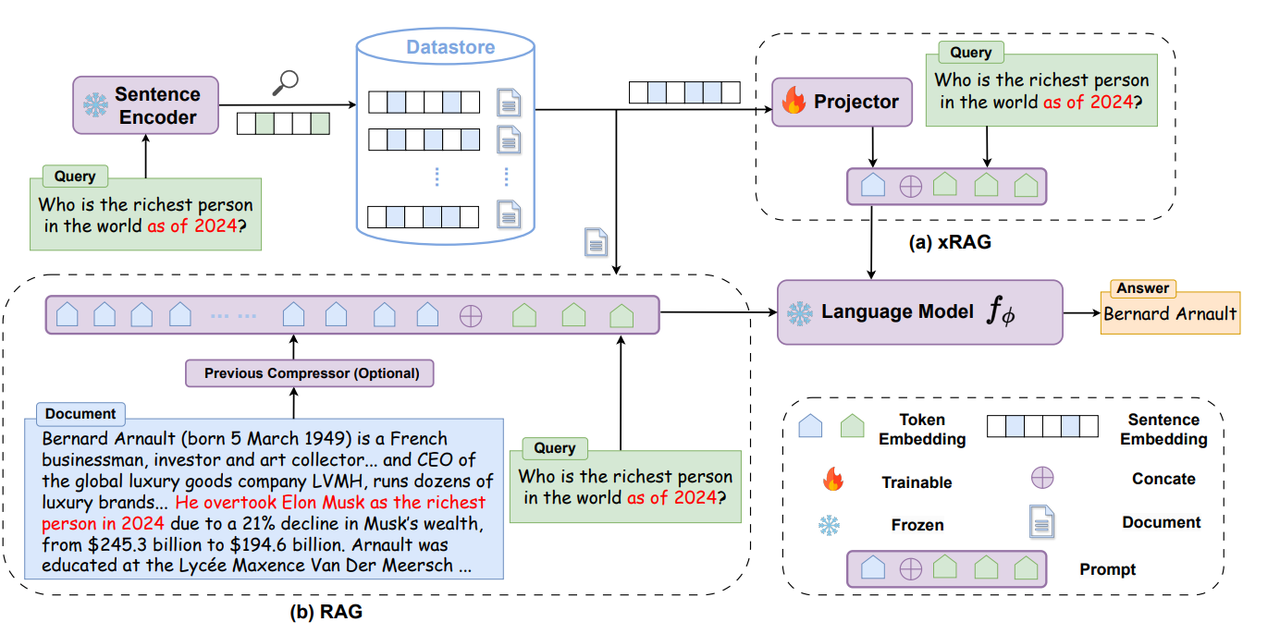
LLM Inference Optimization Overview - From Data to System Architecture ...

LLM Inference Guide: 12 Proven Ways To Speed Up AI Models