
Paper Page Draft Based Approximate Inference For Llms

Paper page - Draft-based Approximate Inference for LLMs

Paper page - Ltri-LLM: Streaming Long Context Inference for LLMs with ...
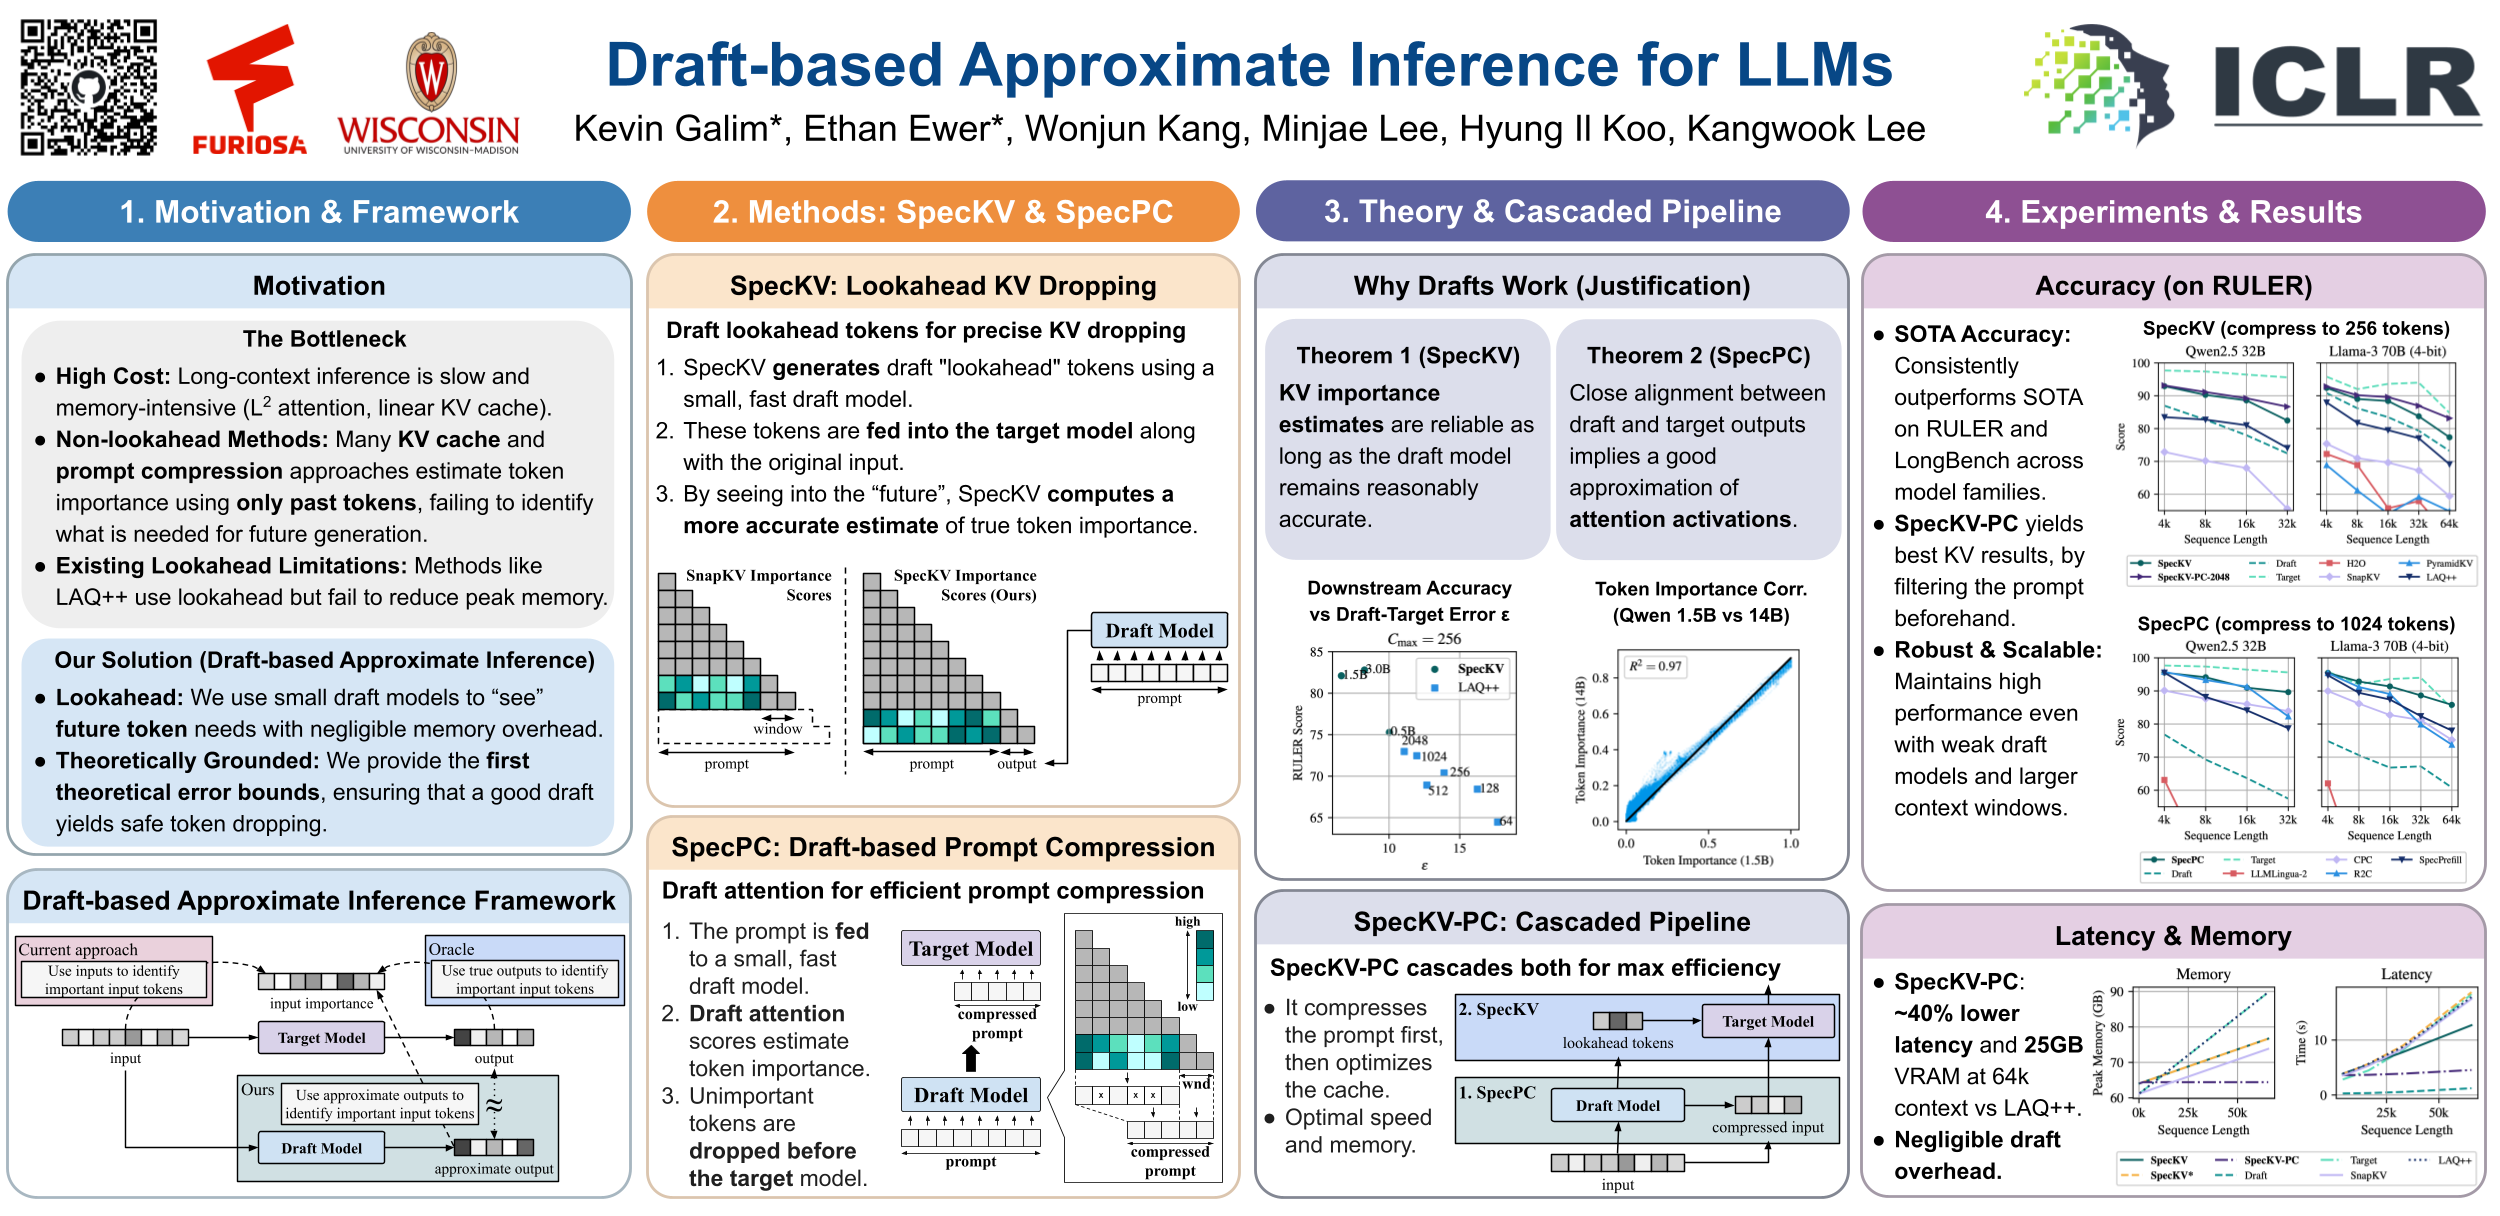
ICLR Poster Draft-based Approximate Inference for LLMs

[论文评述] Draft-based Approximate Inference for LLMs
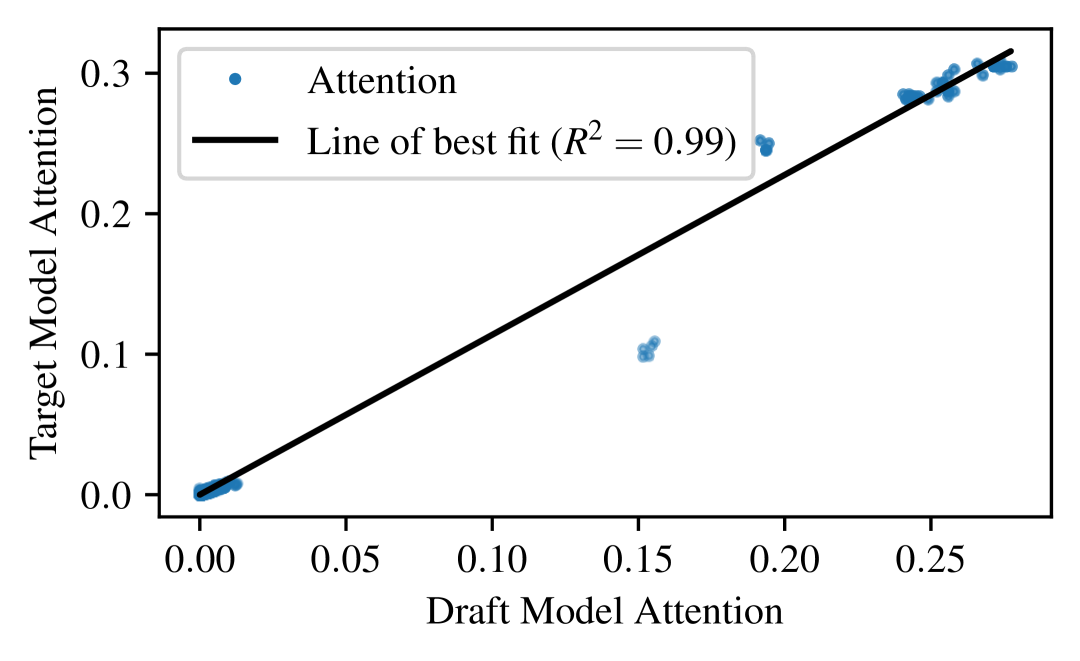
[2506.08373] Draft-based Approximate Inference for LLMs

Paper page - Not all Layers of LLMs are Necessary during Inference

Paper page - PICE: A Semantic-Driven Progressive Inference System for ...

Paper page - Deja Vu: Contextual Sparsity for Efficient LLMs at ...

Paper page - Agentic Reasoning and Tool Integration for LLMs via ...

Paper page - Who's Harry Potter? Approximate Unlearning in LLMs
Advertisement Space (300x250)

Paper page - REAL: Response Embedding-based Alignment for LLMs

Paper page - Dynamic Memory Compression: Retrofitting LLMs for ...

Paper page - Few-shot training LLMs for project-specific code-summarization

Paper page - QuaRot: Outlier-Free 4-Bit Inference in Rotated LLMs
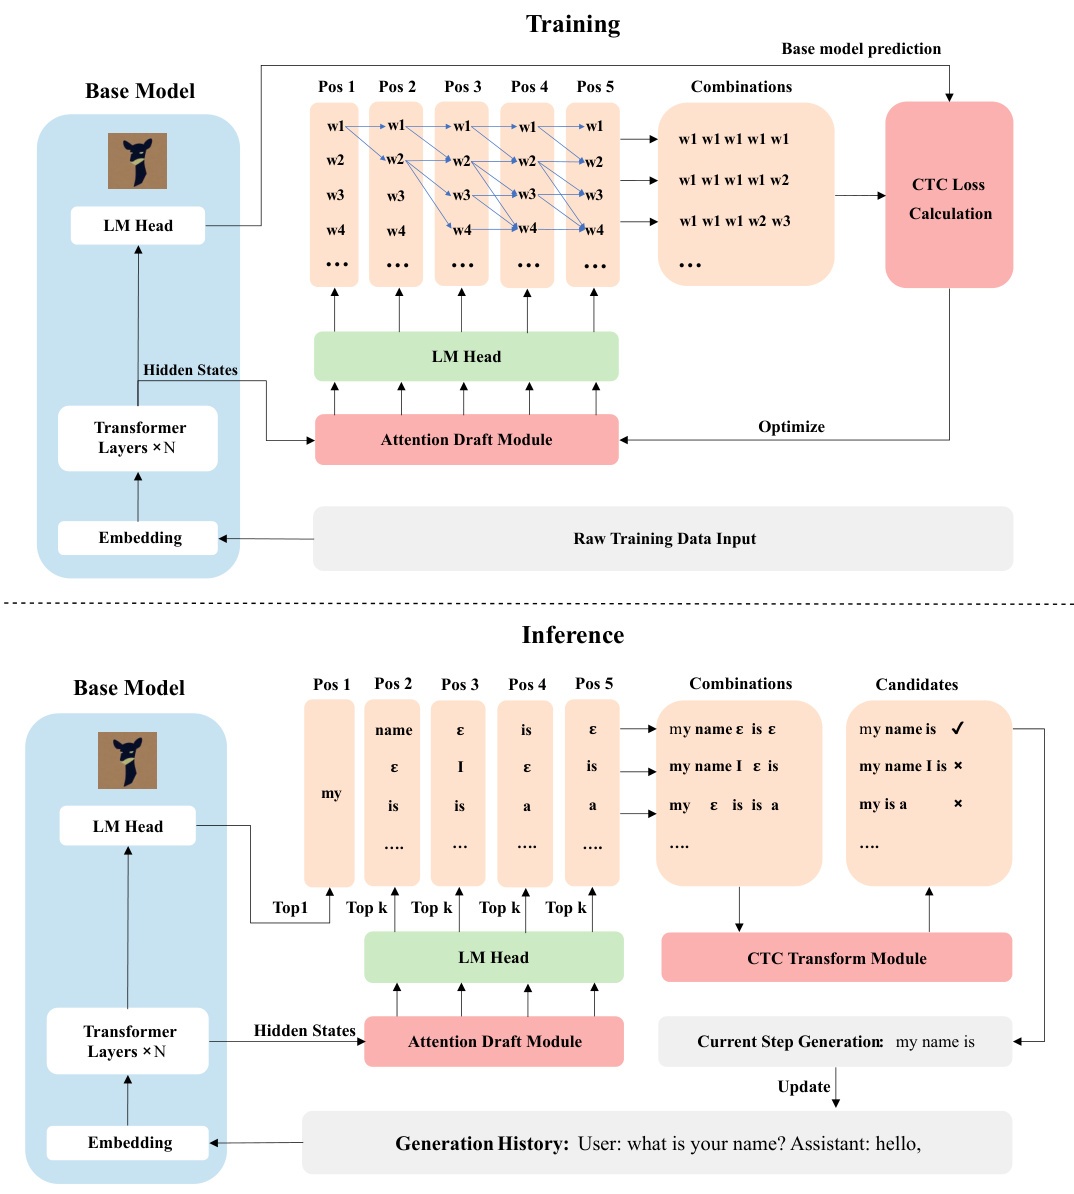
Speculative Decoding with CTC-based Draft Model for LLM Inference ...

Paper page - PARD: Accelerating LLM Inference with Low-Cost PARallel ...

Paper page - Inference without Interference: Disaggregate LLM Inference ...
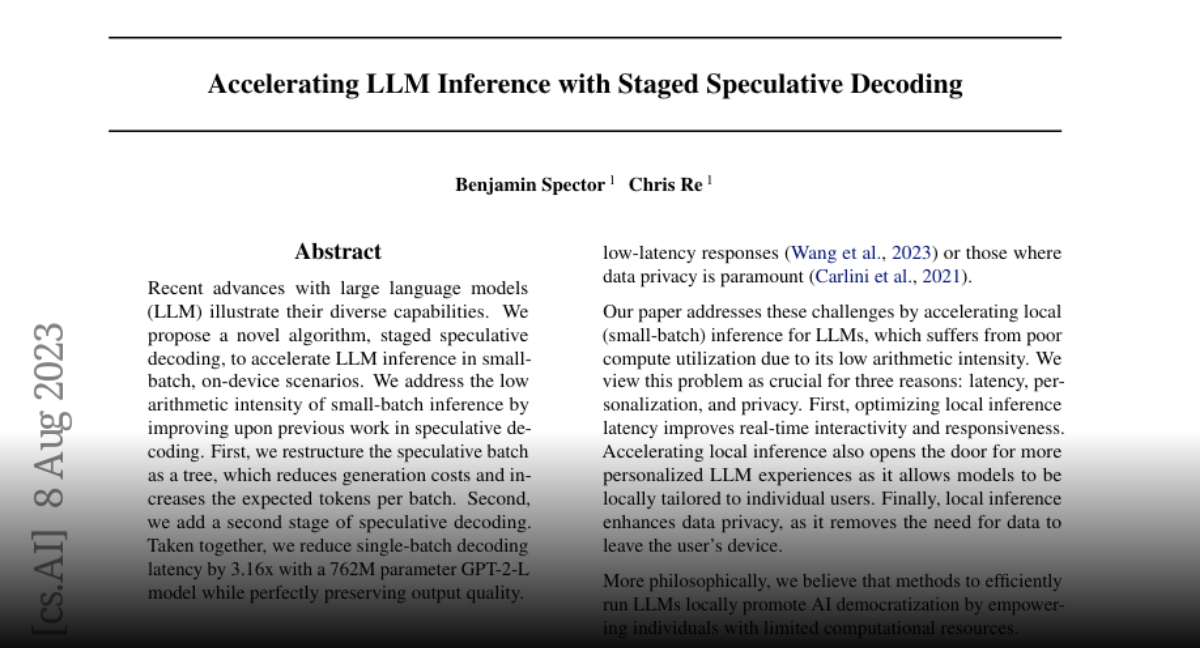
Paper page - Accelerating LLM Inference with Staged Speculative Decoding

Paper page - A Probabilistic Inference Approach to Inference-Time ...
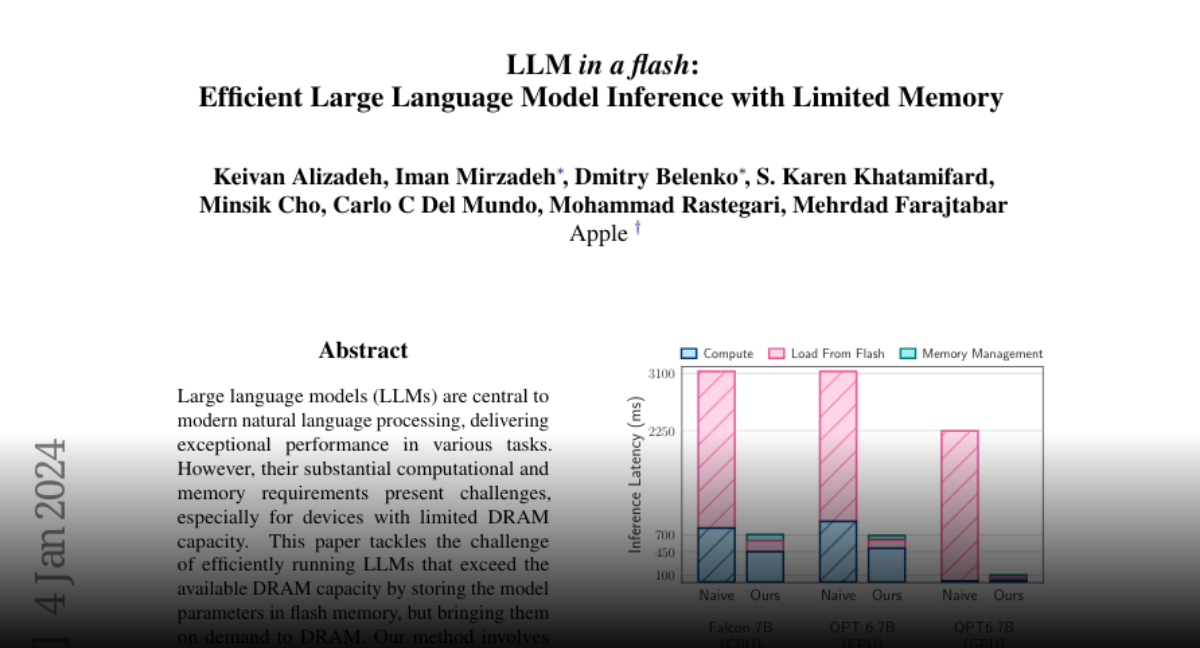
Paper page - LLM in a flash: Efficient Large Language Model Inference ...
Advertisement Space (336x280)

(PDF) SplitLLM: Collaborative Inference of LLMs for Model Placement and ...

Paper page - LUT-LLM: Efficient Large Language Model Inference with ...

Paper page - Scaling Laws Meet Model Architecture: Toward Inference ...

Paper page - AccLLM: Accelerating Long-Context LLM Inference Via ...

Paper page - LLM Inference Unveiled: Survey and Roofline Model Insights

Paper page - Efficient LLM Inference with Kcache

Paper page - Beyond LLM-as-a-Judge: Deterministic Metrics for ...

Paper page - DiffAdapt: Difficulty-Adaptive Reasoning for Token ...

Paper page - Structured Uncertainty guided Clarification for LLM Agents

Paper page - On Data Engineering for Scaling LLM Terminal Capabilities
Advertisement Space (336x280)

Paper page - LMCache: An Efficient KV Cache Layer for Enterprise-Scale ...

Paper page - BatchLLM: Optimizing Large Batched LLM Inference with ...

Paper page - TokenSelect: Efficient Long-Context Inference and Length ...

Paper page - Medusa: Simple LLM Inference Acceleration Framework with ...

Paper page - LLM-Inference-Bench: Inference Benchmarking of Large ...

Variational Sampling for Approximate Inference | PDF | Normal ...