
66 Serving Llms At Scale Huggingface Triton Vllm In The Enterprise

#66 | Serving LLMs at Scale: HuggingFace, Triton, vLLM in the Enterprise

Serving LLMs at Scale: HuggingFace, Triton, vLLM in the Enterprise | by ...

Serving LLMs at Scale: HuggingFace, Triton, vLLM in the Enterprise | by ...

Serving LLMs in Production: Performance, Cost & Scale - Event | MLOps ...
QCon AI Boston 2026 | Serving LLMs at Scale: The Hidden KV Cache Advantage

Inferencing LLMs at Scale with Kubernetes and vLLM | by Welzin ...
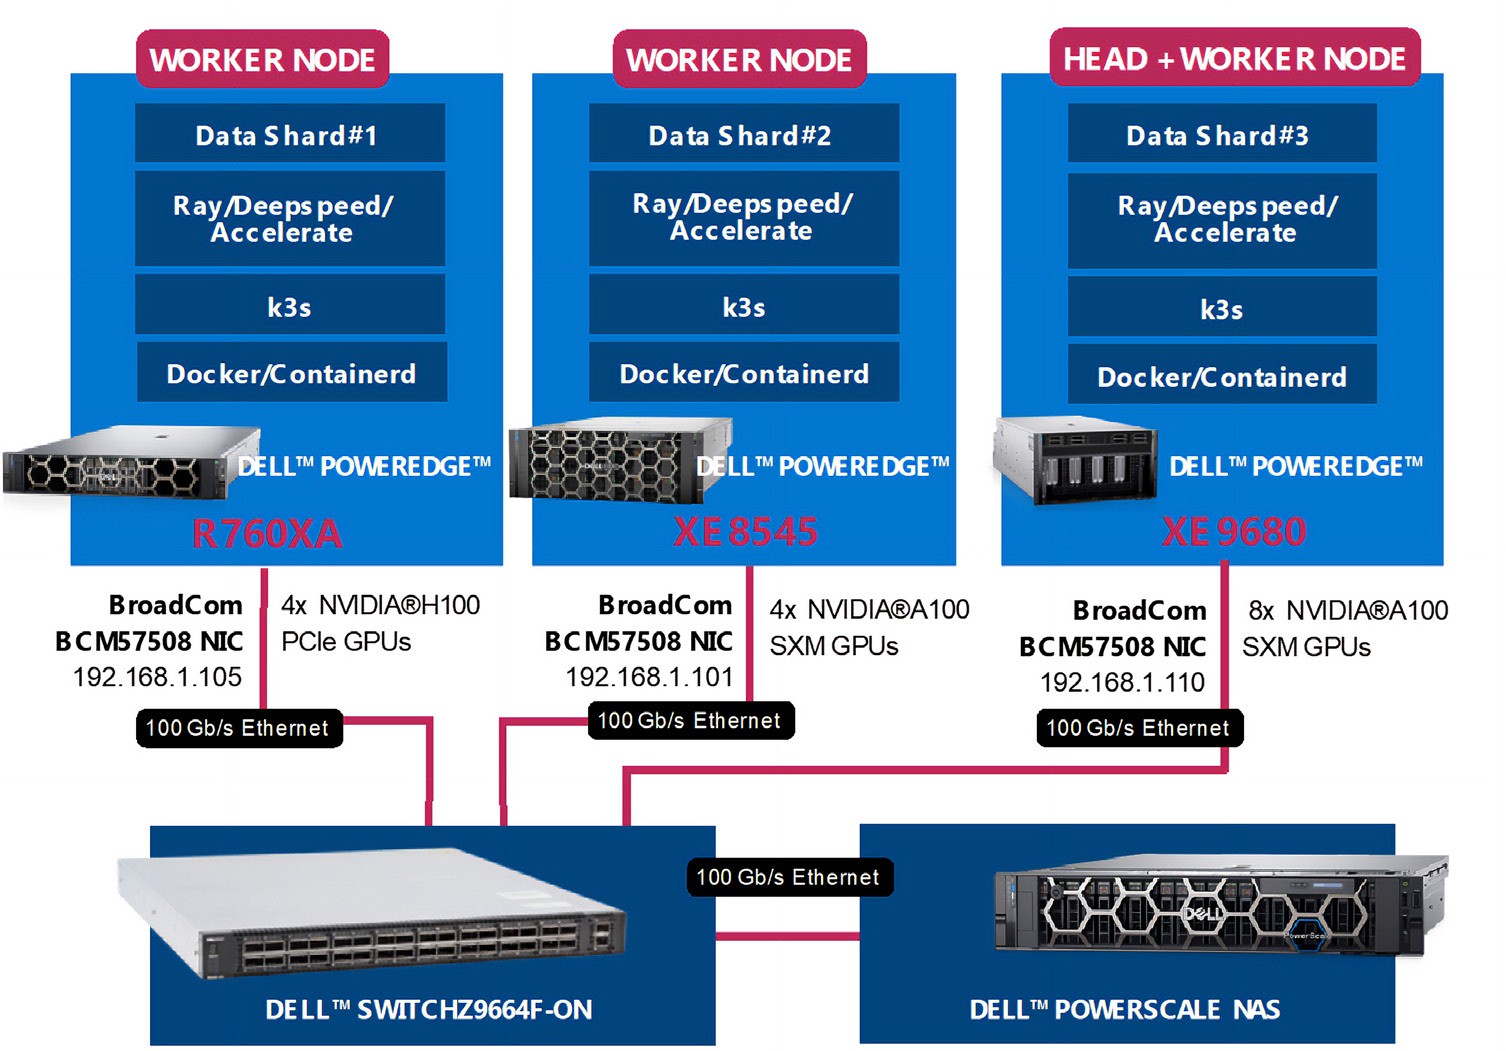
Fine-Tuning Enterprise LLMs at Scale with Dell™ PowerEdge™ & Broadcom ...
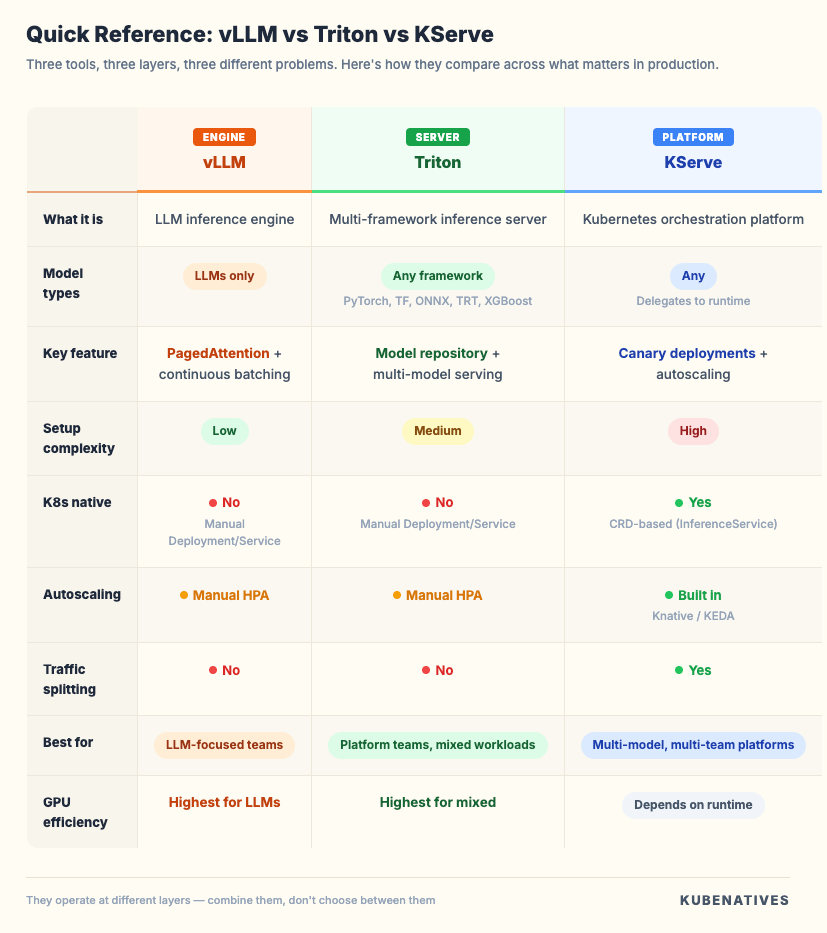
vLLM vs Triton vs KServe: Model Serving on Kubernetes
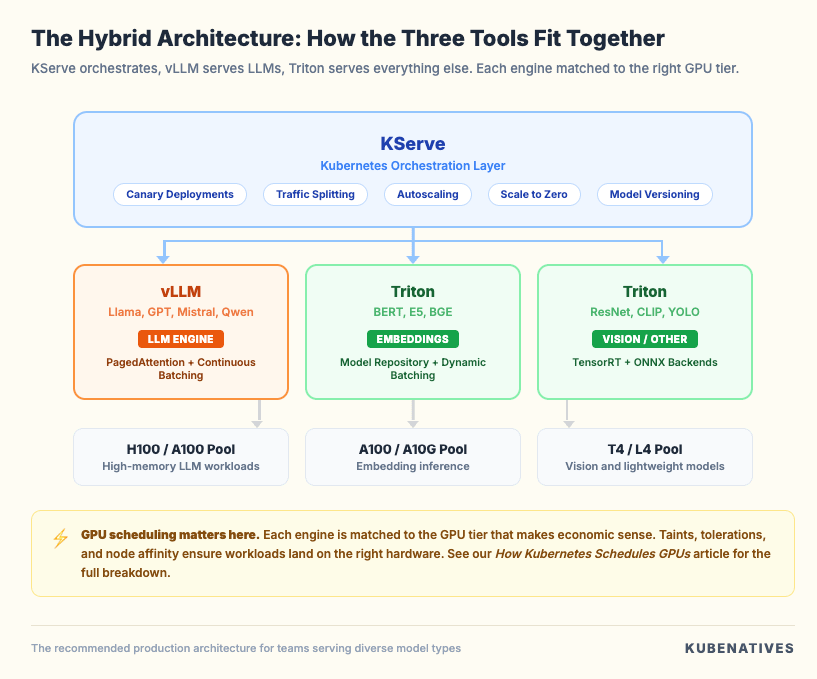
vLLM vs Triton vs KServe: Model Serving on Kubernetes
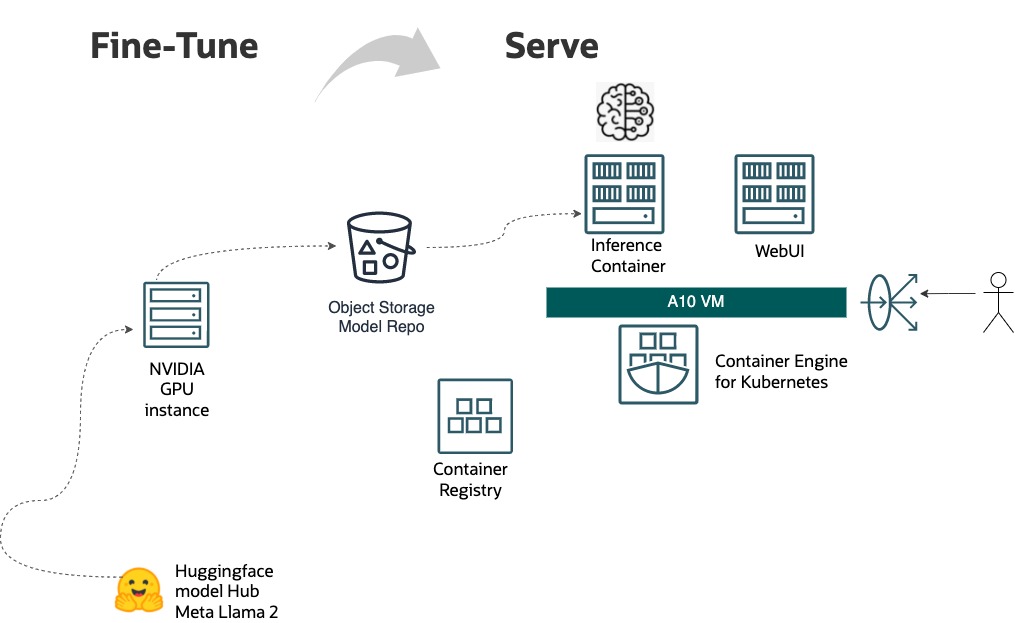
Serving LLMs using HuggingFace and Kubernetes on OCI | ai-and-datascience
Advertisement Space (300x250)
AI/ML Infra Meetup | Deployment, Discovery and Serving of LLMs at Uber ...
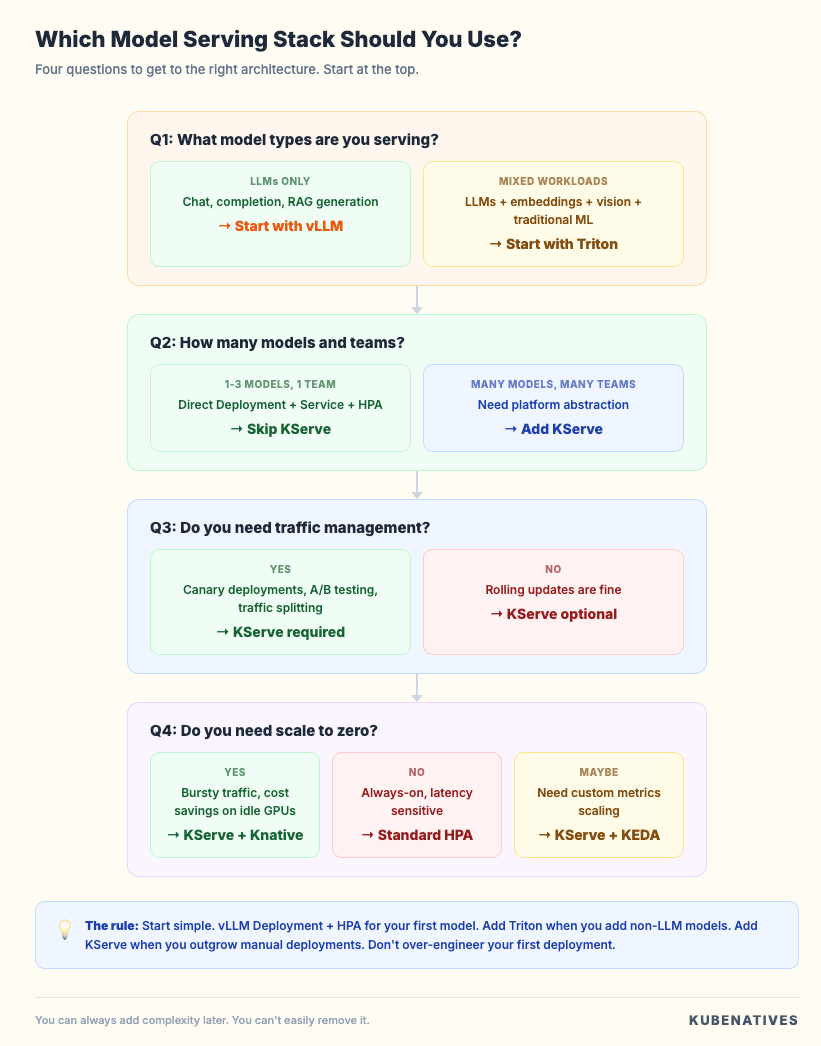
vLLM vs Triton vs KServe: Model Serving on Kubernetes
Scaling Llms with Nvidia Triton and Tensorrt-LLM: The Complete Guide to ...

vLLM: Deploying LLMs at Scale - Fractal Analytics
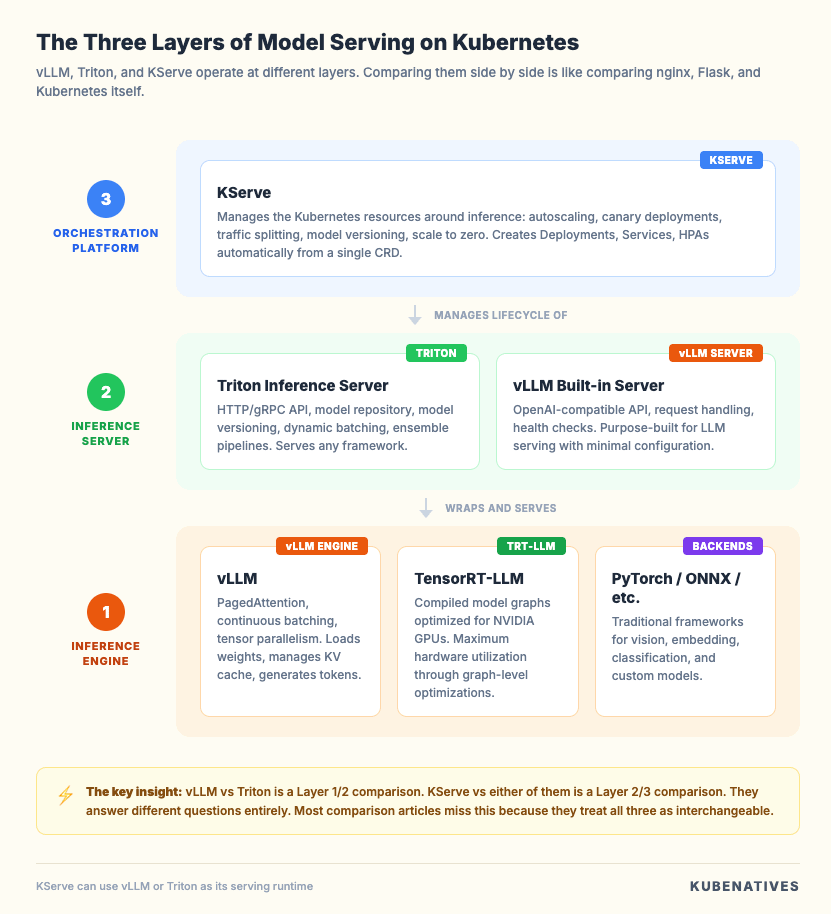
vLLM vs Triton vs KServe: Model Serving on Kubernetes

Guide to LLM Serving Stacks: vLLM vs TGI vs Triton | by Roushan Kumar ...

Beyond the Model: How vLLM Powers Enterprise-Scale LLM Serving | by ...

Guide to LLM Serving Stacks: vLLM vs TGI vs Triton | by Roushan Kumar ...

Scale Open LLMs with vLLM Production Stack | by Shahrukh khan | Medium

vLLM: Deploying LLMs at Scale Like OpenAI
Advertisement Space (336x280)
Self-Hosting LLMs on Kubernetes: Serving LLMs using vLLM

vLLM: Deploying LLMs at Scale Like OpenAI
Vllm Vs Triton | Which Open Source Library is BETTER in 2026? - YouTube

vLLM vs. Triton Inference Server: In-Depth Comparison for Optimized LLM ...
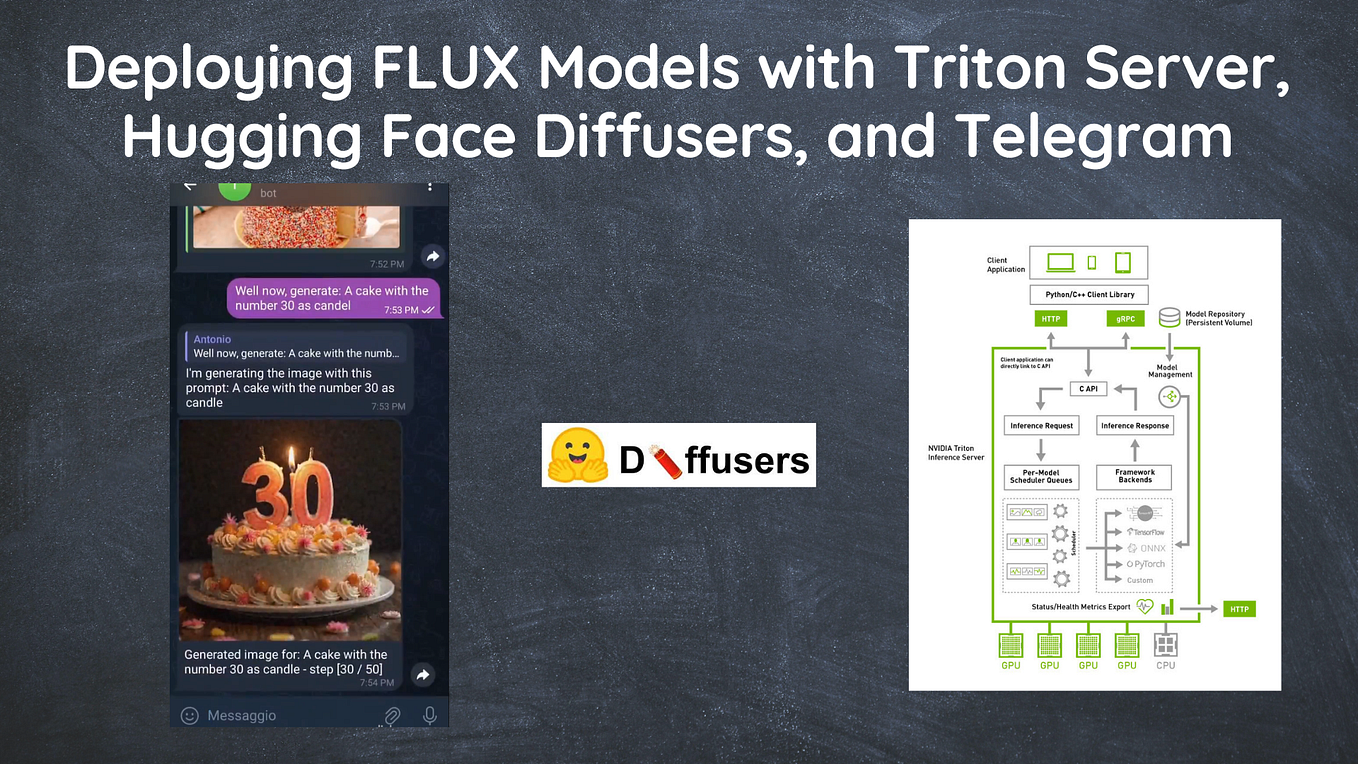
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...

vLLM vs. Triton Inference Server: In-Depth Comparison for Optimized LLM ...
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...

vLLM vs. Triton Inference Server: In-Depth Comparison for Optimized LLM ...
Scaling LLMs with NVIDIA Triton and NVIDIA TensorRT-LLM Using ...
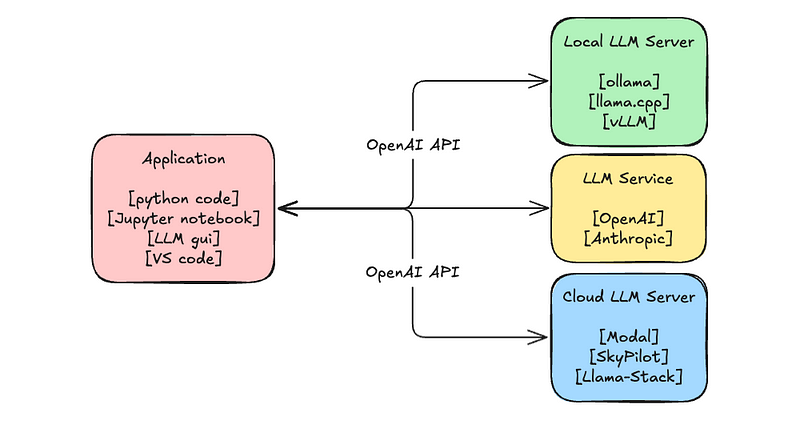
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...
Advertisement Space (336x280)
vLLM vs Triton for Smarter AI Deployment | by Tamanna | Medium

Serving Inference for LLMs: A Case Study with NVIDIA Triton Inference ...
Using a Huggingface Token for vLLM Support · Issue #1471 ...
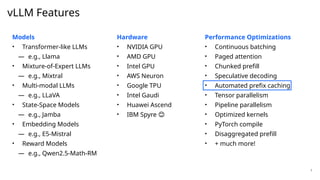
vLLM: High-performance serving of LLMs using open-source technology | PPTX

vLLM: High-performance serving of LLMs using open-source technology | PPTX
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...