
Serving Llms At Scale Huggingface Triton Vllm In The Enterprise By

Serving LLMs at Scale: HuggingFace, Triton, vLLM in the Enterprise | by ...

Serving LLMs at Scale: HuggingFace, Triton, vLLM in the Enterprise | by ...

#66 | Serving LLMs at Scale: HuggingFace, Triton, vLLM in the Enterprise

Inferencing LLMs at Scale with Kubernetes and vLLM | by Welzin ...

Beyond the Model: How vLLM Powers Enterprise-Scale LLM Serving | by ...

Guide to LLM Serving Stacks: vLLM vs TGI vs Triton | by Roushan Kumar ...

Scale Open LLMs with vLLM Production Stack | by Shahrukh khan | Medium
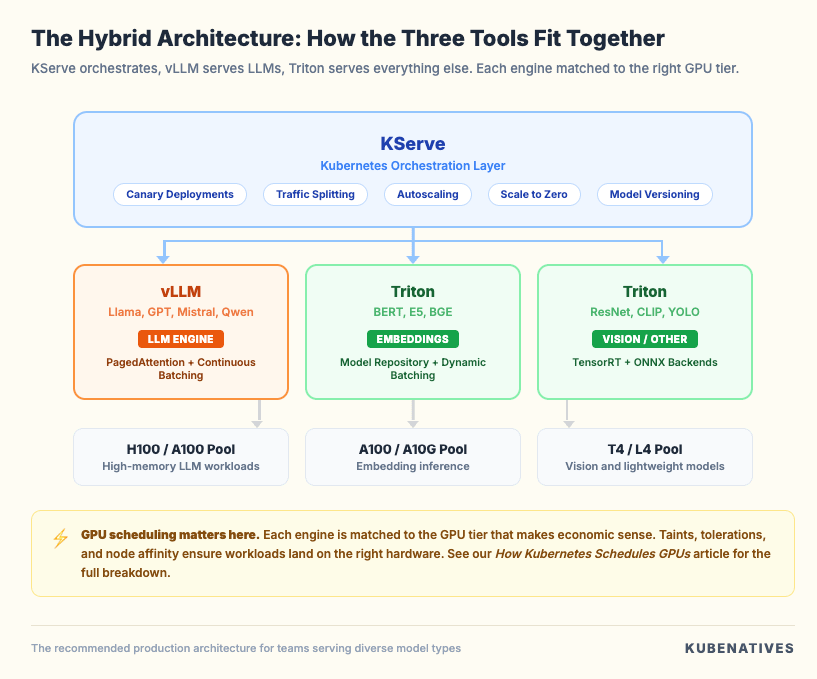
vLLM vs Triton vs KServe: Model Serving on Kubernetes
AI/ML Infra Meetup | Deployment, Discovery and Serving of LLMs at Uber ...
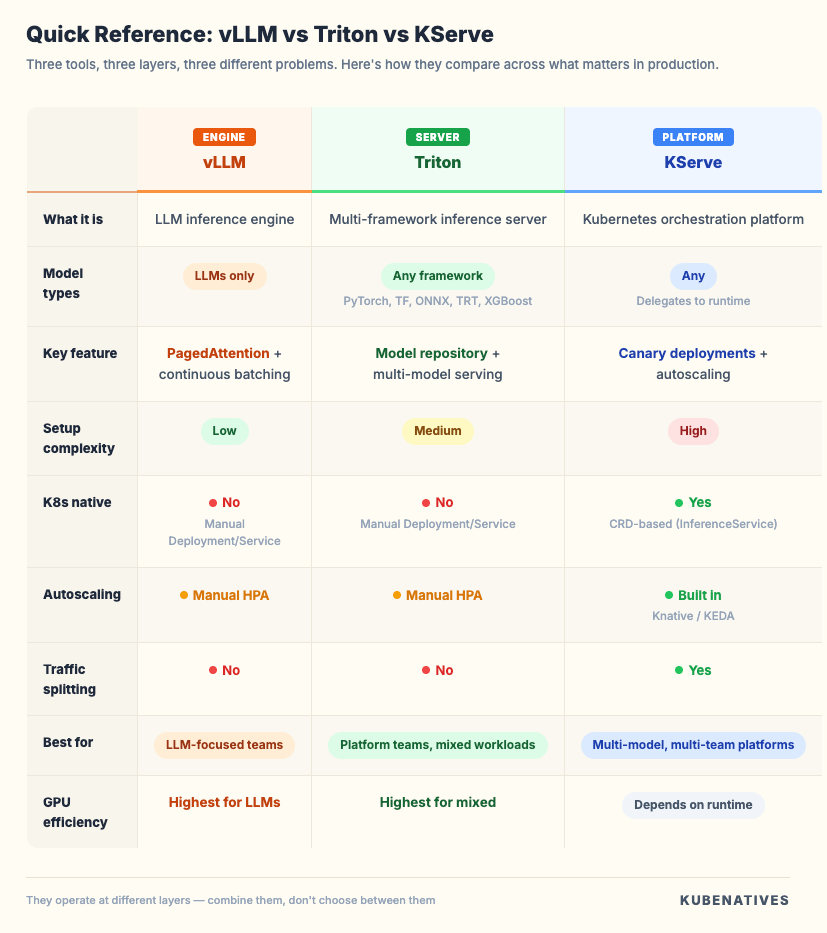
vLLM vs Triton vs KServe: Model Serving on Kubernetes
Advertisement Space (300x250)
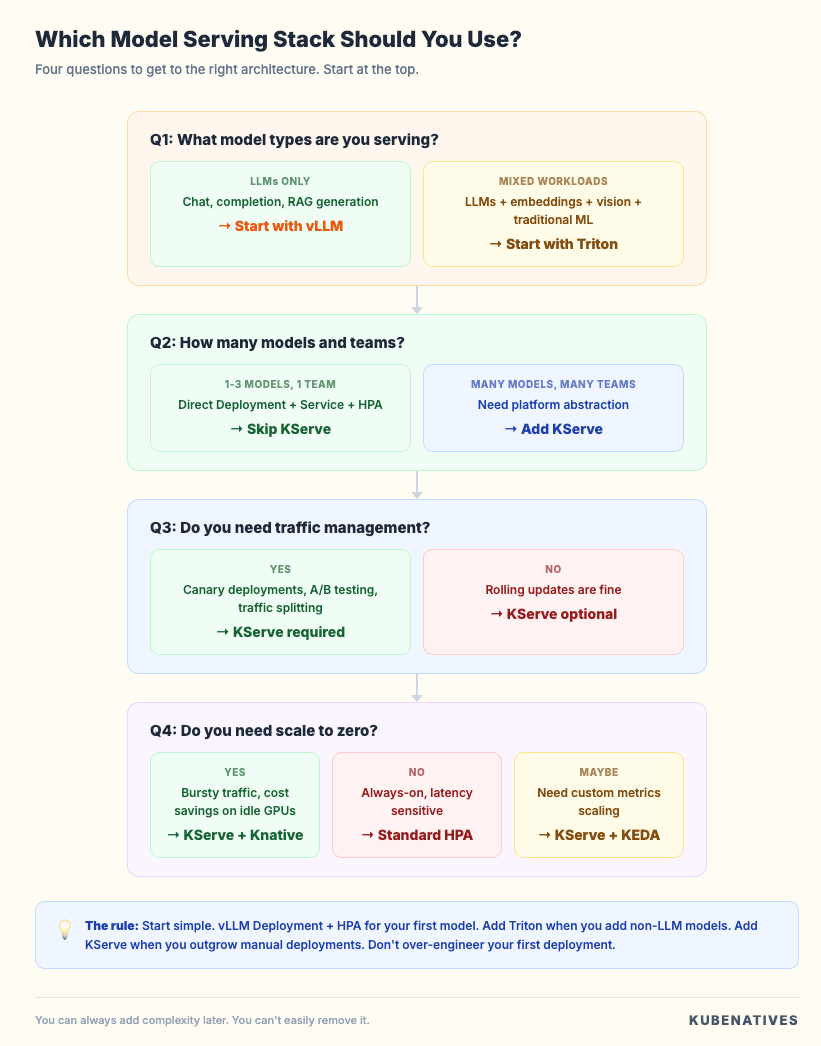
vLLM vs Triton vs KServe: Model Serving on Kubernetes
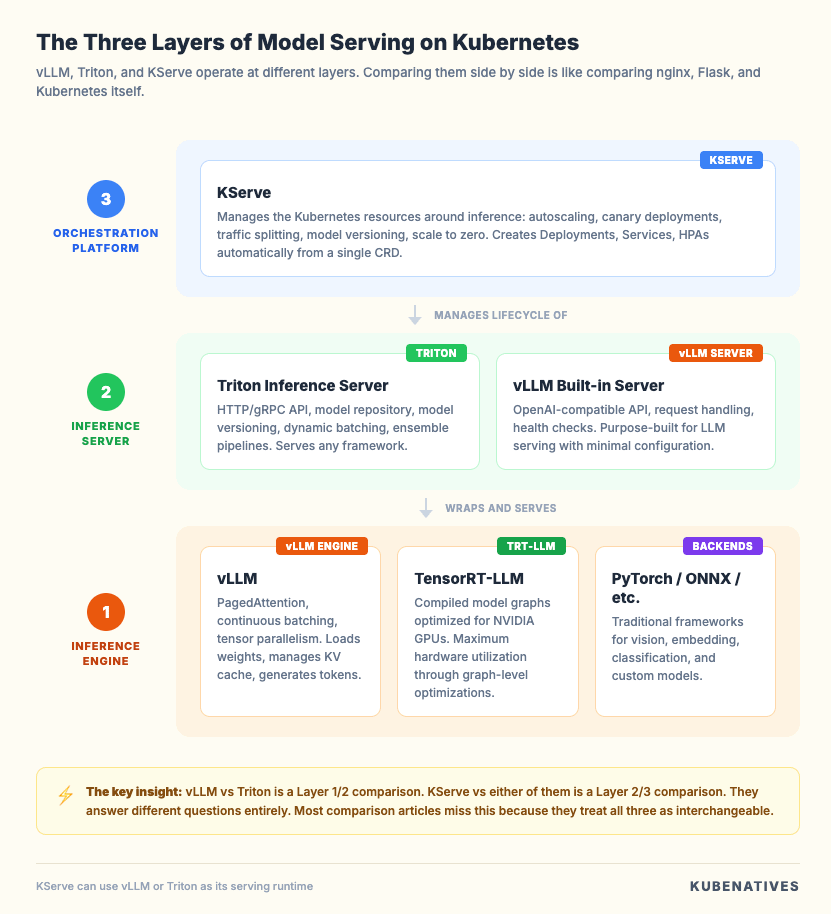
vLLM vs Triton vs KServe: Model Serving on Kubernetes
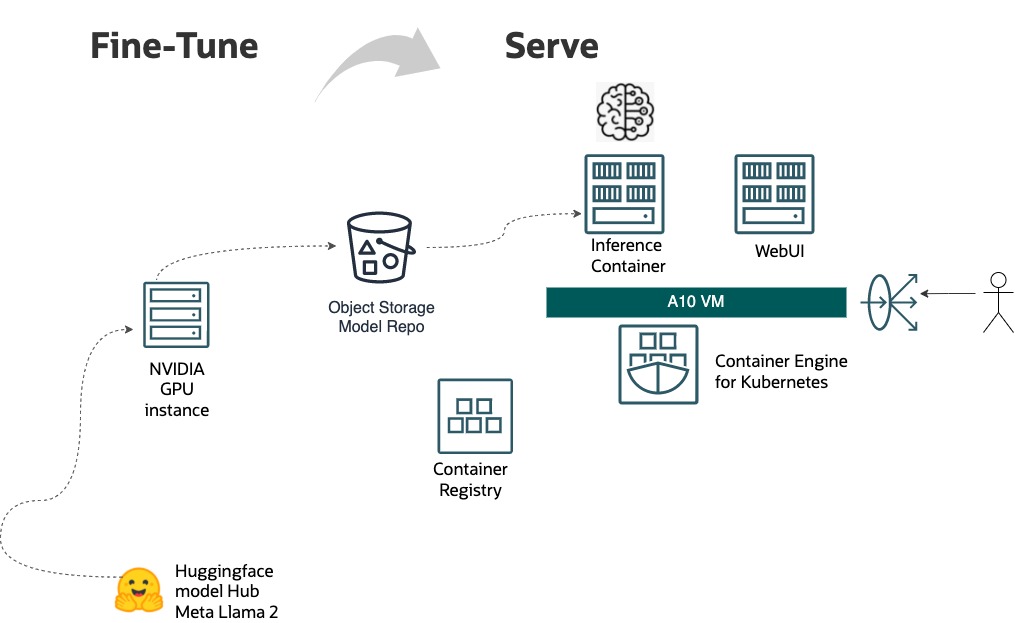
Serving LLMs using HuggingFace and Kubernetes on OCI | ai-and-datascience
Scaling Llms with Nvidia Triton and Tensorrt-LLM: The Complete Guide to ...

vLLM: Deploying LLMs at Scale - Fractal Analytics

vLLM: Deploying LLMs at Scale Like OpenAI
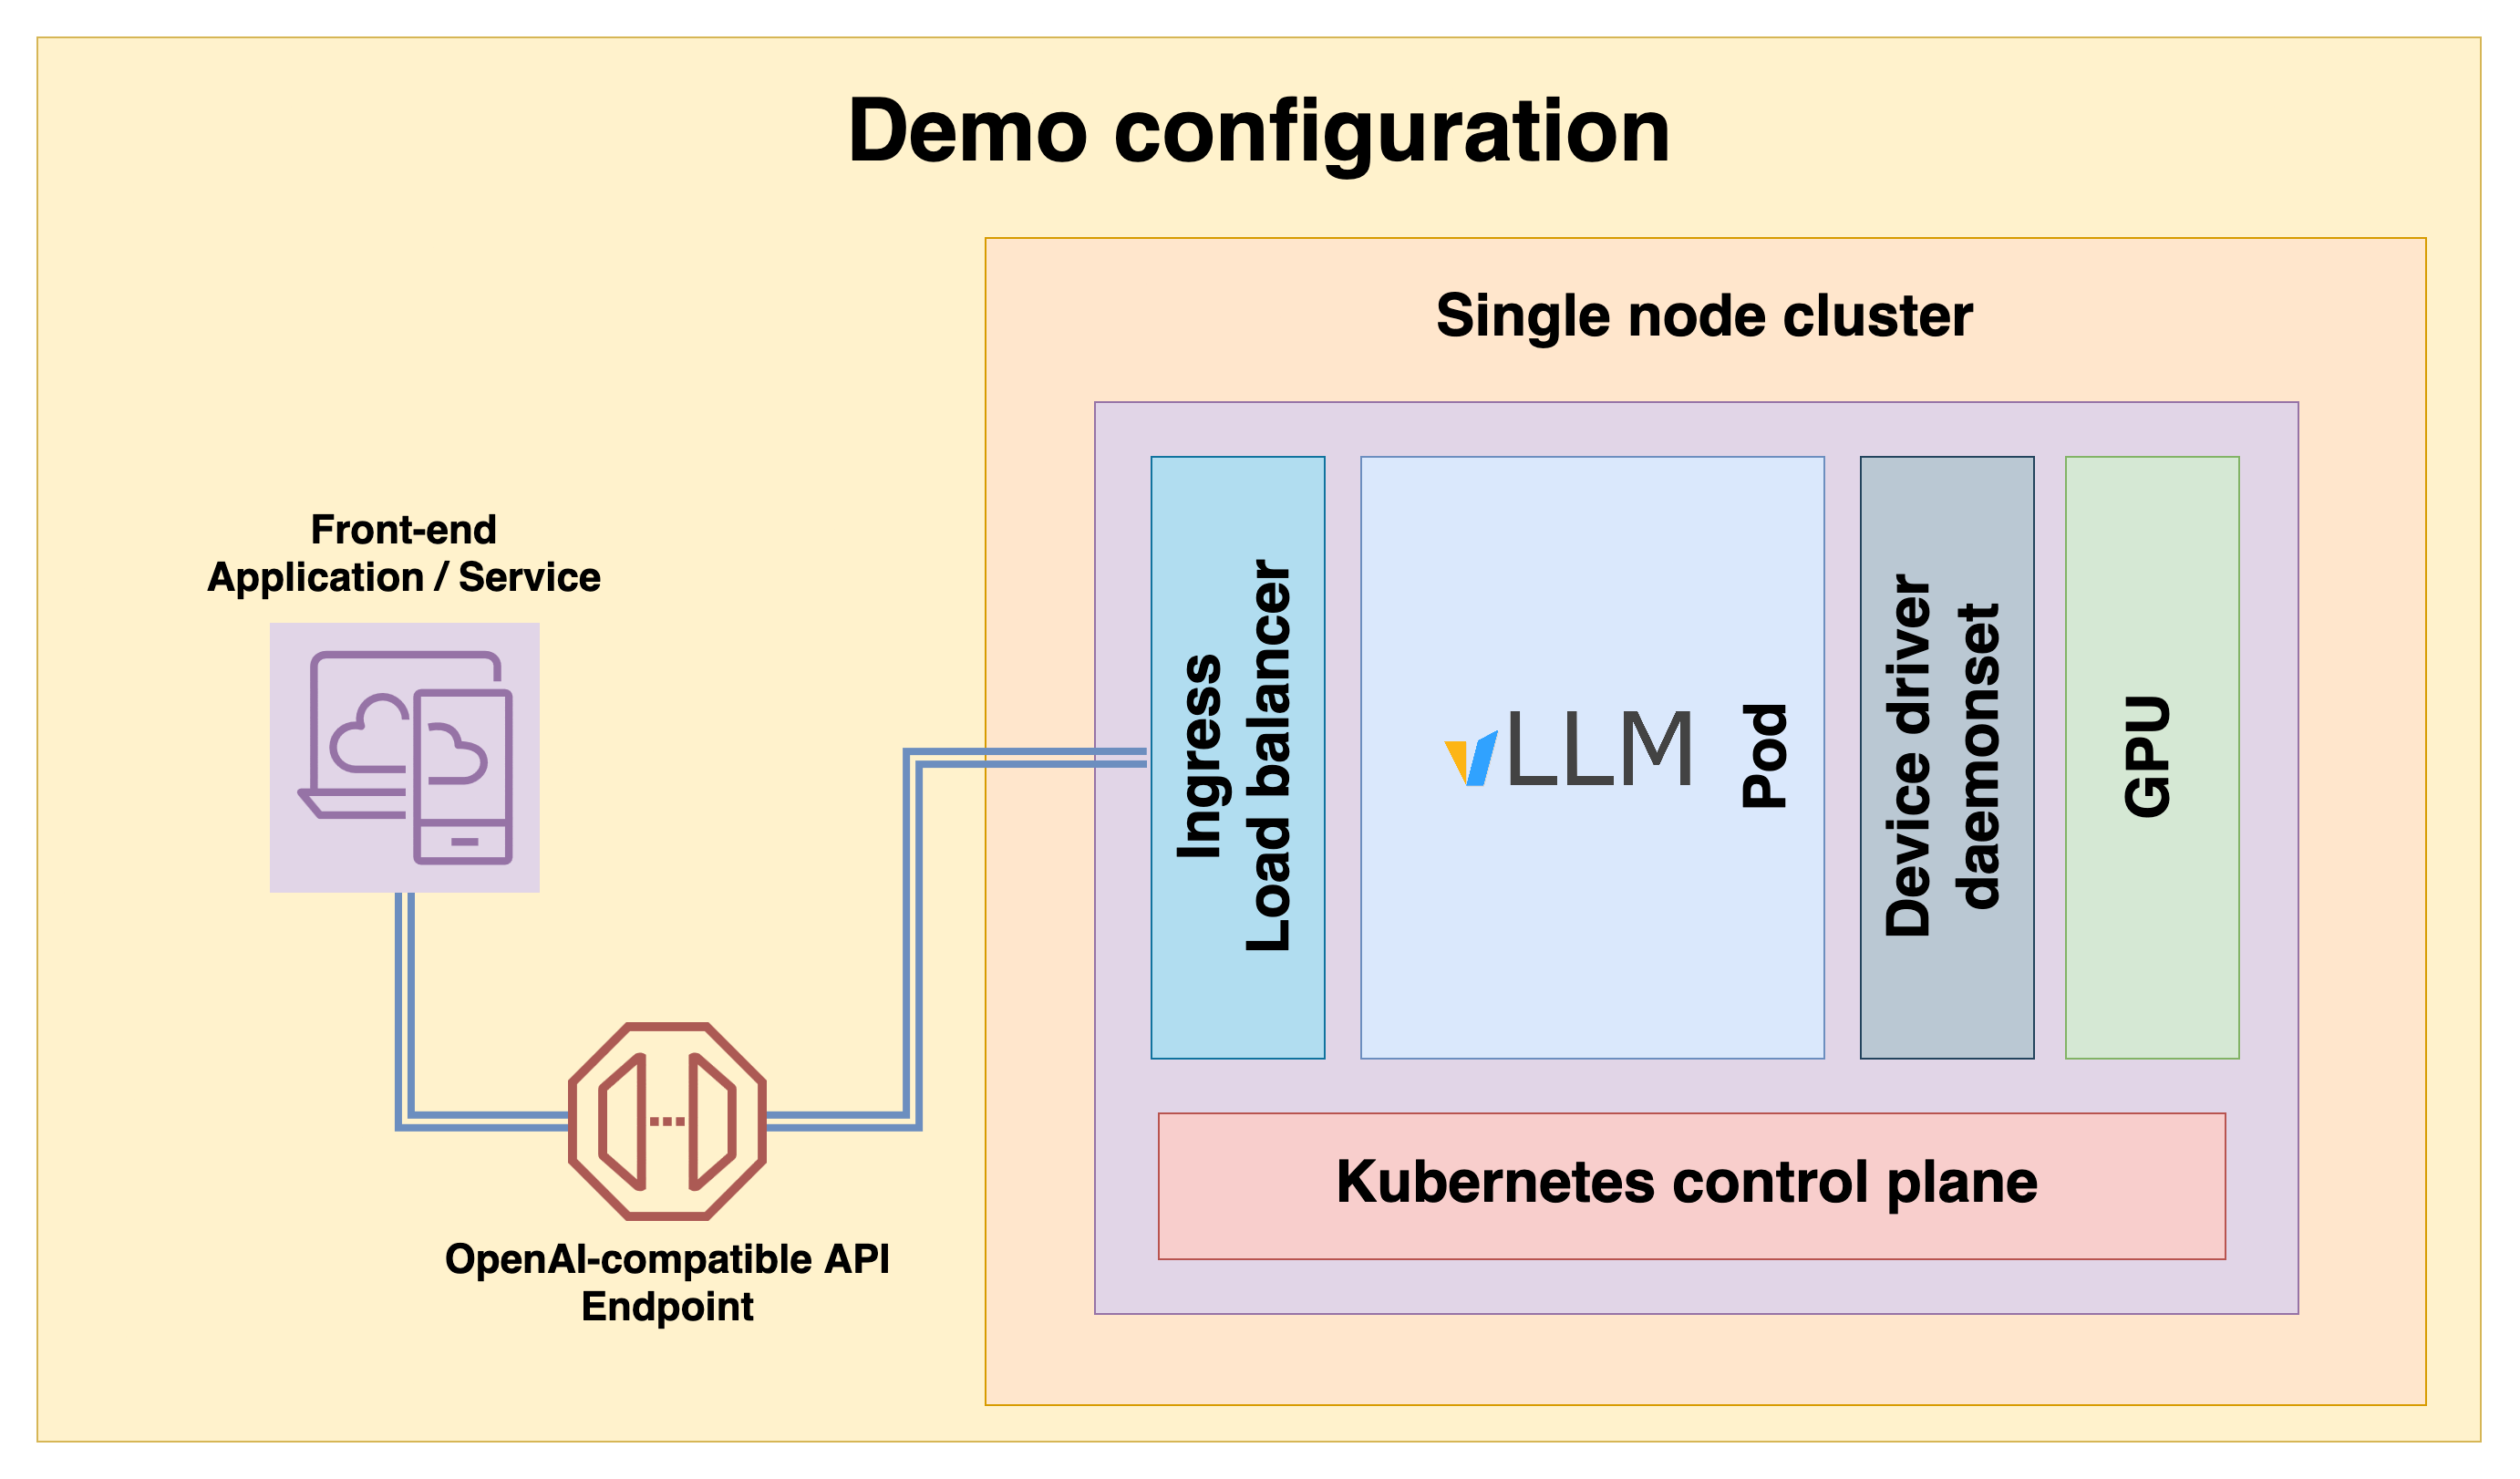
How to deploy LLMs in production • The Register
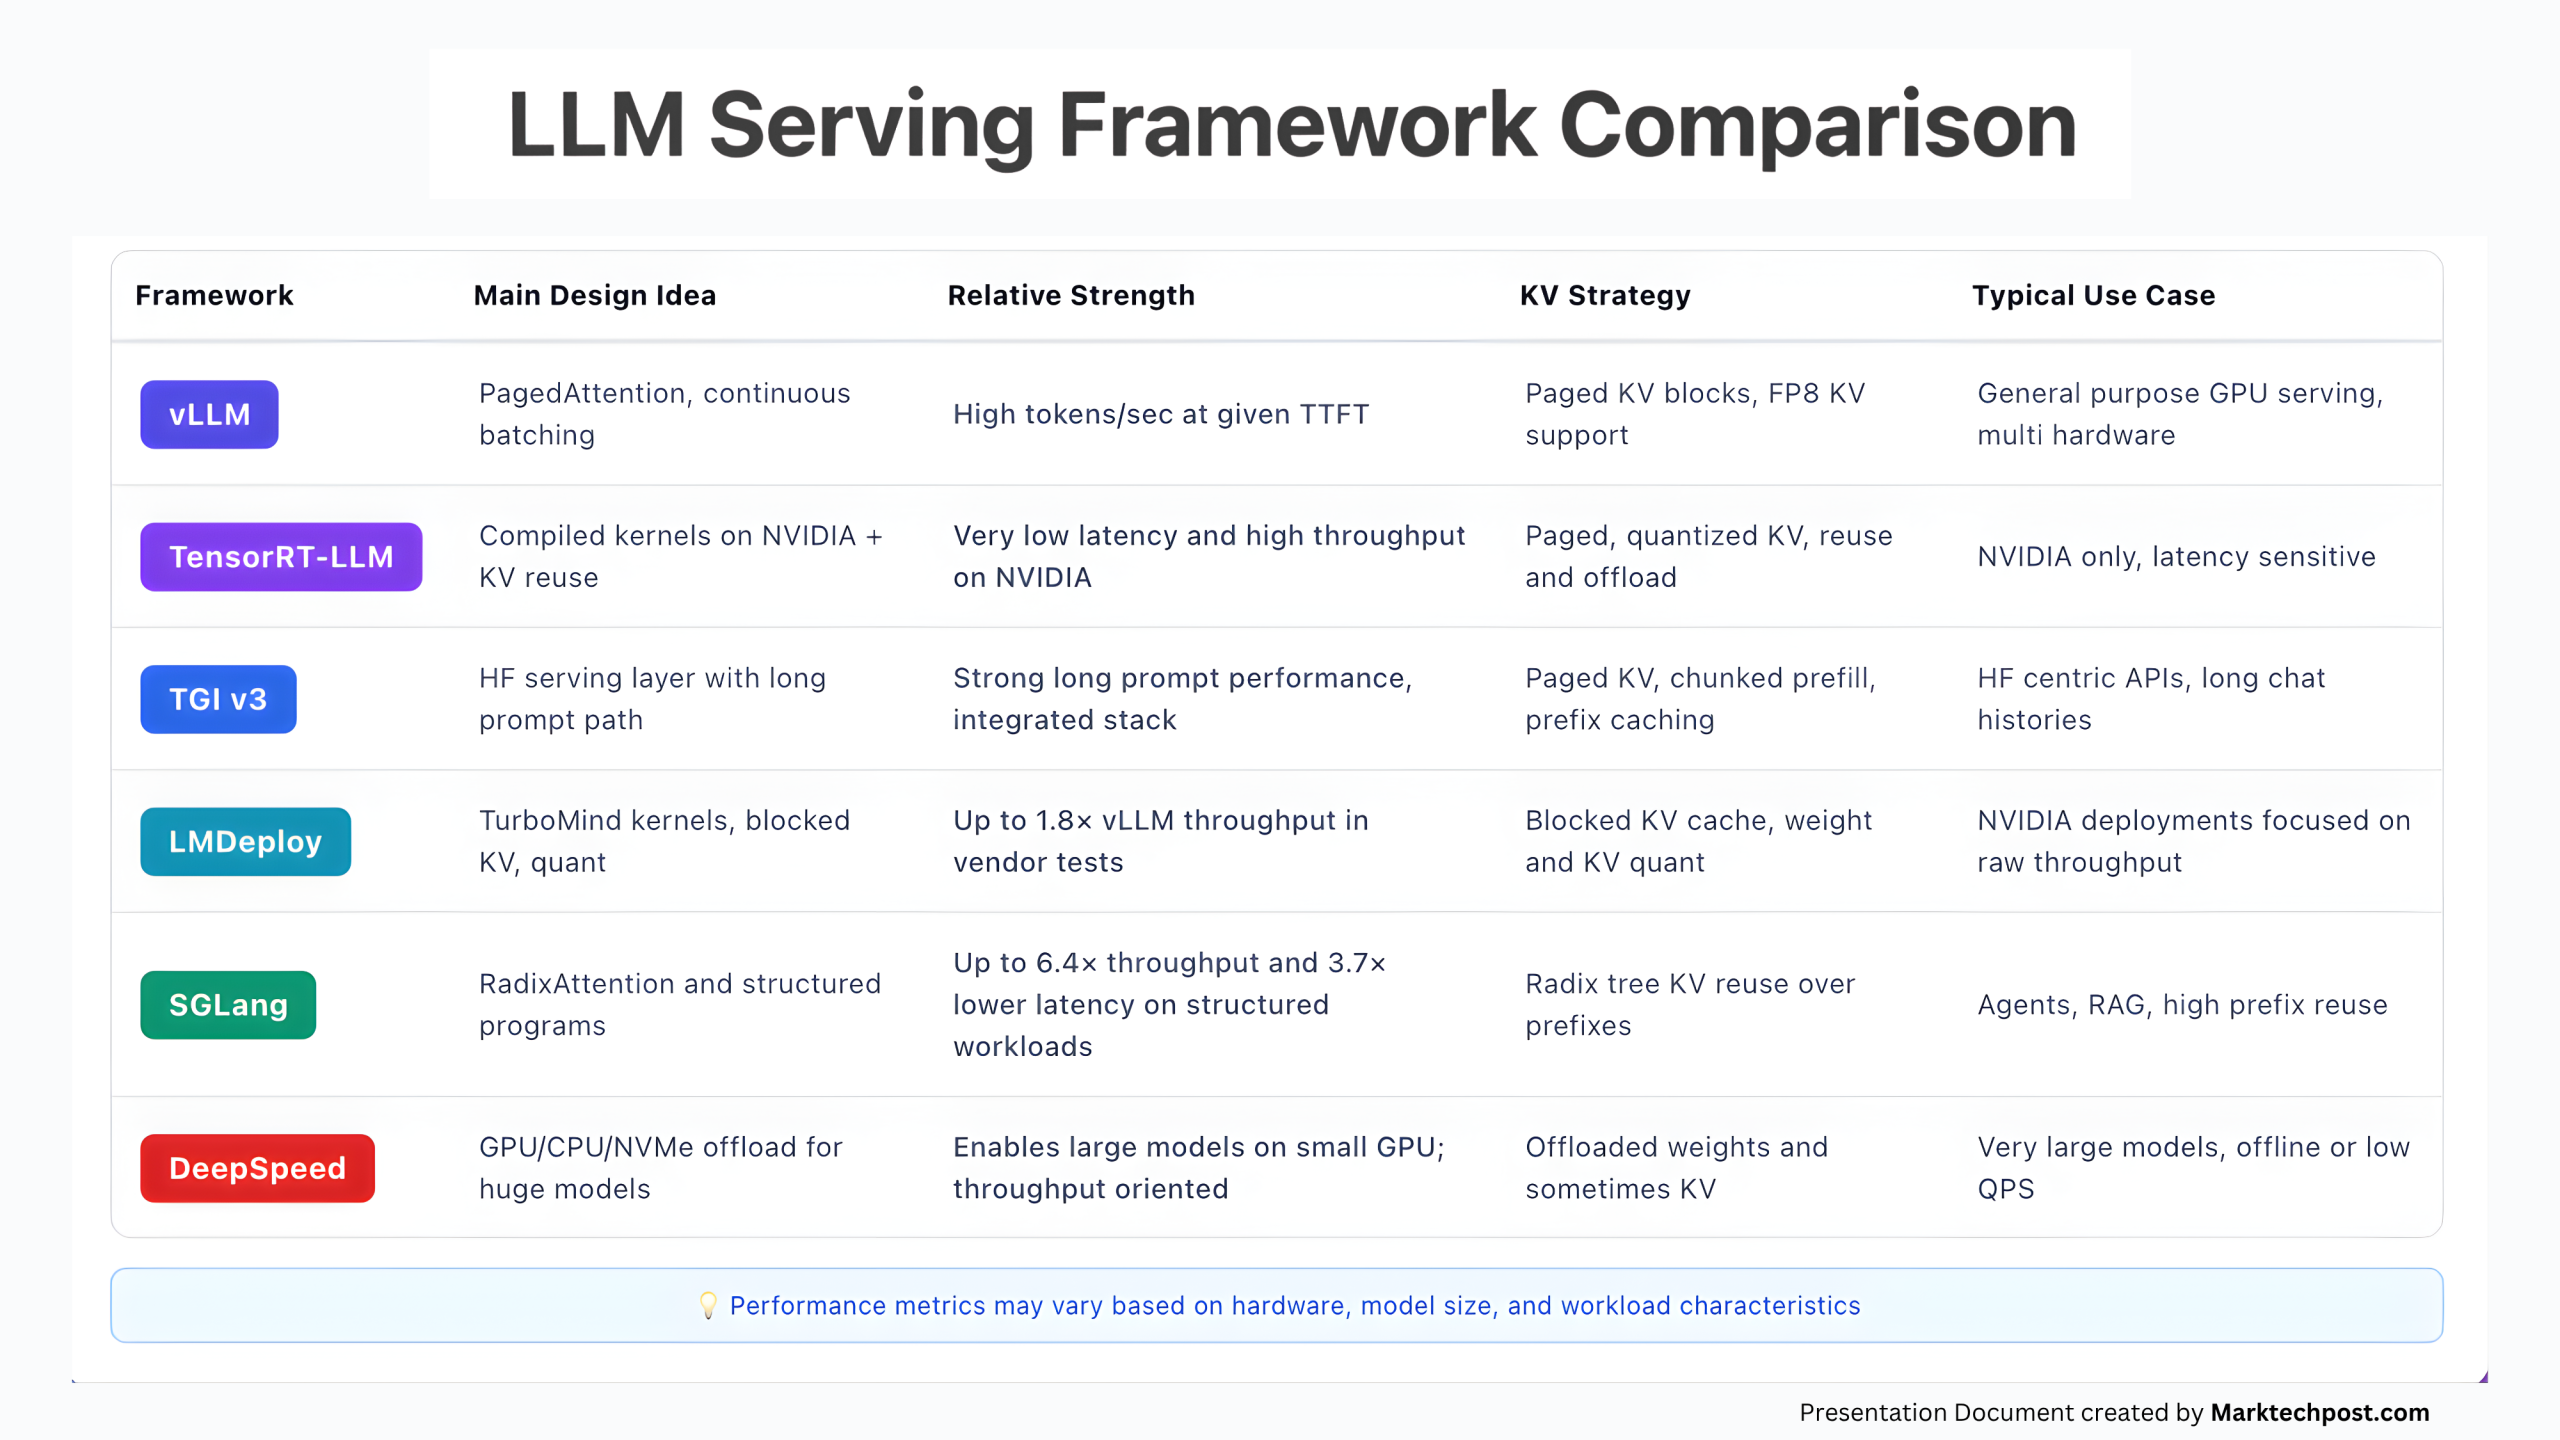
Comparing the Top 6 Inference Runtimes for LLM Serving in 2025 ...
vLLM on SageMaker and Bedrock: The Definitive Guide to Serving Fine ...
Self-Hosting LLMs on Kubernetes: Serving LLMs using vLLM
Advertisement Space (336x280)

vLLM: Deploying LLMs at Scale Like OpenAI

How does vLLM serve LLMs efficiently at scale?

Efficiently Serving Open Source LLMs | by Ryan Shrott | Towards Data ...
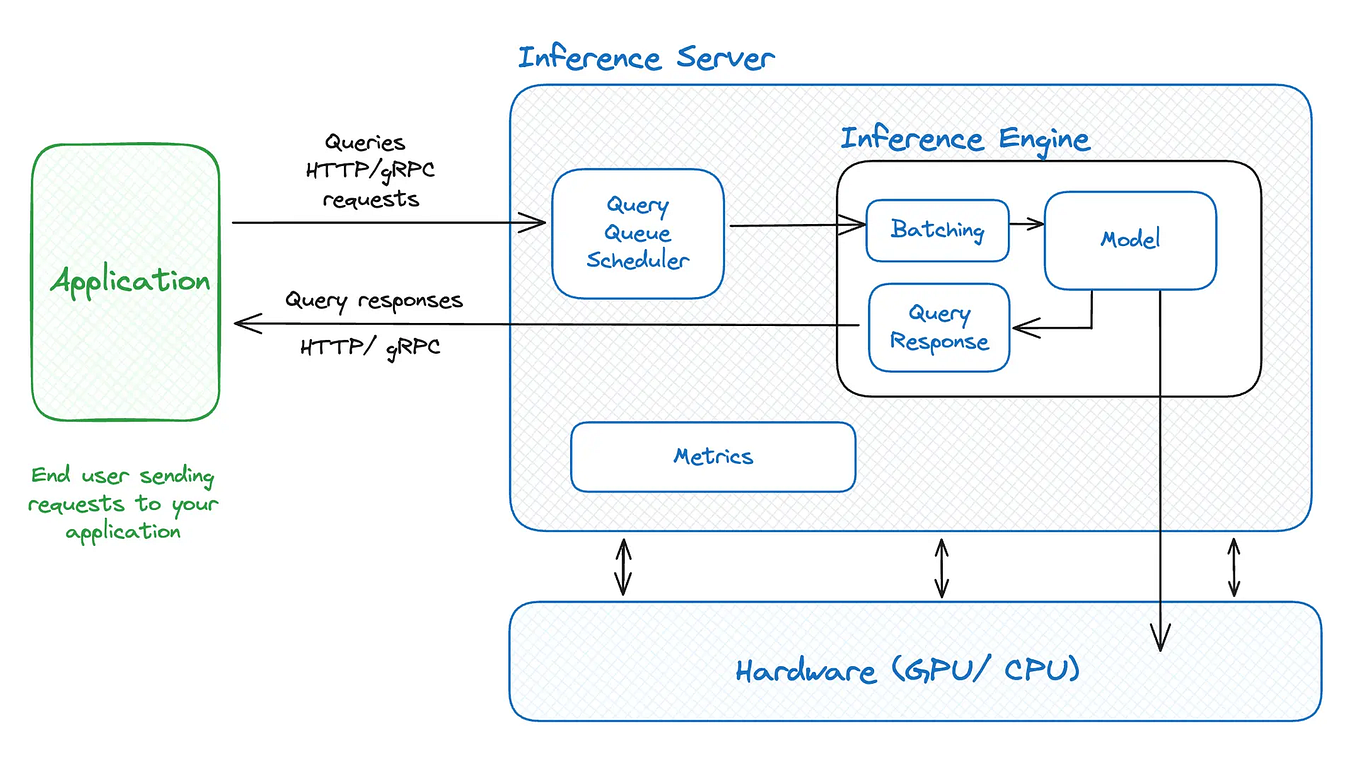
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...

vLLM vs. Triton Inference Server: In-Depth Comparison for Optimized LLM ...
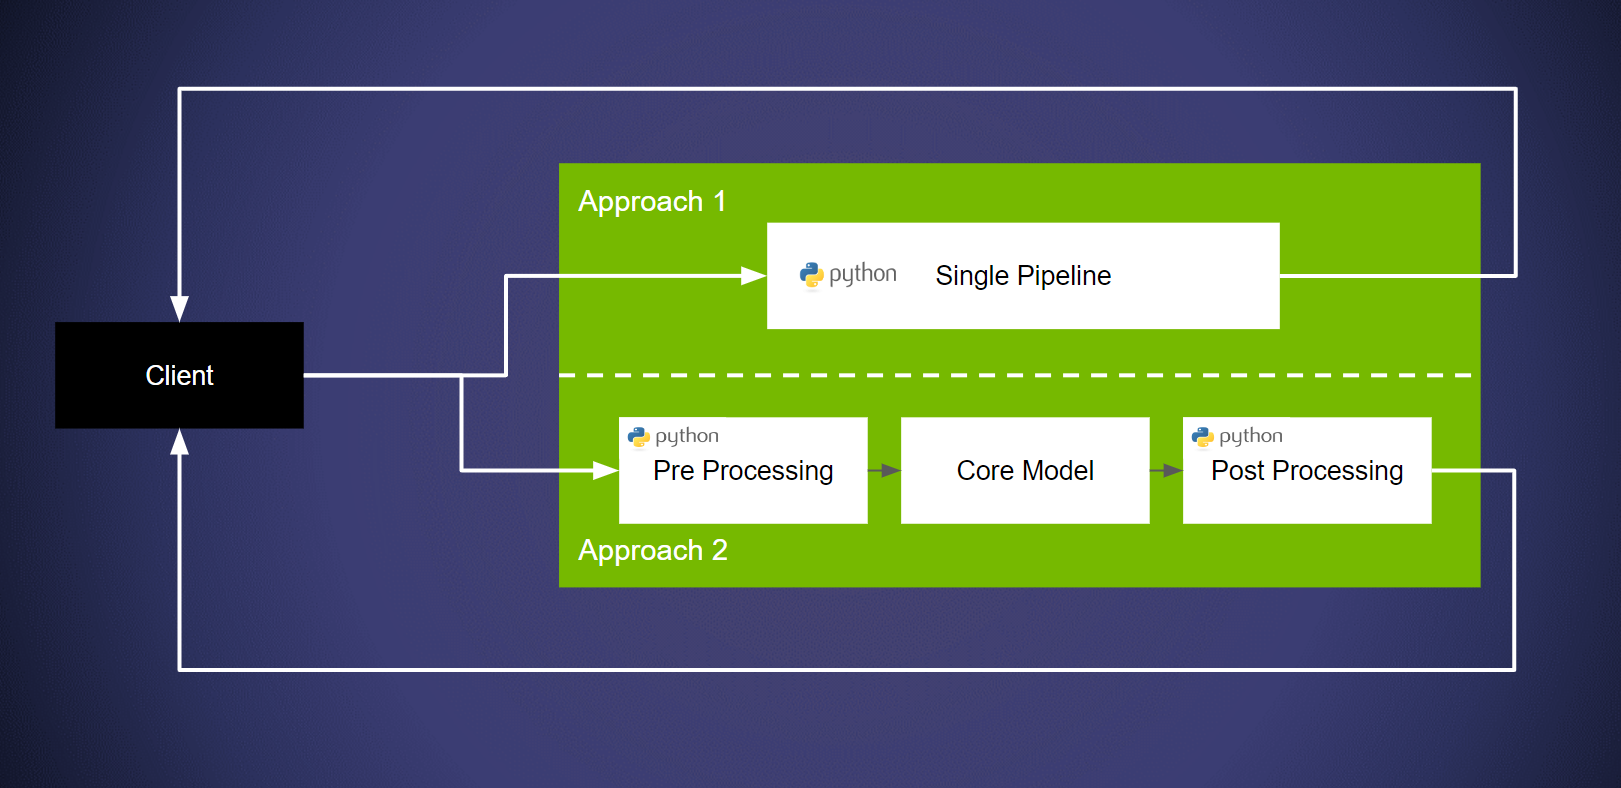
Deploying HuggingFace models — NVIDIA Triton Inference Server

vLLM vs. Triton Inference Server: In-Depth Comparison for Optimized LLM ...
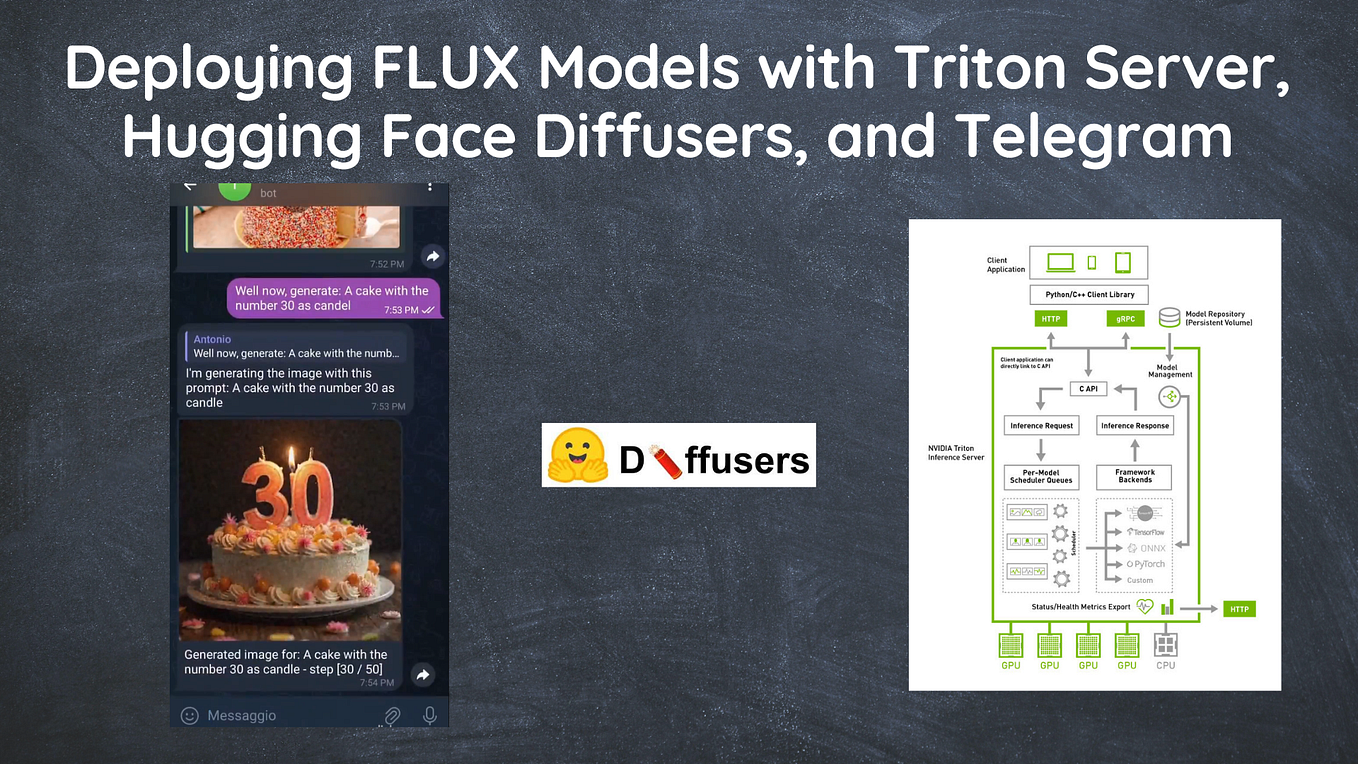
Transforming LLM Serving: NVIDIA Triton Inference Server Meets vLLM ...

vLLM vs. Triton Inference Server: In-Depth Comparison for Optimized LLM ...
LLM inference engines performance testing: SGLang VS. vLLM | by ...
Advertisement Space (336x280)

vLLM: High-performance serving of LLMs using open-source technology | PPTX
Using a Huggingface Token for vLLM Support · Issue #1471 ...

Fine Tuning LLMs Using HuggingFace [Code Walkthrough]

vLLM: High-performance serving of LLMs using open-source technology | PPTX
Serving machine learning models with Ray Serve | by Vasil Dedejski | Medium