
Introduction To Vllm A High Performance Llm Serving Engine The New Stack

Introduction to vLLM: A High-Performance LLM Serving Engine - The New Stack

The Imperative: Why LLM Serving Engine Choice Defines Performance ...

A Gentle Introduction to vLLM for Serving - KDnuggets

Free Video: Scalable and Efficient LLM Serving With the VLLM Production ...

Scaling AI in production: A practical guide to LLM Serving - Fractal ...

Deploy the vLLM Inference Engine to Run Large Language Models (LLM) on ...

Optimize LLM Serving with vLLM for Better Performance | Rahul Reddy ...

Beyond the Model: How vLLM Powers Enterprise-Scale LLM Serving | by ...

A Brief Introduction to Optimized Batched Inference with vLLM | by ...

Scaling LLM Inference on GKE: Serving with vLLM or llm-d | by Don ...
Advertisement Space (300x250)

Deploy DeepSeek-R1 with the vLLM V1 engine and build an AI-powered ...

vLLM Review: High-Performance LLM Inference Engine for GPU ...
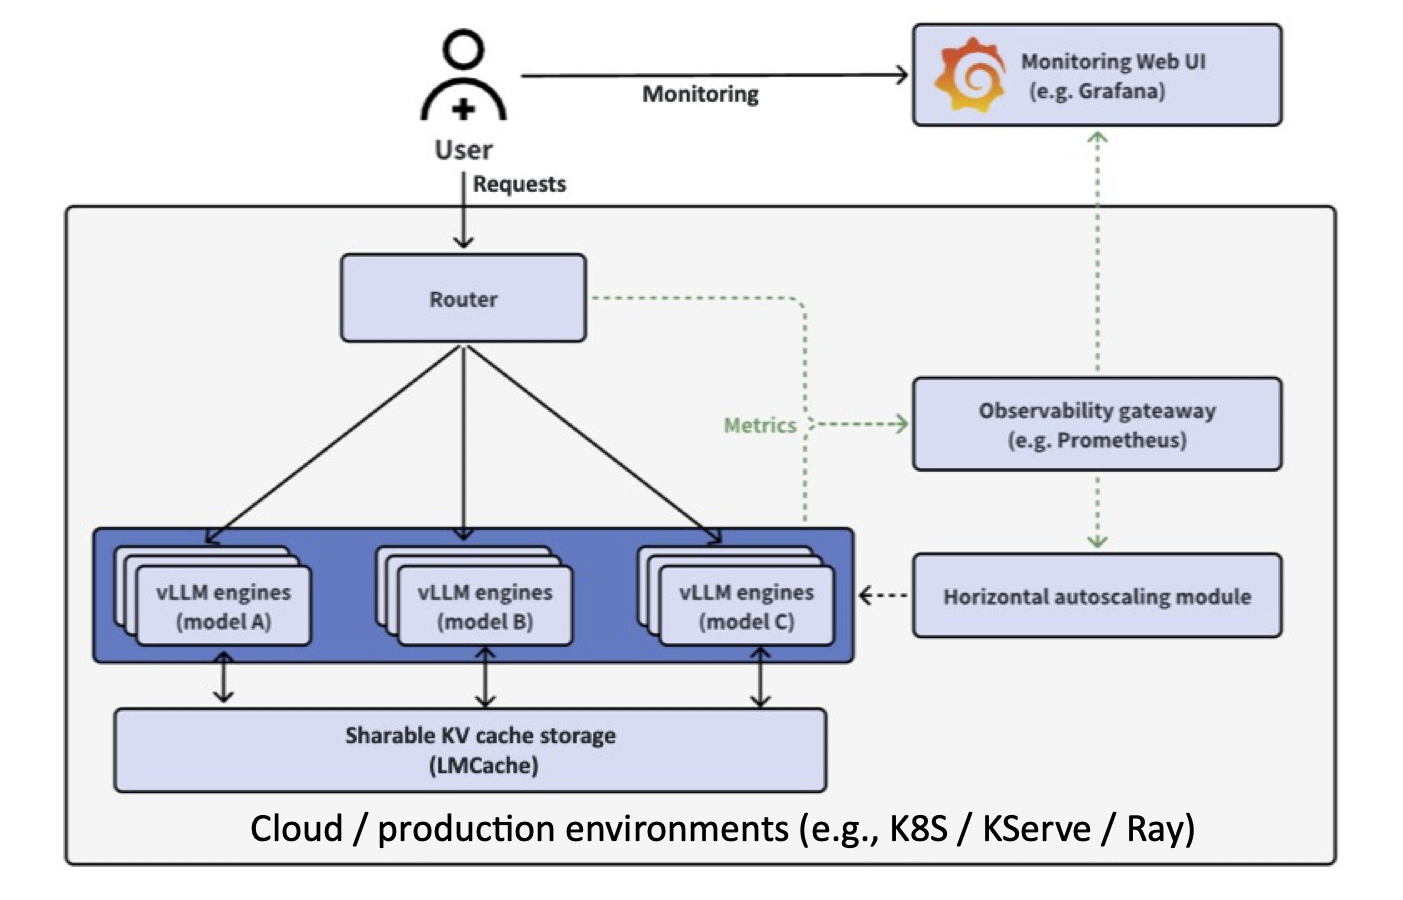
High Performance and Easy Deployment of vLLM in K8S with “vLLM ...
High Performance and Easy Deployment of vLLM in K8S with vLLM ...
vLLM 2026: Open Source LLM Inference Engine im Detail
vLLM: High-Throughput LLM Inference Serving Engine | Inference Systems
vLLM Guide 2026 | High-Throughput LLM Serving
vLLM Architecture — Inside the Fastest Open-Source LLM Server | tutorialQ

Free Video: vLLM Inference and LLM Server Engine for Machine Learning ...

Optimizing LLM Throughput with vLLM: Understanding the Engine Behind ...
Advertisement Space (336x280)
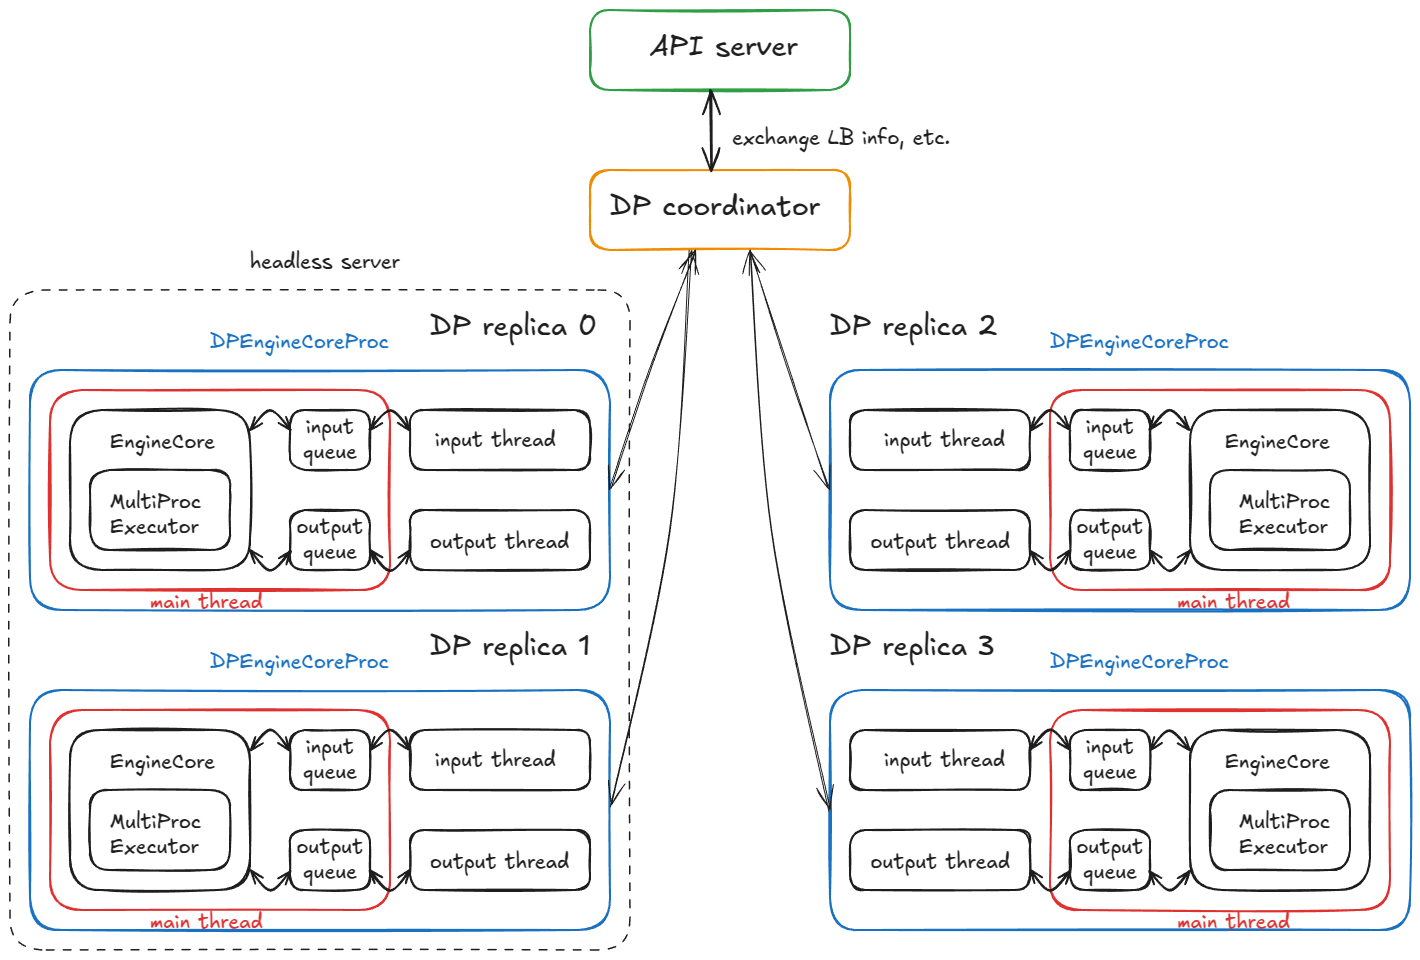
Inside vLLM: Anatomy of a High-Throughput LLM Inference System | vLLM Blog

Autellix: An Efficient Serving Engine for LLM Agents as General ...
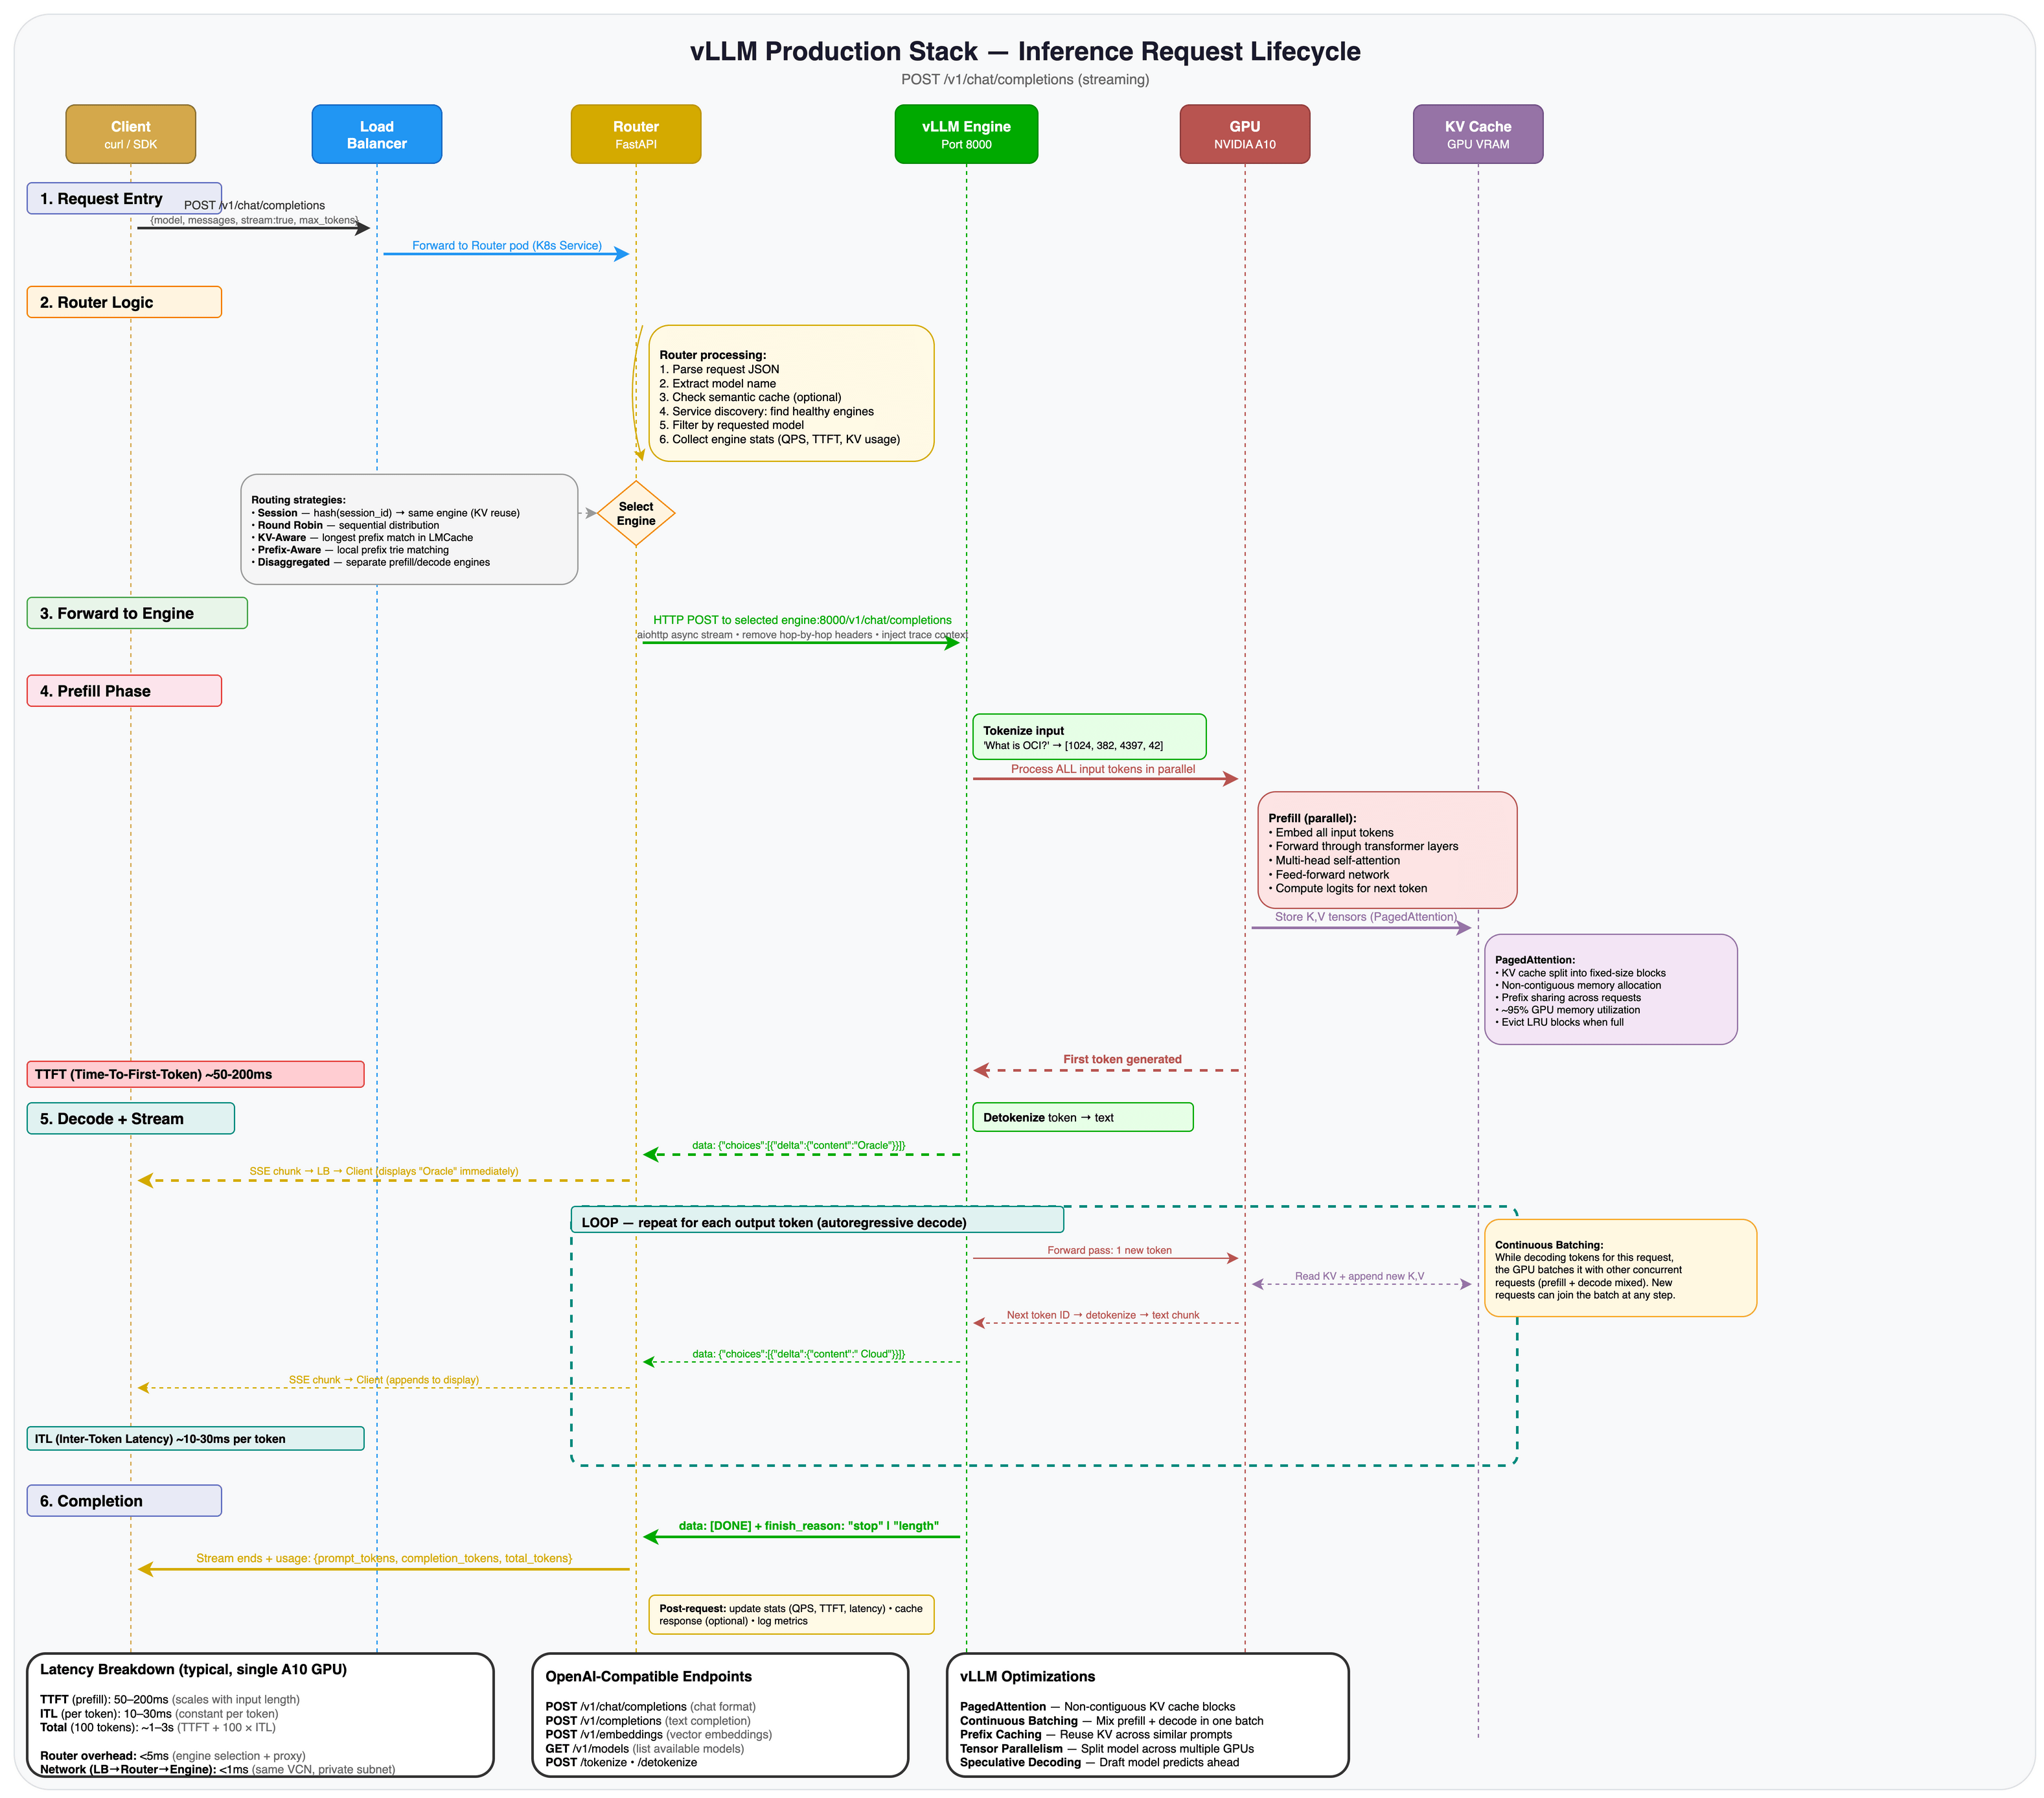
Deploy OpenAI vLLM Production Stack on Oracle Kubernetes Engine (OKE)
vLLM, SGLang, or TensorRT-LLM? Picking an LLM Serving Stack | Jarvis ...

LLM Serving Engine Comparison: vLLM, TensorRT-LLM, SGLang | Adiyogi ...
Maximizing LLM Performance through vLLM Techniques

vLLM Explained in 10 Minutes: Faster LLM Serving - YouTube

LLM vs vLLM: The Engine Behind AI Success | Sam Sadra Shokouhi posted ...

How vLLM solves LLM serving issues for AI apps | Aaroh Bhardwaj posted ...
Efficient LLM Inference and Serving with vLLM
Advertisement Space (336x280)
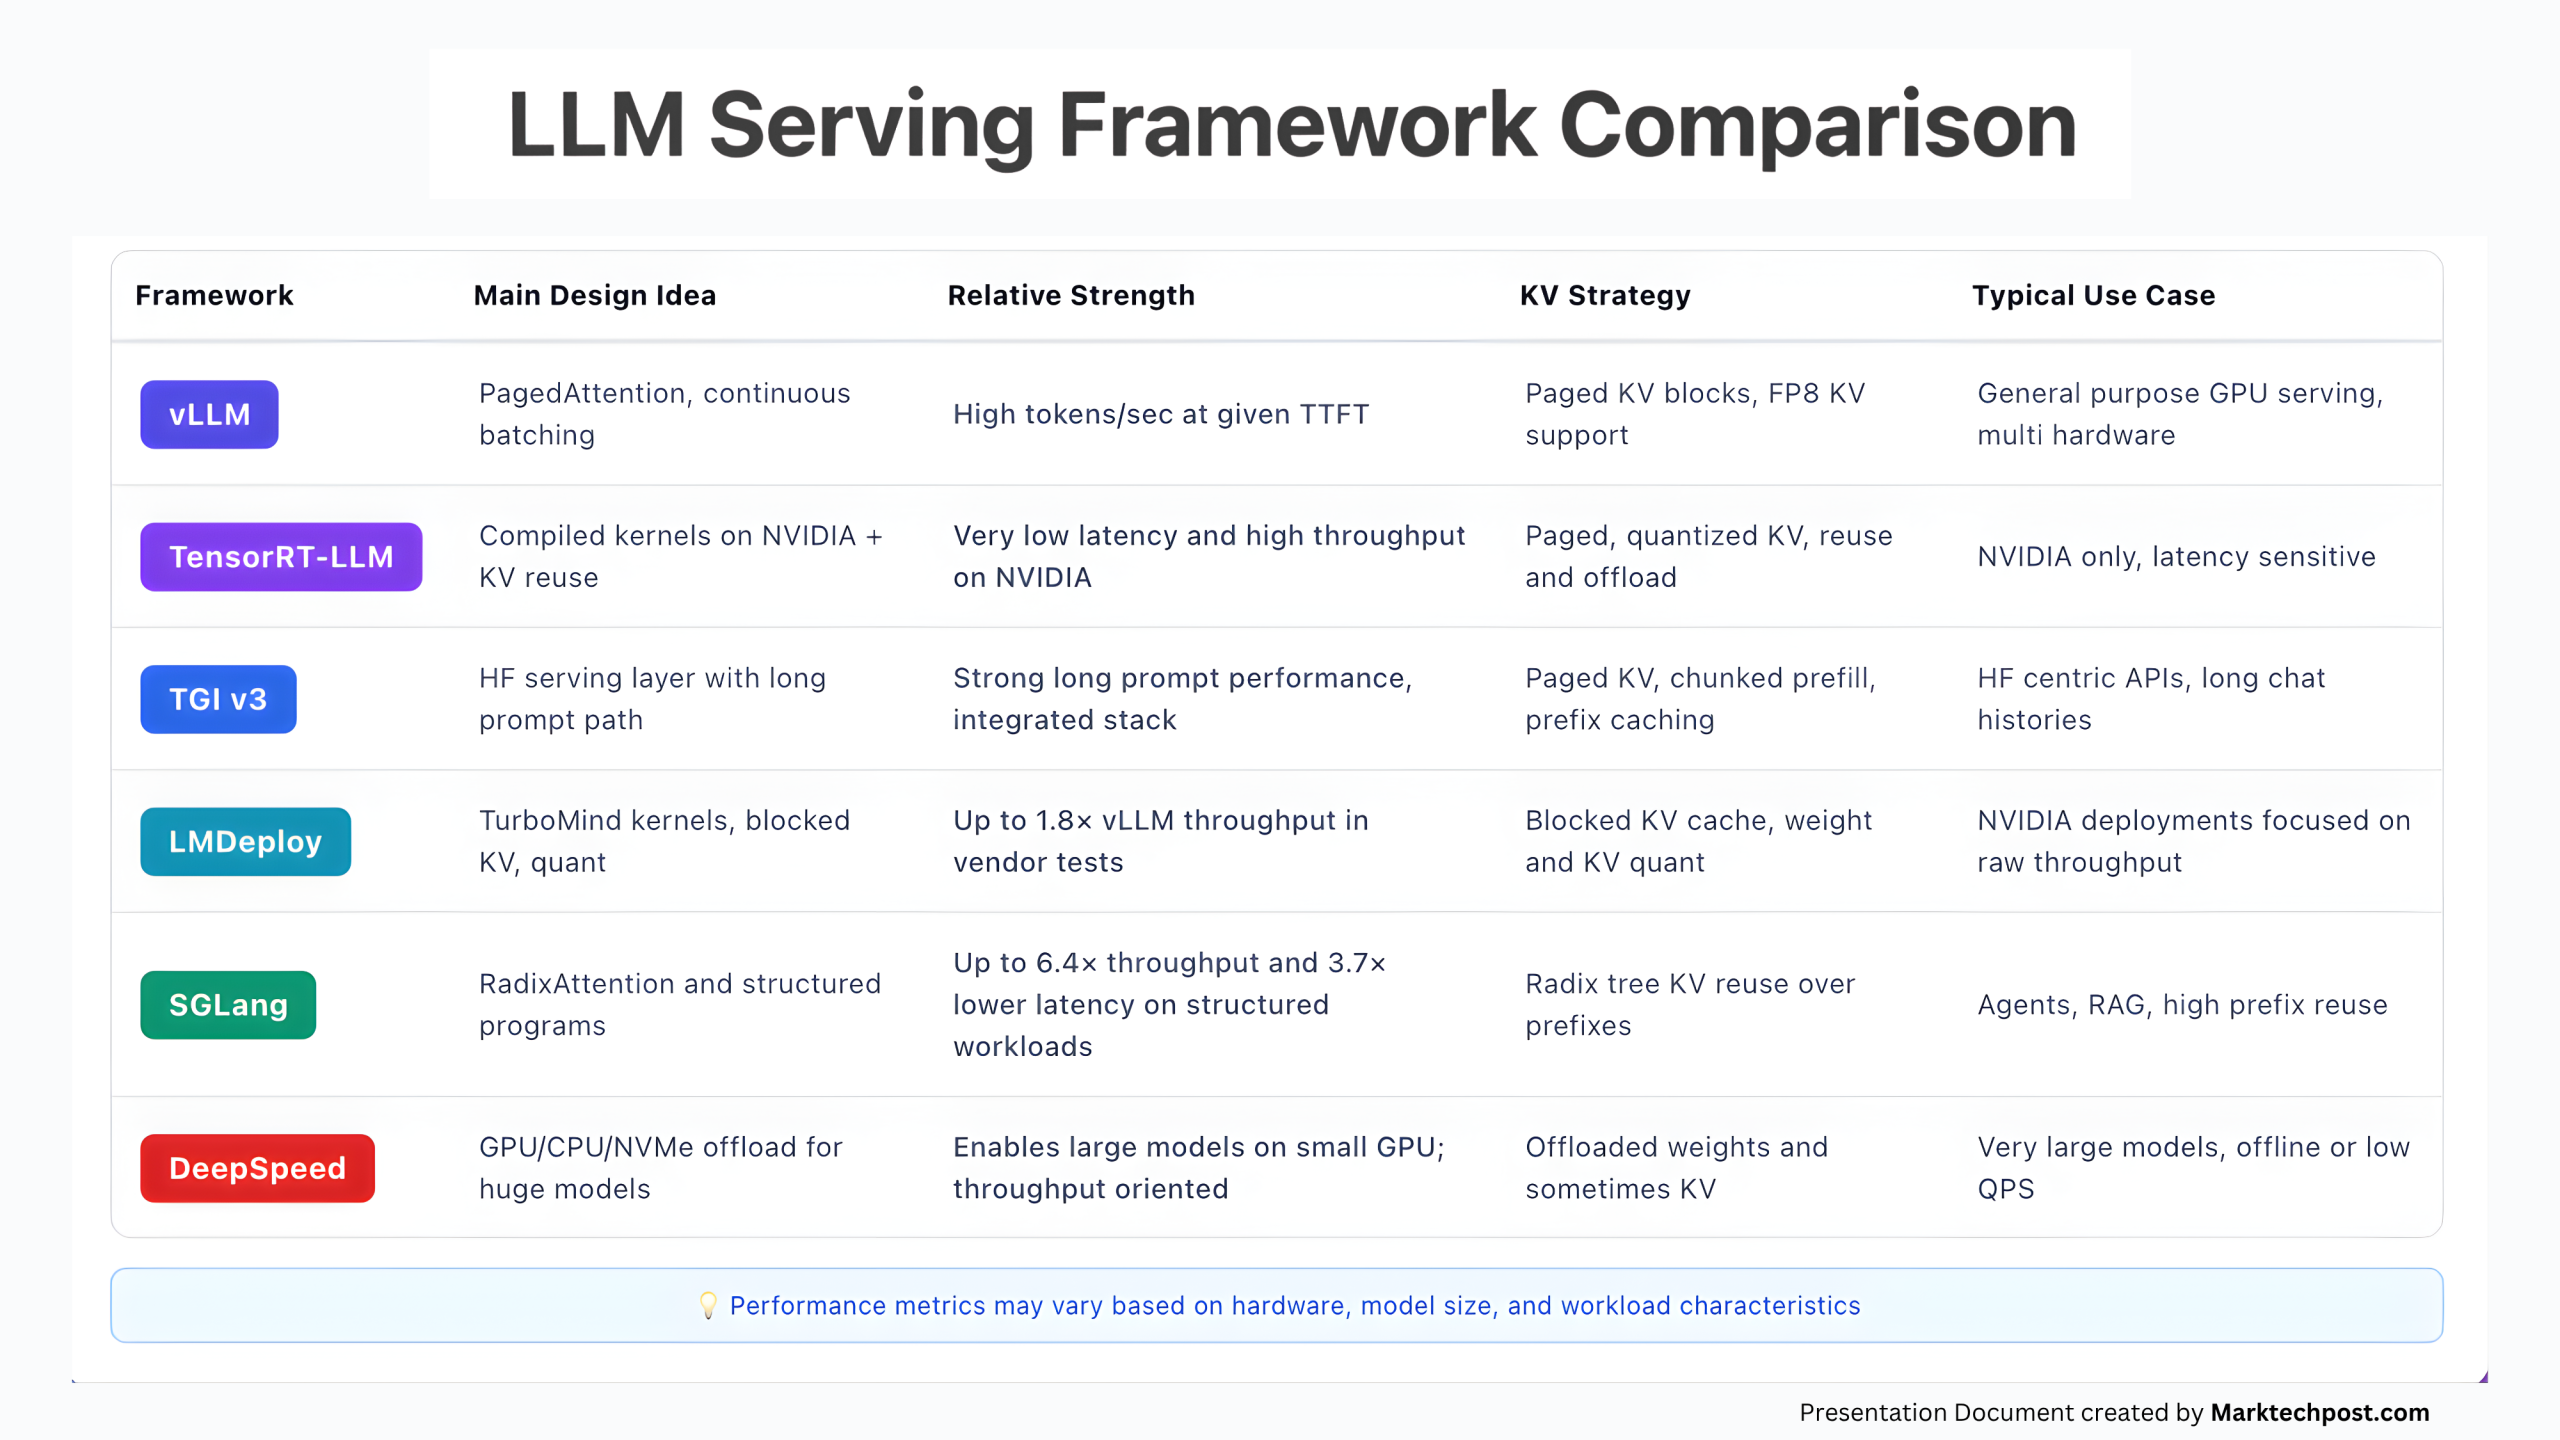
Comparing the Top 6 Inference Runtimes for LLM Serving in 2025 ...
vLLM - High-throughput LLM inference engine with PagedAttention ... at ...

Install vLLM on Linux for Production LLM Serving (2026 Guide)
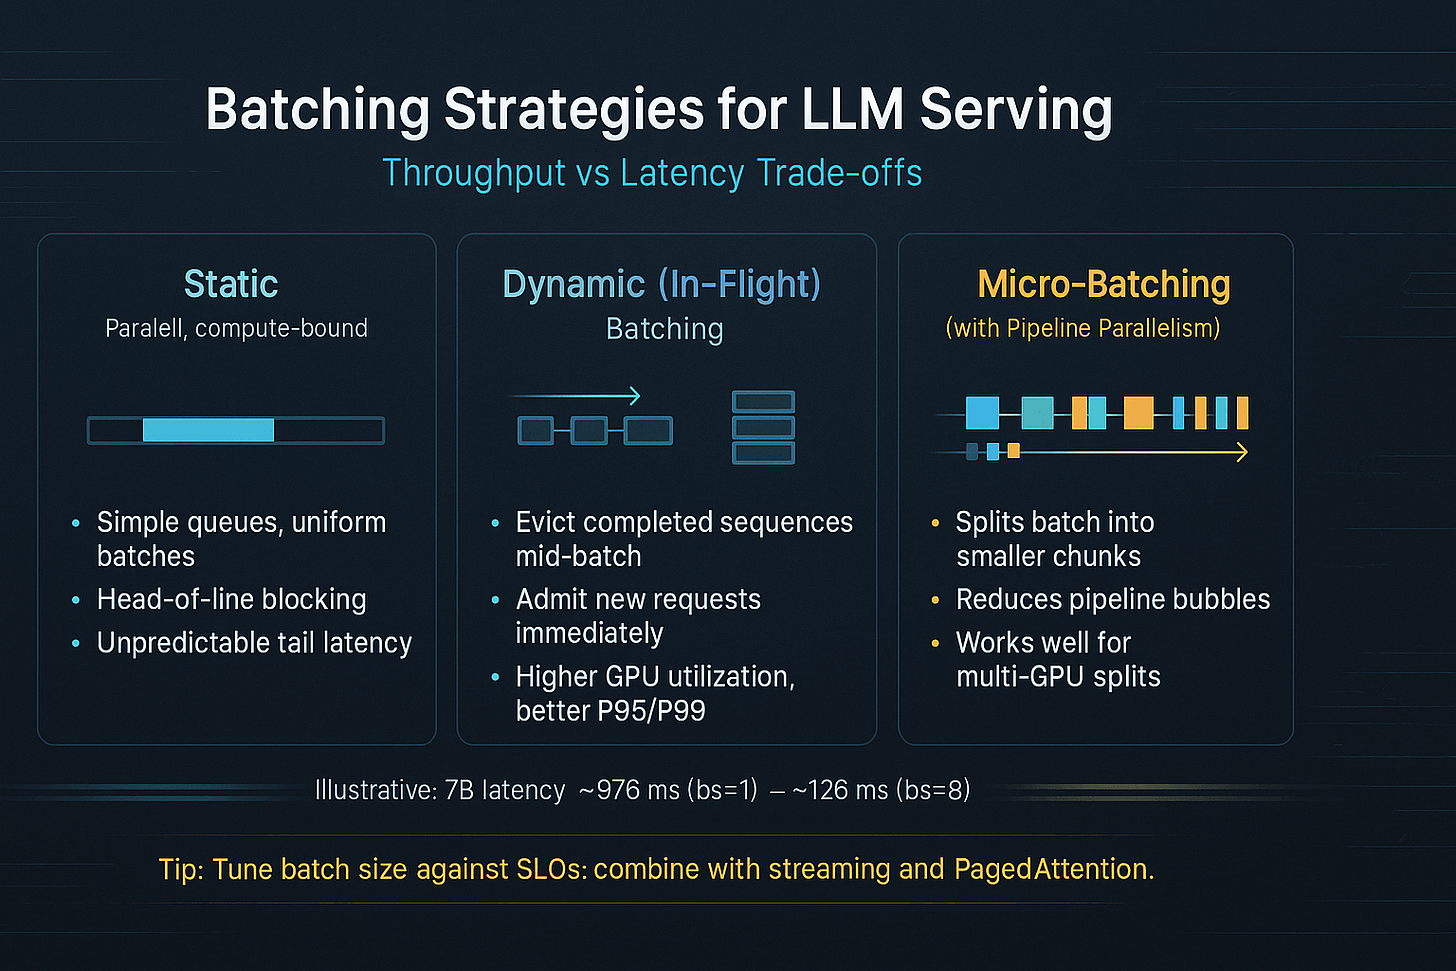
Nano vLLM: A Tiny Inference Engine that Teaches you the Big Ideas ...
vLLM 2026: Open Source LLM Inference Engine im Detail

vLLM Review 2026: High-Throughput LLM Inference Engine | ToolHalla