
Optimize Automotive Inference Pipelines With Tensorrt Llm And Onnx
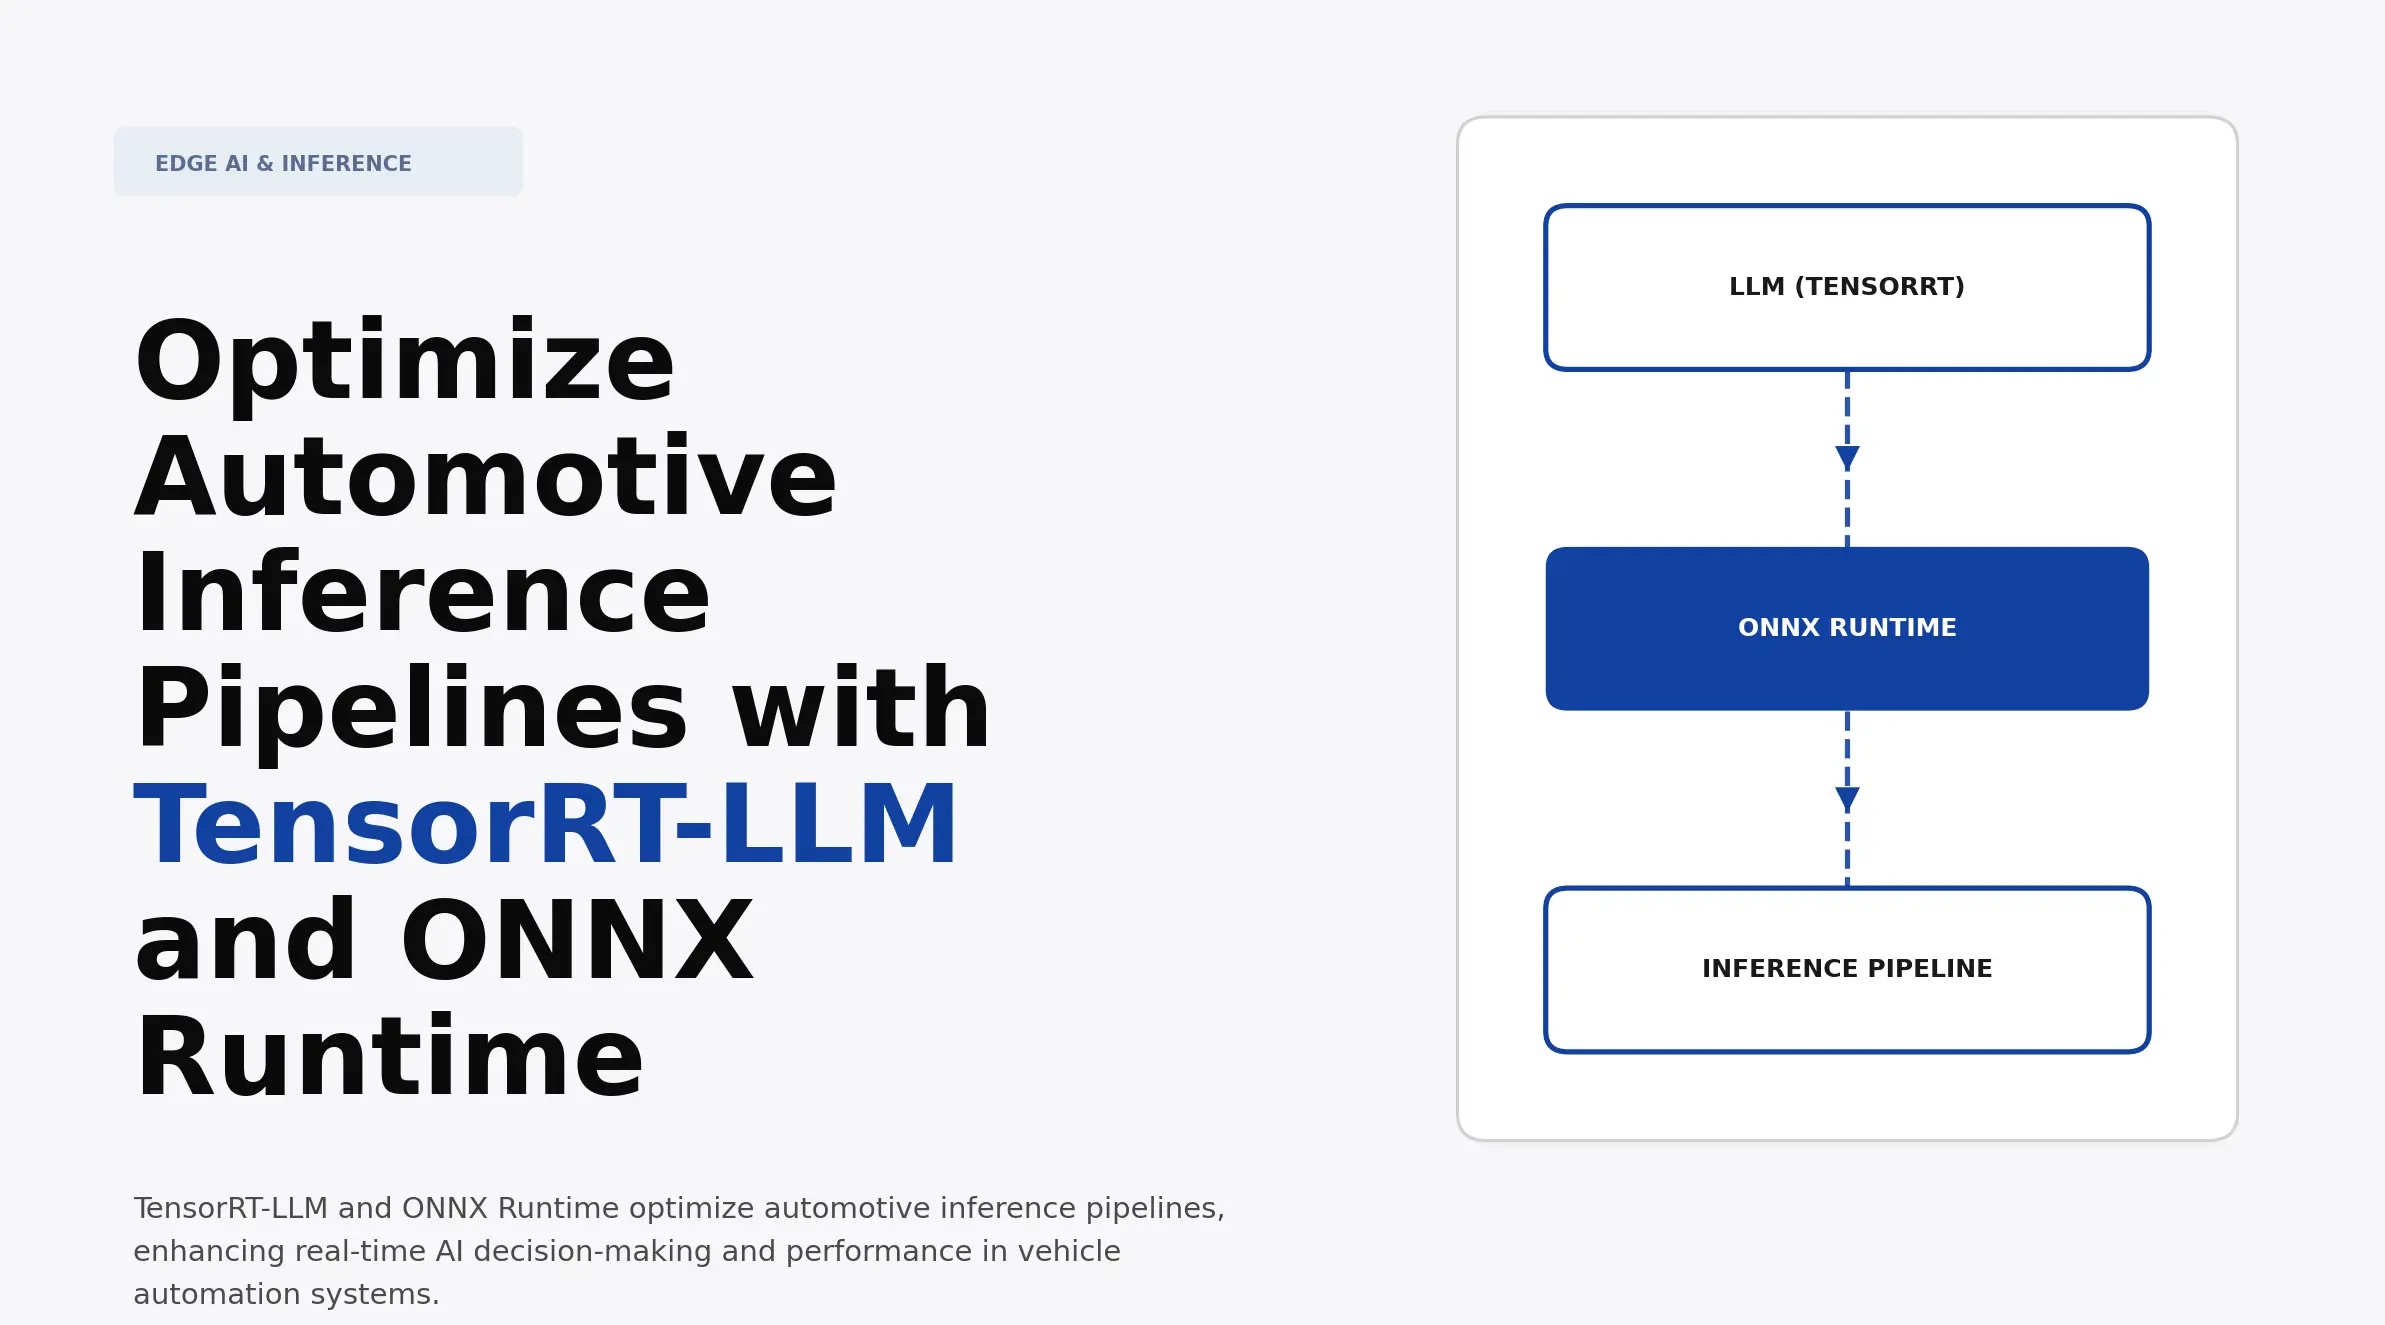
Optimize Automotive Inference Pipelines with TensorRT-LLM and ONNX ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...

Accelerating LLM and VLM Inference for Automotive and Robotics with ...
Advertisement Space (300x250)

Accelerating LLM and VLM Inference for Automotive and Robotics with ...
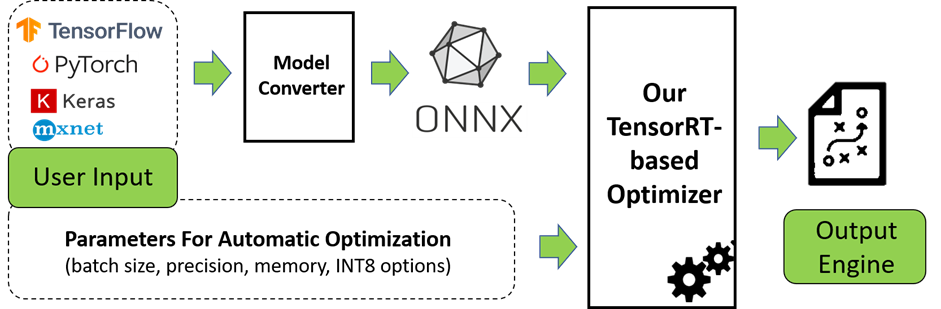
Nvidia Tensorrt Inference With Onnx – OHYE
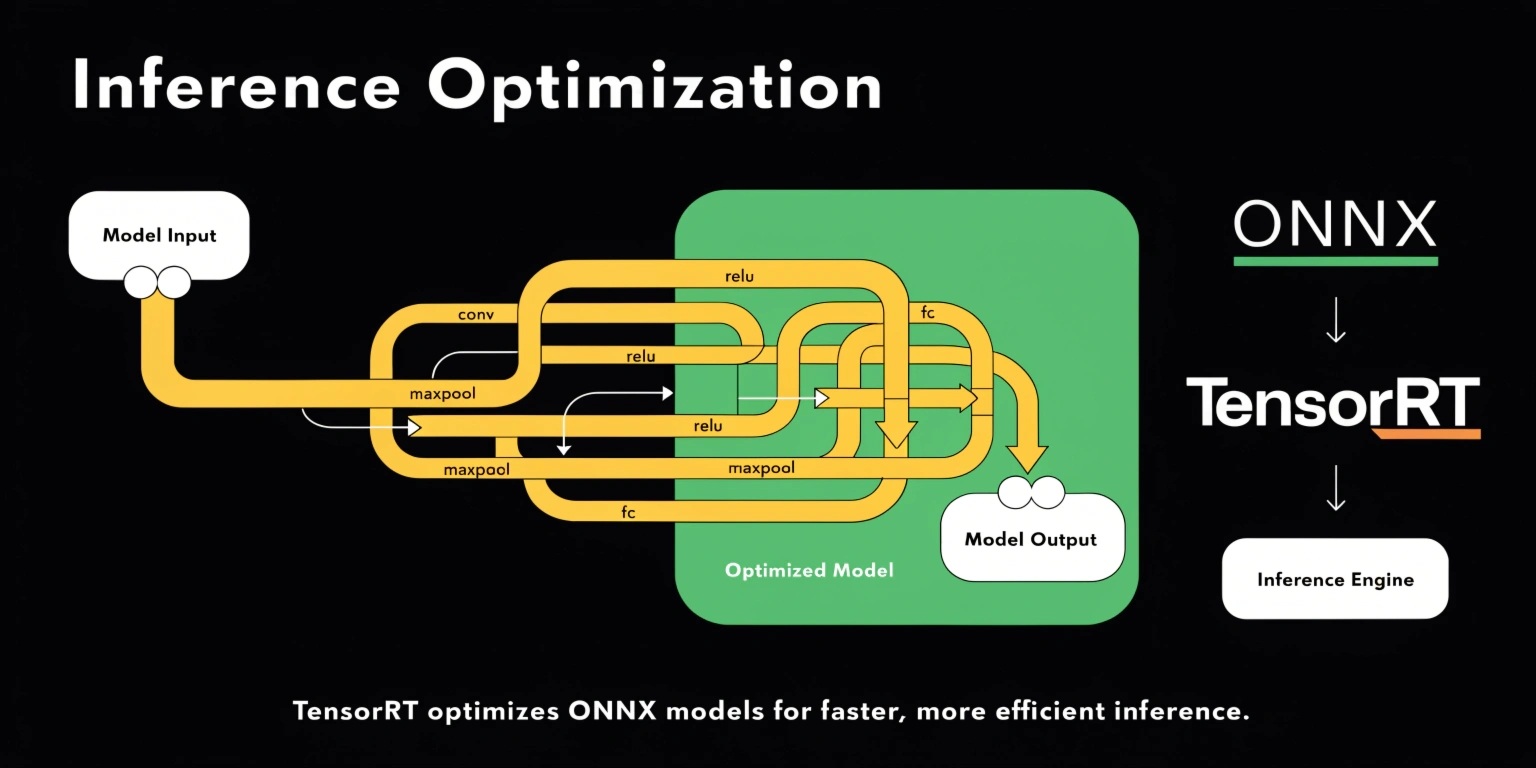
Inference Optimization Using TensorRT and ONNX for Faster AI Model ...

Automating Inference Optimizations with NVIDIA TensorRT LLM AutoDeploy ...
Optimize Generative AI inference with Quantization in TensorRT-LLM and ...

Automating Inference Optimizations with NVIDIA TensorRT LLM AutoDeploy ...

Automating Inference Optimizations with NVIDIA TensorRT LLM AutoDeploy ...

Automating Inference Optimizations with NVIDIA TensorRT LLM AutoDeploy ...

Automating Inference Optimizations with NVIDIA TensorRT LLM AutoDeploy ...

How to Optimize LLM Pipelines with TextGrad
Advertisement Space (336x280)
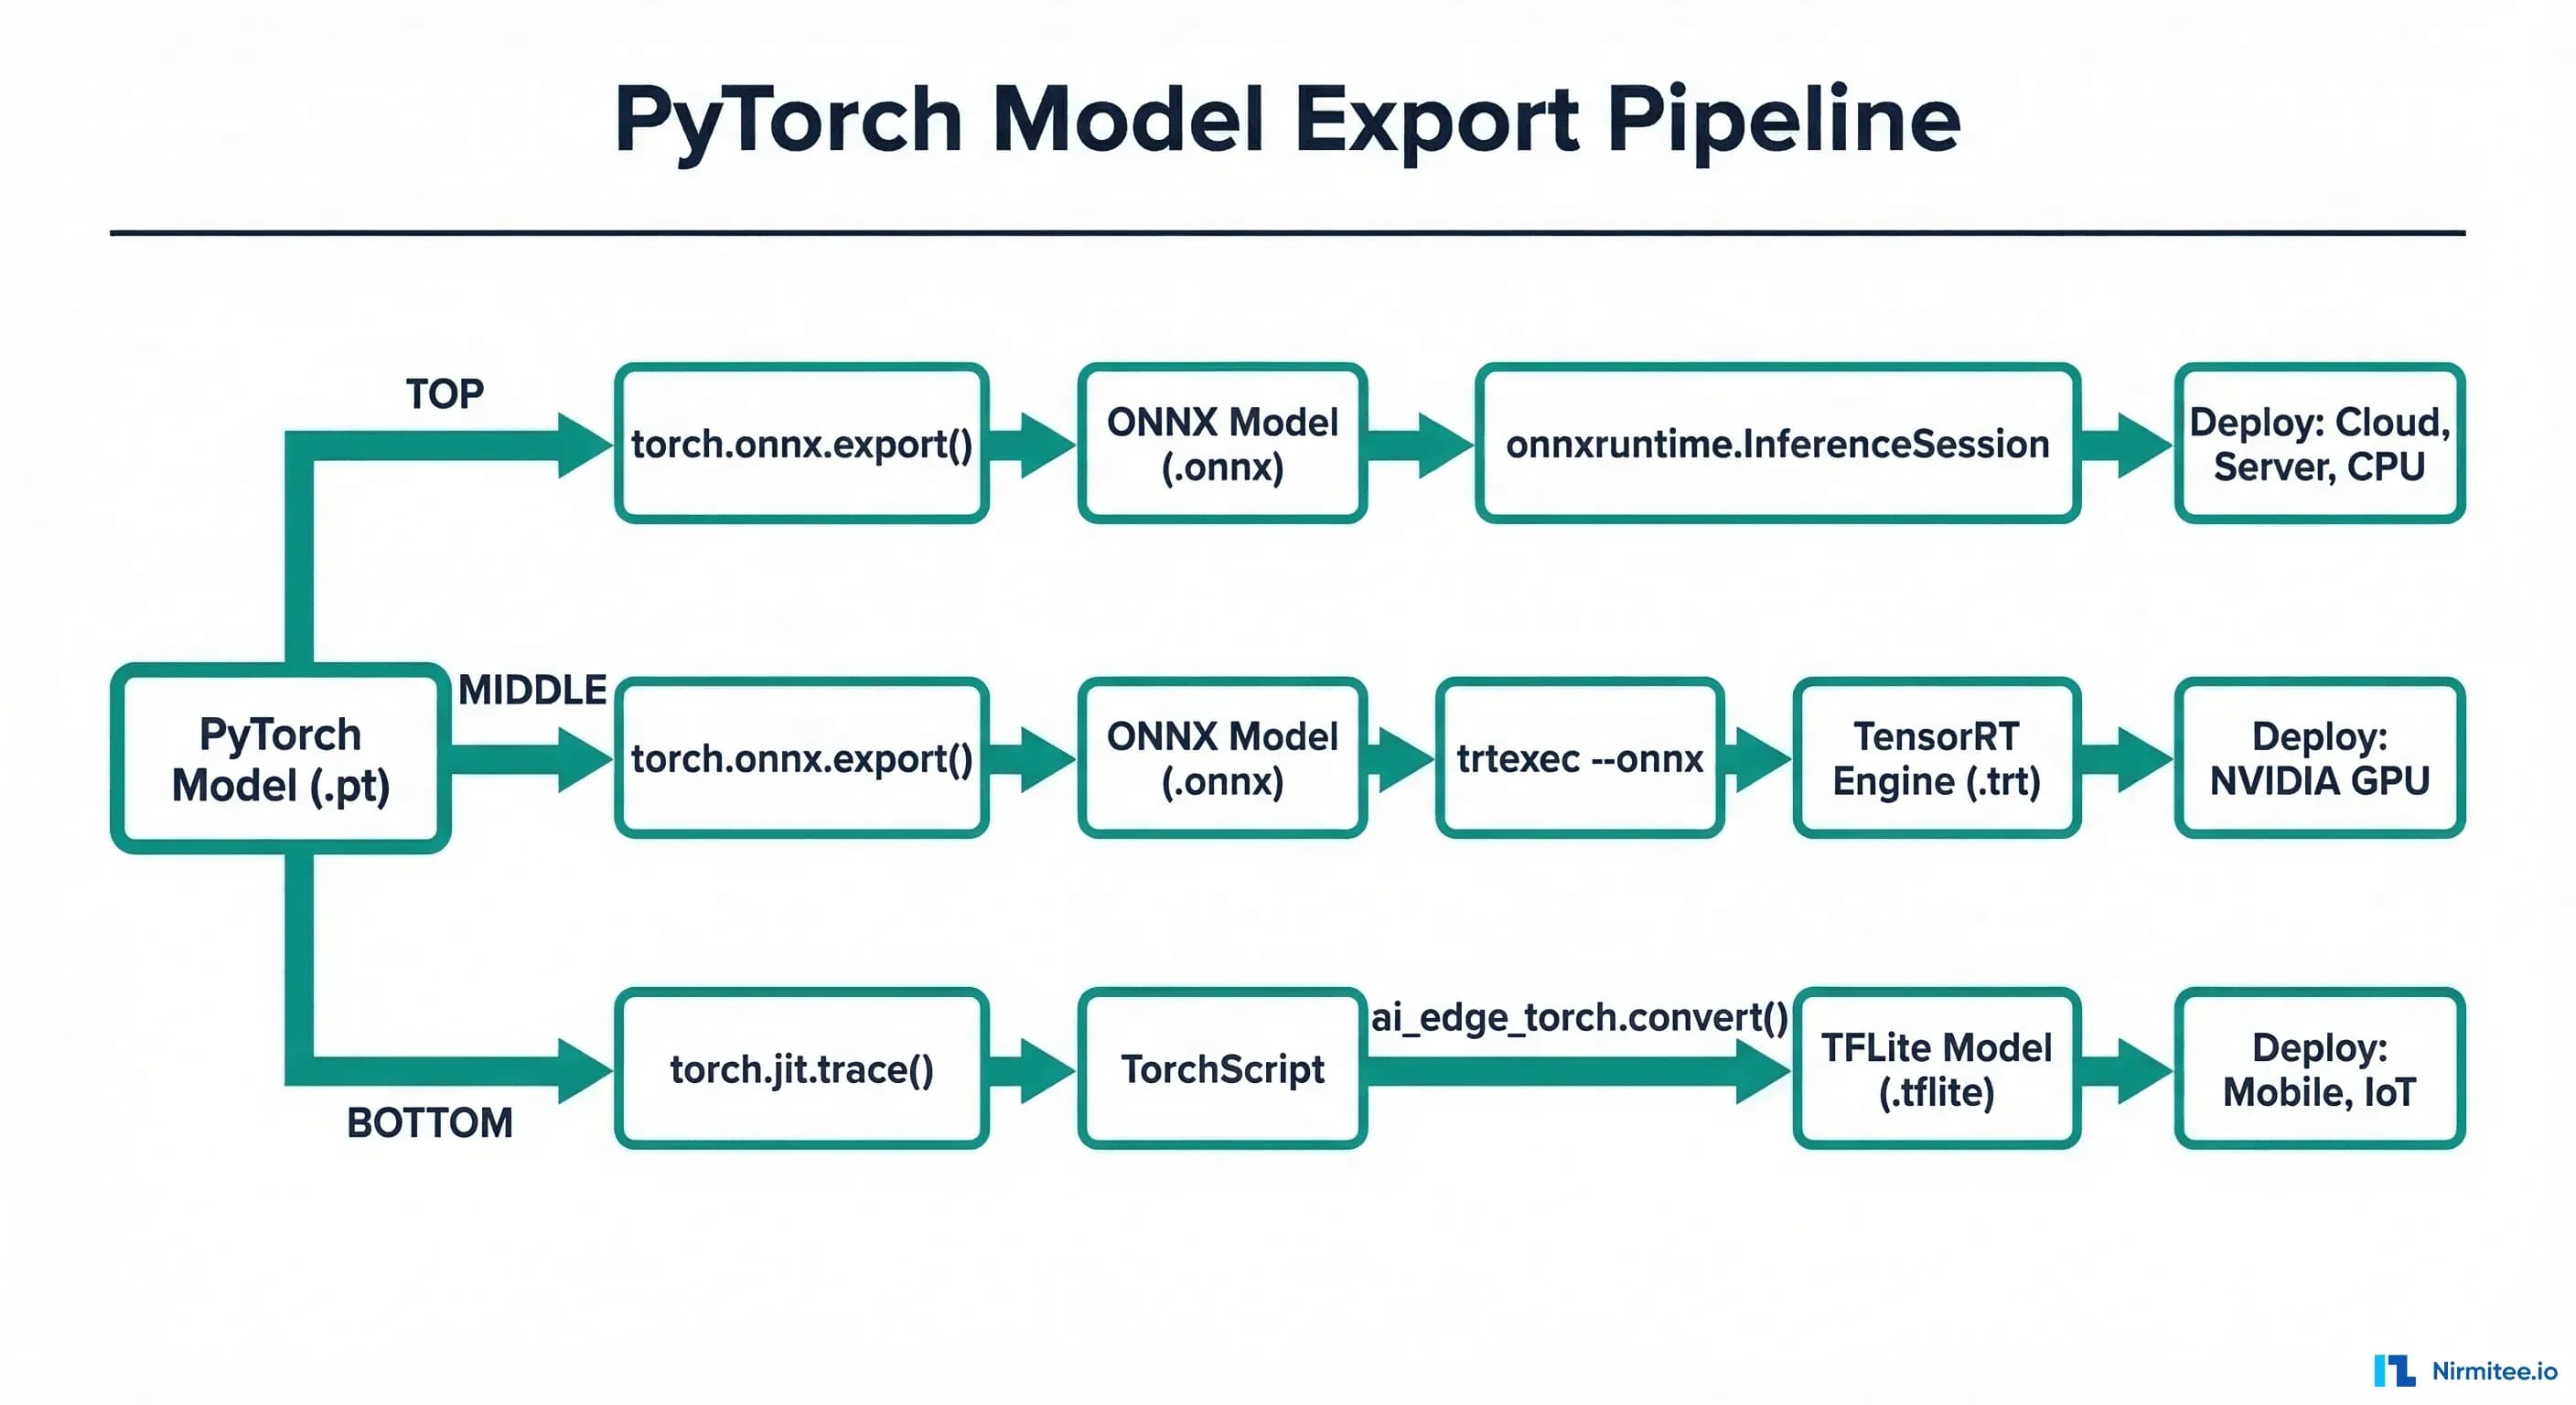
ONNX vs TensorRT vs TFLite: Choosing Your ML Inference
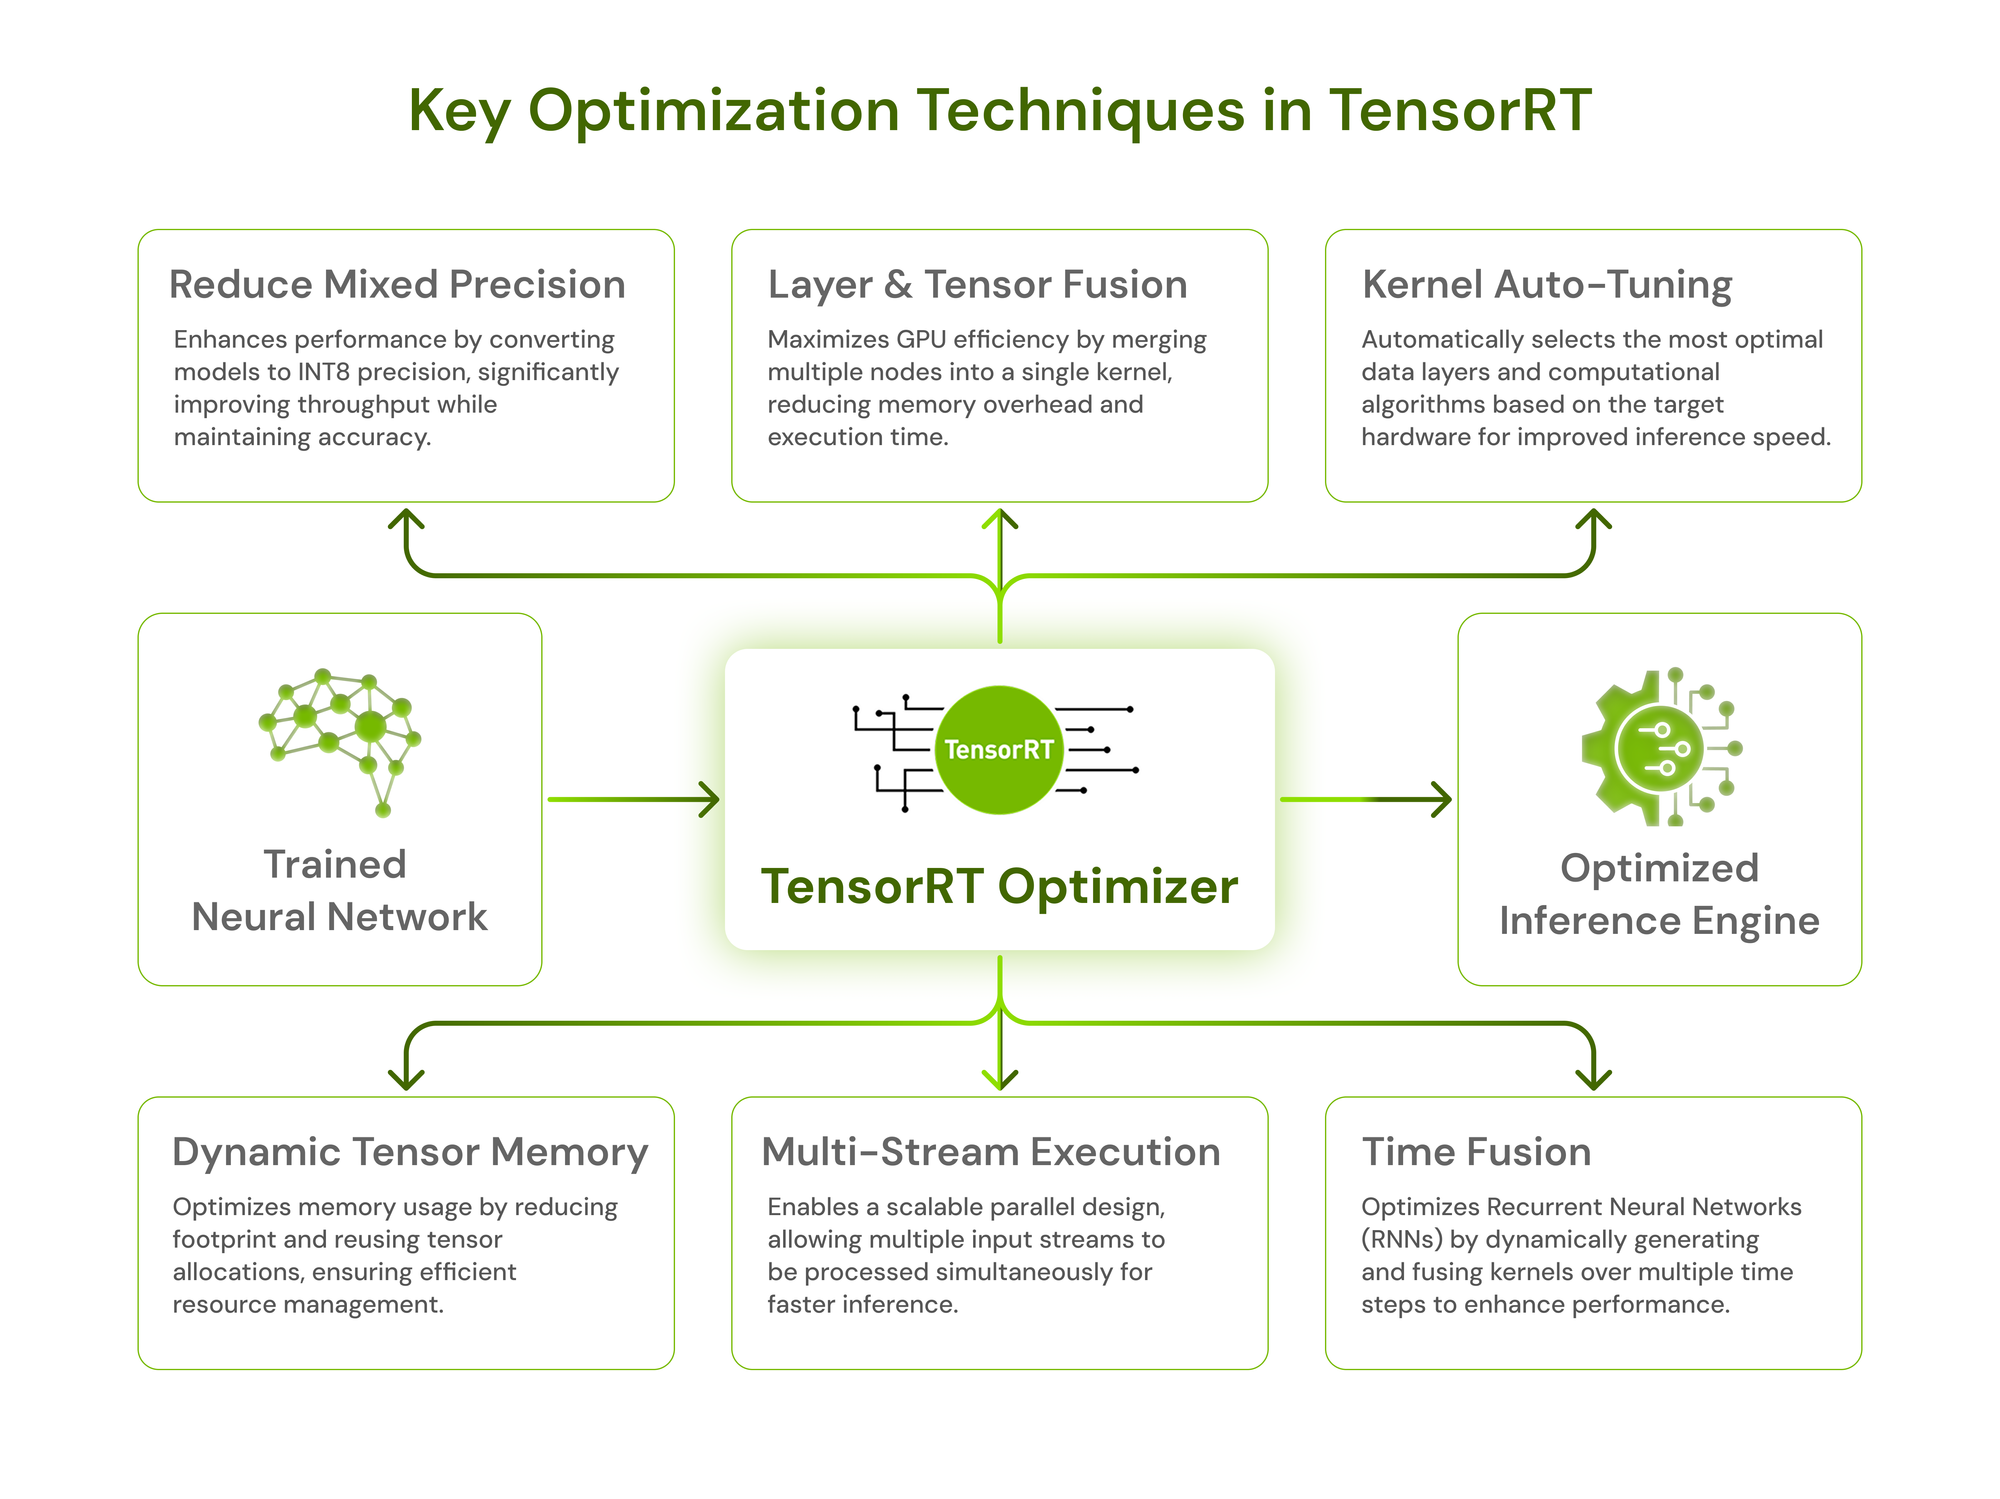
How to optimize inference using TensorRT on Jetson AGX Orin
AI Inference Optimization: TensorRT vs OpenVINO vs ONNX Runtime
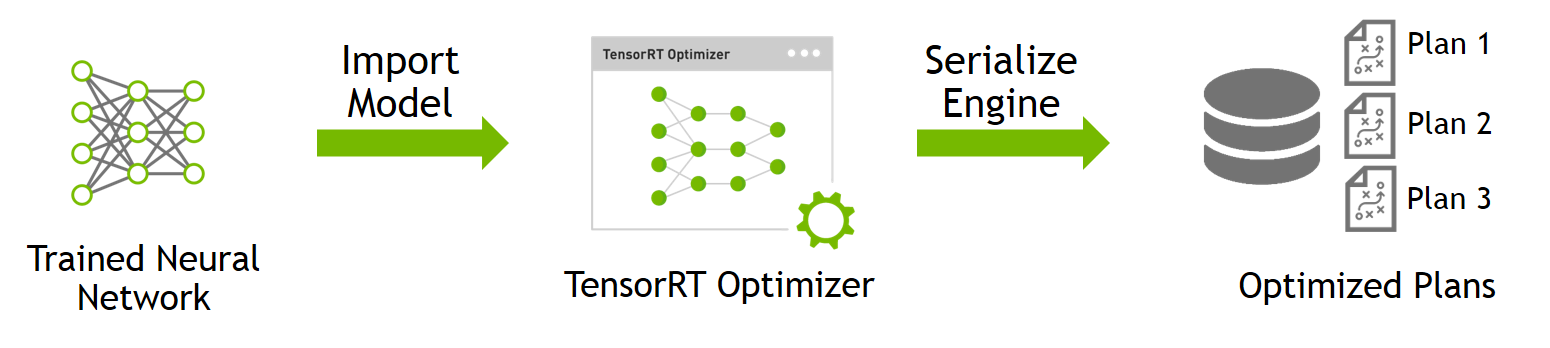
TensorRT 3: Faster TensorFlow Inference and Volta Support | NVIDIA ...
Building Industrial embedded deep learning inference pipelines with ...

ONNX (Open Neural Network Exchange): Portable AI Models, TensorRT and ...

Serving ML Model Pipelines on NVIDIA Triton Inference Server with ...
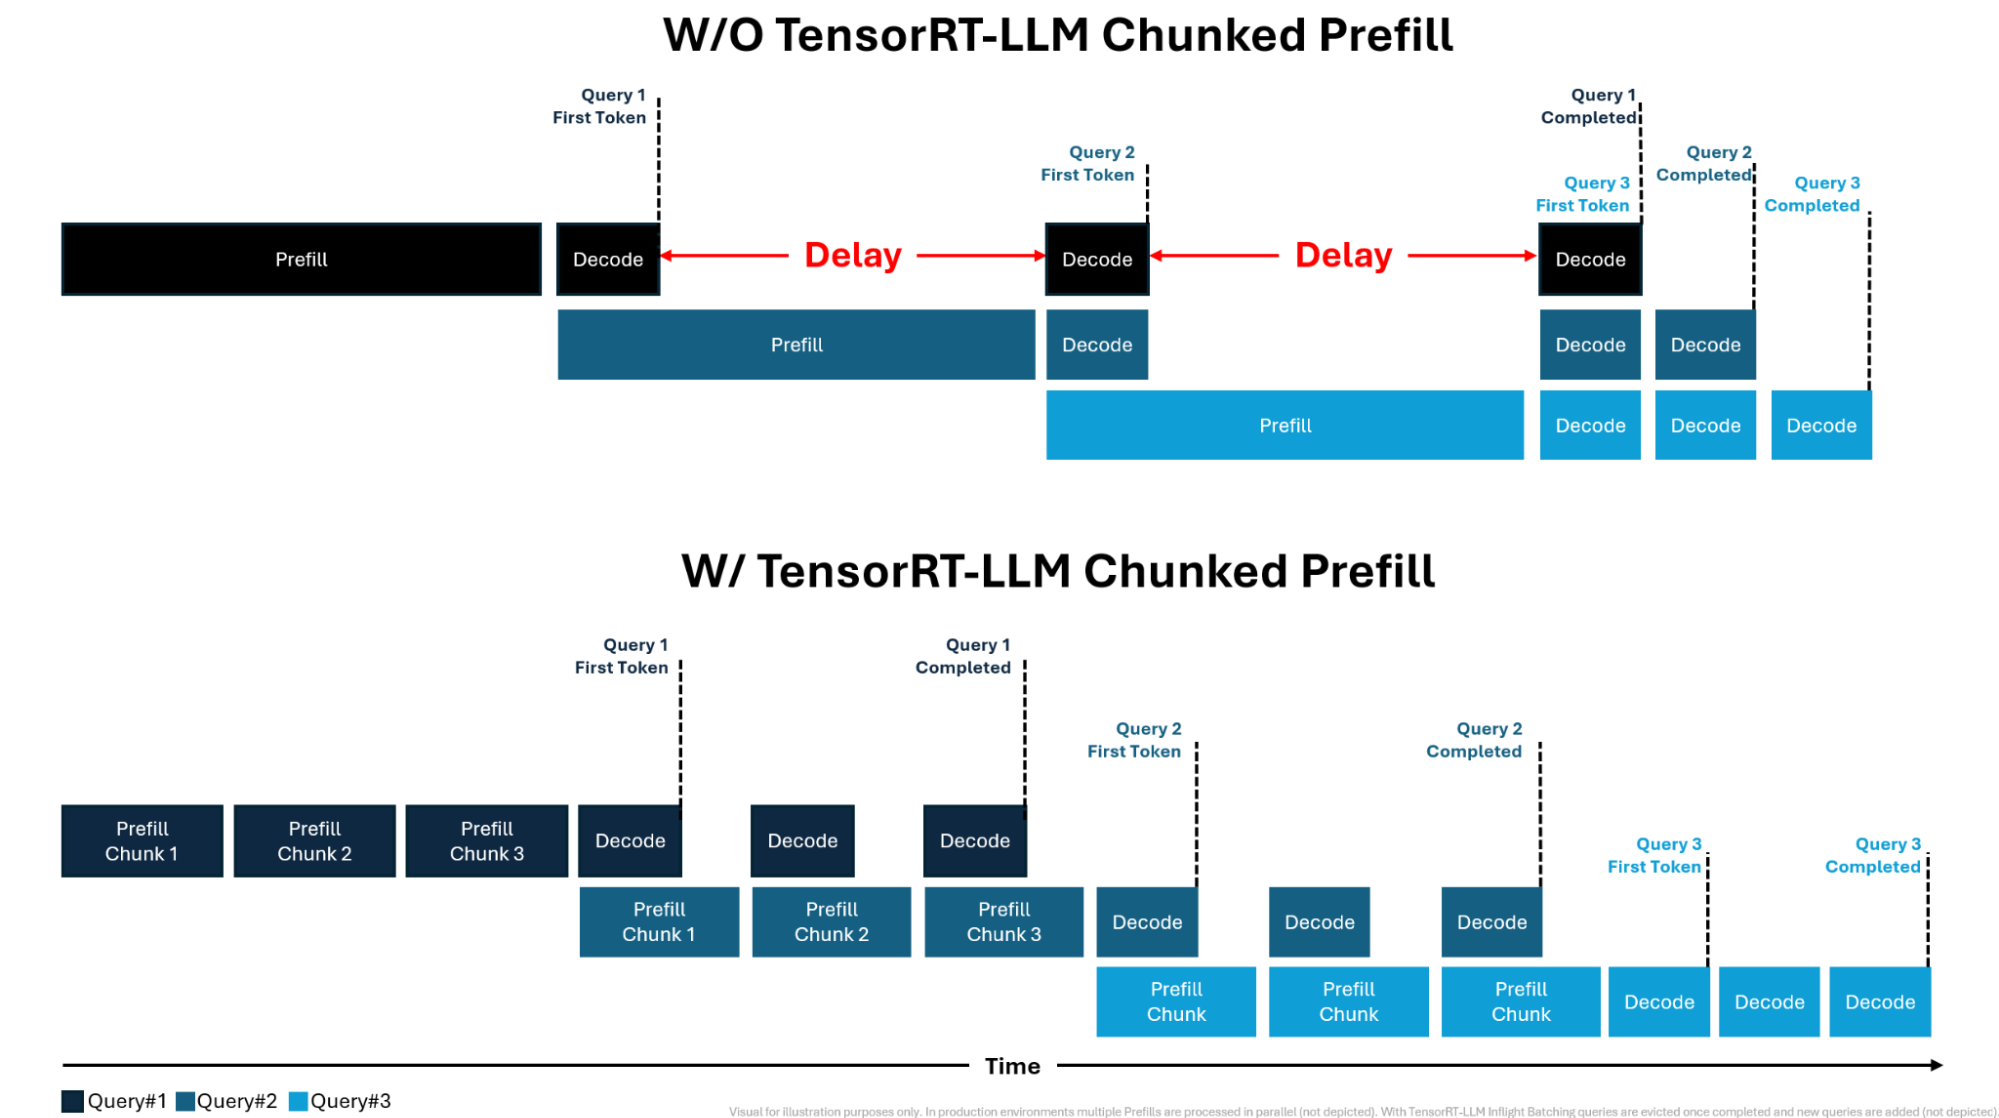
Streamlining AI Inference Performance and Deployment with NVIDIA ...

Accelerate LLM inference with NVIDIA TensorRT-LLM – optimise for speed ...
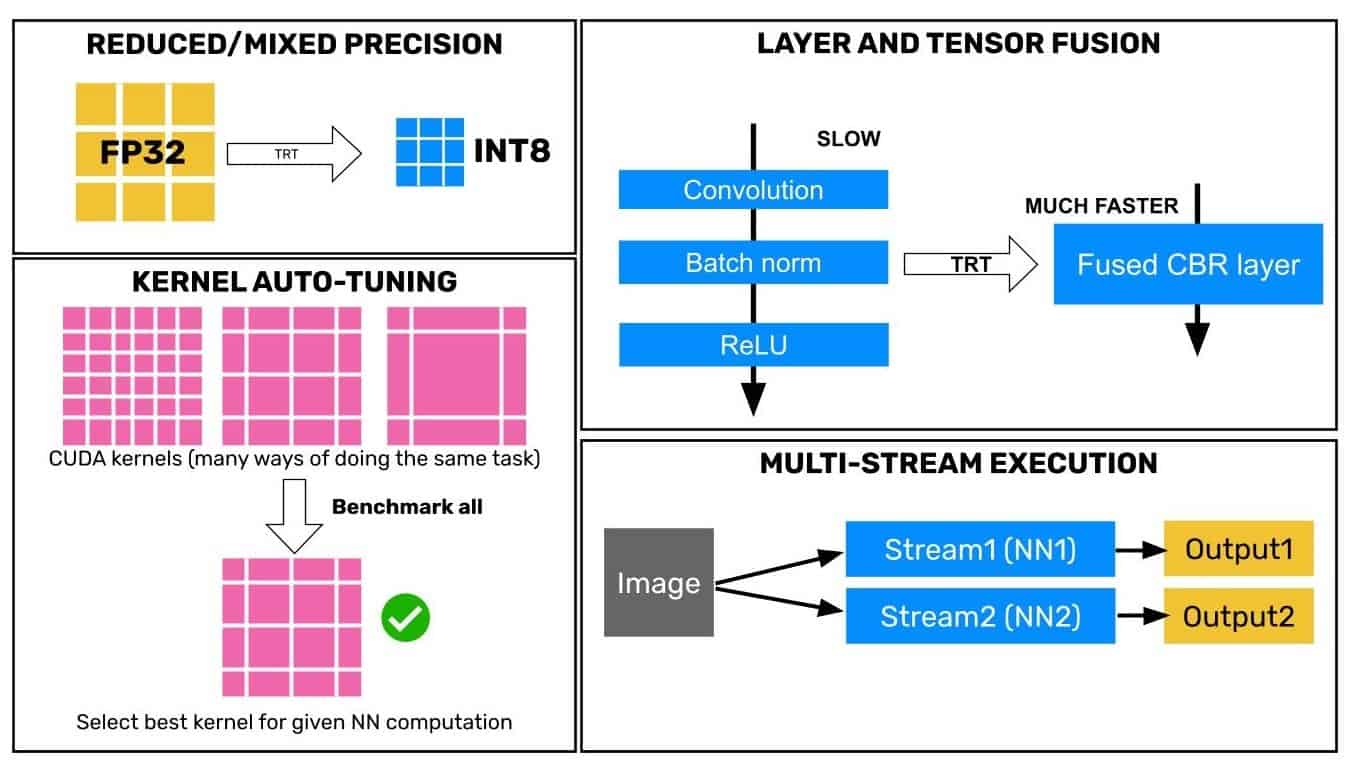
Building Industrial embedded deep learning inference pipelines with ...
Advertisement Space (336x280)

LLM Inference Benchmarking: Performance Tuning with TensorRT-LLM ...
Boost inference speeds with NVIDIA TensorRT on UbiOps - UbiOps - AI ...

AI Inference Optimization: TensorRT vs OpenVINO vs ONNX Runtime

TensorRT inference optimization process. | Download Scientific Diagram

ONNX Runtime and TensorRT总结 - 知乎

TensorRT 和 ONNX Runtime 推理优化实战:10 个降低延迟的工程技巧_tensorrt runtime-CSDN博客