
Achieve 23x Llm Inference Throughput Reduce P50 Latency
Achieve 23x LLM Inference Throughput & Reduce p50 Latency
Achieve 23x LLM Inference Throughput & Reduce p50 Latency
Achieve 23x LLM Inference Throughput & Reduce p50 Latency
Achieve 23x LLM Inference Throughput & Reduce p50 Latency
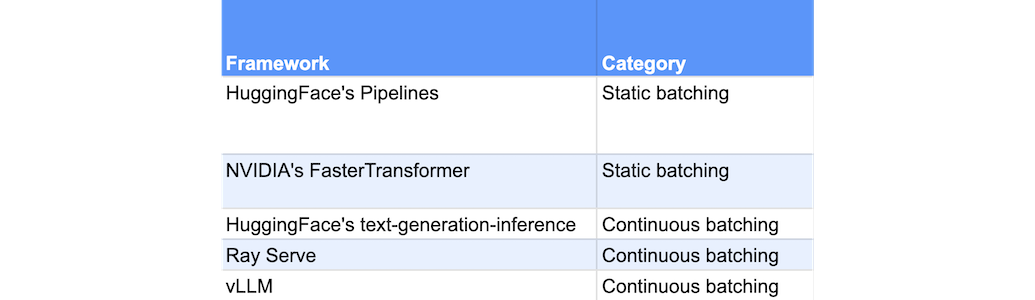
Achieve 23x LLM Inference Throughput & Reduce p50 Latency
Achieve 23x LLM Inference Throughput & Reduce p50 Latency
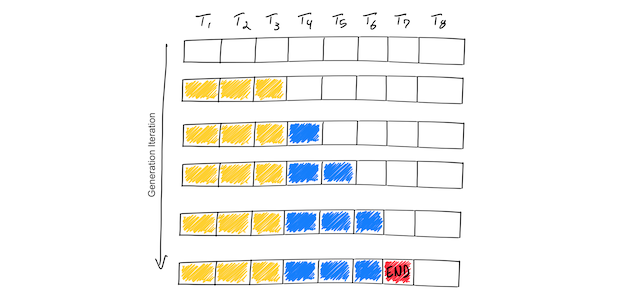
Achieve 23x LLM Inference Throughput & Reduce p50 Latency
Achieve 23x LLM Inference Throughput & Reduce p50 Latency

Adrian White on LinkedIn: Achieve 23x LLM Inference Throughput & Reduce ...
Continuous batching to increase LLM inference throughput and reduce p50 ...
Advertisement Space (300x250)

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...
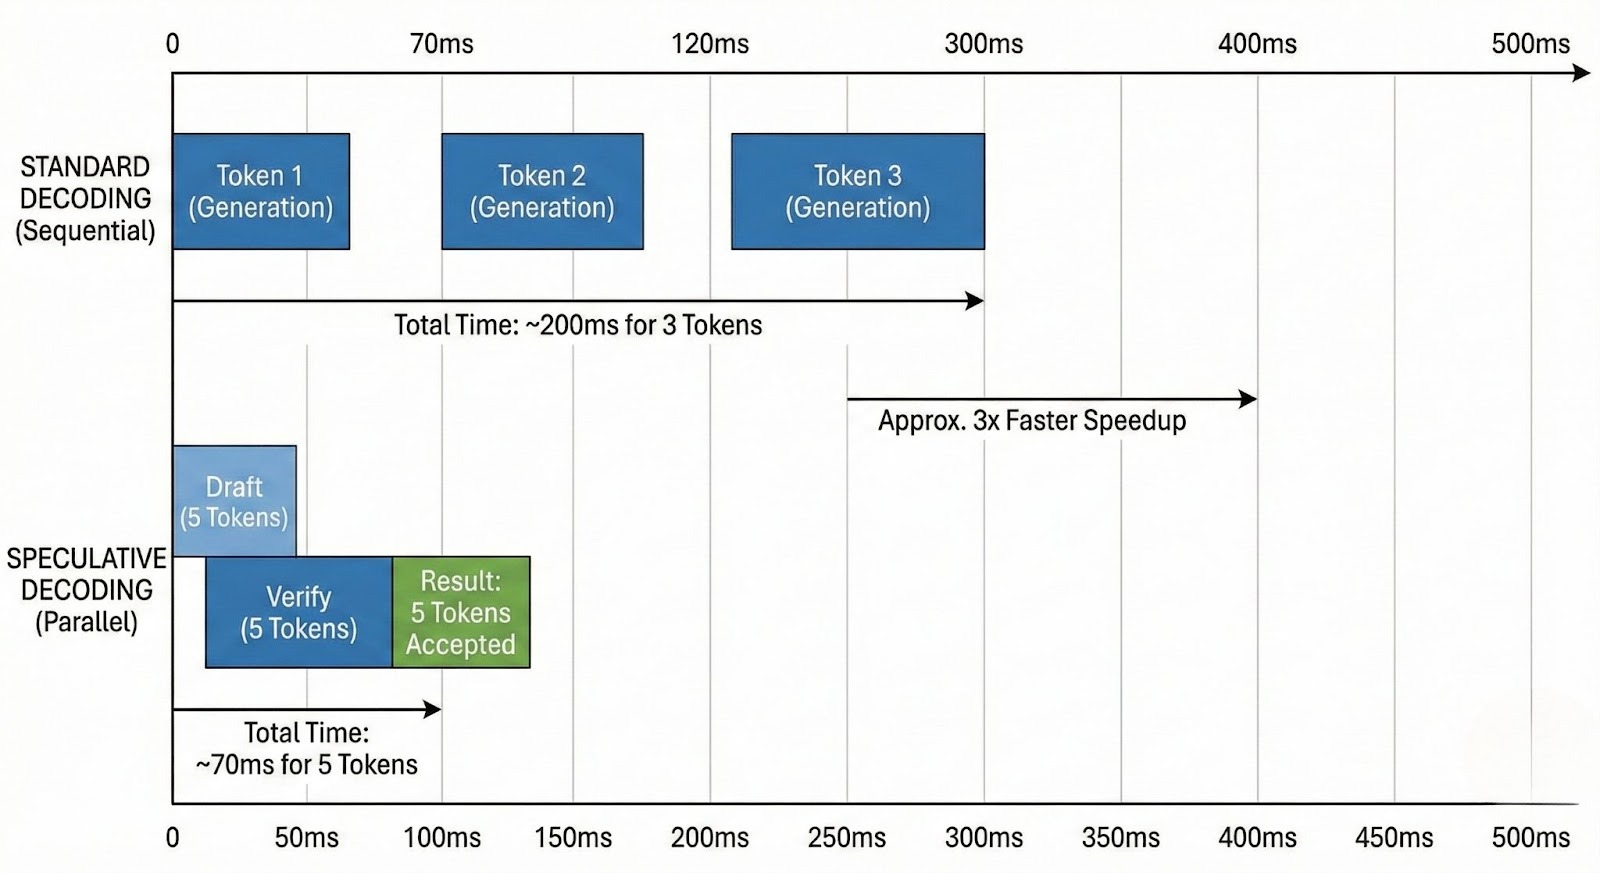
How to Achieve Ultra-Low Latency LLM Inference in the Cloud

LLM Inference Performance: Latency and Throughput Metrics - YouTube

How continuous batching enables 23x throughput in LLM inference ...

LLM Inference Optimization: Techniques That Actually Reduce Latency and ...

LLM Inference Optimization: Techniques That Actually Reduce Latency and ...
Advertisement Space (336x280)

LLM Inference Optimization: Techniques That Actually Reduce Latency and ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

LLM Inference Optimization: Techniques That Actually Reduce Latency and ...
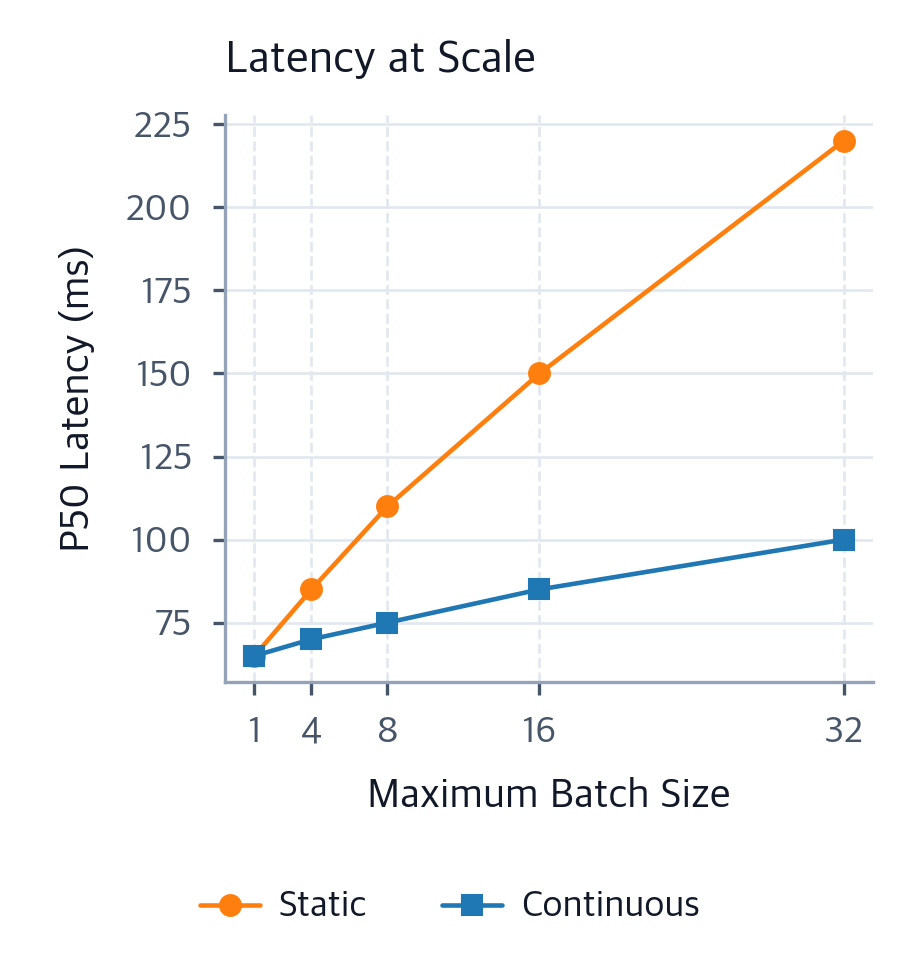
Continuous Batching: Optimizing LLM Inference Throughput - Interactive ...
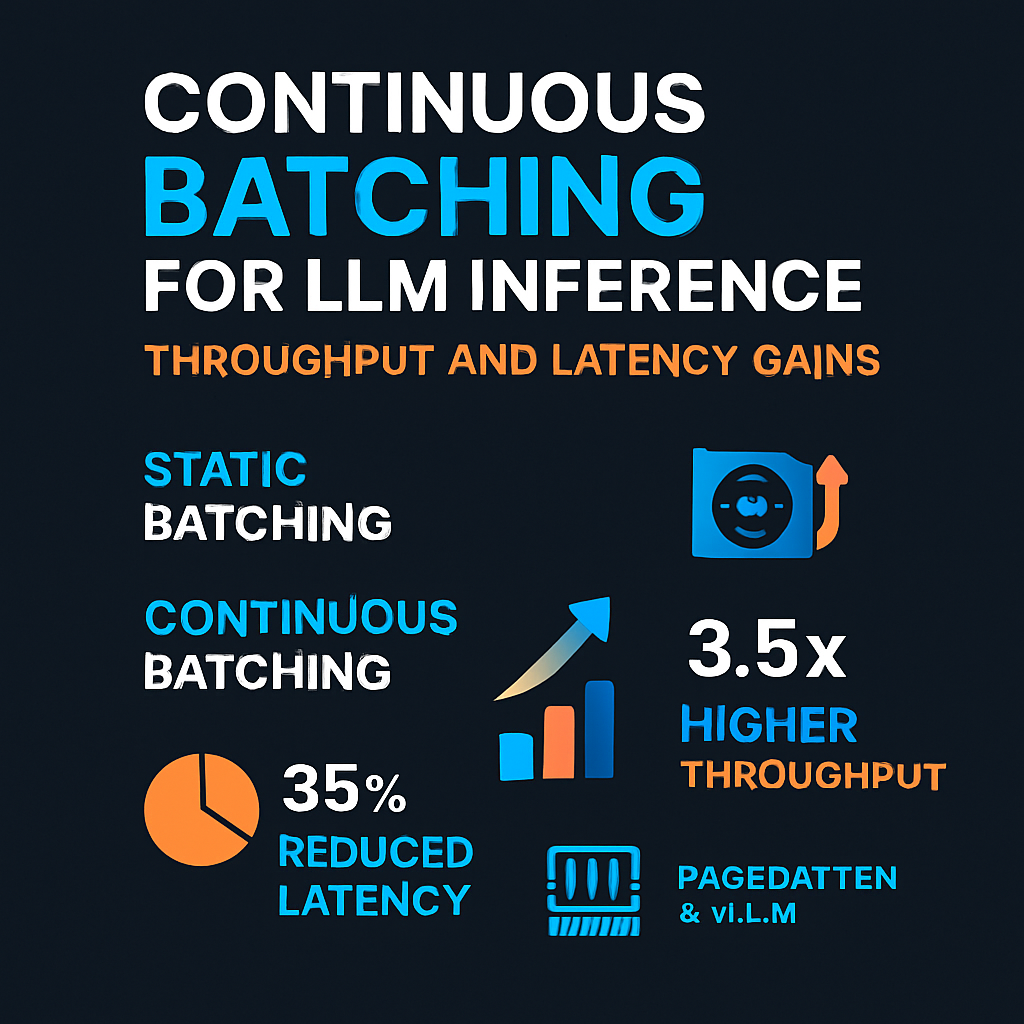
Continuous Batching for LLM Inference: Throughput and Latency Gains ...
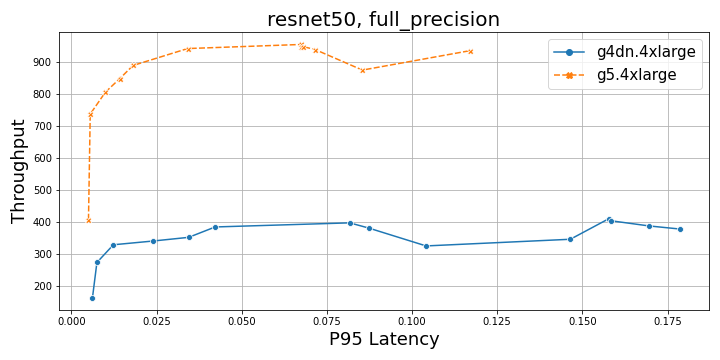
Achieve four times higher ML inference throughput at three times lower ...
Advertisement Space (336x280)

Achieve four times higher ML inference throughput at three times lower ...
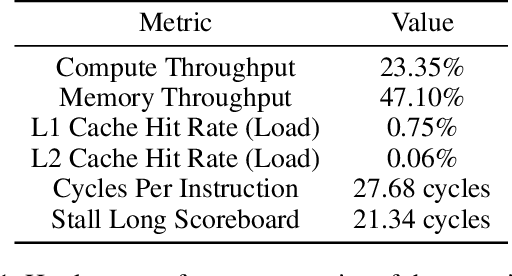
Table 1 from Accelerating LLM Inference Throughput via Asynchronous KV ...
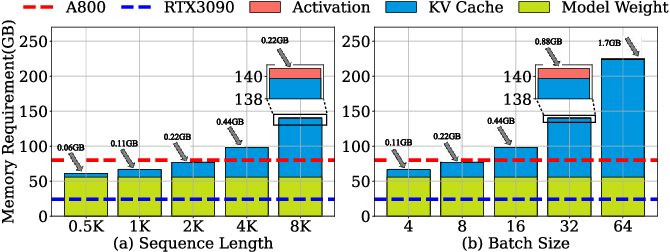
Figure 1 from TightLLM: Maximizing Throughput for LLM Inference via ...
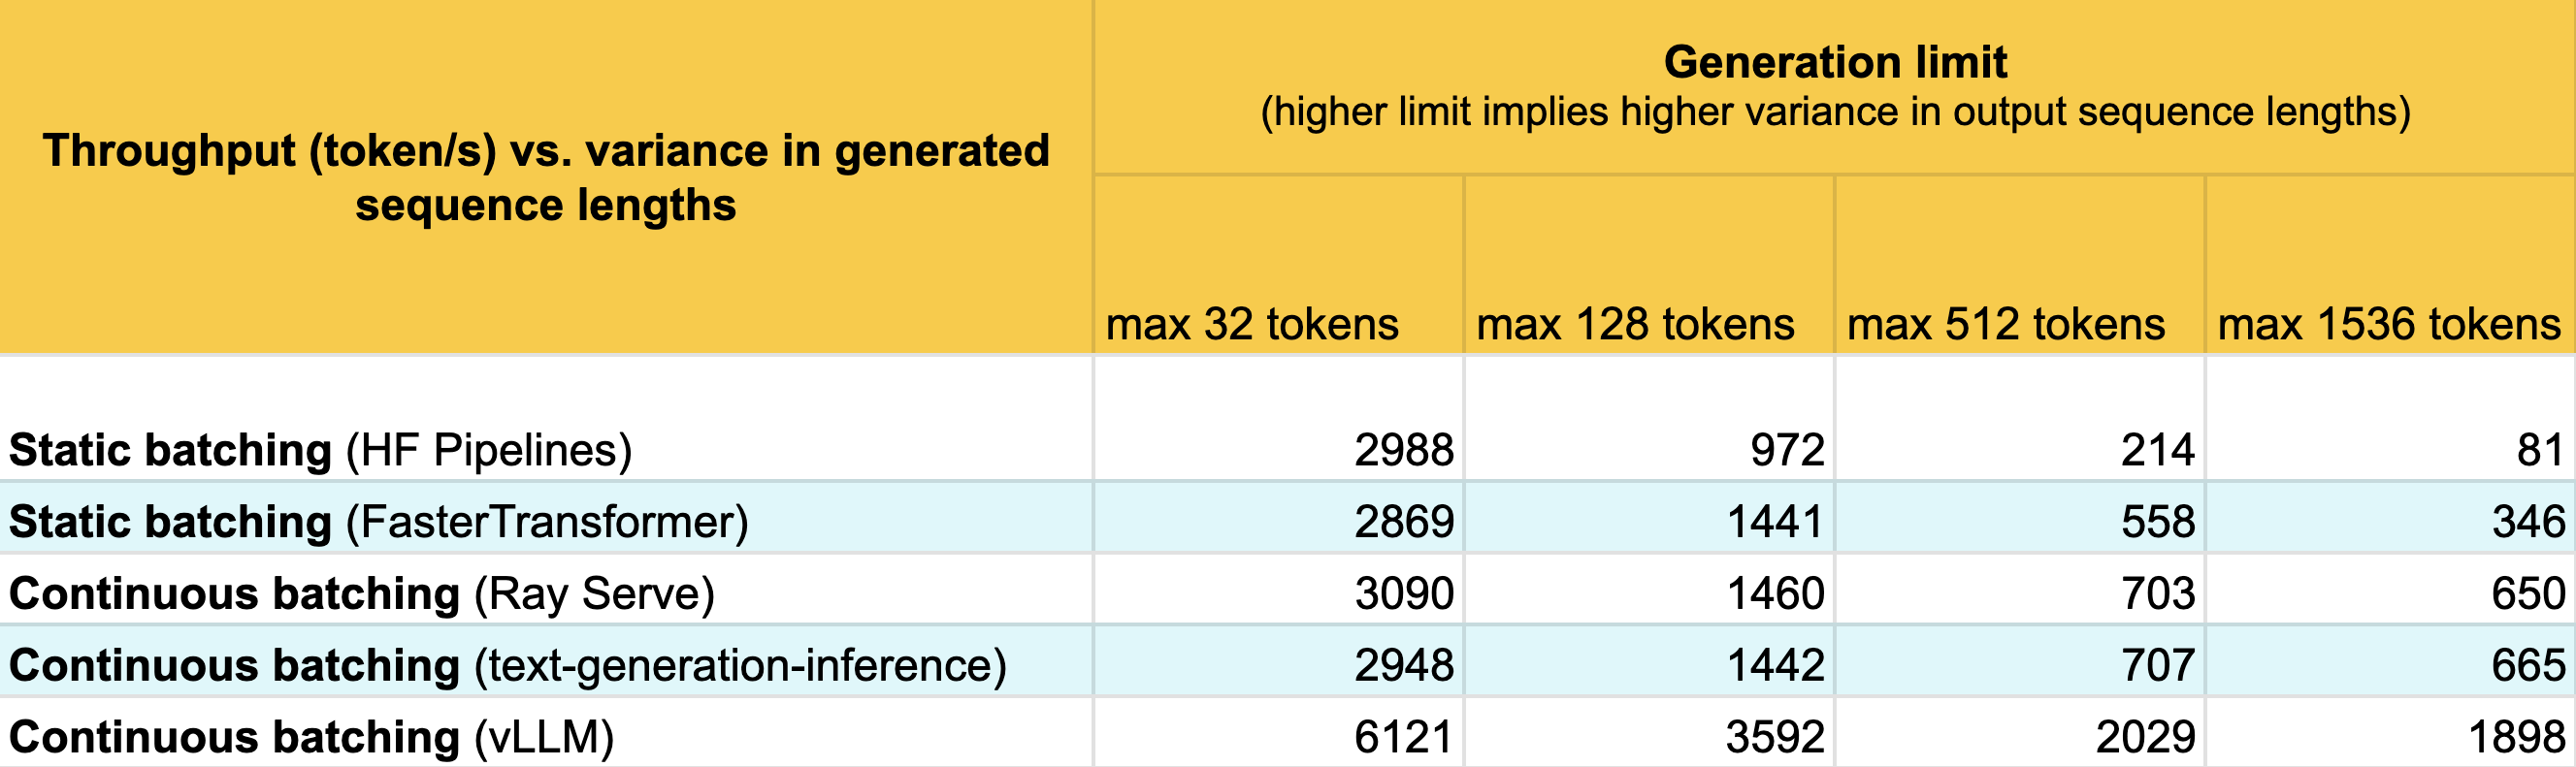
What Is P50 Latency at Lois Lumpkin blog
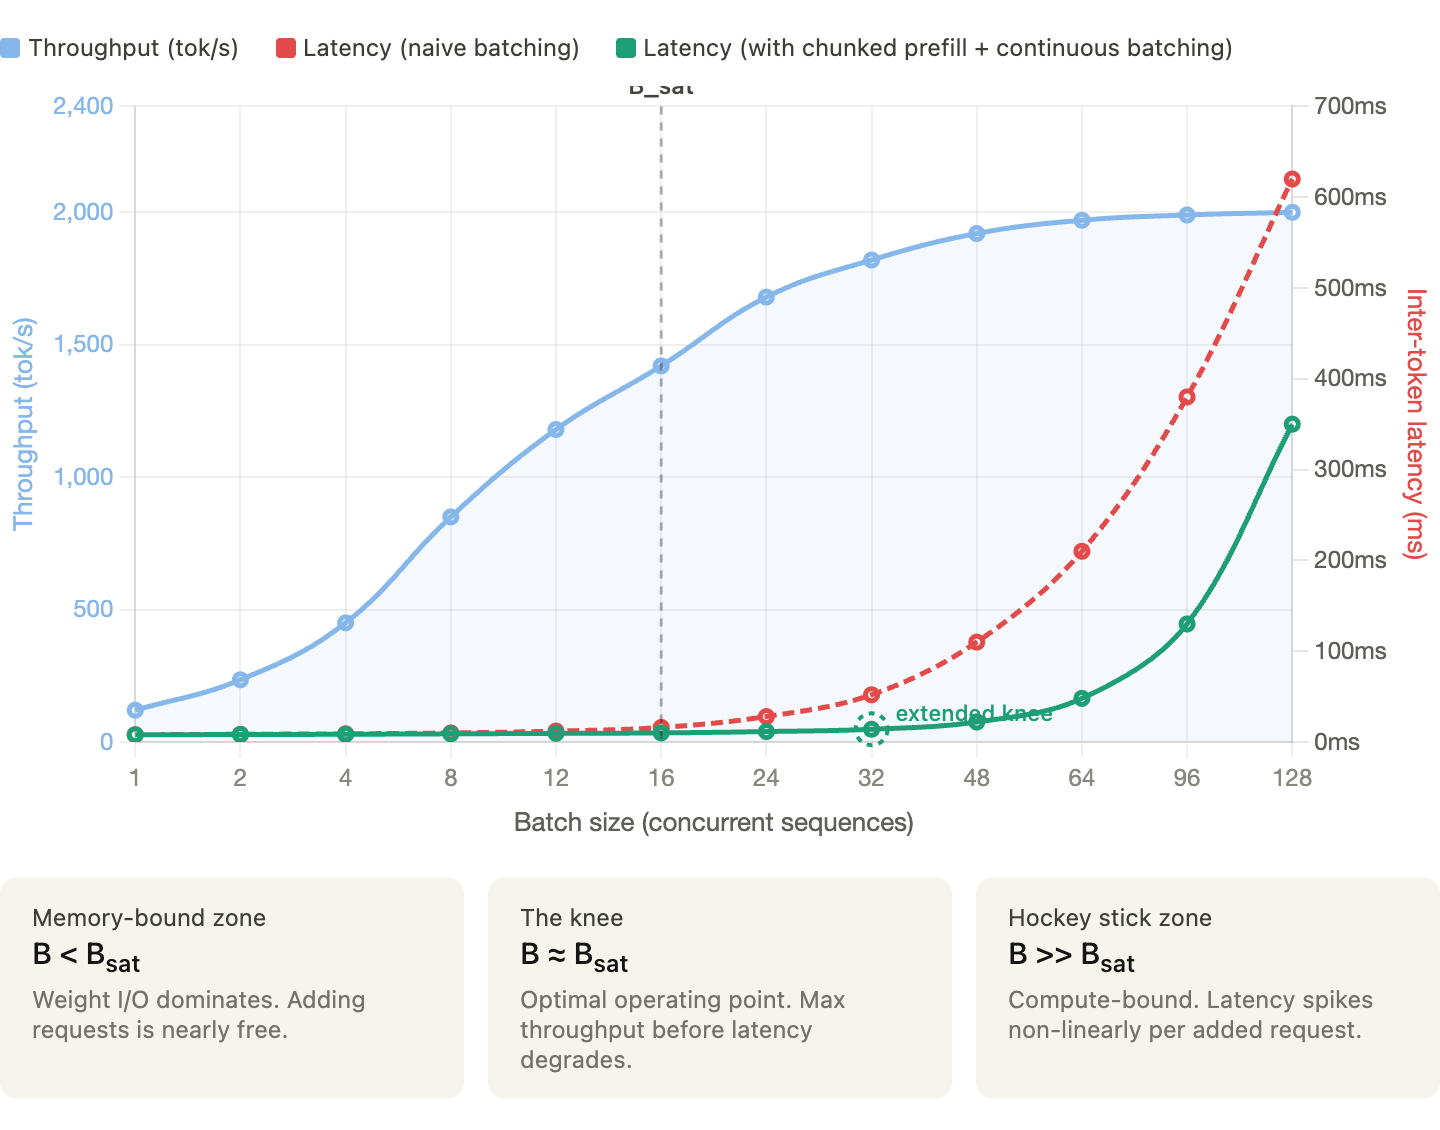
The LLM Inference Trilemma: Throughput, Latency, Cost | DigitalOcean
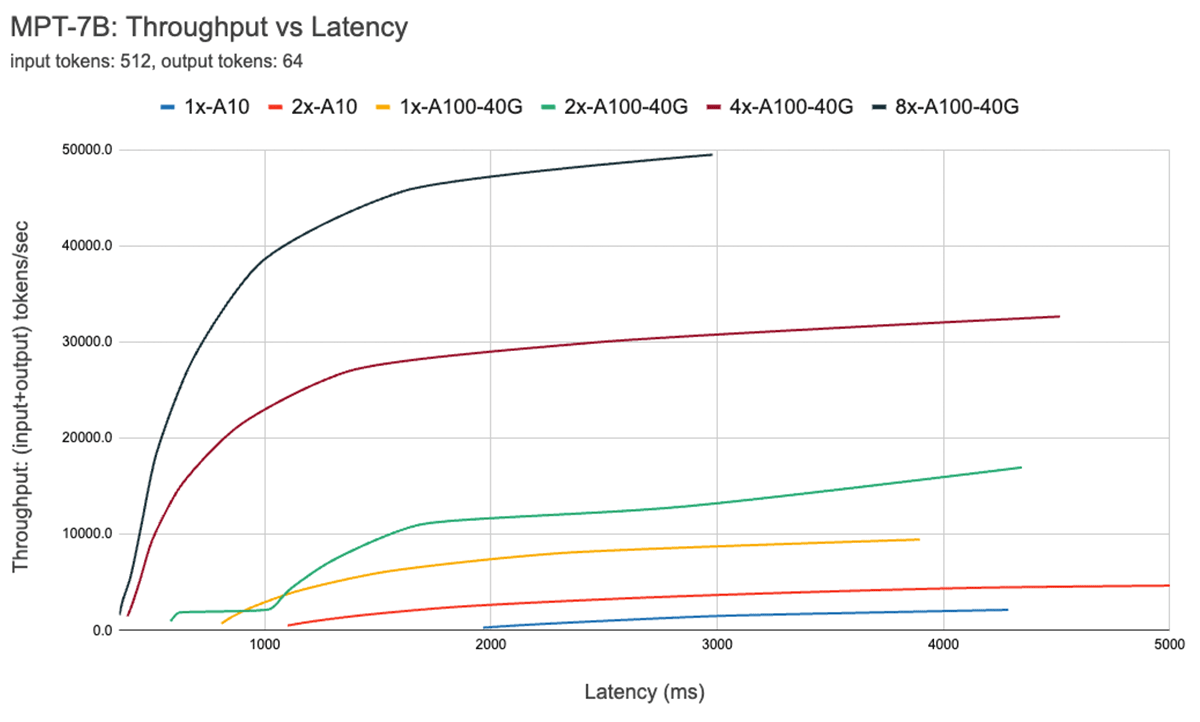
LLM Inference Performance Engineering: Best Practices | Databricks Blog