
Adrian White On Linkedin Achieve 23x Llm Inference Throughput Reduce

Adrian White on LinkedIn: Achieve 23x LLM Inference Throughput & Reduce ...
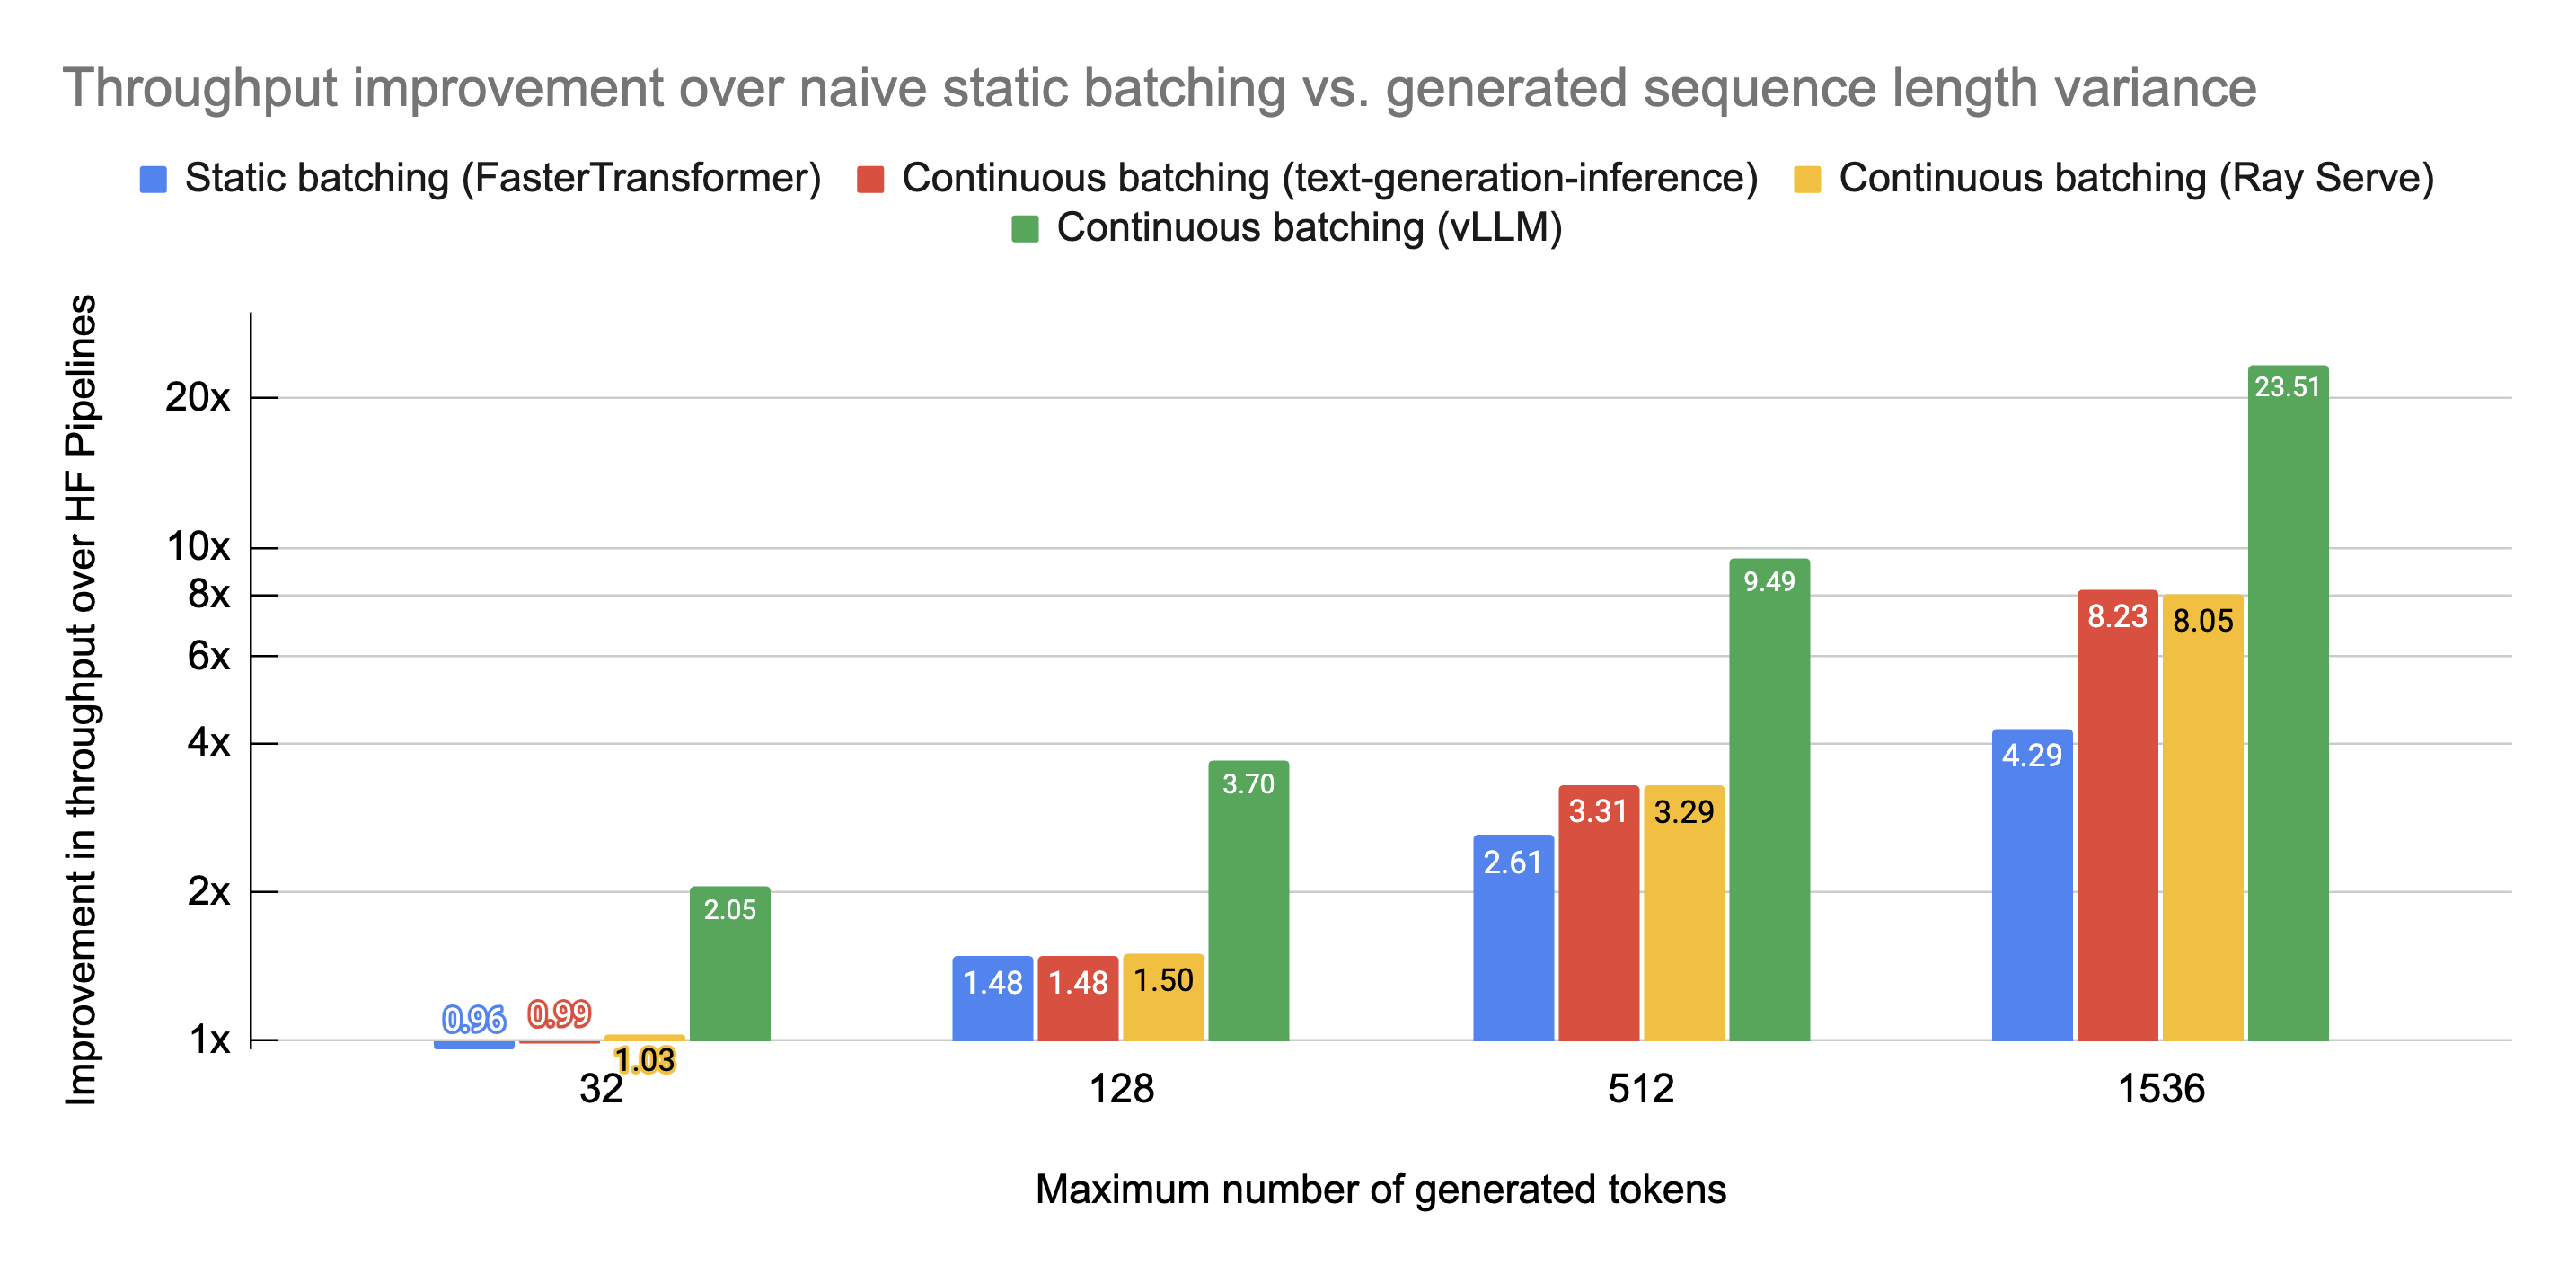
Achieve 23x LLM Inference Throughput & Reduce p50 Latency
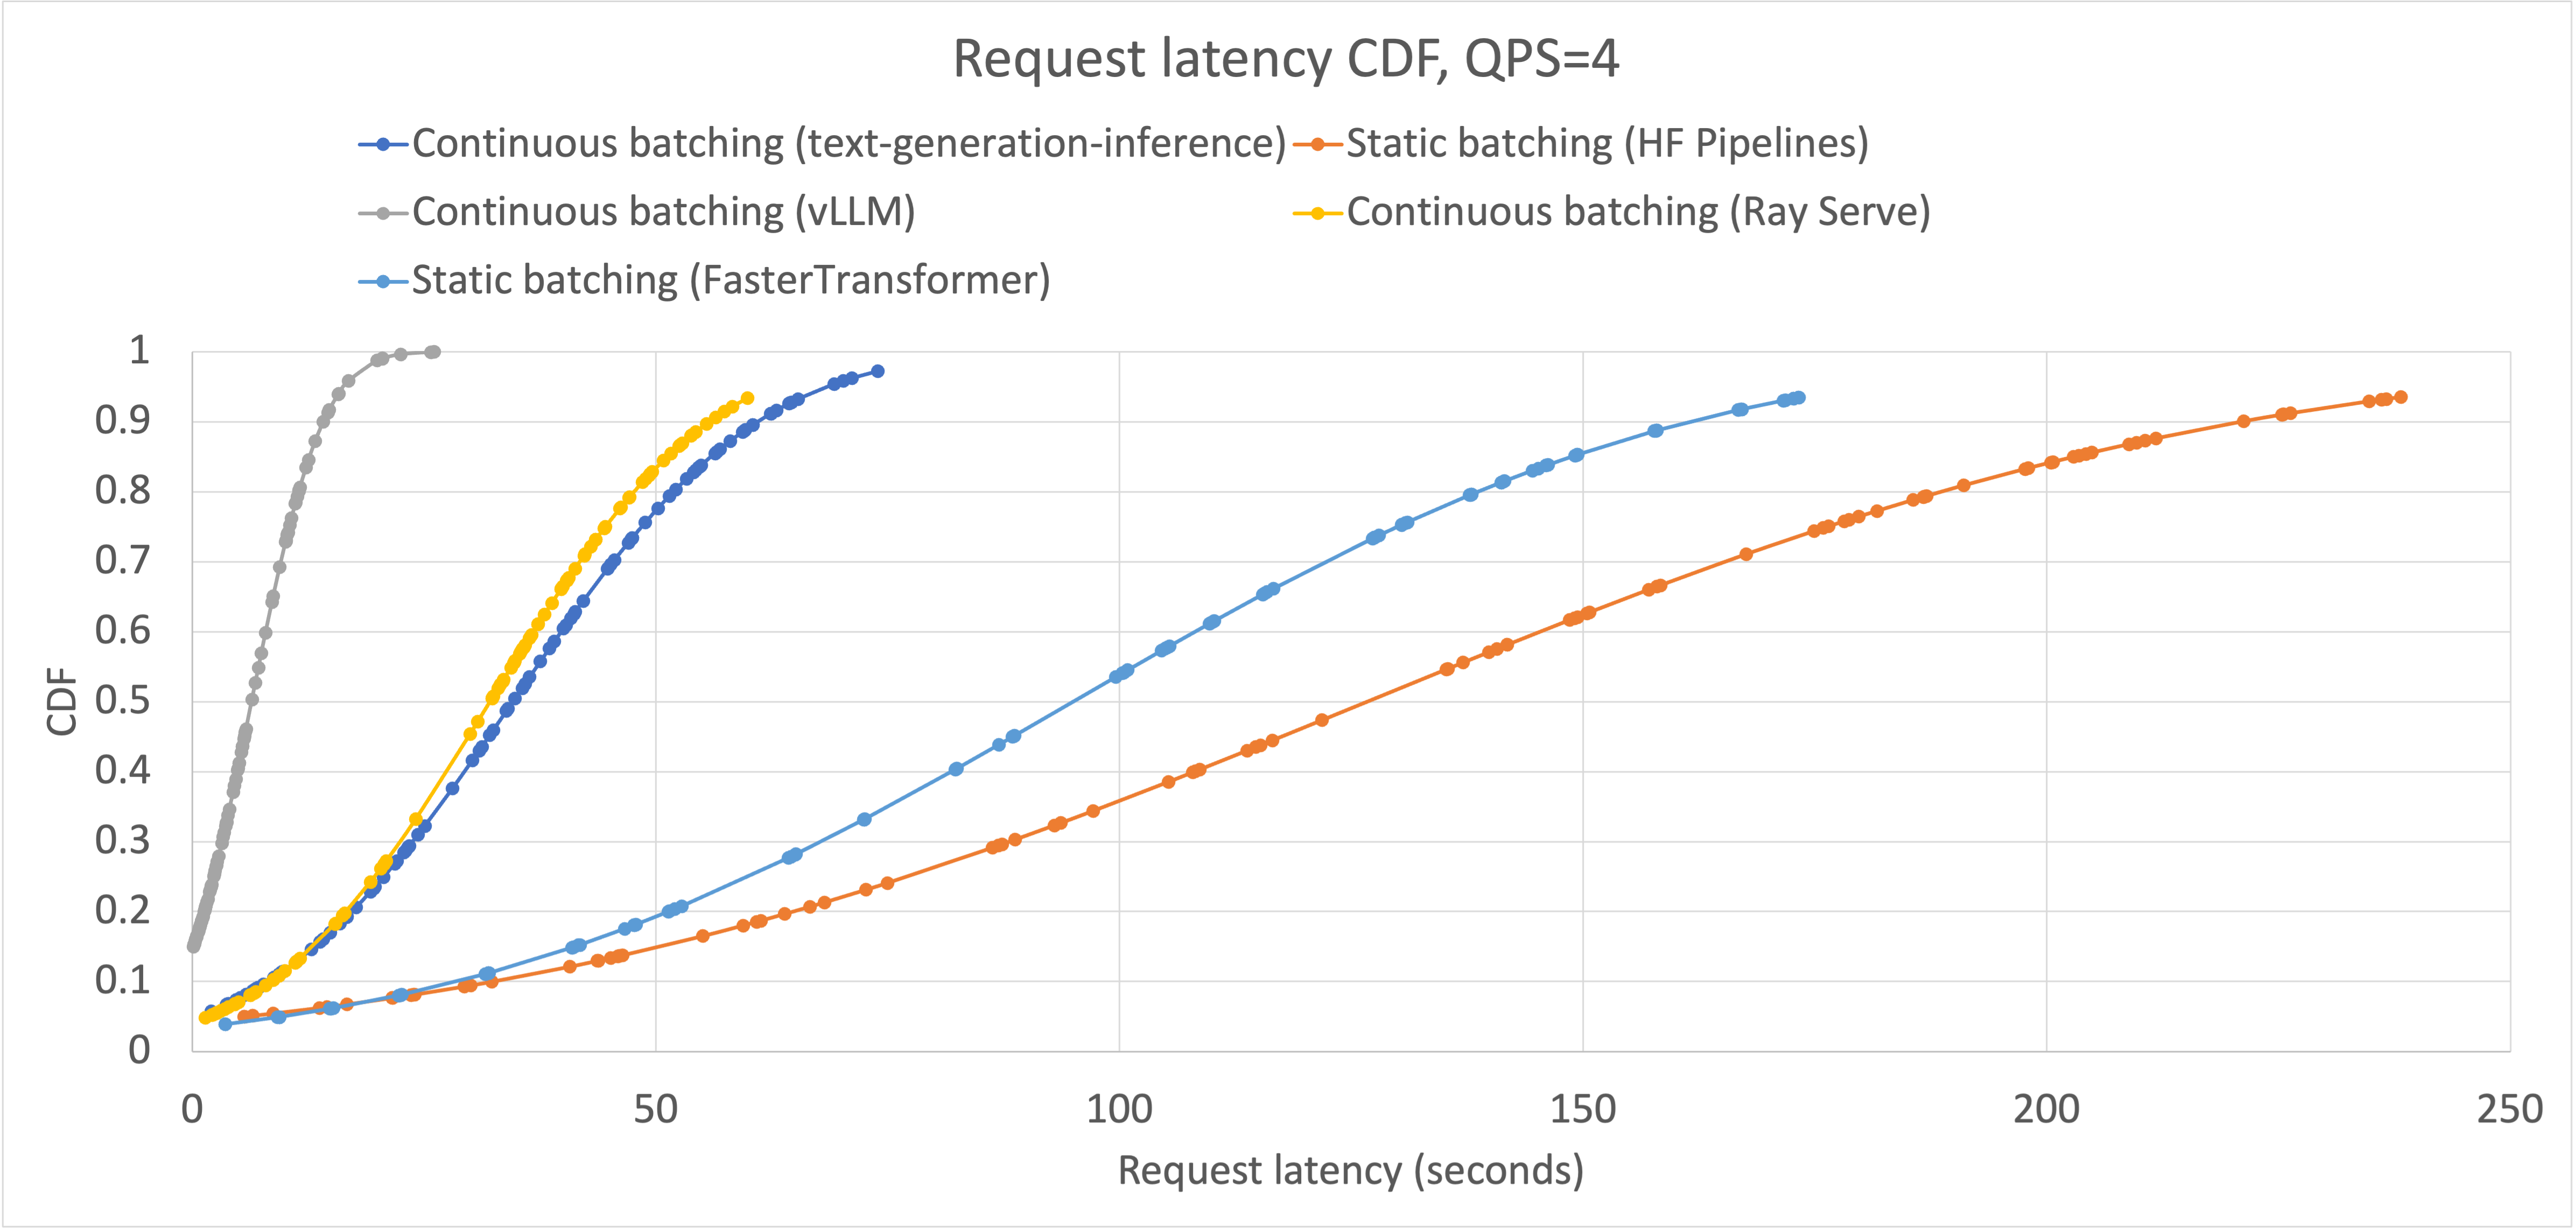
Achieve 23x LLM Inference Throughput & Reduce p50 Latency
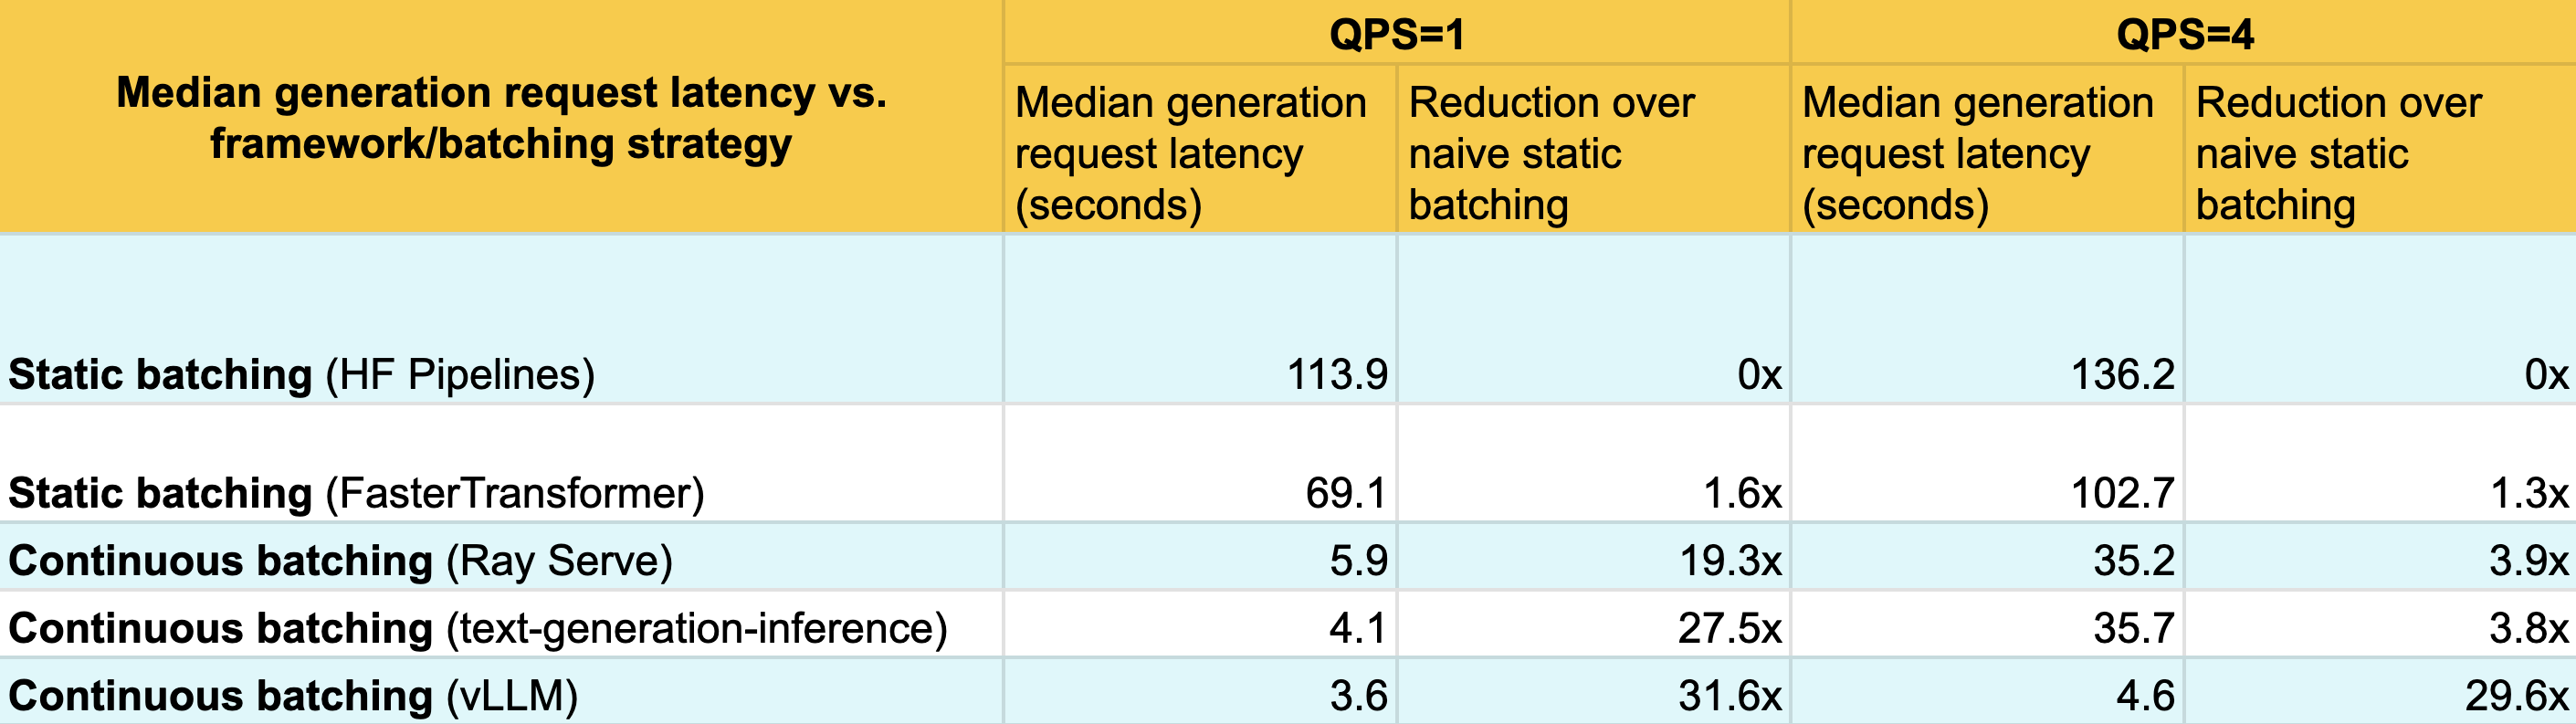
Achieve 23x LLM Inference Throughput & Reduce p50 Latency
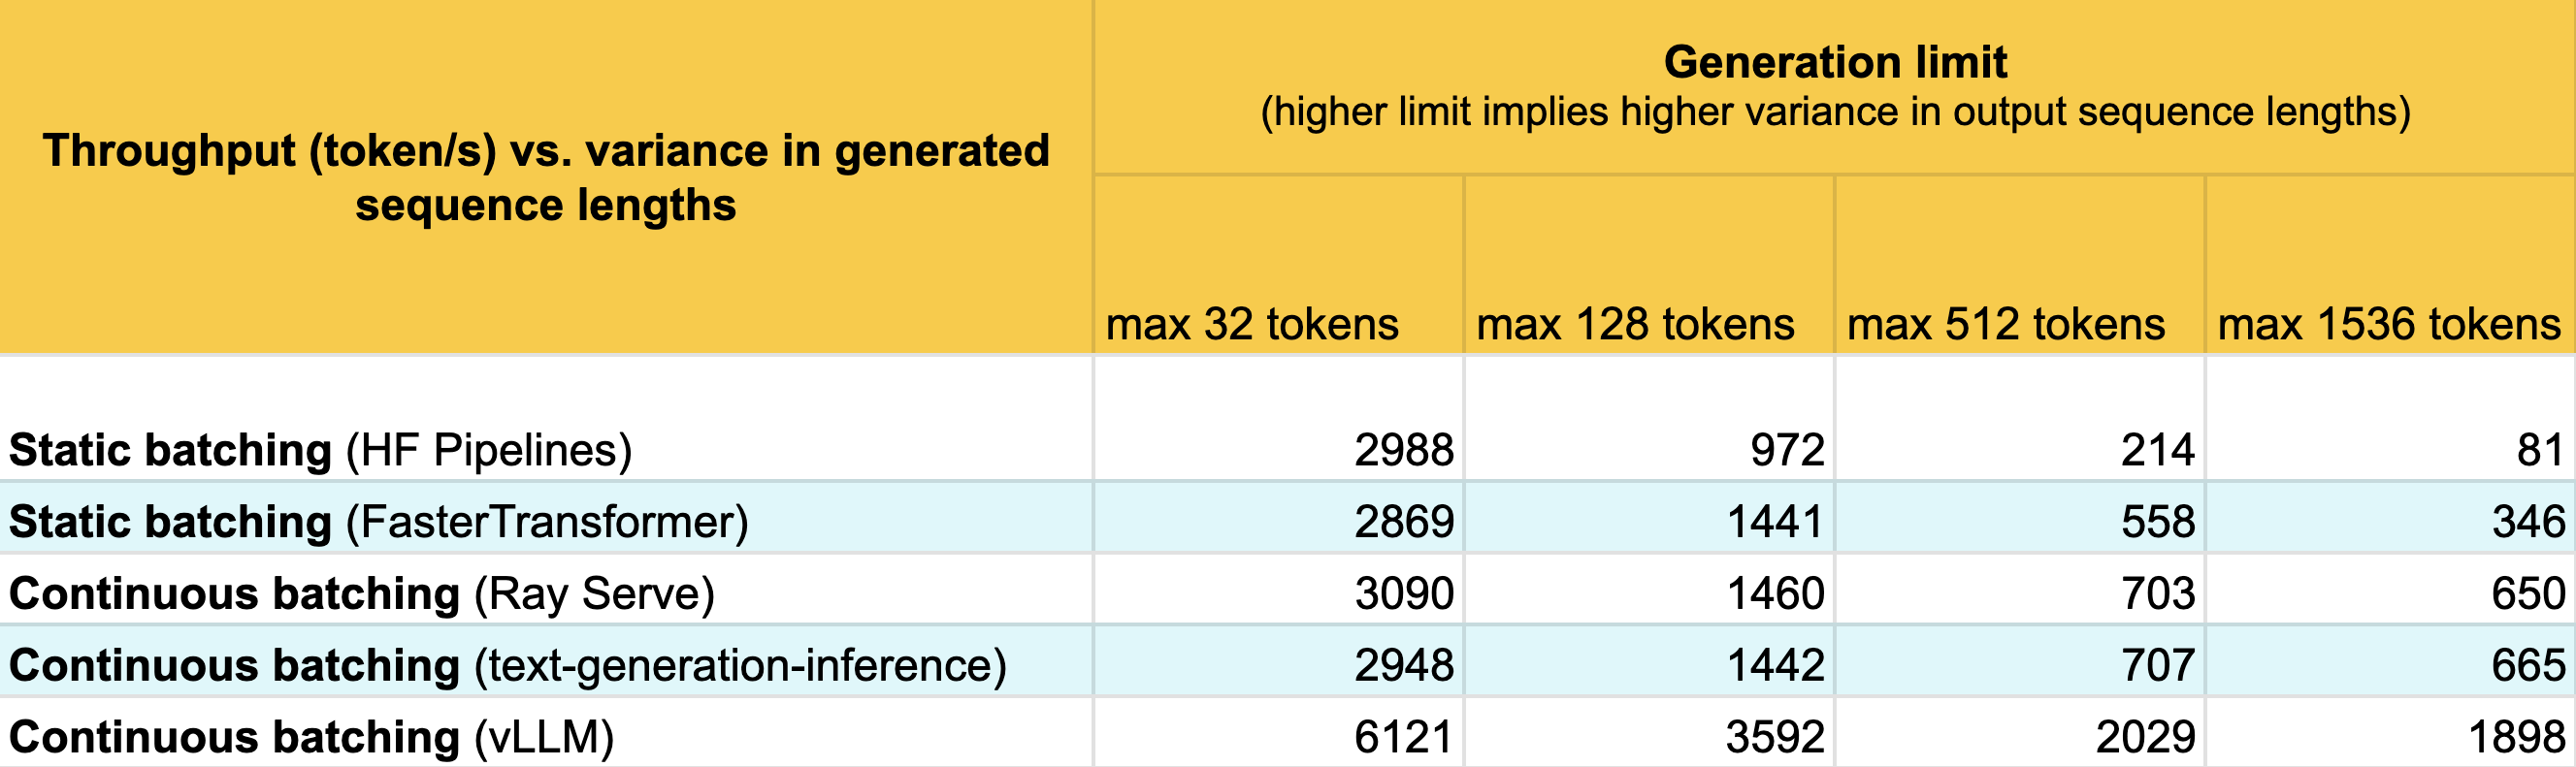
Achieve 23x LLM Inference Throughput & Reduce p50 Latency
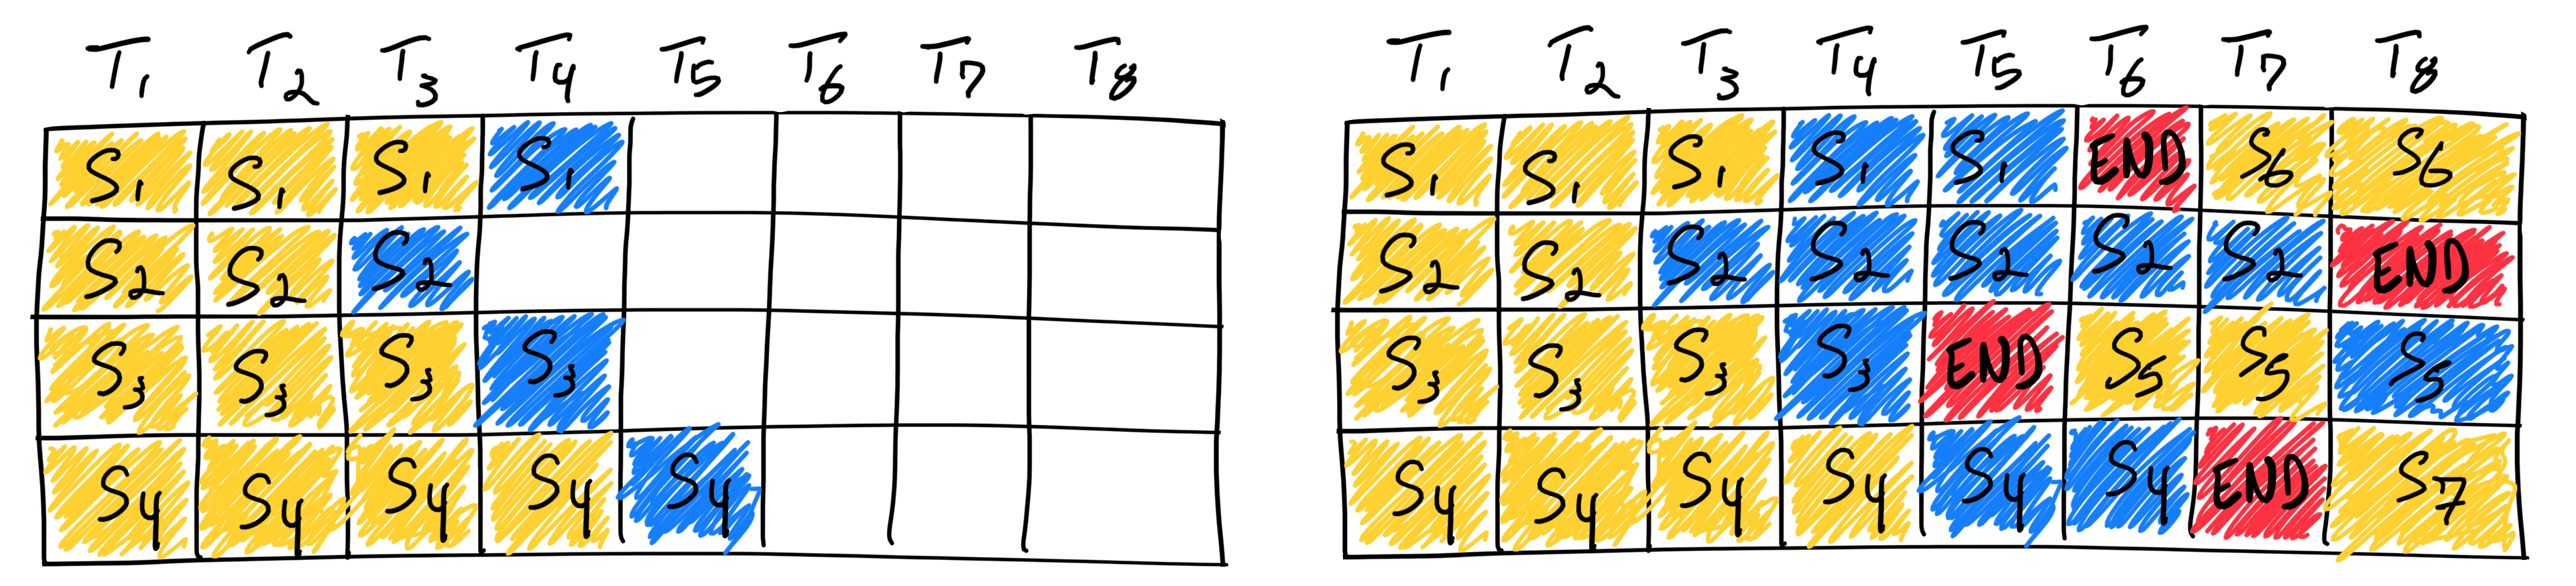
Achieve 23x LLM Inference Throughput & Reduce p50 Latency
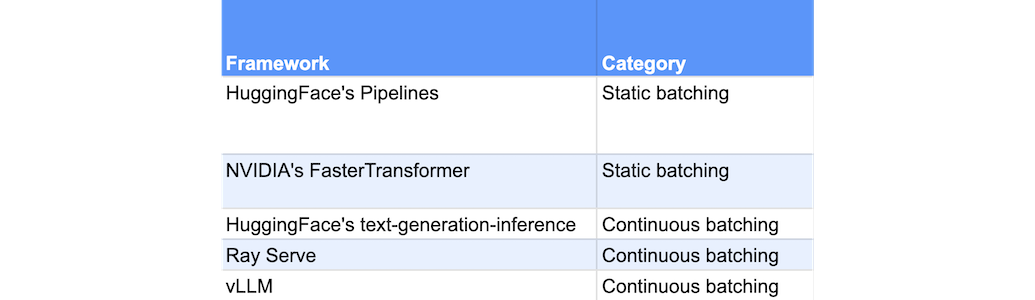
Achieve 23x LLM Inference Throughput & Reduce p50 Latency
Achieve 23x LLM Inference Throughput & Reduce p50 Latency
Achieve 23x LLM Inference Throughput & Reduce p50 Latency

How continuous batching enables 23x throughput in LLM inference ...
Advertisement Space (300x250)

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...
Advertisement Space (336x280)

How AdaInfer can reduce LLM inference time | Avinash P. posted on the ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...
Continuous batching to increase LLM inference throughput and reduce p50 ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

How continuous batching enables 23x throughput in LLM inference ...

LLM Inference Performance: Latency and Throughput Metrics - YouTube

Adrian White on LinkedIn: Really looking forward to joining a panel at ...
Advertisement Space (336x280)

Run LLM inference at maximum throughput | Modal Docs

Scaling Up Throughput-oriented LLM Inference Applications on ...
Optimizing LLM inference for higher throughput

Adrian White - -- | LinkedIn
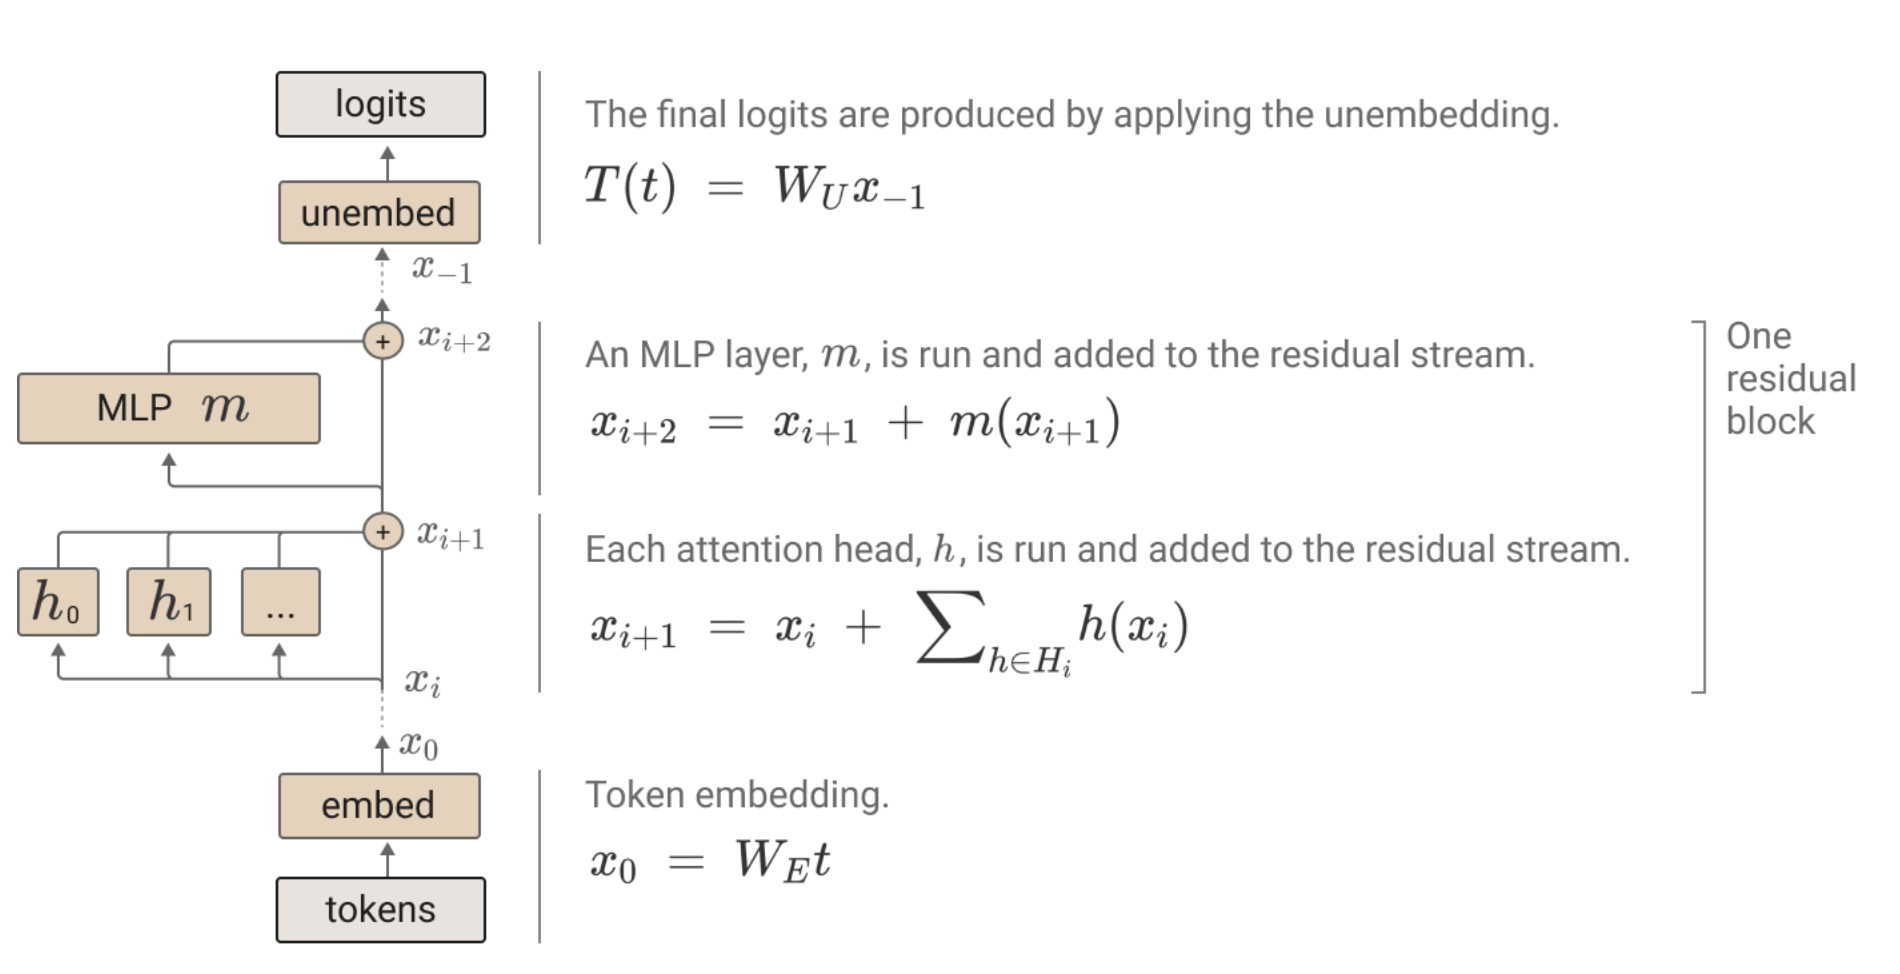
Optimise LLM Inference Throughput from First Principles

Optimizing LLM Inference on Edge Devices | Mirai Labs posted on the ...