
Beyond The Model How Vllm Powers Enterprise Scale Llm Serving By

Beyond the Model: How vLLM Powers Enterprise-Scale LLM Serving | by ...
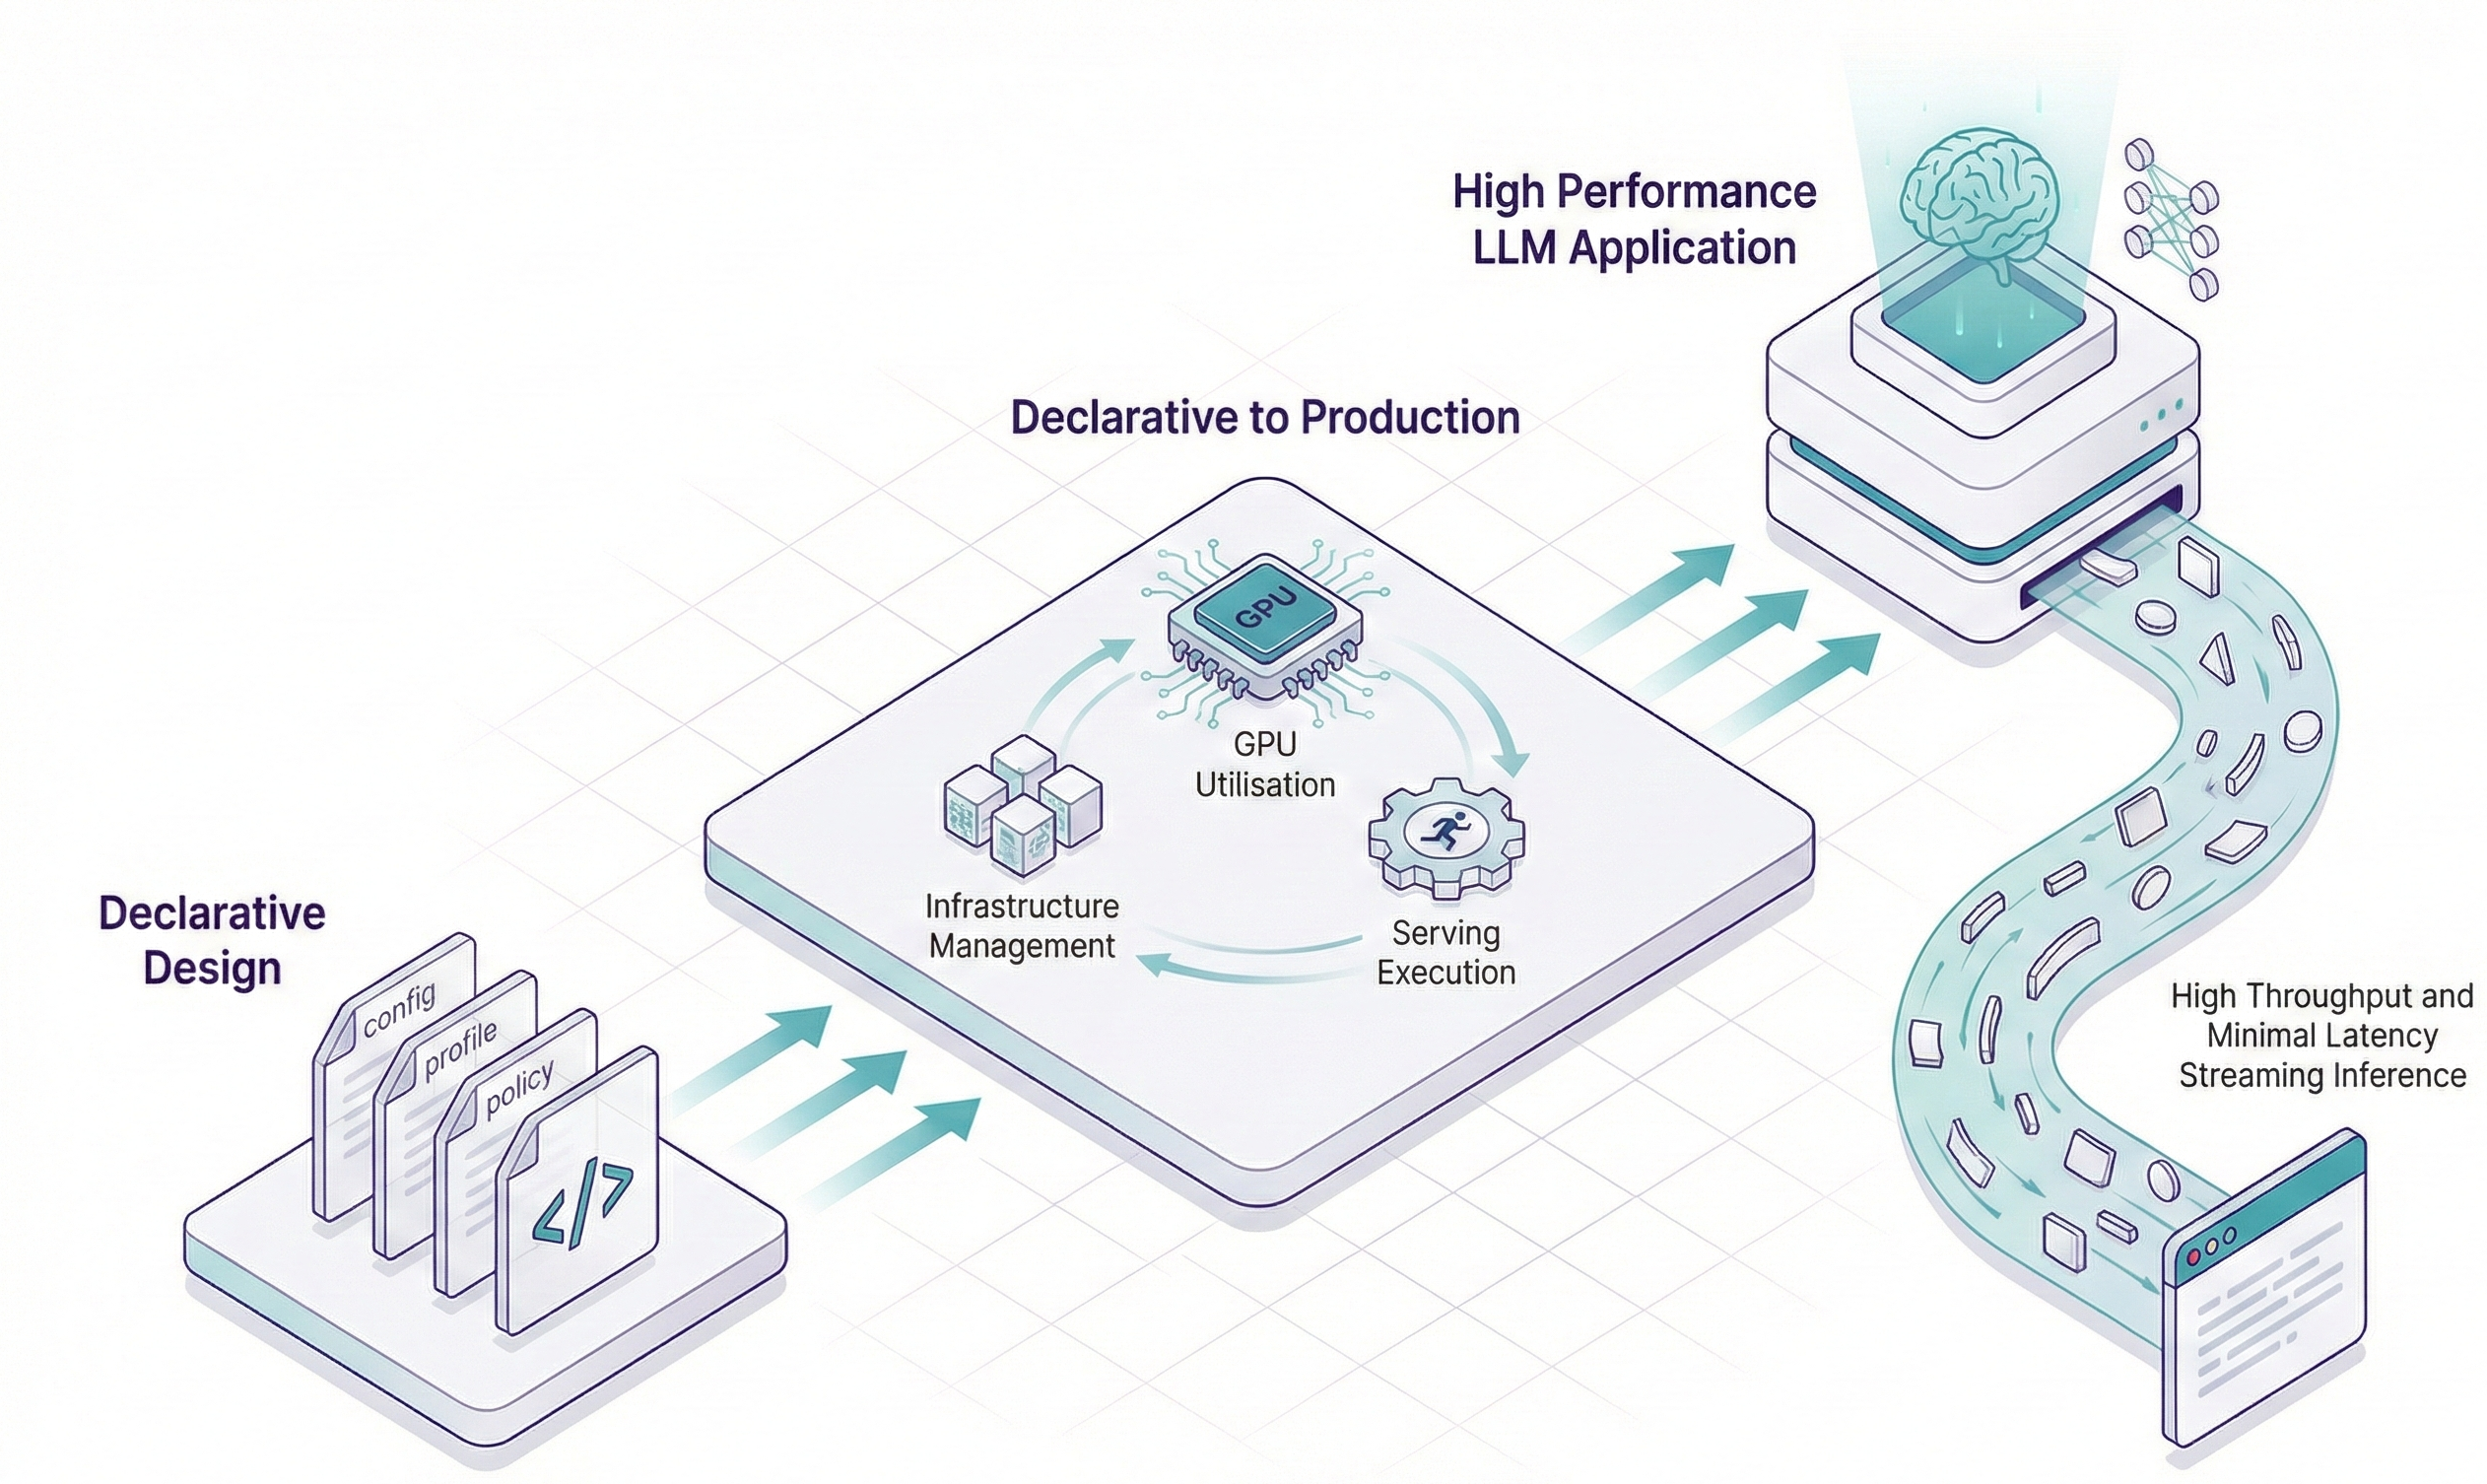
Model Serving - The Enterprise LLM Operating Layer

Serving LLMs at Scale: HuggingFace, Triton, vLLM in the Enterprise | by ...
Serving LLMs at Scale: HuggingFace, Triton, vLLM in the Enterprise | by ...

How vLLM solves LLM serving issues for AI apps | Aaroh Bhardwaj posted ...

How Do You Actually Scale High-Throughput LLM Serving in Production ...

Free Video: Scalable and Efficient LLM Serving With the VLLM Production ...

Comparing two LLM serving frameworks: Friendli Engine vs. vLLM | by ...

Unlocking Enterprise AI with Gaudi 3: Model Serving and Fine-Tuning at ...
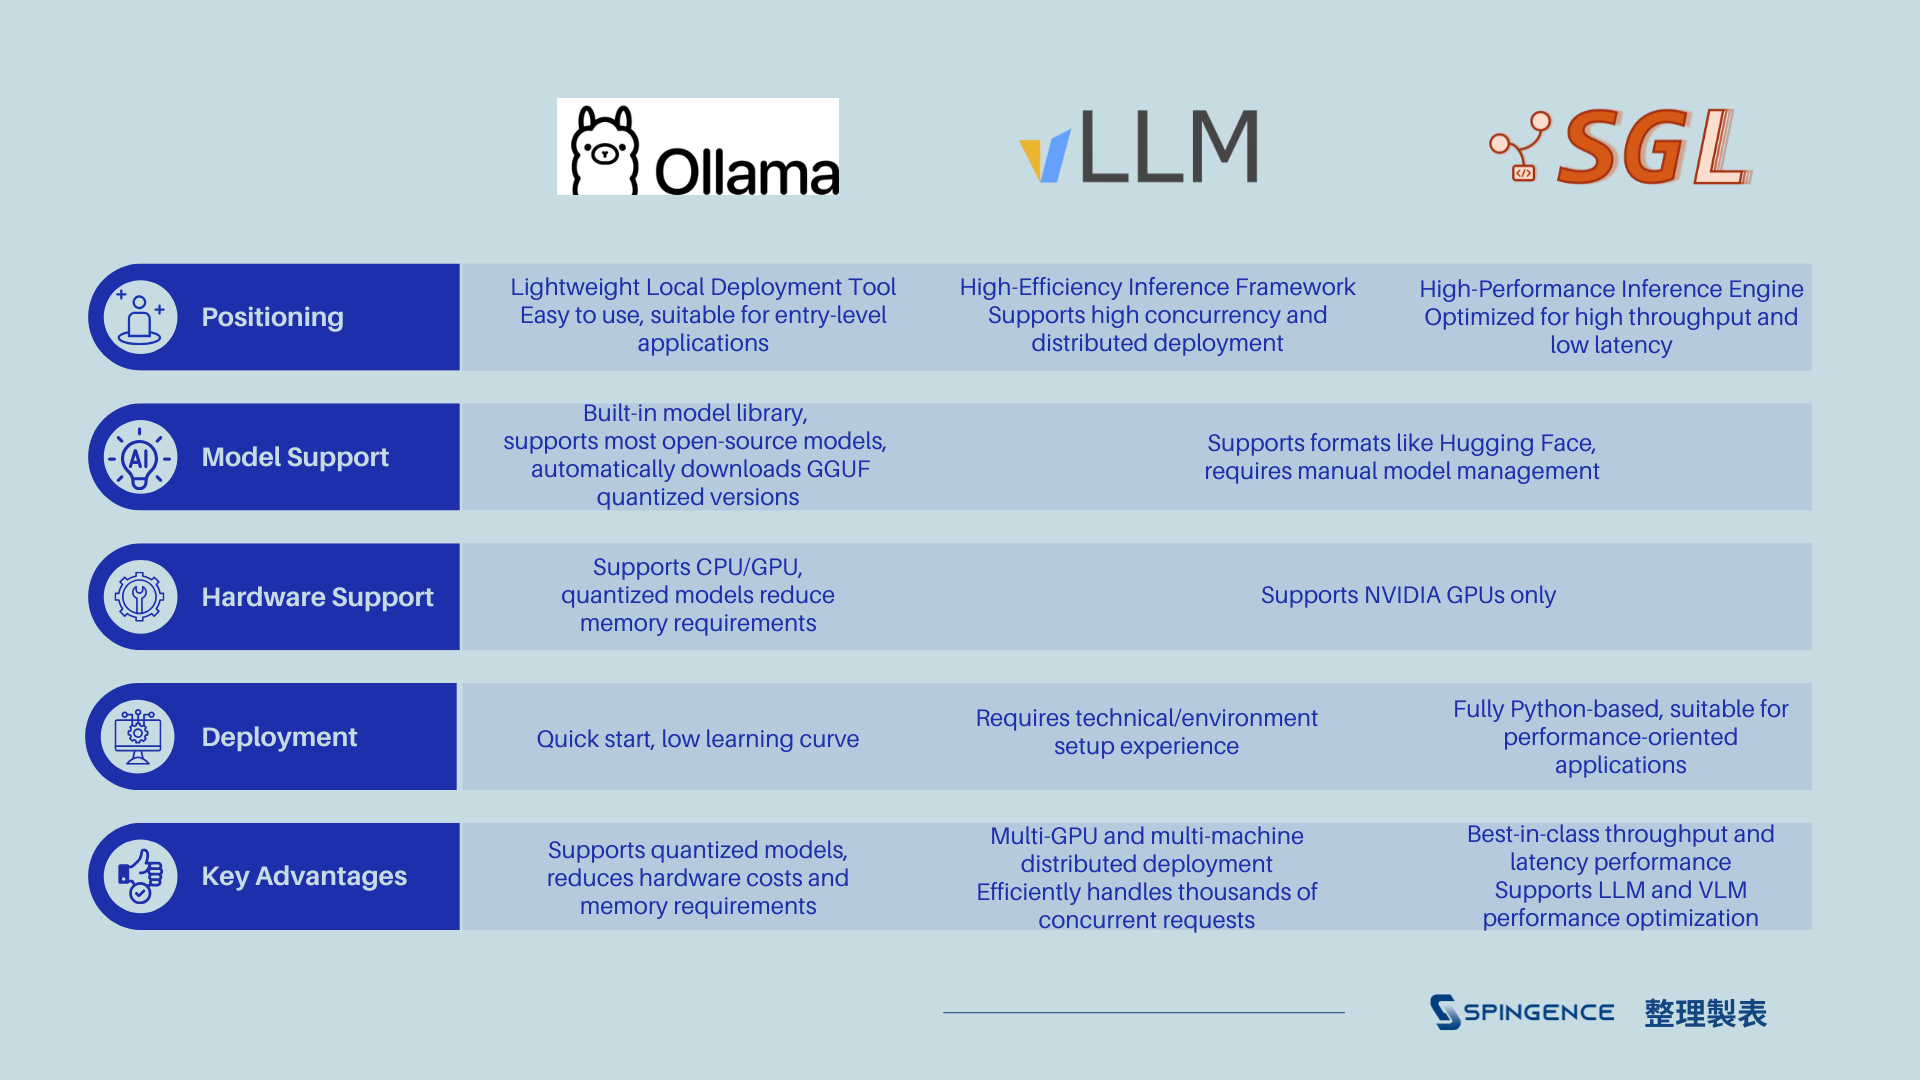
Enhancing Enterprise Inference Efficiency: Choosing the Right LLM ...
Advertisement Space (300x250)
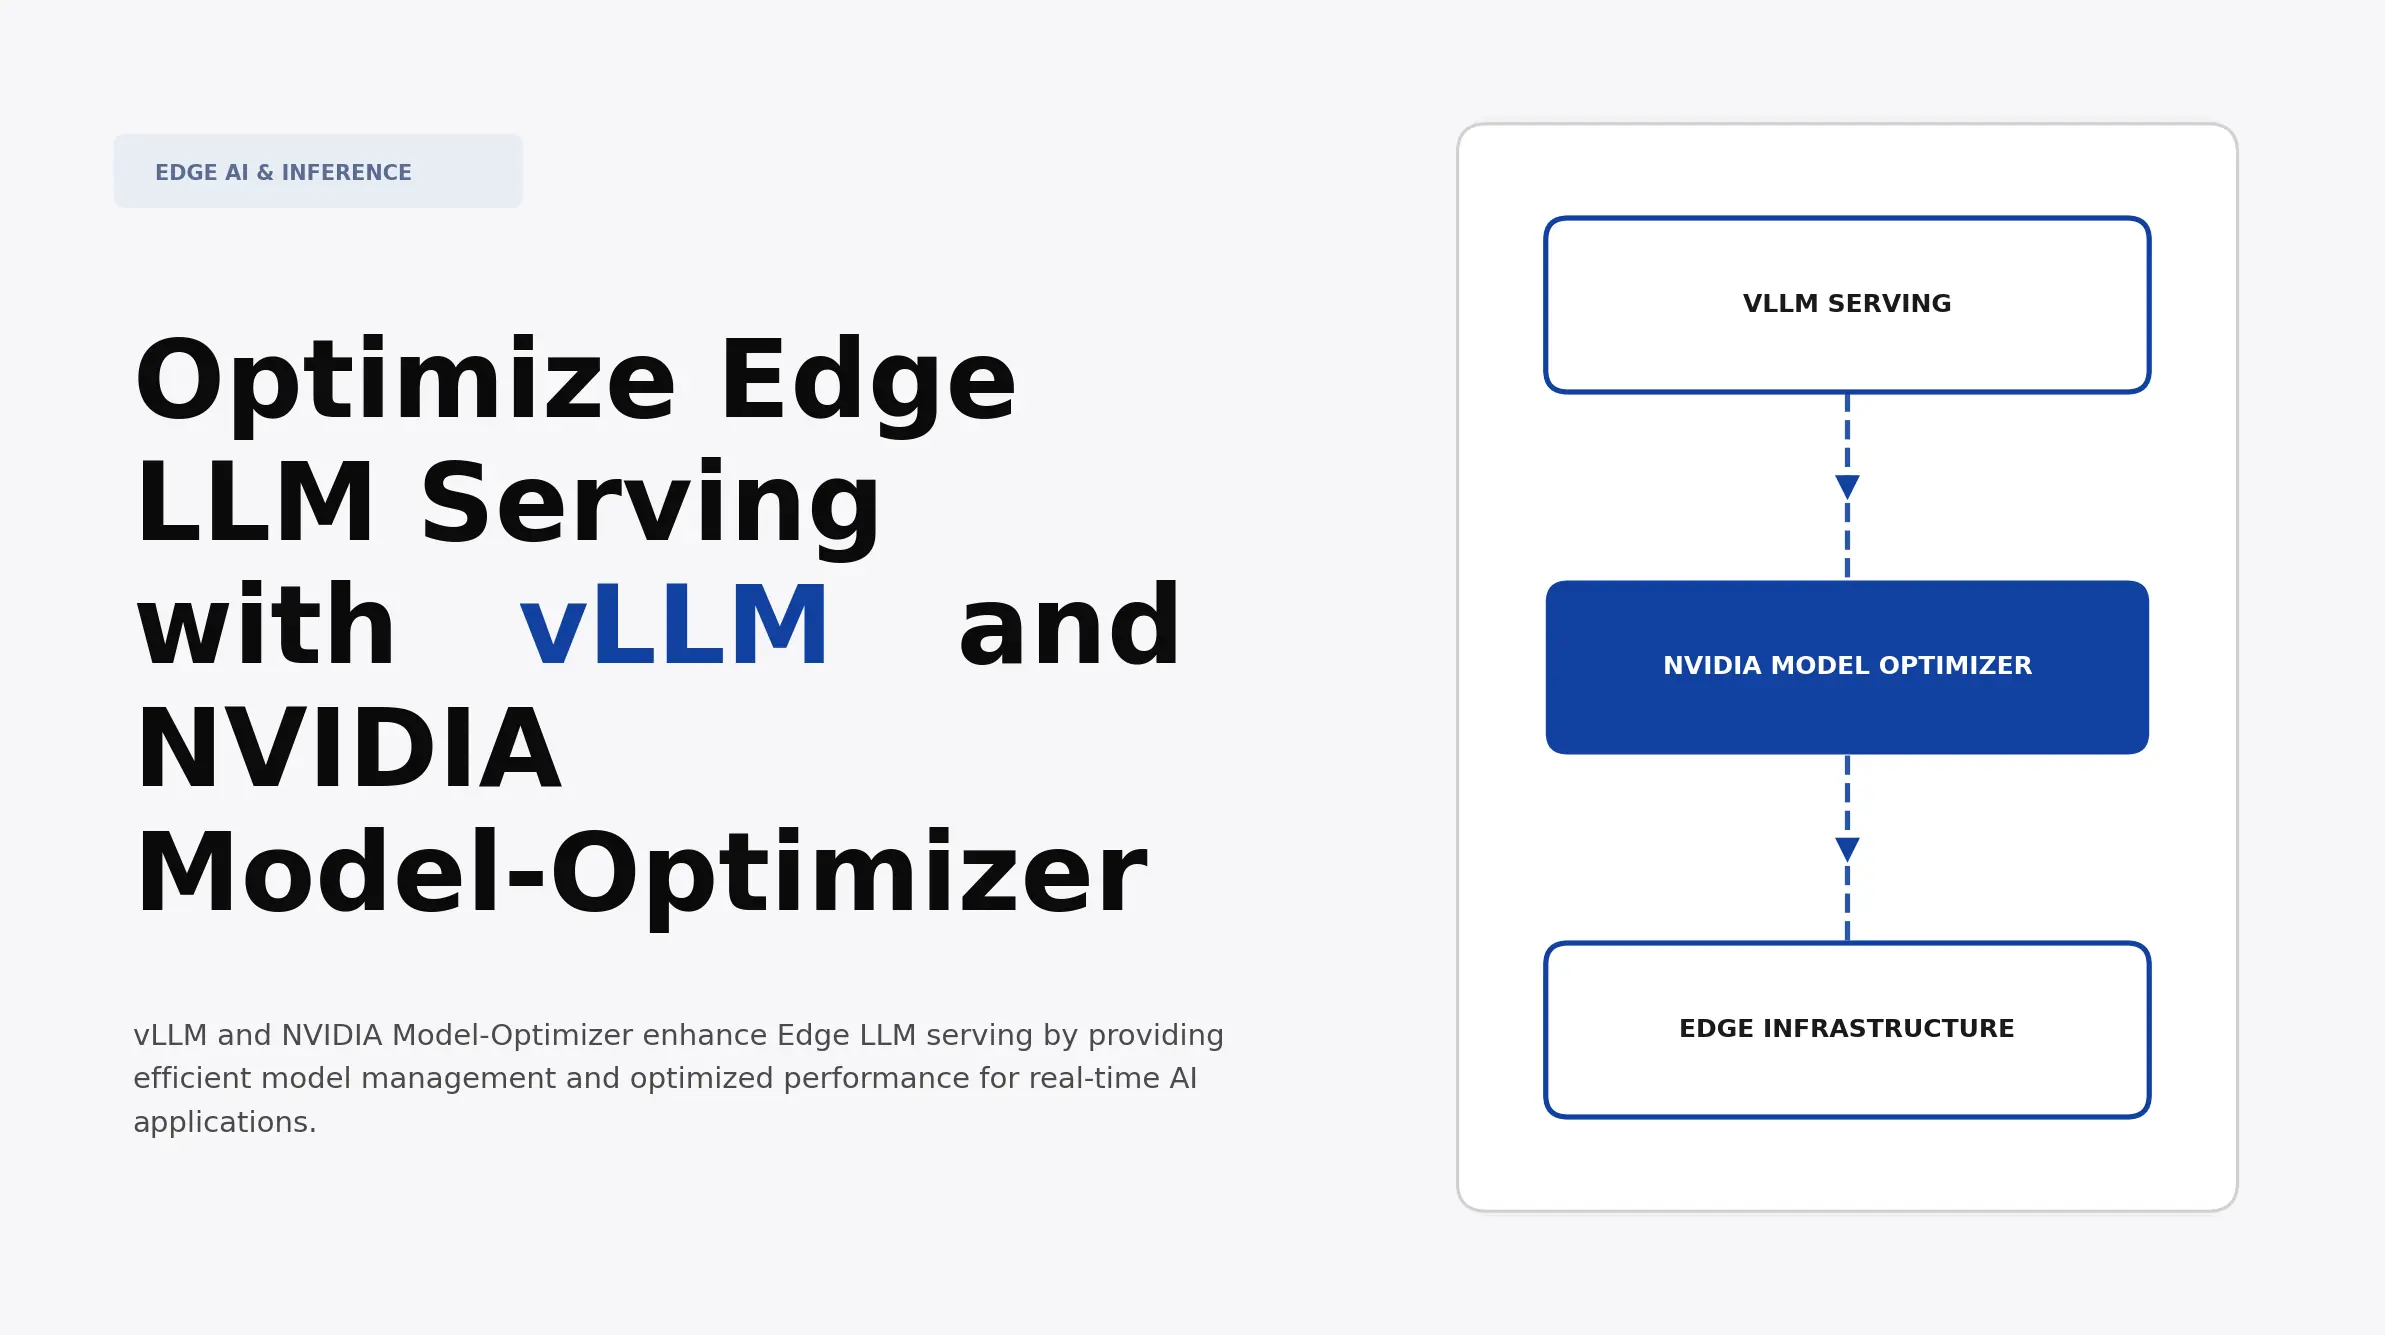
Optimize Edge LLM Serving with vLLM and NVIDIA Model-Optimizer | Atomic ...
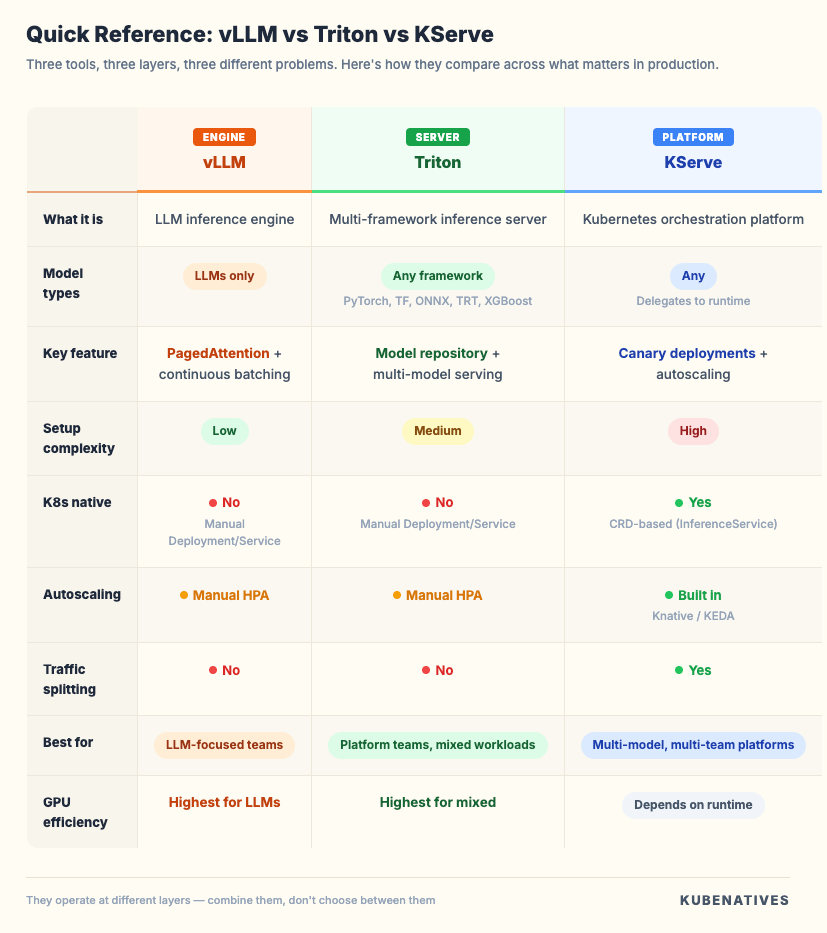
vLLM vs Triton vs KServe: Model Serving on Kubernetes
Hexon Global Guide: Streamlining LLM Model Deployment with vLLM - Hexon ...
vLLM Guide 2026 | High-Throughput LLM Serving
Efficient LLM Inference and Serving with vLLM

Install vLLM on Linux for Production LLM Serving (2026 Guide)
Ray Serve LLM on Anyscale: Wide-EP and Disaggregated Serving with vLLM
Scale Open LLMs with vLLM Production Stack | by Shahrukh khan | Medium
vLLM Essentials Revolutionizing LLM Deployment and Performance | by ...

vLLM: A milestone in LLM serving technology | E.G. Nadhan posted on the ...
Advertisement Space (336x280)

Comparing two LLM serving frameworks: Friendli Inference vs. vLLM

Comparing the Top 6 Inference Runtimes for LLM Serving in 2025 ...

vLLM vs SGLang: Enterprise LLM Inference Comparison - DEV Community
The Rise of Multimodal LLMs and Efficient Serving with vLLM - PyImageSearch

Serving AI models at scale with vLLM - YouTube

vLLM vs SGLang: Enterprise LLM Inference Comparison - DEV Community

Enterprise LLM Paving the Way for AI Business Transformation | VNG Cloud

Model Routing | Open‑Source LLM Inferencing at Scale: vLLM Production ...
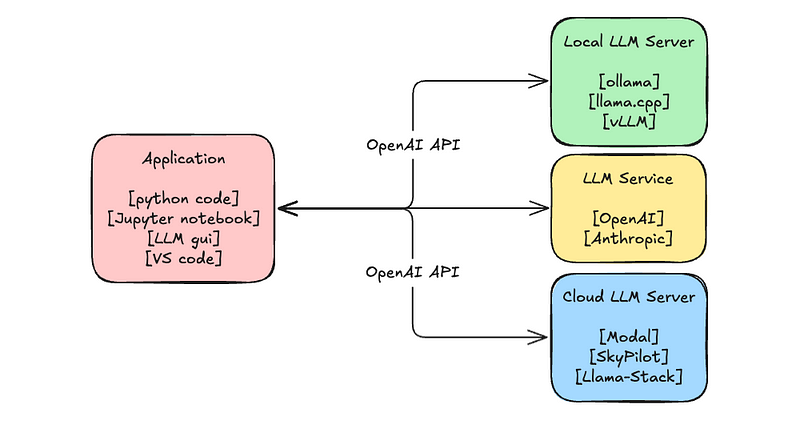
LLM Deployment with vLLM. In the rapidly evolving landscape of… | by ...
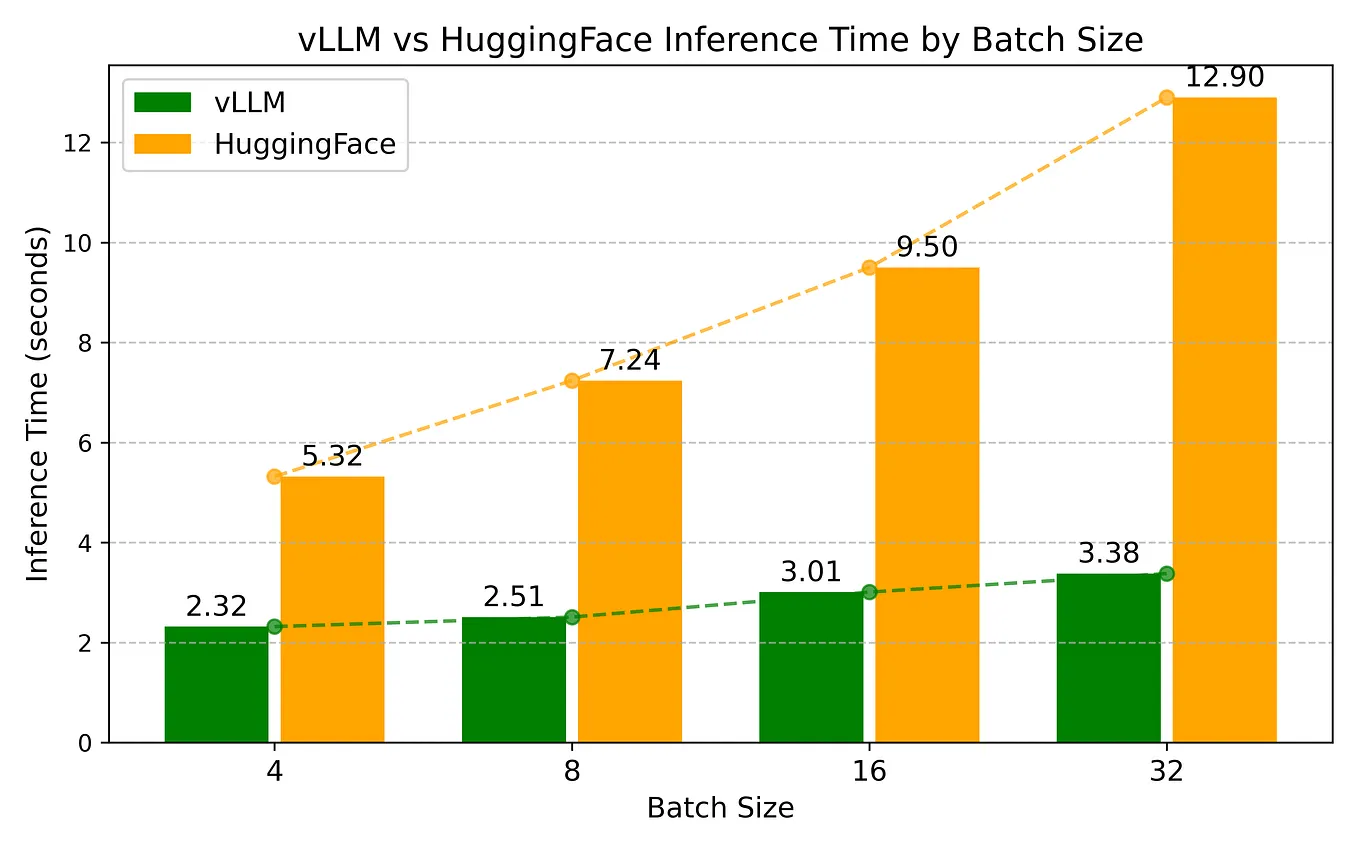
Serving Large Language Models with vLLM on AMD ROCm GPUs | by Trade ...
Advertisement Space (336x280)

SharkTime Software - Lokales Serving des LLM mit vLLM

Beyond the Hype: How Visual Language models ( VLM) and Large language ...

Beyond Model Serving: Inside vLLM’s Architecture for Enterprise-Scale ...

Beyond Model Serving: Inside vLLM’s Architecture for Enterprise-Scale ...

Beyond Model Serving: Inside vLLM’s Architecture for Enterprise-Scale ...