
Boost Llm Inference Optimize Speculative Decoding Batching Kv Cache
Boost LLM Inference: Optimize Speculative Decoding, Batching, KV Cache ...
LLM 推理优化全指南:从 KV Cache 到 Speculative Decoding | AI 实战派 · 从技术到赚钱

LLM Inference Bottleneck: KV Cache vs Model Weights | Vinjam ...
基于全局 KV Cache 存储系统的高效 LLM 推理加速方案 Efficient LLM Inference Acceleration ...

LLM inference optimization: Architecture, KV cache and Flash attention ...

Optimizing LLM Inference: KV Cache Quantization and Speculative ...
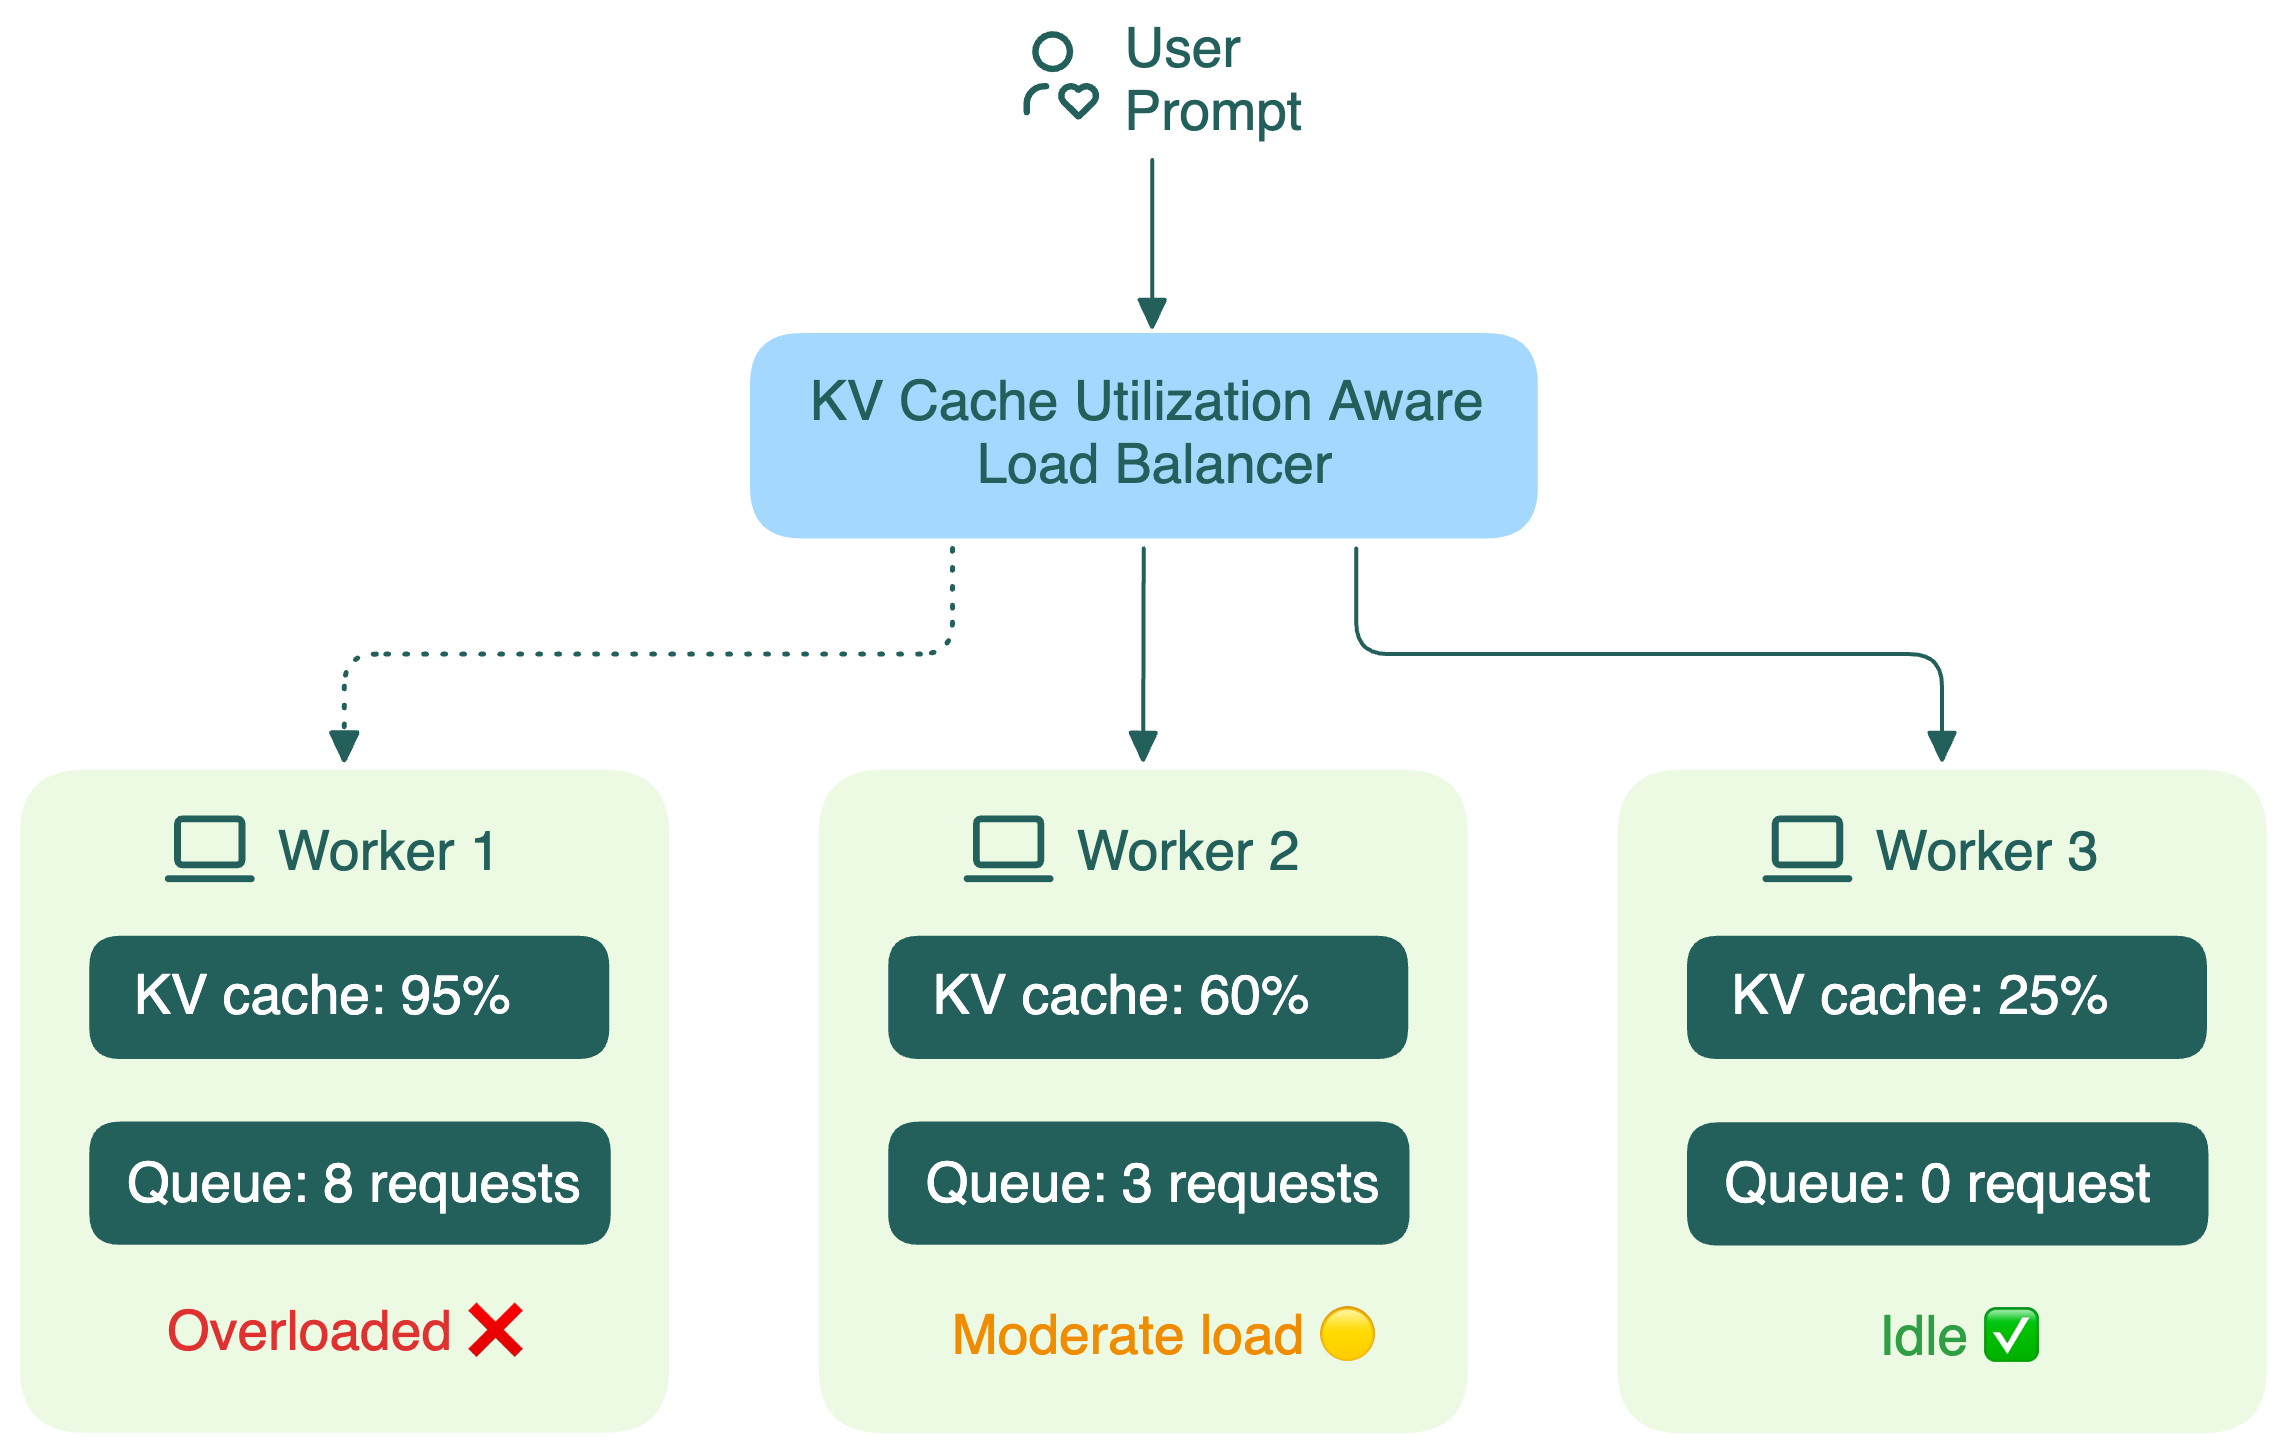
KV cache utilization-aware load balancing | LLM Inference Handbook

[论文评述] Accelerating LLM Inference Throughput via Asynchronous KV Cache ...

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...
LLM 인퍼런스 속도를 2~5배 높이는 법 — Speculative Decoding과 KV Cache 최적화 실전 가이드 ...
Advertisement Space (300x250)
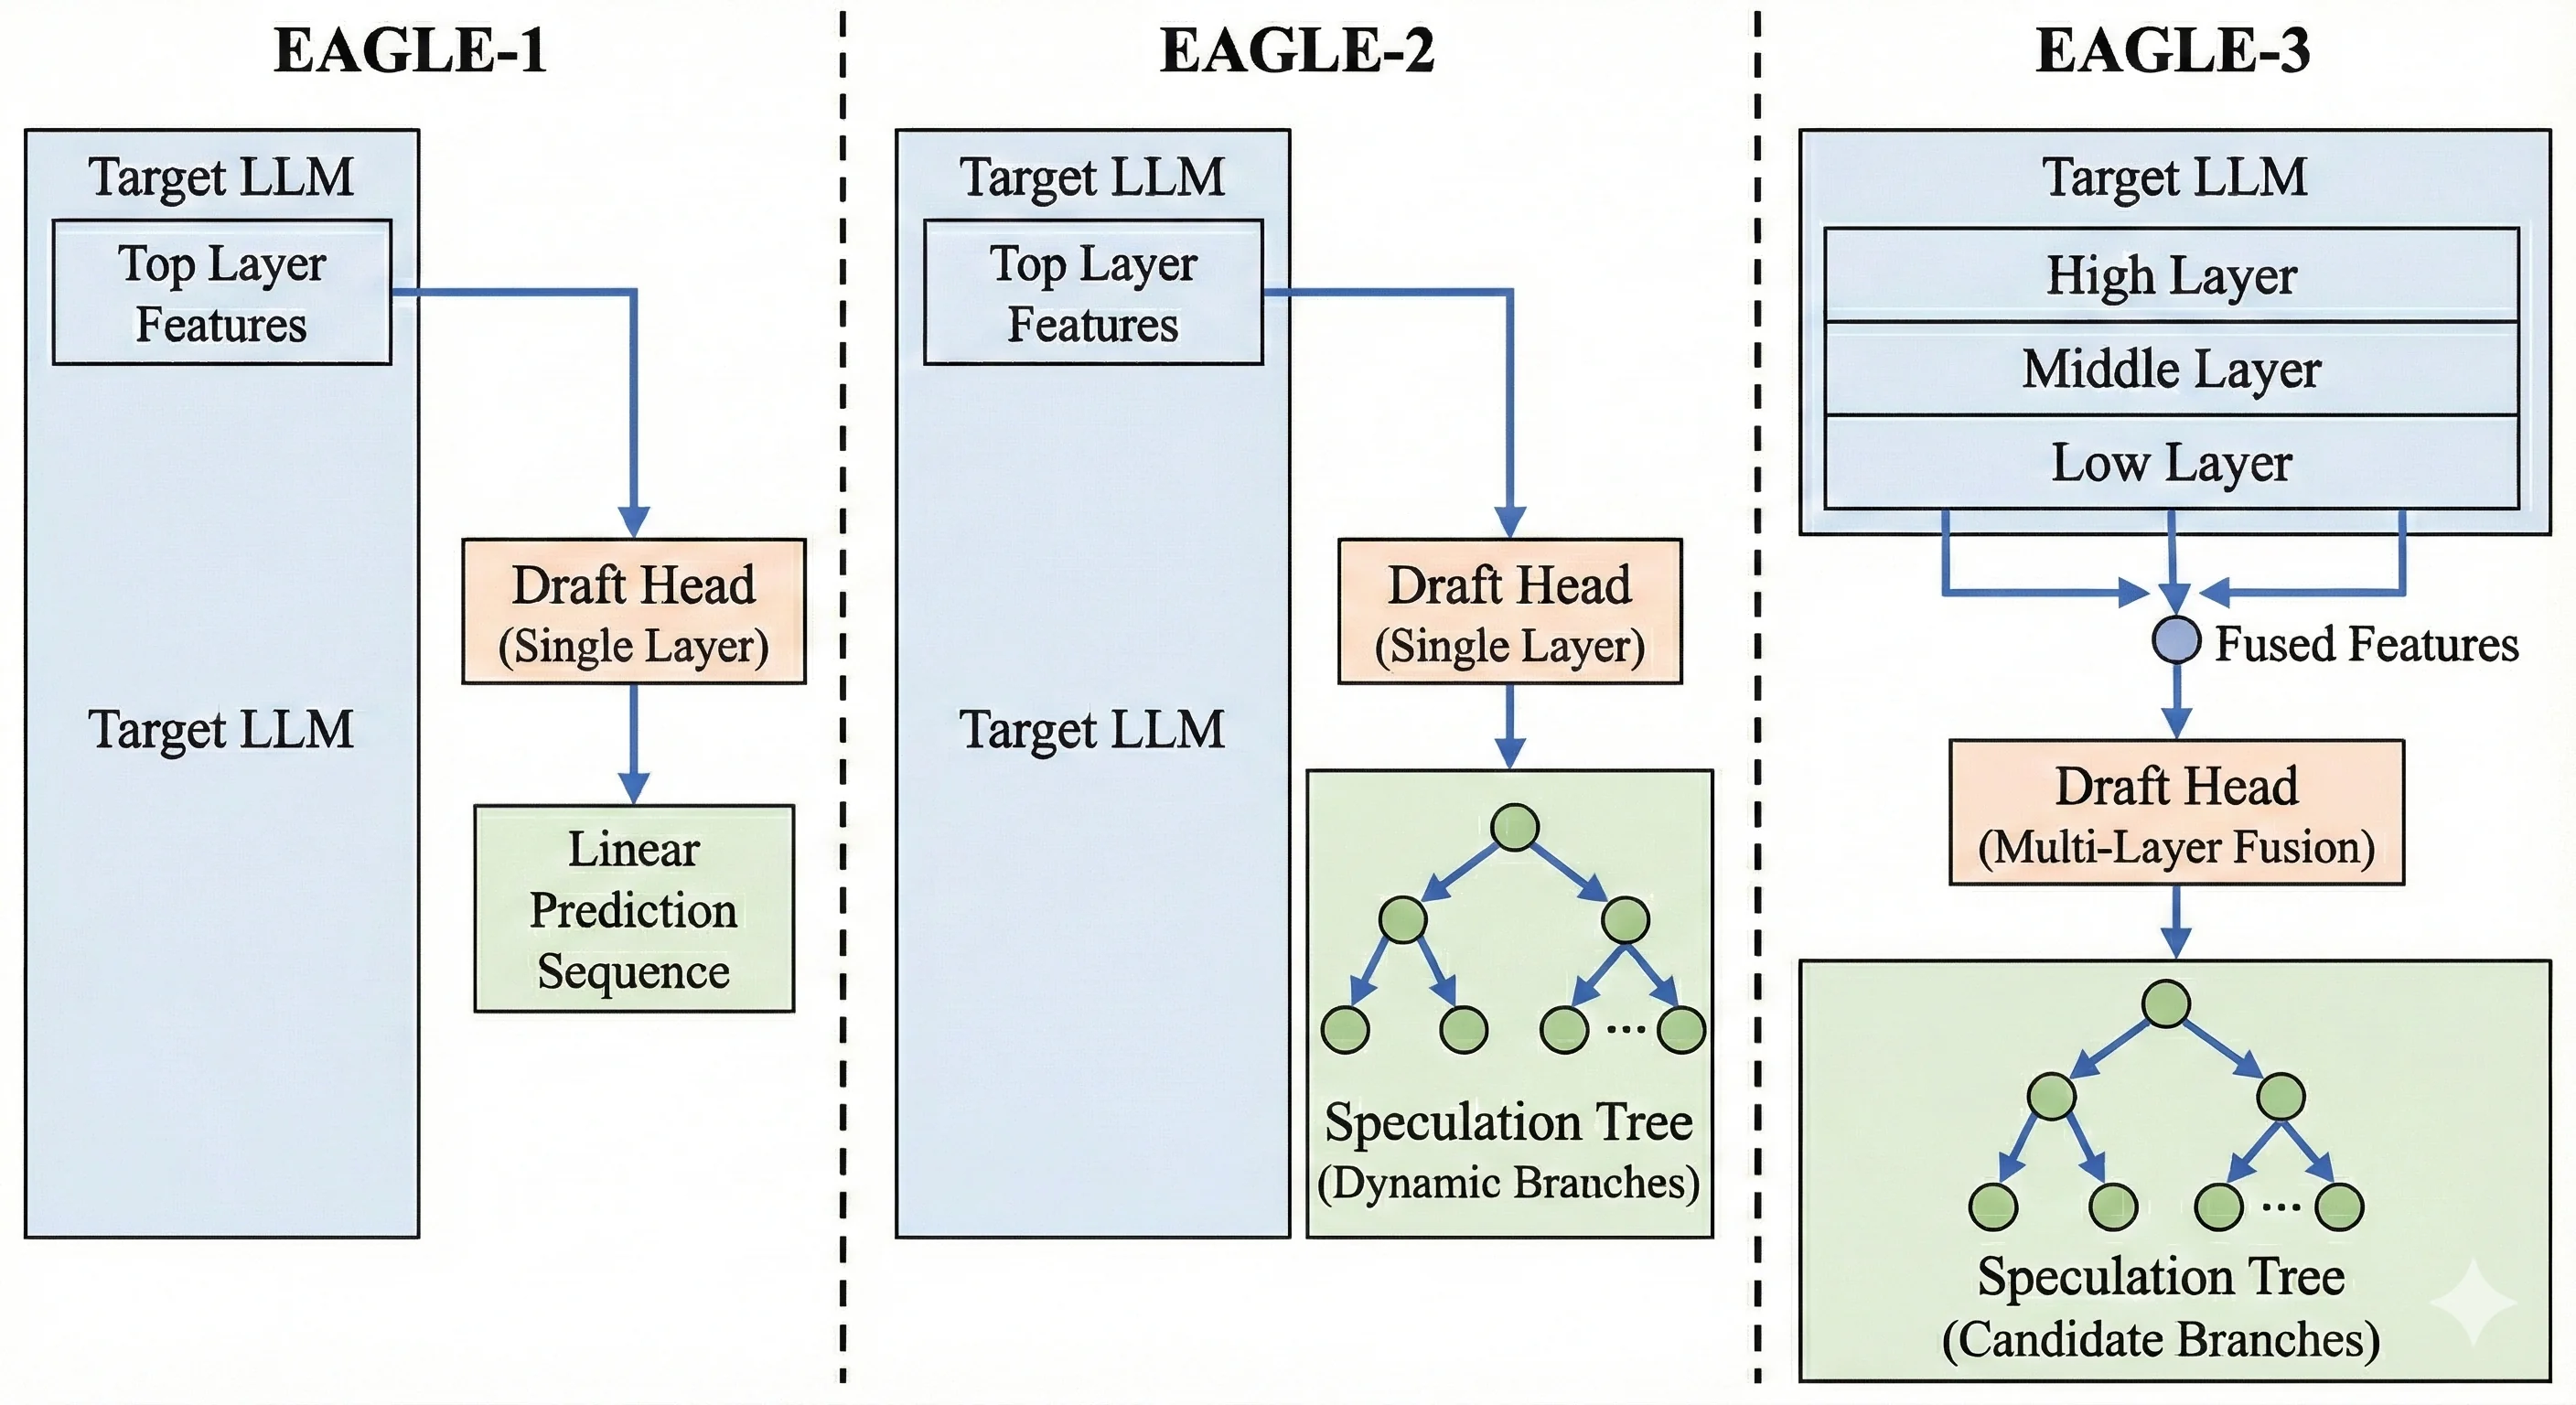
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
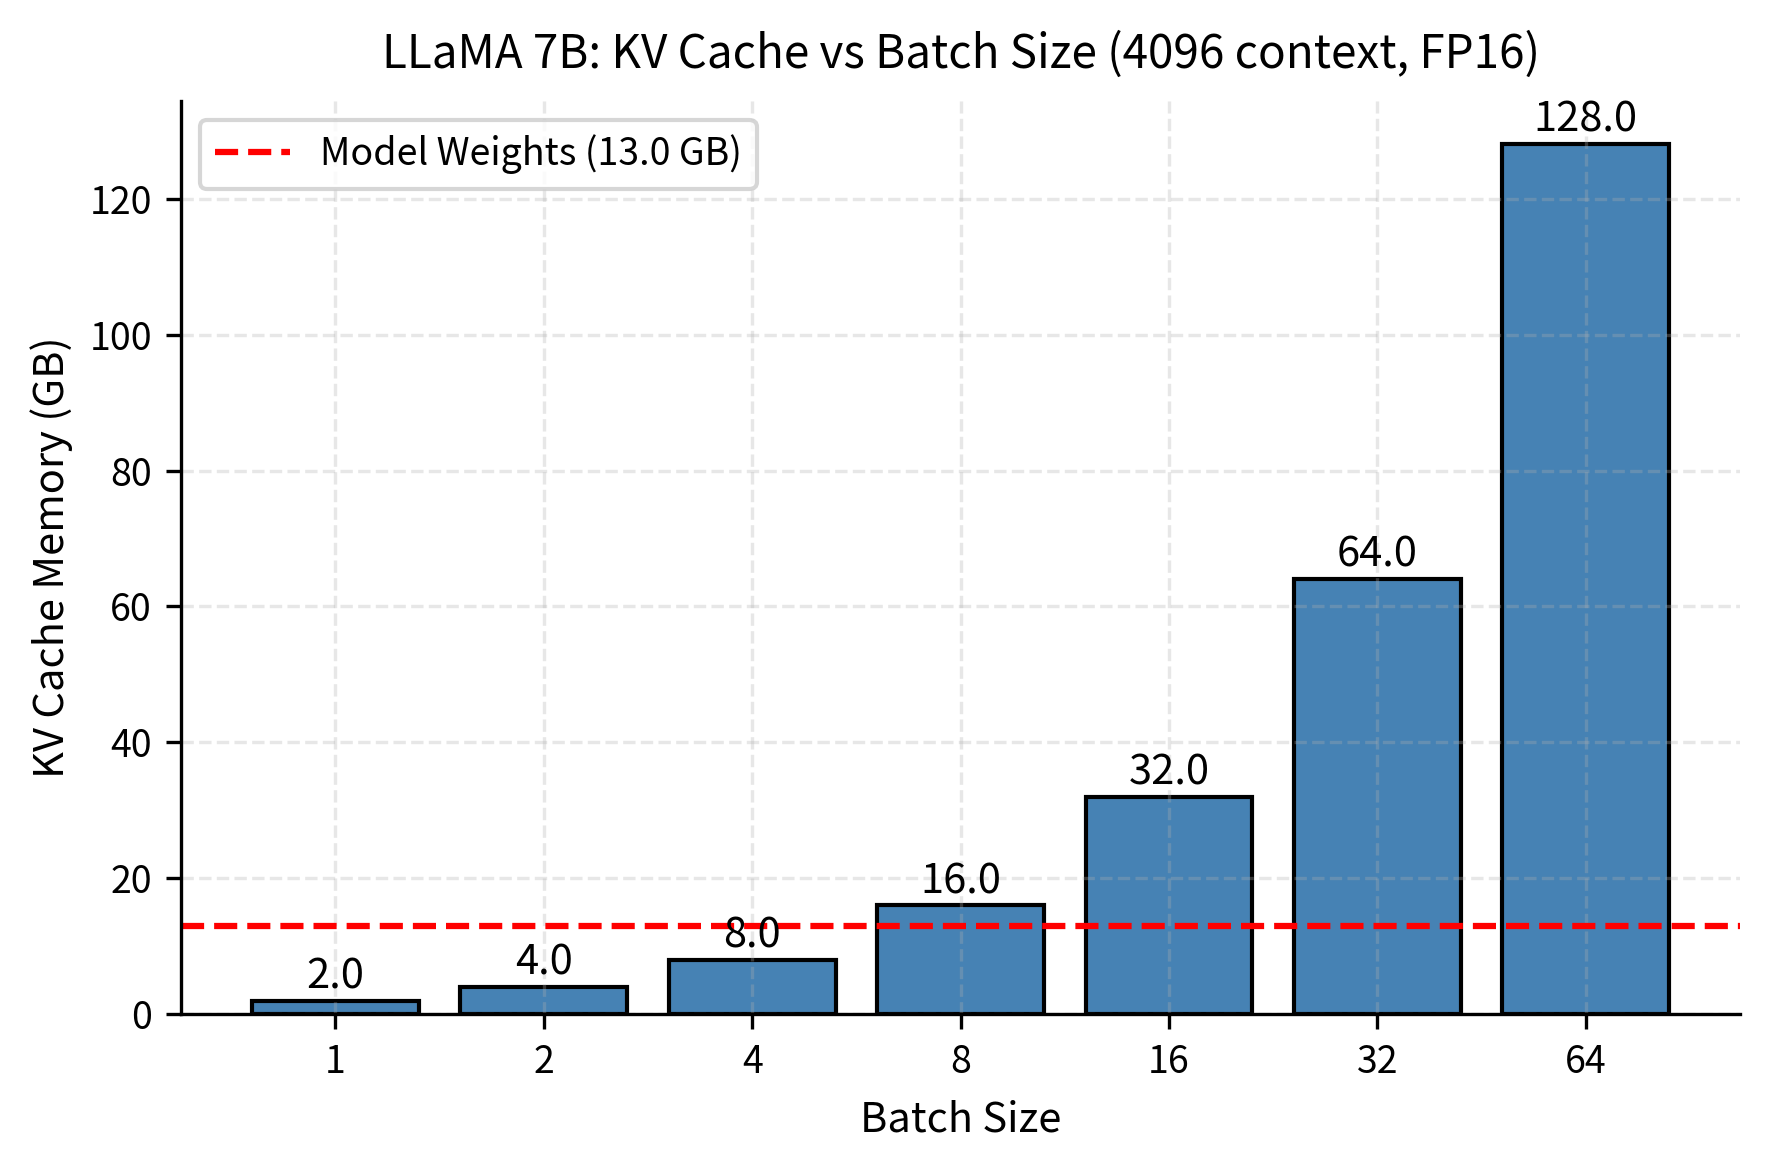
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference
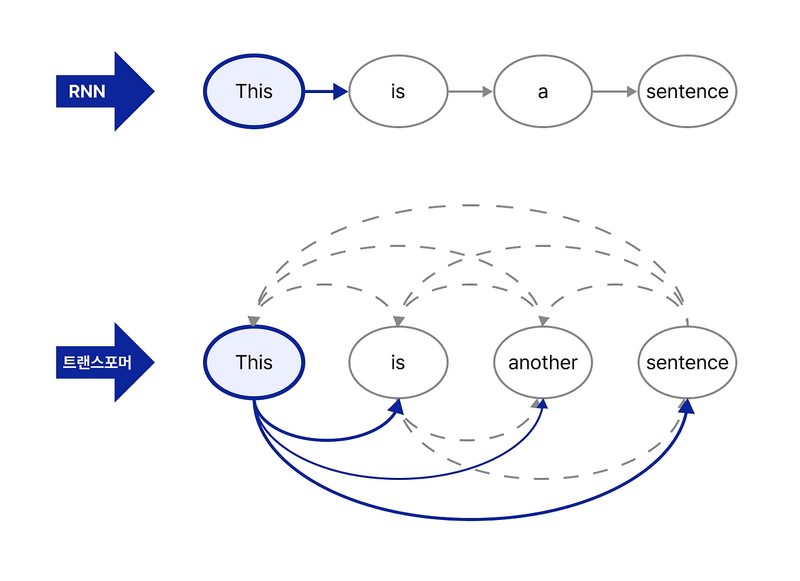
LLM 인퍼런스 속도를 2~5배 높이는 법 — Speculative Decoding과 KV Cache 최적화 실전 가이드 ...

KV Cache Optimization Strategies for Scalable and Efficient LLM Inference

KV Cache in LLM Inference - Complete Technical Deep Dive - YouTube

KV Cache Memory: Sizing LLM Inference

整合 Speculative Decoding 和 KV Cache 之實作筆記 - Clay-Technology World
LLM 인퍼런스 속도를 2~5배 높이는 법 — Speculative Decoding과 KV Cache 최적화 실전 가이드 ...
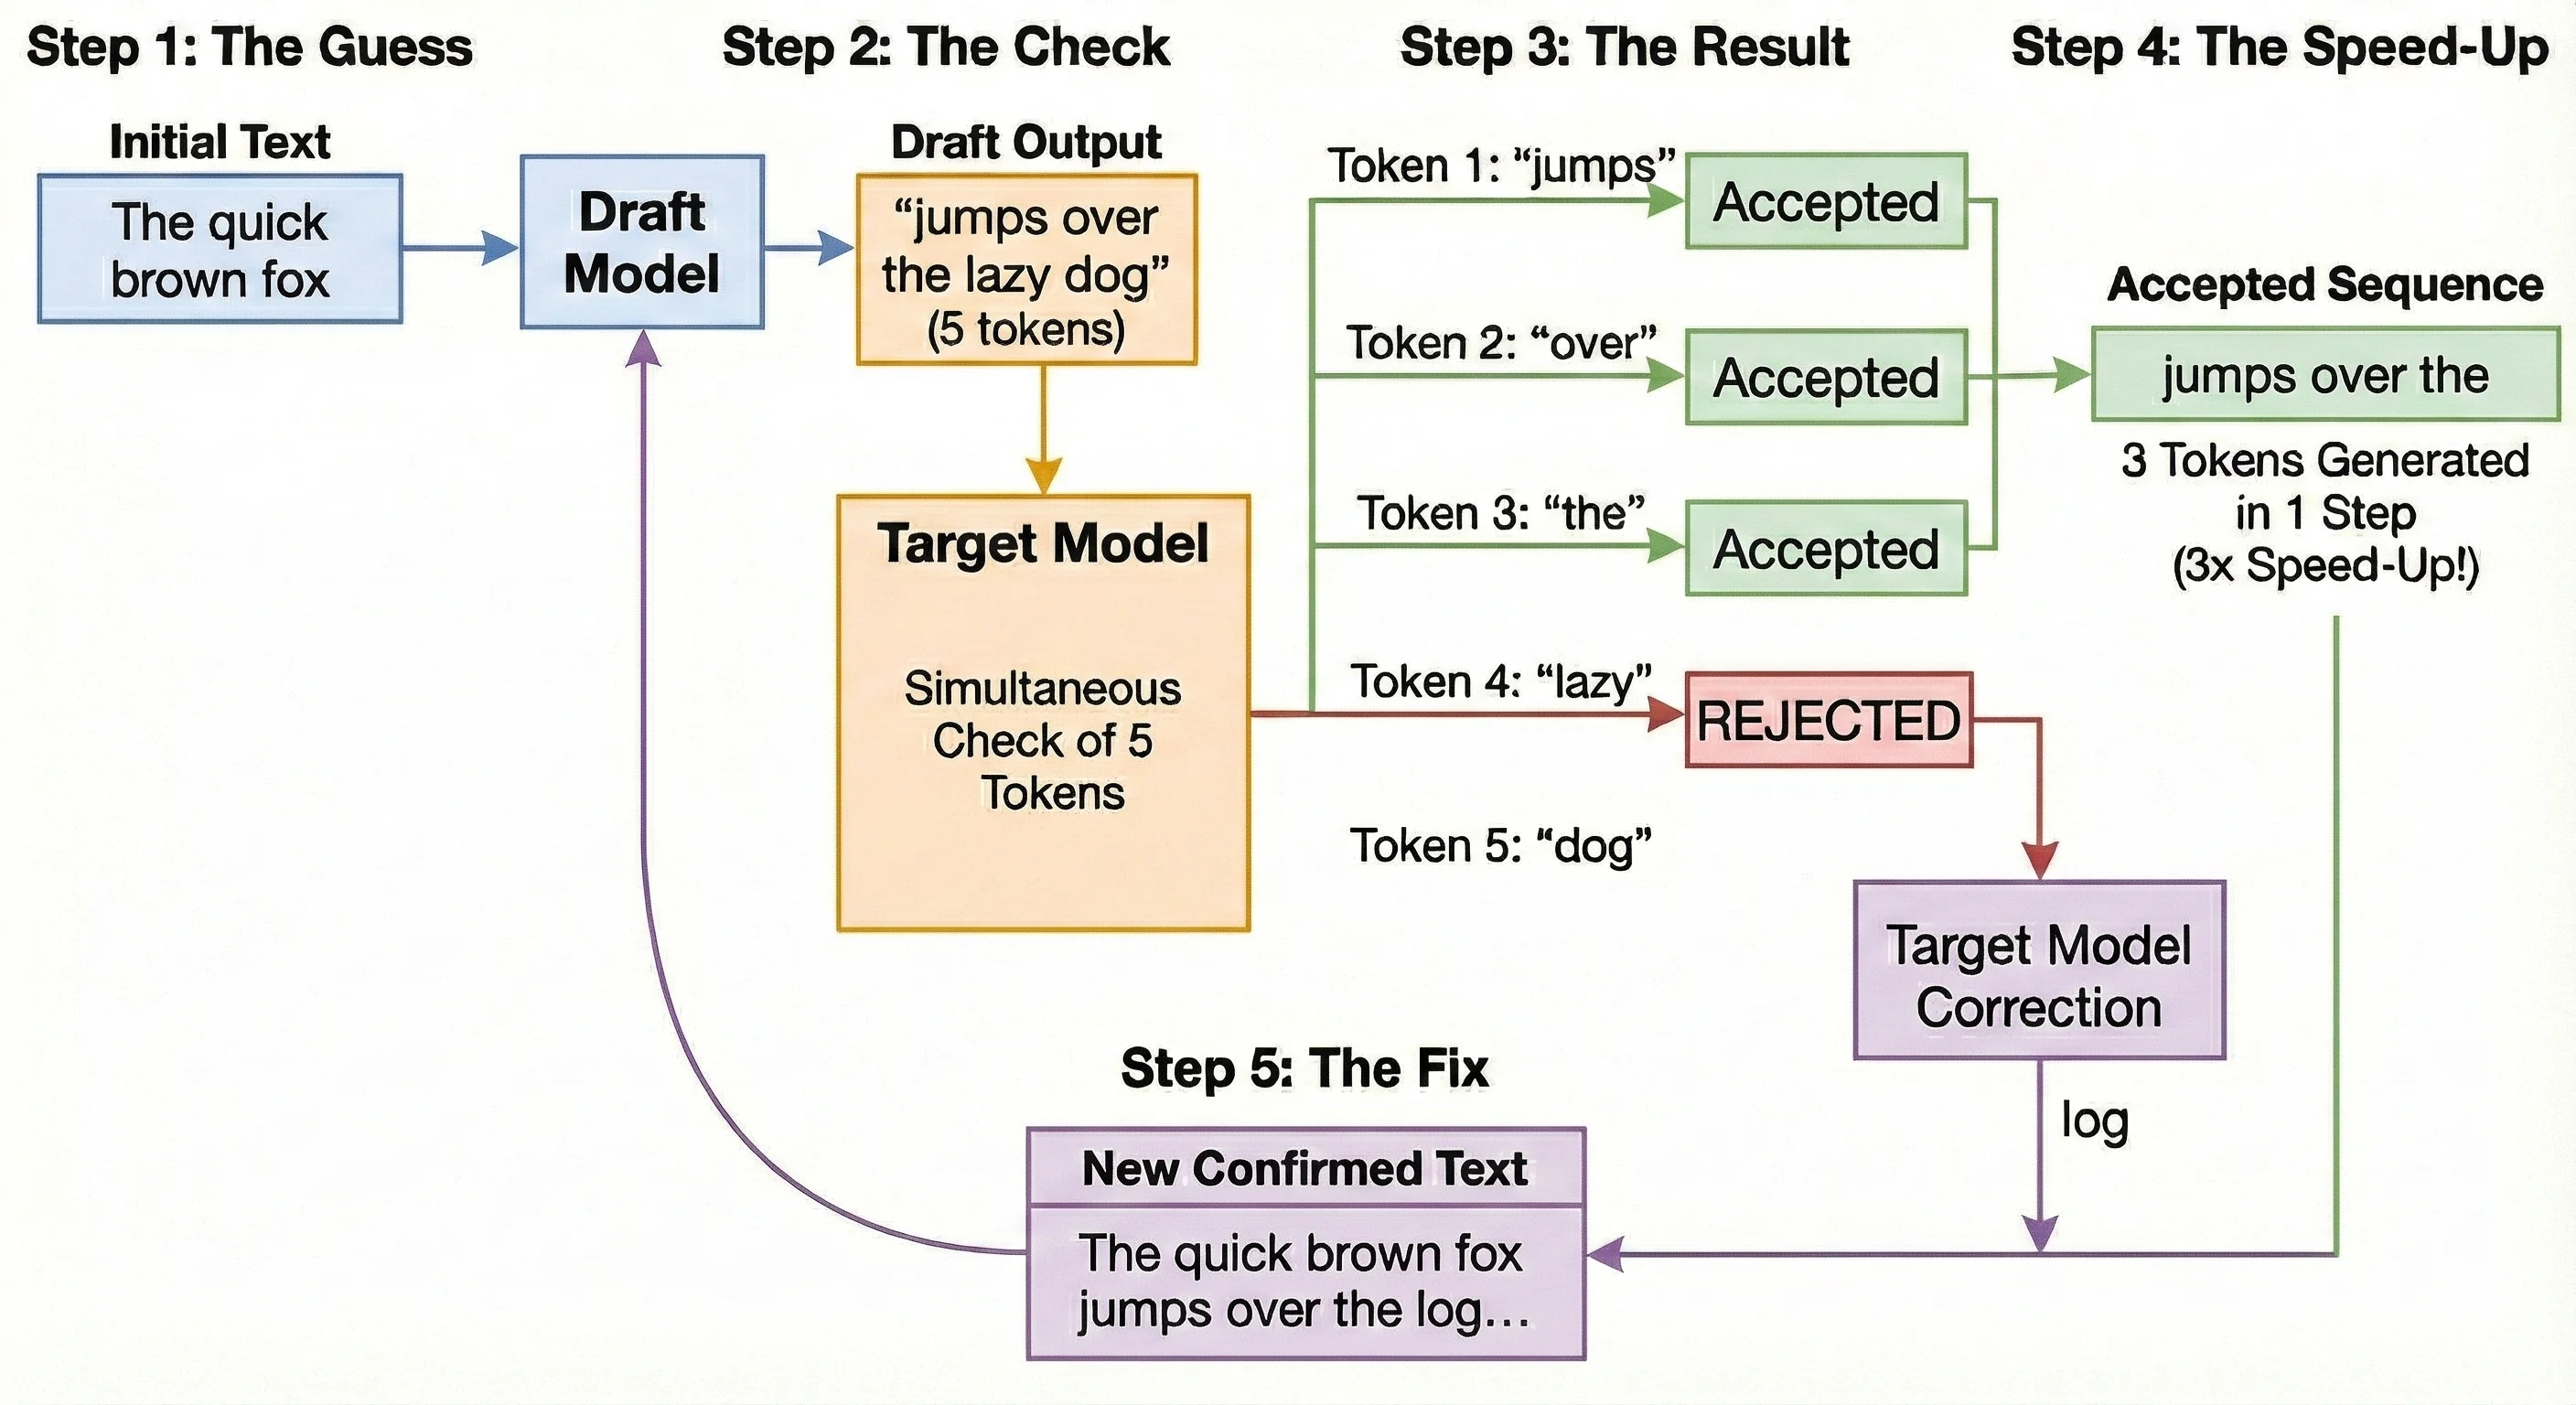
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
Advertisement Space (336x280)
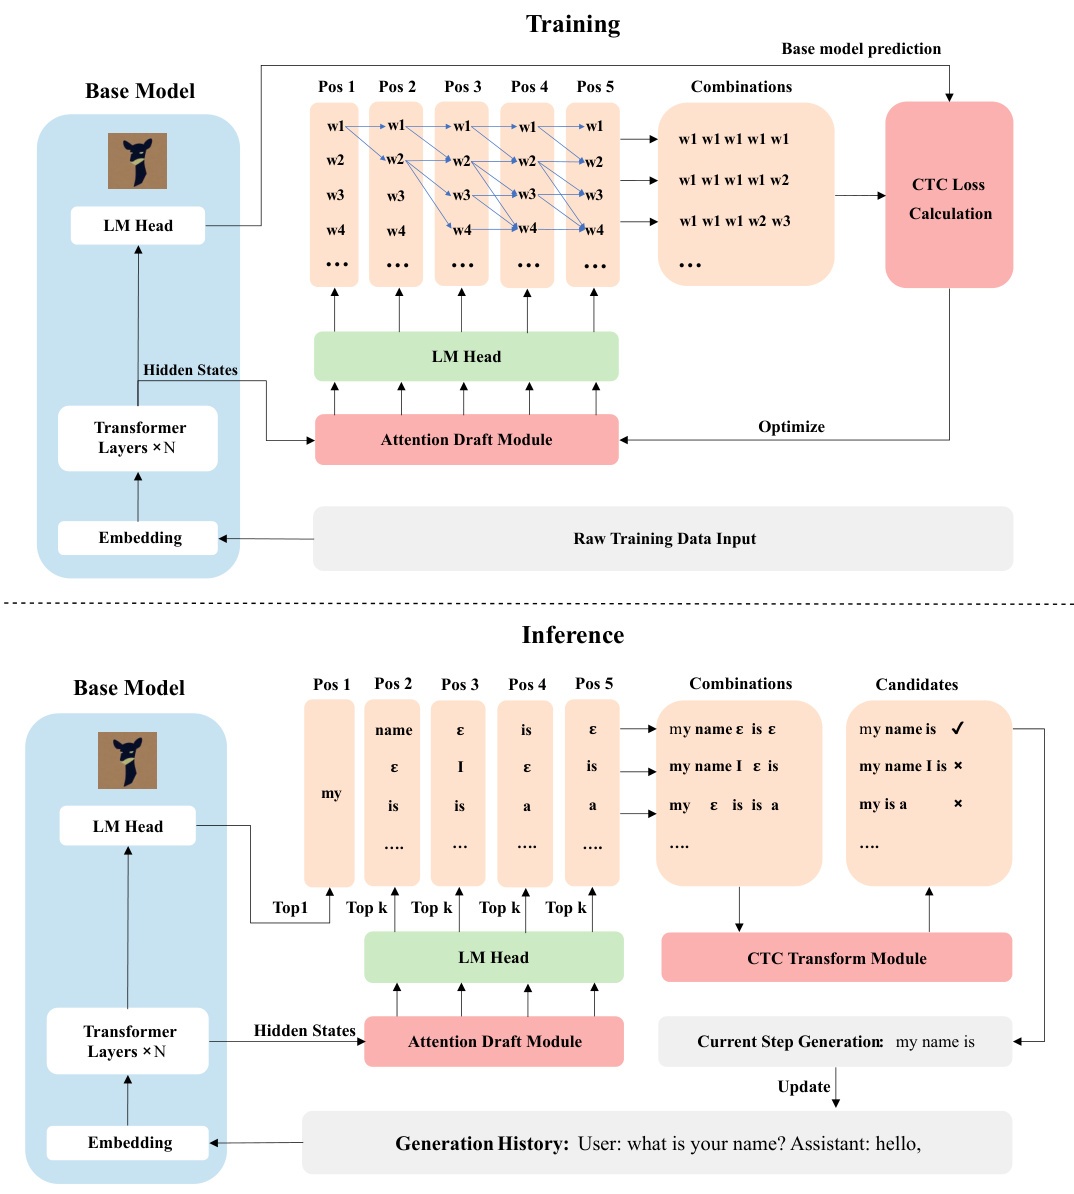
Speculative Decoding with CTC-based Draft Model for LLM Inference ...

LLM Inference Optimization: KV Caching Bottleneck | Sanyam Sharma ...
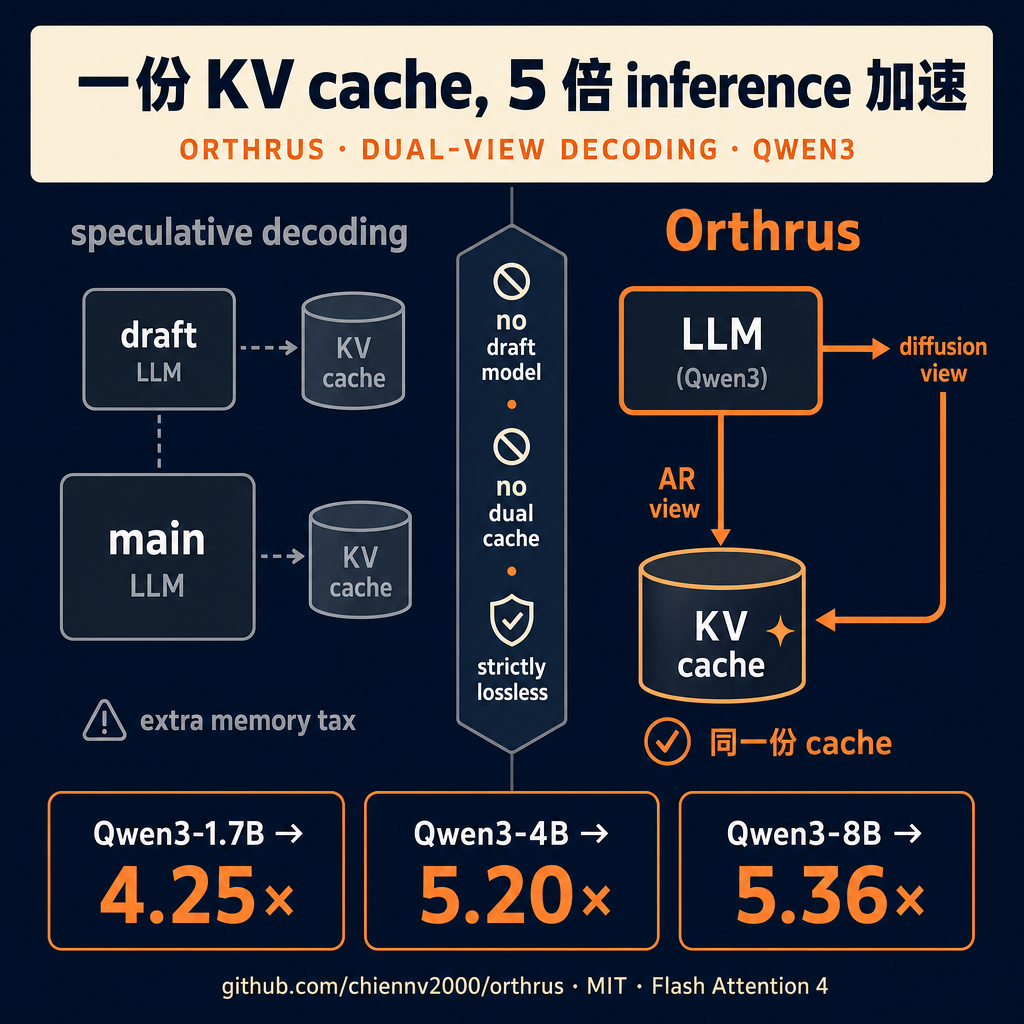
speculative decoding 这条 inference 加速路线,过去一年是默认选择——但有人在用另一种思路把 5 倍速度搞出来 ...
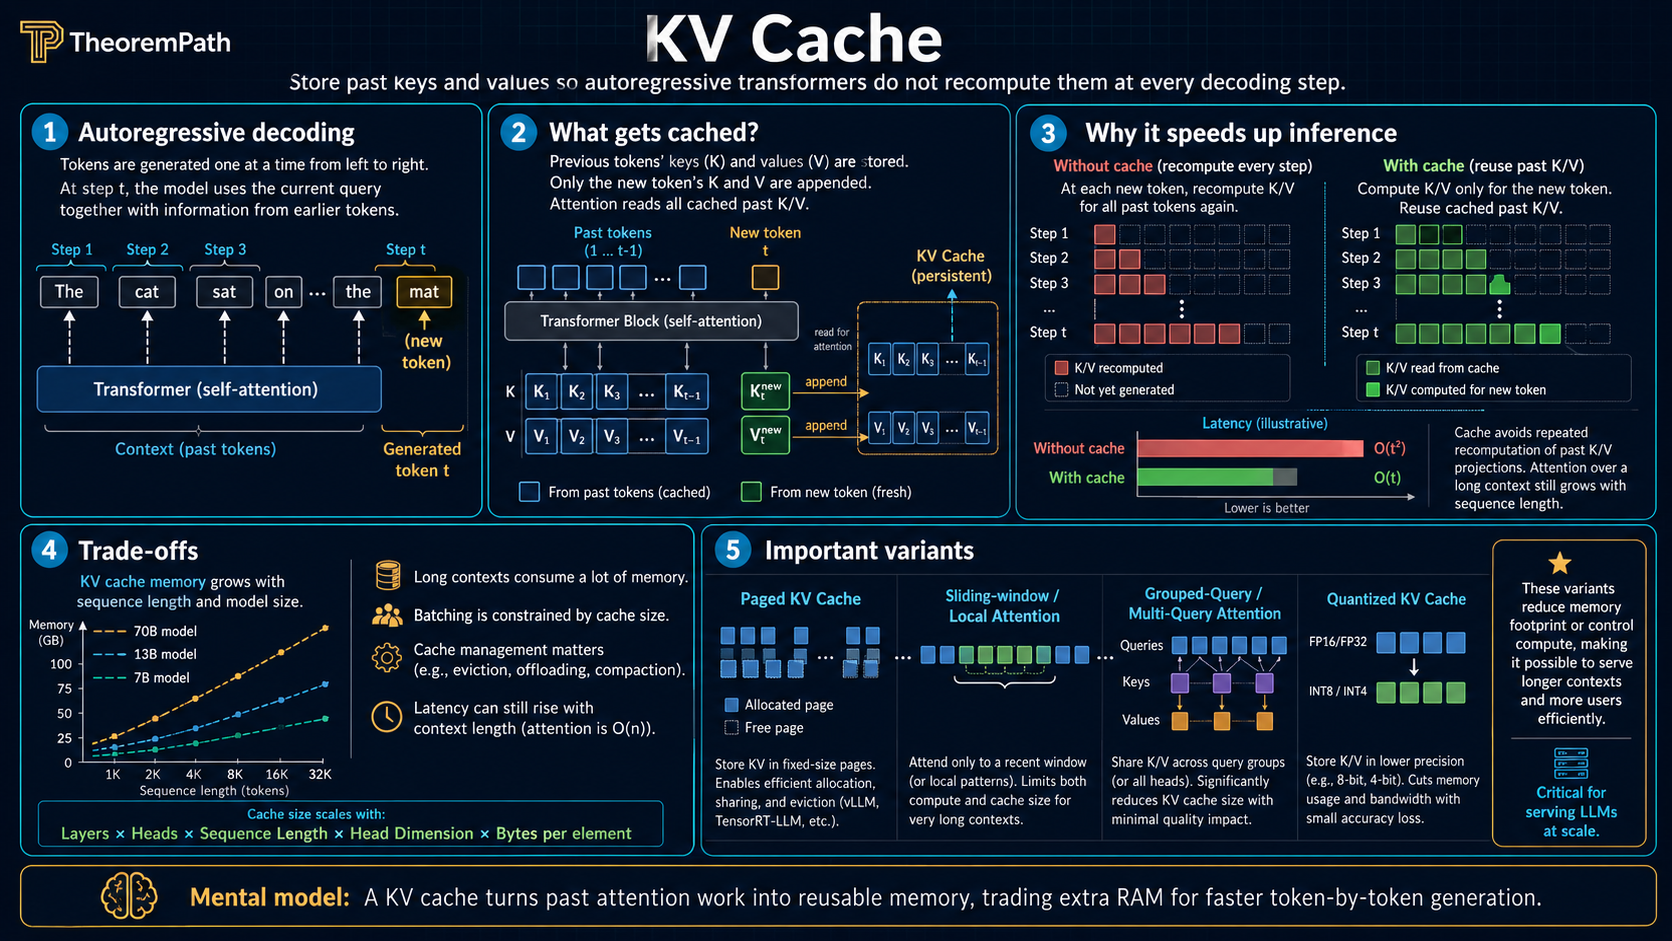
KV Cache. Inference Memory Bottleneck. LLM Construction | TheoremPath

How continuous batching enables 23x throughput in LLM inference ...

Comparative Characterization of KV Cache Management Strategies for LLM ...
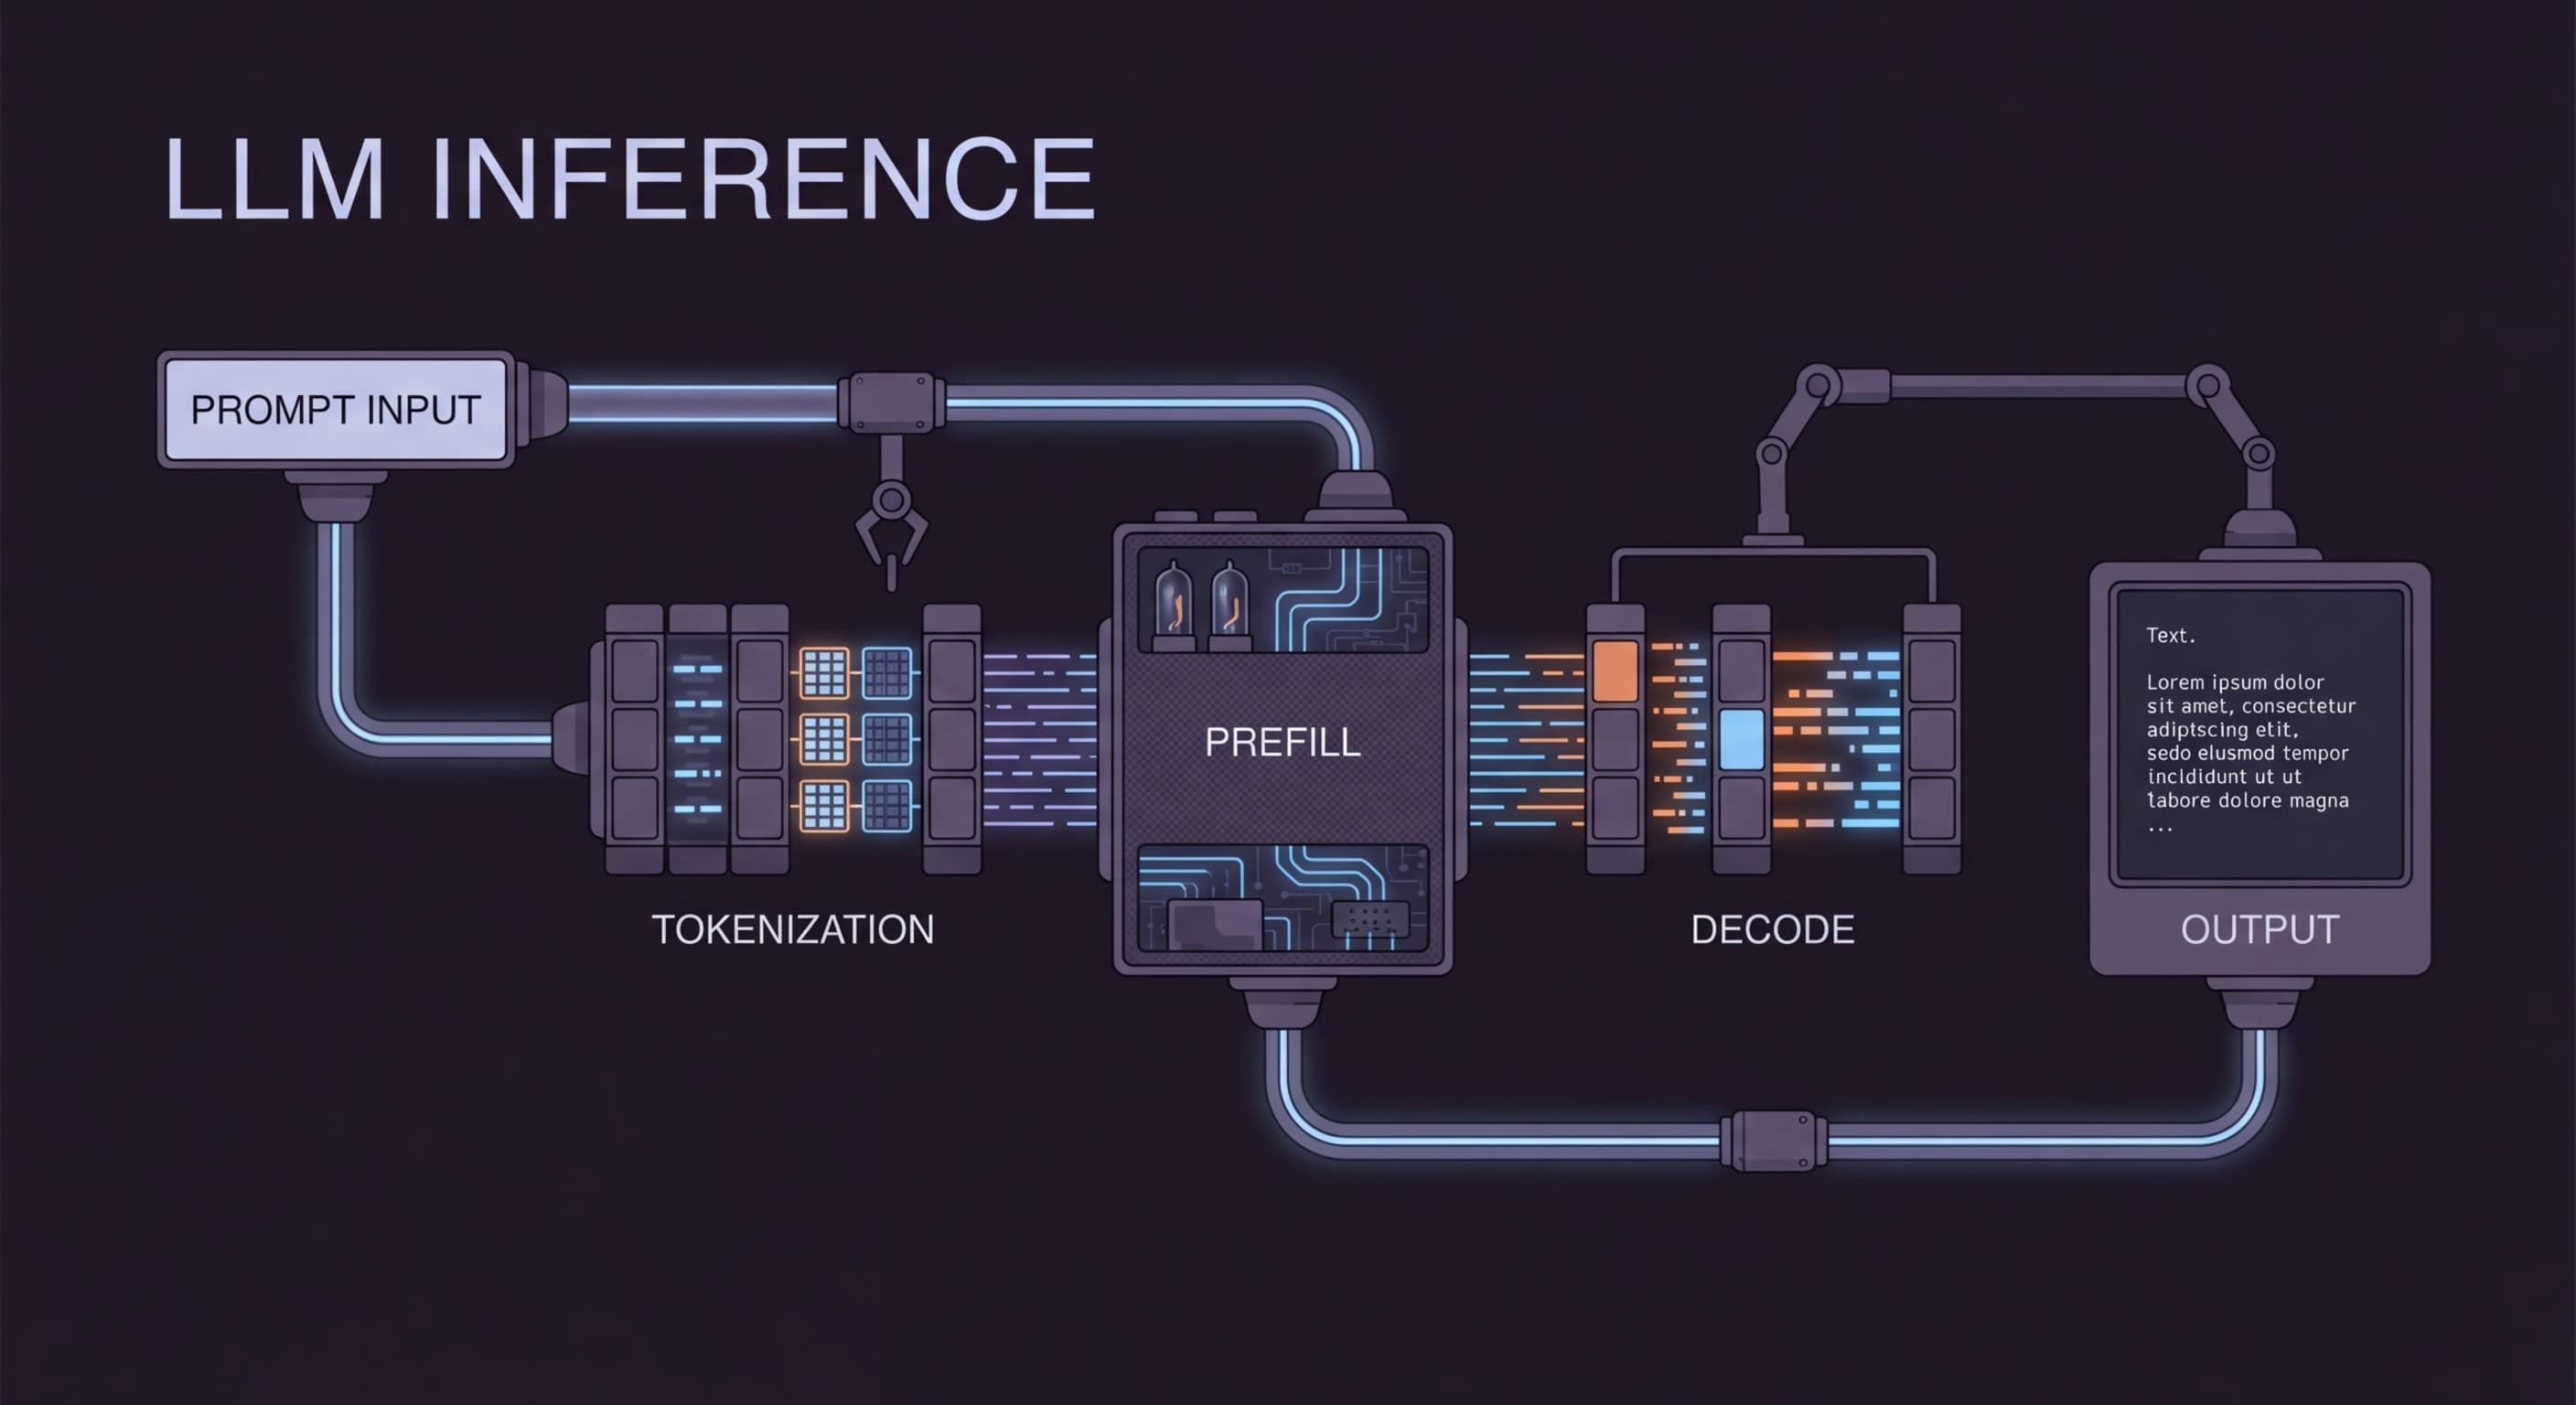
LLM Inference: Prefill, Decode, KV Cache & Cost Guide (2026) | Morph

Efficient LLM Inference 与 Serving:KV Cache、Speculative Decoding ...

LLM Inference Optimization: Batching, Quantization, and Speculative ...
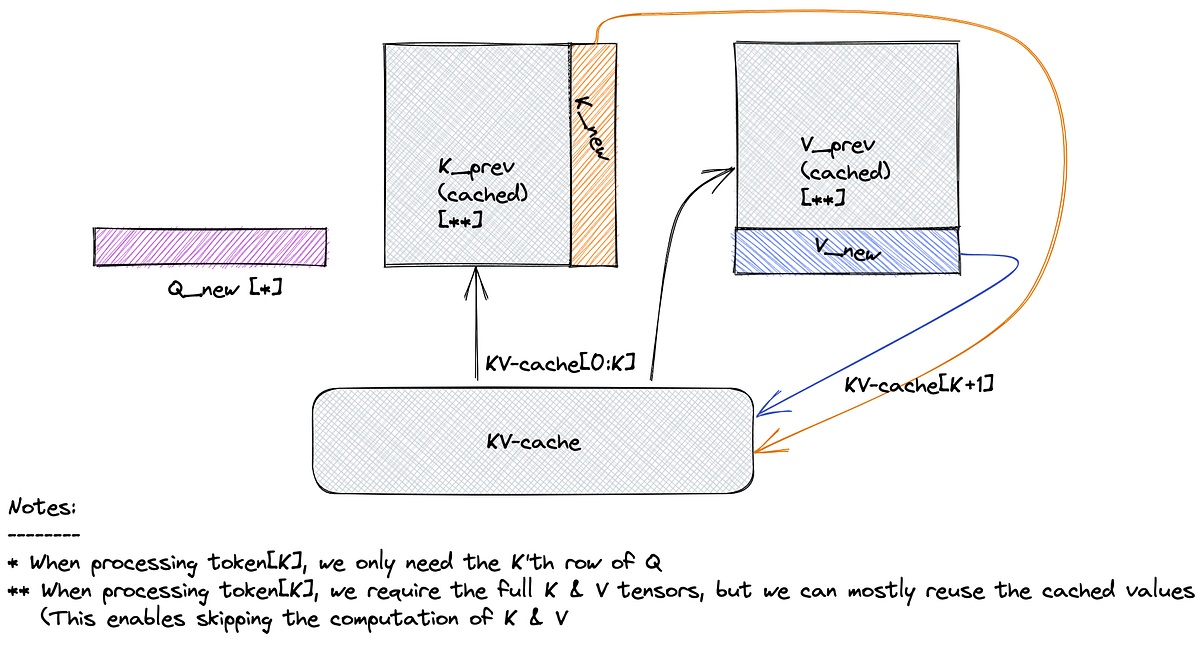
How to Optimize LLM Inference ?. In this blog, we’ll explore how to ...
Advertisement Space (336x280)

Efficient LLM Inference 与 Serving:KV Cache、Speculative Decoding ...
Speculative KV Cache: Definition & Optimization | Inference Systems
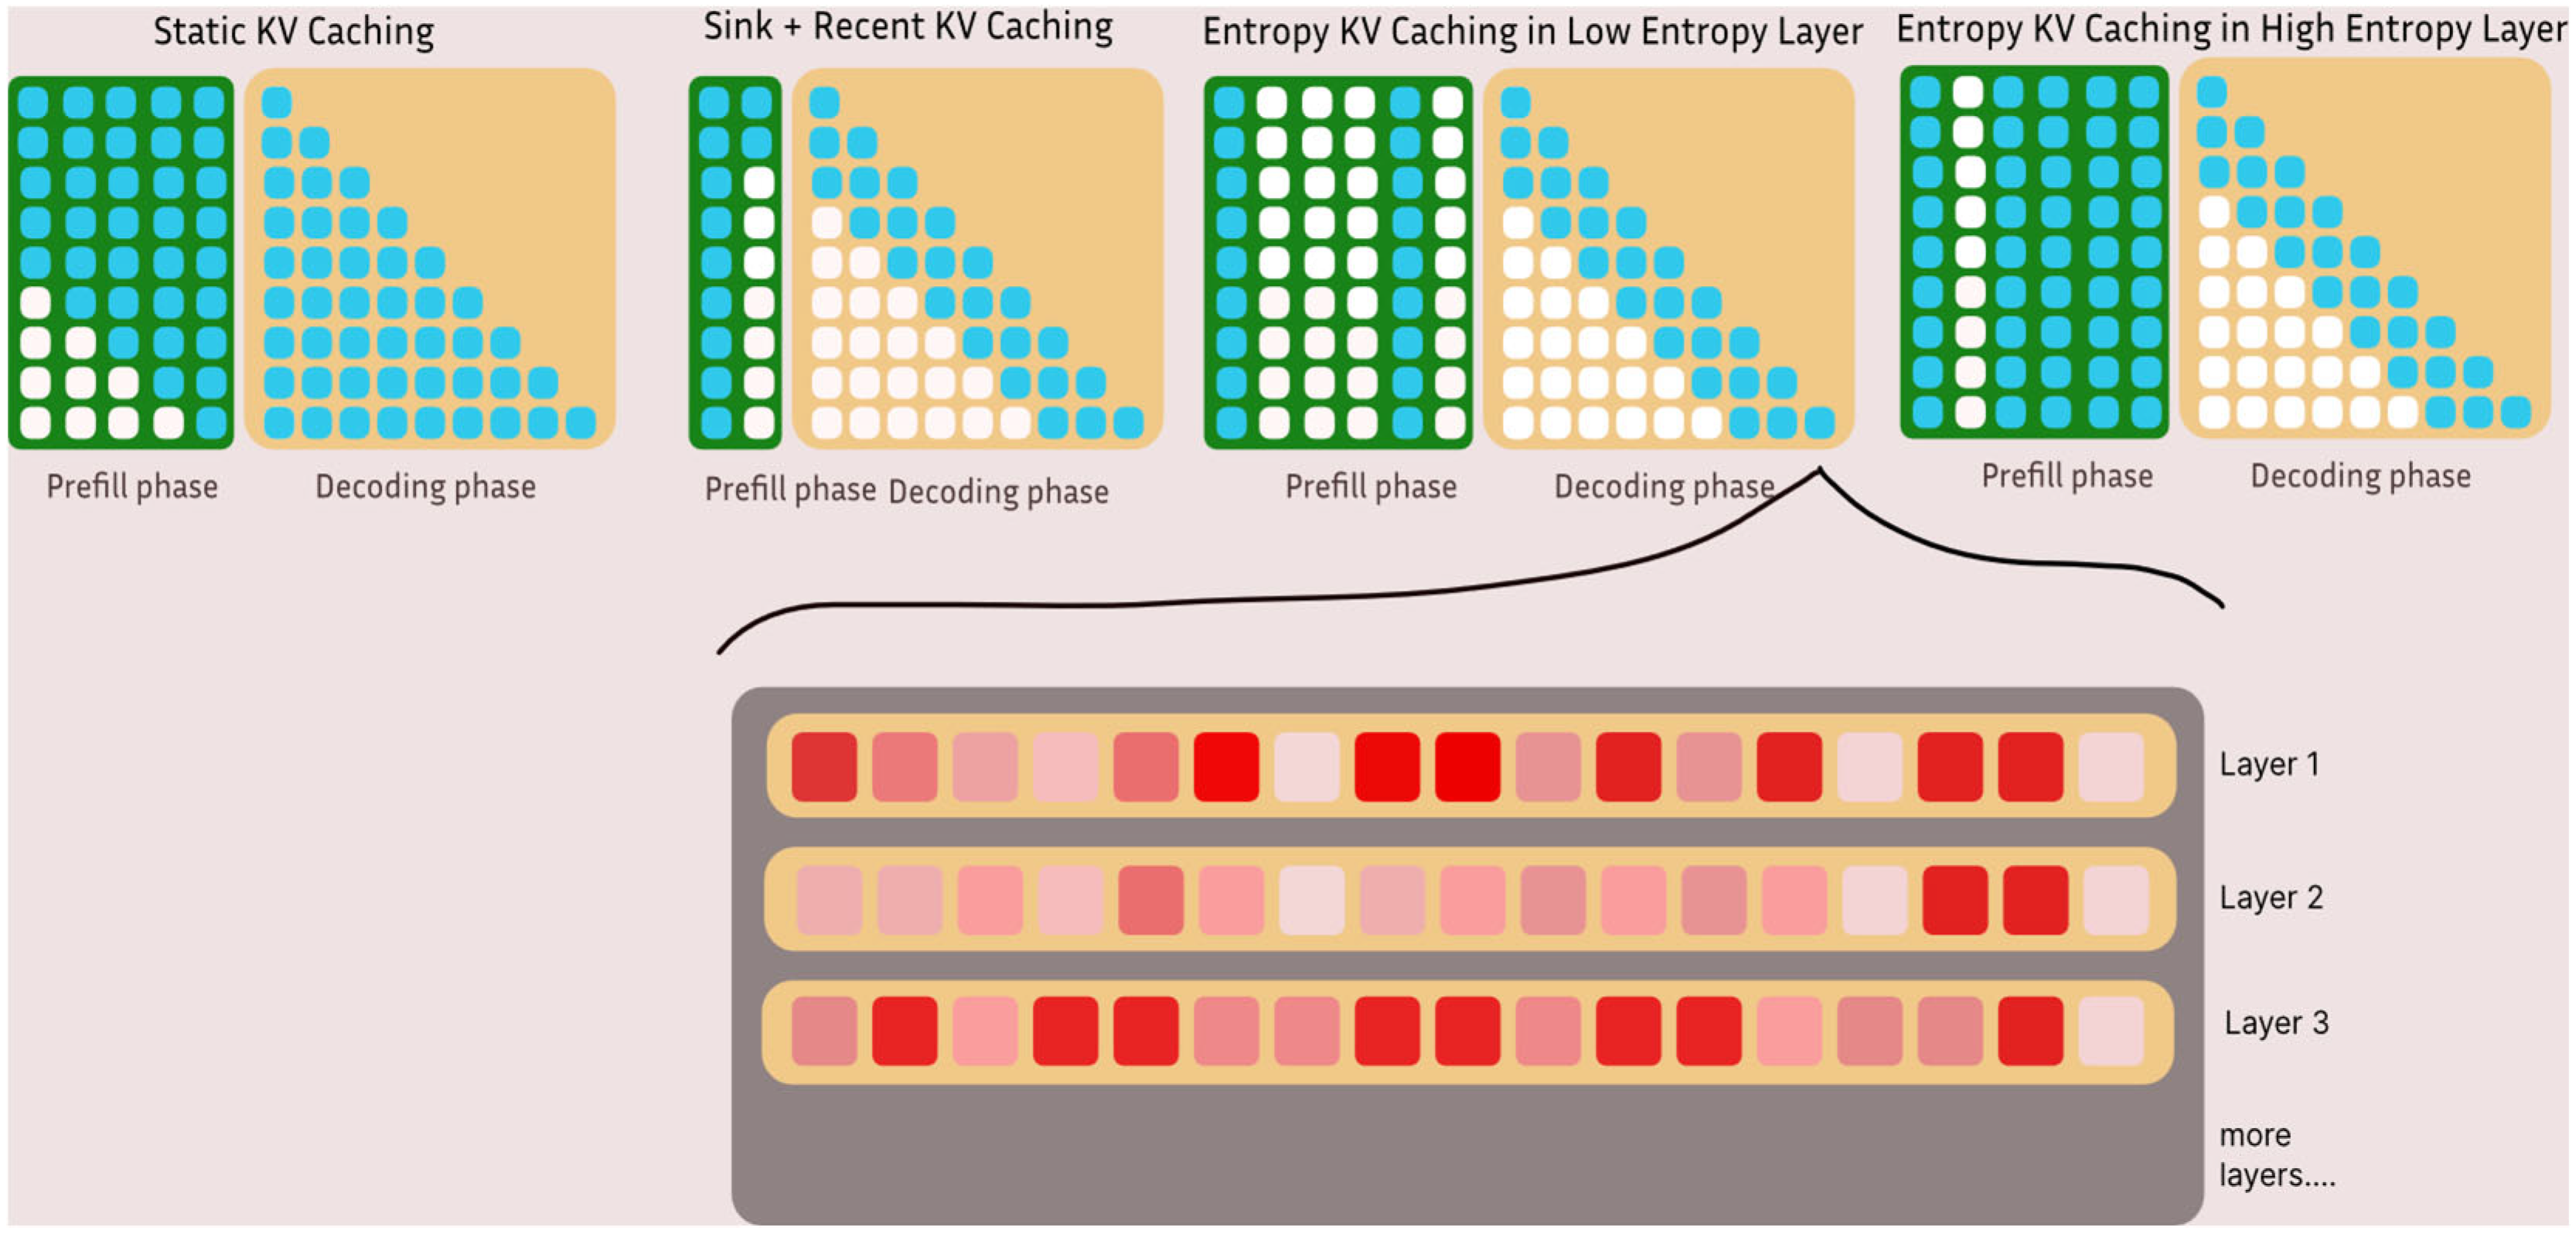
Entropy-Guided KV Caching for Efficient LLM Inference

Comparative Characterization of KV Cache Management Strategies for LLM ...
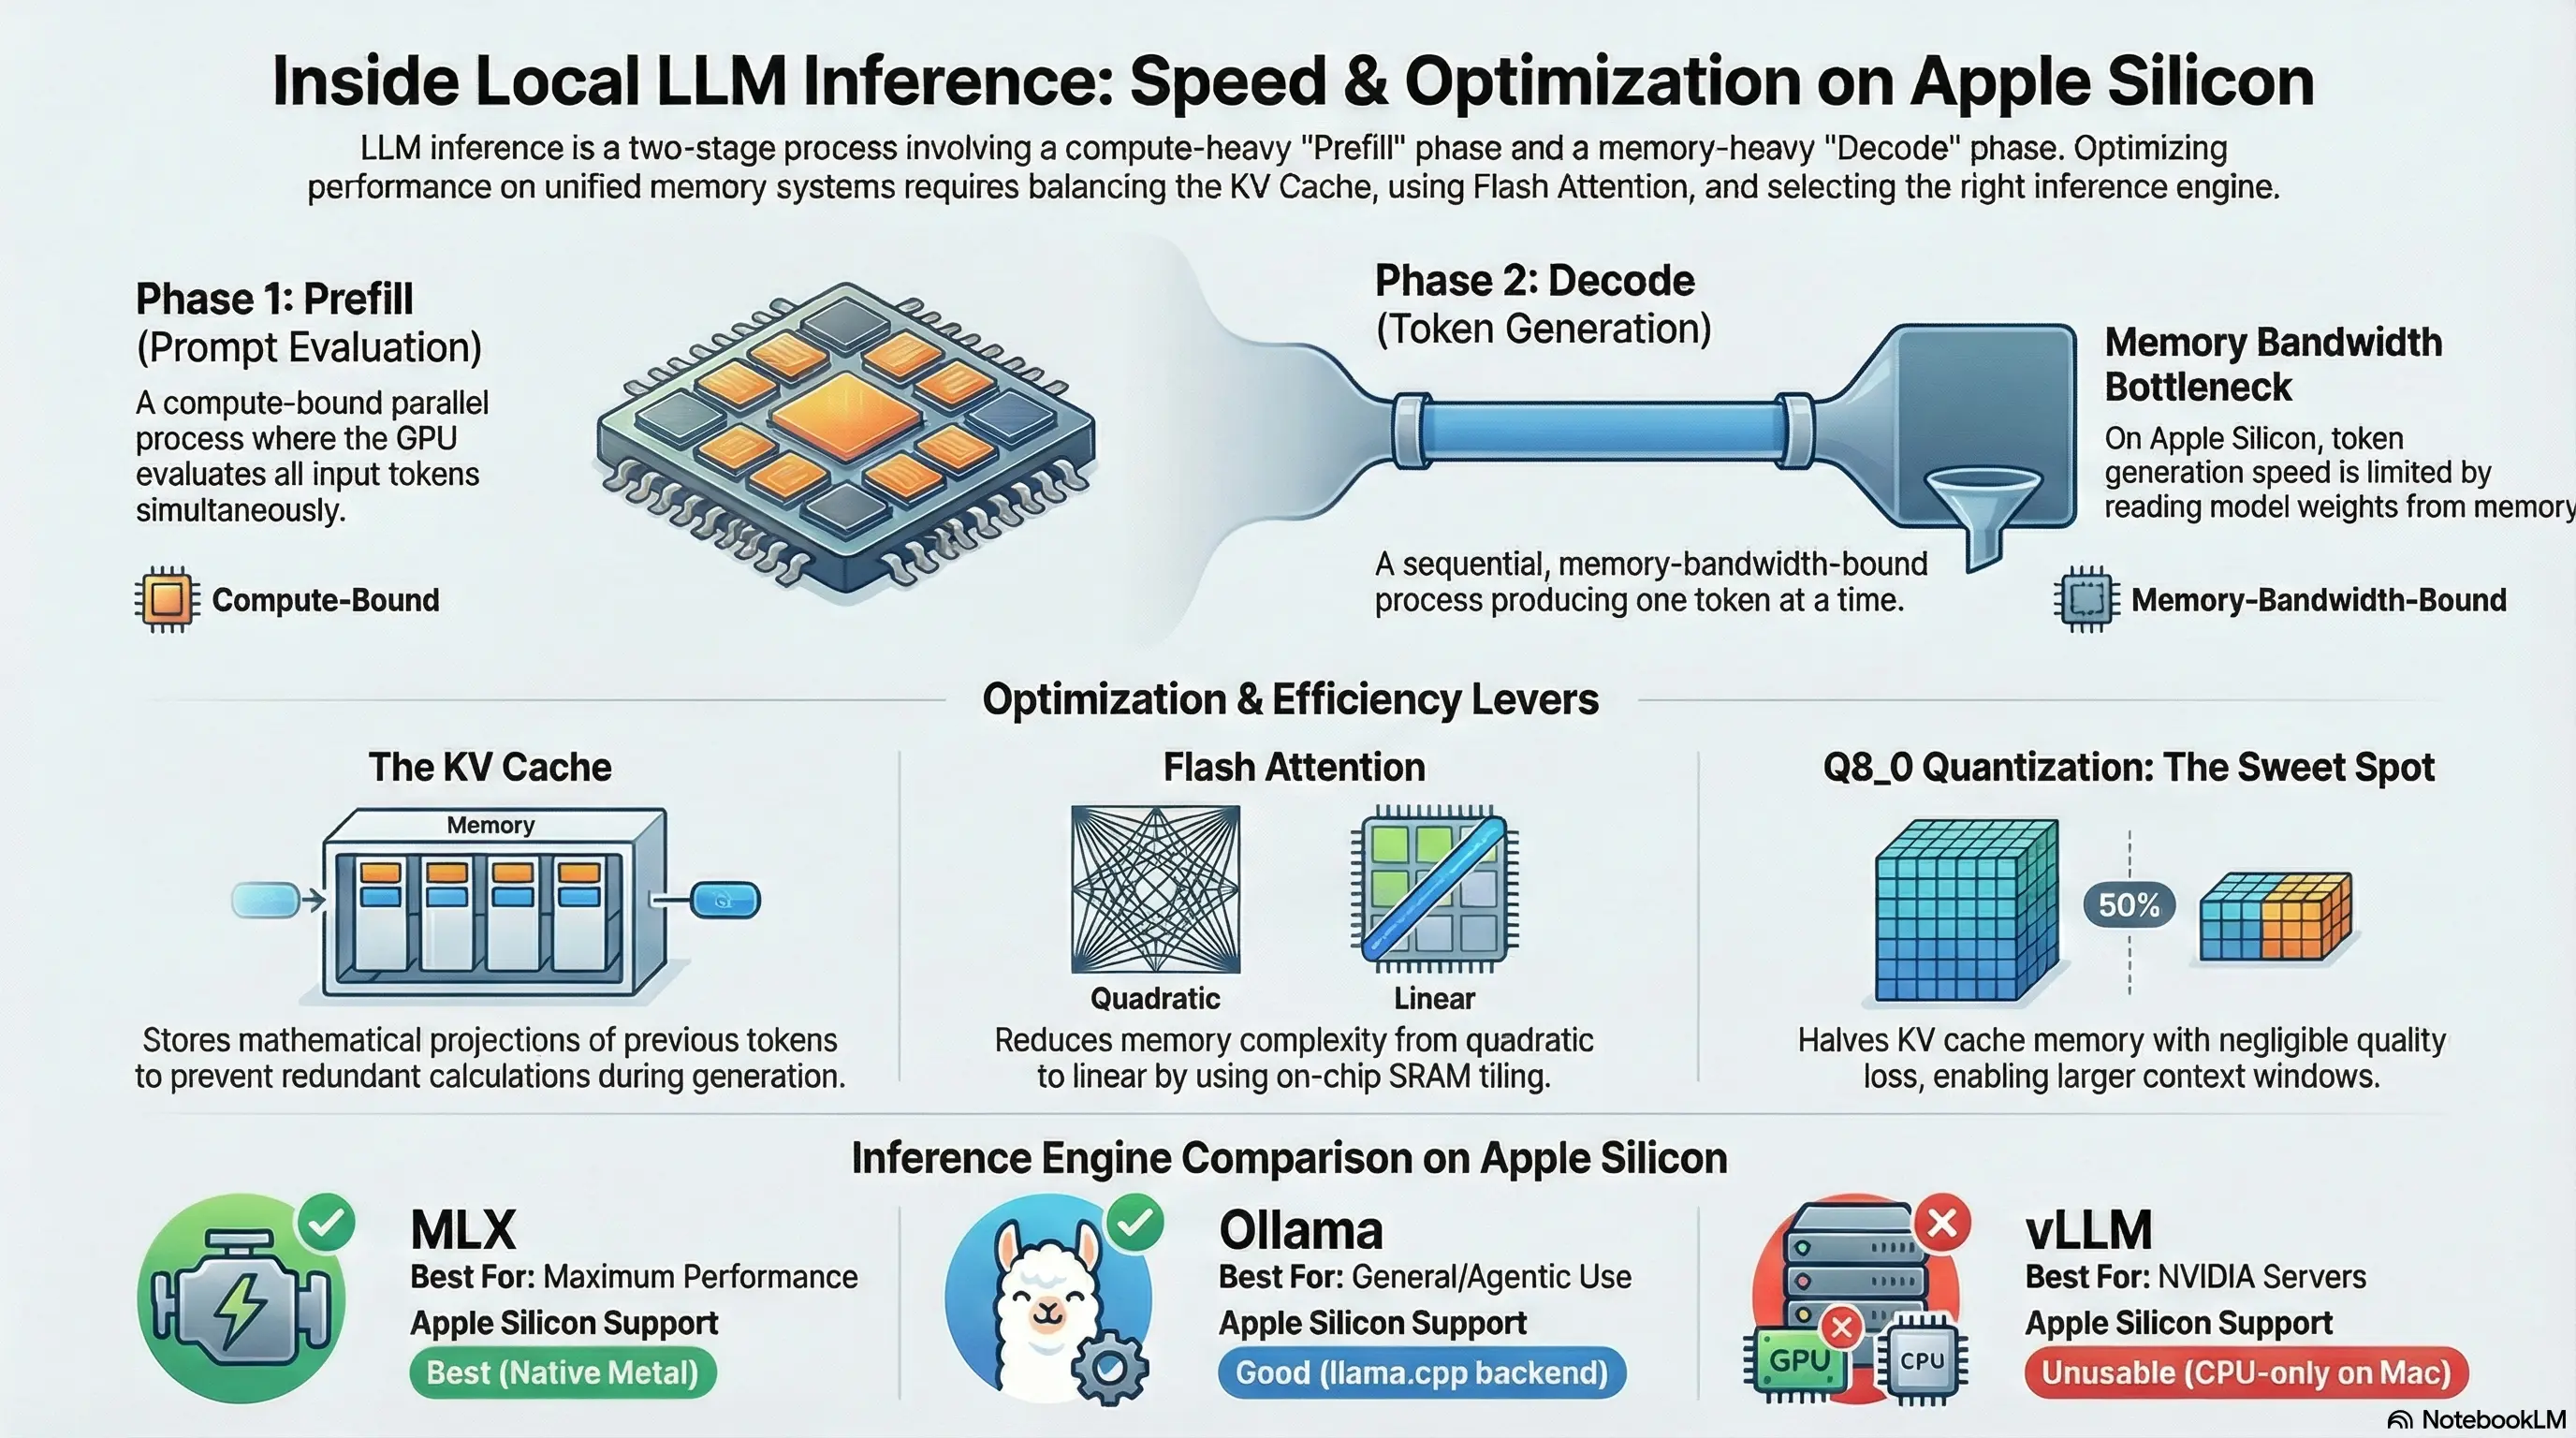
LLM Inference Internals: KV Cache, Flash Attention, and Optimizing for ...

Comparative Characterization of KV Cache Management Strategies for LLM ...