
Llm Kv Cache Speculative Decoding Ai
LLM 推理优化全指南:从 KV Cache 到 Speculative Decoding | AI 实战派 · 从技术到赚钱
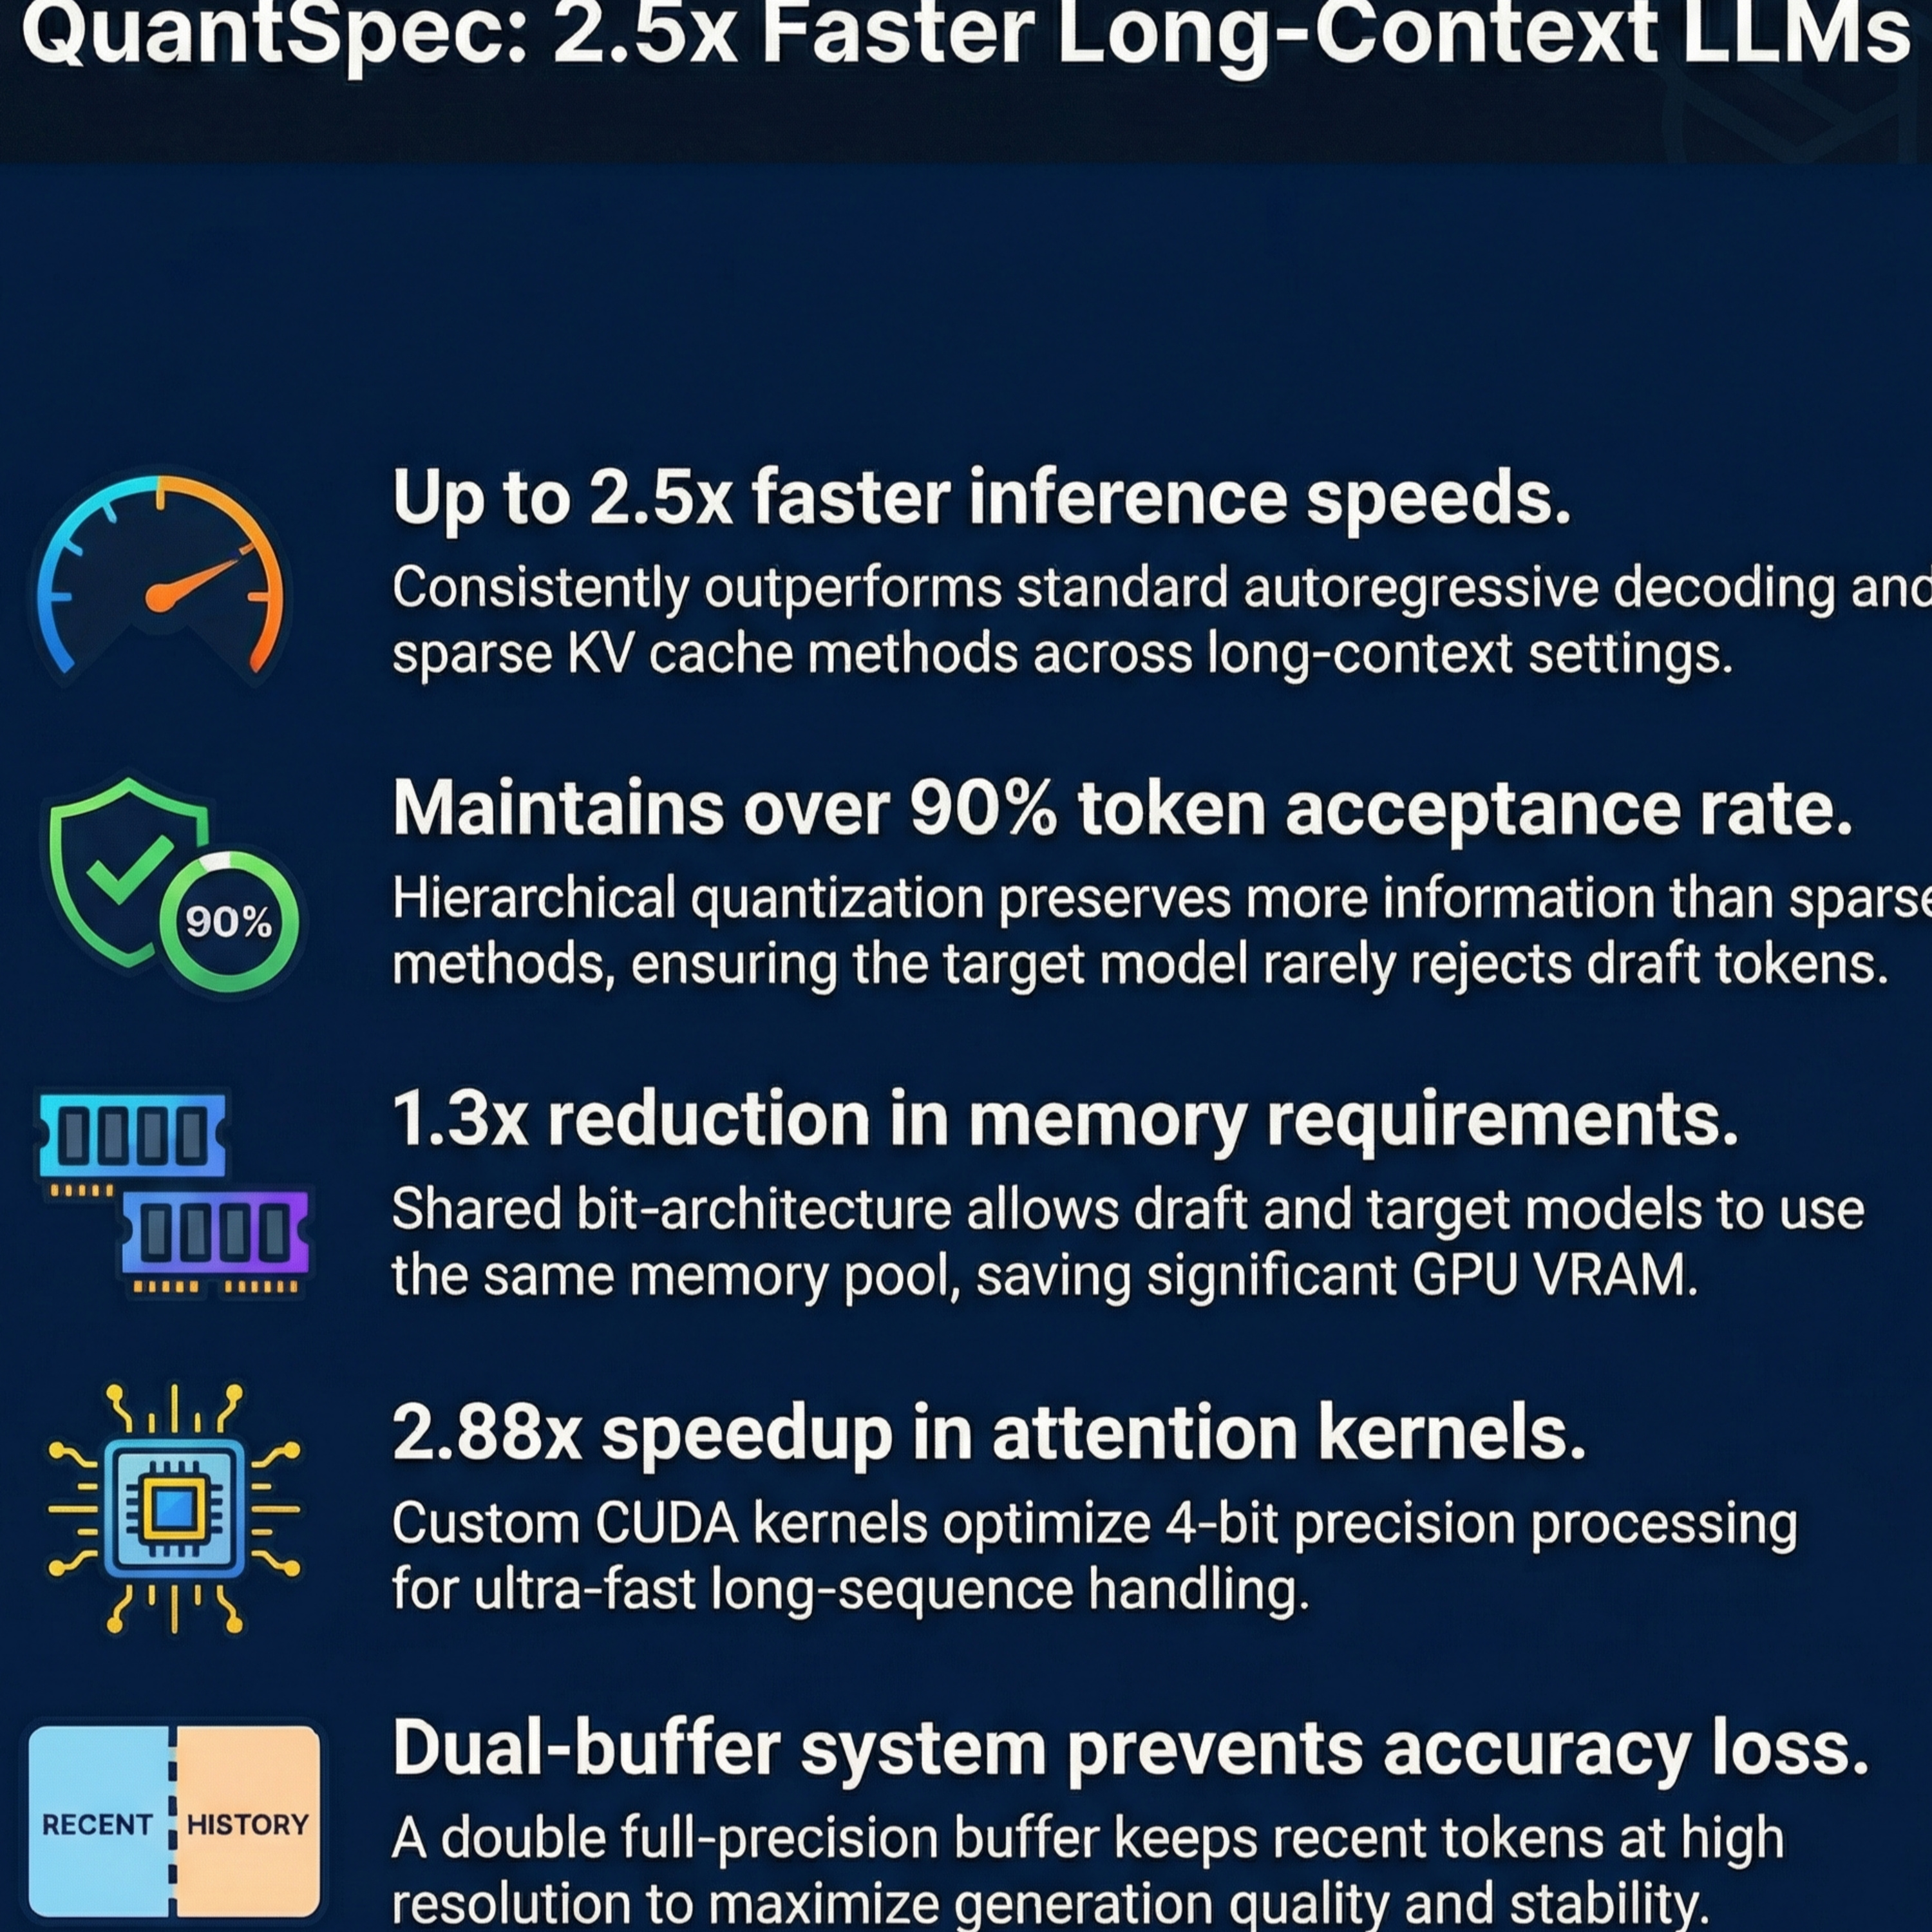
QuantSpec: Hierarchical KV Cache for Self-Speculative Decoding — AI ...

整合 Speculative Decoding 和 KV Cache 之實作筆記 - Clay-Technology World

Optimizing LLM Inference: KV Cache Quantization and Speculative ...
LLM 인퍼런스 속도를 2~5배 높이는 법 — Speculative Decoding과 KV Cache 최적화 실전 가이드 ...
LLM 인퍼런스 속도를 2~5배 높이는 법 — Speculative Decoding과 KV Cache 최적화 실전 가이드 ...
Speculative KV Coding Achieves 4× Lossless Compression of LLM Cache ...
Boost LLM Inference: Optimize Speculative Decoding, Batching, KV Cache ...

Entropy-Aware Speculative Decoding Toward Improved LLM Reasoning | AI ...
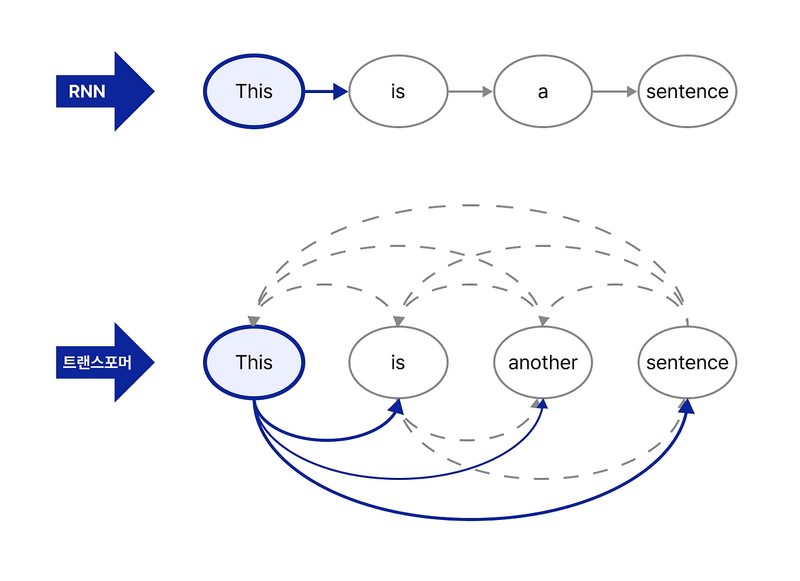
LLM 인퍼런스 속도를 2~5배 높이는 법 — Speculative Decoding과 KV Cache 최적화 실전 가이드 ...
Advertisement Space (300x250)

G-KV: Decoding-Time KV Cache Eviction with Global Attention | AI ...

Revolutionizing AI Efficiency: Breakthroughs in KV Cache Compression ...

Revolutionizing AI Efficiency: Breakthroughs in KV Cache Compression ...
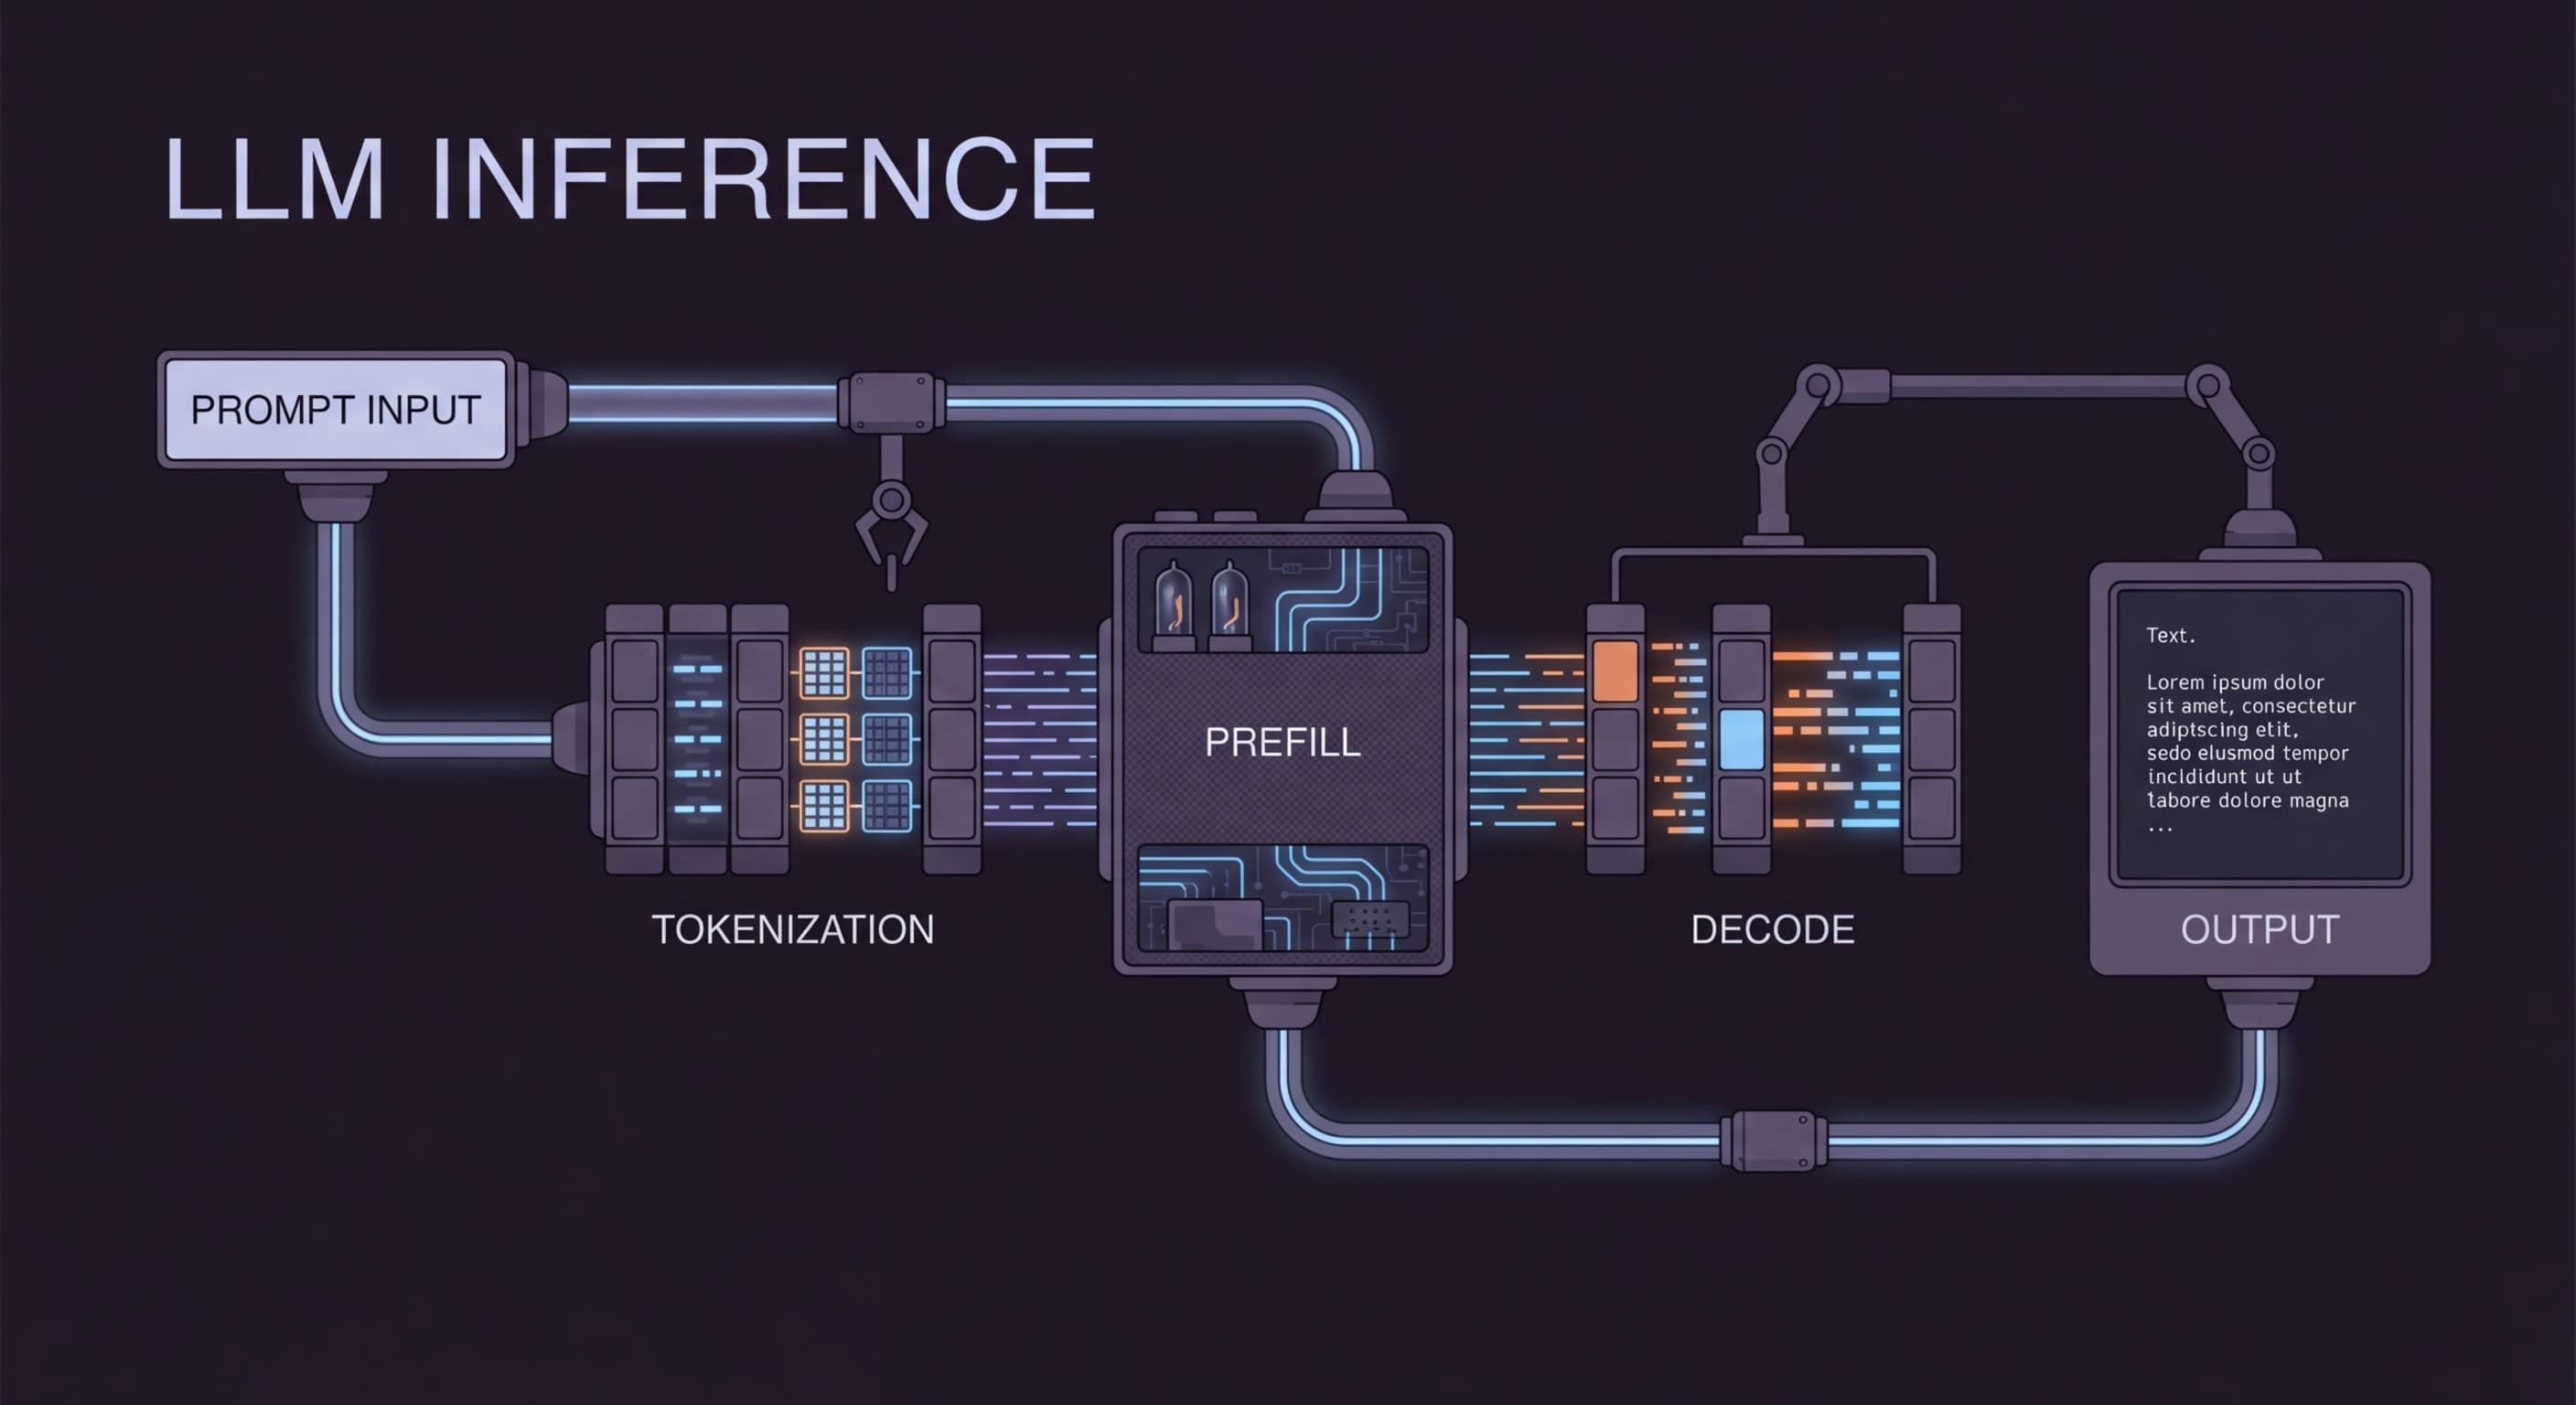
LLM Inference: Prefill, Decode, KV Cache & Cost Guide (2026) | Morph
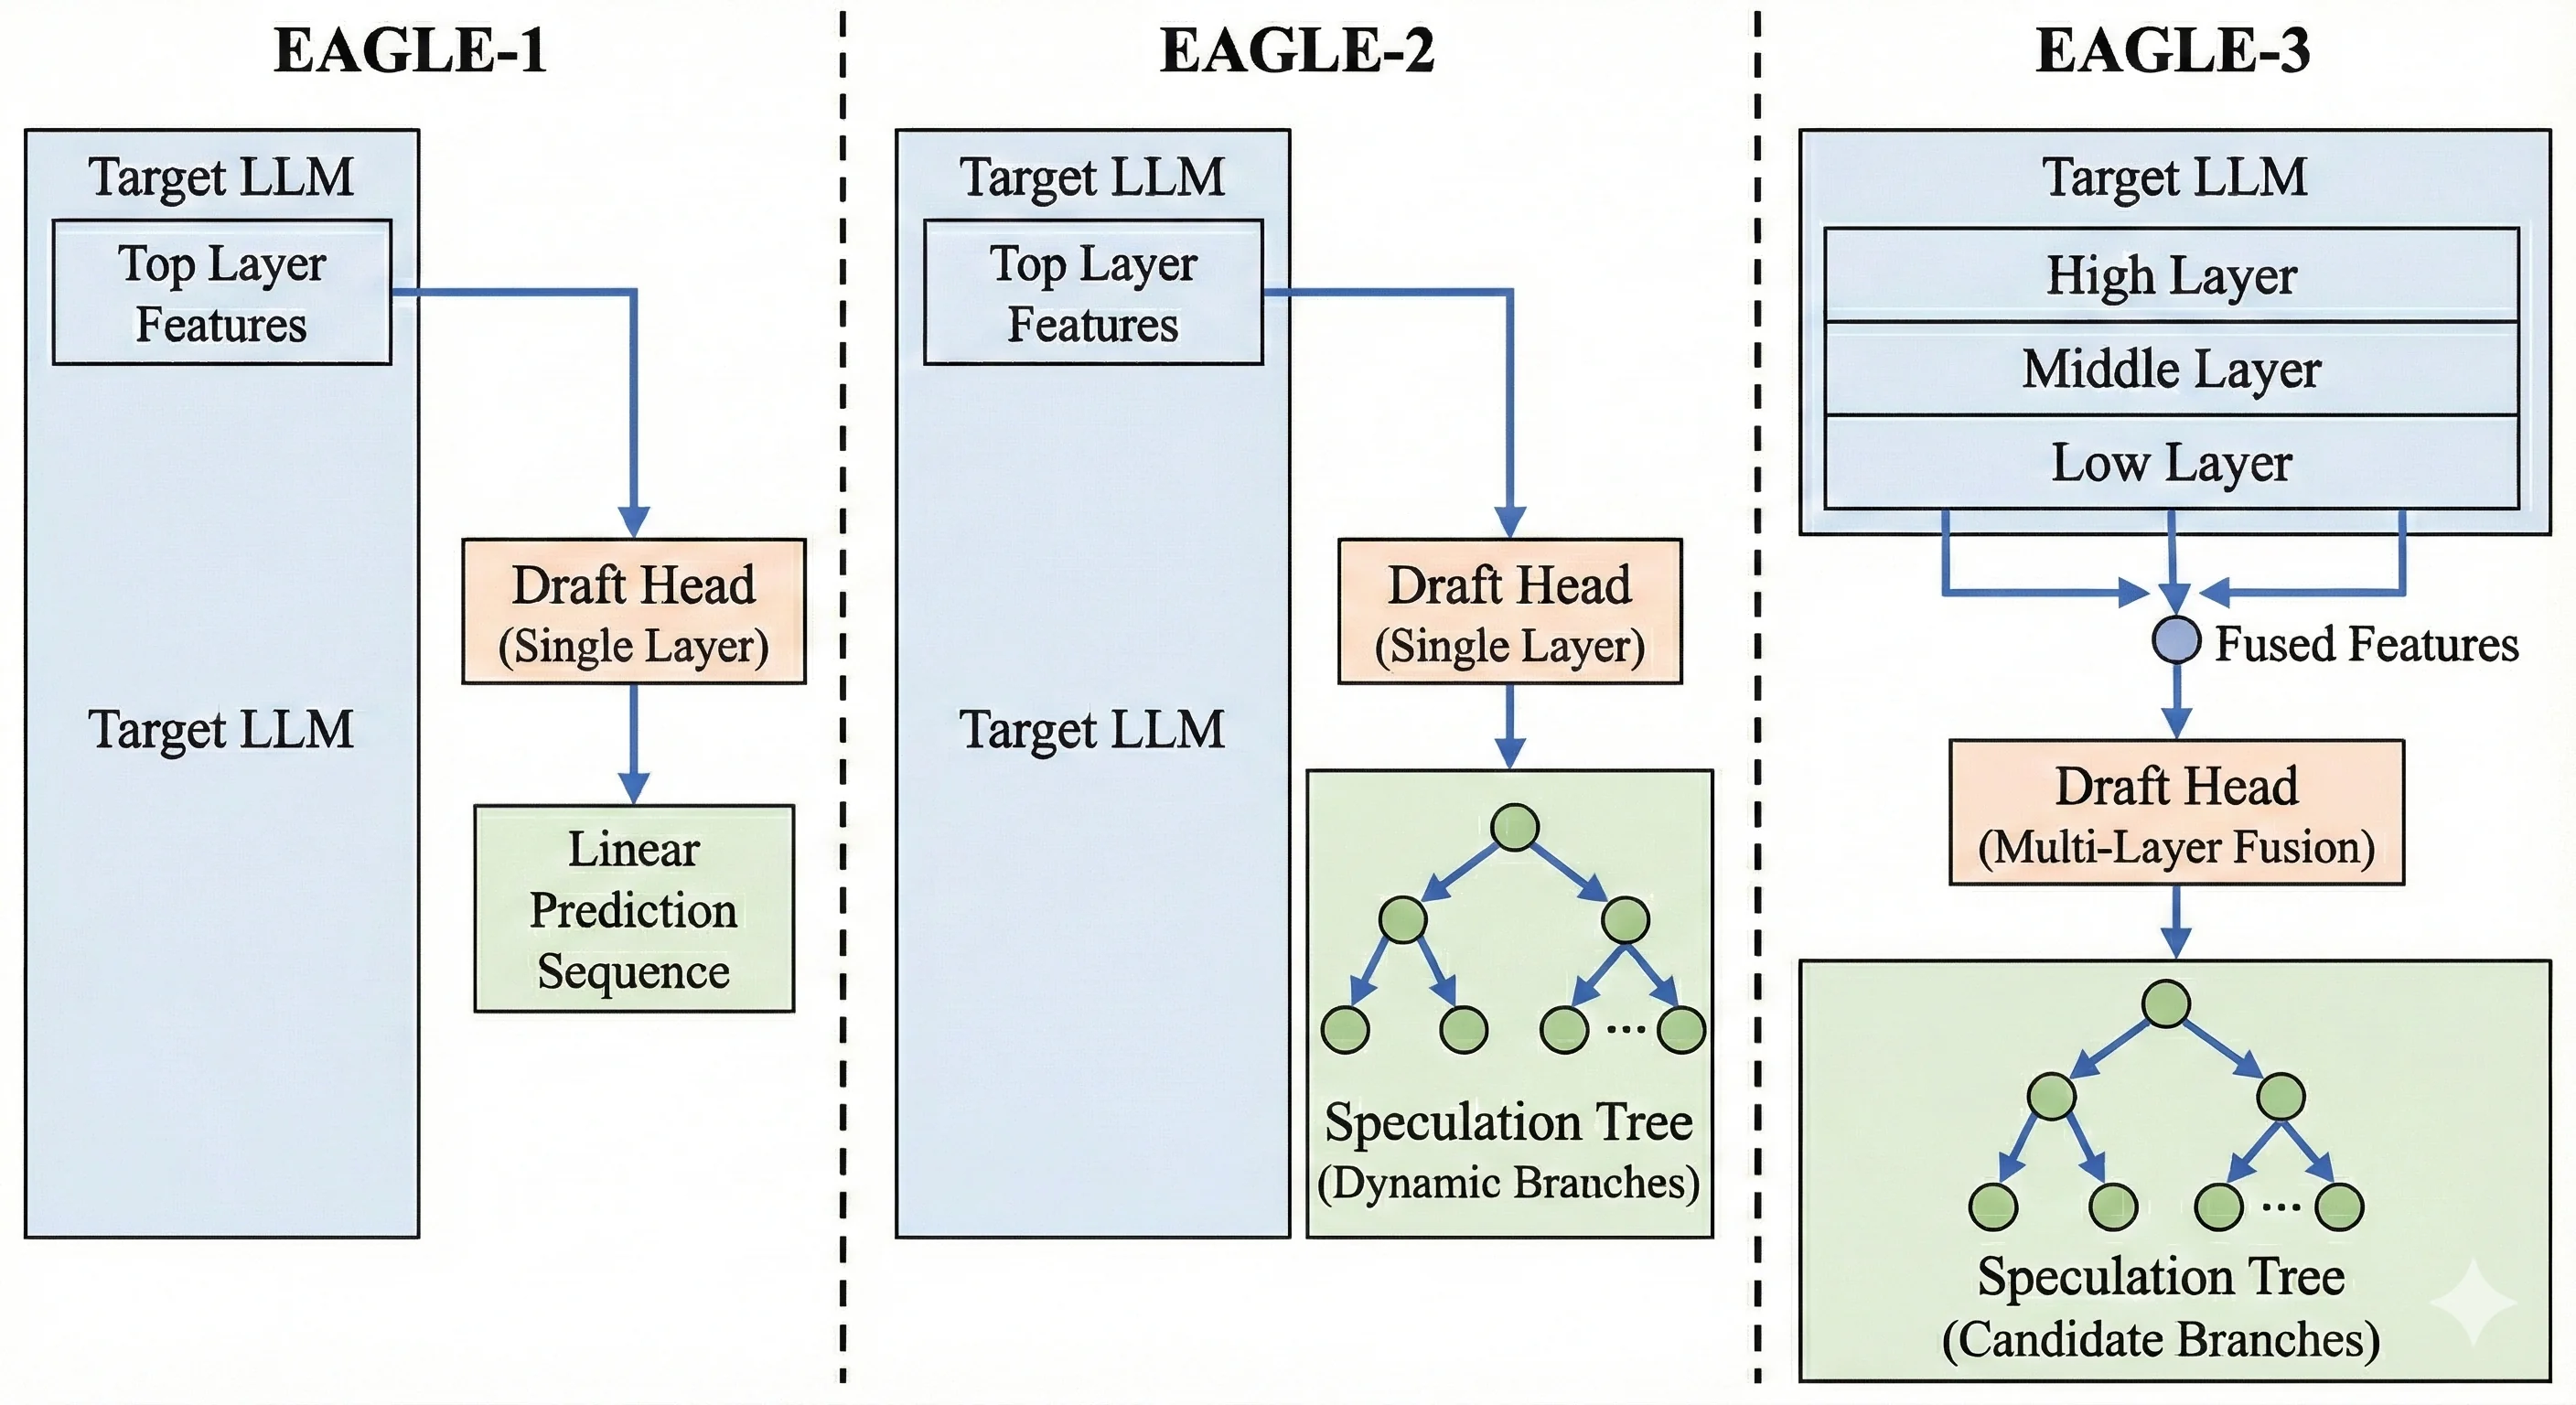
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
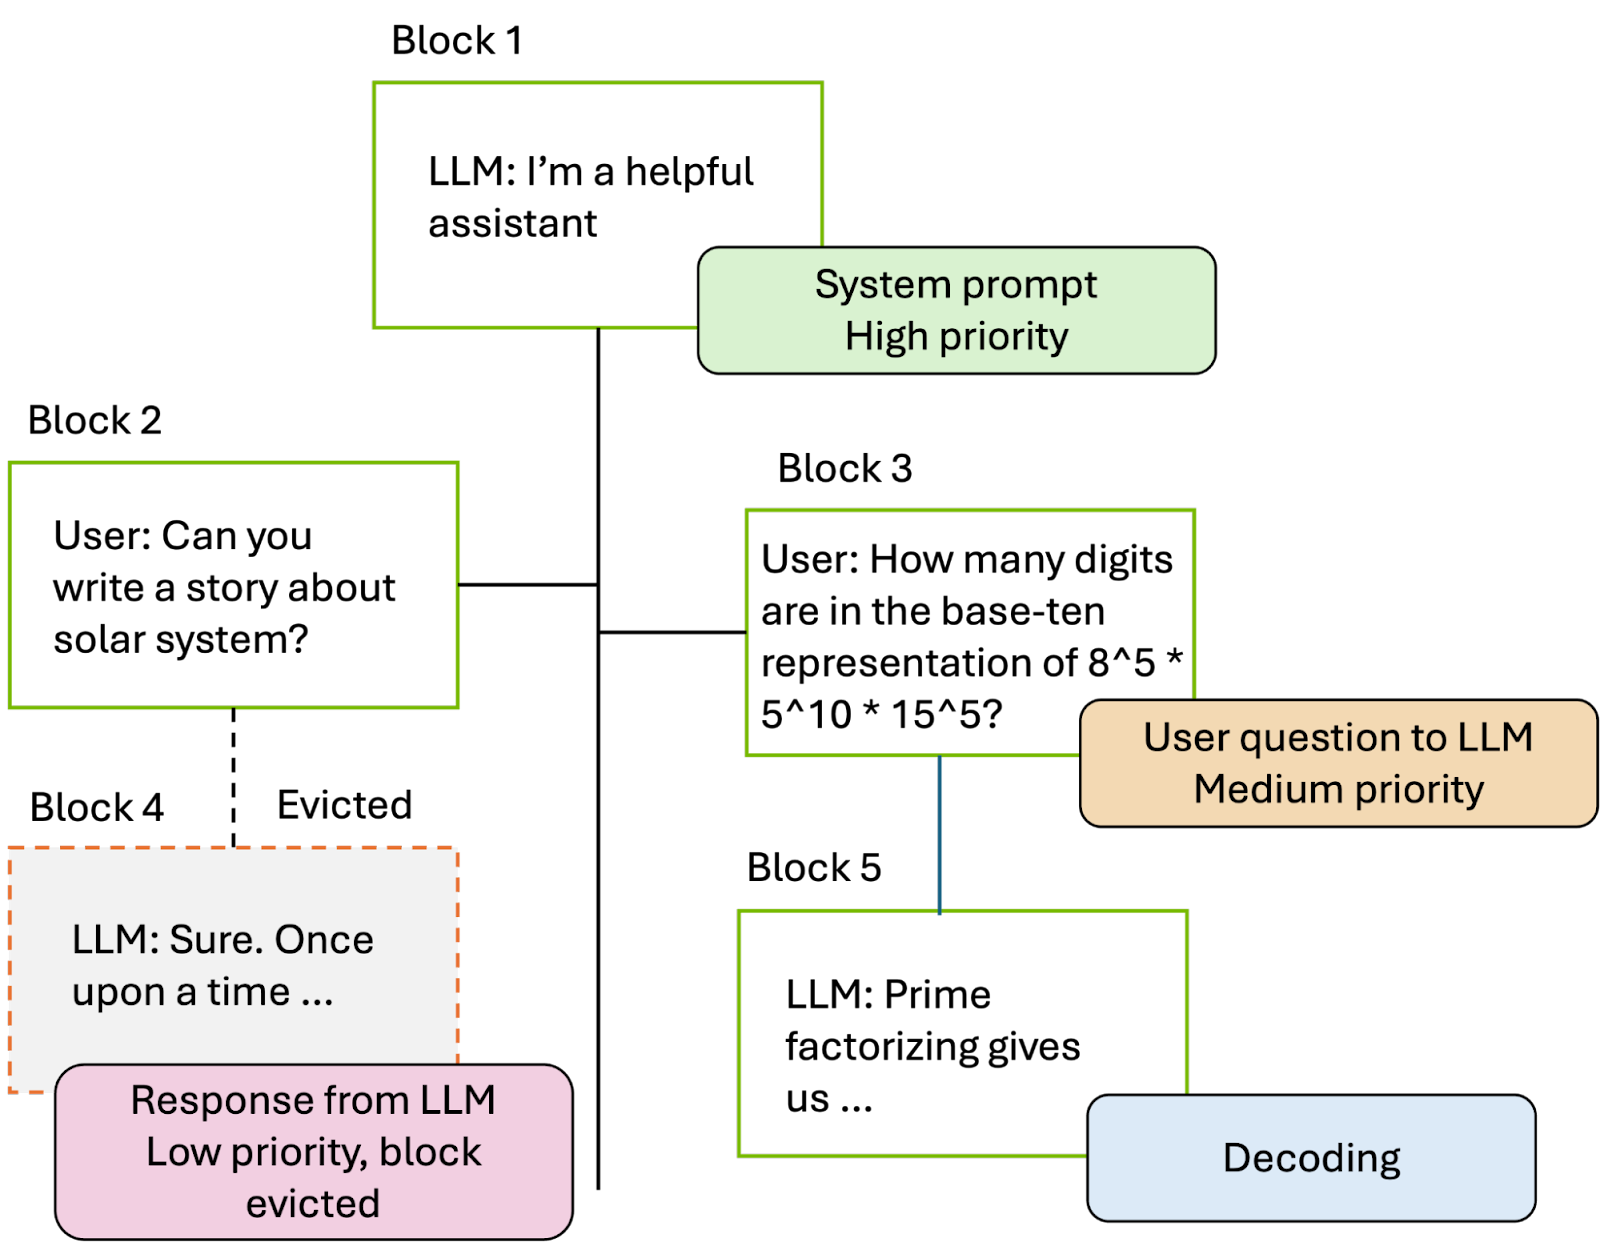
KV Caching and Speculative Decoding
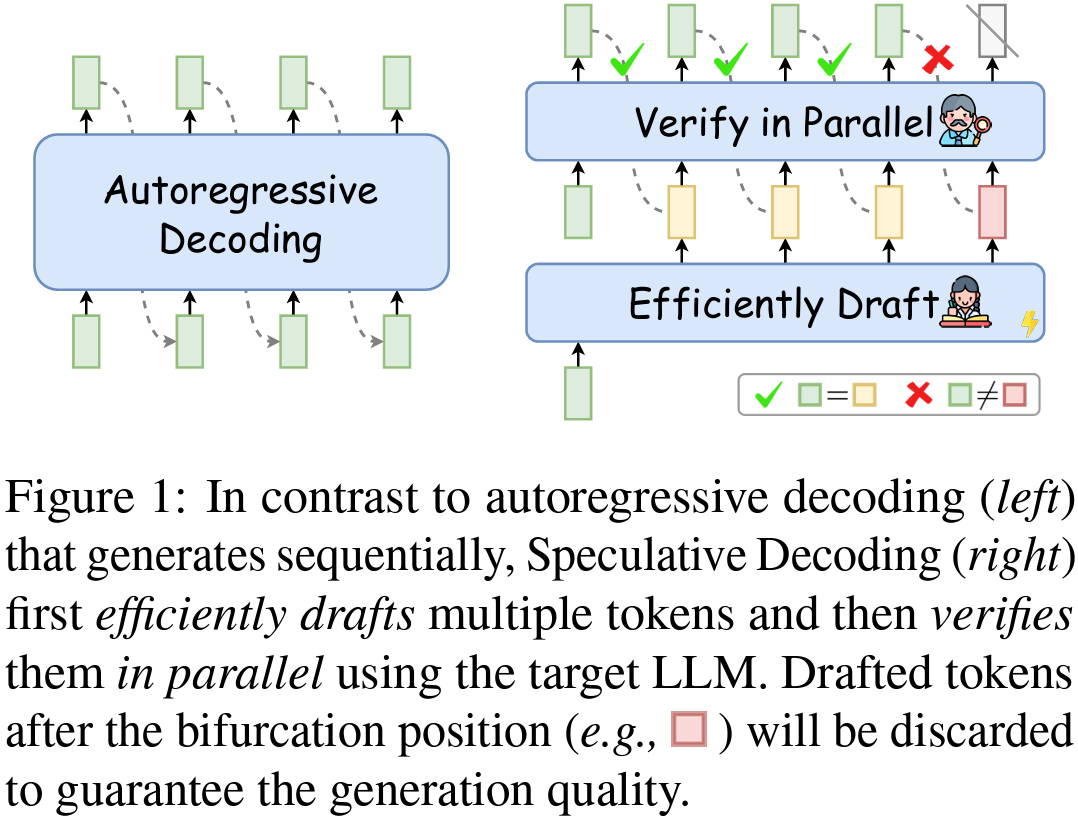
This AI Paper Unveils the Potential of Speculative Decoding for Faster ...
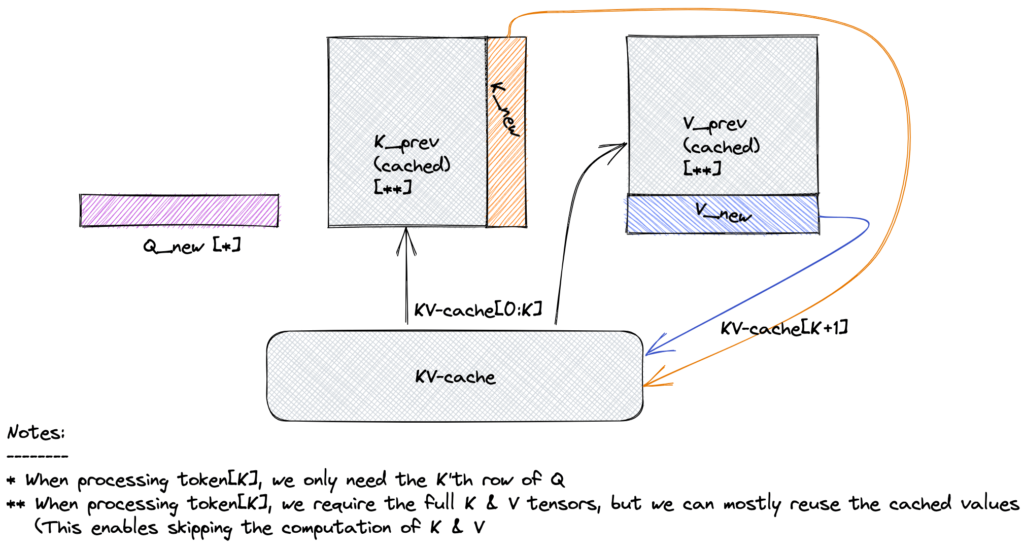
KV Cache in Transformer Models - Data Magic AI Blog

Boosting LLM Inference Speed Using Speculative Decoding | Towards Data ...
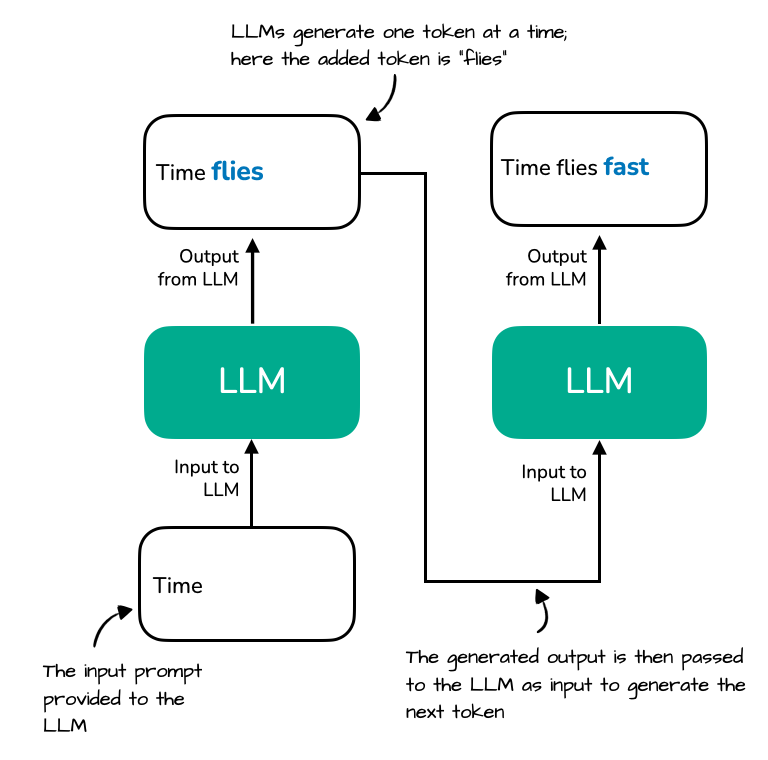
KV Caching and Speculative Decoding
Advertisement Space (336x280)
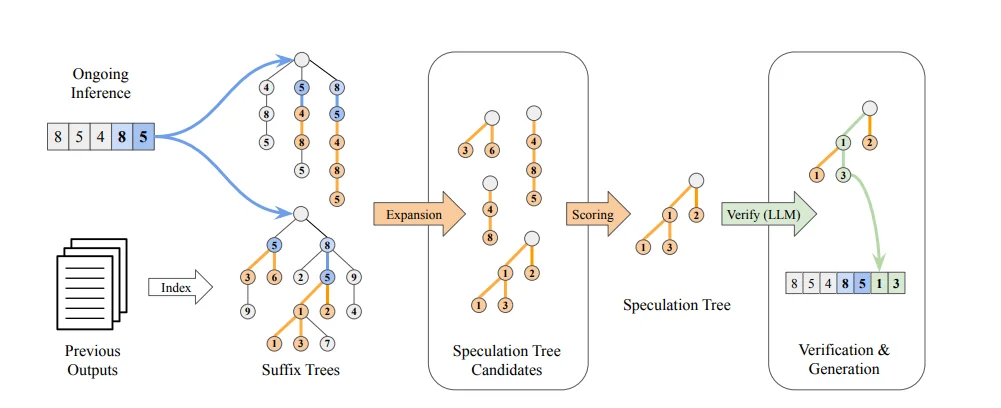
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
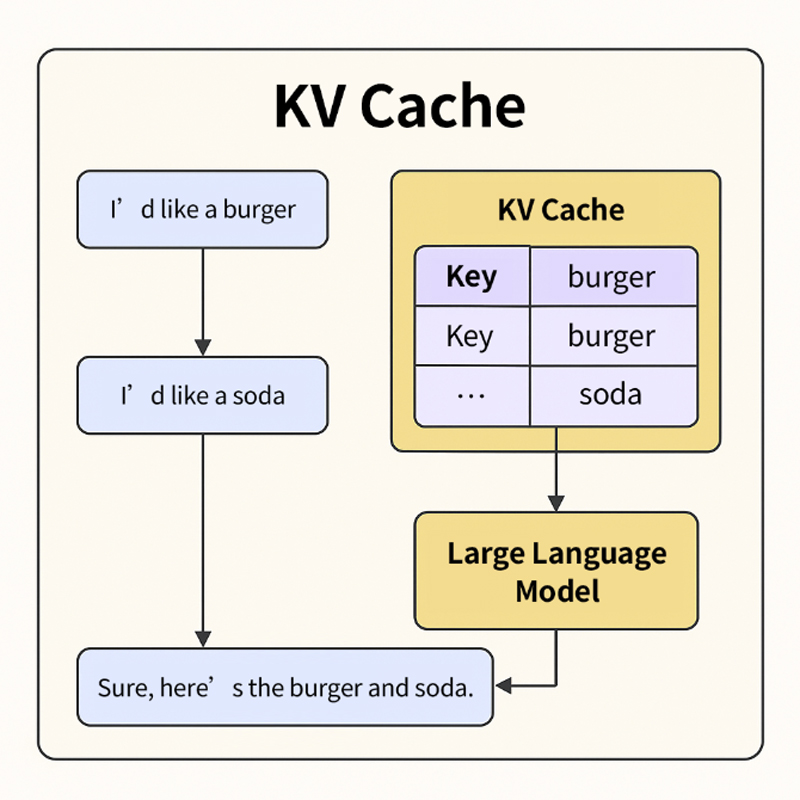
KV Cache Meets NVMe: The Key to Accelerating LLM Inference
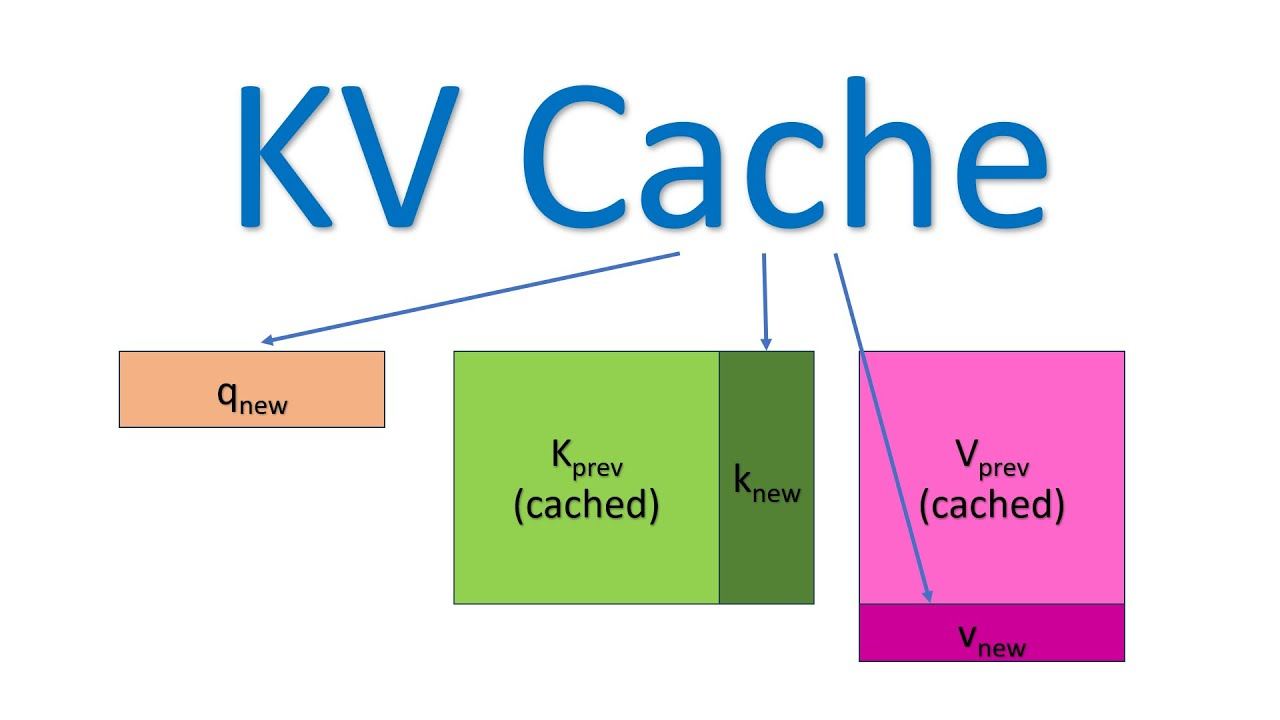
KV Cache 详解:新手也能理解的 LLM 推理加速技巧-CSDN博客
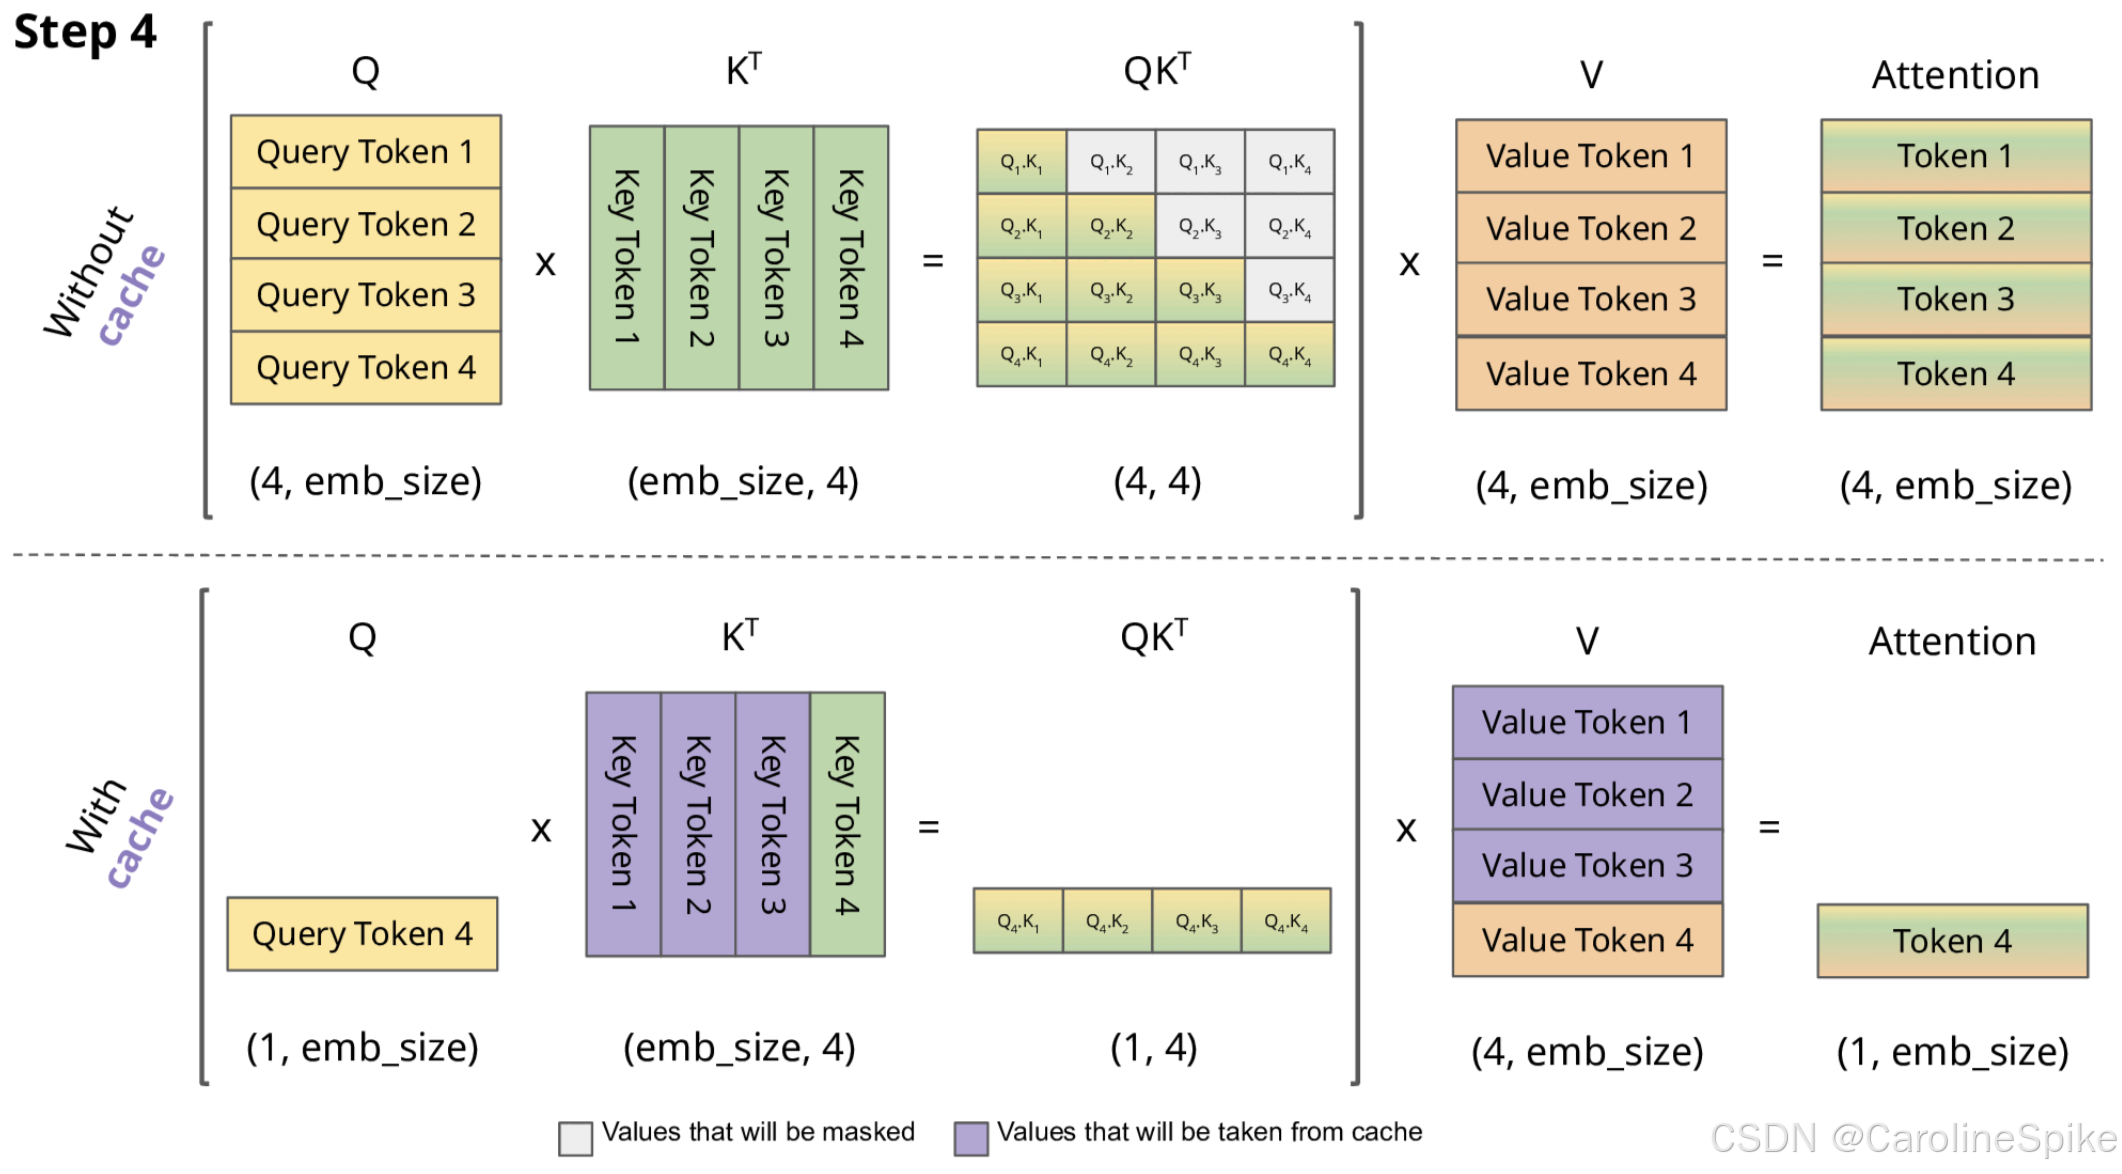
LLM - GPT(Decoder Only) 类模型的 KV Cache 公式与原理 教程_大模型 (LLM)-CSDN专栏
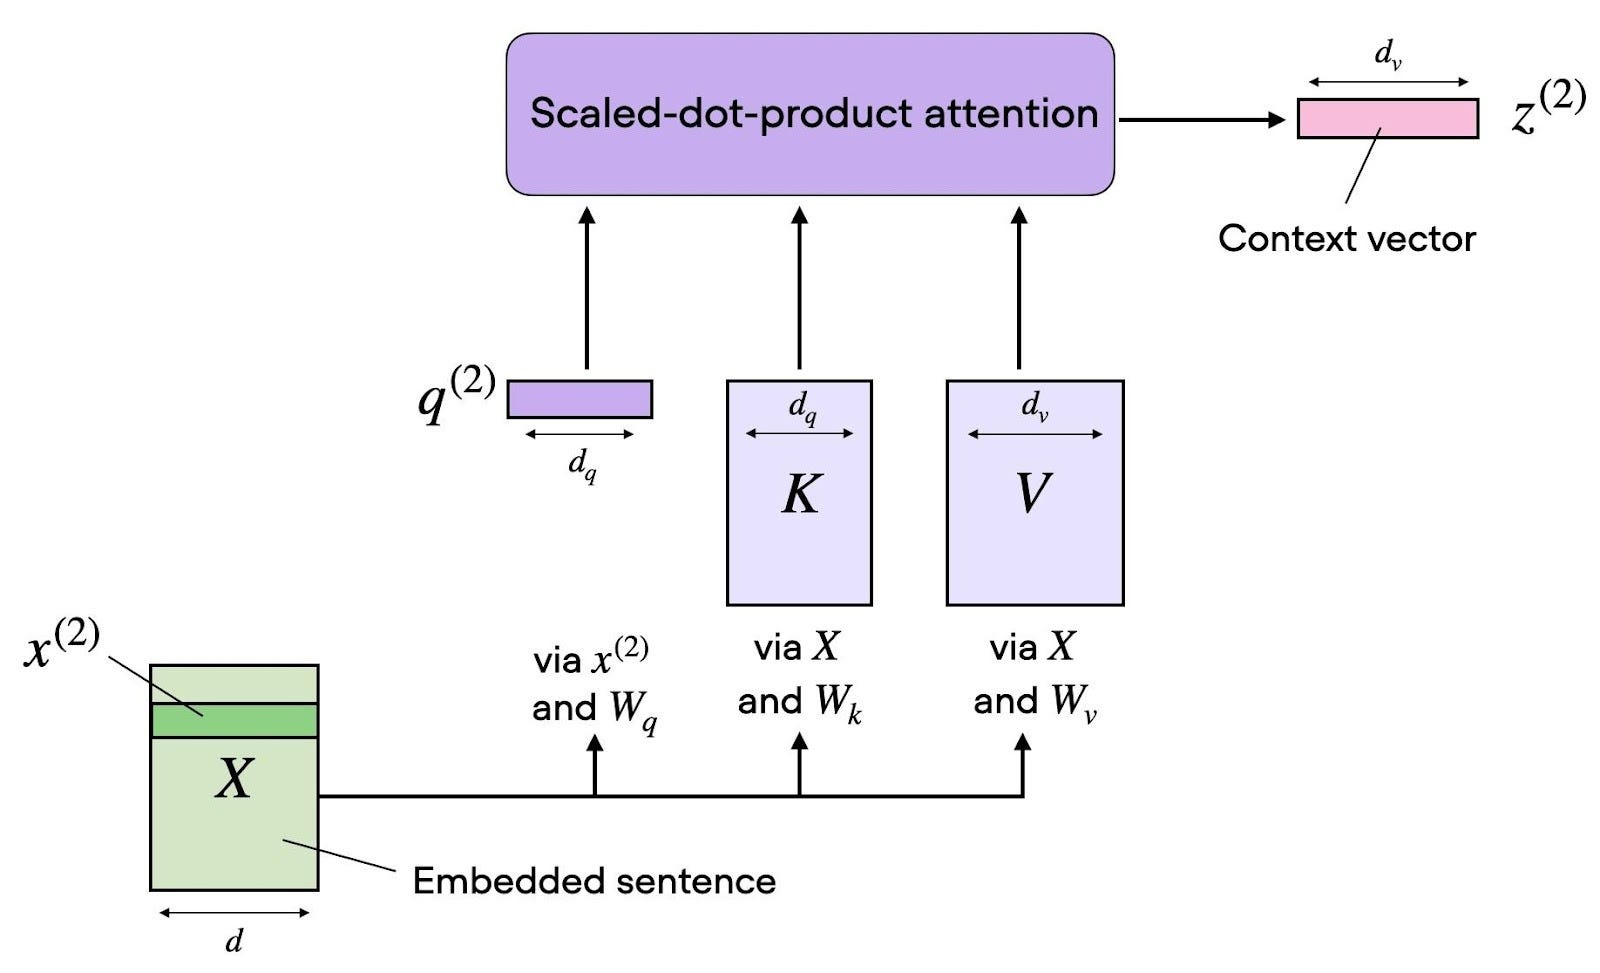
KV Caching and Speculative Decoding
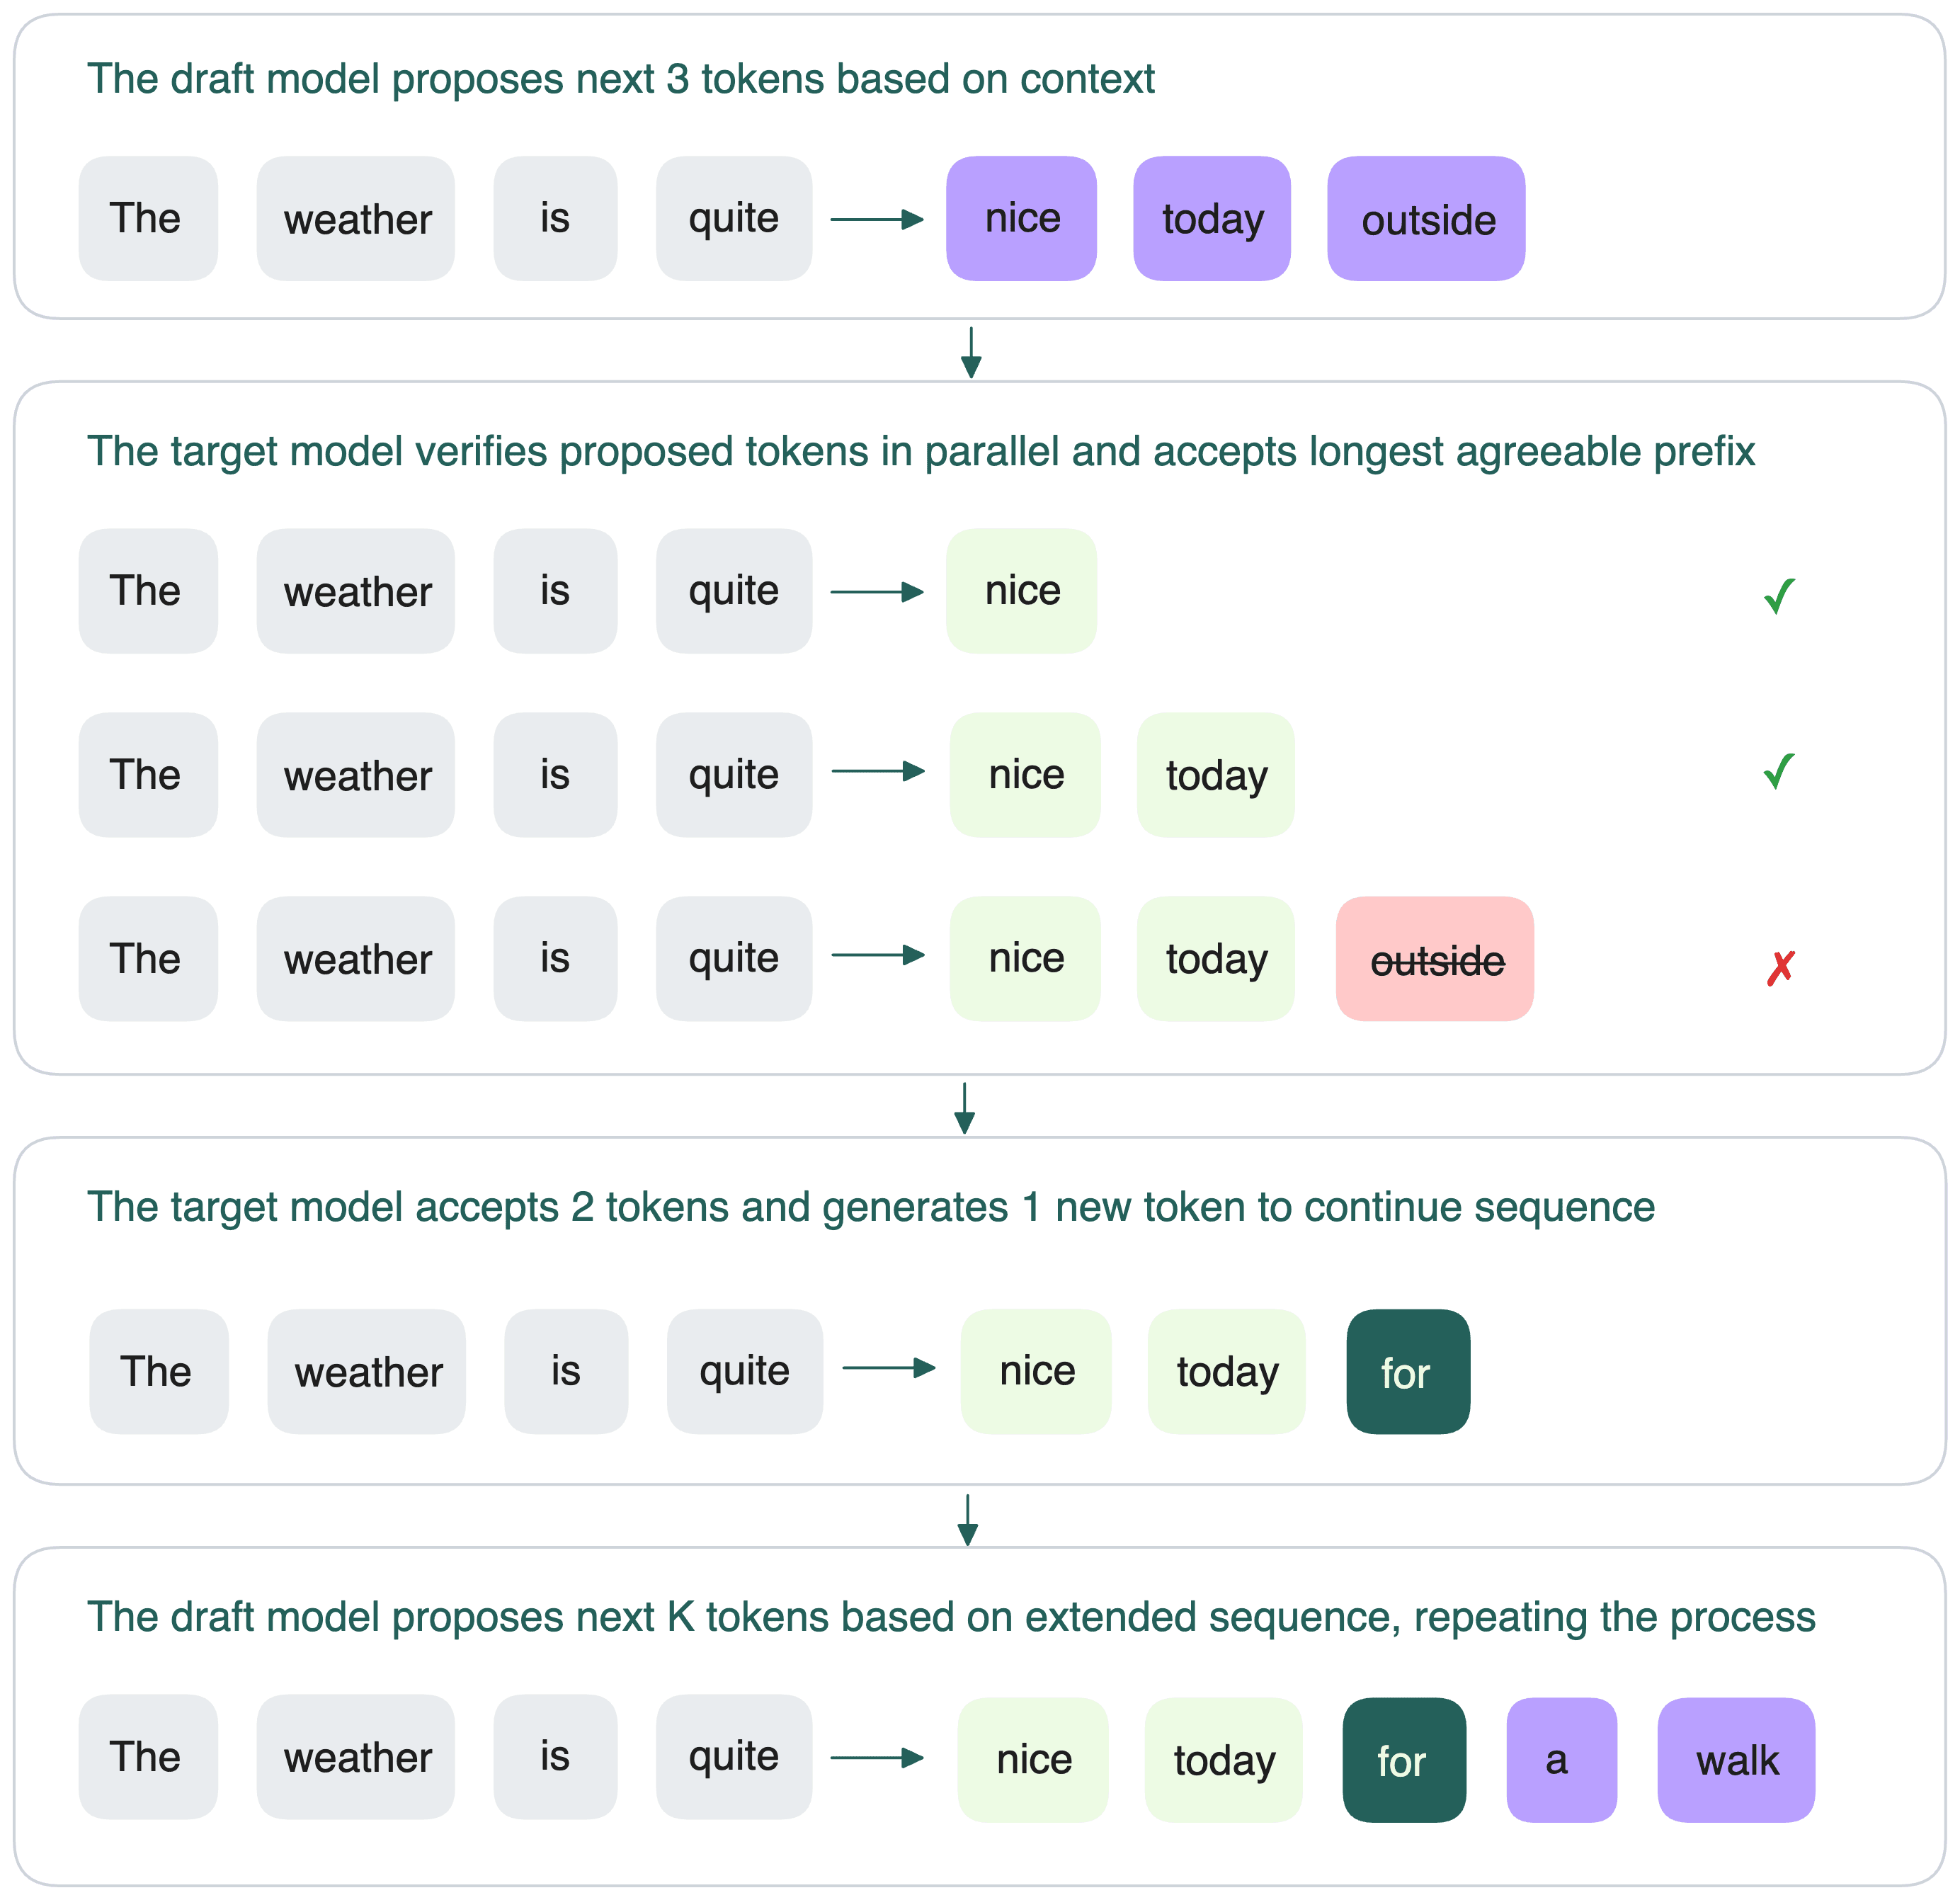
Get 3× Faster LLM Inference with Speculative Decoding Using the Right ...
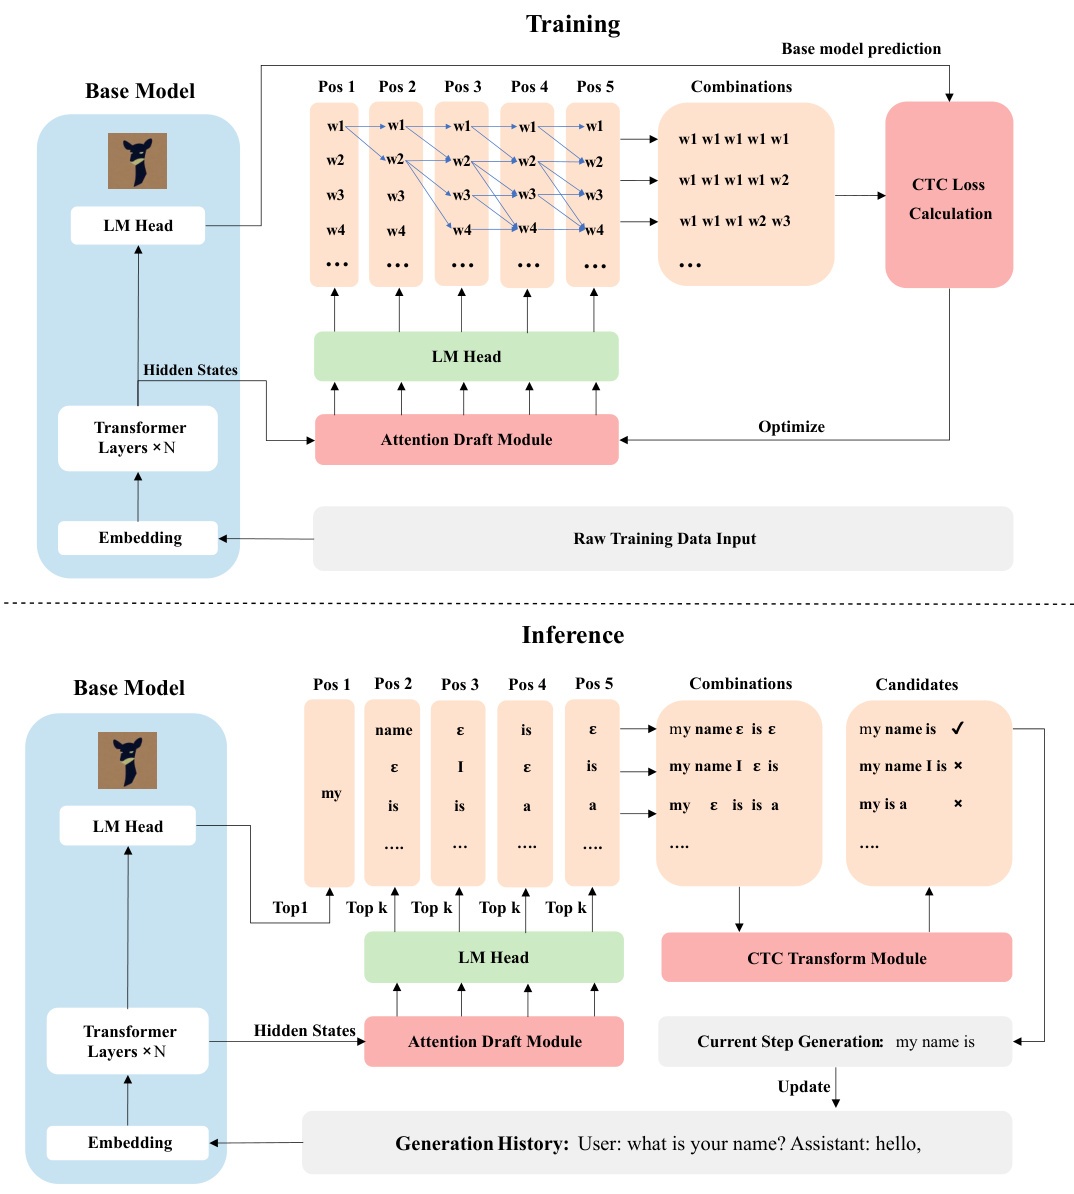
Speculative Decoding with CTC-based Draft Model for LLM Inference ...

Scaling Multi-Turn LLM Inference with KV Cache Storage Offload and Dell ...
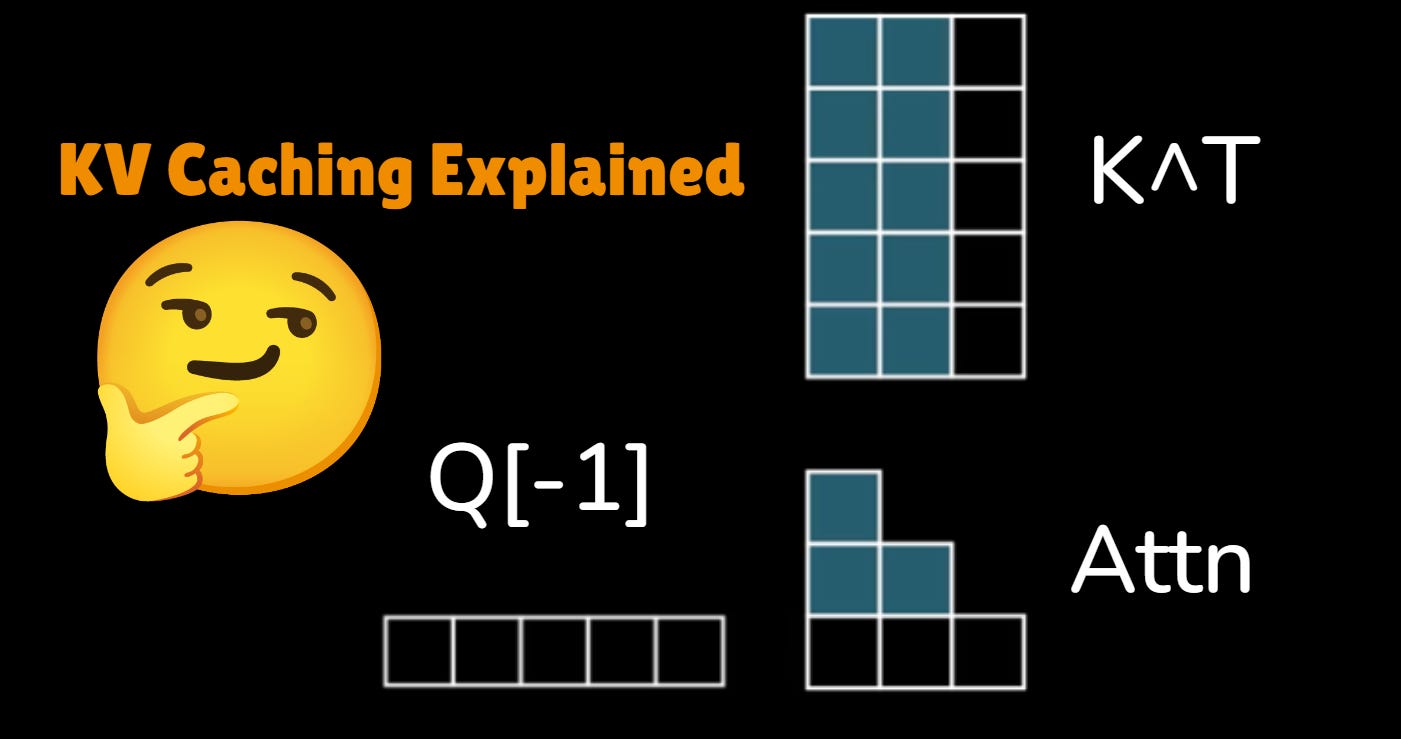
KV Caching and Speculative Decoding
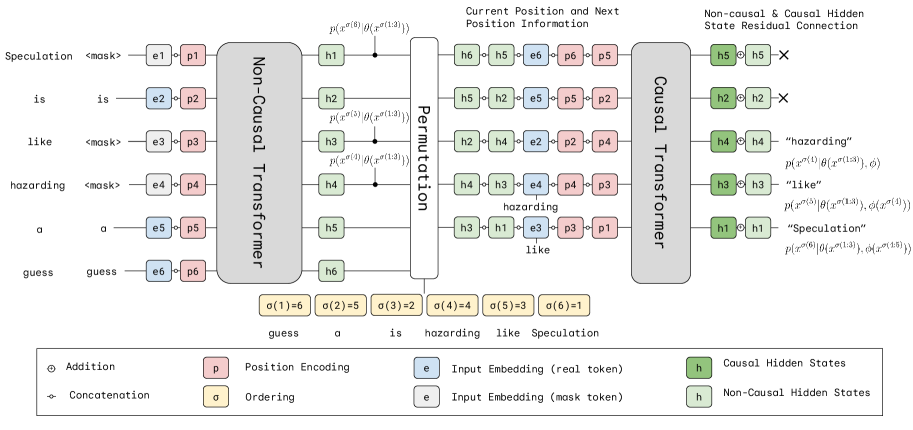
Speculative decoding | AI Research Papers
Advertisement Space (336x280)

Accelerating LLM Inference with Speculative Decoding Using OpenVINO ...
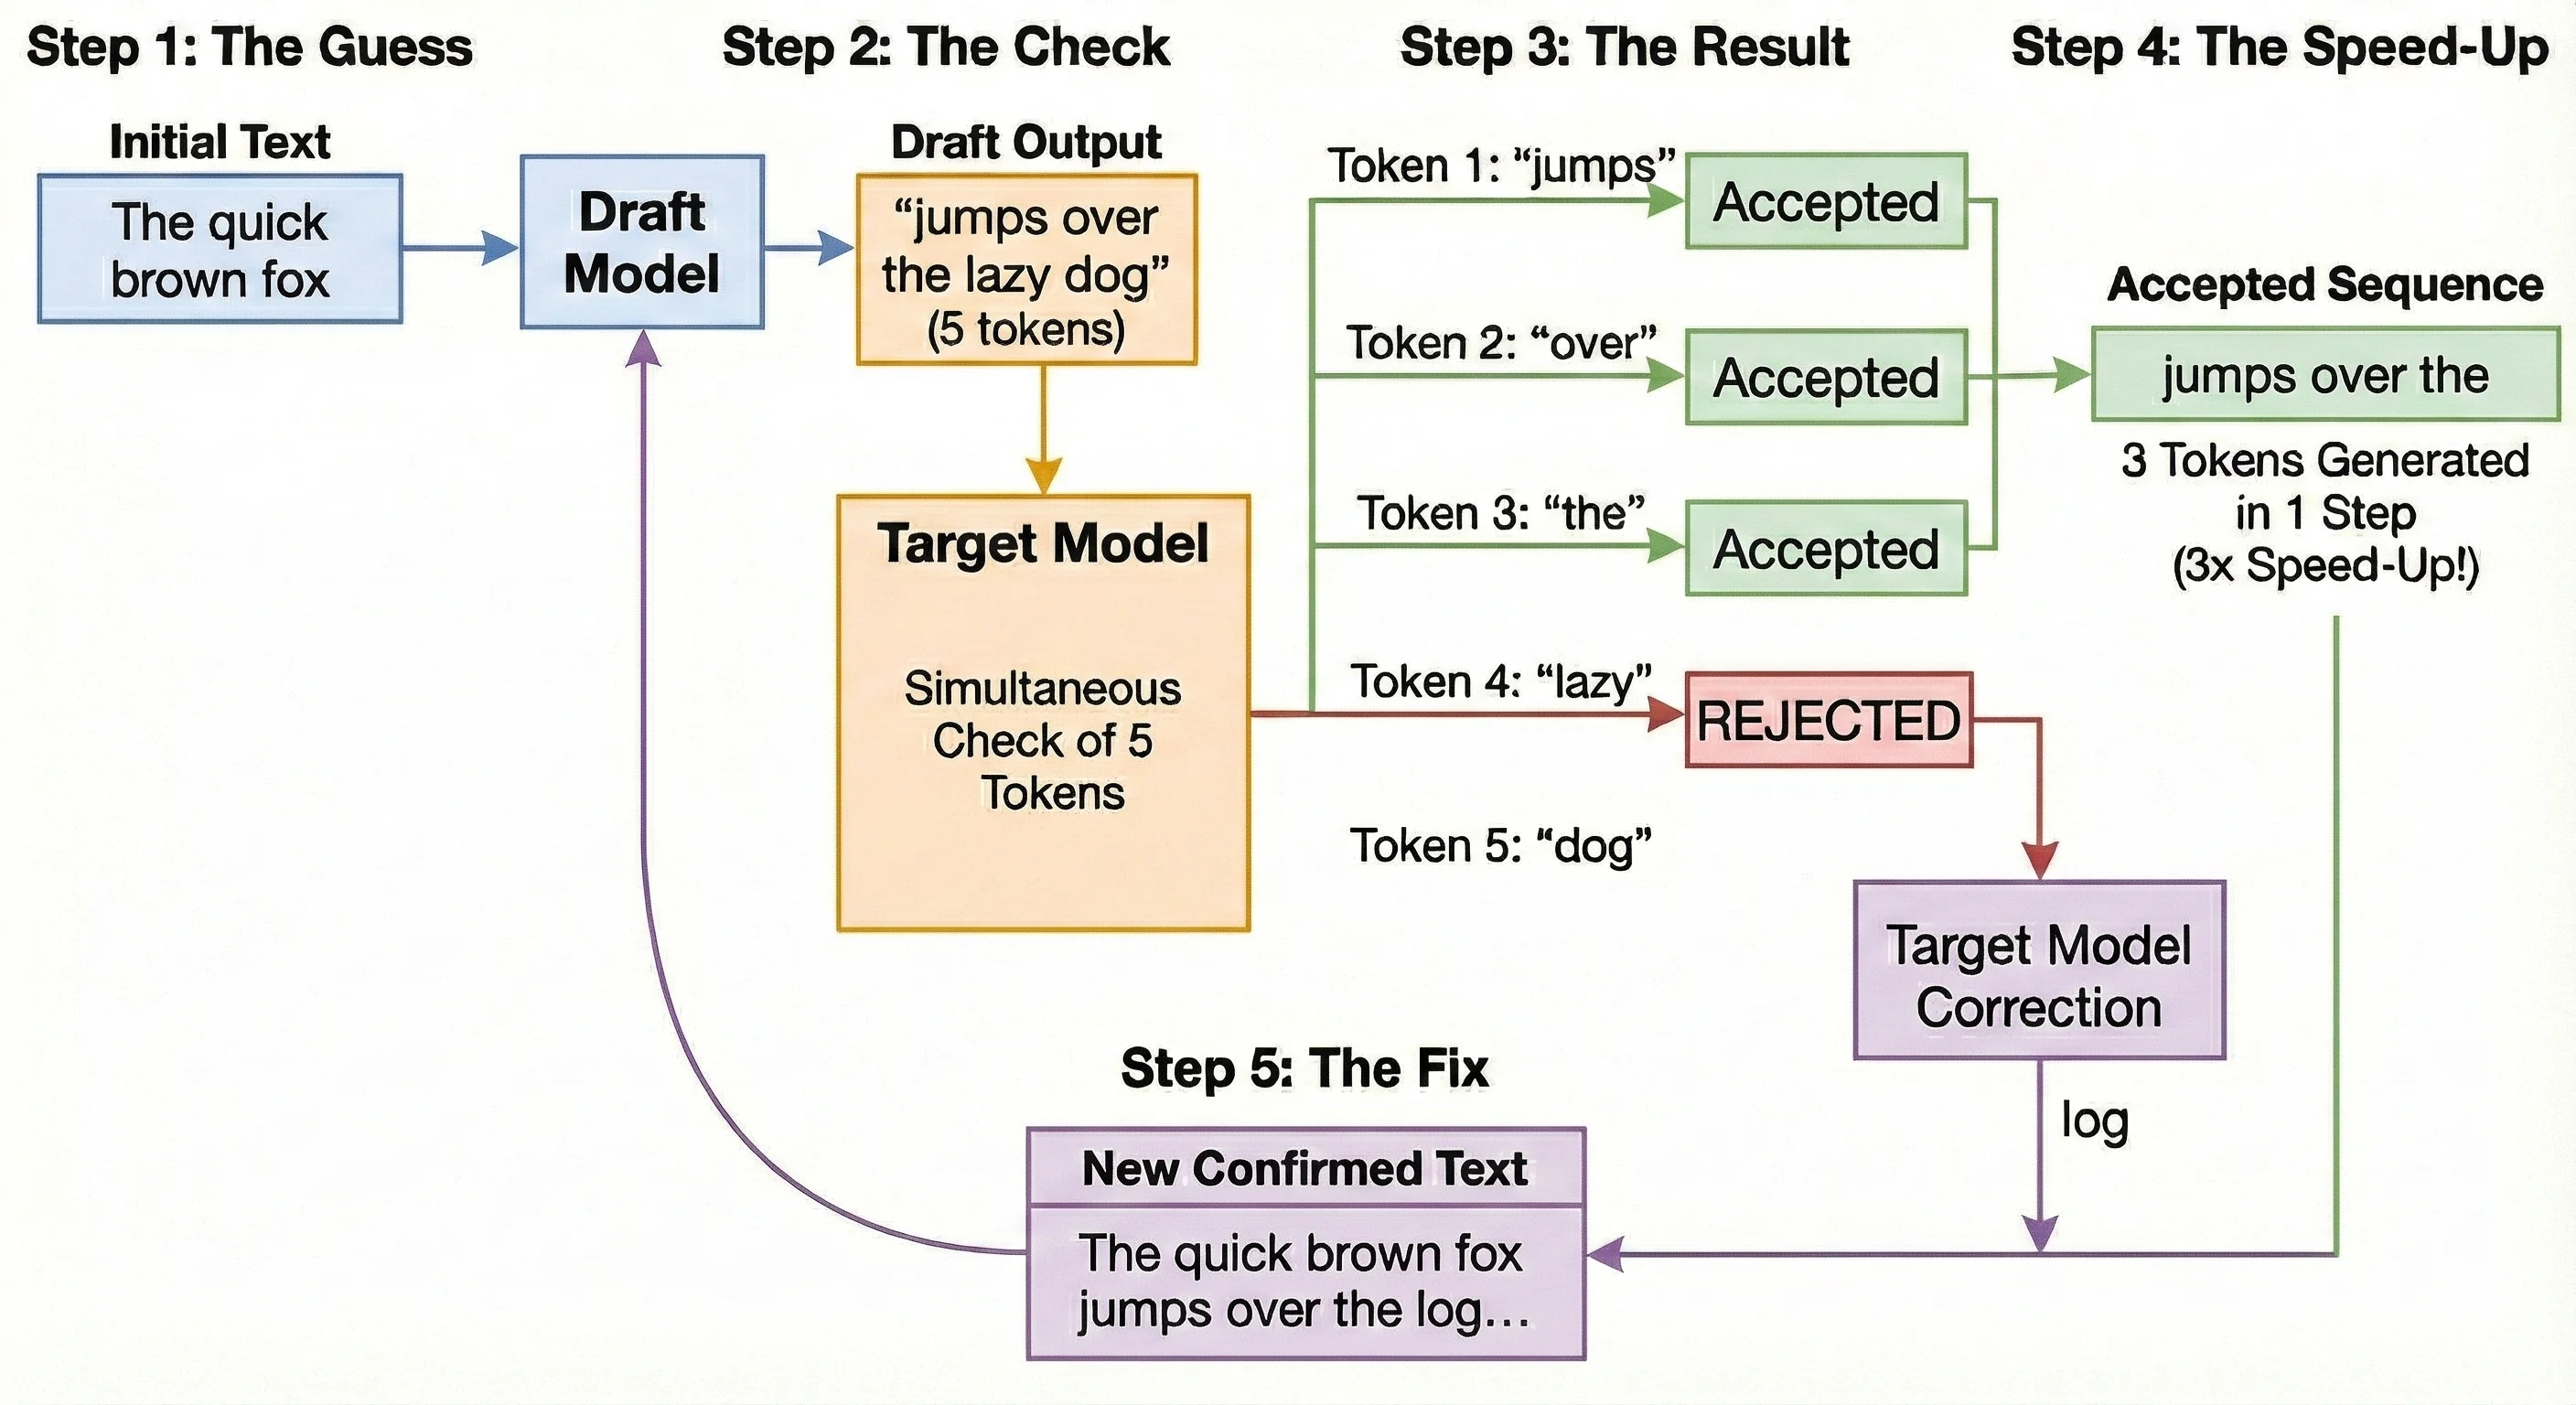
Speculative Decoding in vLLM: Complete Guide to Faster LLM Inference ...
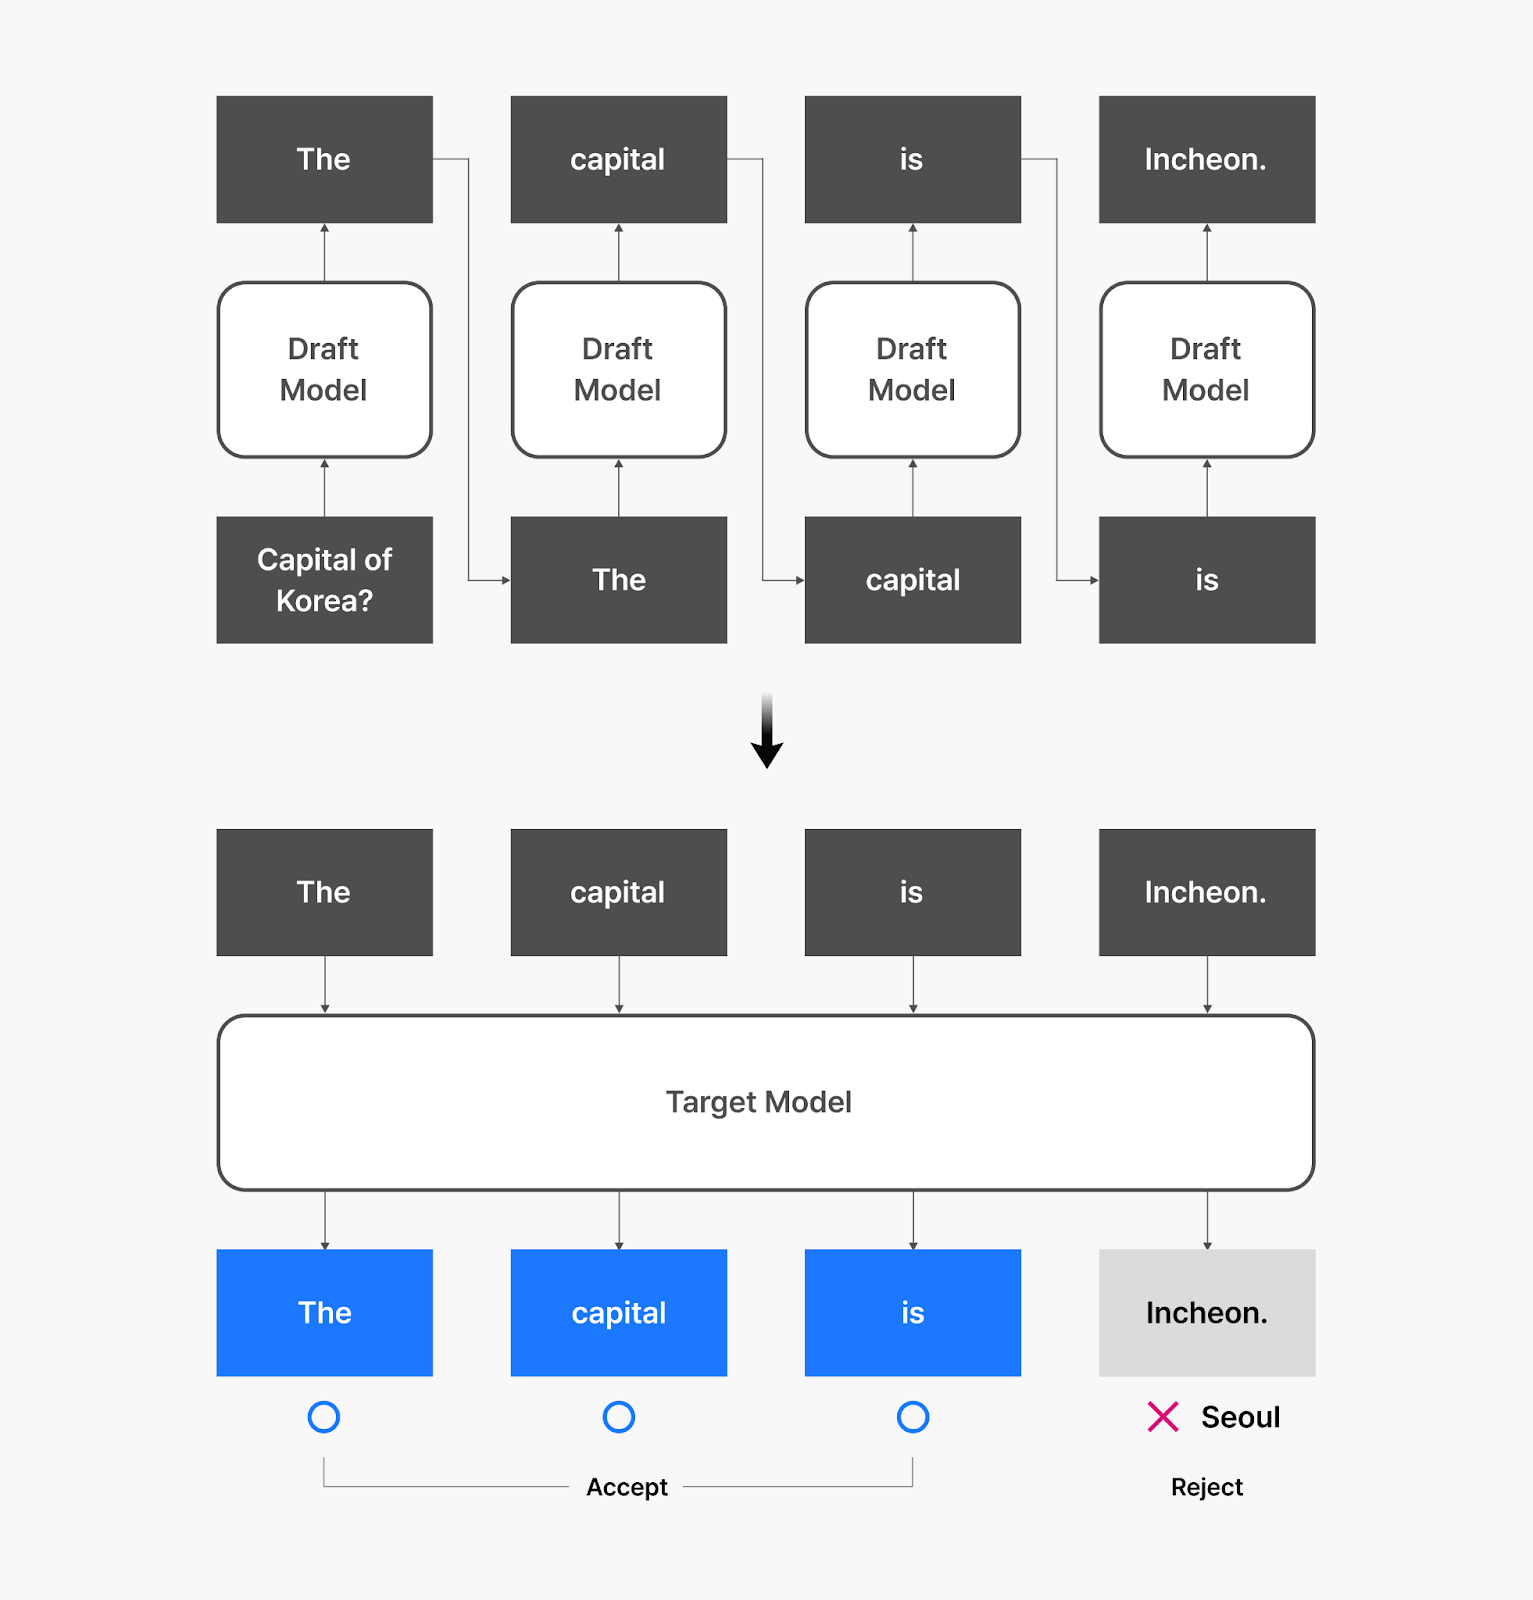
KV Caching and Speculative Decoding
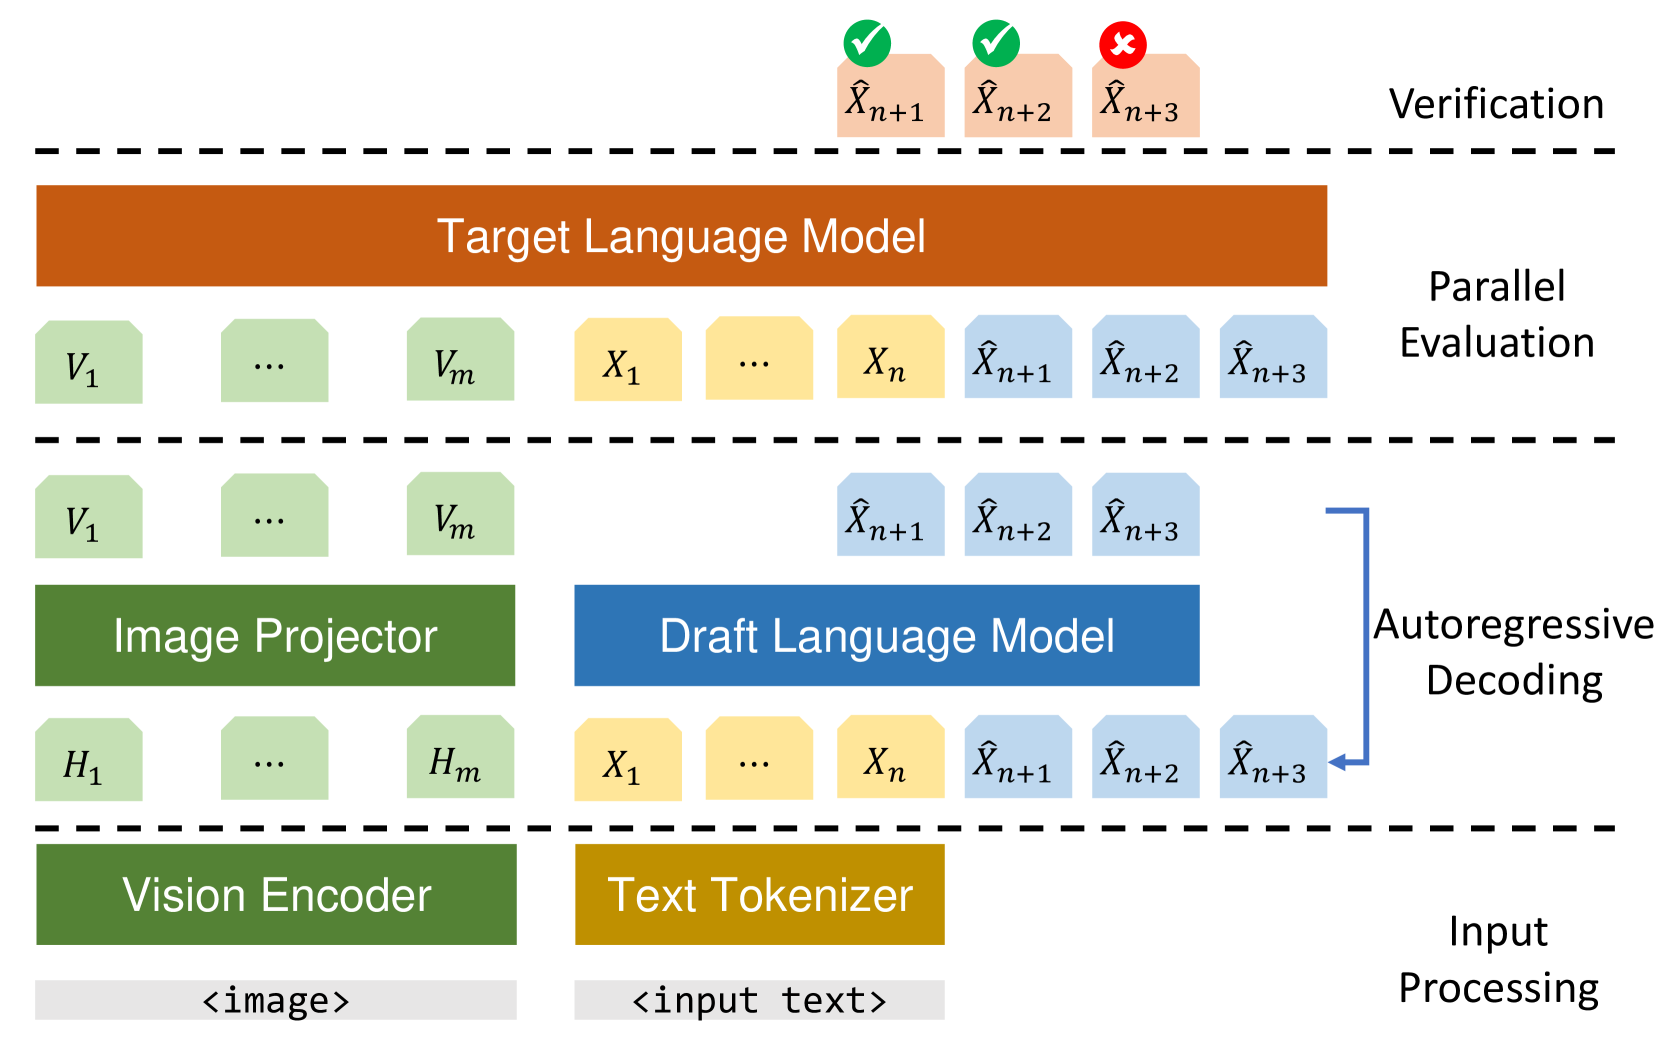
SpecExec: Massively Parallel Speculative Decoding for Interactive LLM ...

Aman's AI Journal • Primers • Speculative Decoding