
Multi Head Latent Attention And Multi Token Prediction In Deepseek V3

Multi-Head Latent Attention and Multi-token Prediction in Deepseek v3
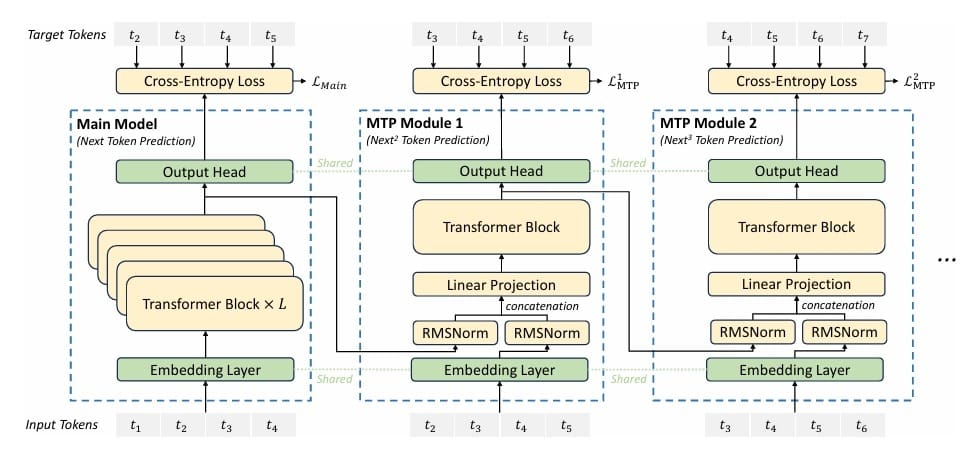
Autoregressive Model Limits and Multi-Token Prediction in DeepSeek-V3 ...

Inside DeepSeek V3: Breaking Down Multi-Head Latent Attention (MLA ...

Three Interpretations of DeepSeek V2's Multi-headed Latent Attention Layer

DeepSeek Multihead Latent Attention - YouTube

Three Interpretations of DeepSeek V2's Multi-headed Latent Attention Layer

DeepSeek + SGLang: Multi-Head Latent Attention

Multilingual Capabilities of DeepSeek v3 in AI Applications

Advancements in Machine Learning with DeepSeek v3

Multilingual Capabilities of DeepSeek v3 in AI Applications
Advertisement Space (300x250)
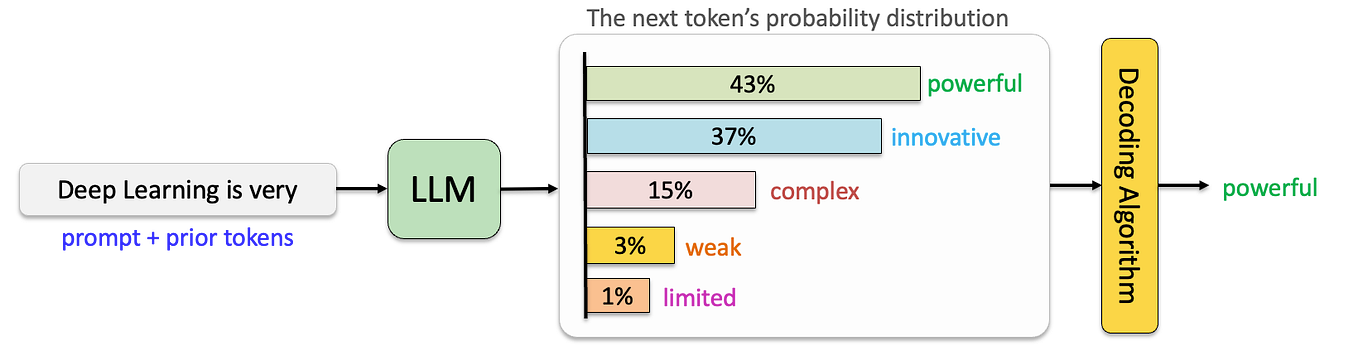
DeepSeek-V3 — Advances in MoE Load Balancing and Multi-Token Prediction ...

DeepSeek + SGLang: Multi-Head Latent Attention
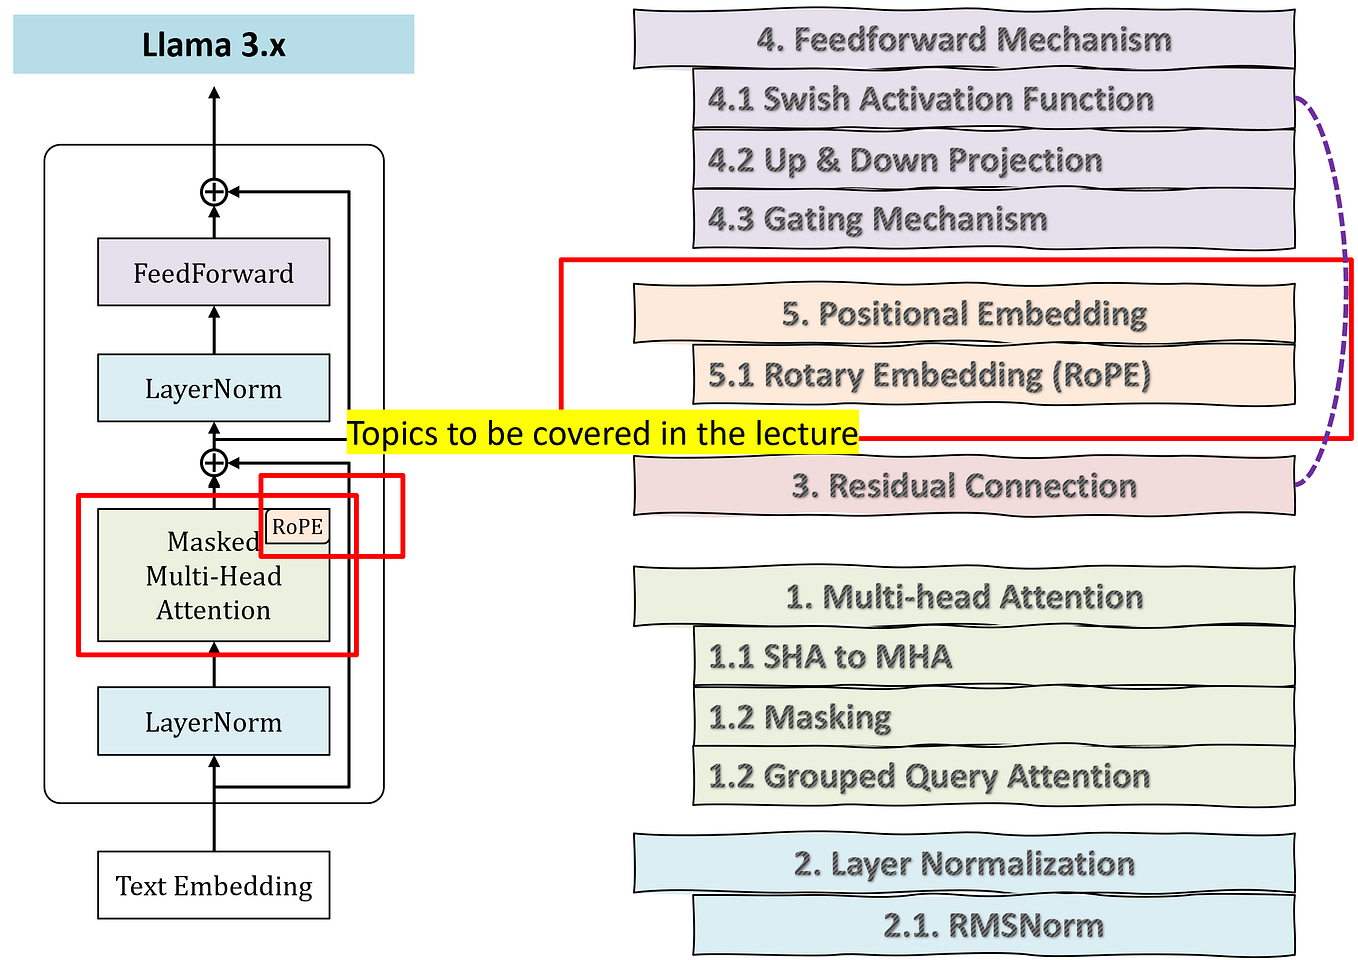
DeepSeek-V3 — Advances in MoE Load Balancing and Multi-Token Prediction ...

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

A Technical Tour of the DeepSeek Models from V3 to V3.2

[论文评述] Hardware-Centric Analysis of DeepSeek's Multi-Head Latent Attention

Multi-Head Latent Attention (MLA) 详细介绍(来自Deepseek V3的回答) - 知乎

Enhancing Natural Language Processing with DeepSeek v3
Top 5 Features of DeepSeek v3 You Should Know
Build DeepSeek-V3: Multi-Head Latent Attention (MLA) Architecture ...
Advertisement Space (336x280)

Attention Evolved: How Multi-Head Latent Attention Works | by Karl ...
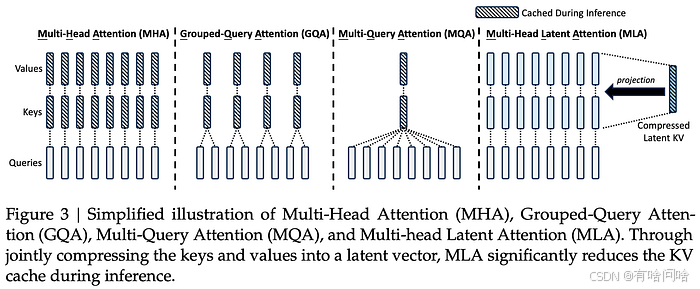
【有啥问啥】DeepSeek V3中的Multi-Head Latent Attention (MLA):技术解析与应用-CSDN博客

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

Enhancing Predictive Analytics Using DeepSeek v3

Transforming Data Analysis Using DeepSeek v3

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

DeepSeek 注意力之 MLA(Multi-Head Latent Attention) - 知乎

Enhancing Predictive Analytics Using DeepSeek v3

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science
Advertisement Space (336x280)

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

Understanding Multi-Token Prediction (MTP) in DeepSeek-V3 | by Bing ...

Enhancing User Experience Through DeepSeek v3
Build DeepSeek-V3: Multi-Head Latent Attention (MLA) Architecture ...

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

Transforming Data Analysis Using DeepSeek v3