
Direct Advantage Regression Aligning Llms With Online Ai Reward Ai

Direct Advantage Regression: Aligning LLMs with Online AI Reward | AI ...

Direct Advantage Regression: Aligning LLMs with Online AI Reward | AI ...

Direct Advantage Regression: Aligning LLMs with Online AI Reward | AI ...

Direct Advantage Regression: Aligning LLMs with Online AI Reward | AI ...

(PDF) Direct Advantage Regression: Aligning LLMs with Online AI Reward

Direct Advantage Regression: Aligning LLMs with Online AI Reward | AI ...

Aligning LLMs with Domain Invariant Reward Models | AI Research Paper ...

Online Learning with LLMs | AI Tutorial | Next Electronics

Figure 3 from Direct Language Model Alignment from Online AI Feedback ...

Confidence as a Reward: Transforming LLMs into Reward Models | AI ...
Advertisement Space (300x250)

Aligning LLMs with Direct Preference Optimization - Events ...

Harmless reward hacks can generalize to misalignment in LLMs — AI ...

Interaction Dynamics as a Reward Signal for LLMs | AI Research Paper ...
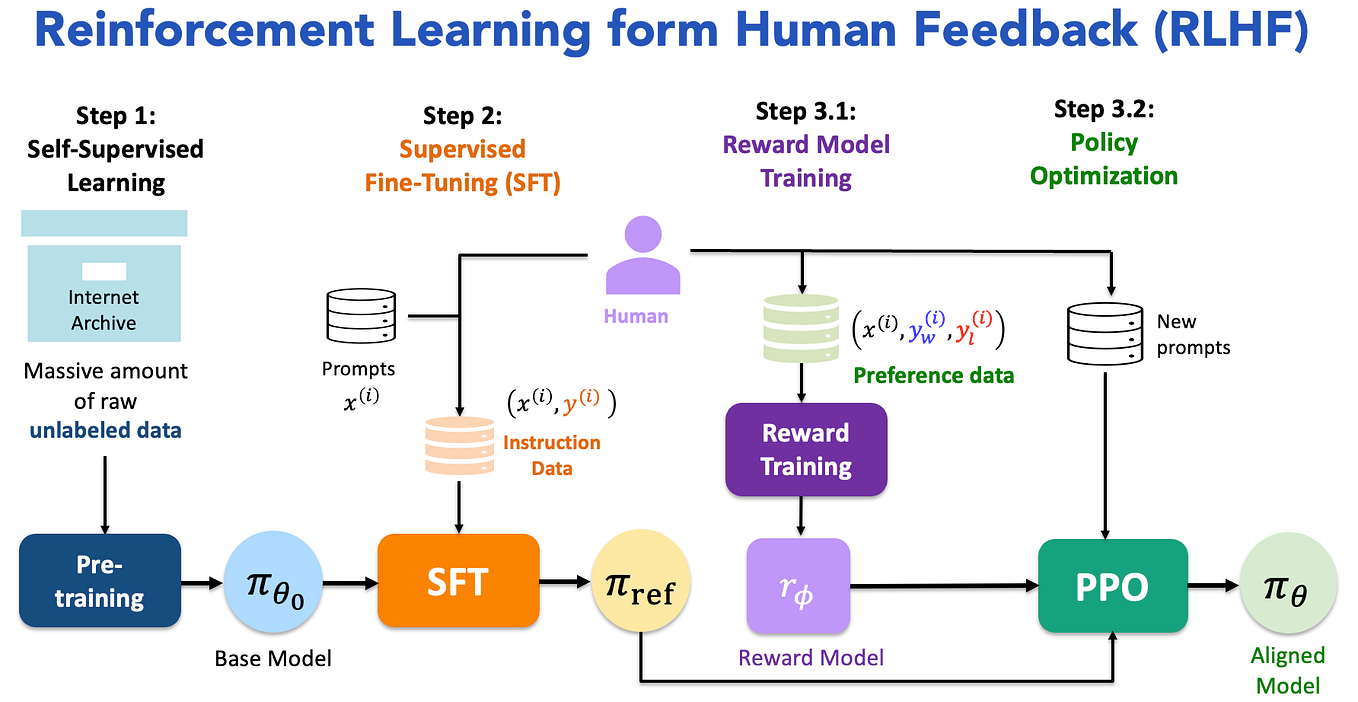
Aligning LLMs with Direct Preference Optimization (DPO)— background ...

Bridging Offline and Online Reinforcement Learning for LLMs | AI ...

Guiding LLM Decision-Making with Fairness Reward Models | AI Research ...
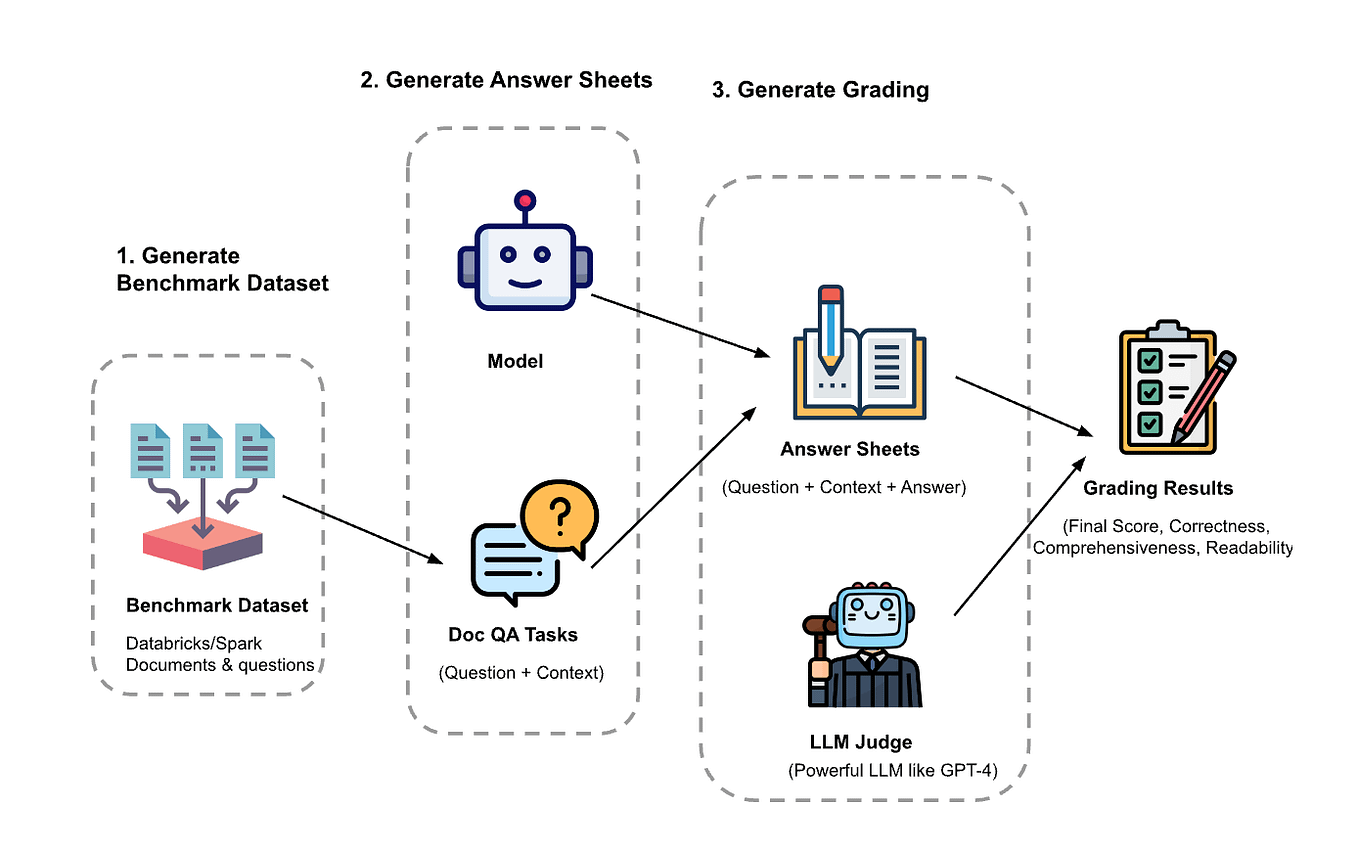
How To Generate Synthetic Data for Fine-Tuning LLMs with AI Alignment ...

Boosting Productivity with LLMs and AI Agents

Aligning llms with direct preference optimization - YouTube

Generalizable Reward Model (GRM): An Efficient AI Approach to Improve ...
Advertisement Space (336x280)
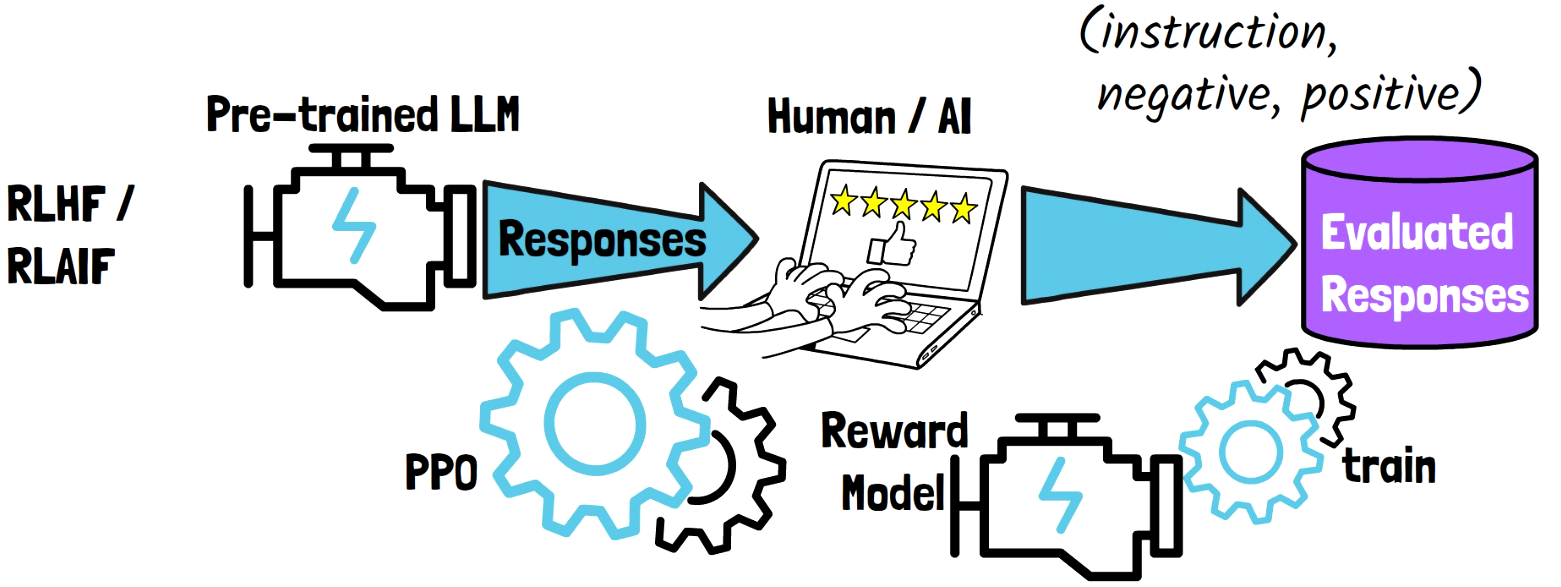
Generative Reward Models: Hybrid RL from Human & AI Feedback

Direct Reasoning Optimization: LLMs Can Reward And Refine Their Own ...

Reward Model Routing in Alignment | AI Research Paper Details

This AI Paper Explores Reinforced Learning and Process Reward Models ...

Aligning LLMs on a Budget: Inference-Time Alignment with Heuristic ...

Mitigating Reward Over-optimization in Direct Alignment Algorithms with ...

Real-Time Aligned Reward Model beyond Semantics | AI Research Paper Details

Optimizing LLMs from a Dataset Perspective - Lightning AI

Sample-Efficient Alignment for LLMs | AI Research Paper Details

ReMoDetect: Reward Models Recognize Aligned LLM's Generations | AI ...
Advertisement Space (336x280)

How to Compare LLMs and AI Models Easily ? | Eden AI

This AI Paper Introduces Agentic Reward Modeling (ARM) and REWARDAGENT ...

Sample-Efficient Alignment for LLMs · HF Daily Paper Reviews by AI

Using RLHF to Align LLMs | AI Tutorial | Next Electronics

Sample-Efficient Alignment for LLMs · HF Daily Paper Reviews by AI

Towards developing future-ready skills with generative AI