
Pdf Direct Advantage Regression Aligning Llms With Online Ai Reward

Direct Advantage Regression: Aligning LLMs with Online AI Reward | AI ...

(PDF) Direct Advantage Regression: Aligning LLMs with Online AI Reward

Direct Advantage Regression: Aligning LLMs with Online AI Reward | AI ...

Direct Advantage Regression: Aligning LLMs with Online AI Reward | AI ...

Direct Advantage Regression: Aligning LLMs with Online AI Reward | AI ...

Direct Advantage Regression: Aligning LLMs with Online AI Reward | AI ...

Aligning LLMs with Domain Invariant Reward Models | AI Research Paper ...

Paper page - Aligning LLMs with Domain Invariant Reward Models

InverseRLignment: Aligning LLMs with AfD | PDF | Machine Learning ...

Aligning LLMs with Direct Preference Optimization - Events ...
Advertisement Space (300x250)

Aligning LLMs with Pedagogy via RL | PDF | Applied Mathematics | Learning

Aligning LLMs with Individual Preferences via Interaction | AI Research ...
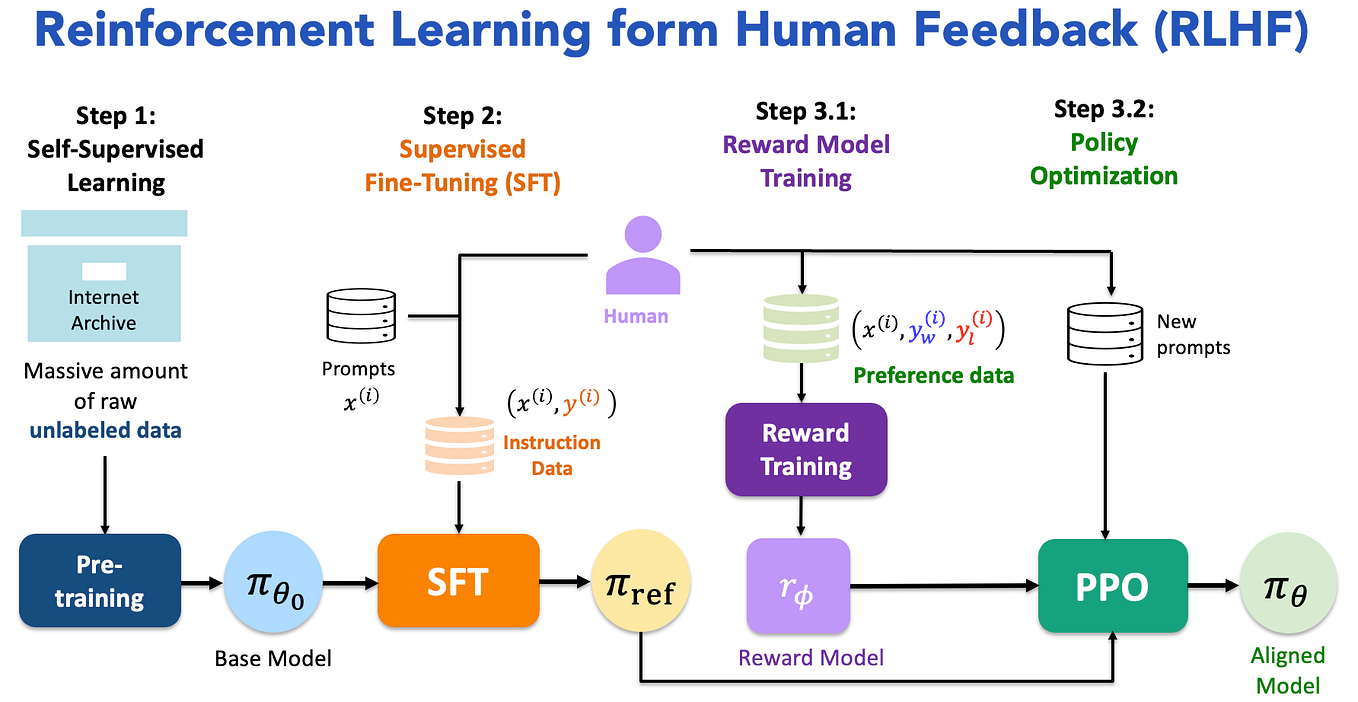
Aligning LLMs with Direct Preference Optimization (DPO)— background ...

[2501.00911] Aligning LLMs with Domain Invariant Reward Models

[2501.00911] Aligning LLMs with Domain Invariant Reward Models

Online Learning with LLMs | AI Tutorial | Next Electronics

Varying Shades of Wrong: Aligning LLMs with Wrong Answers Only | AI ...

Mitigating Reward Over-optimization in Direct Alignment Algorithms with ...

PRPO: Aligning Process Reward with Outcome Reward in Policy ...

Aligning LLMs on a Budget: Inference-Time Alignment with Heuristic ...
Advertisement Space (336x280)

Direct Reasoning Optimization: LLMs Can Reward And Refine Their Own ...

InstructGPT: Aligning LMs with Feedback | PDF | Artificial Intelligence ...

Aligning Motion with LLM Text Descriptions | PDF

SALMON: Self-Alignment with Instructable Reward Models | AI Research ...

RPO-RAG: Aligning Small LLMs with Relation-aware Preference ...

Reward Collapse in Aligning Large Language Models | PDF | Mathematics ...

(PDF) Cost-Effective Online Multi-LLM Selection with Versatile Reward ...

Bridging Offline and Online Reinforcement Learning for LLMs | AI ...
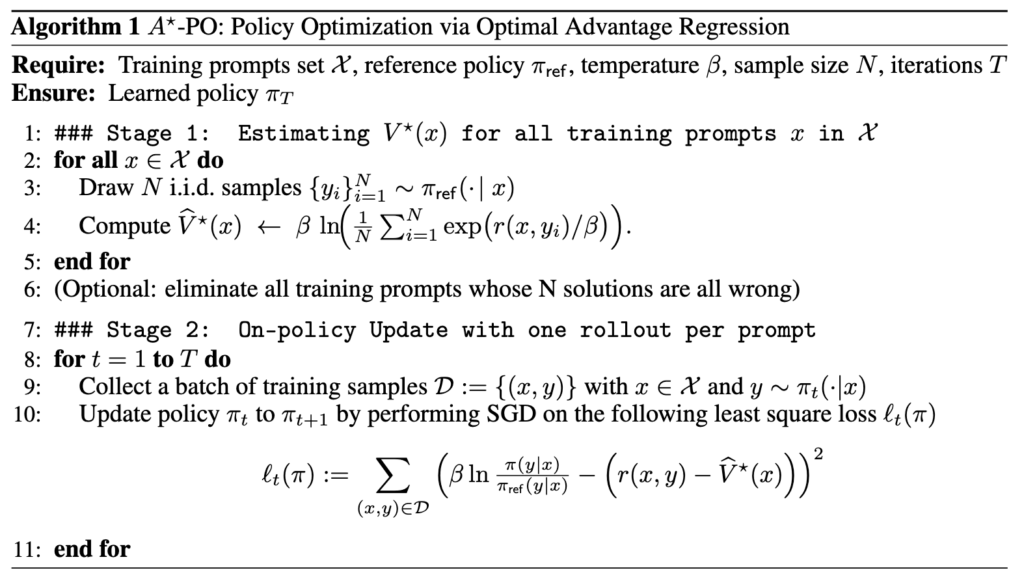
Accelerating RL for LLM Reasoning with Optimal Advantage Regression ...

论文理解【LLM-回归】—— 【RAFT】Better autoregressive regression with LLMs via ...
Advertisement Space (336x280)

[论文评述] Accelerating RL for LLM Reasoning with Optimal Advantage Regression

[논문 리뷰] Confidence as a Reward: Transforming LLMs into Reward Models
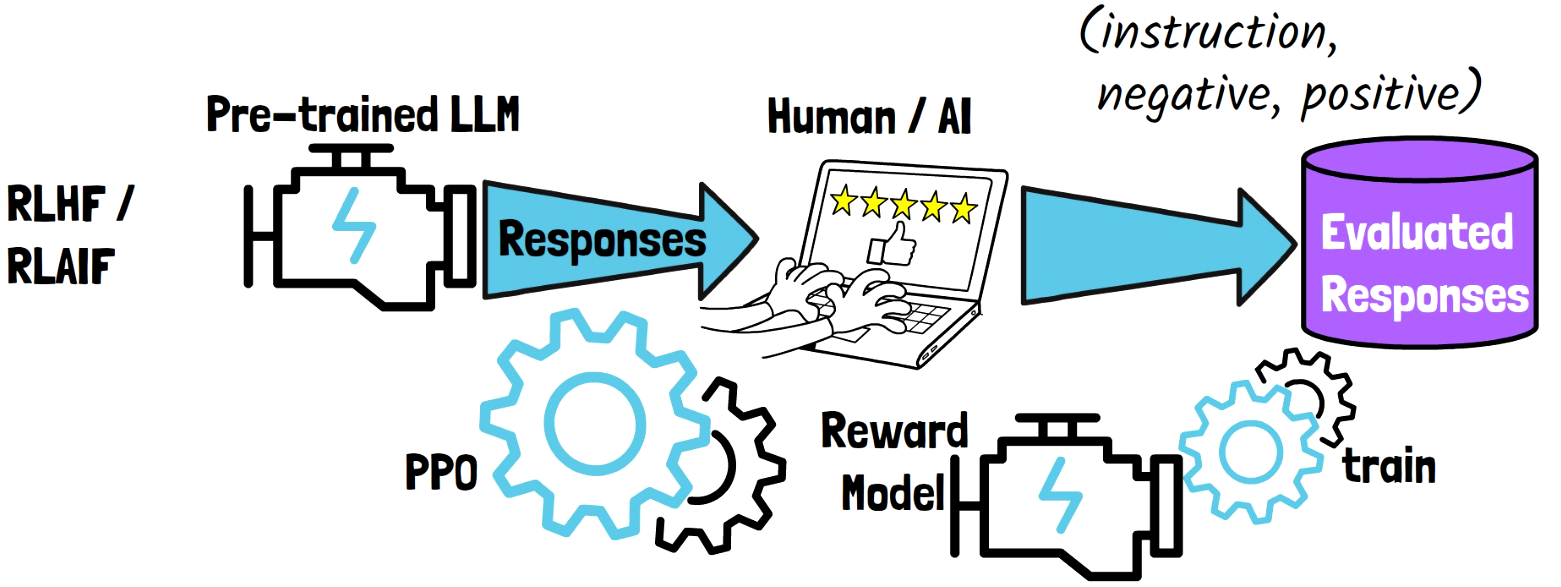
Generative Reward Models: Hybrid RL from Human & AI Feedback
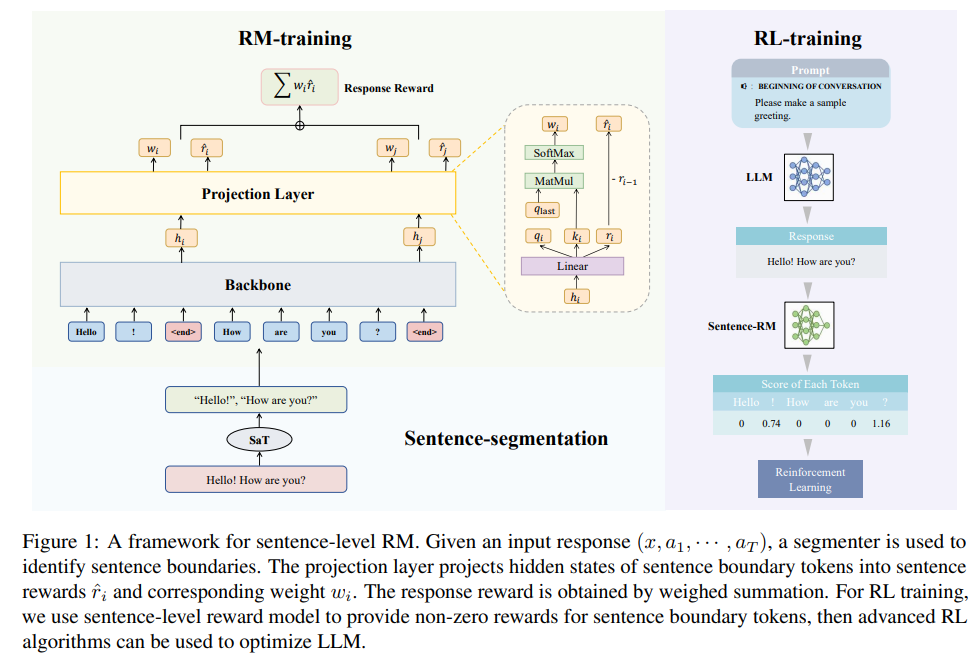
别再卷参数了!LLM 奖励模型才是让 AI 听话的终极杀器!_process reward models-CSDN博客

Online versus Offline RL for LLMs

Sample-Efficient Alignment for LLMs | AI Research Paper Details