
E02 Multihead Latent Attention Why Is Deepseek Cheap And Good With

E02 Multihead Latent Attention | Why is DeepSeek cheap and good? (with ...

Under the Hood of DeepSeek V2: How Multihead Latent Attention is ...

DeepSeek Multihead Latent Attention - YouTube

Multi-Head Latent Attention and Multi-token Prediction in Deepseek v3
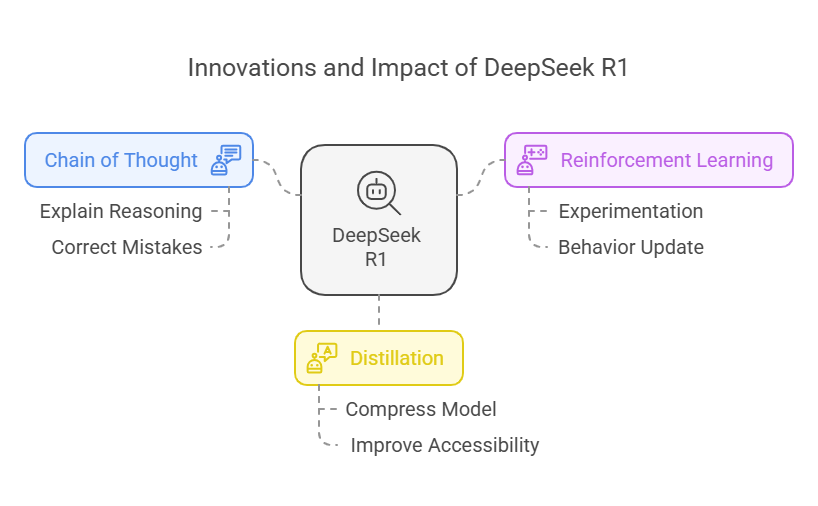
🤯 DeepSeek R1: How Multi-Head Latent Attention is Redefining AI ...

Three Interpretations of DeepSeek V2's Multi-headed Latent Attention Layer

Three Interpretations of DeepSeek V2's Multi-headed Latent Attention Layer

Inside DeepSeek V3: Breaking Down Multi-Head Latent Attention (MLA ...

Attention の基礎から DeepSeek MLA (Multi-Head Latent Attention) を解説する

DeepSeek + SGLang: Multi-Head Latent Attention
Advertisement Space (300x250)

DeepSeek + SGLang: Multi-Head Latent Attention

DeepSeek + SGLang: Multi-Head Latent Attention

Full single-type deep learning models with multihead attention for ...

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

Implementing DeepSeek-V2’s Multi-Head Latent Attention (MLA) from ...

[论文评述] Hardware-Centric Analysis of DeepSeek's Multi-Head Latent Attention

DeepSeek Series: A Comprehensive Deep Dive into Multi-Head Latent ...
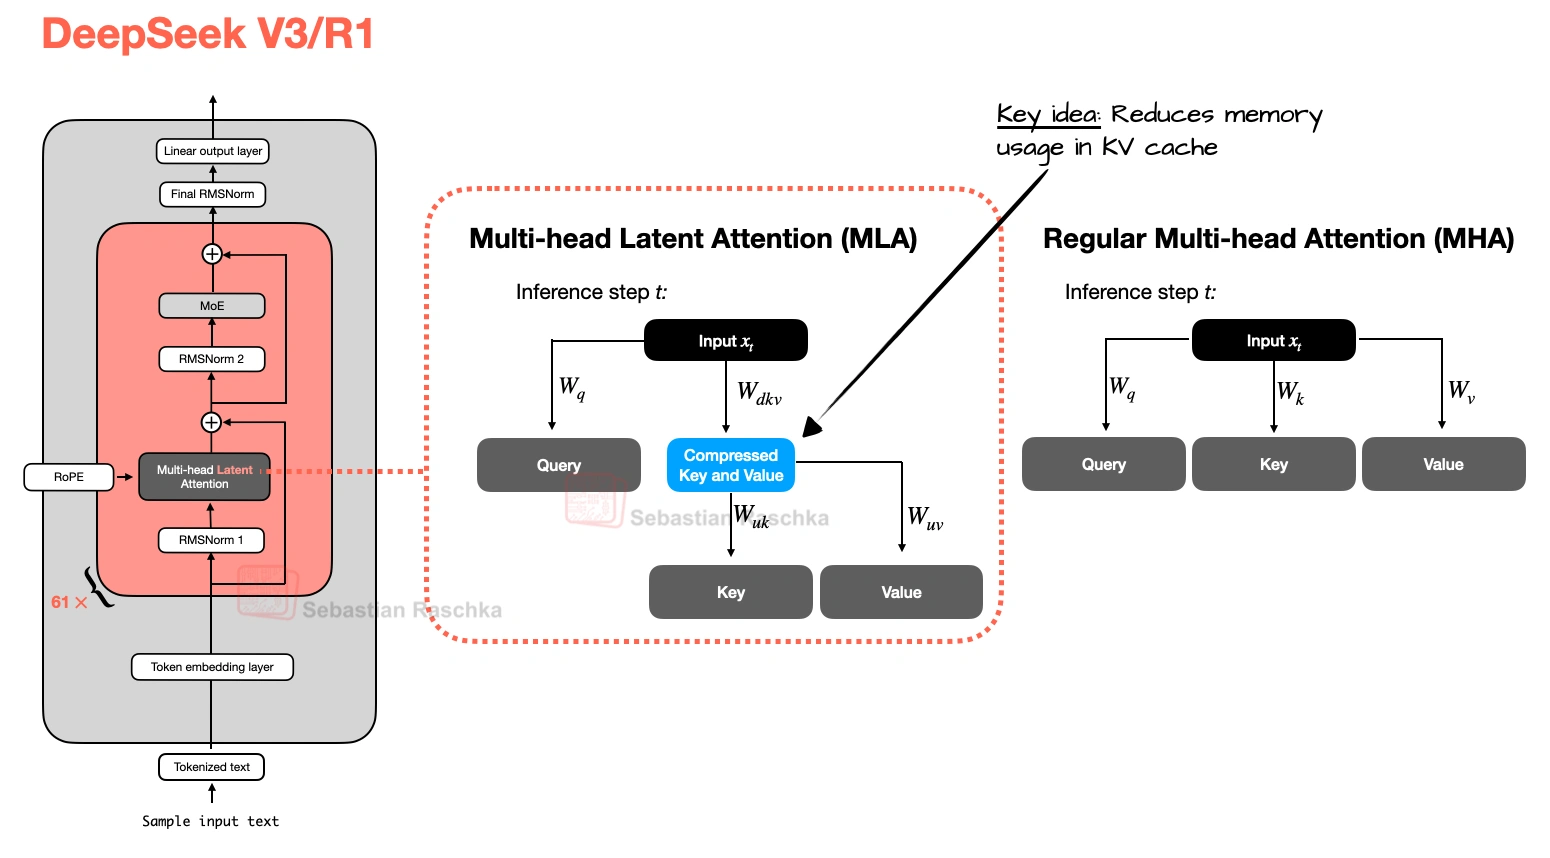
Multi-Head Latent Attention (MLA) | Sebastian Raschka, PhD

Multi-Head Latent Attention Explained Simply - YouTube

Enhancing Natural Language Processing with DeepSeek v3
Advertisement Space (336x280)

Multi-headed Attention the mathematical meaning - NLP with Attention ...

What Is DeepSeek v3? A Comprehensive Overview

DeepSeek Multi-Head Attention Explained - Part 1 - YouTube
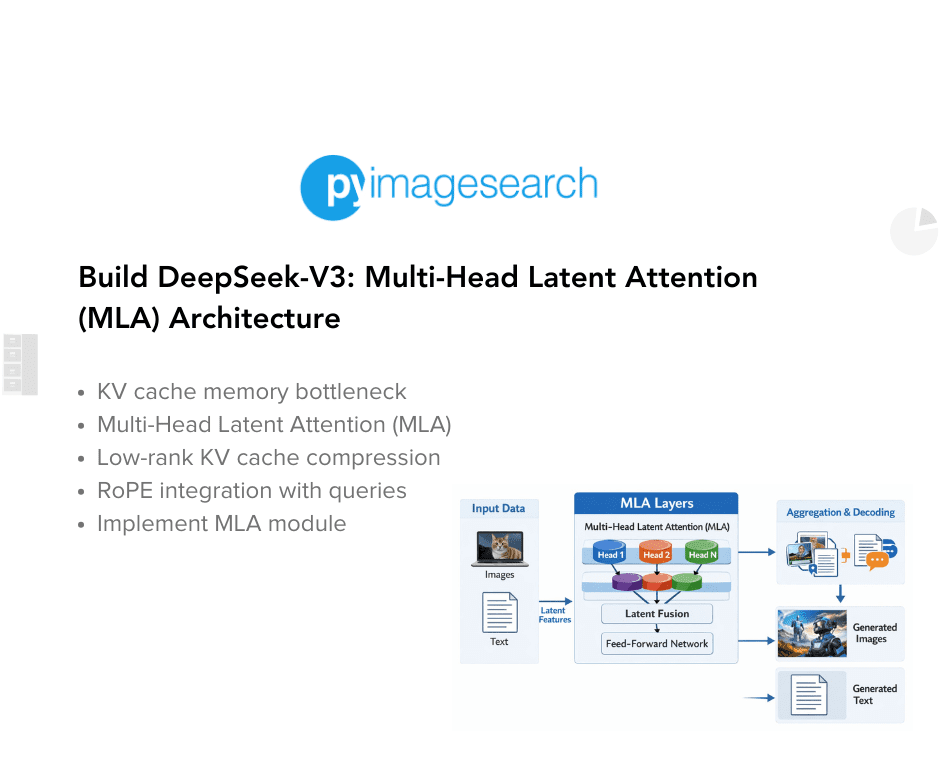
Build DeepSeek-V3: Multi-Head Latent Attention (MLA) Architecture ...

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science

How DeepSeek's Multi-Head Latent Attention Changed the Game - YouTube

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science
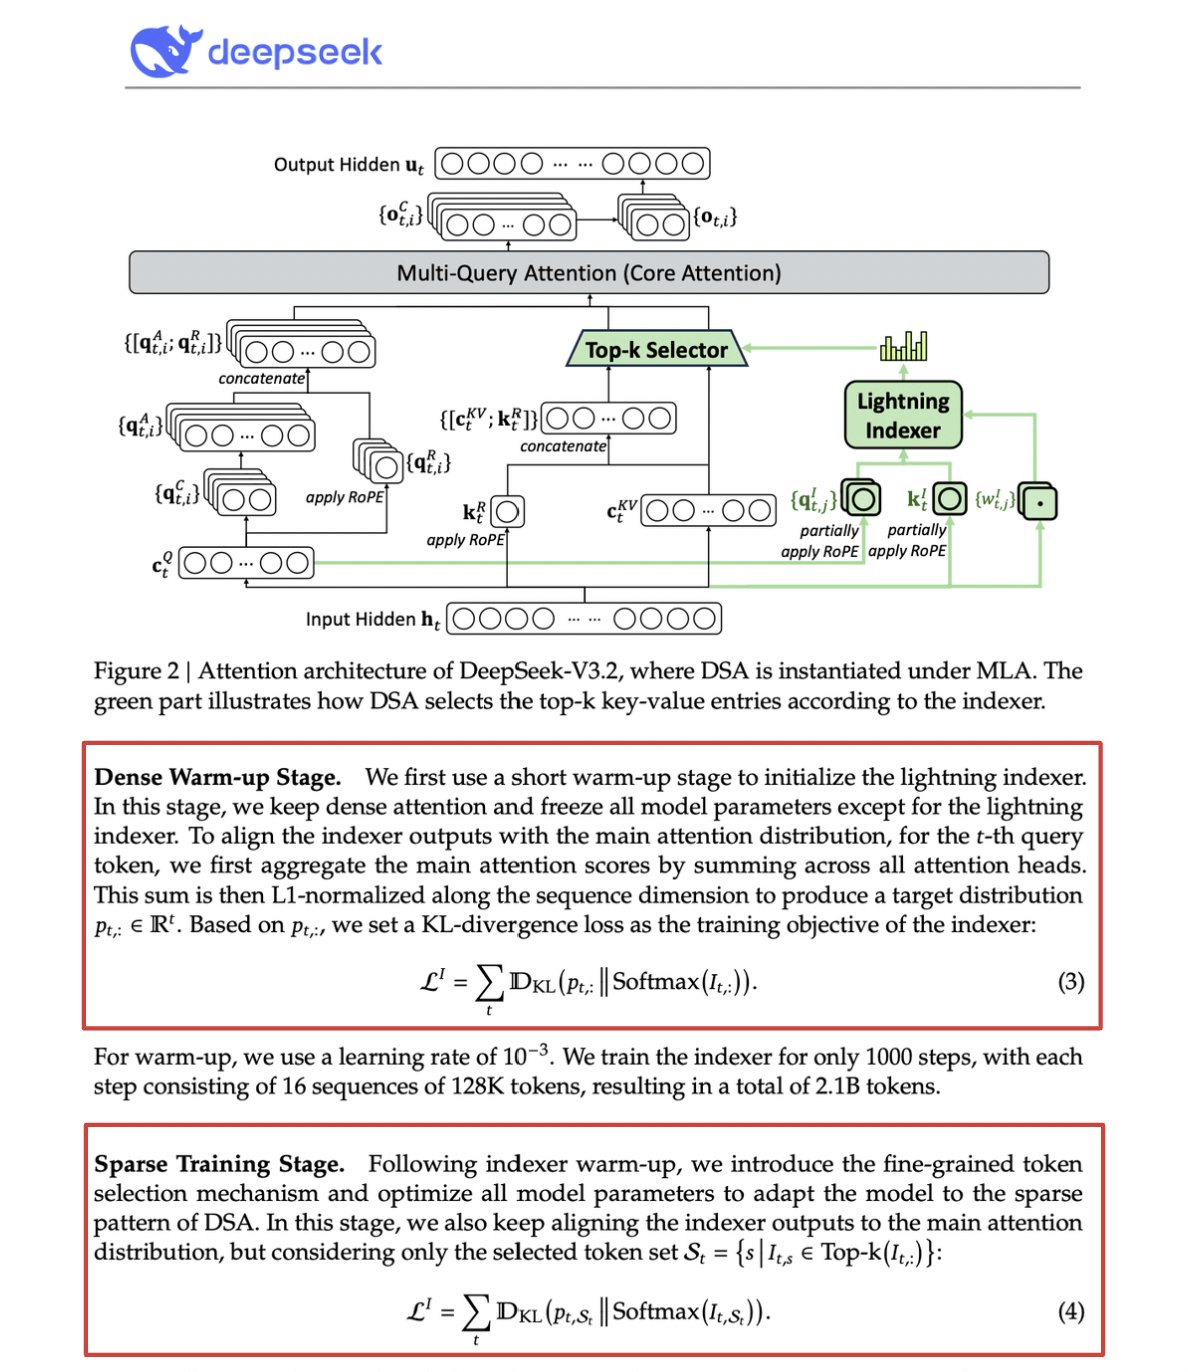
DeepSeek Cracked The O(L²) Attention Bottleneck

DeepSeek-V3 Explained 1: Multi-head Latent Attention | Towards Data Science
Advertisement Space (336x280)

The Sequence AI of the Week #733: DeepSeek 3.2 Makes Long Context Cheap
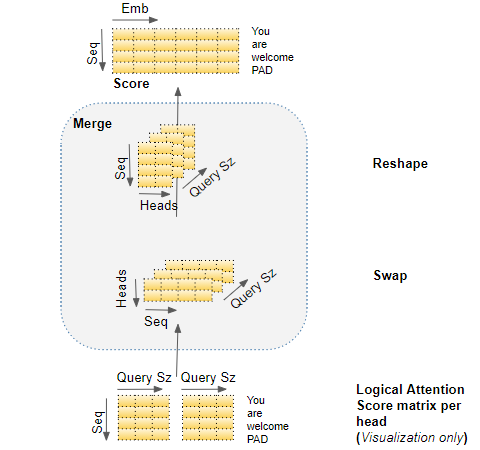
Deepseek 이해하기 (1) - MLA (Multi-Head Latent Attention)
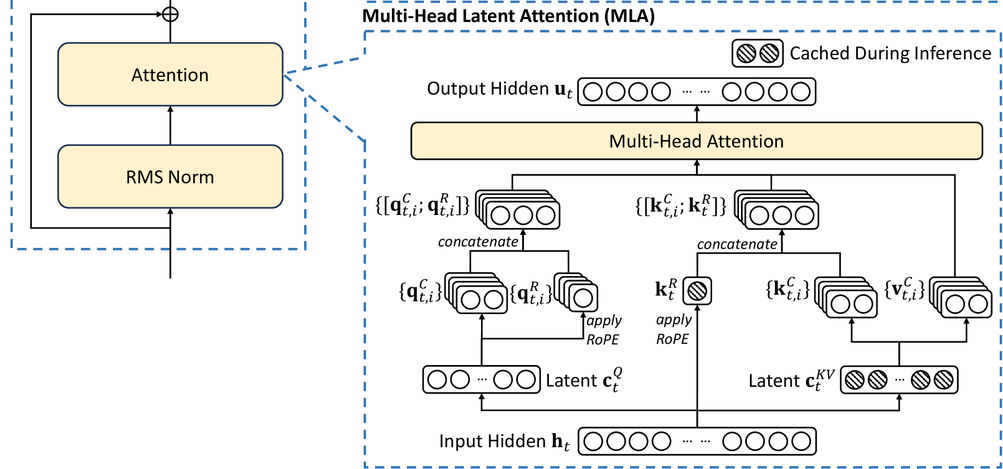
DeepSeek-V3 论文解读:MLA, Multi-Head Latent Attention – remaper

DeepSeek 注意力之 MLA(Multi-Head Latent Attention) - 知乎

Multi-Head Latent Attention – Latent KV-Cache (DeepSeek v3) – Lechuck Park
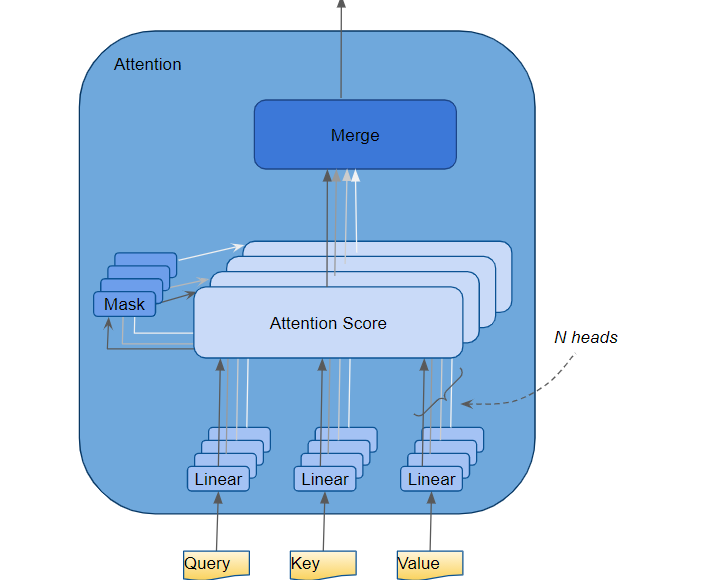
Deepseek 이해하기 (1) - MLA (Multi-Head Latent Attention)