
Usage The Gpu Kv Cache Usage Is Still Small Below 20 Most Of Time
[Usage]: The GPU KV cache usage is still small (below 20% most of time ...
Why is the GPU KV cache usage very low? · Issue #5626 · vllm-project ...
Metric: GPU KV Cache Usage | Deka GPU Documentations
Example: Autoscaling vLLM with KEDA based on GPU KV Cache Usage ...
vLLM model serving server hangs when GPU KV cache usage reaches 10% ...
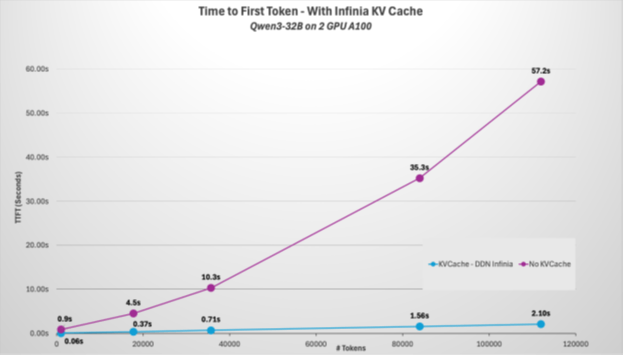
How DDN Eliminates the GPU Waste Spiral for AI Reasoning with KV Cache

KV Cache Reuse - The GPU Memory Game
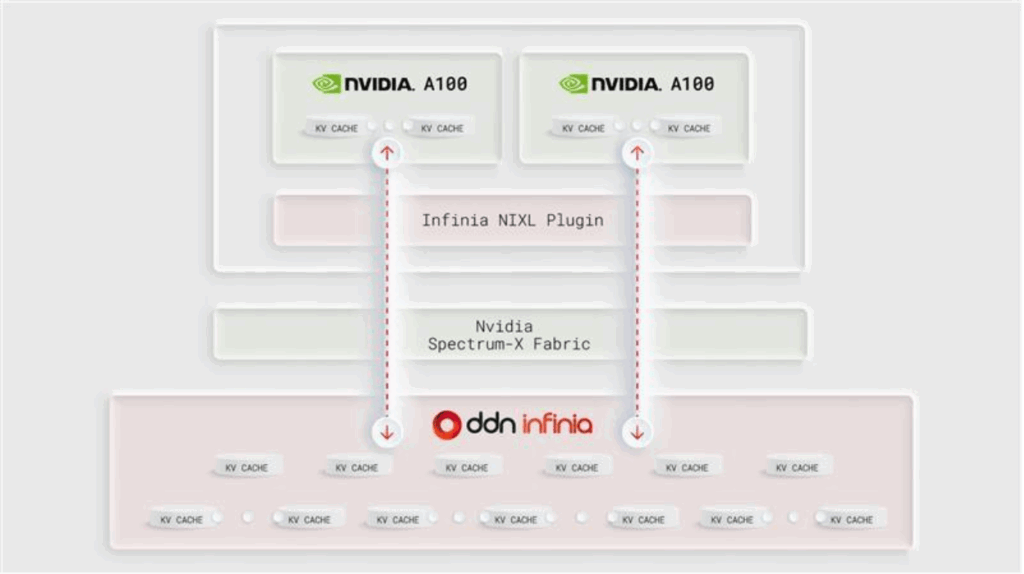
How DDN Eliminates the GPU Waste Spiral for AI Reasoning with KV Cache

zai-org/GLM-4.7-Flash · Why does the KV cache occupy so much GPU memory?
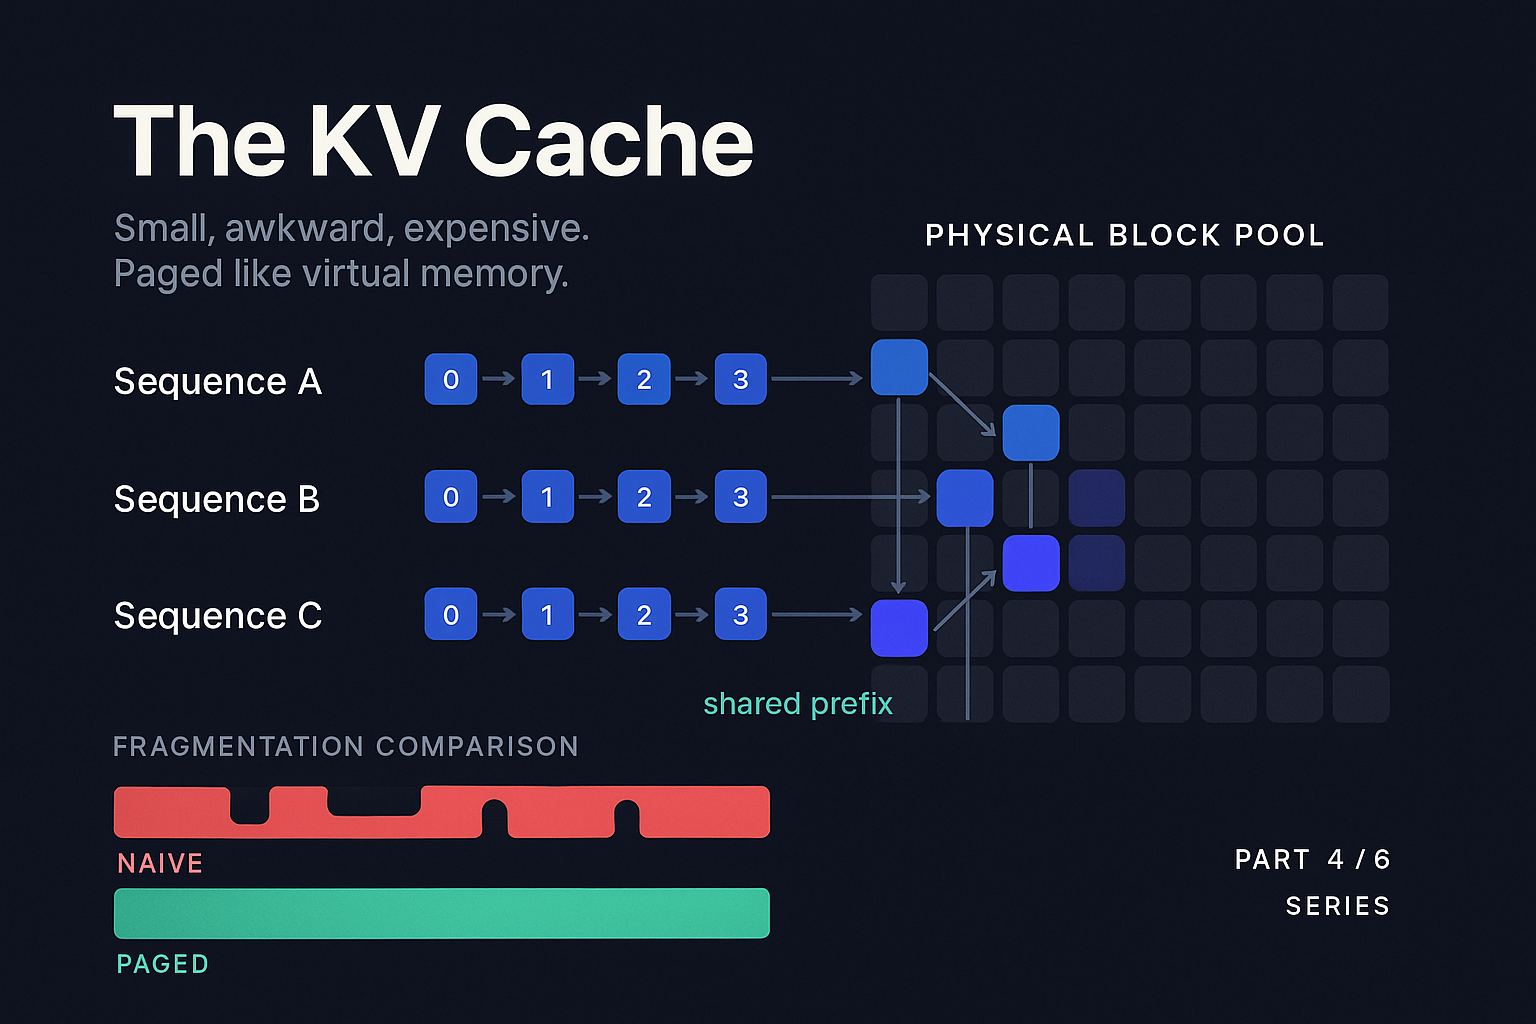
The KV Cache - Part 4 of 6 - Strongly.AI
Advertisement Space (300x250)

How Much Gpu Usage Is Normal ? (Complete 2026 Guide)

Comparative Characterization of KV Cache Management Strategies for LLM ...

5x Faster Time to First Token with NVIDIA TensorRT-LLM KV Cache Early ...
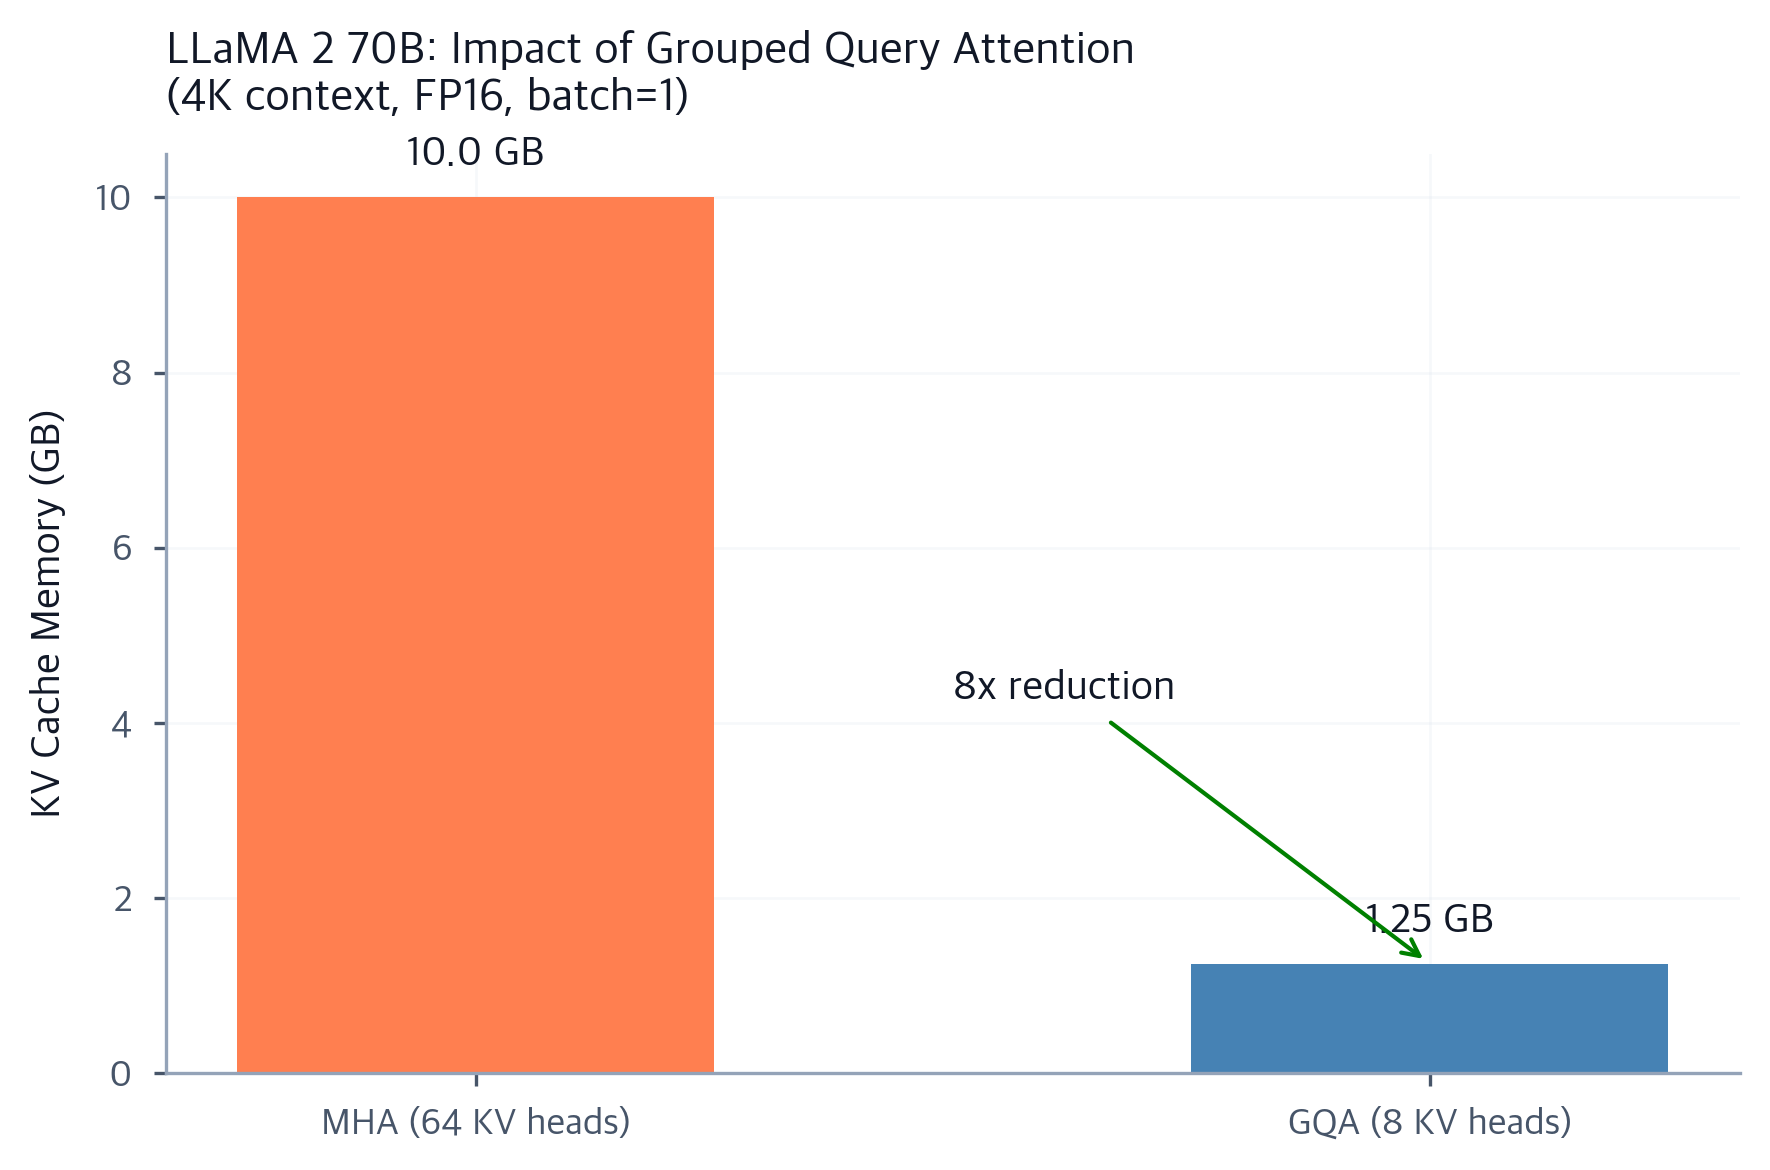
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
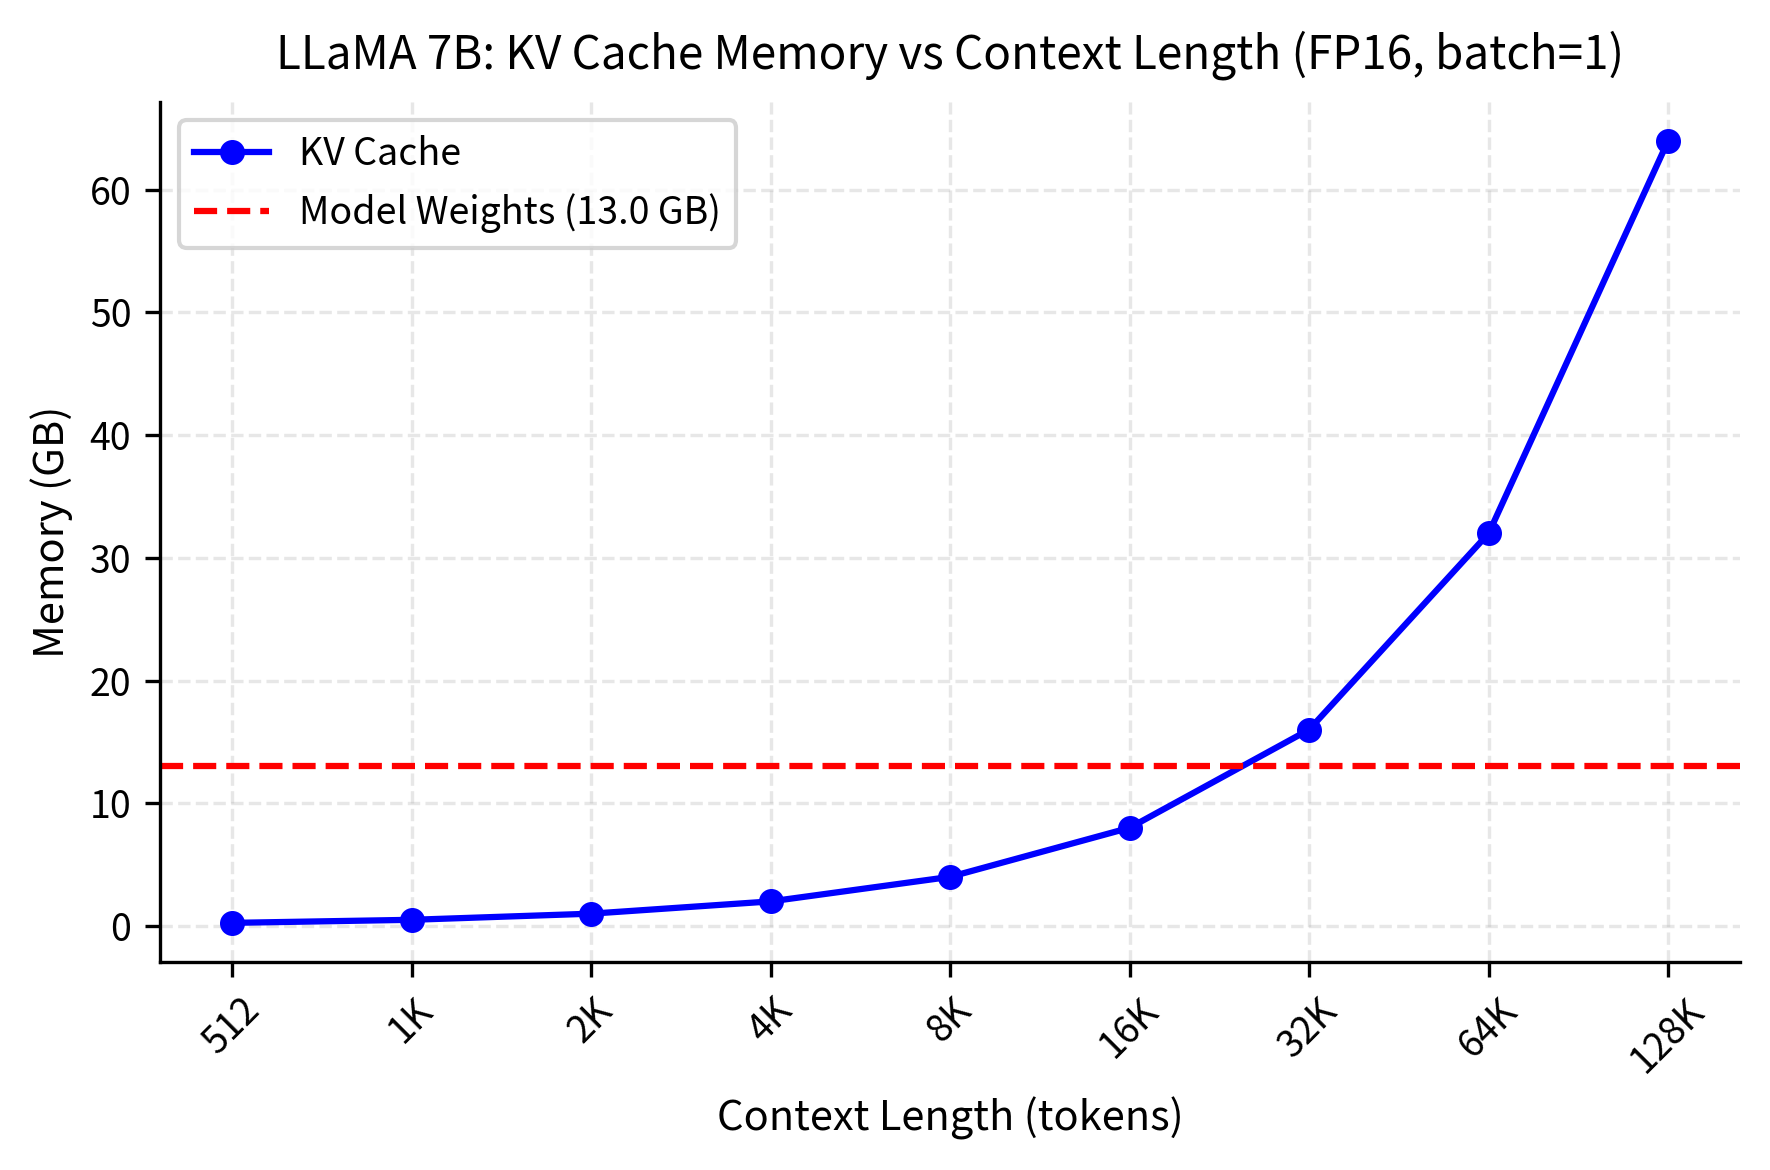
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
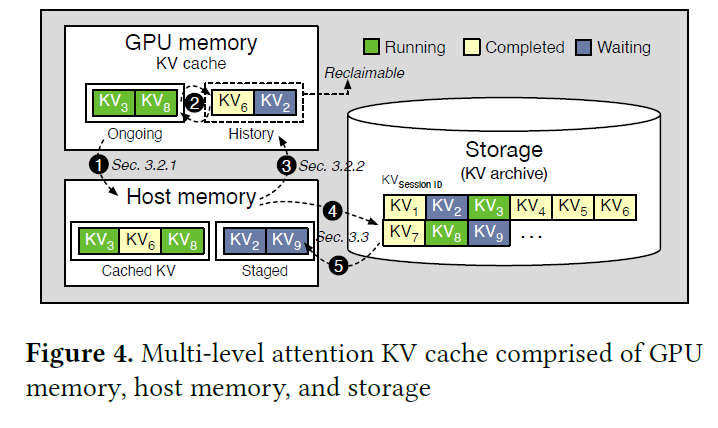
CUDA Meets Python: How NVIDIA Is Ushering in a New Era of GPU ...

What is the KV cache? | Matt Log

TurboQuant Targets the KV Cache Memory Wall: Extreme Compression for ...
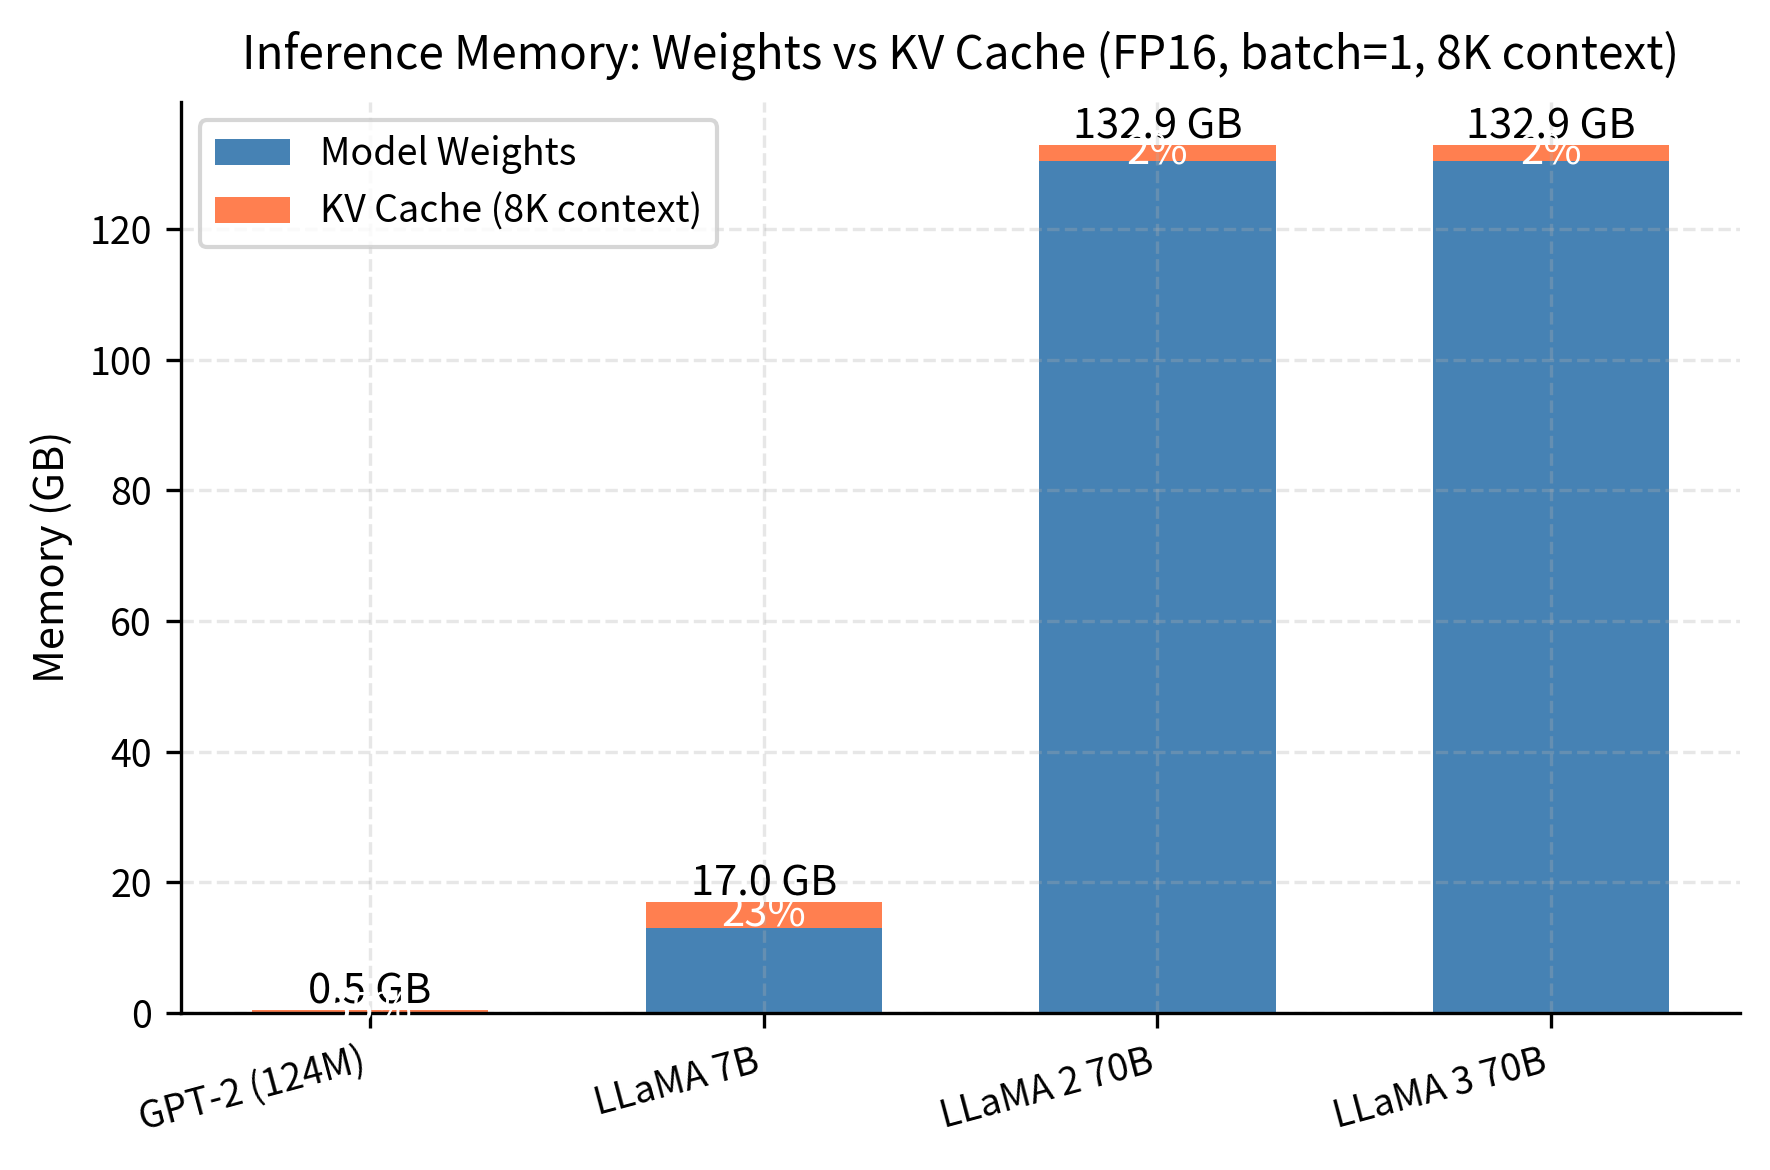
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
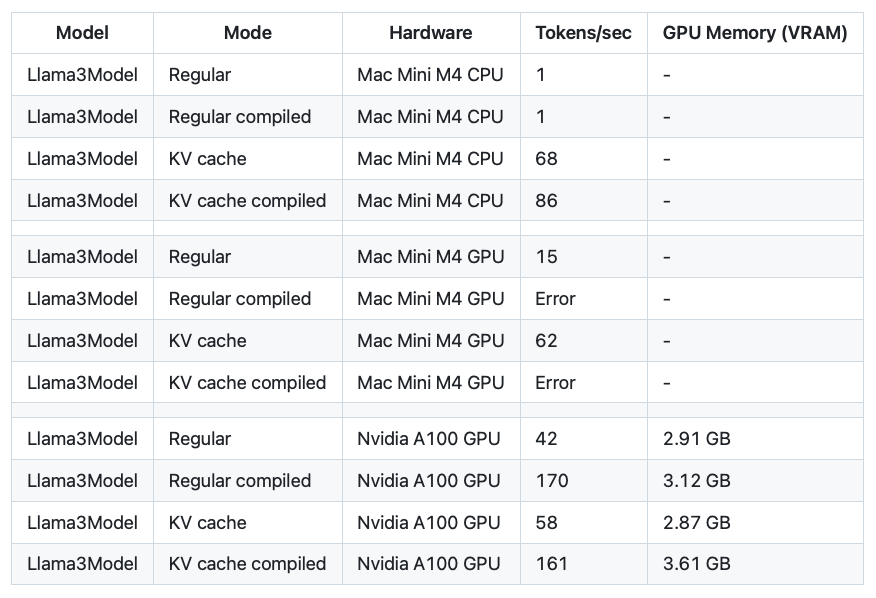
Understanding and Coding the KV Cache in LLMs from Scratch
Advertisement Space (336x280)

Will KV Cache Exhaust Your GPU Memory? Enterprise AI Deployment Guide 2026
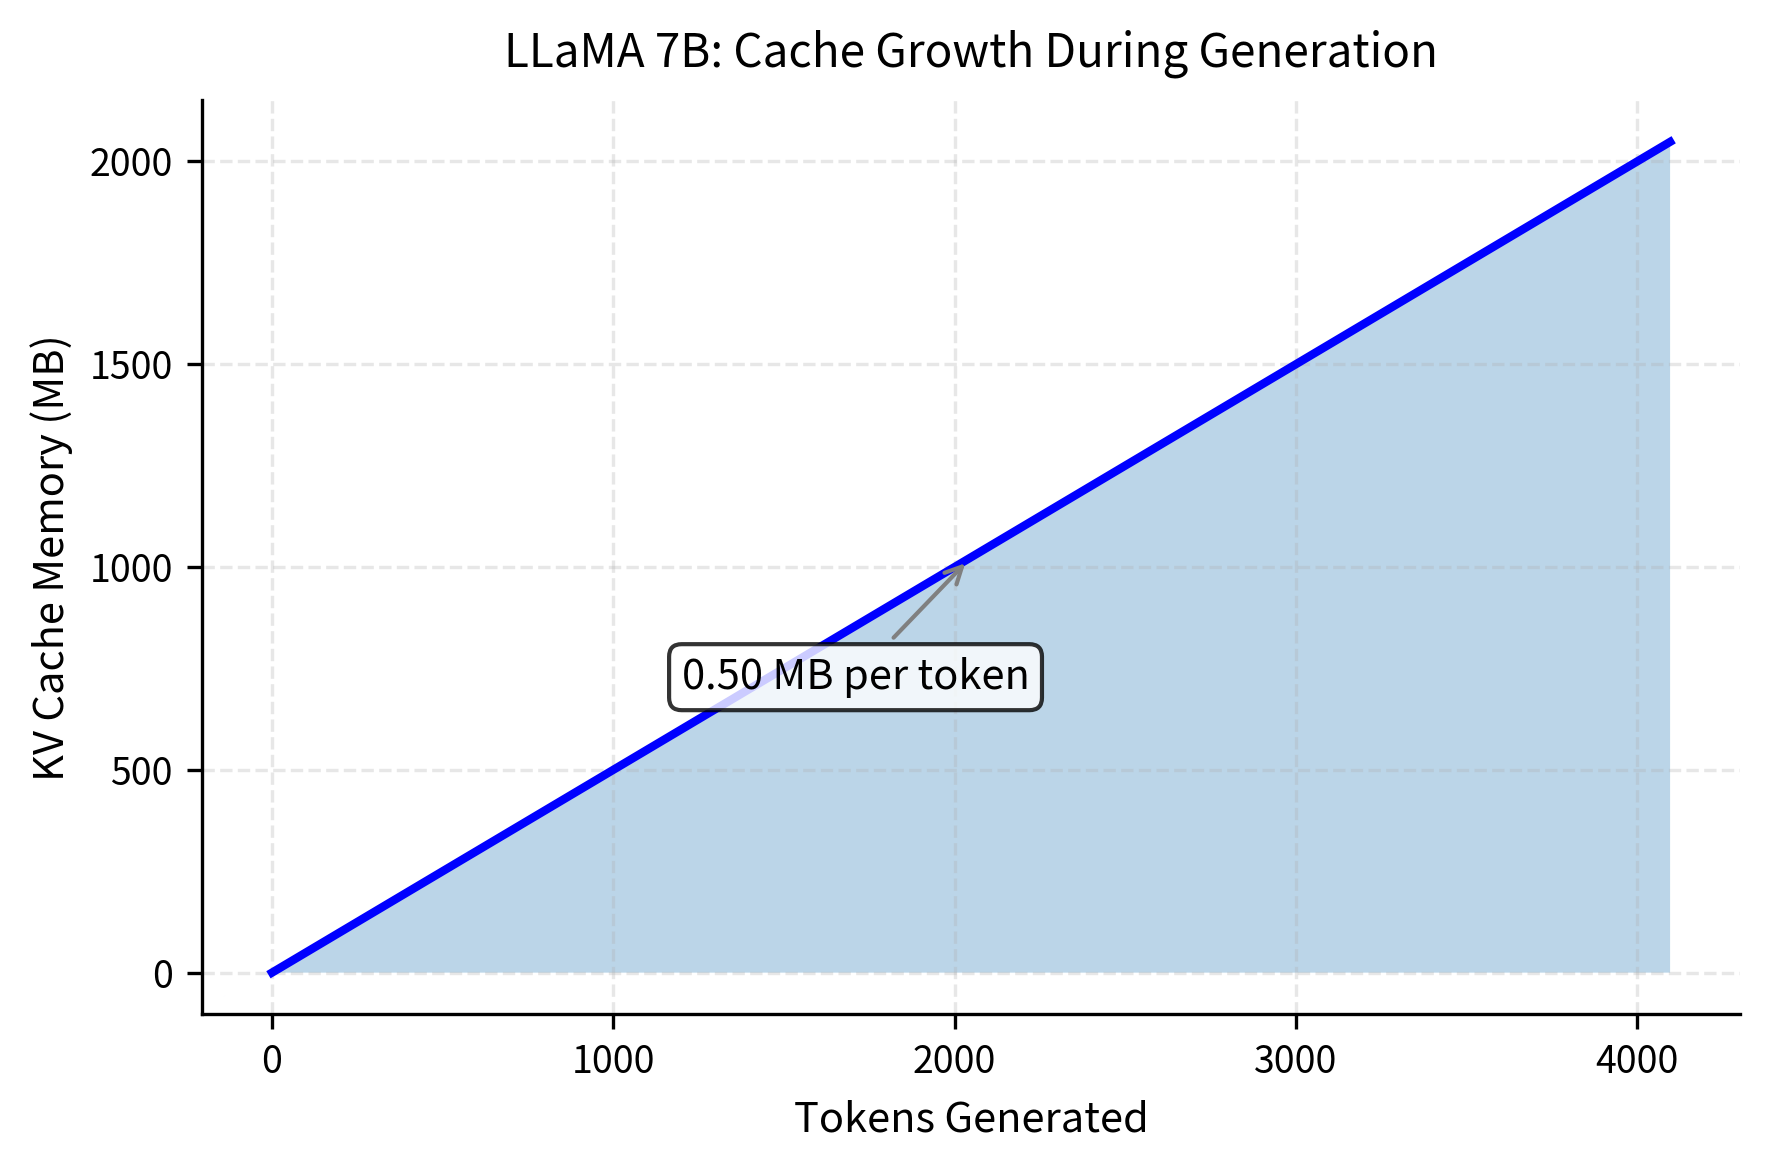
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...
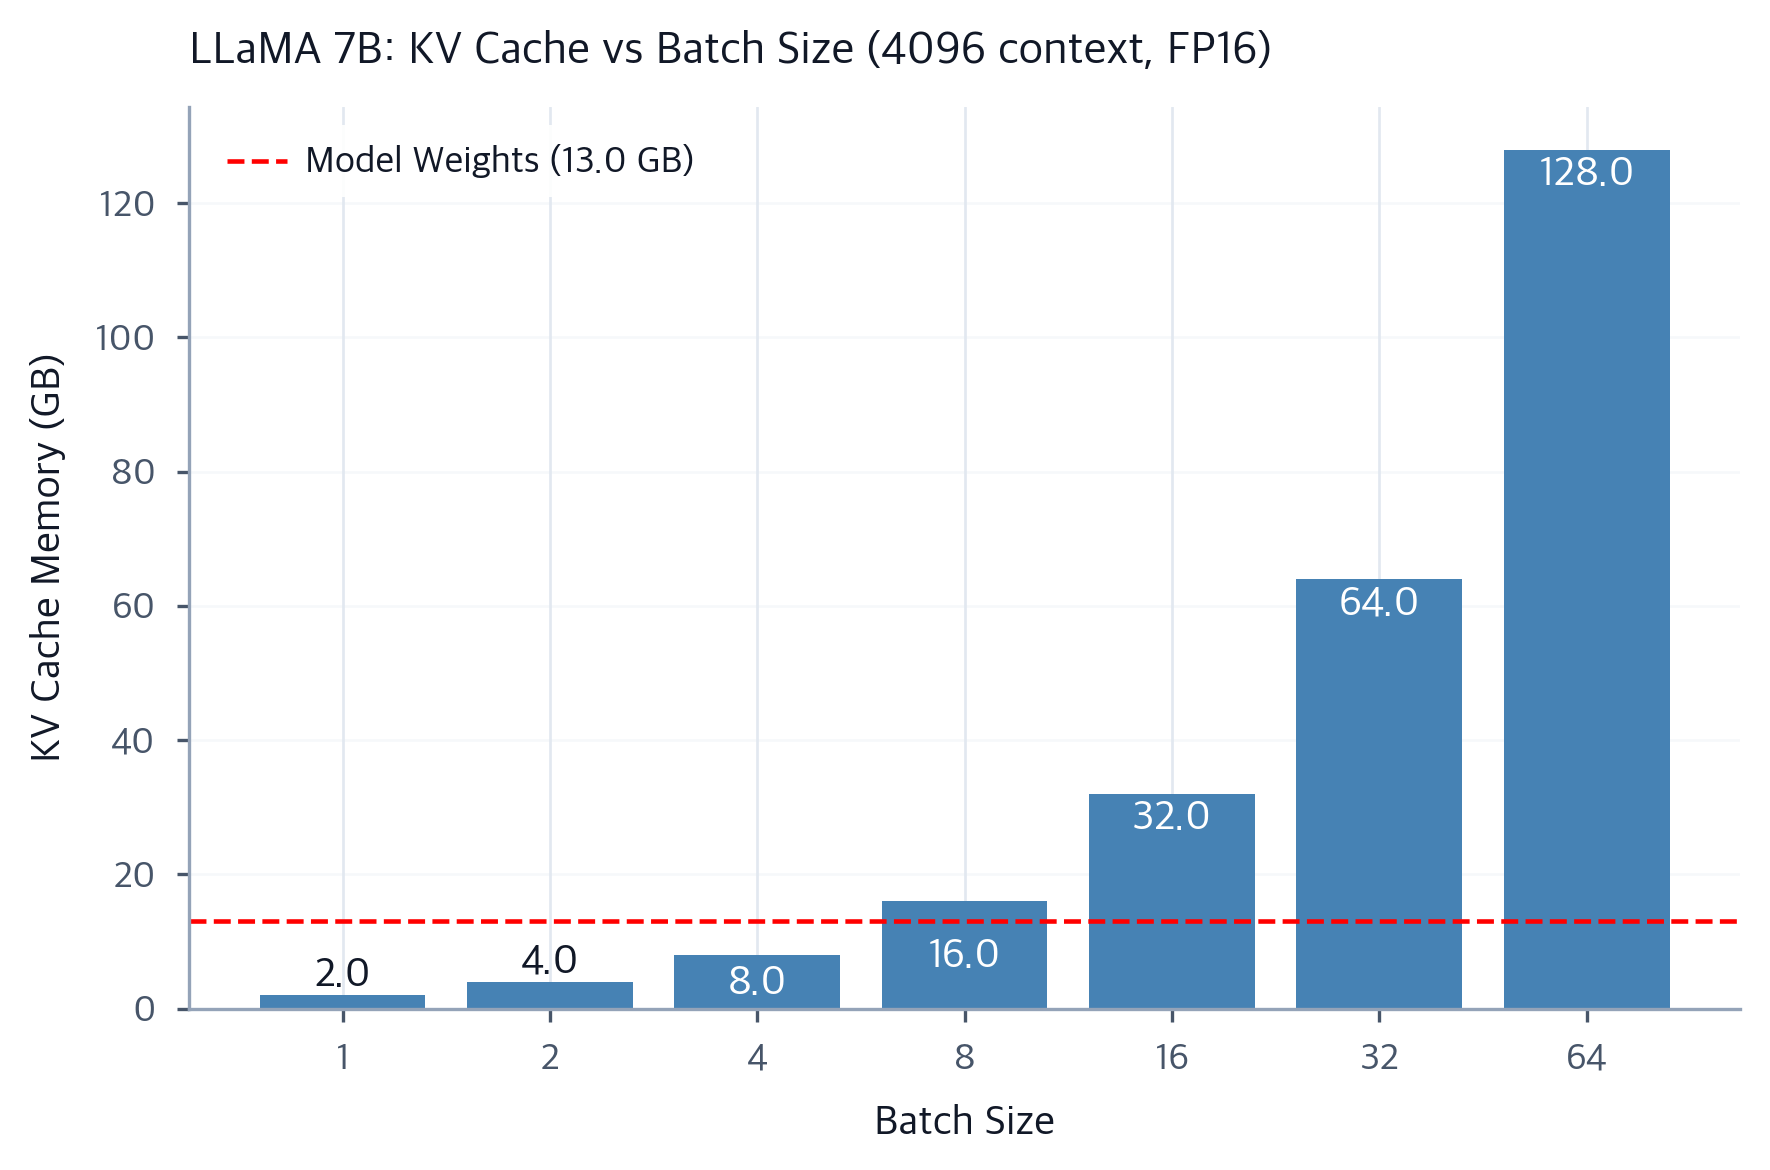
KV Cache Memory: Calculating GPU Requirements for LLM Inference ...

5x Faster Time to First Token with NVIDIA TensorRT-LLM KV Cache Early ...

Comparative Characterization of KV Cache Management Strategies for LLM ...

Caching Strategies for LLM Systems (Part 2): KV Cache and the ...
[Performance] KV cache reuse is slower when batch size > 1 · Issue ...
GPU KV cache usage: 100.0%以后就卡住 · Issue #1206 · vllm-project/vllm · GitHub

KV Cache and Prompt Caching: How to Leverage them to Cut Time and Costs ...

KV Cache Is Eating Your VRAM. Here’s How Google Fixed It With ...
Advertisement Space (336x280)
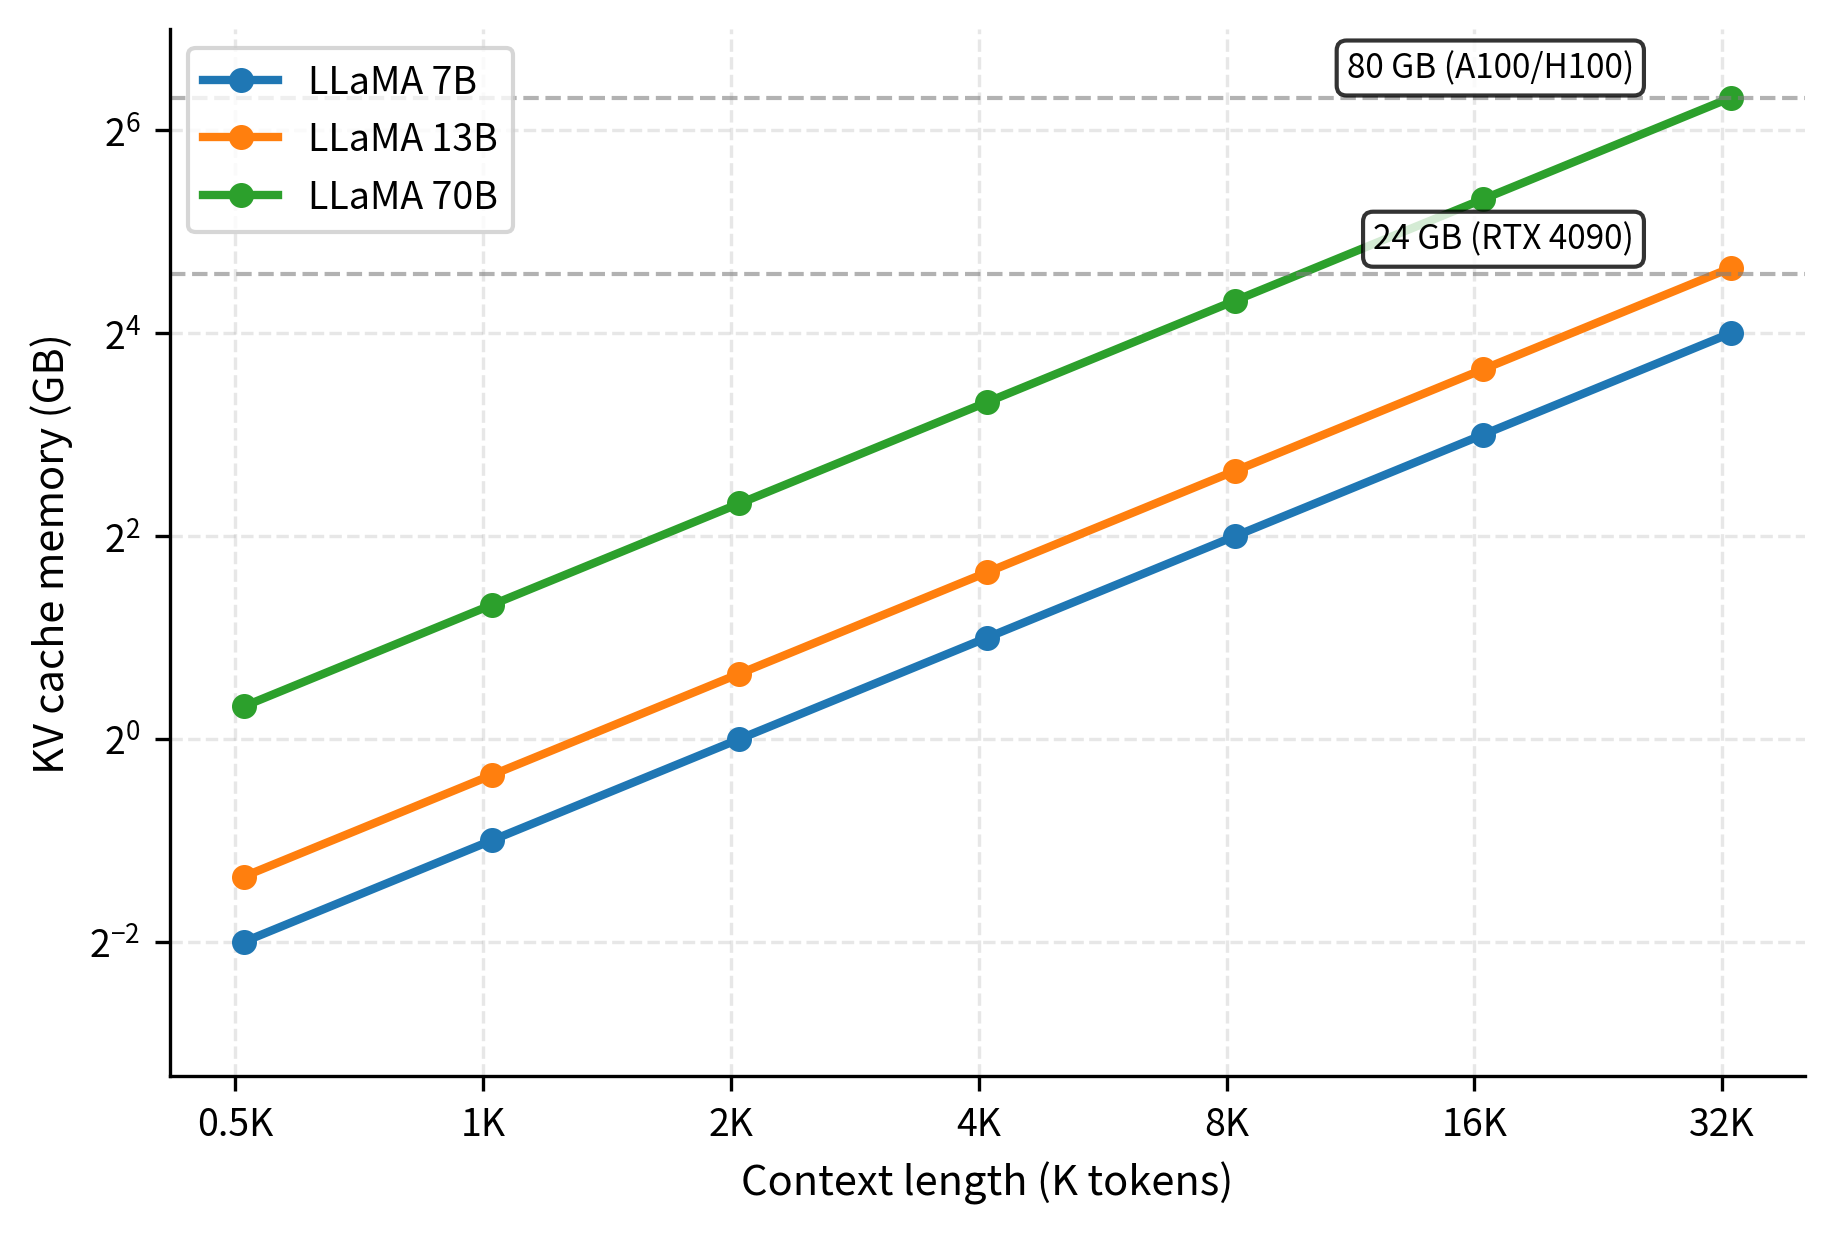
KV Cache Explained: Efficient Attention for LLM Generation ...
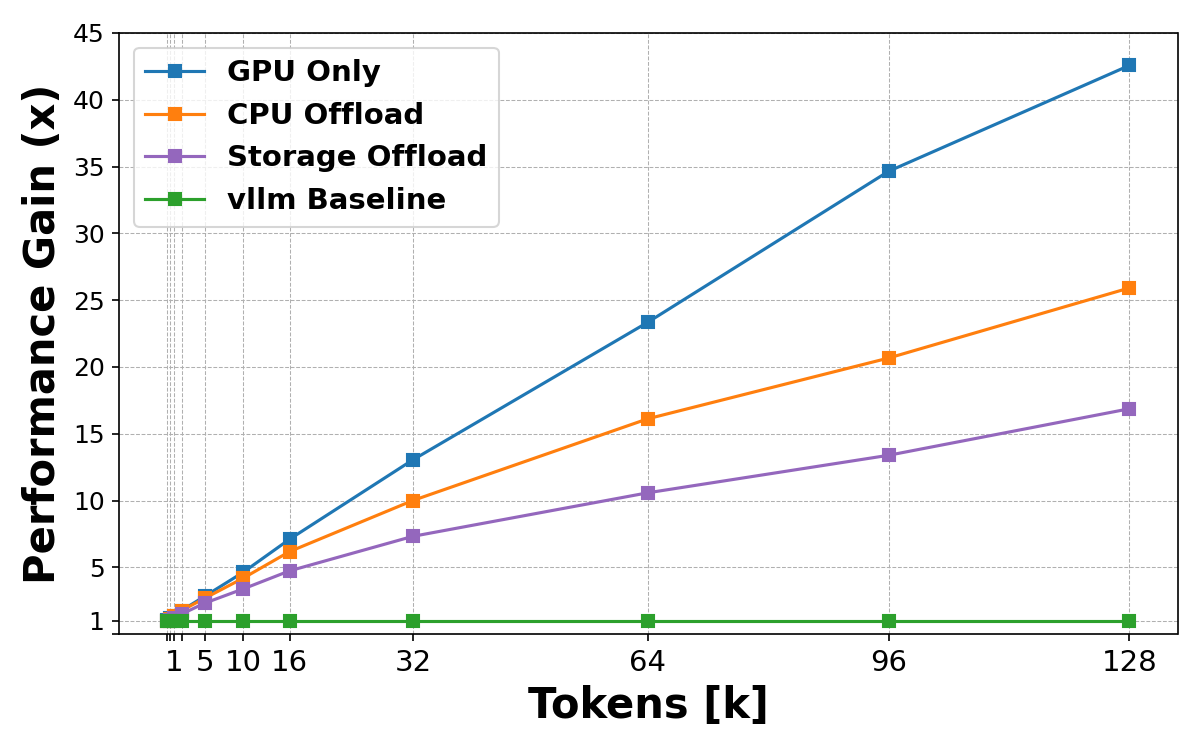
Native KV Cache Offloading to Any Filesystem with llm-d | llm-d

How to Reduce KV Cache Bottlenecks with NVIDIA Dynamo | NVIDIA ...
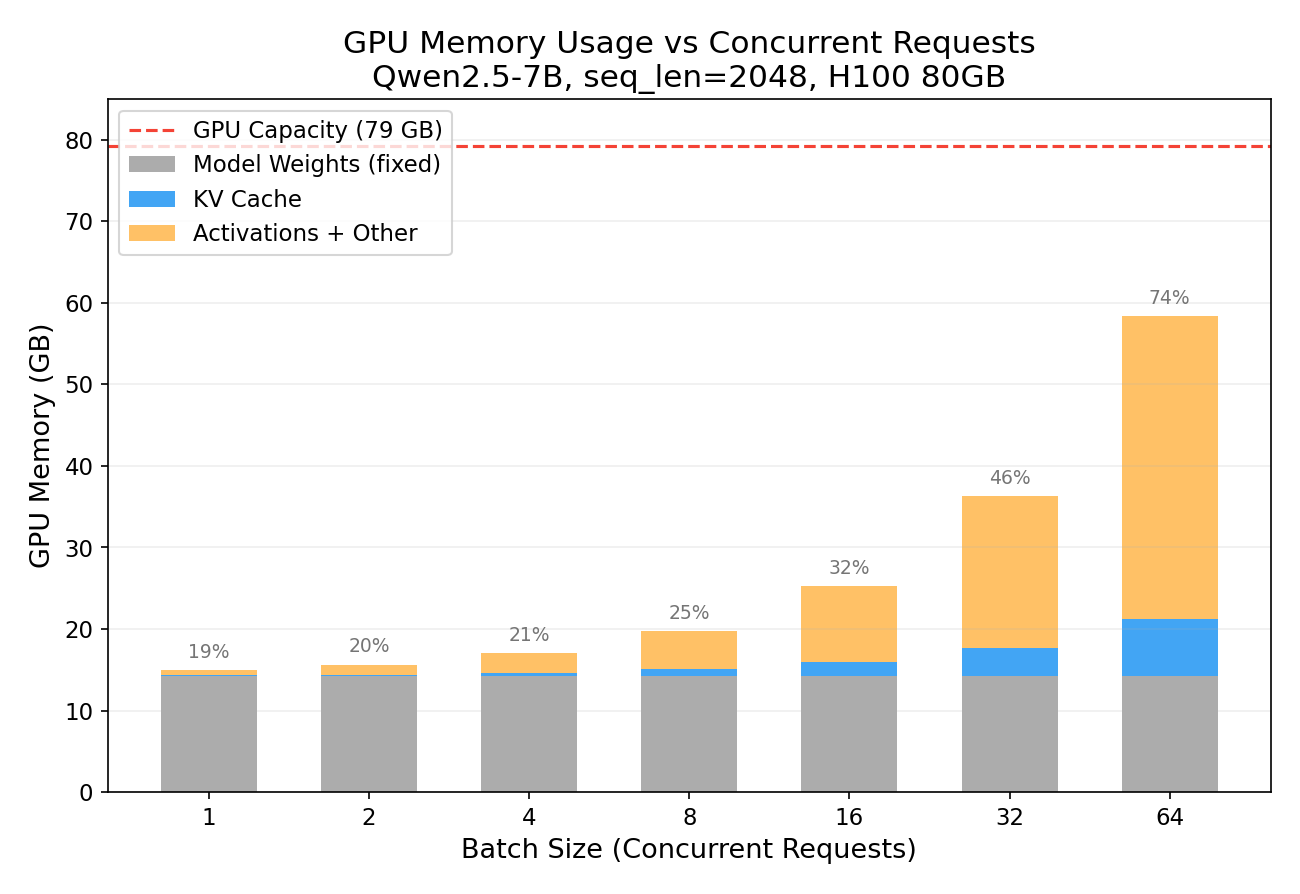
Understanding KV Cache in LLM Inference - Jingchao’s Website

KV-Cache Is the Real Latency Monster in Agentic Workloads | HackerNoon
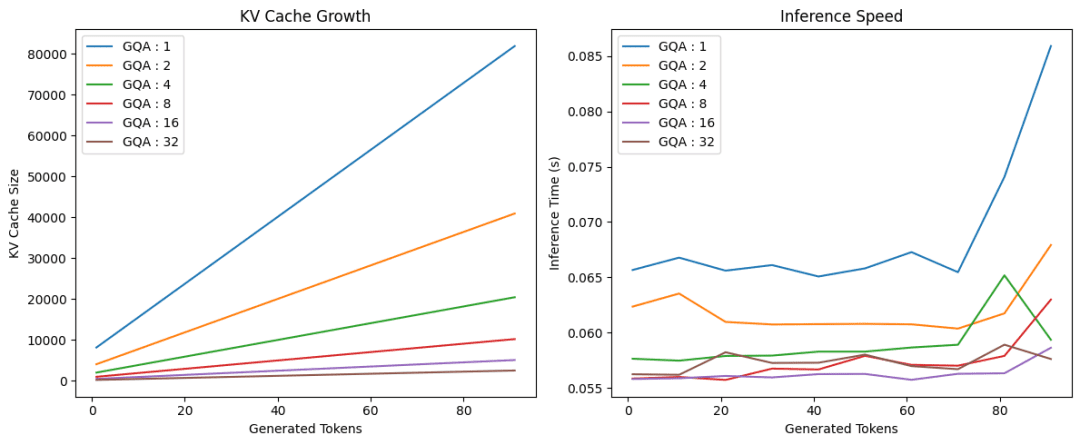
Introduction to KV Cache Optimization Utilizing Grouped Question ...