
Figure 1 From Dae Former Dual Attention Guided Efficient Transformer

Figure 1 from Efficient Dual Attention Transformer for Image Super ...
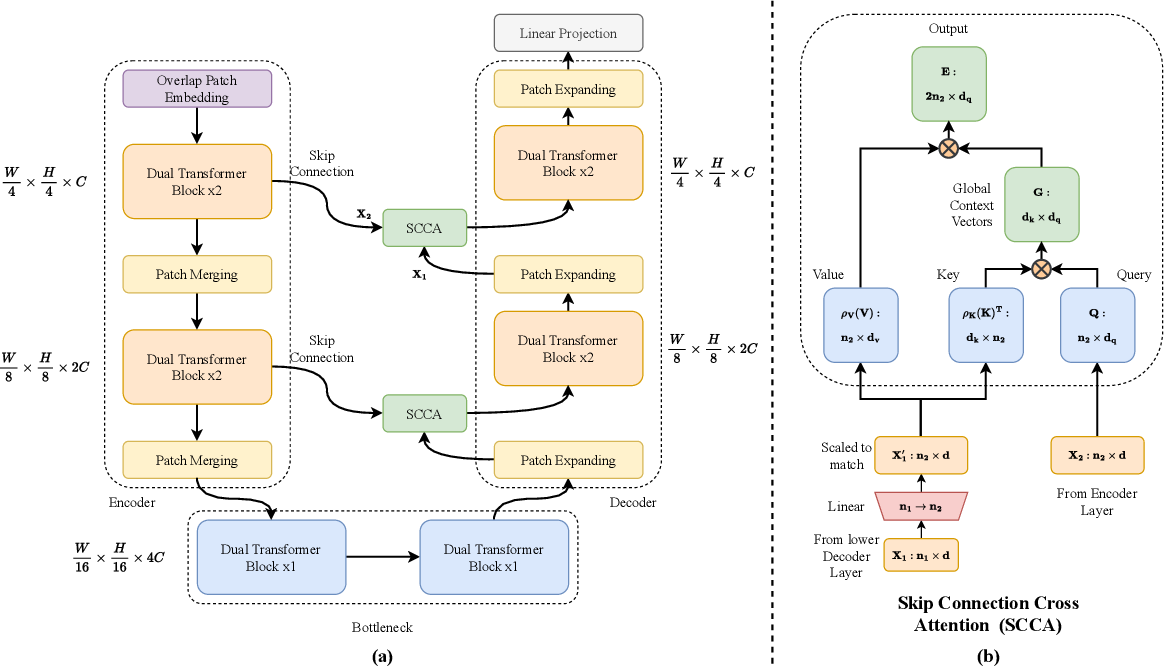
Figure 1 from DAE-Former: Dual Attention-guided Efficient Transformer ...
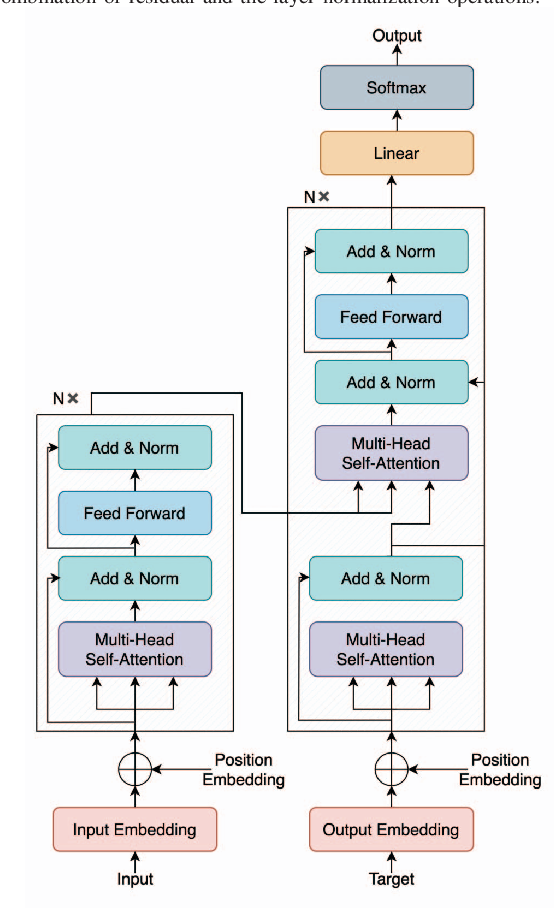
Figure 1 from An Efficient Transformer with Distance-aware Attention ...

Figure 1 from Exploring Attention Map Reuse for Efficient Transformer ...

Figure 2 from DAE-Former: Dual Attention-guided Efficient Transformer ...

Table 1 from DAE-Former: Dual Attention-guided Efficient Transformer ...
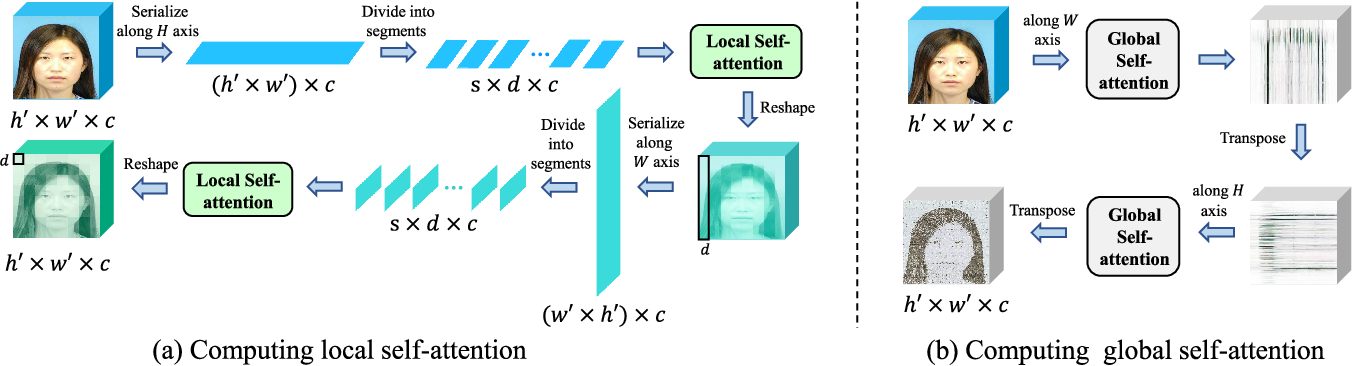
Figure 1 from An Efficient Transformer Based on Global and Local Self ...
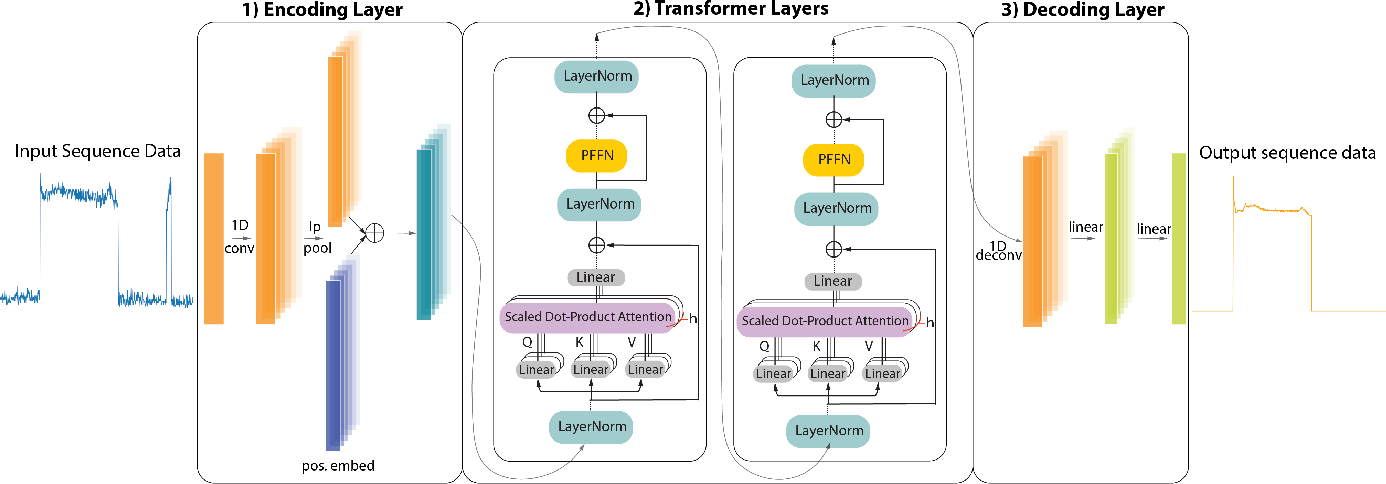
Figure 1 from An Efficient Deep Bidirectional Transformer Model for ...

Figure 1 from Knowing What it is: Semantic-Enhanced Dual Attention ...

Figure 1 from Efficient Transformer Inference with Statically ...
Advertisement Space (300x250)
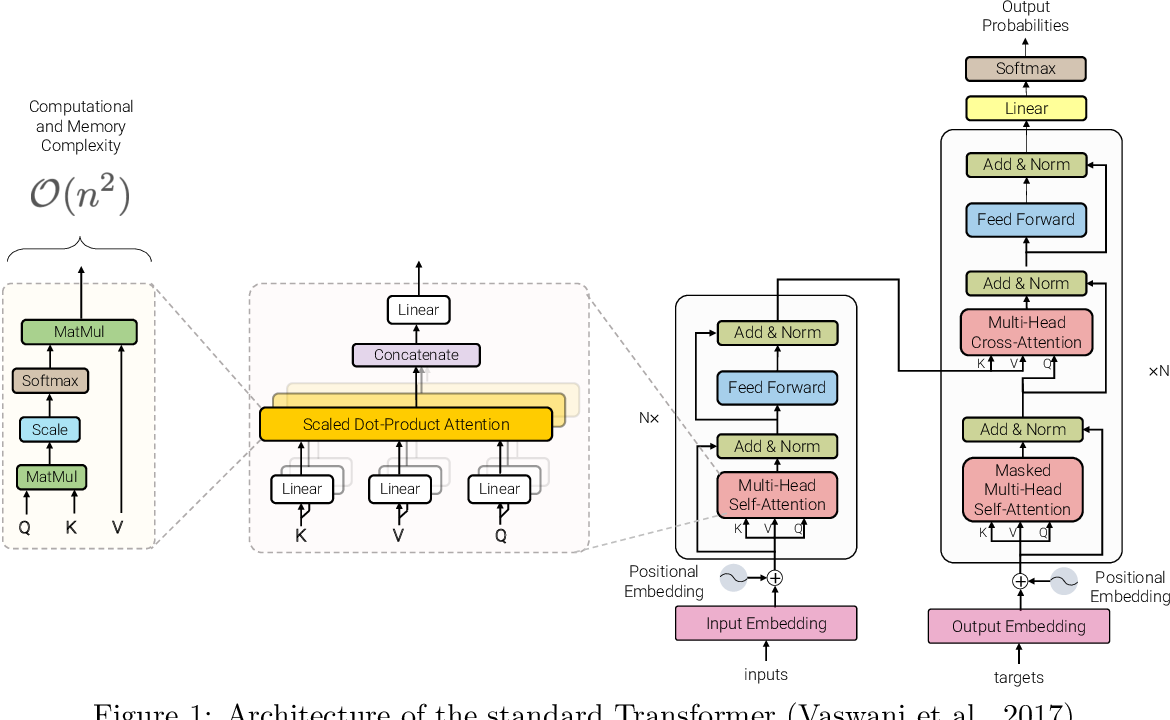
Figure 1 from Efficient Transformers: A Survey | Semantic Scholar
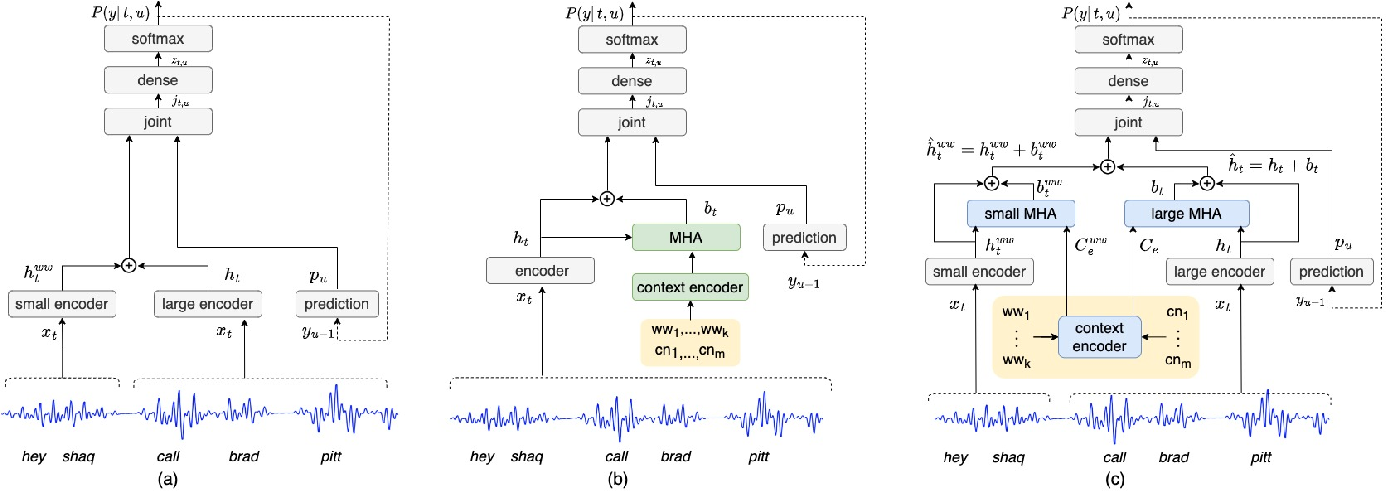
Figure 1 from Dual-Attention Neural Transducers for Efficient Wake Word ...
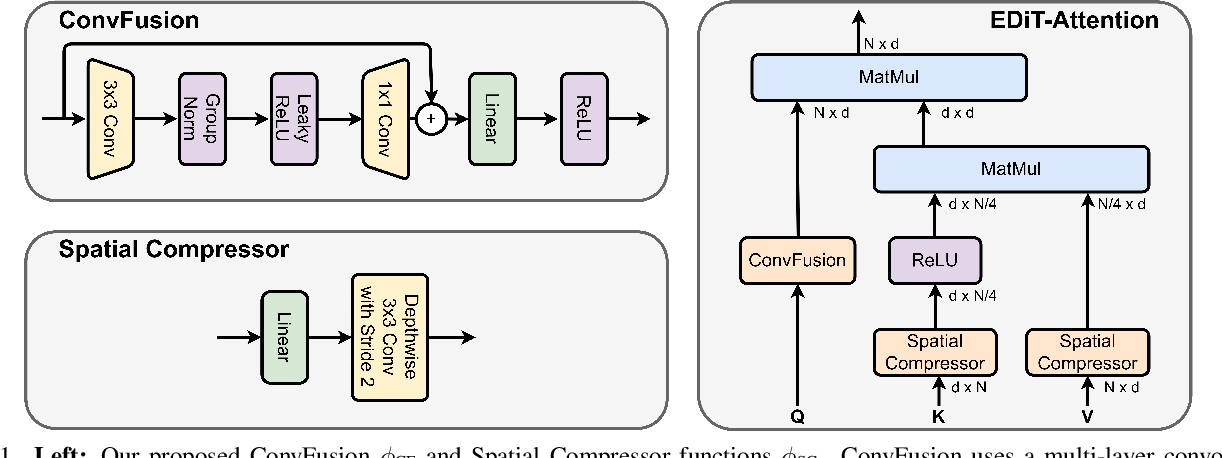
Figure 1 from Edit: Efficient Diffusion Transformers with Linear ...
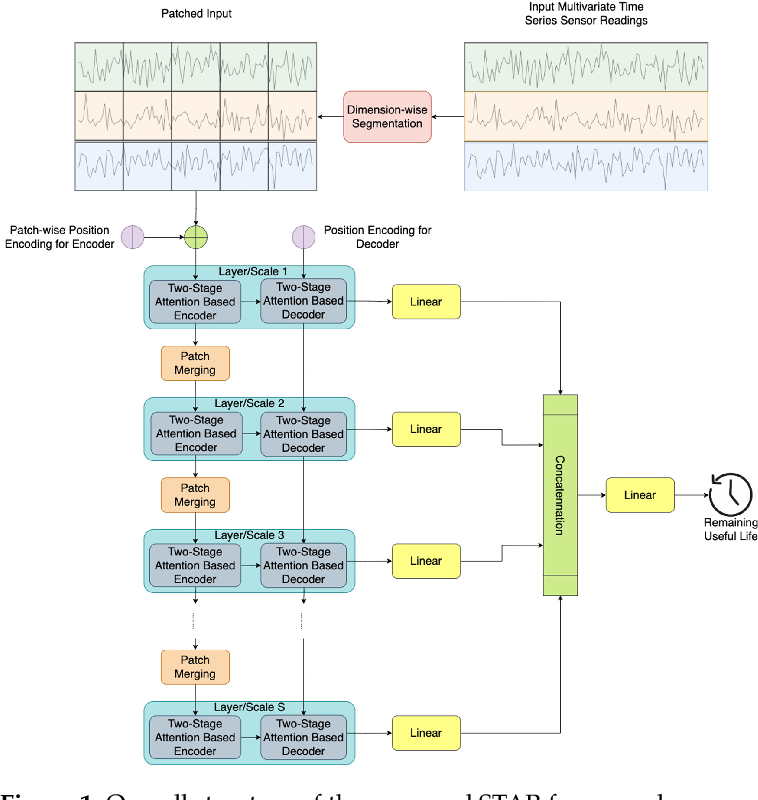
Figure 1 from A Two-Stage Attention-Based Hierarchical Transformer for ...

Figure 2 from ETMA: Efficient Transformer-Based Multilevel Attention ...

Figure 2 from Dual-path Transformer Based On Efficient Channel ...

Figure 1 from KSCAMa: A Lightweight Mamba Network Enhanced with Dual ...

Figure 2 from Knowing What it is: Semantic-Enhanced Dual Attention ...

Figure 1 from An Exploration of Hierarchical Attention Transformers for ...

Figure 1 from Improving Deep Transformer with Depth-Scaled ...
Advertisement Space (336x280)
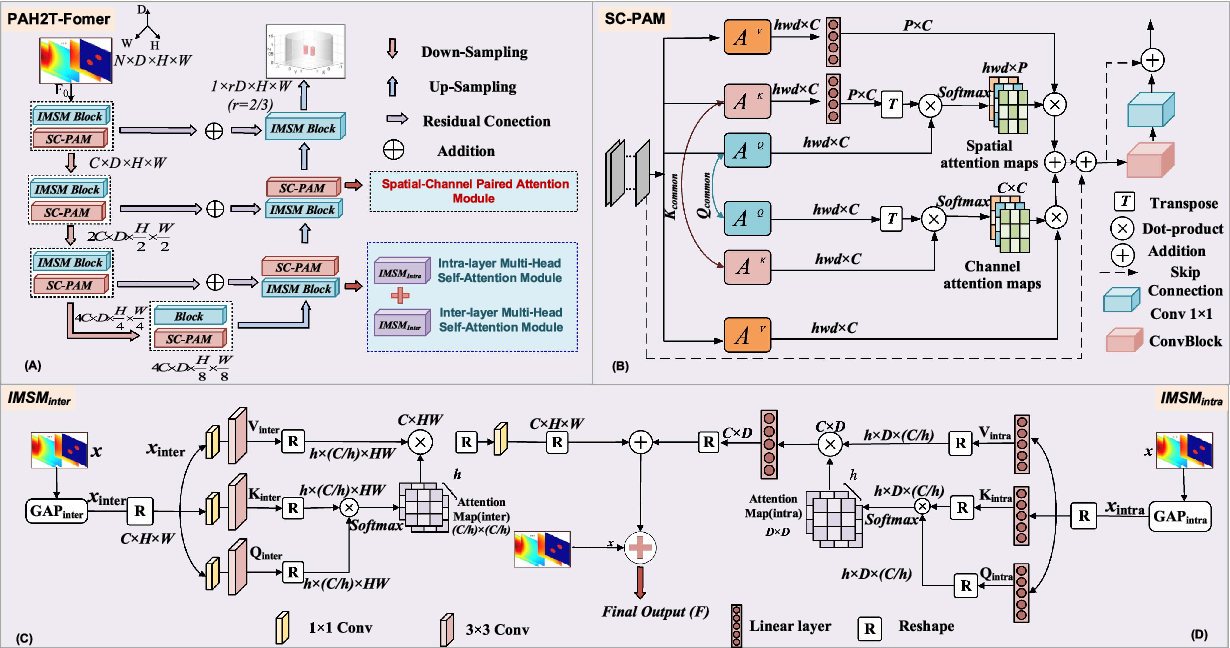
Figure 1 from PAH2T-Former: Paired-Attention Hybrid Hierarchical ...

(PDF) DAE-Former: Dual Attention-guided Efficient Transformer for ...
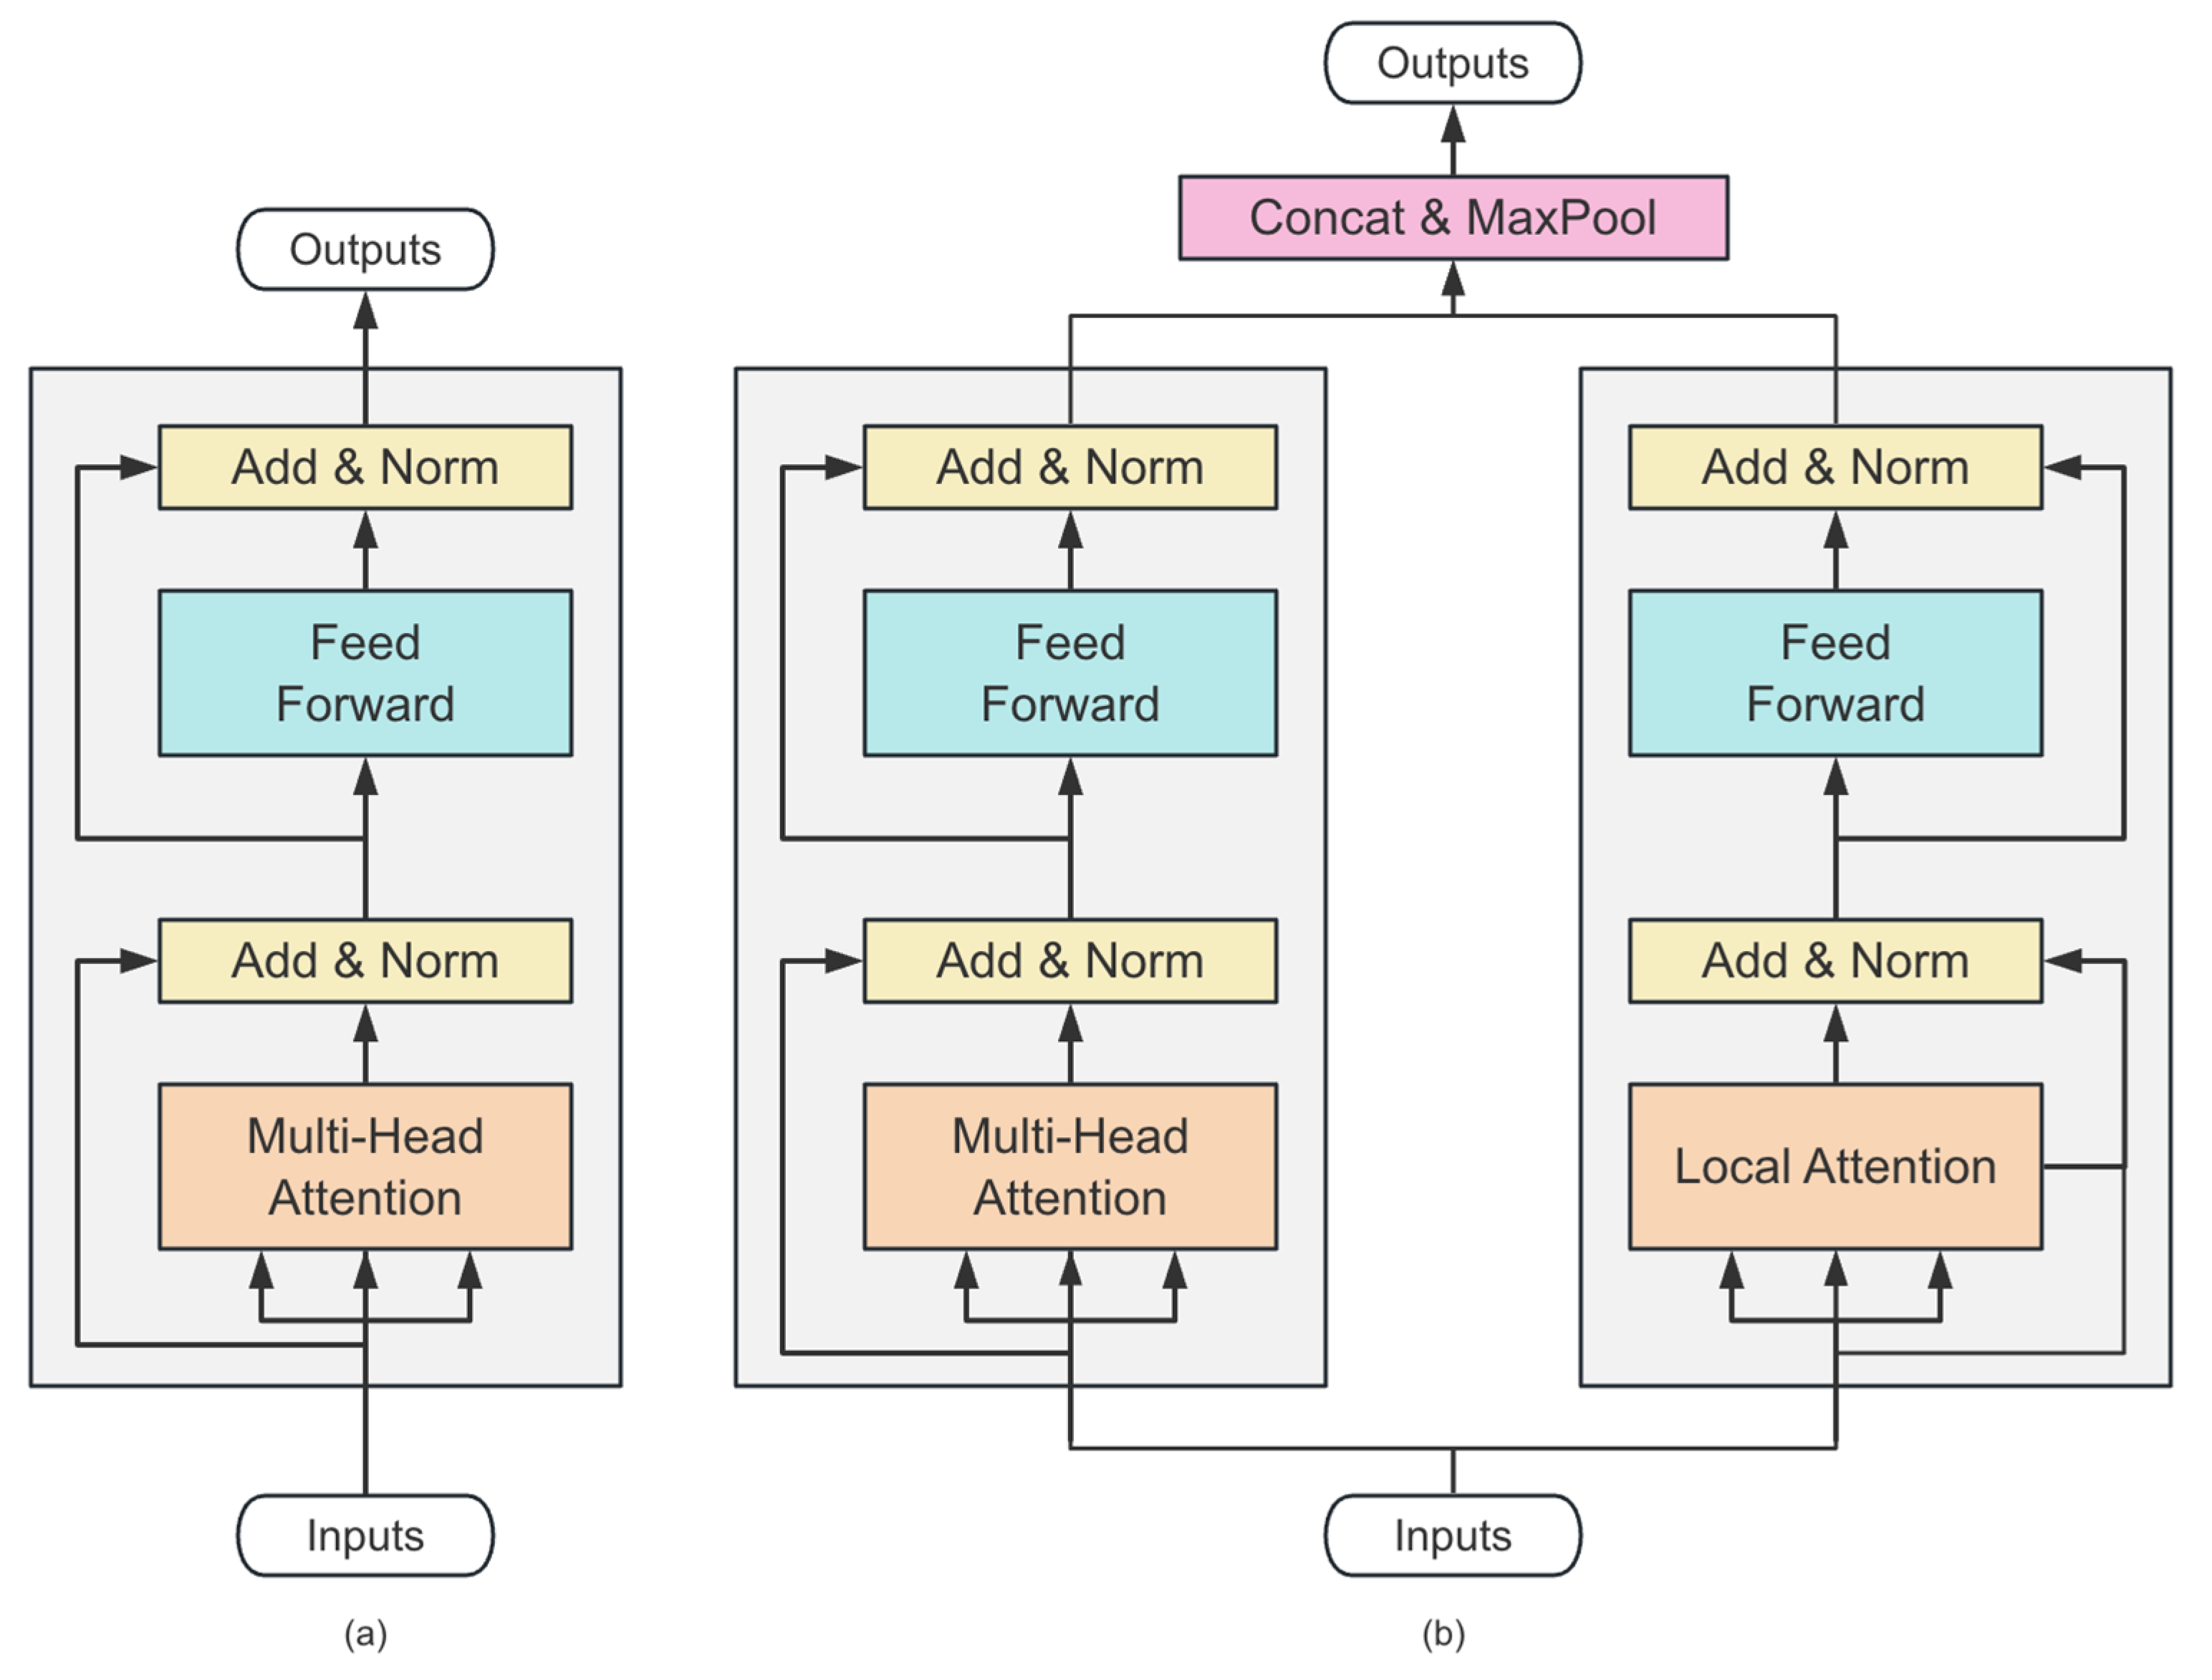
TTDAT: Two-Step Training Dual Attention Transformer for Malware ...

TransDAE: Dual Attention Mechanism in a Hierarchical Transformer for ...
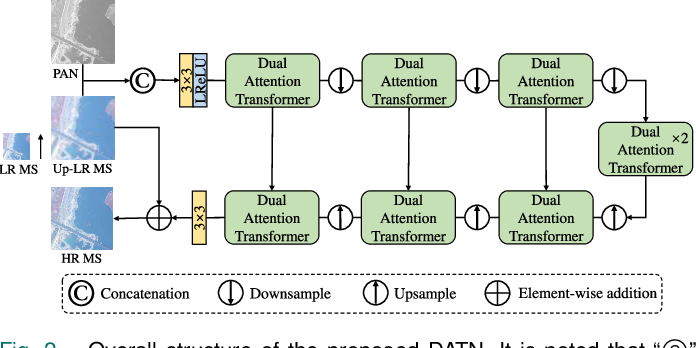
Figure 2 from A Dual-Attention Transformer Network for Pansharpening ...

Figure 2 from Accelerating Transformers with Fourier-Based Attention ...

Query-Based Instance Segmentation with Dual Attention Transformer for ...

Figure 3 from Dual-former: Hybrid Self-attention Transformer for ...

Exploring Attention Map Reuse for Efficient Transformer Neural Networks

Figure 4 from Scene Text Image Super-Resolution via Anchor Point Guided ...
Advertisement Space (336x280)

(PDF) ParaFormer: Parallel Attention Transformer for Efficient Feature ...
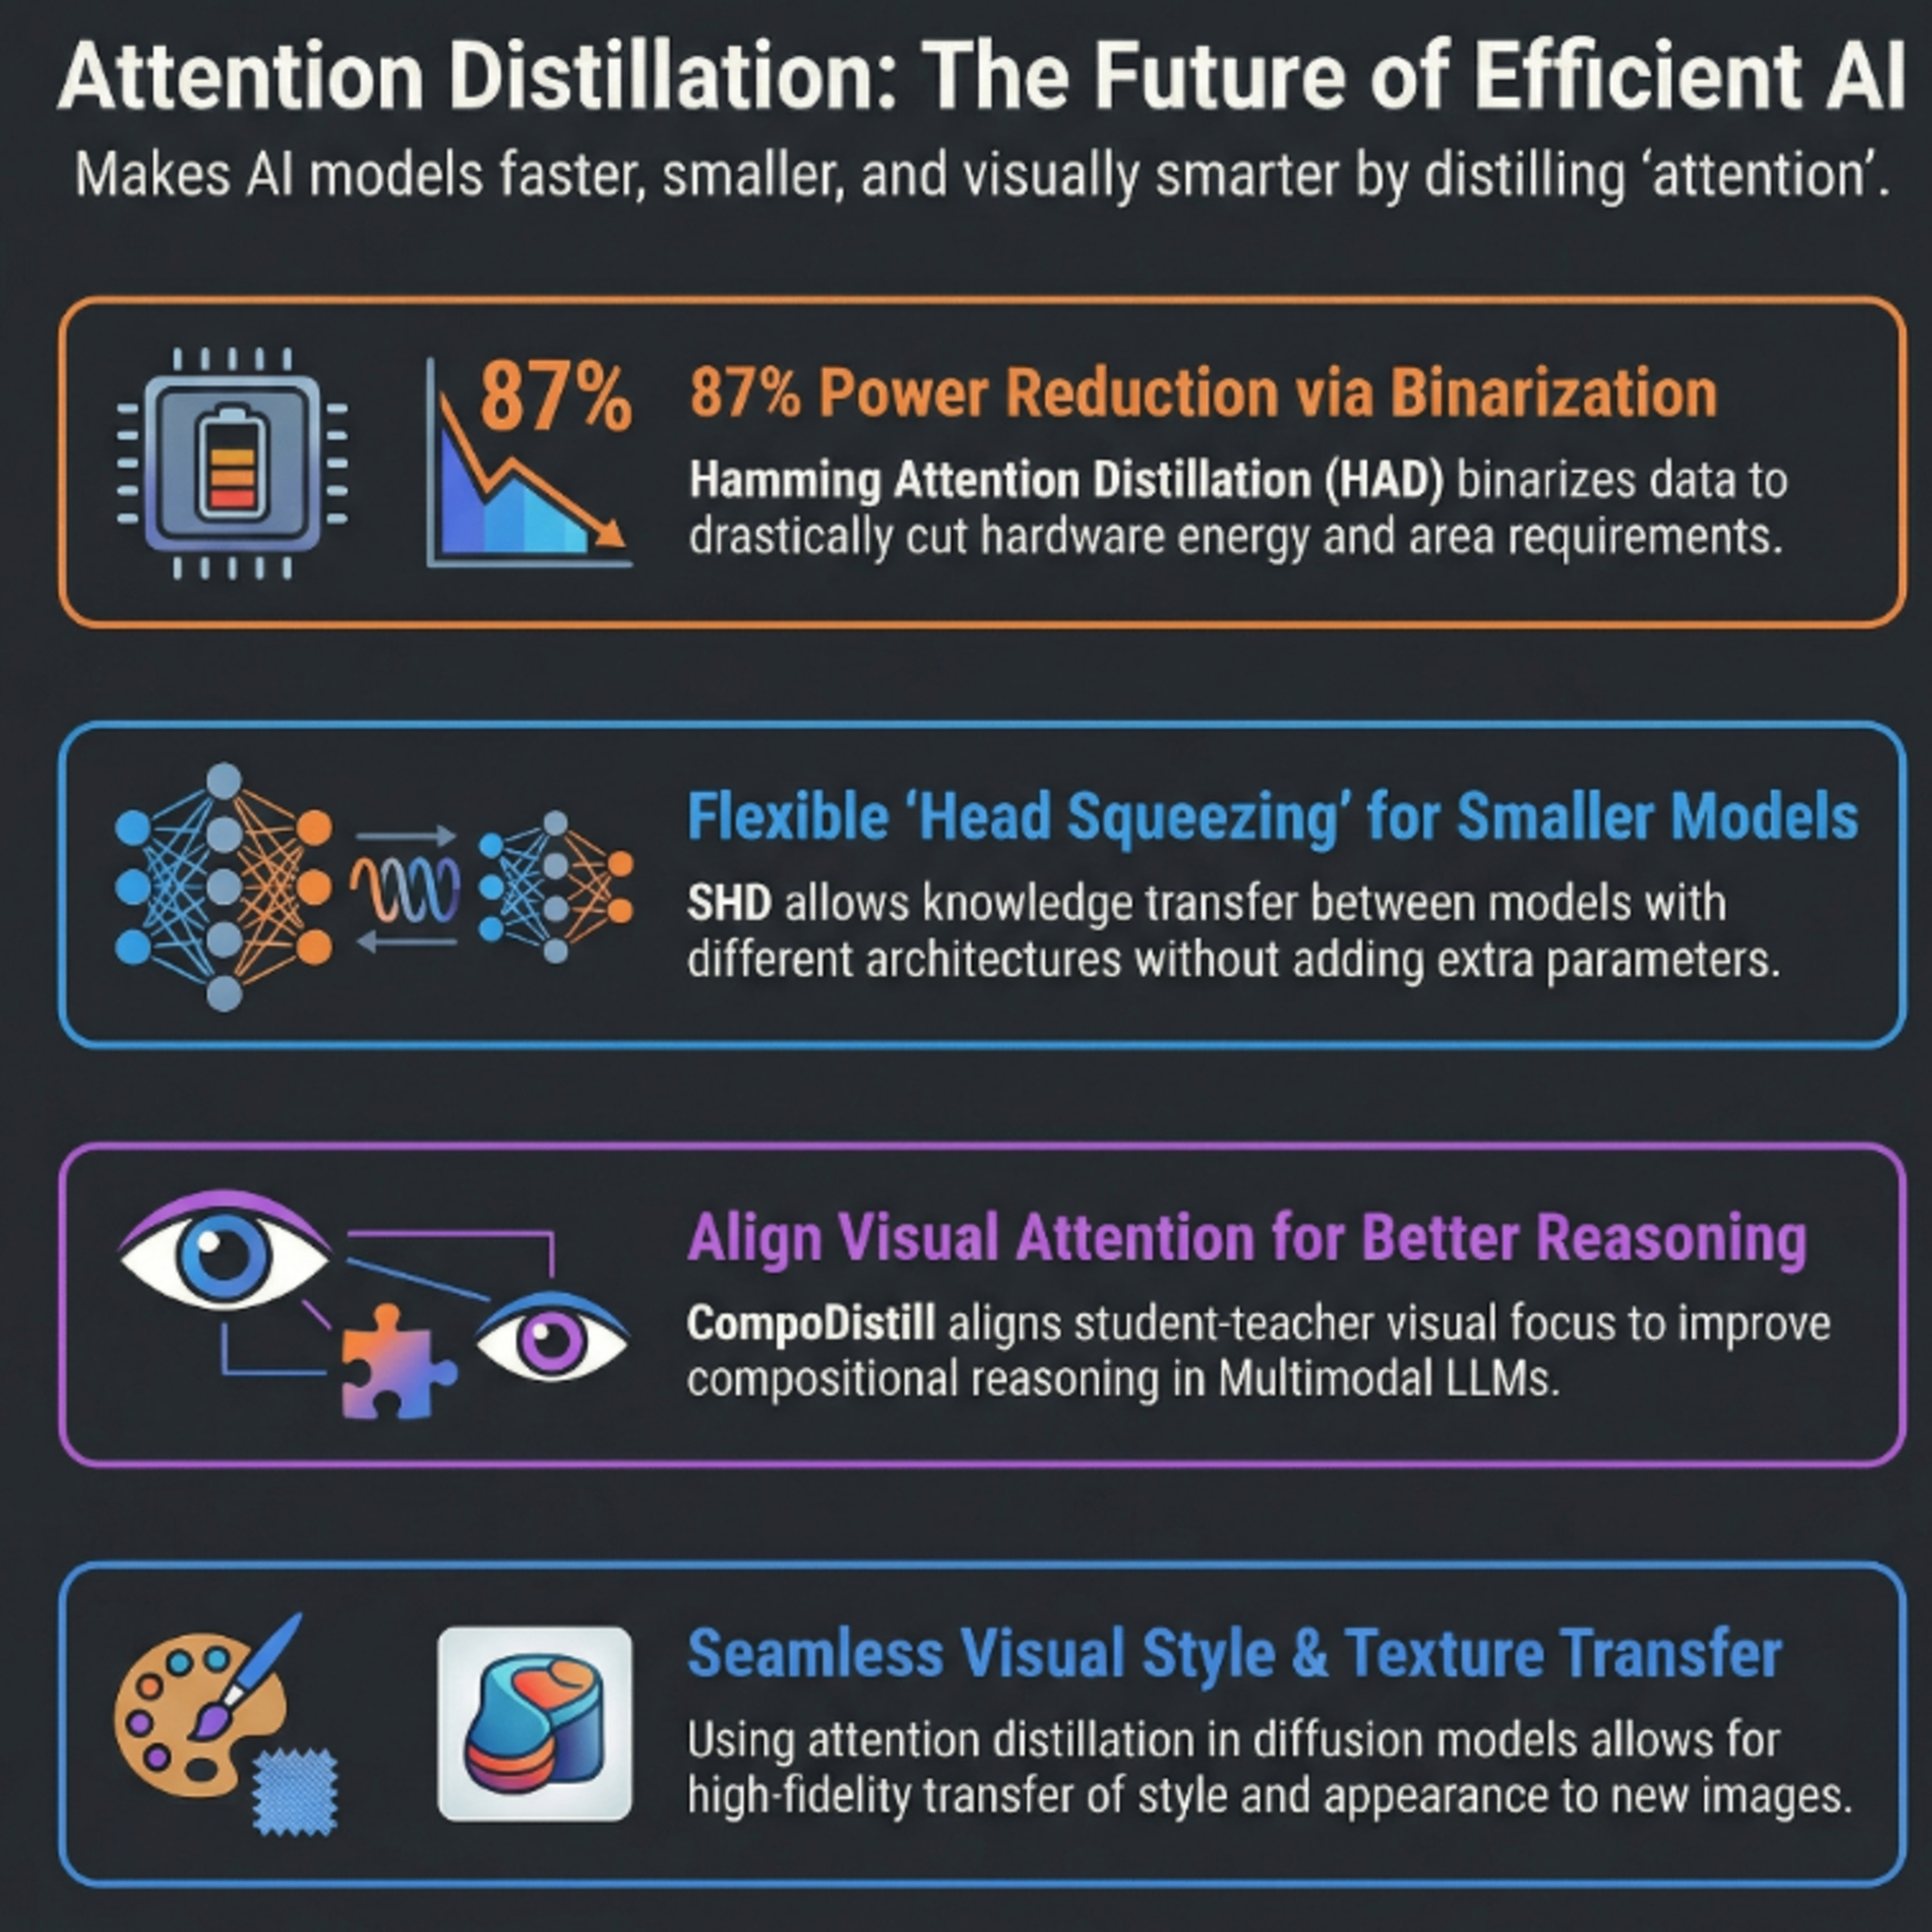
Advances in Attention Distillation for Efficient Transformer Models ...
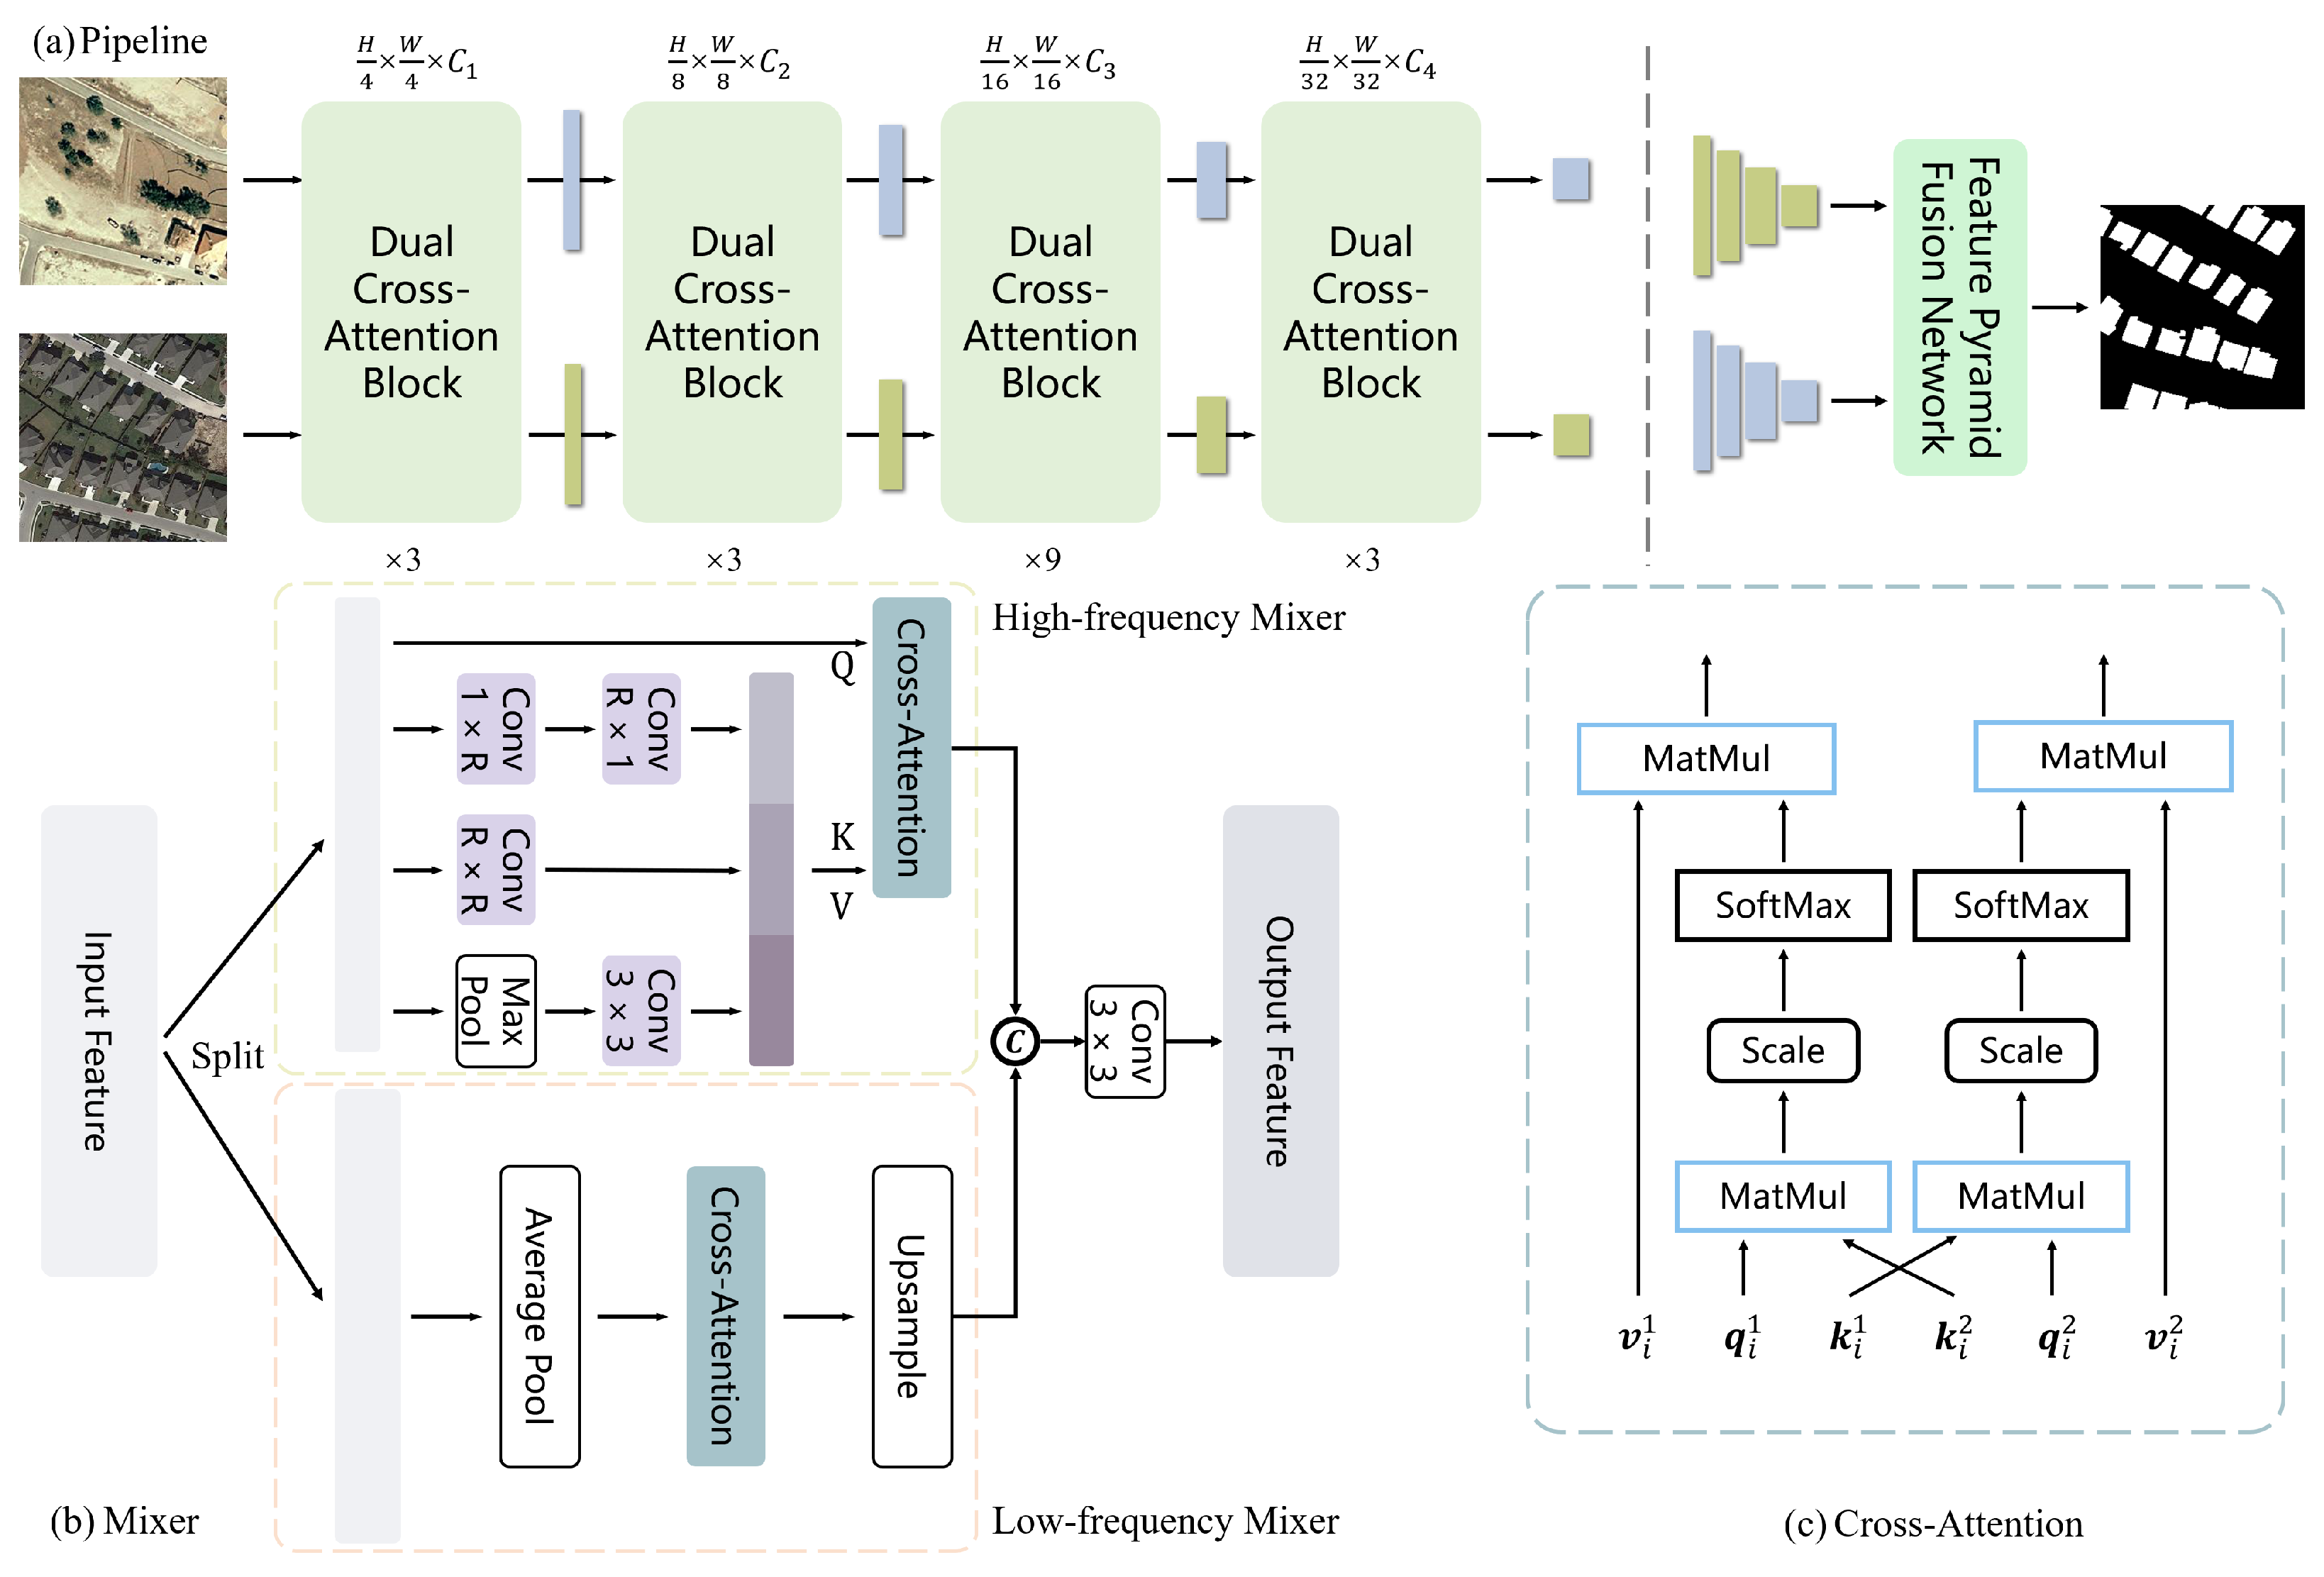
DCAT: Dual Cross-Attention-Based Transformer for Change Detection

is Multi-head Attention mechanism layer in Efficient Transformer, 1×1 ...

Dual-former: Hybrid Self-attention Transformer for Efficient Image ...
GitHub - xmindflow/DAEFormer: [MICCAI 2023] DAE-Former: Dual Attention ...