
Table 1 From Dae Former Dual Attention Guided Efficient Transformer

Table 1 from DAE-Former: Dual Attention-guided Efficient Transformer ...

Table 1 from Dual Path Transformer with Partition Attention | Semantic ...

Figure 1 from Efficient Dual Attention Transformer for Image Super ...
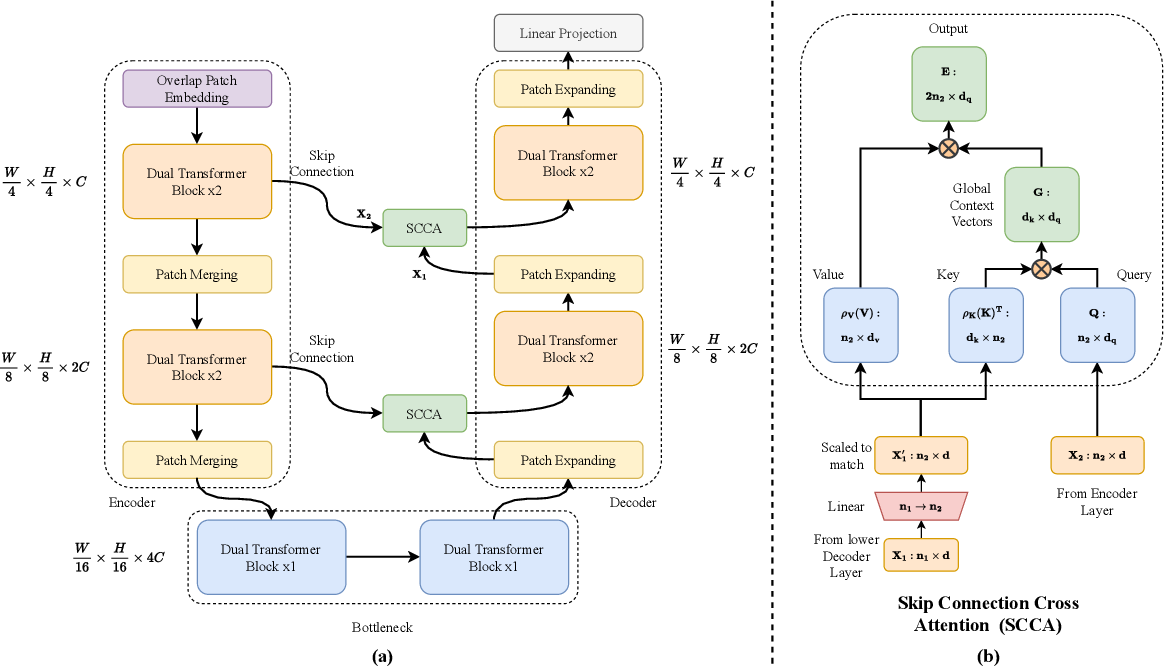
Figure 1 from DAE-Former: Dual Attention-guided Efficient Transformer ...

Figure 1 from Dual Path Transformer with Partition Attention | Semantic ...

Figure 1 from Dual Path Transformer with Partition Attention | Semantic ...
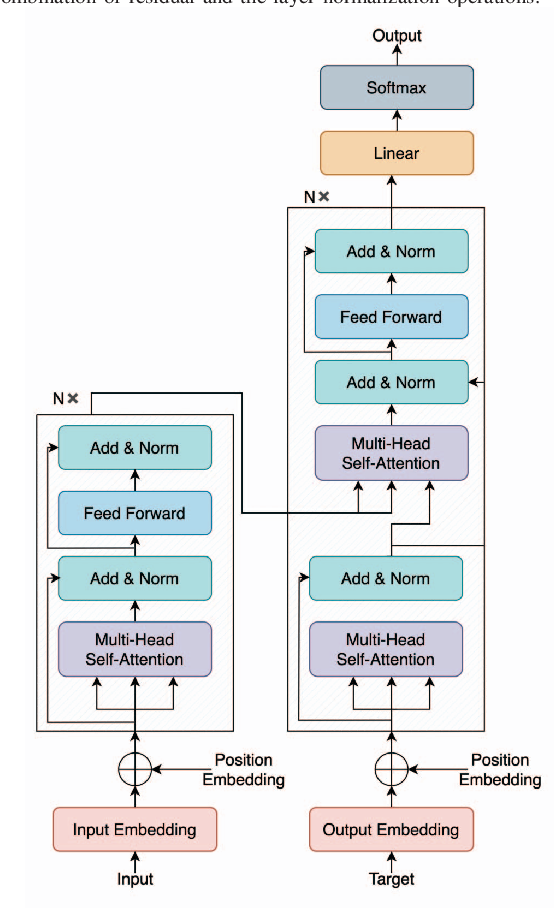
Figure 1 from An Efficient Transformer with Distance-aware Attention ...

Figure 1 from Exploring Attention Map Reuse for Efficient Transformer ...
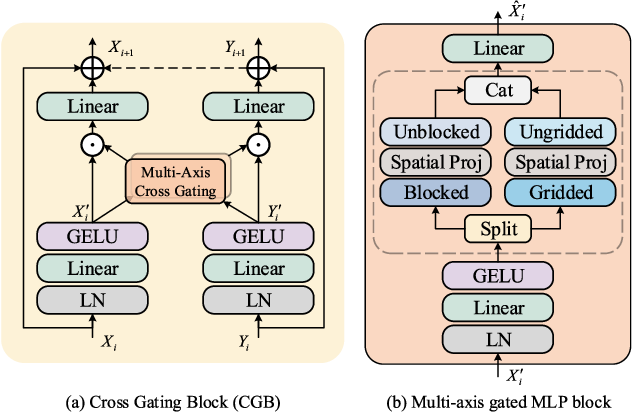
Figure 4 from A Prior Guided Wavelet-Spatial Dual Attention Transformer ...
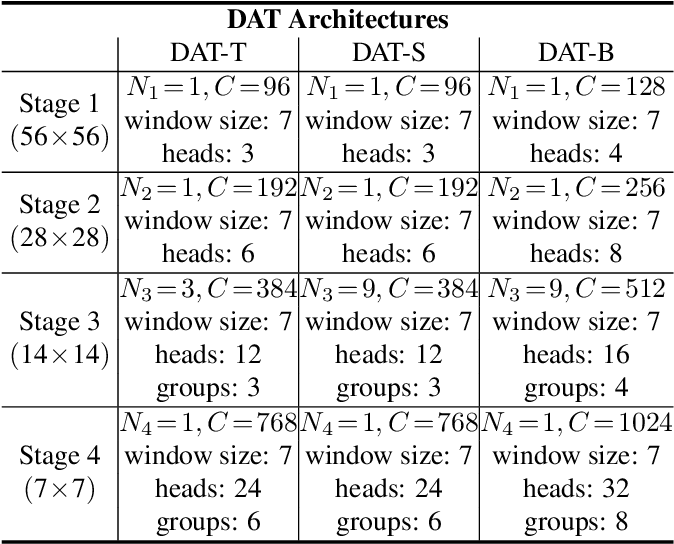
Table 1 from Vision Transformer with Deformable Attention | Semantic ...
Advertisement Space (300x250)

Figure 2 from DAE-Former: Dual Attention-guided Efficient Transformer ...

Table 1 from Fractal-Guided Token Pruning for Efficient Vision ...

Table 1 from An Exploration of Hierarchical Attention Transformers for ...
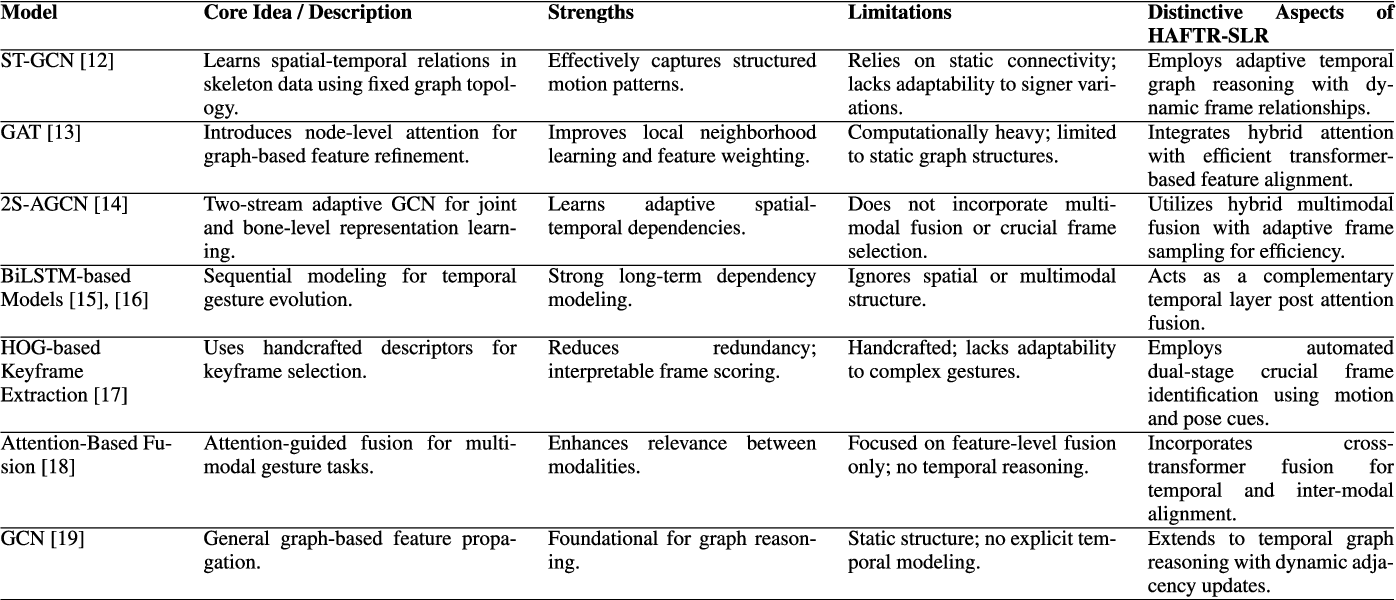
Table 1 from An Efficient Hybrid Attention-Guided Frame-Wise Temporal ...

Table 1 from DAGformer: Directed Acyclic Graph Transformer | Semantic ...

Table 1 from Learning Image Deraining Transformer Network with Dynamic ...

Figure 1 from Efficient Transformer Inference with Statically ...

(PDF) DAE-Former: Dual Attention-guided Efficient Transformer for ...
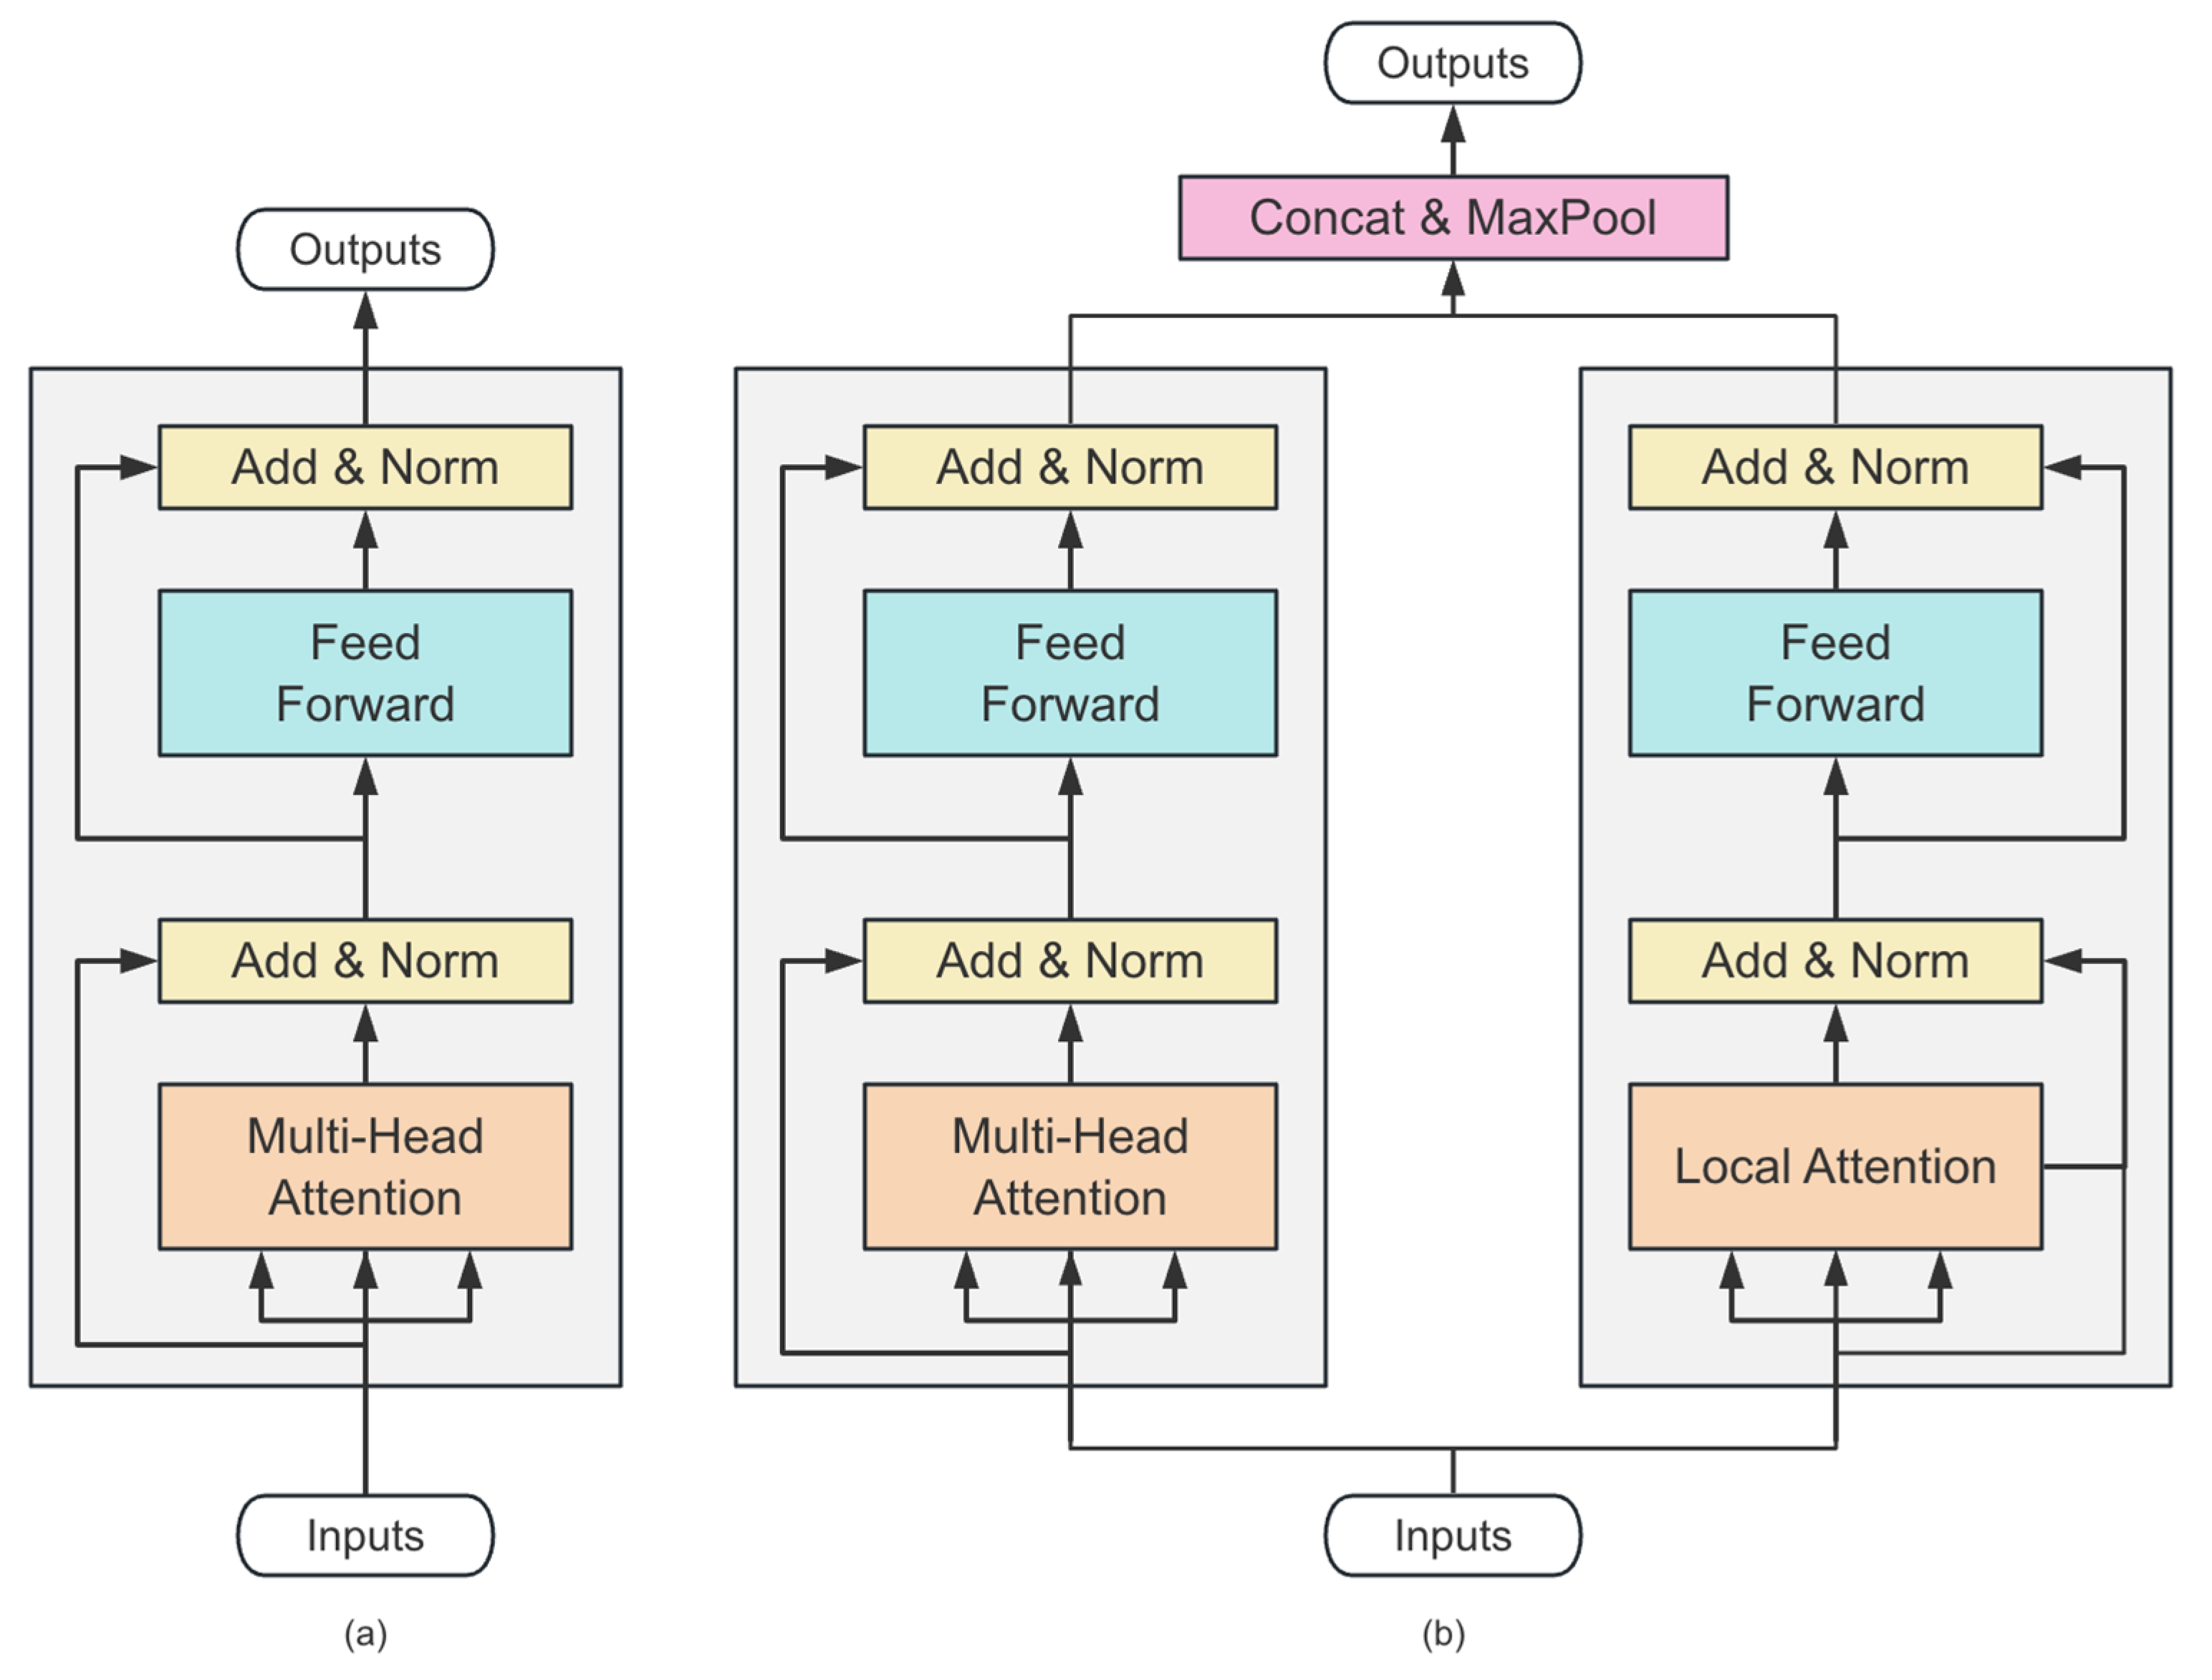
TTDAT: Two-Step Training Dual Attention Transformer for Malware ...

TransDAE: Dual Attention Mechanism in a Hierarchical Transformer for ...
Advertisement Space (336x280)

Table I from Accelerating Transformers with Fourier-Based Attention for ...

Figure 2 from Dual-path Transformer Based On Efficient Channel ...
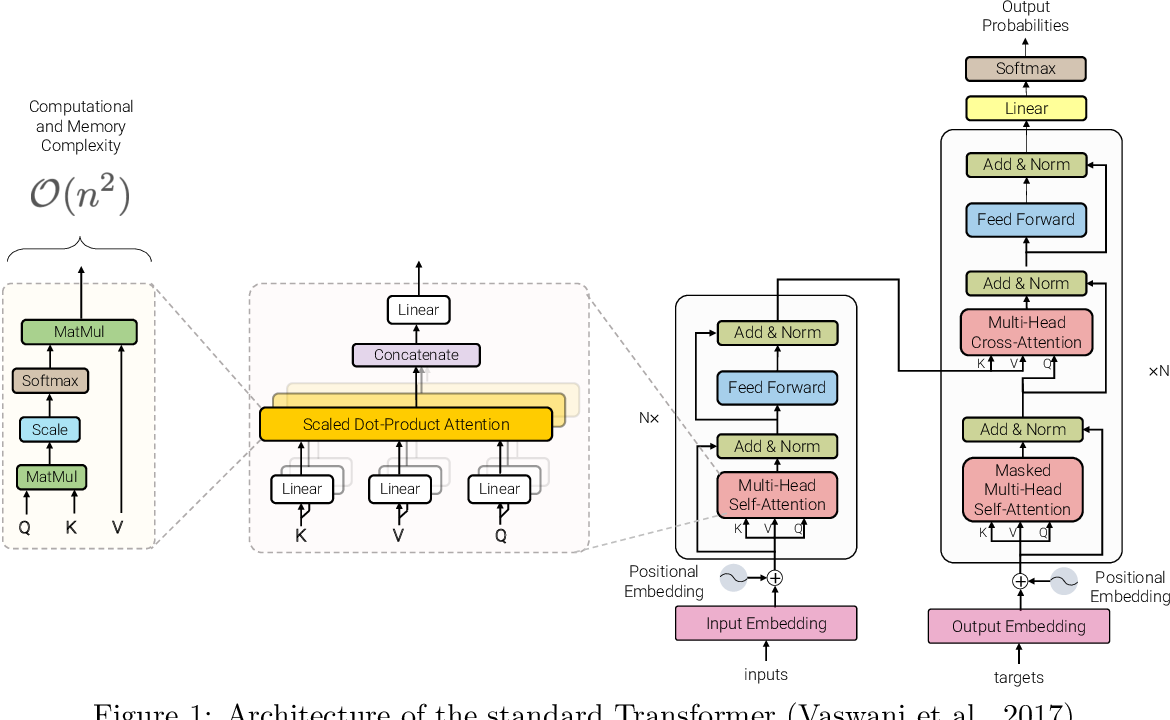
Figure 1 from Efficient Transformers: A Survey | Semantic Scholar

DAE-Former: Dual Attention-Guided Efficient Transformer for Medical ...
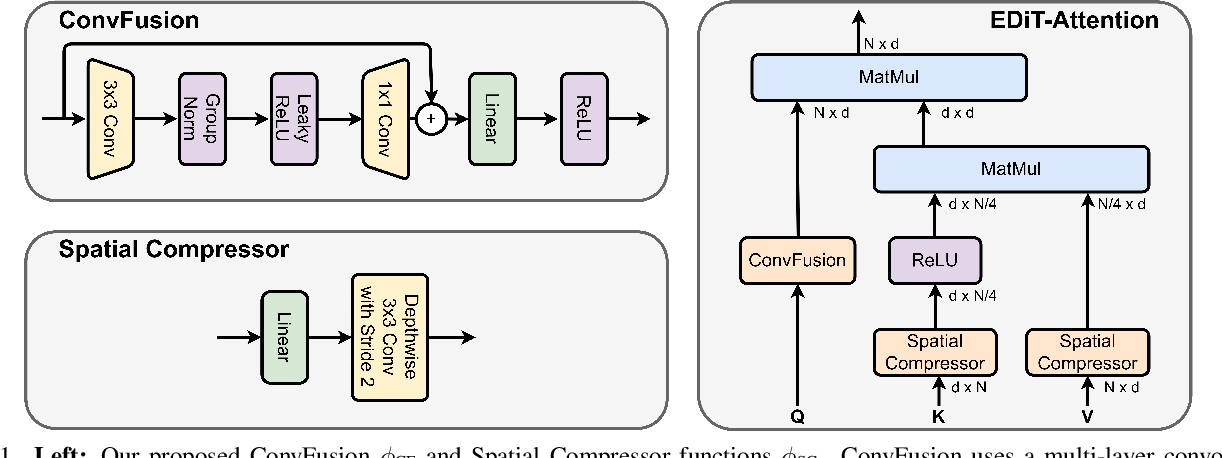
Figure 1 from Edit: Efficient Diffusion Transformers with Linear ...

Figure 2 from ETMA: Efficient Transformer-Based Multilevel Attention ...

ParaFormer: Parallel Attention Transformer for Efficient Feature ...

(PDF) DBA: Efficient Transformer with Dynamic Bilinear Low-Rank Attention

Table 2 from The Inhibitor: ReLU and Addition-Based Attention for ...

Exploring Attention Map Reuse for Efficient Transformer Neural Networks
Advertisement Space (336x280)

Figure 2 from LADA-Trans-NER: Adaptive Efficient Transformer for ...

Figure 1 from KSCAMa: A Lightweight Mamba Network Enhanced with Dual ...
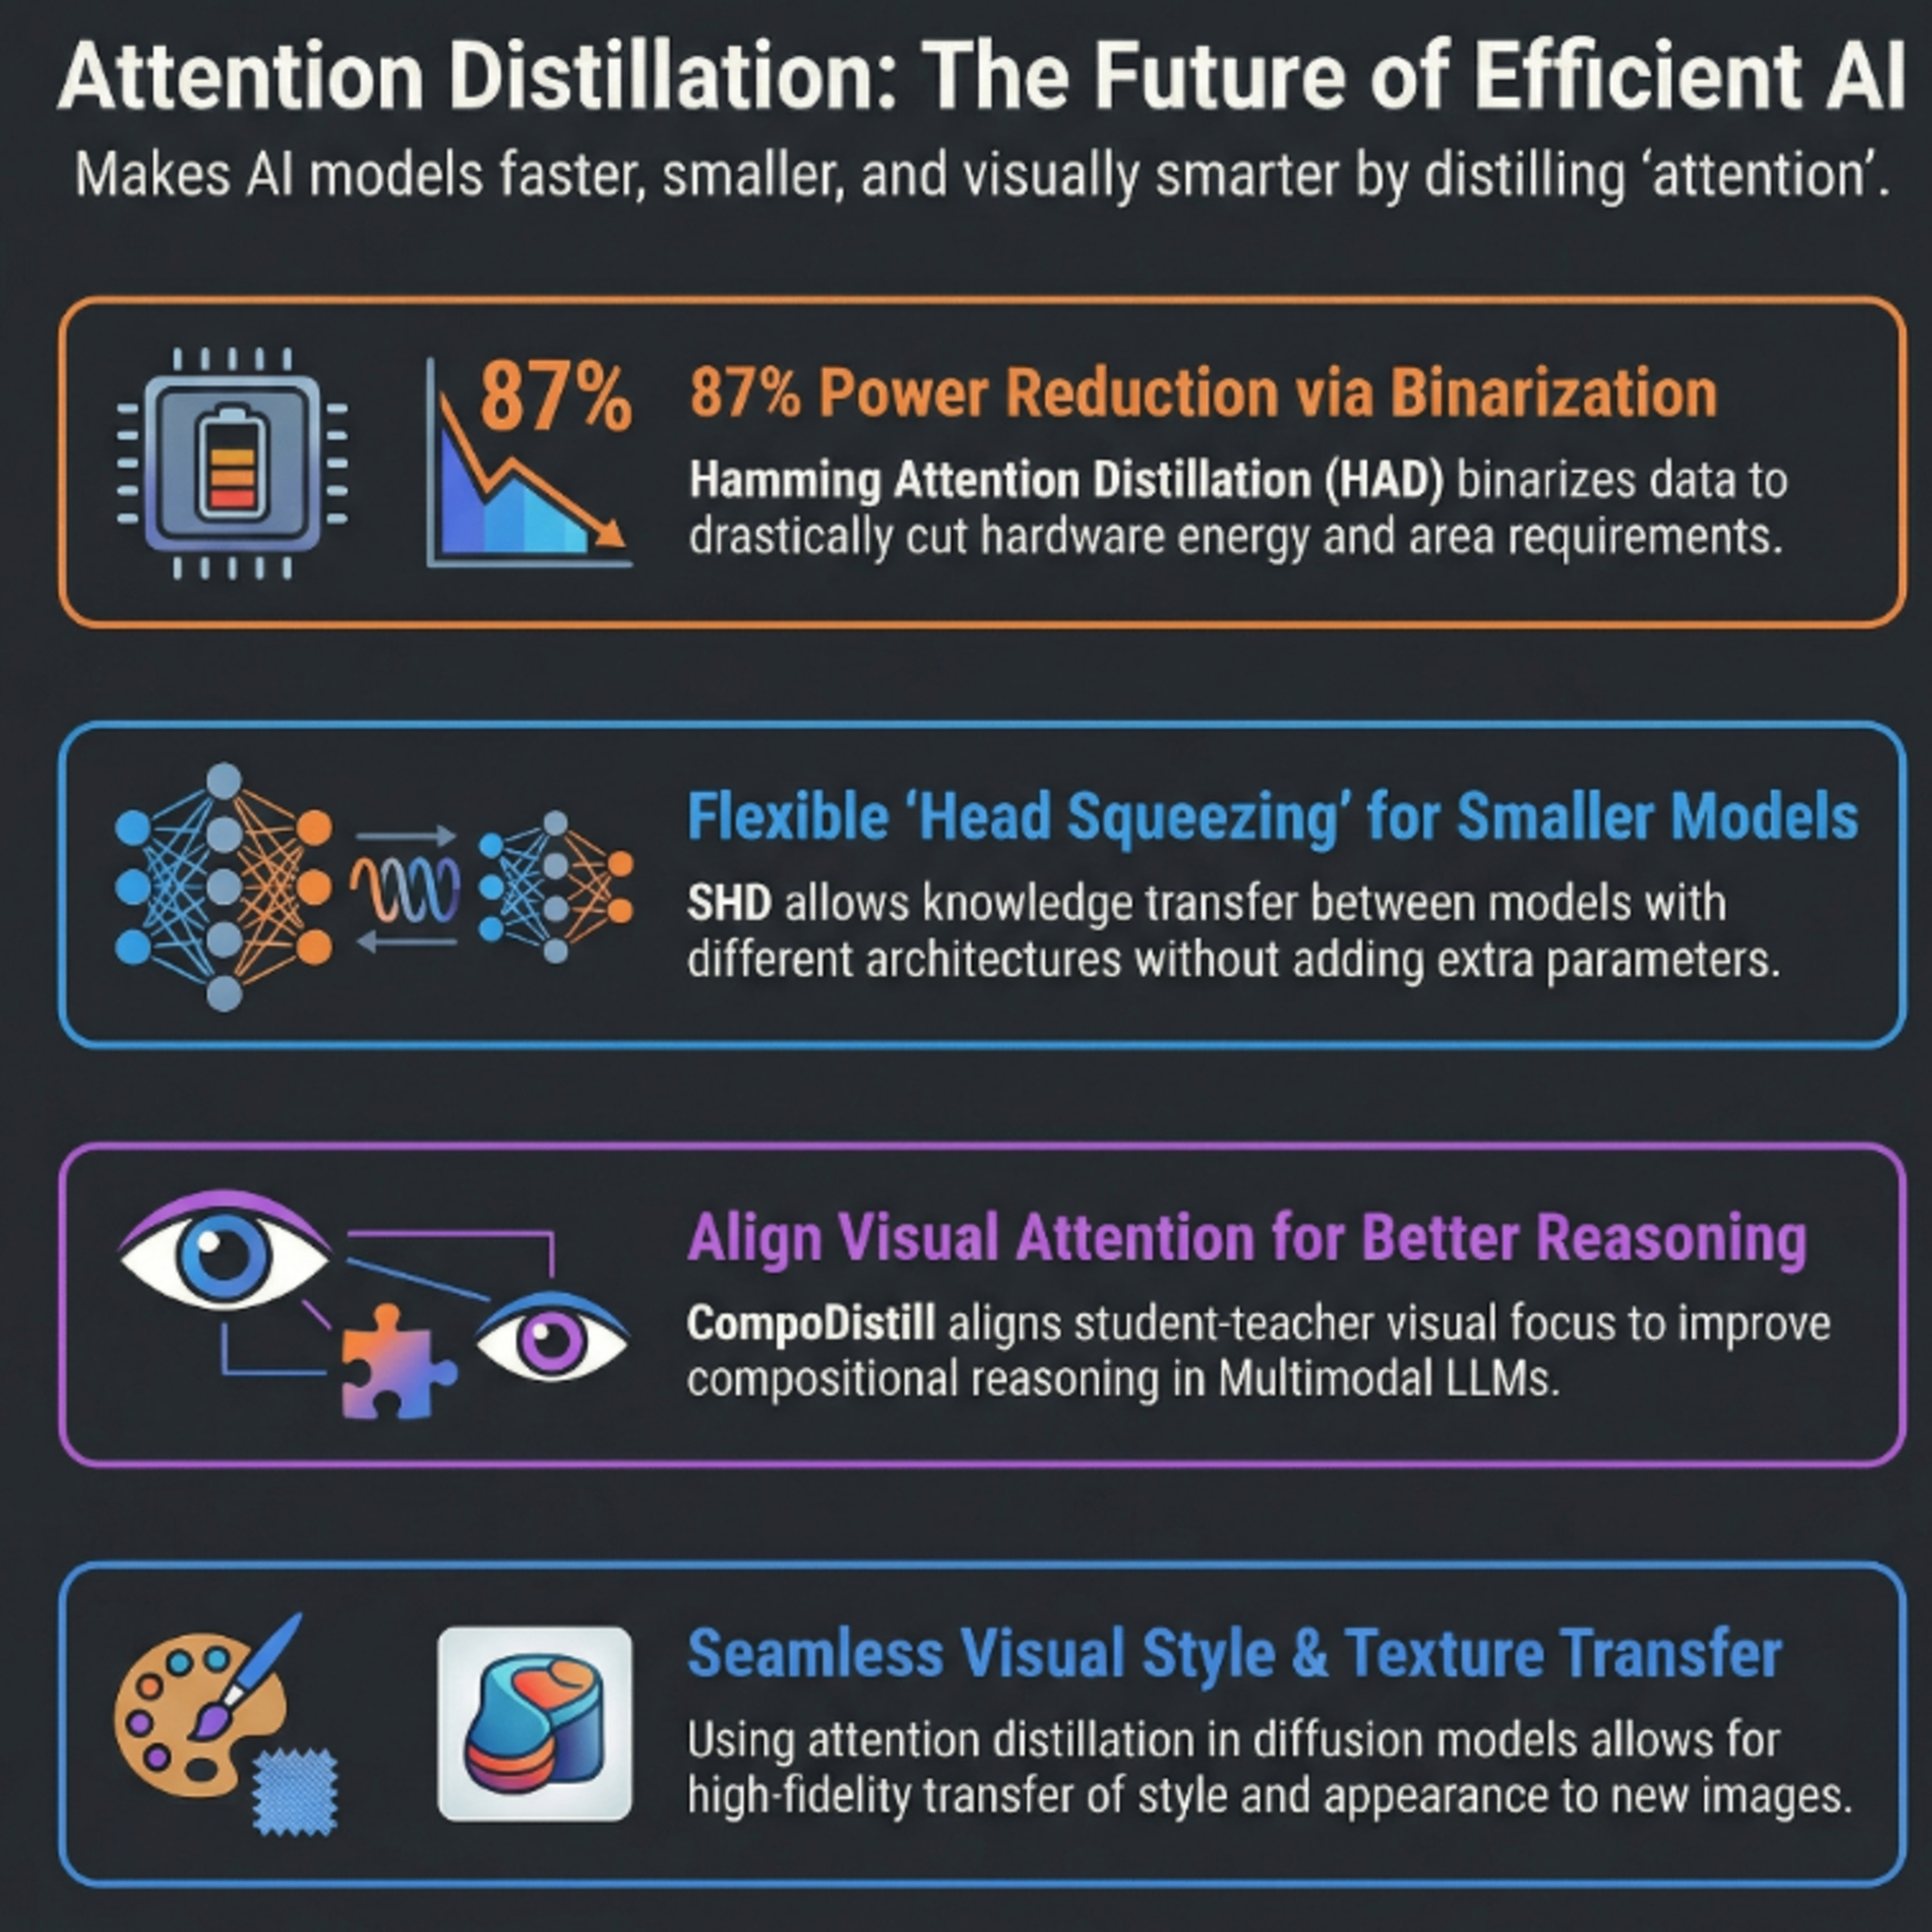
Advances in Attention Distillation for Efficient Transformer Models ...

(PDF) Attention Guided Alignment in Efficient Vision-Language Models
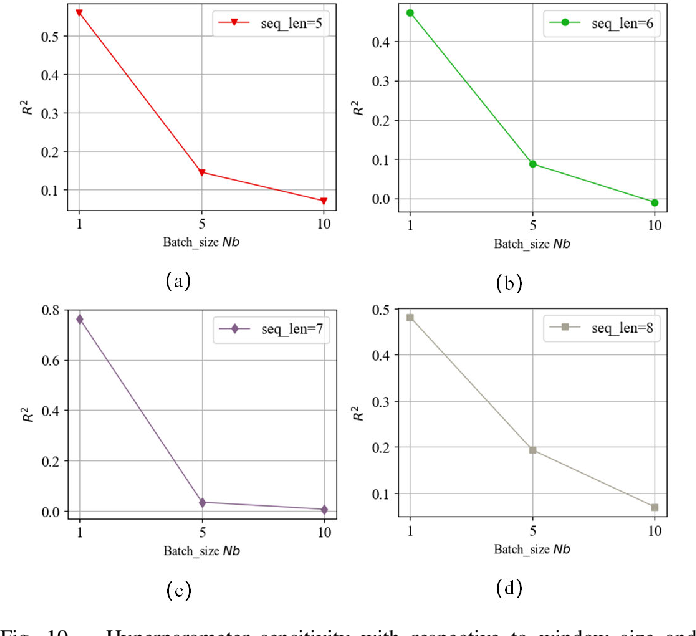
Figure 10 from Dual Cross-Attention Transformer Networks for Temporal ...
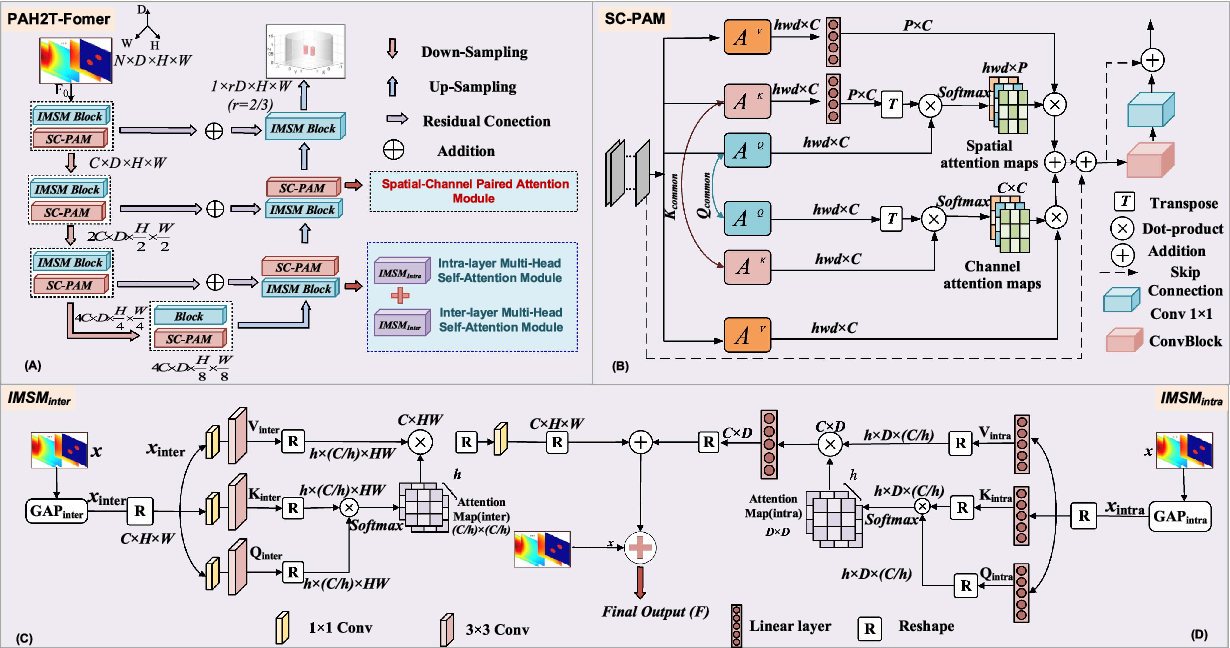
Figure 1 from PAH2T-Former: Paired-Attention Hybrid Hierarchical ...