
Figure 1 From Joint Audio And Speech Understanding Semantic Scholar
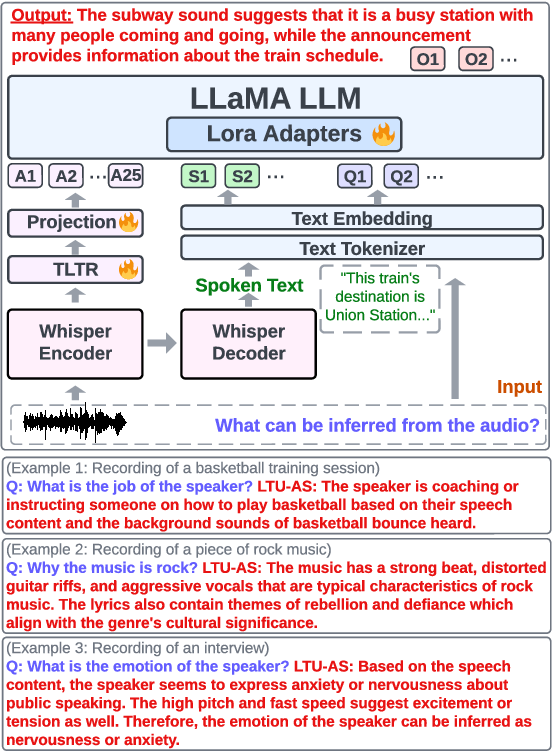
Figure 1 from Joint Audio and Speech Understanding | Semantic Scholar

Figure 1 from Joint Audio and Speech Understanding | Semantic Scholar
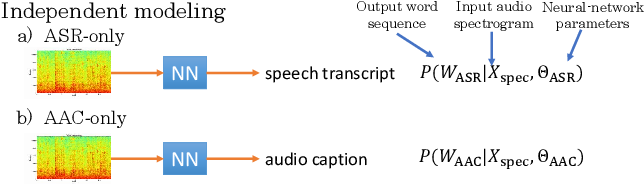
Figure 1 from Joint Speech Recognition and Audio Captioning | Semantic ...
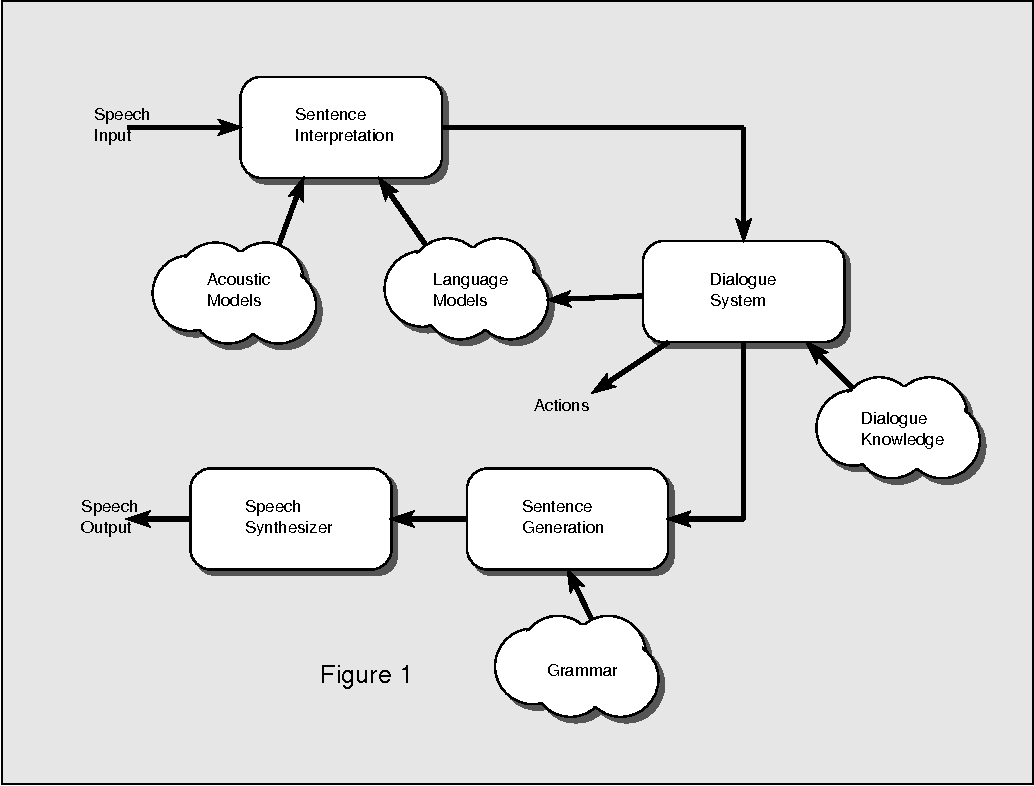
Figure 1 from Speech and Signal Understanding | Semantic Scholar
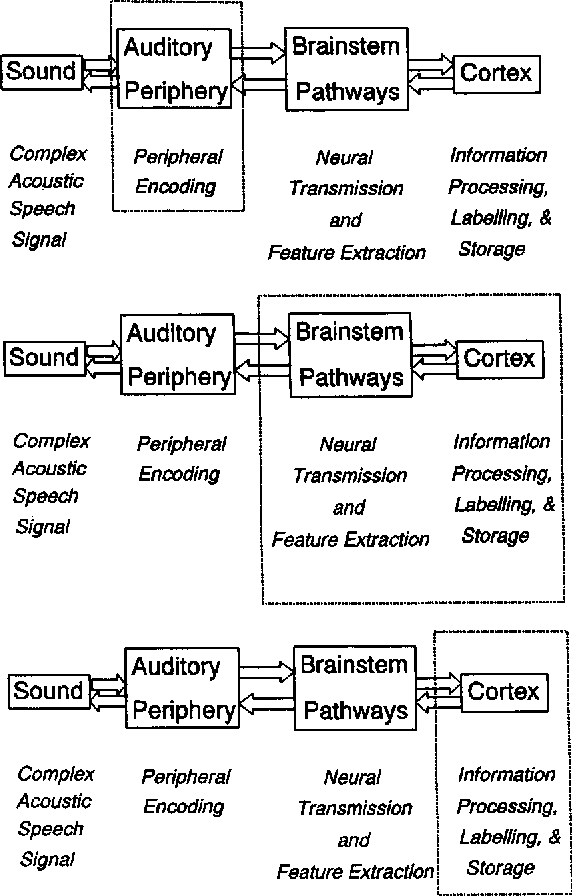
Figure 1 from Speech understanding in the elderly. | Semantic Scholar

Figure 1 from Joint Semantic and Spatial Feature Learning for Audio ...
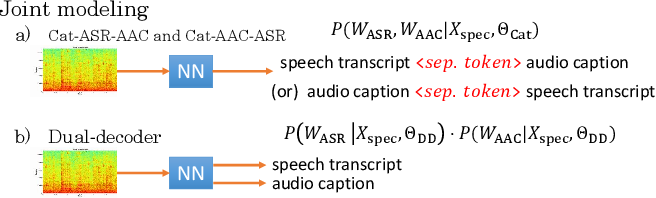
Figure 2 from Joint Speech Recognition and Audio Captioning | Semantic ...

Figure 1 from Extending Large Language Models for Speech and Audio ...

Figure 1 from Streaming Joint Speech Recognition and Disfluency ...
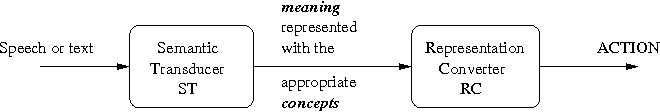
Figure 1 from A Complete Understanding Speech System Based on Semantic ...
Advertisement Space (300x250)
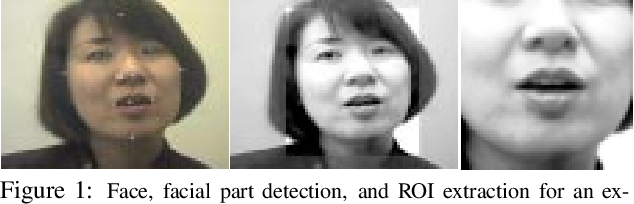
Figure 1 from Joint audio-visual speech processing for recognition and ...

Figure 1 from Joint Speech Enhancement and Speaker Identification Using ...
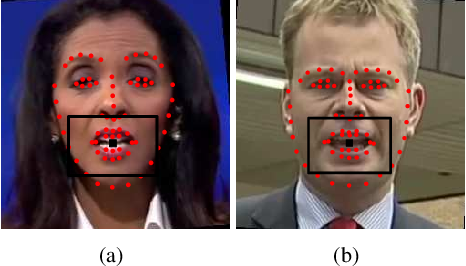
Figure 1 from End-to-End Audiovisual Speech Recognition | Semantic Scholar
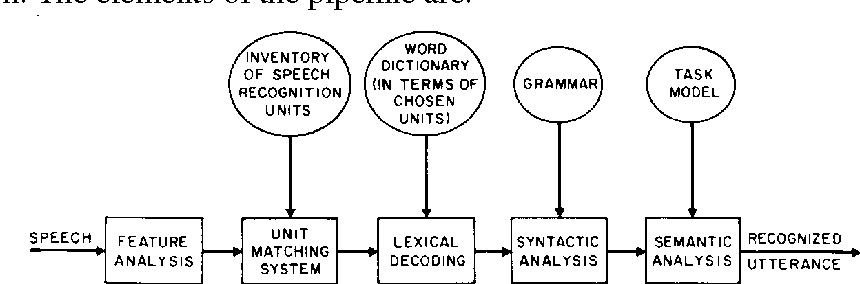
Figure 1 from SPEECH RECOGNITION SYSTEM | Semantic Scholar
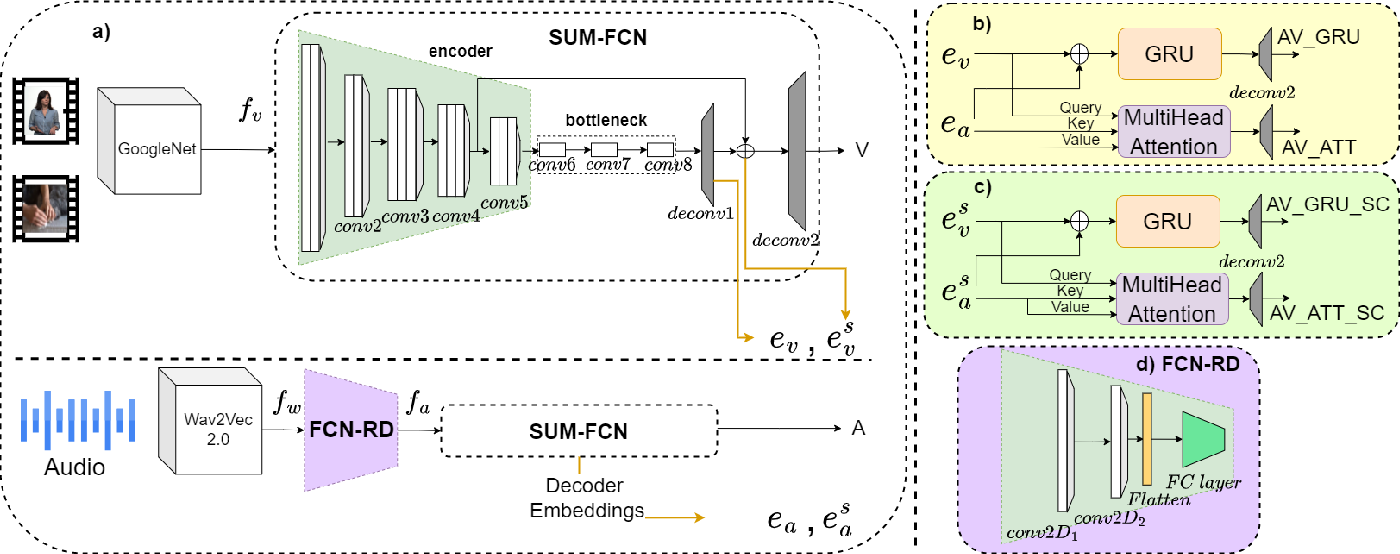
Figure 1 from Role of Audio In Video Summarization | Semantic Scholar

Figure 1 from Joint Language Semantic and Structure Embedding for ...
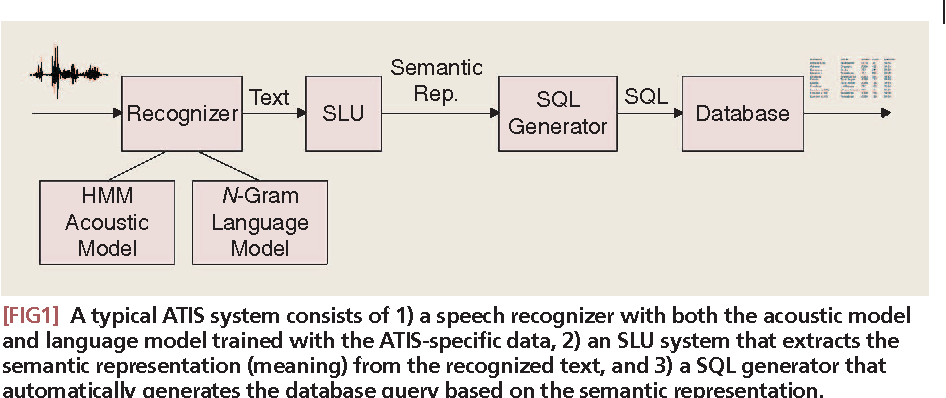
Figure 1 from Spoken language understanding | Semantic Scholar
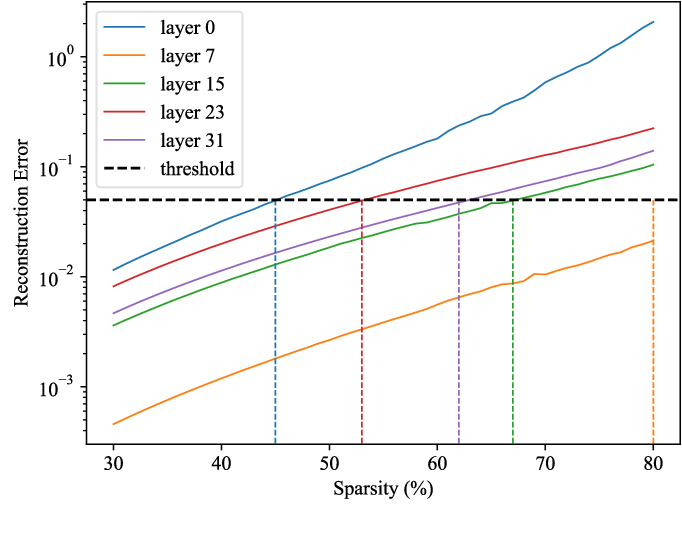
Figure 1 from MixPQ: Joint Pruning and Quantization for Speech and ...
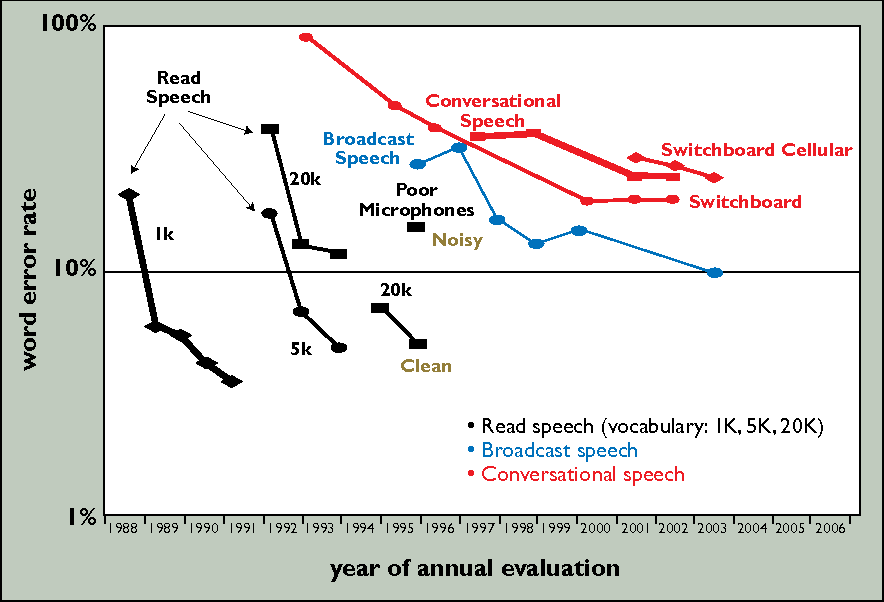
Figure 1 from Speech Recognition CHALLENGES IN ADOPTING | Semantic Scholar

Figure 1 from Jointly Learning Visual and Auditory Speech ...
Advertisement Space (336x280)

Figure 1 from Audio-visual speech separation based on joint feature ...
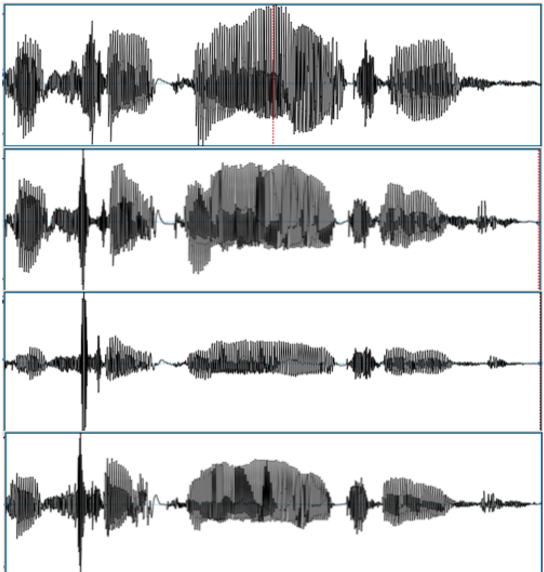
Figure 1 from The Remarkable Unremarkableness of Joint Speech ...

Figure 1 from Audio-visual speech recognition in noisy audio ...

Figure 1 from Analysis of Joint Speech-Text Embeddings for Semantic ...

Figure 1 from Direction-Aware Joint Adaptation of Neural Speech ...

Figure 1 from A Reality Check and a Practical Baseline for Semantic ...
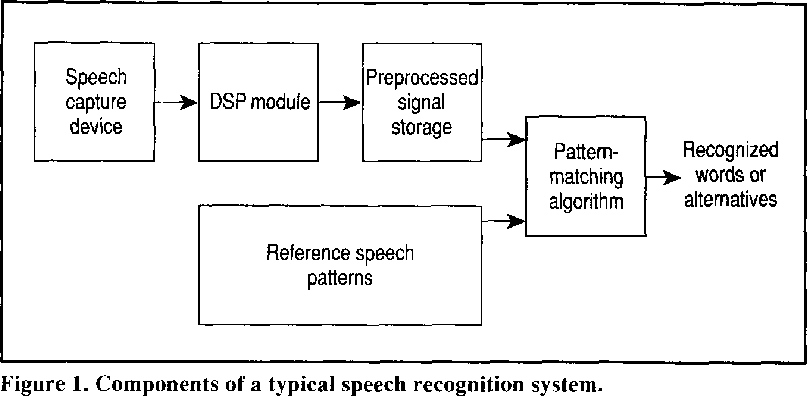
Figure 1 from An introduction to speech and speaker recognition ...

Figure 1 from DNN-Based Speech Separation with Joint Improved ...
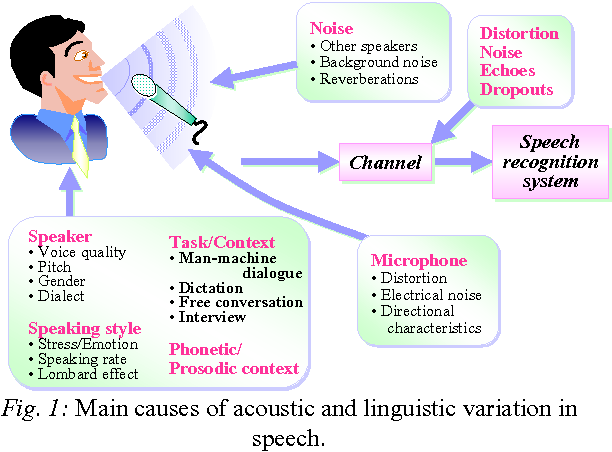
Figure 1 from Robust methods in automatic speech recognition and ...
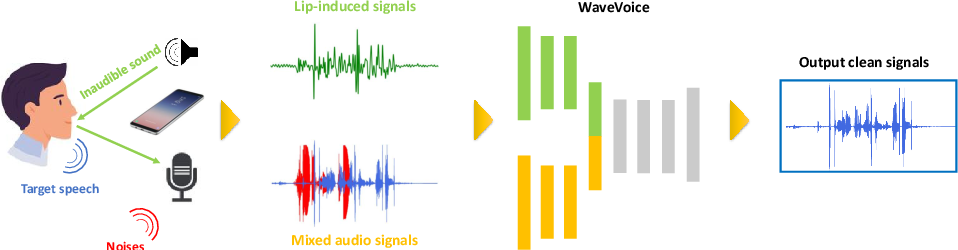
Figure 1 from Sensing to Hear | Semantic Scholar
Advertisement Space (336x280)

Figure 1 from The Ability of Self-Supervised Speech Models for Audio ...
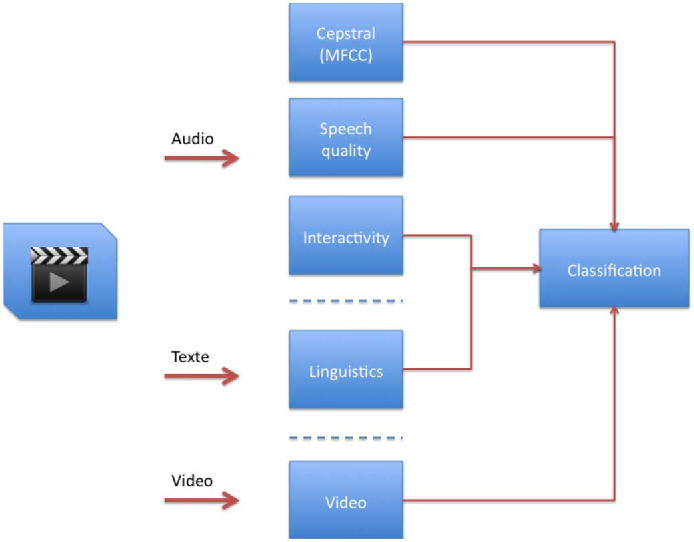
Figure 1 from Audio-Based Video Genre Identification | Semantic Scholar

Figure 1 from Conversational Speech Recognition by Learning Audio ...
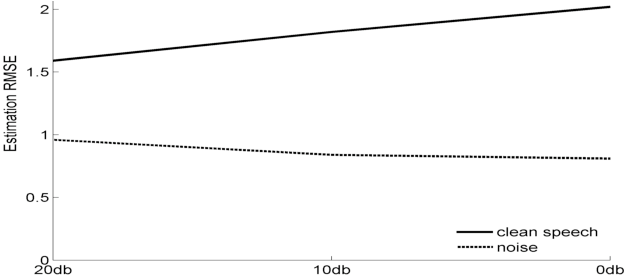
Figure 1 from Enhancing audio speech using visual speech features ...

Figure 1 from Diffusion Models for Audio Semantic Communication ...
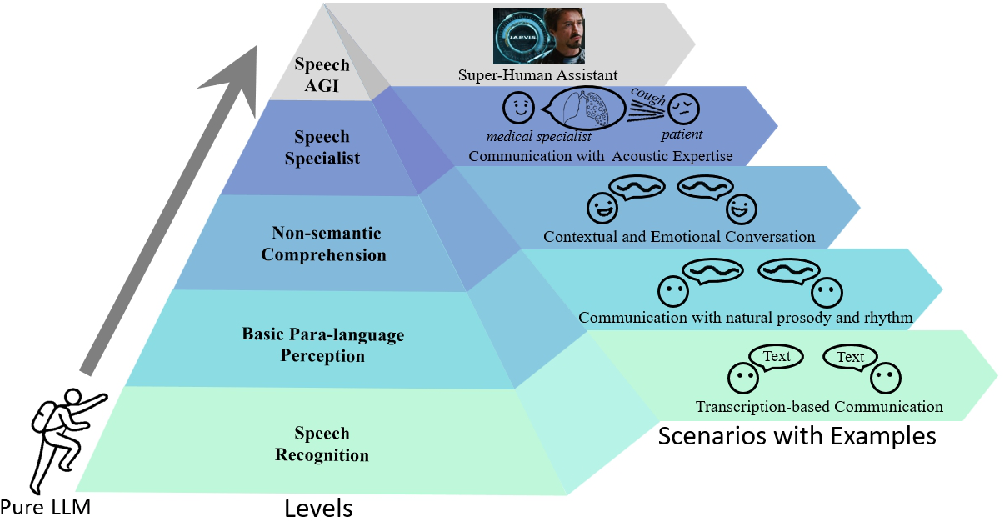
Figure 1 from Roadmap towards Superhuman Speech Understanding using ...