
Scope Kv Cache Optimization Framework For Long Context Generation In
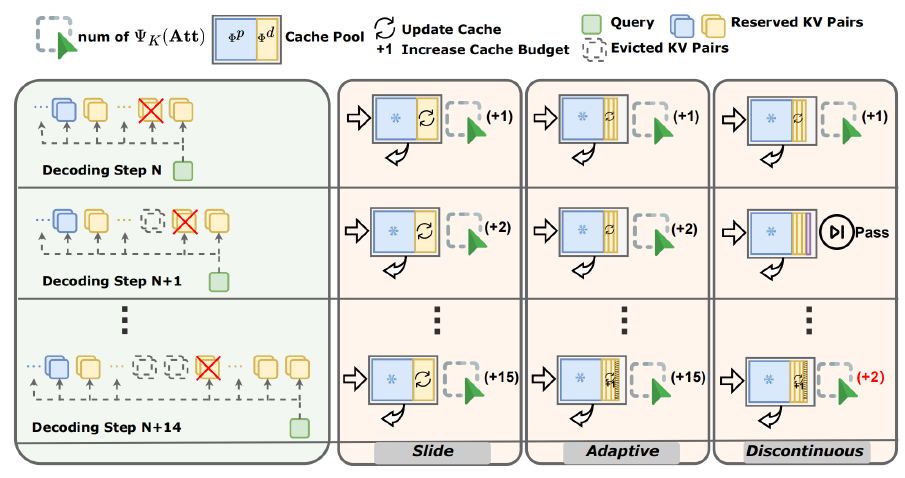
SCOPE: KV Cache optimization framework for long-context generation in ...

LLM Inference: Accelerating Long Context Generation with KV Cache ...
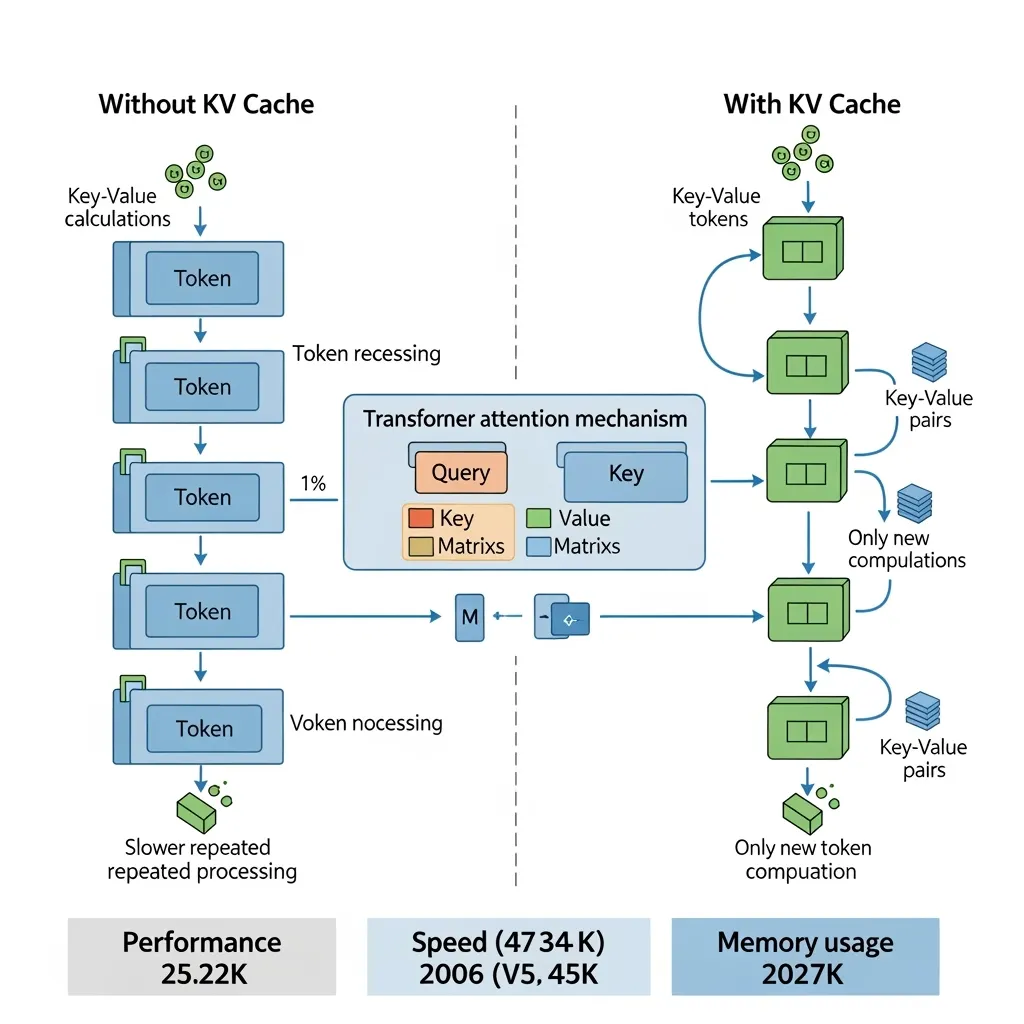
Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...
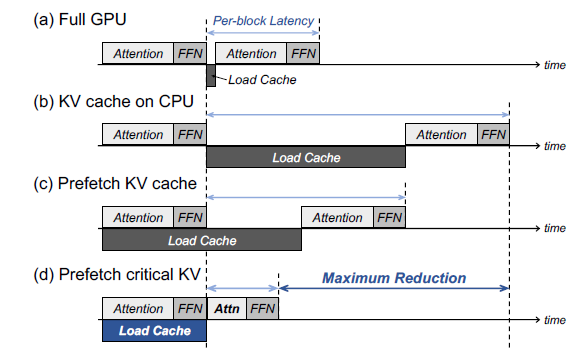
LLM Inference: Accelerating Long Context Generation with KV Cache ...

LOOK-M: Look-Once Optimization in KV Cache for Efficient Multimodal ...

LOOK-M: Look-Once Optimization in KV Cache for Efficient Multimodal ...
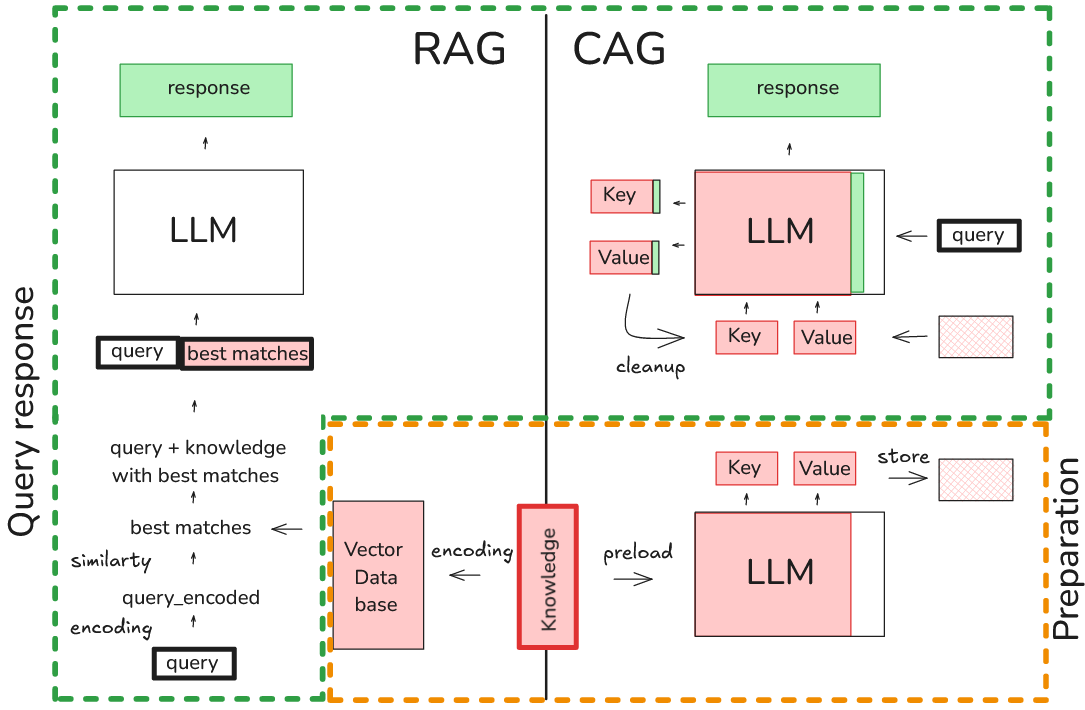
Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...
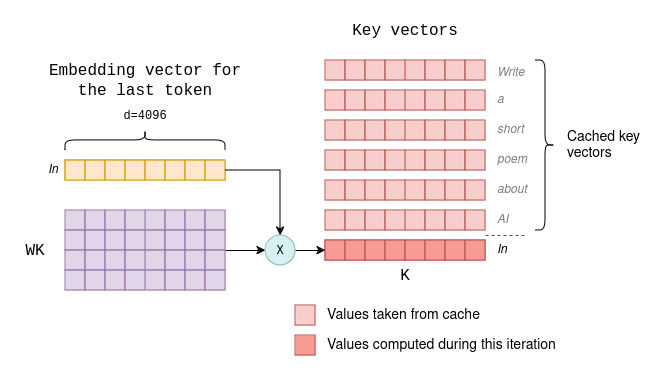
Techniques for KV Cache Optimization in Large Language Models

LLM Inference: Accelerating Long Context Generation with KV Cache ...
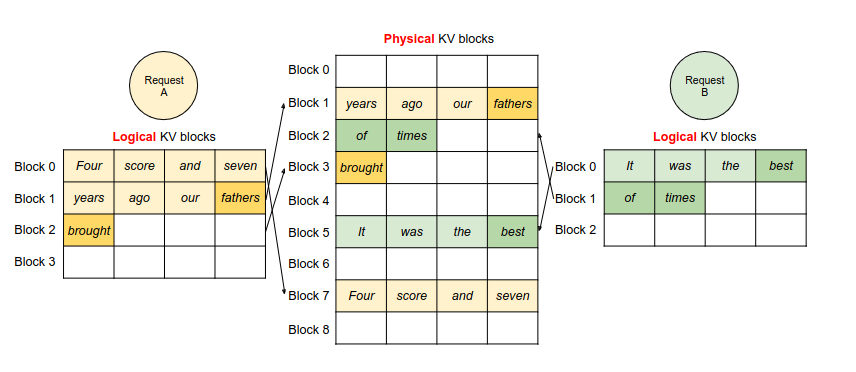
Techniques for KV Cache Optimization in Large Language Models
Advertisement Space (300x250)
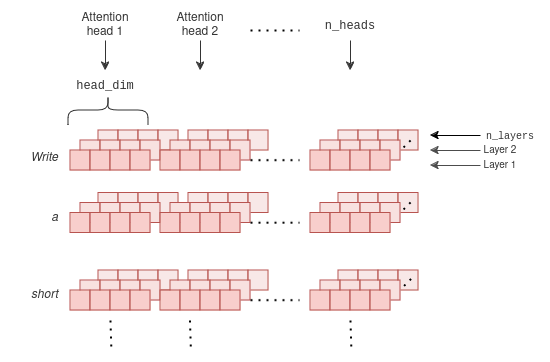
Techniques for KV Cache Optimization in Large Language Models
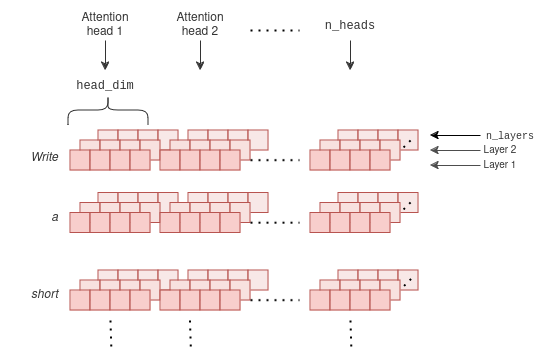
Techniques for KV Cache Optimization in Large Language Models
Memory Optimization in LLMs: Leveraging KV Cache Quantization for ...
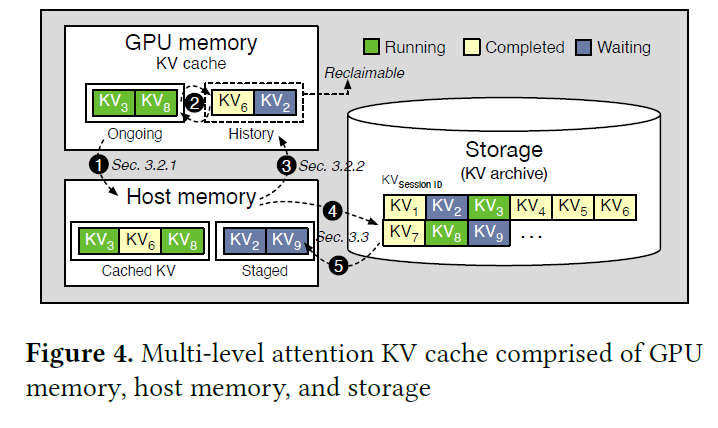
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...
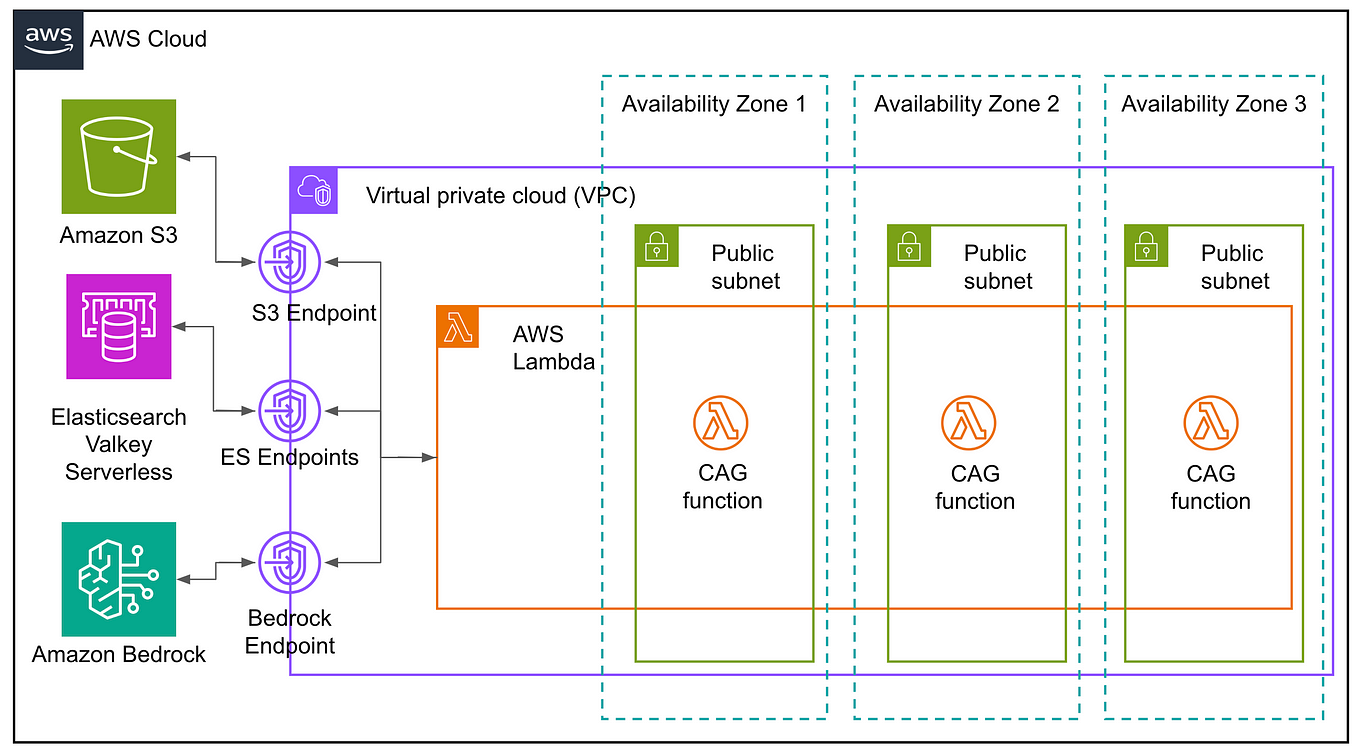
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...
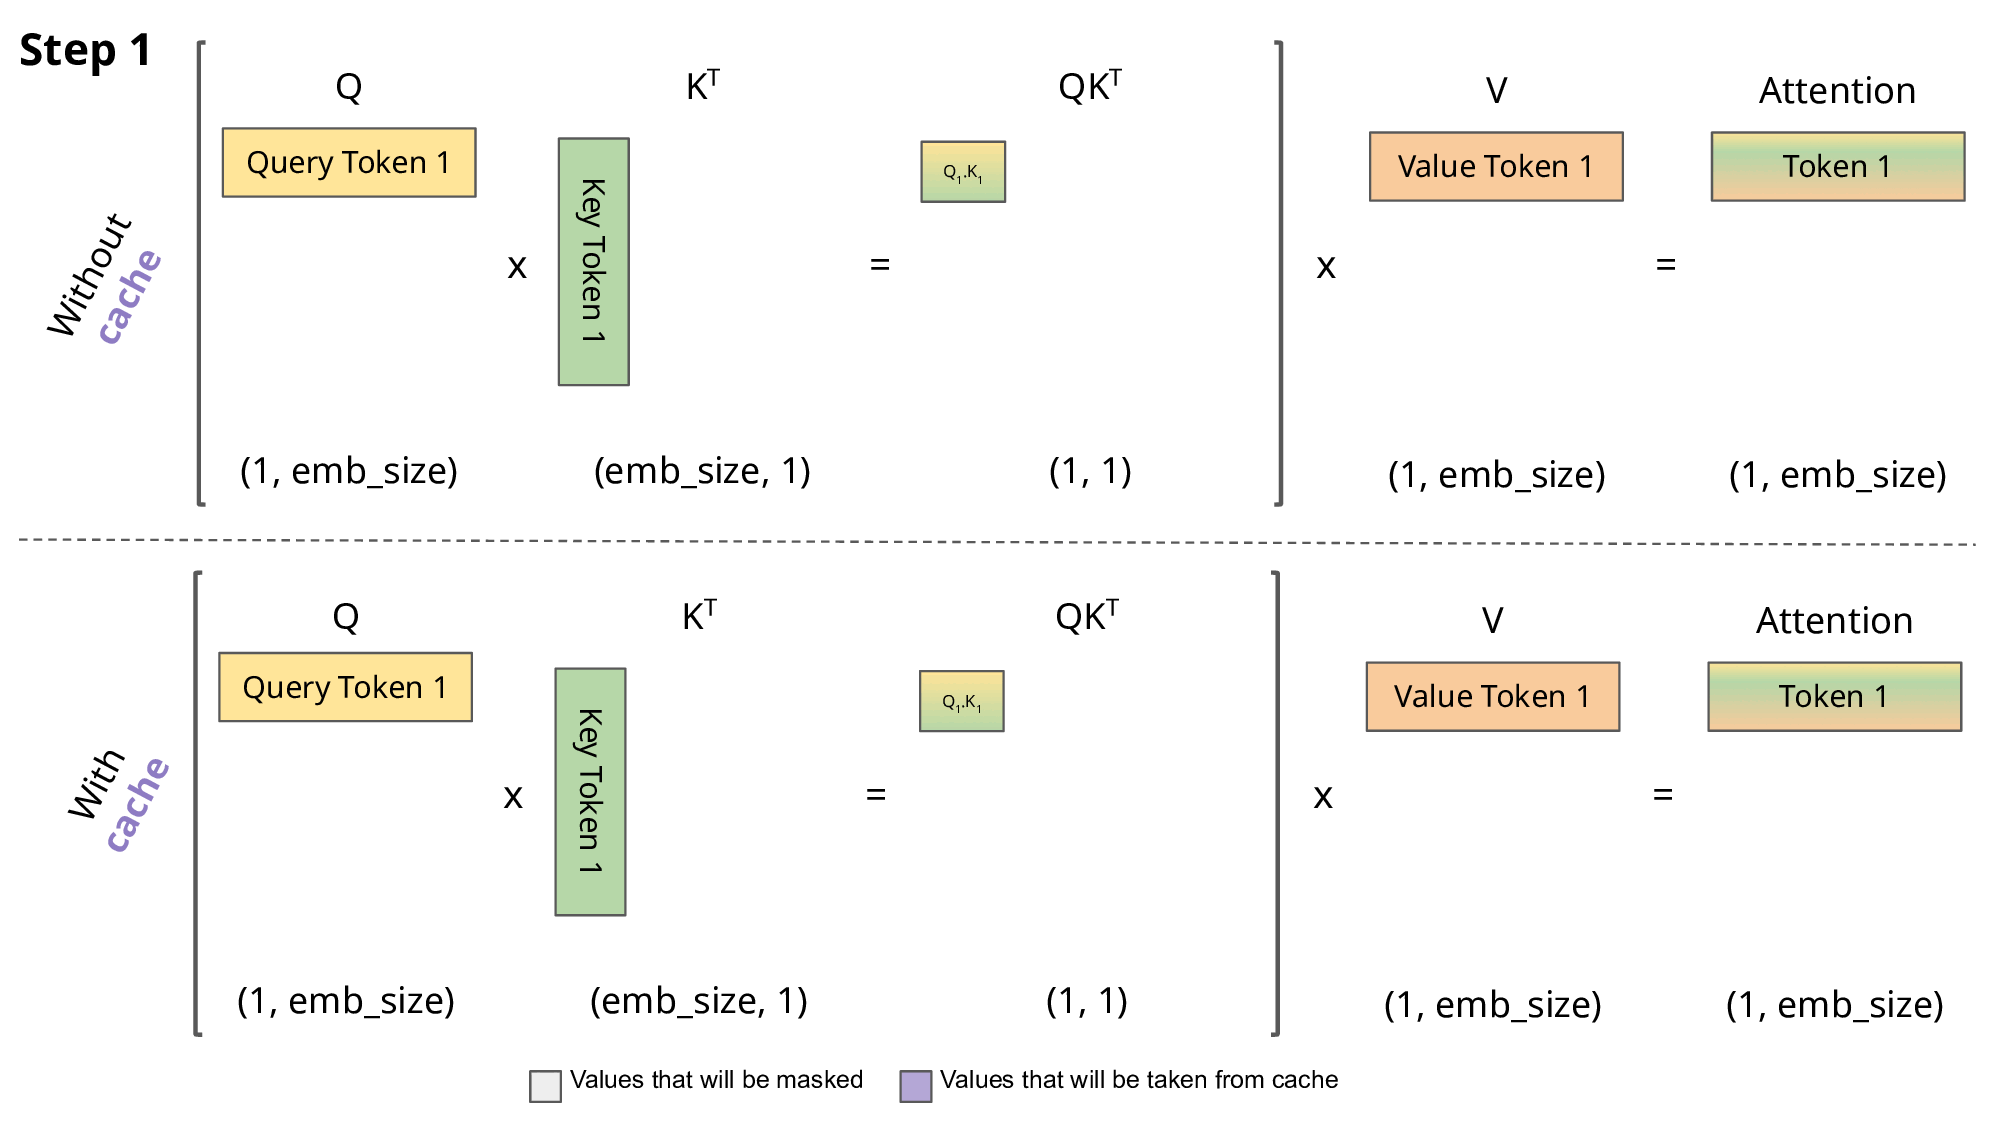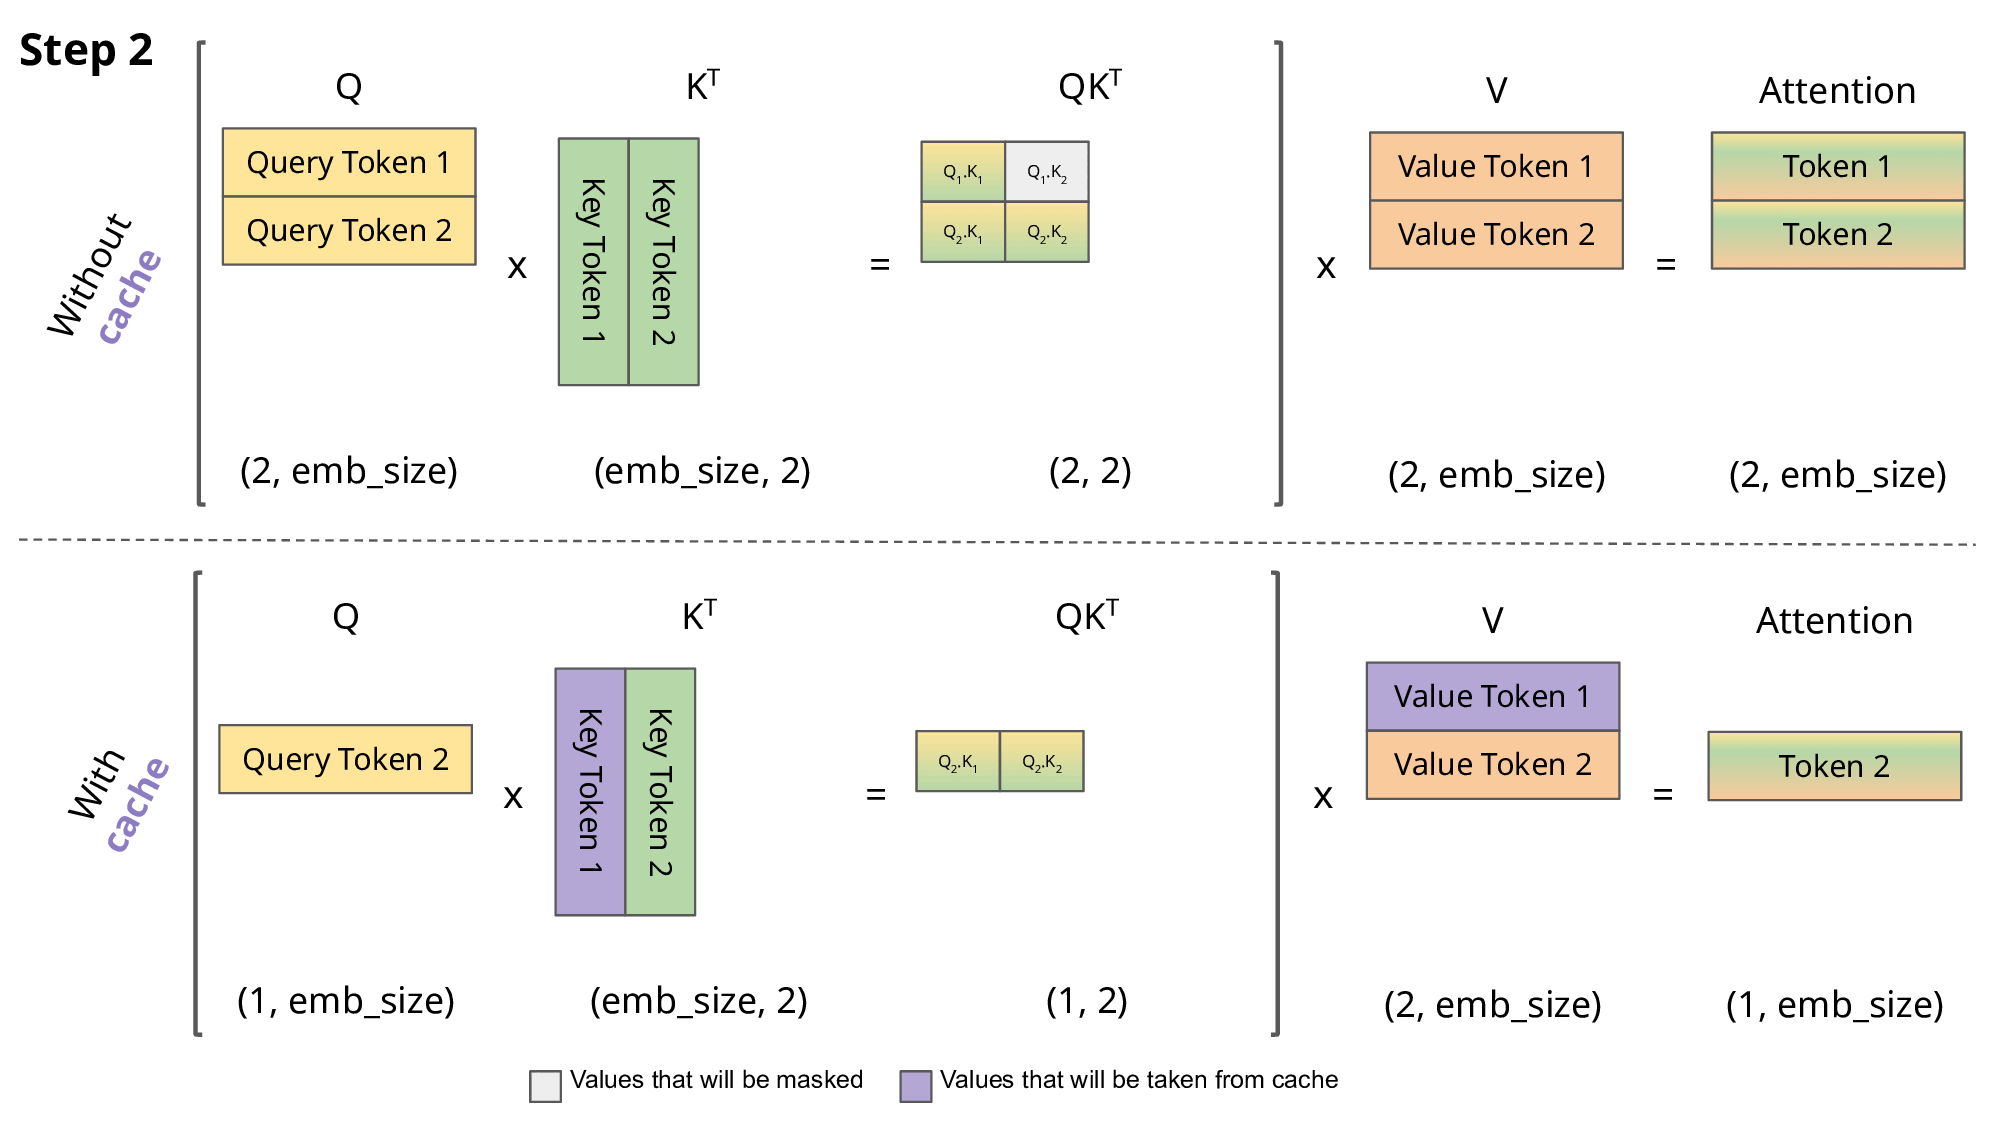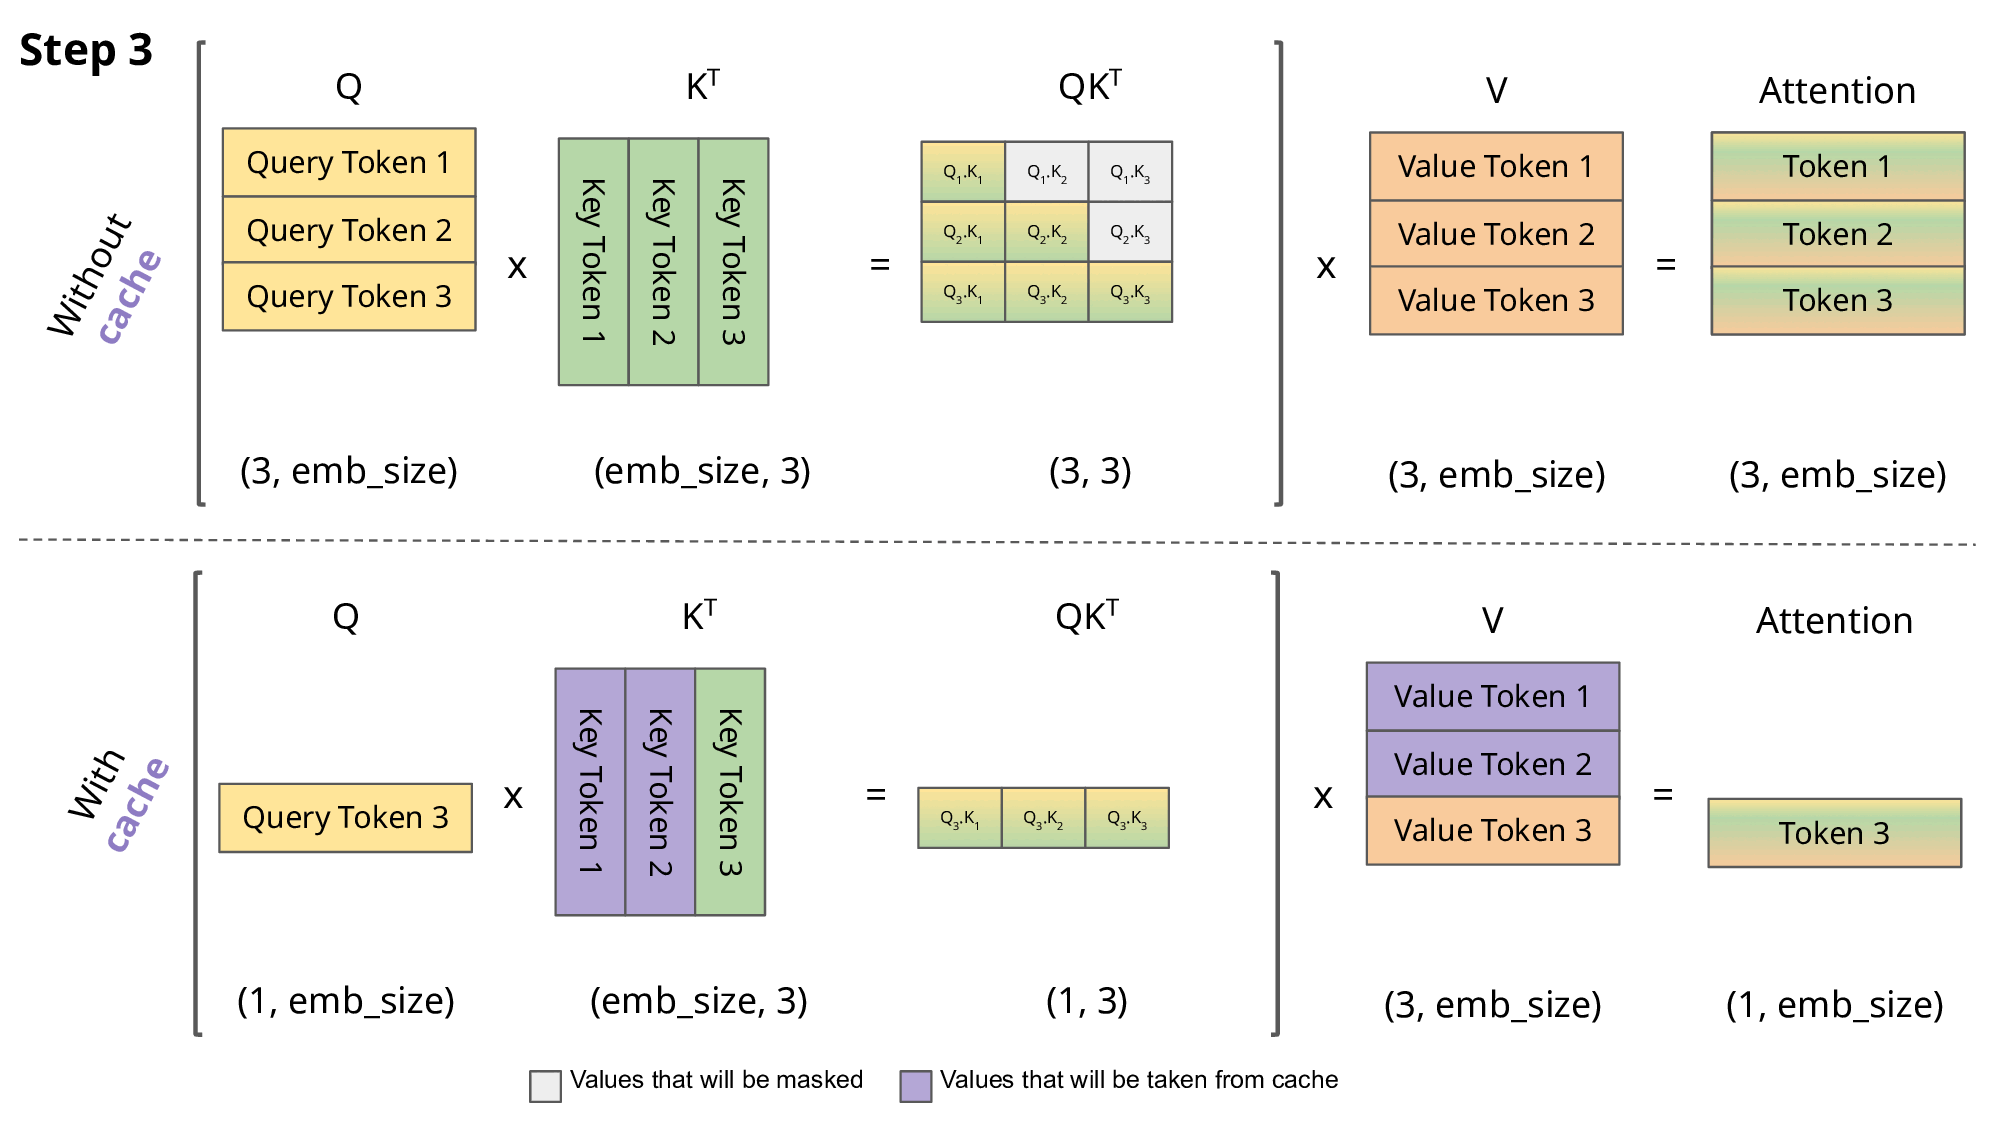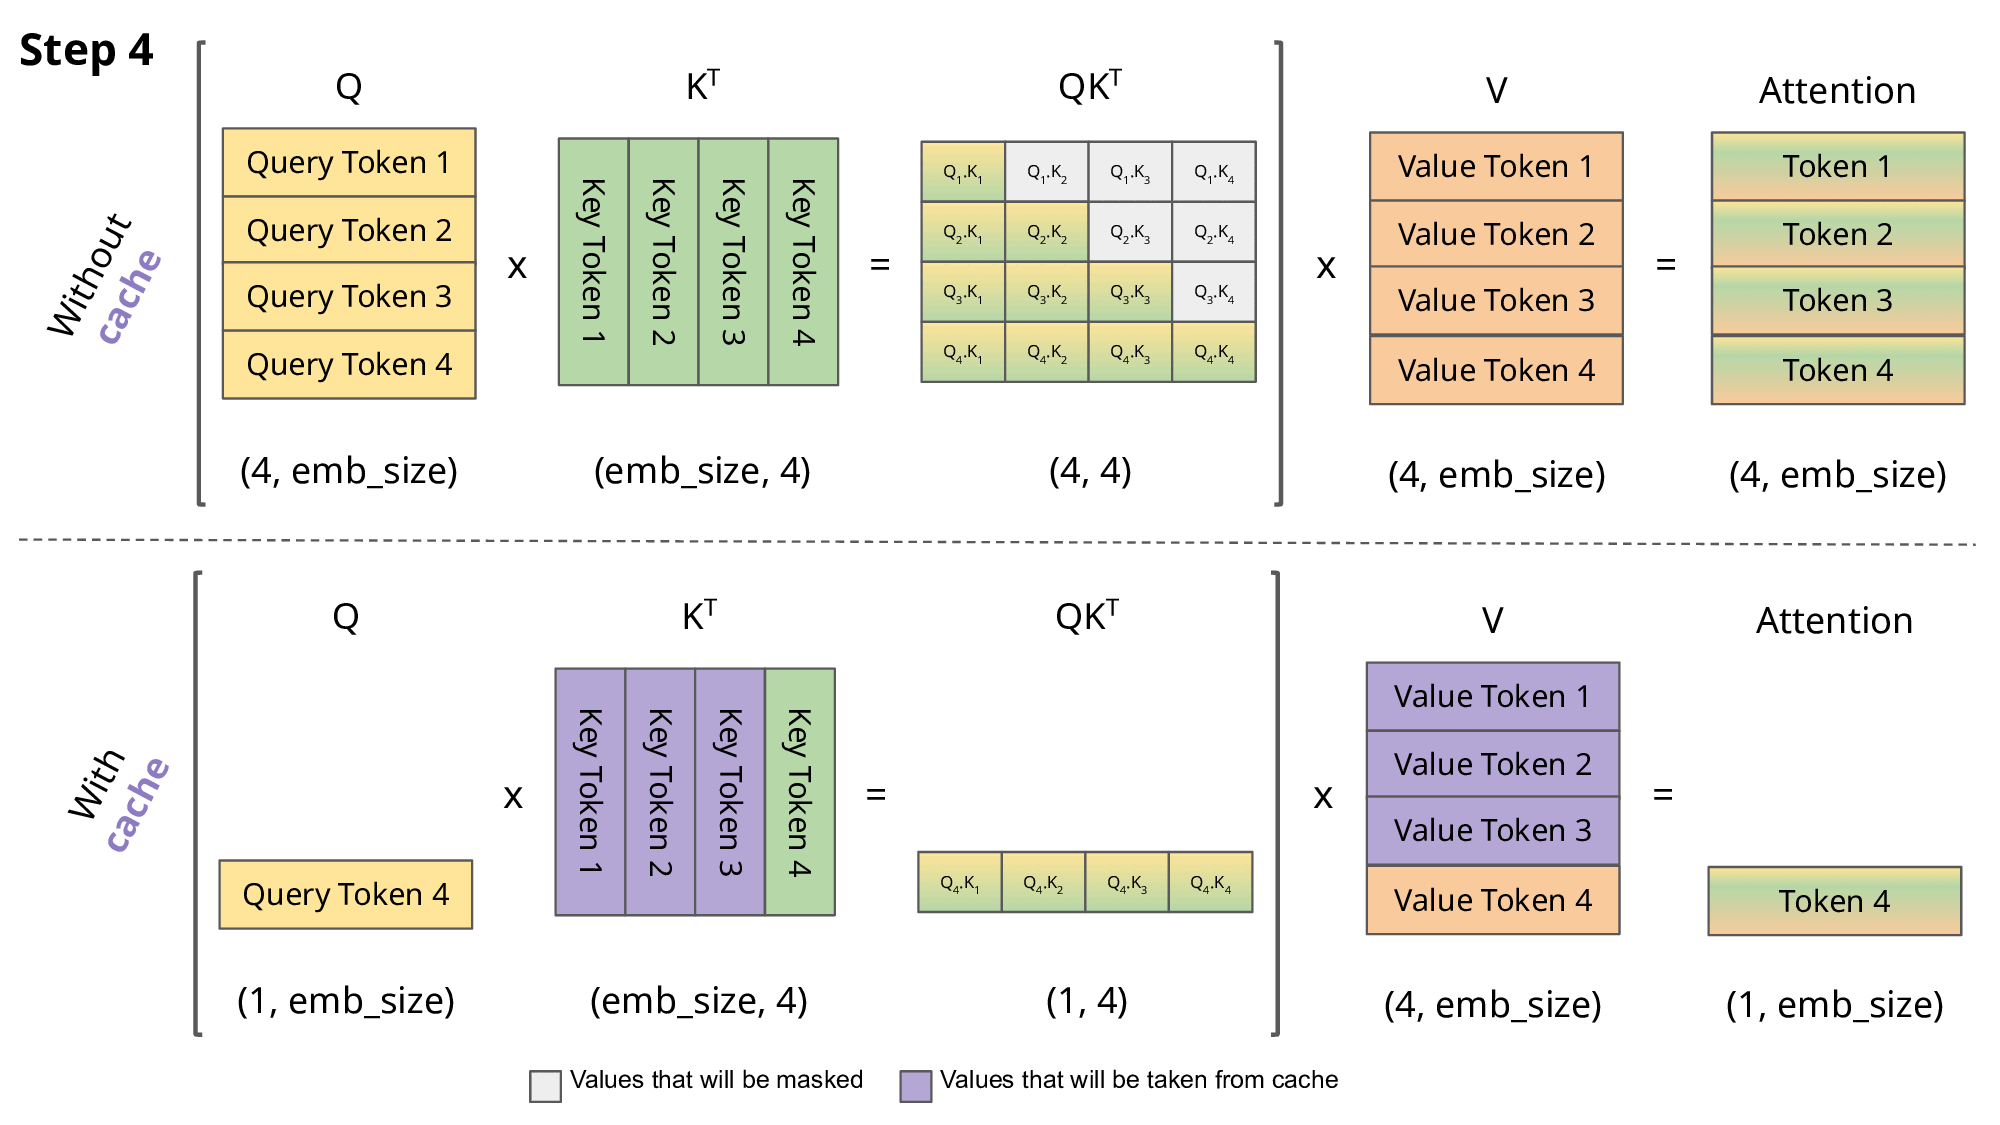
LLM Inference — Optimizing the KV Cache for High-Throughput, Long ...

[논문 리뷰] KV Cache Transform Coding for Compact Storage in LLM Inference
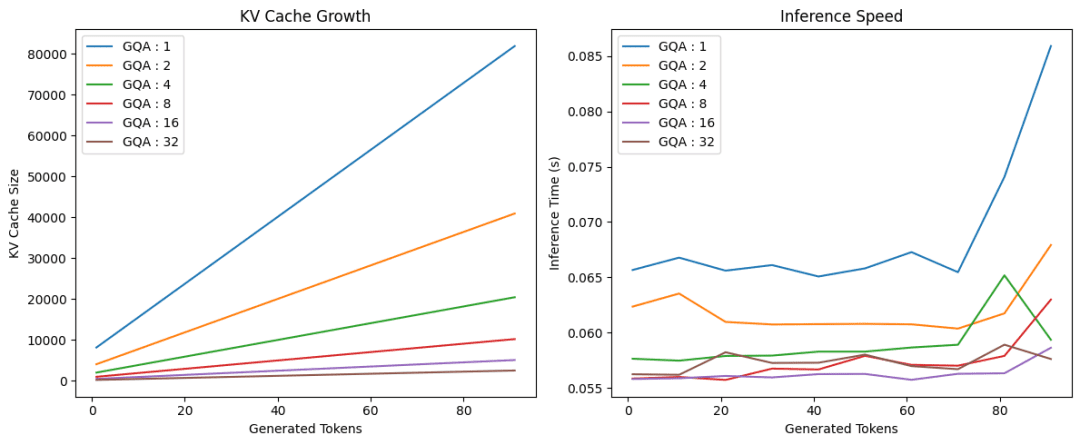
Introduction to KV Cache Optimization Utilizing Grouped Question ...
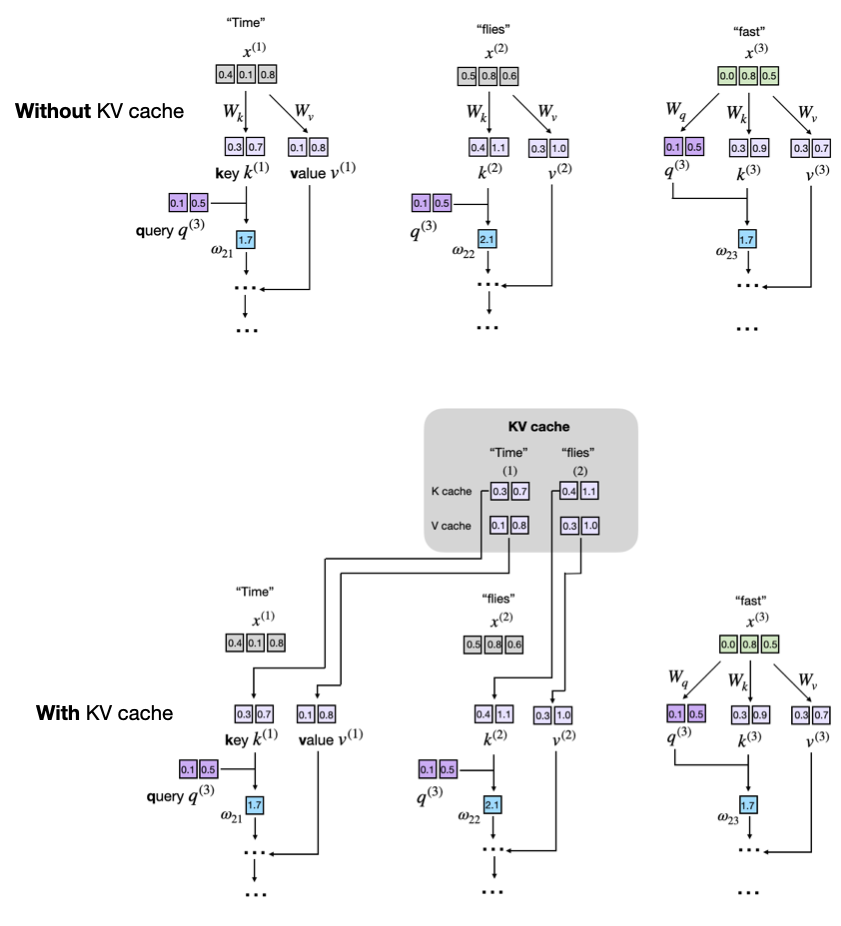
Understanding and Coding the KV Cache in LLMs from Scratch
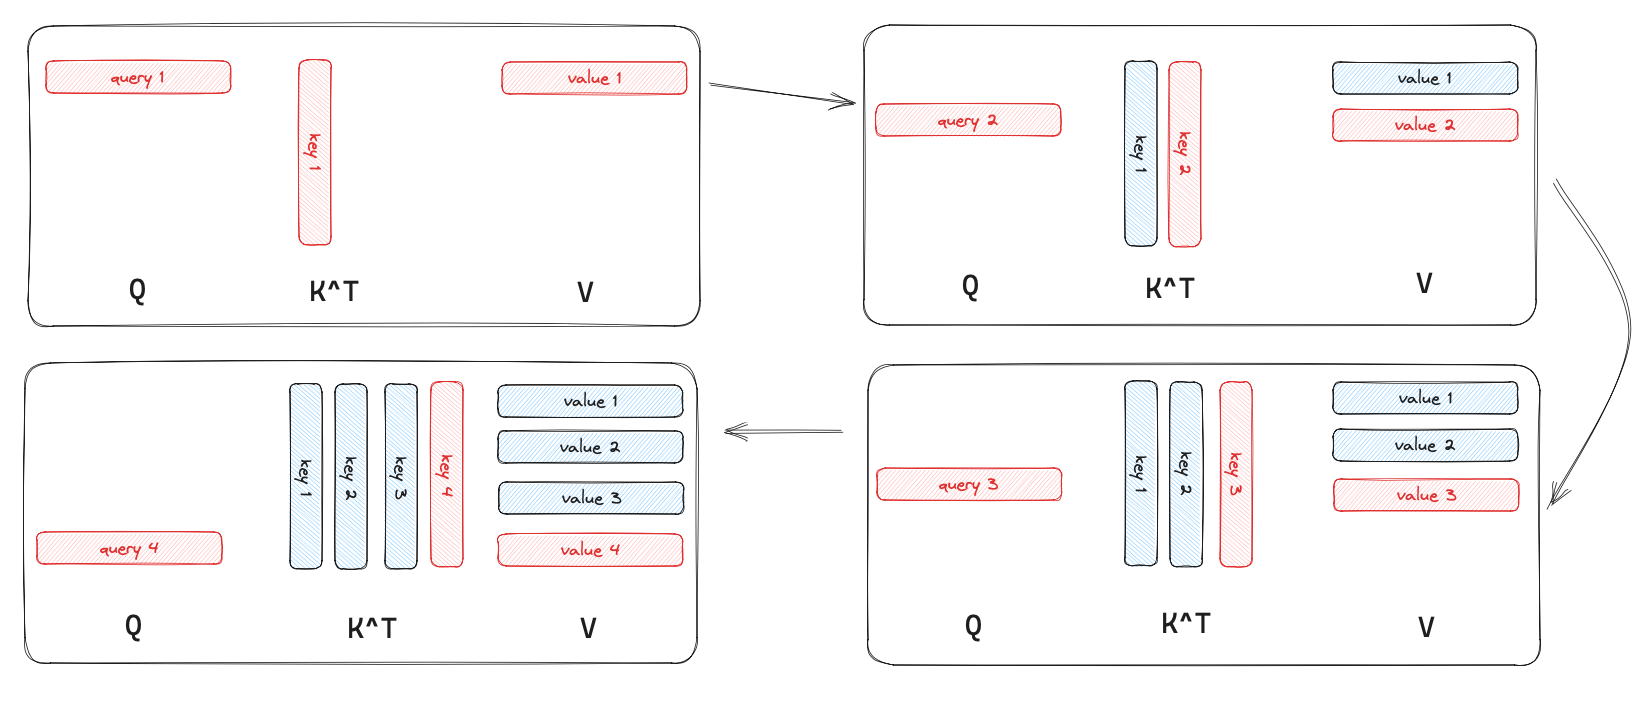
LLM inference optimization (1): KV Cache - MartinLwx's Blog
Advertisement Space (336x280)
KV Cache Compression, But What Must We Give in Return? A Comprehensive ...

KV Cache Optimization: Memory Management for Long-Context LLMs
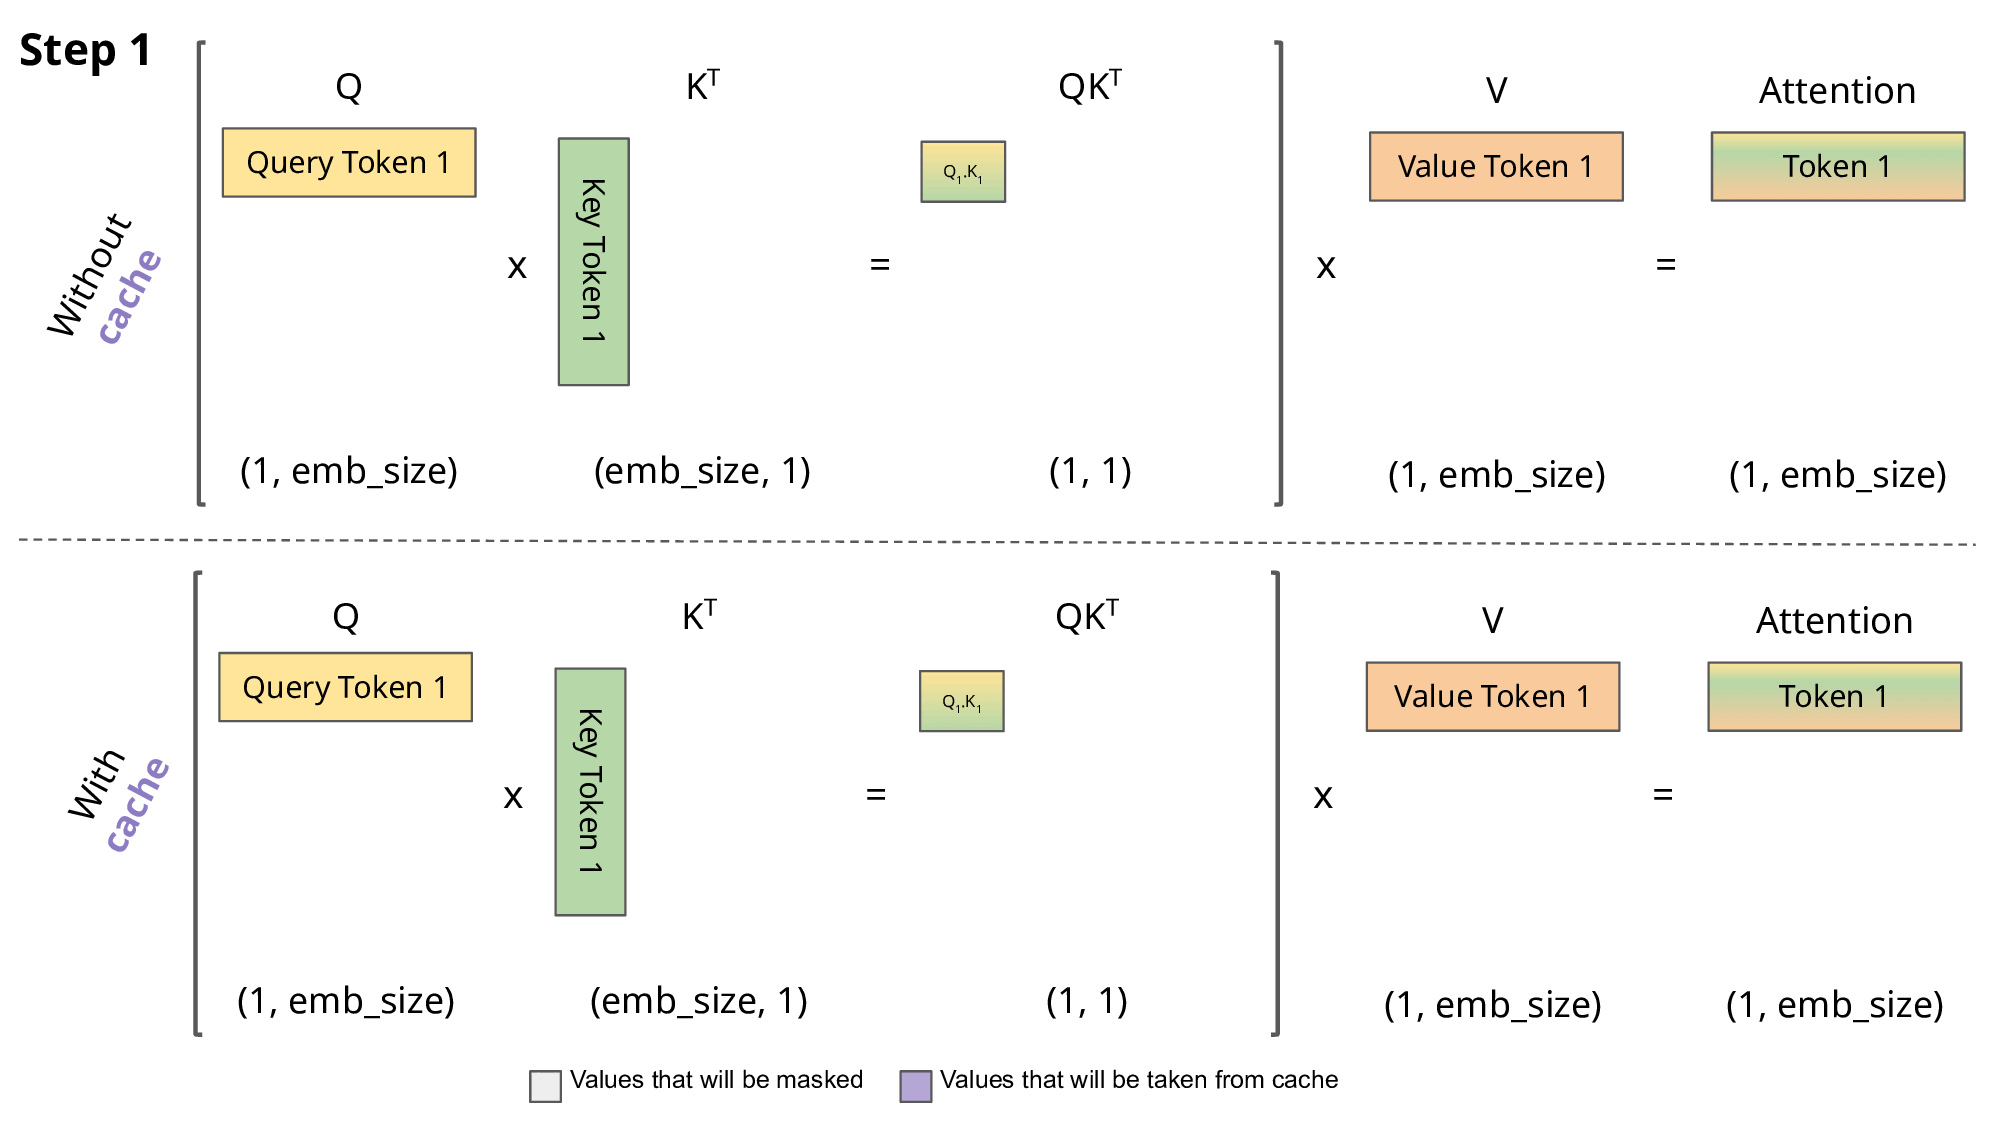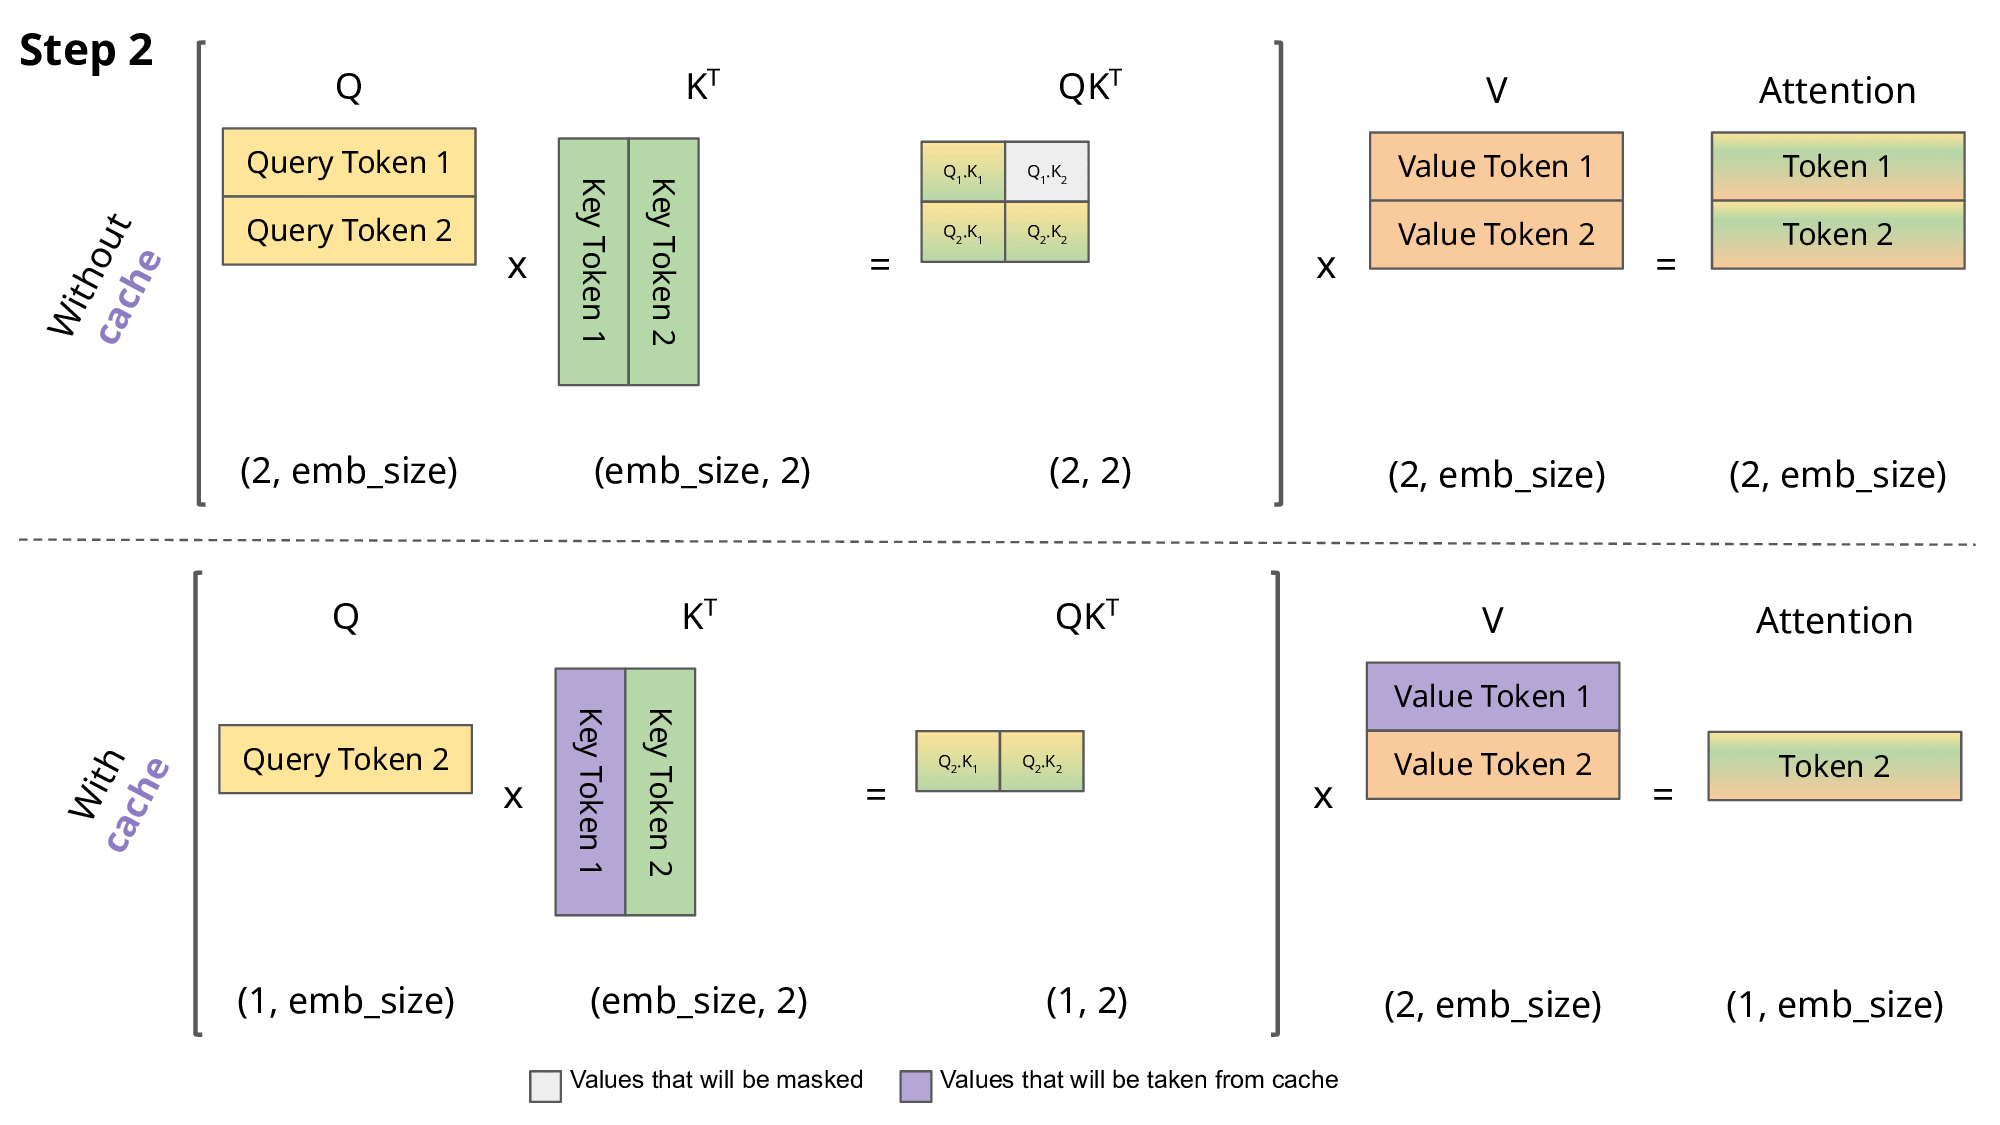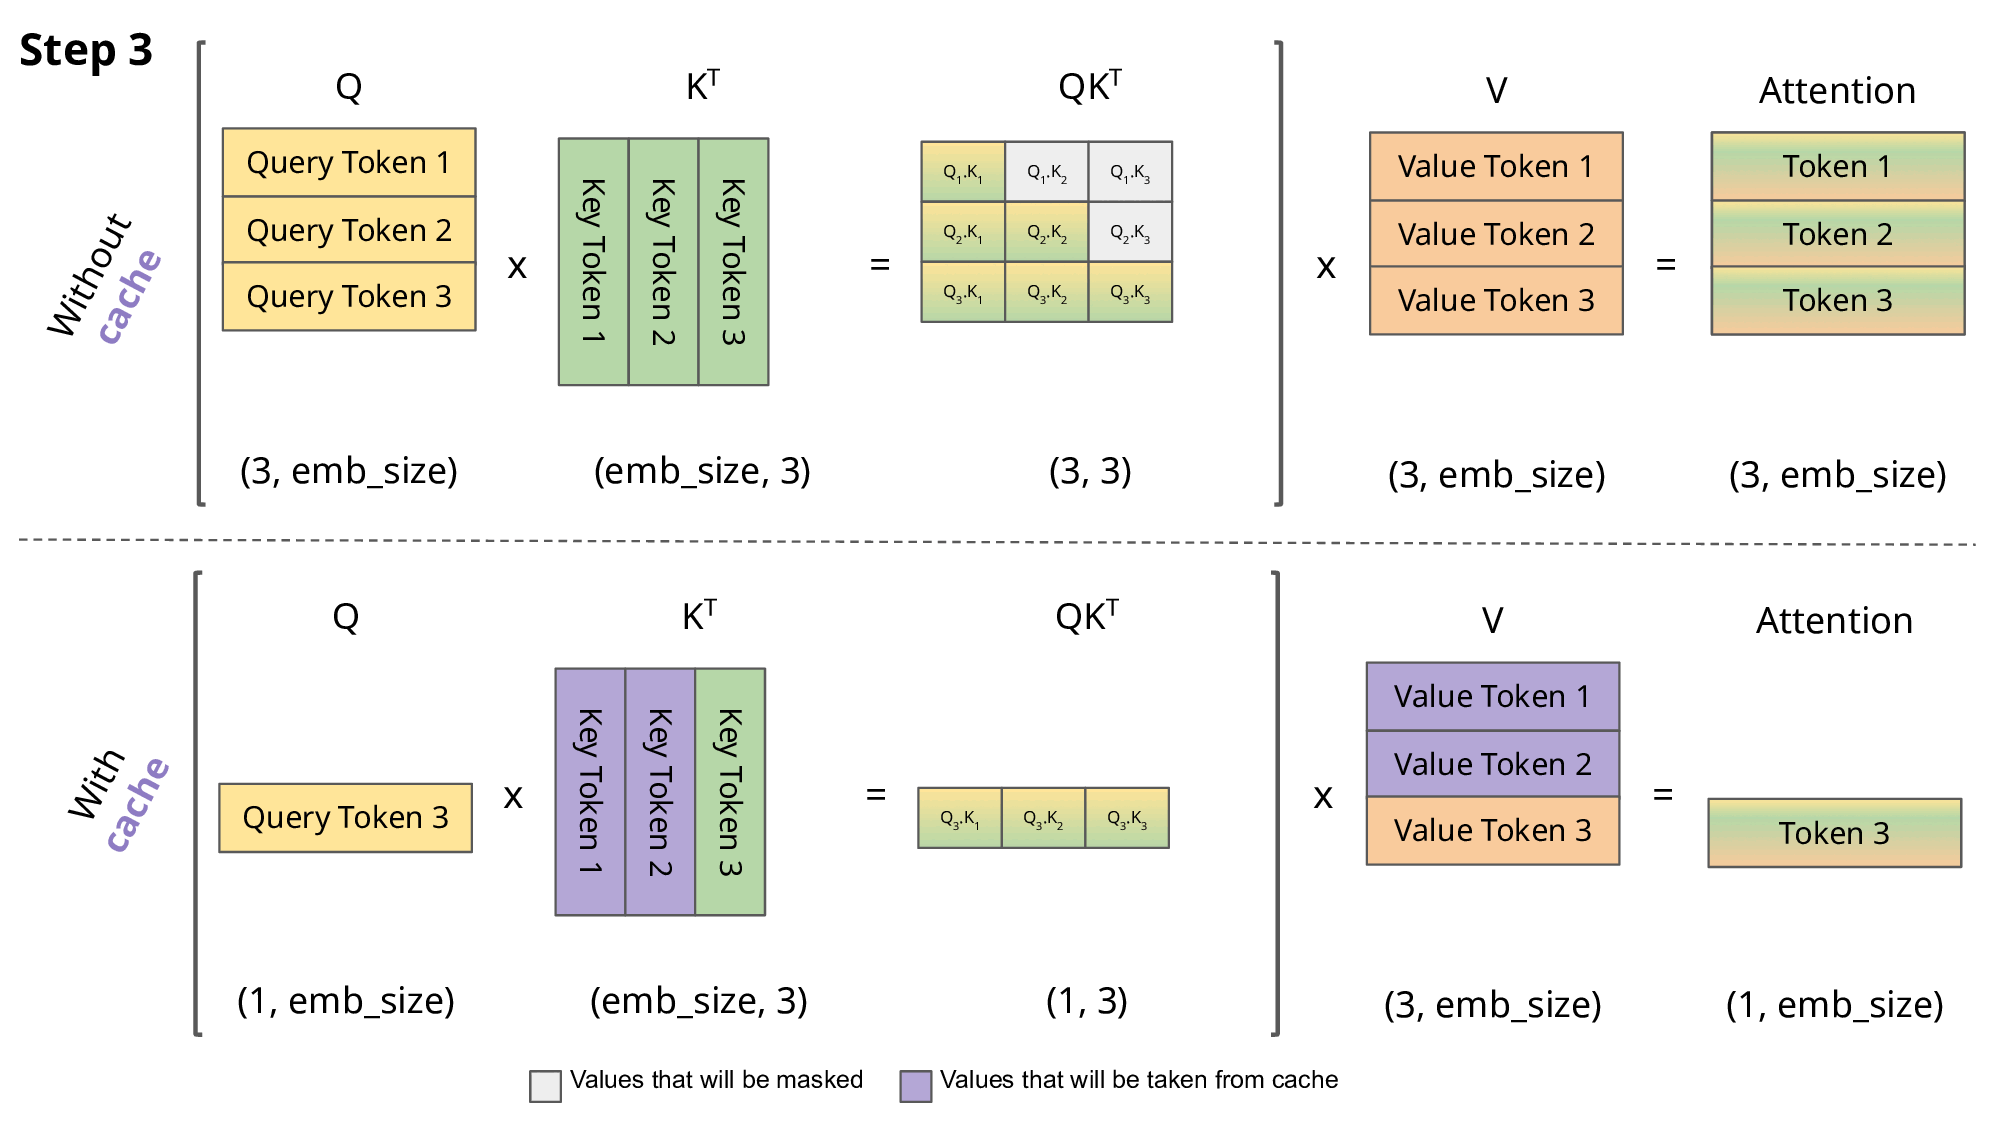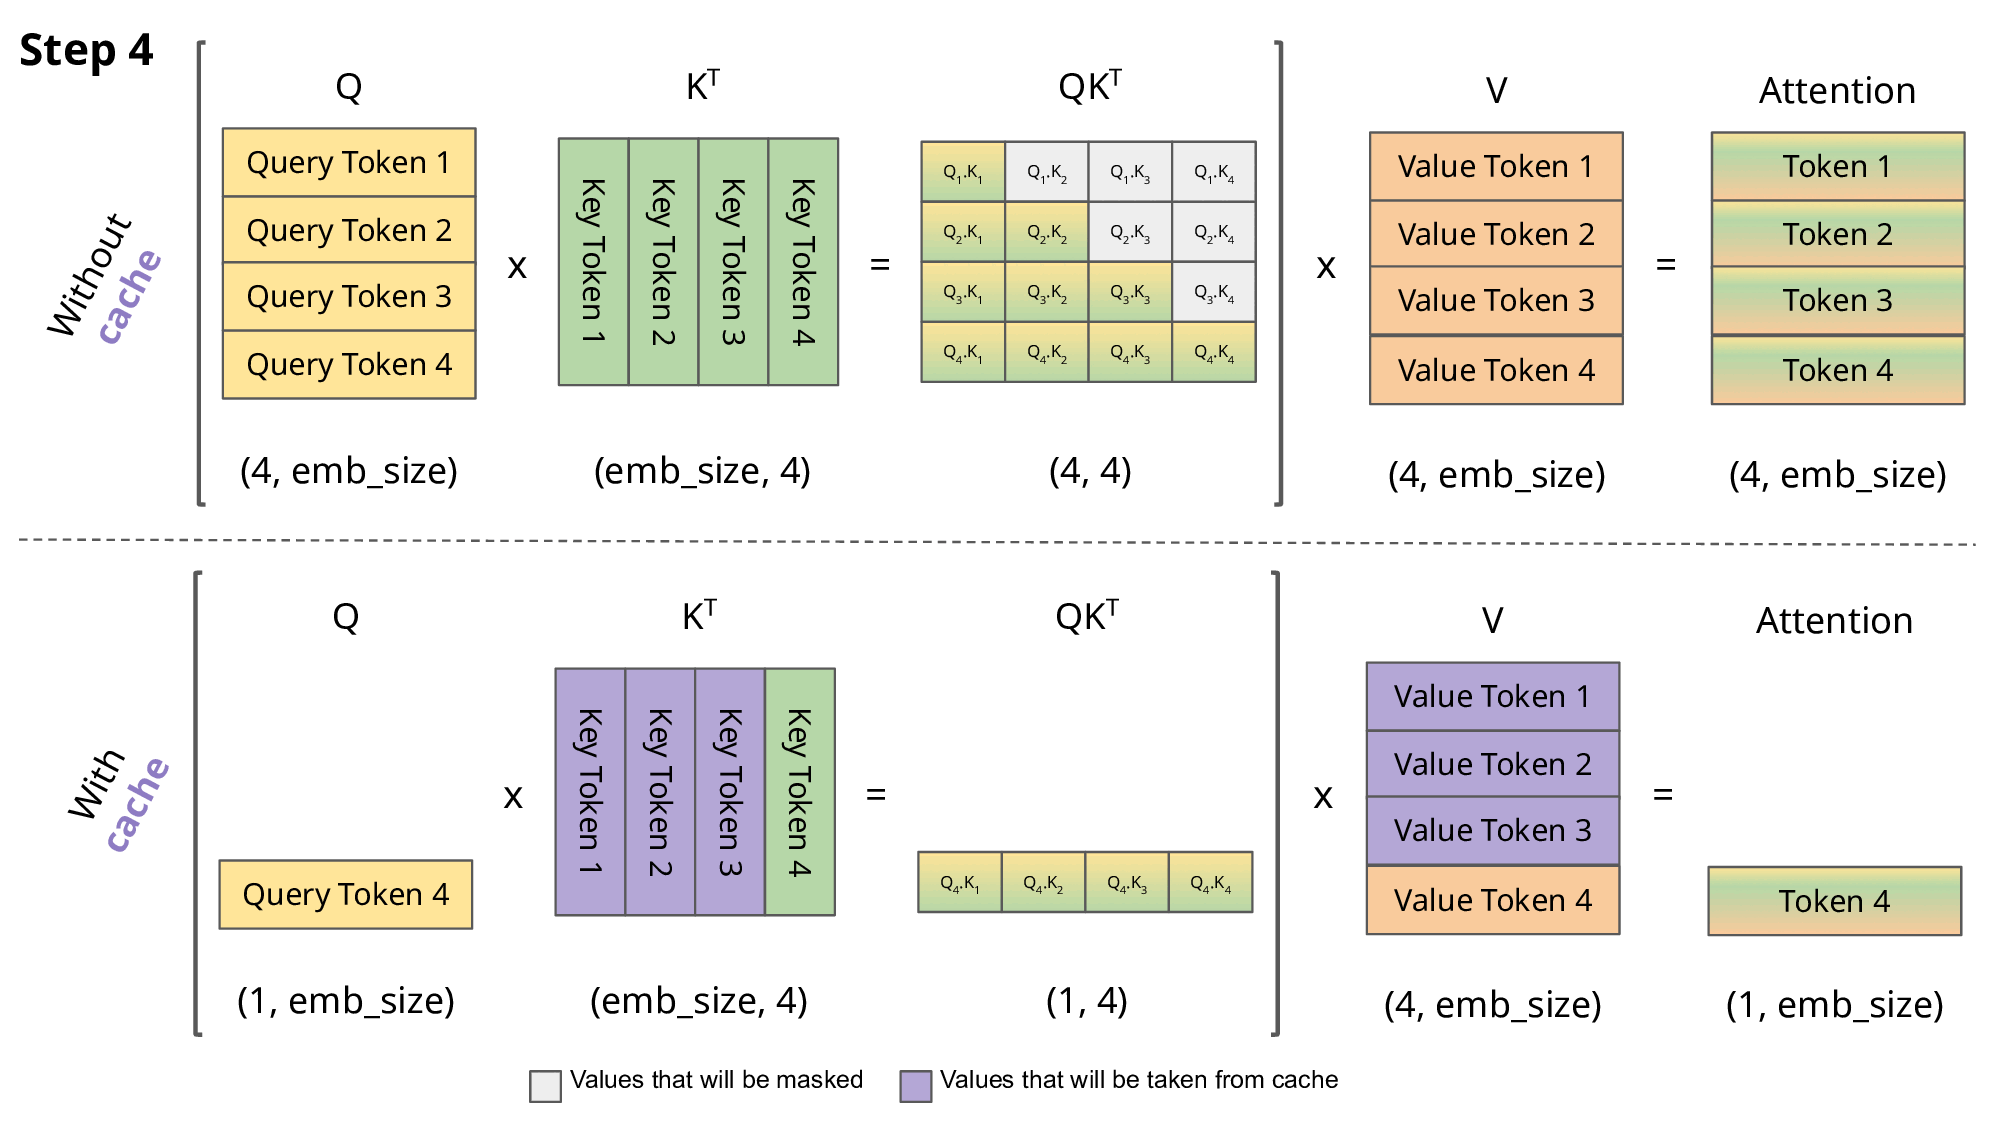
KV Cache in one passage. | Daily Jaredan

[논문 리뷰] SCOPE: Optimizing Key-Value Cache Compression in Long-context ...

Mastering Long Contexts in LLMs with KVPress
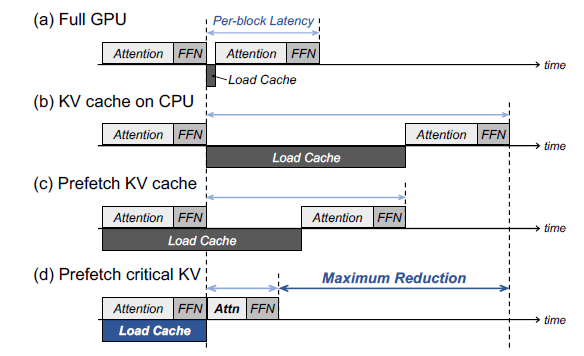
Optimizing LLM Inference: Managing the KV Cache | by Aalok Patwa | Medium
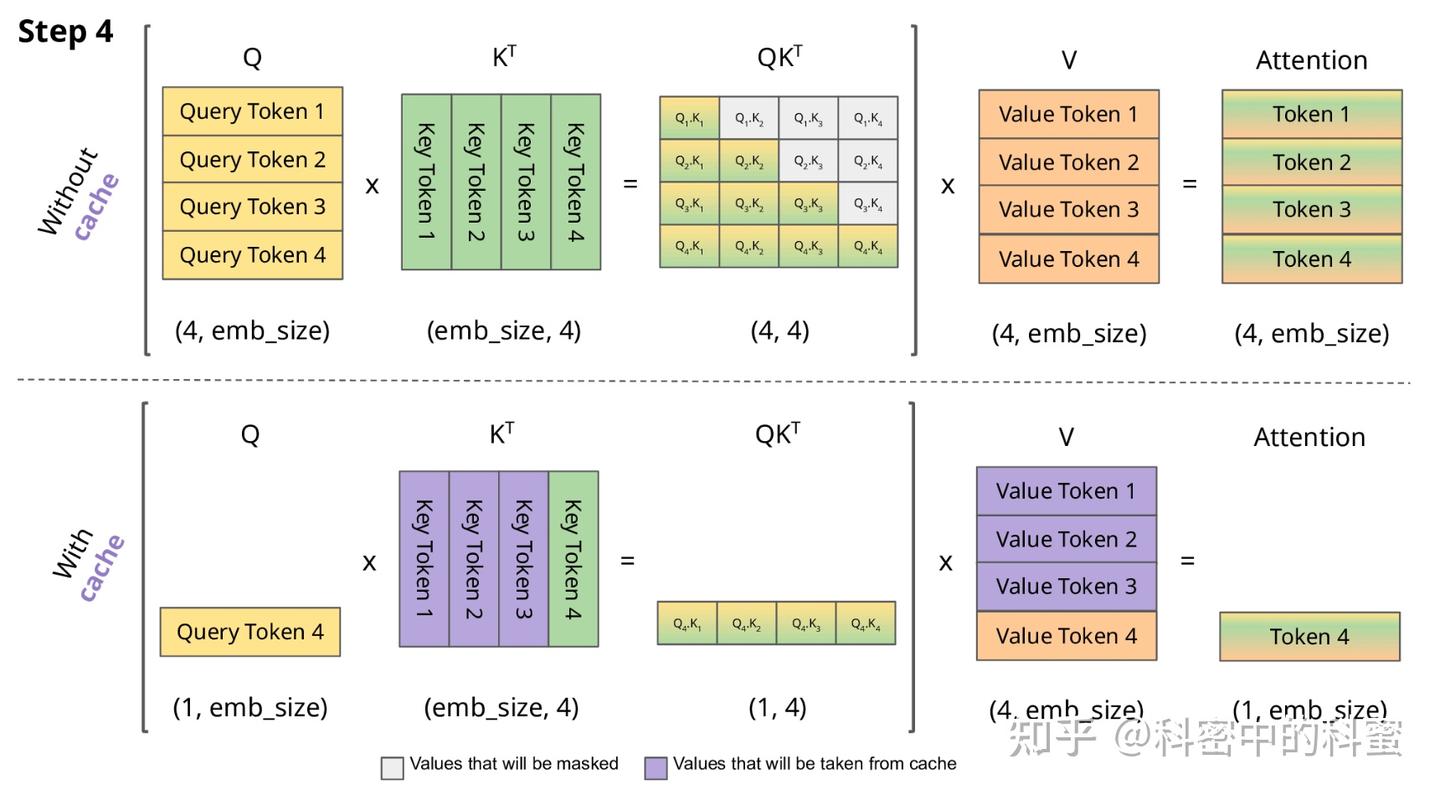
KV cache 缓存与量化:加速大型语言模型推理的关键技术 - 知乎
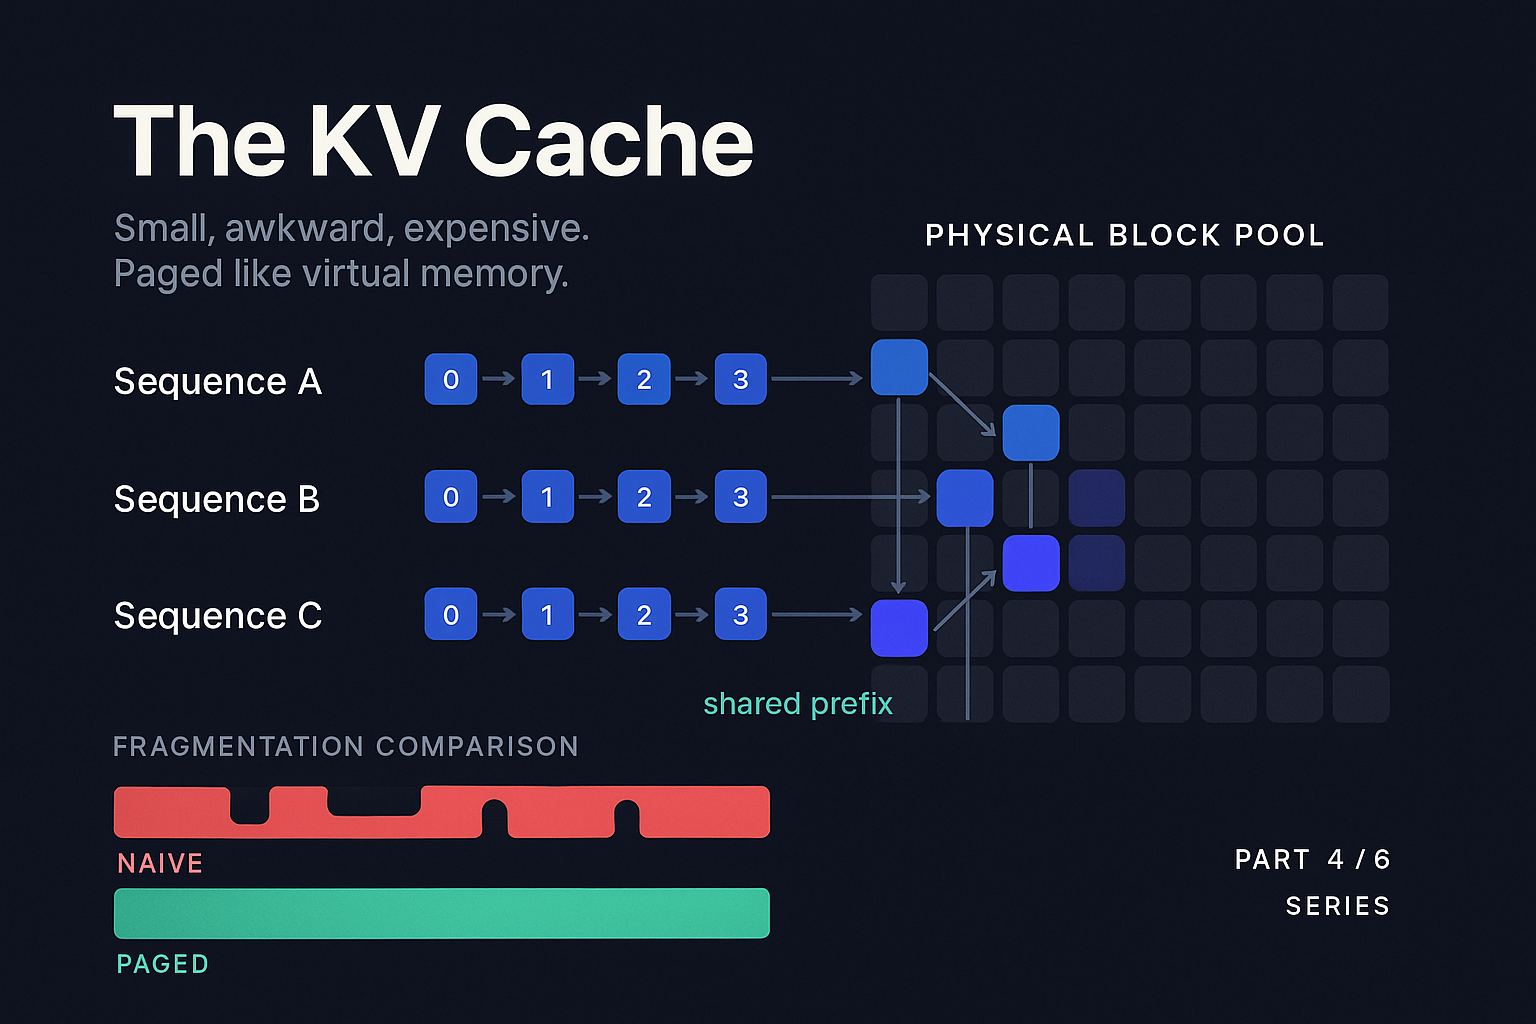
The KV Cache - Part 4 of 6 - Strongly.AI
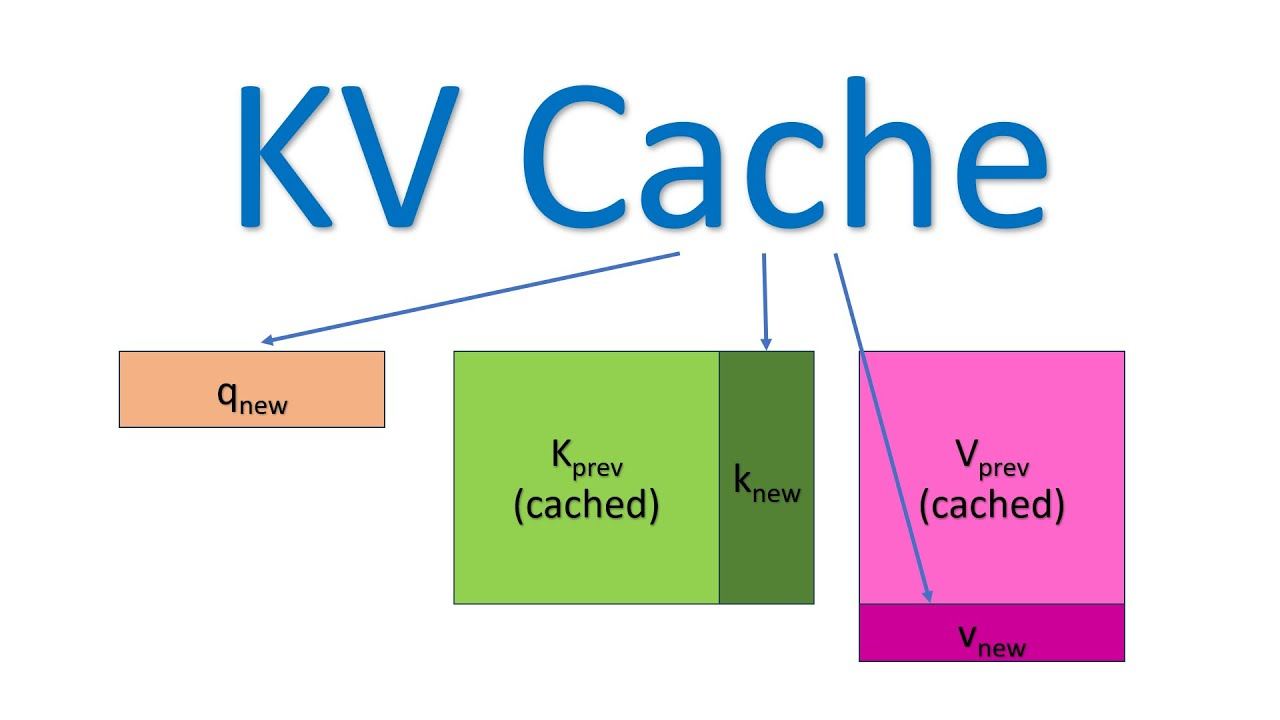
KV Cache 详解:新手也能理解的 LLM 推理加速技巧-CSDN博客

[논문 리뷰] Dual-Signal Adaptive KV-Cache Optimization for Long-Form Video ...
Advertisement Space (336x280)
Architectures of Efficiency: A Comprehensive Analysis of KV Cache ...

KV Cache Optimization: A Deep Dive into PagedAttention & FlashAttention ...
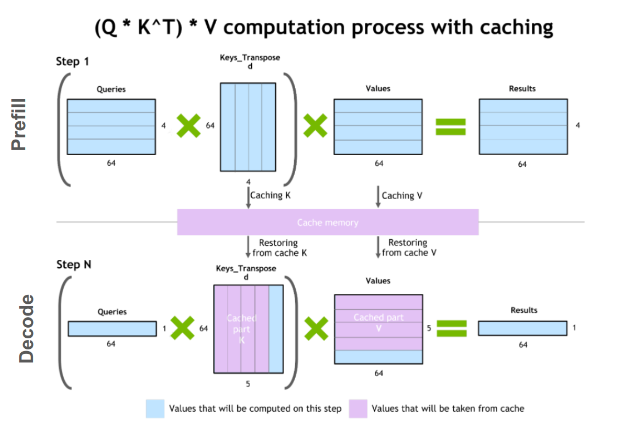
Attention Mechanism 최적화와 KV Cache 계산 | Jongsu Liam Kim | Blog
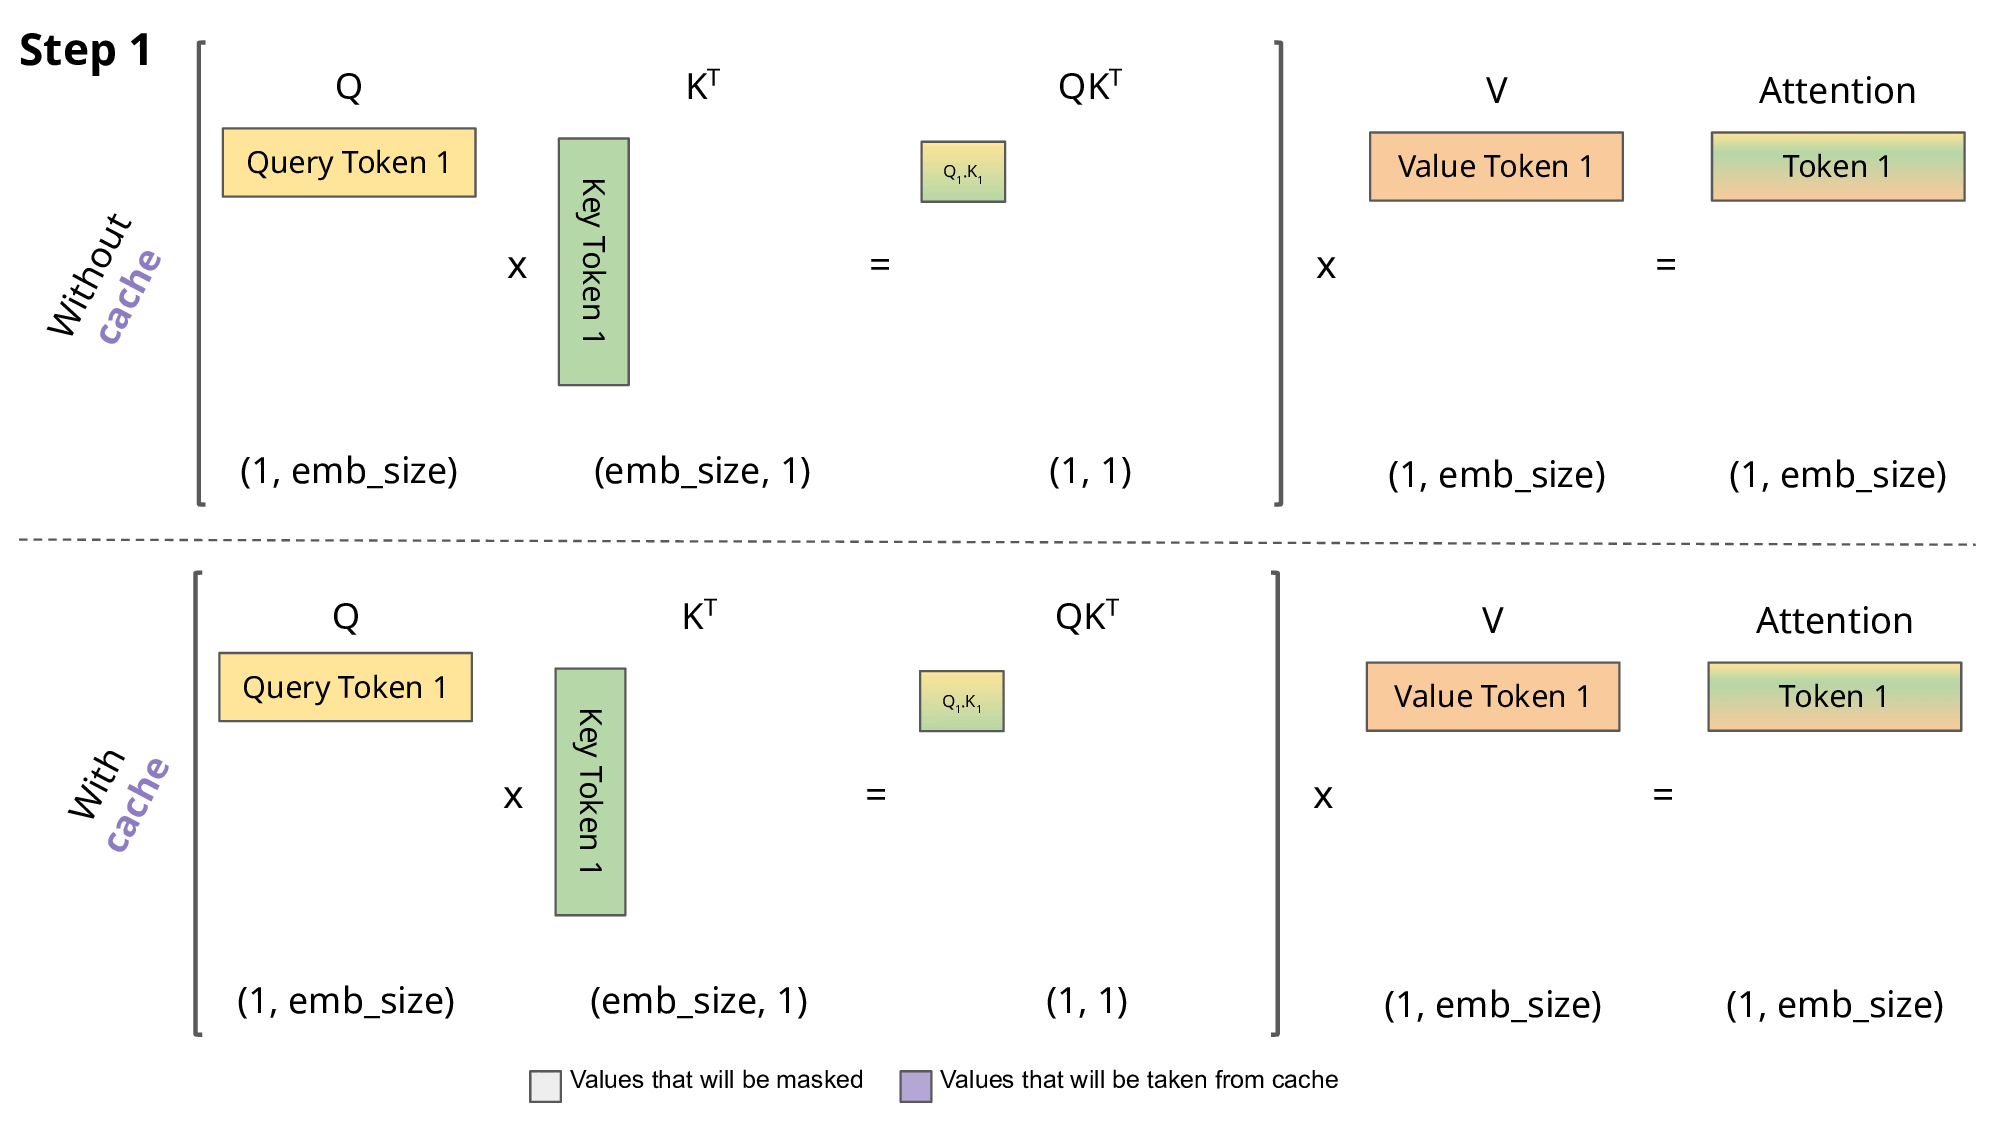
KV cache 缓存与量化:加速大型语言模型推理的关键技术_kvcache的量化怎么做-CSDN博客
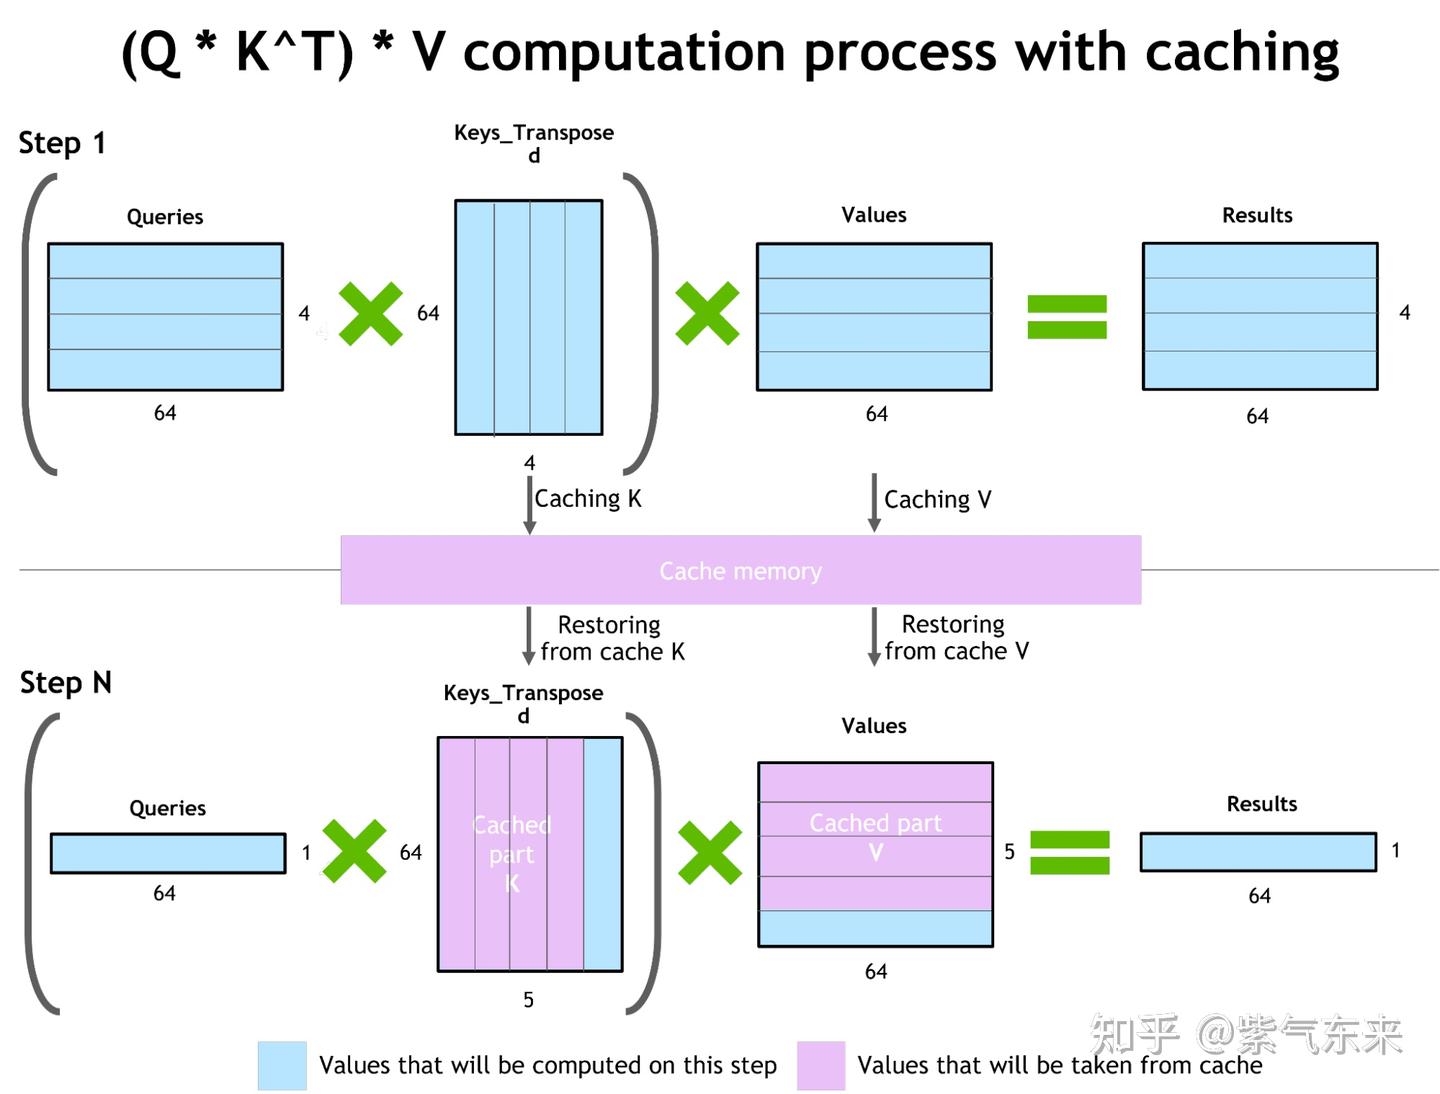
LLM(20):漫谈 KV Cache 优化方法,深度理解 StreamingLLM - 知乎

kv cache 共享可以带来什么 - 知乎