
Figure 1 From Rhythm Modeling For Voice Conversion Semantic Scholar

Figure 1 from Rhythm Modeling for Voice Conversion | Semantic Scholar

Figure 1 from An overview of voice conversion systems | Semantic Scholar
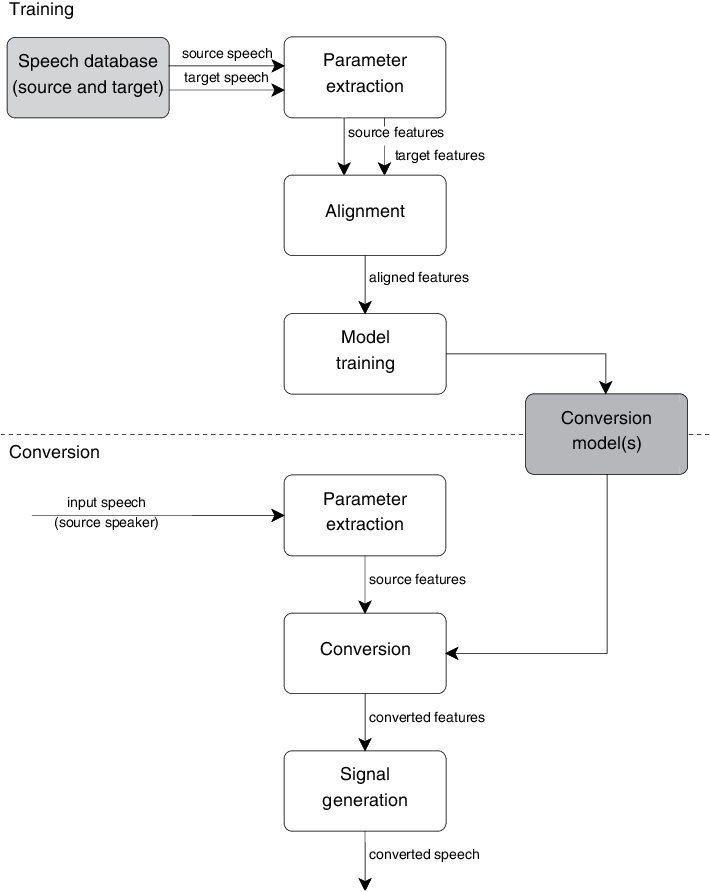
Figure 1 from Voice conversion | Semantic Scholar
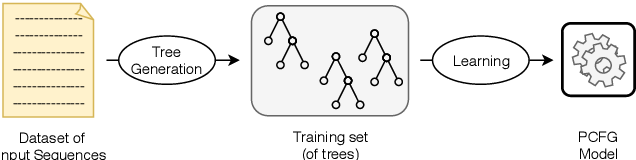
Figure 1 from Modeling and Learning Rhythm Structure | Semantic Scholar

Figure 1 from DeepGen Network based Voice Conversion | Semantic Scholar
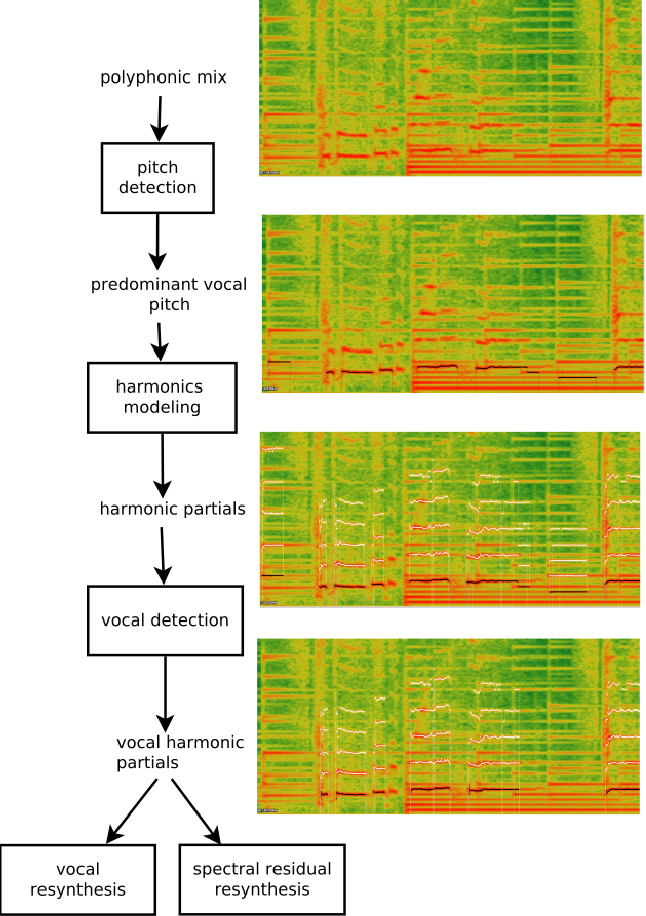
Figure 1 from Singing Voice Separation by Harmonic Modeling | Semantic ...

Figure 1 from Average Modeling Approach to Voice Conversion with Non ...

Figure 1 from The NU Non-Parallel Voice Conversion System for the Voice ...
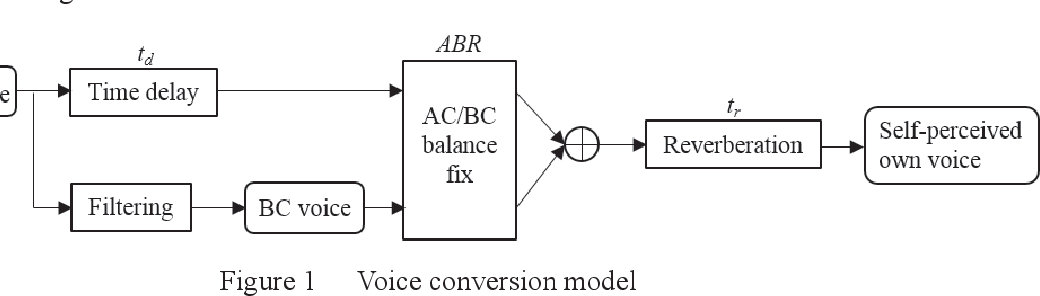
Figure 1 from Voice conversion model for estimation of transfer ...
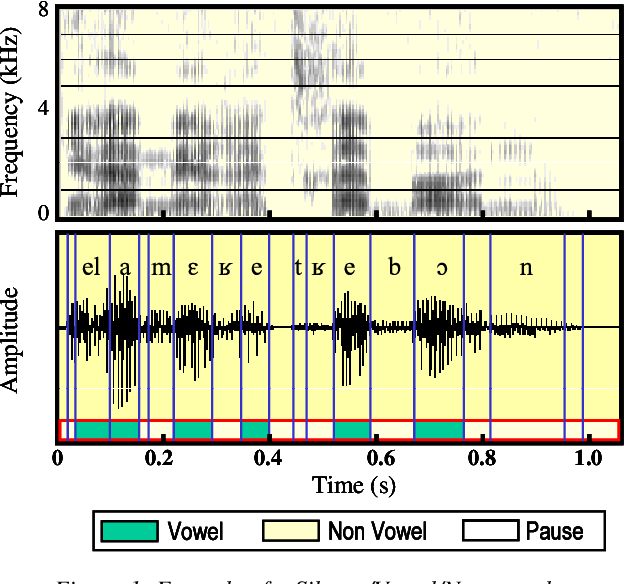
Figure 1 from Automatic rhythm modeling for language identification ...
Advertisement Space (300x250)
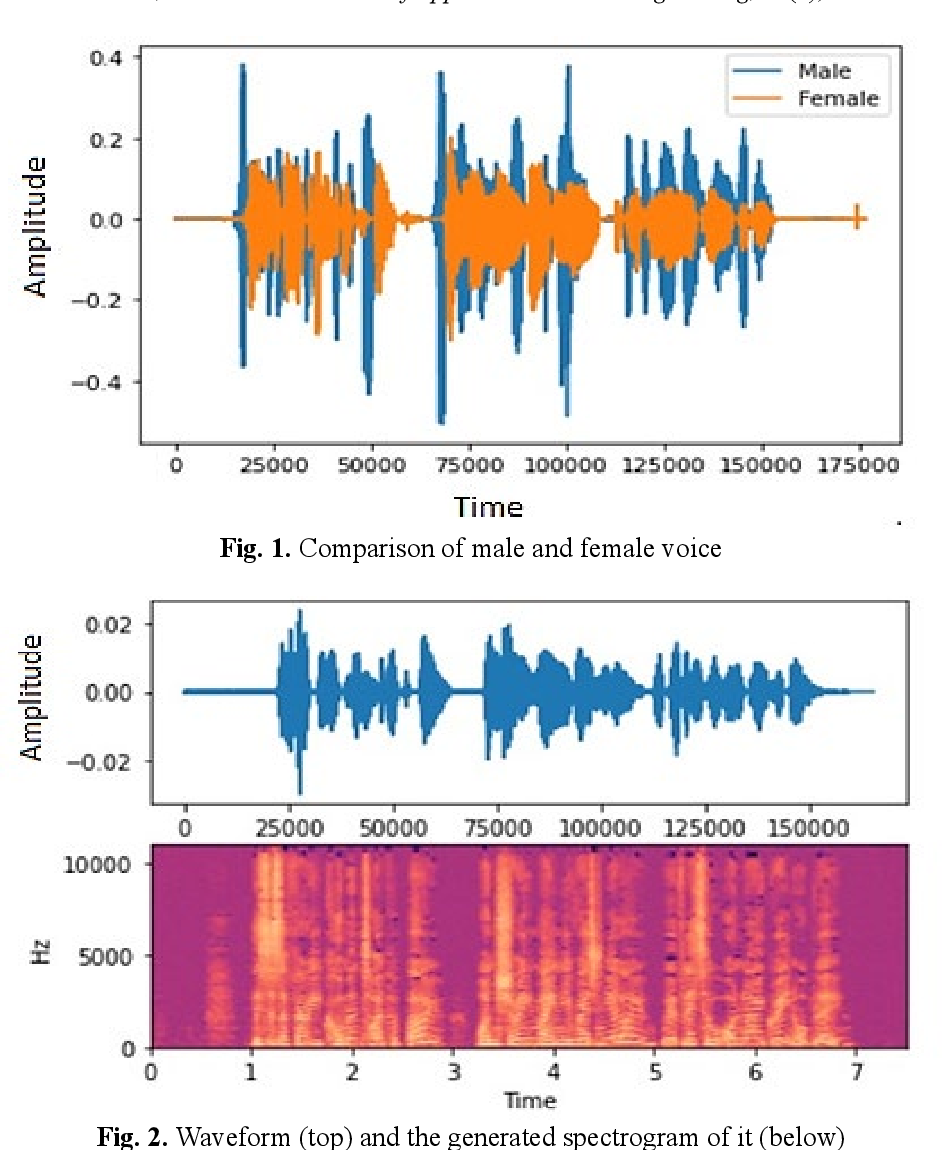
Figure 1 from Audio style conversion using deep learning | Semantic Scholar
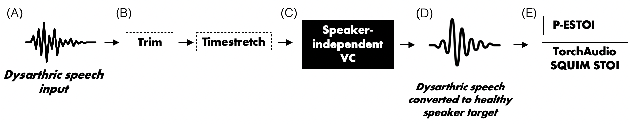
Figure 1 from Towards Speaker-Independent Voice Conversion for ...

Figure 1 from Statistical Voice Conversion Based on Wavenet | Semantic ...
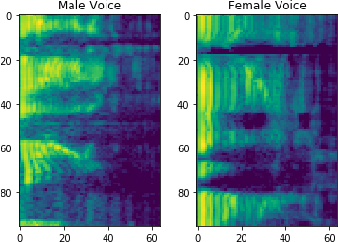
Figure 1 from Voice Conversion using Generative Techniques | Semantic ...
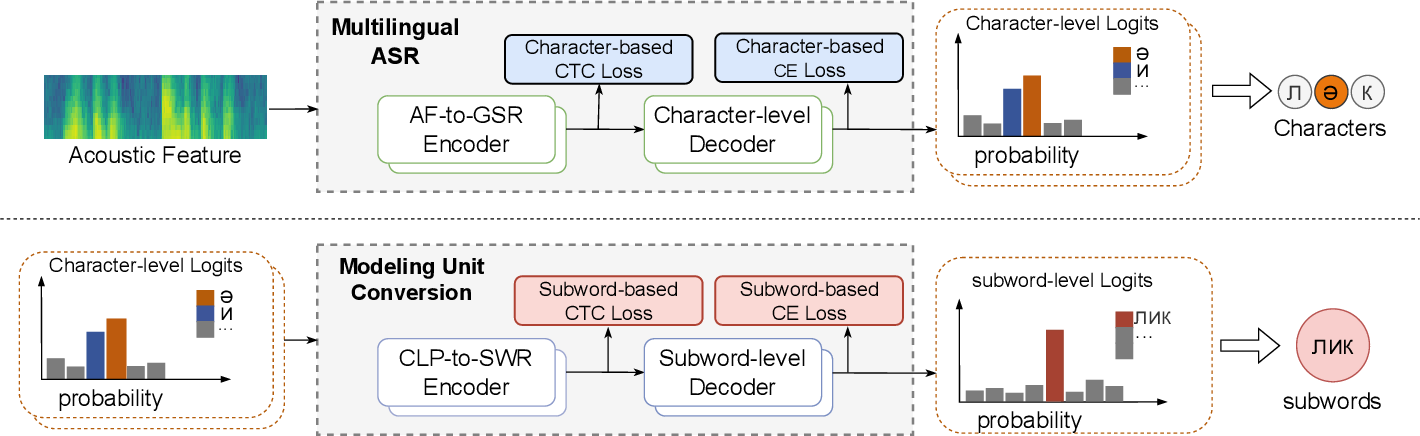
Figure 1 from From Characters to Subwords: Modeling Unit Conversion for ...
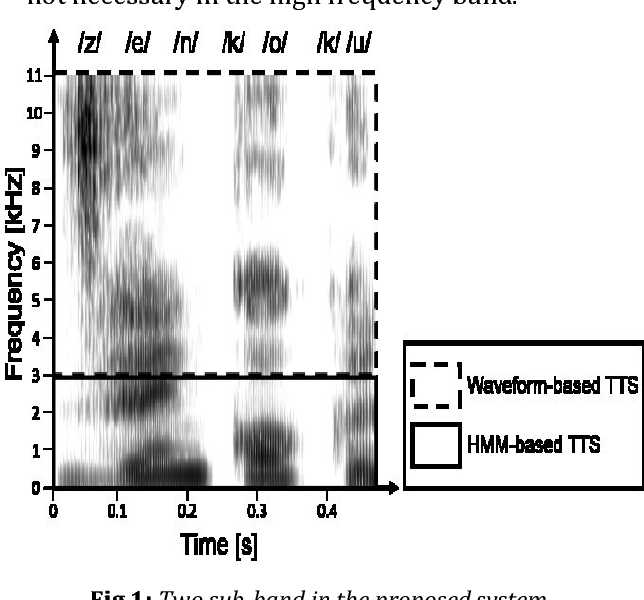
Figure 1 from Text-to-Speech Conversion | Semantic Scholar

Figure 1 from Voice Conversion Augmentation for Speaker Recognition on ...
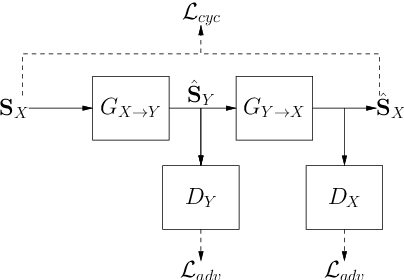
Figure 1 from The UFRJ Entry for the Voice Conversion Challenge 2020 ...

Figure 1 from Transformation of formants for voice conversion using ...

Figure 1 from Low-latency Real-time Voice Conversion on CPU | Semantic ...
Advertisement Space (336x280)
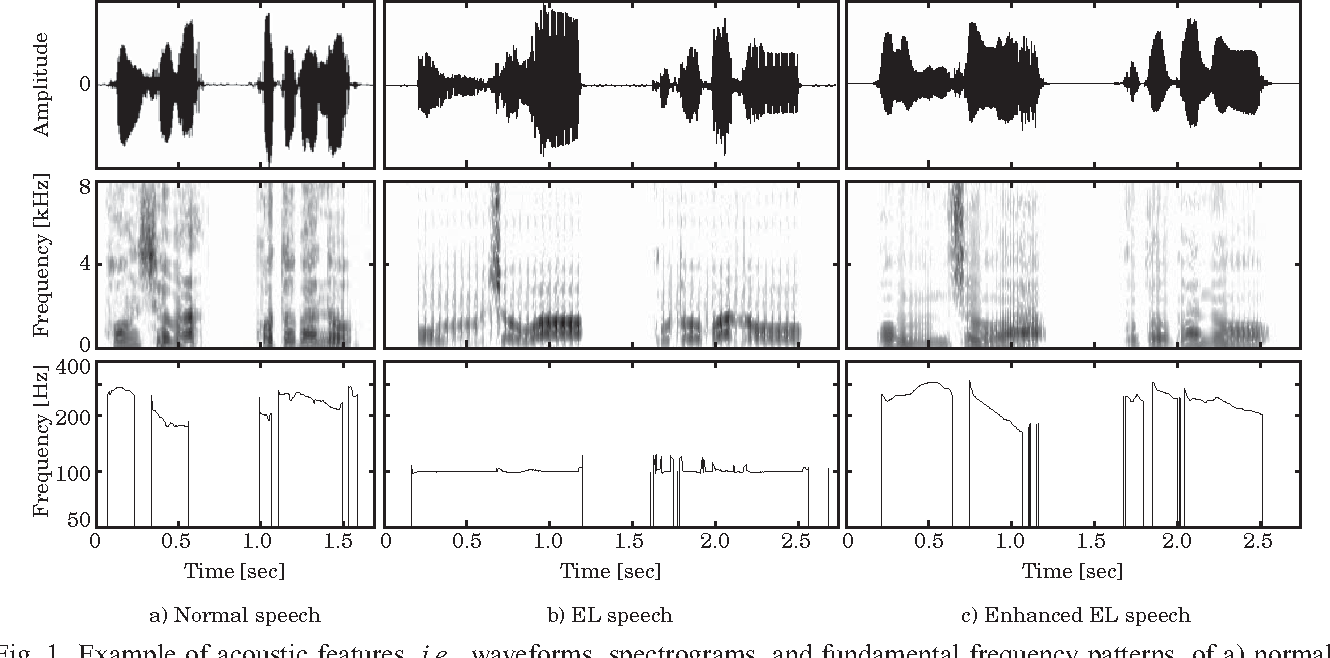
Figure 1 from Statistical Voice Conversion Techniques for Alaryngeal ...
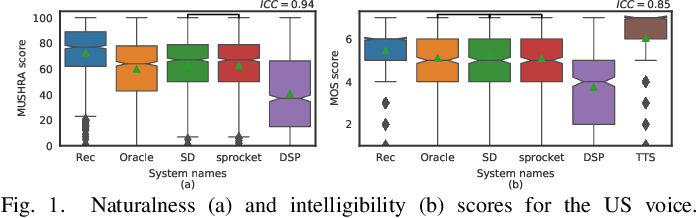
Figure 1 from Voice Conversion for Whispered Speech Synthesis ...

Figure 1 from Improved F0 modeling and generation in voice conversion ...

Figure 1 from NU Voice Conversion System for the Voice Conversion ...
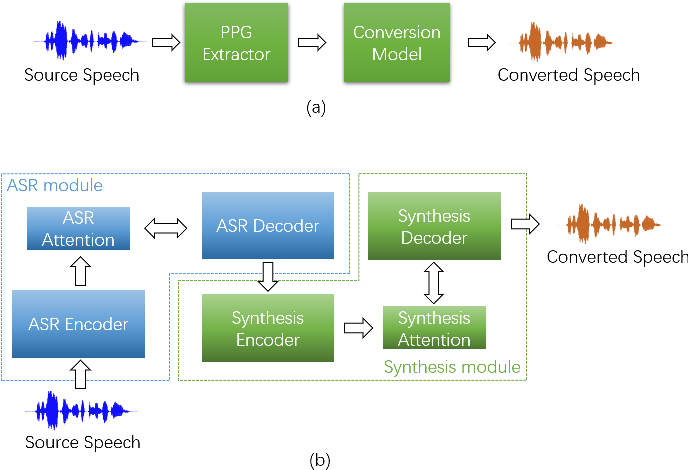
Figure 1 from Any-to-Many Voice Conversion With Location-Relative ...

Figure 1 from A Voice Conversion Framework with Tandem Feature Sparse ...
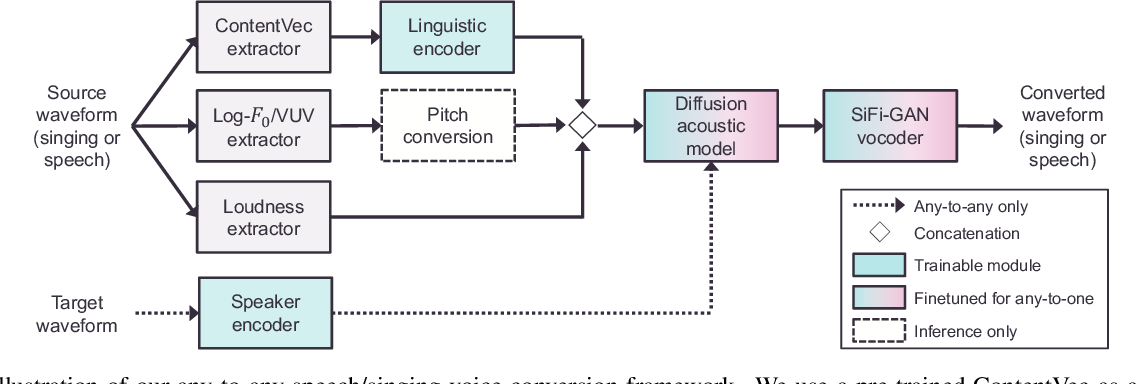
Figure 1 from A Comparative Study of Voice Conversion Models with Large ...

Figure 1 from PMVC: Data Augmentation-Based Prosody Modeling for ...
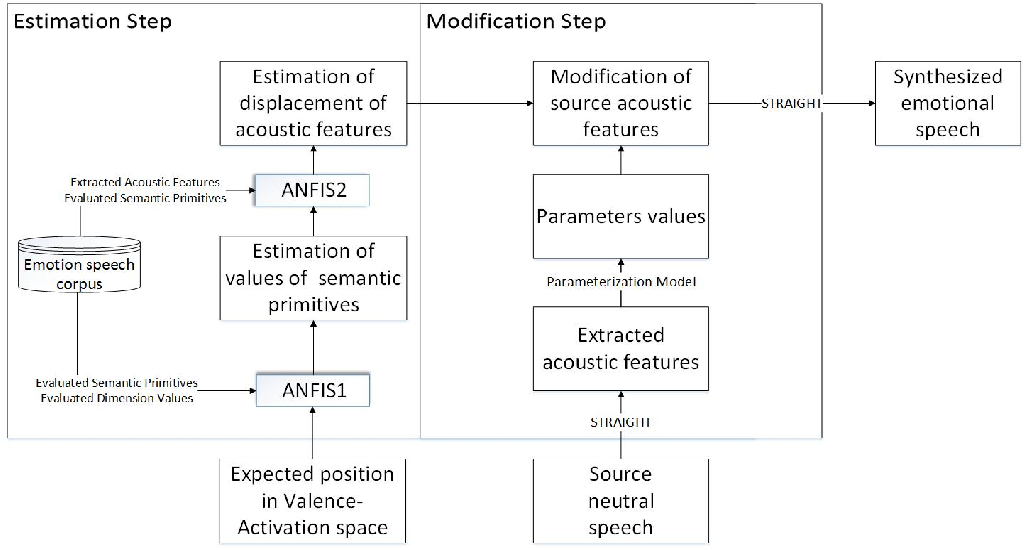
Figure 1 from Voice conversion to emotional speech based on three ...
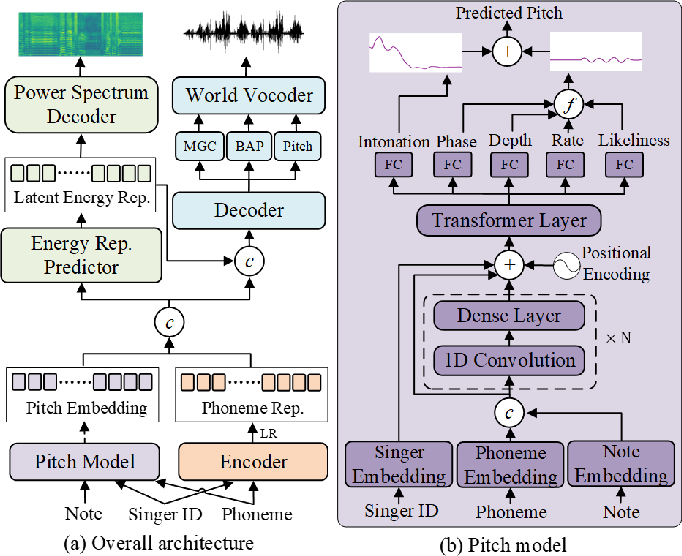
Figure 1 from Singing Voice Synthesis with Vibrato Modeling and Latent ...
Advertisement Space (336x280)
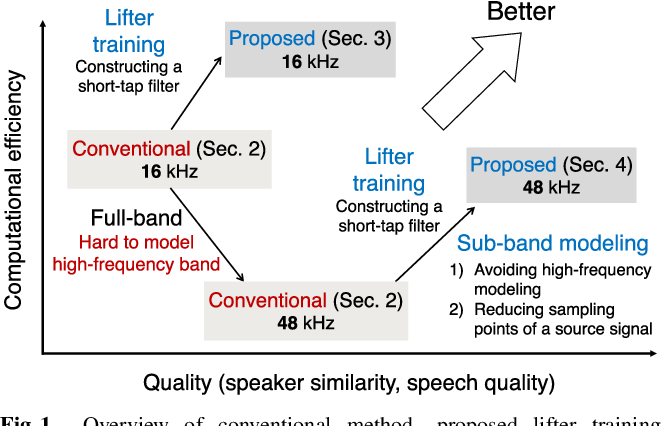
Figure 1 from Real-Time Full-Band Voice Conversion with Sub-Band ...

Figure 1 from DVQVC: An Unsupervised Zero-Shot Voice Conversion ...

Figure 1 from Jointly Trained Conversion Model With LPCNet for Any-to ...

Figure 1 from Style-transfer Autoencoder for Efficient Deep Voice ...

Figure 1 from Statistical singing voice conversion with direct waveform ...
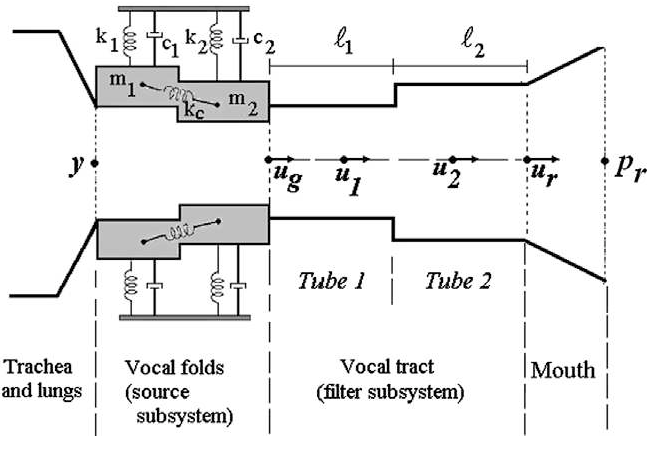
Figure 1 from Modeling random uncertainties in voice production using a ...