
Figure 1 From Streaming Multi Speaker Asr With Rnn T Semantic Scholar

Figure 1 from Streaming Multi-Speaker ASR with RNN-T | Semantic Scholar

Table 1 from Streaming Multi-Speaker ASR with RNN-T | Semantic Scholar
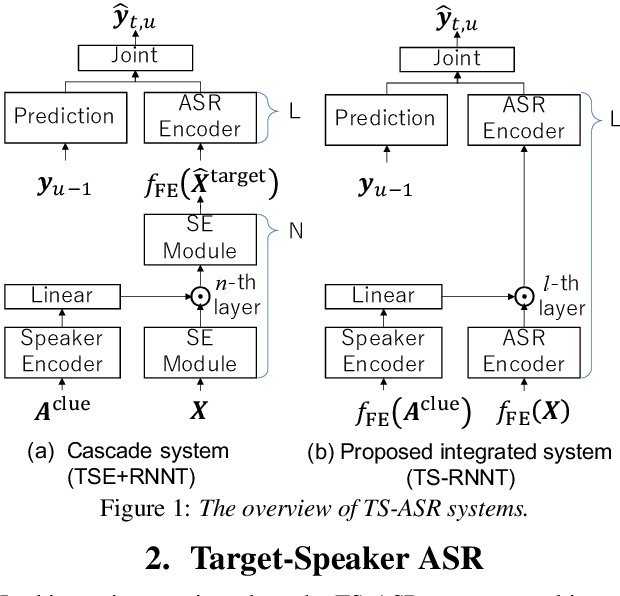
Figure 1 from Streaming Target-Speaker ASR with Neural Transducer ...
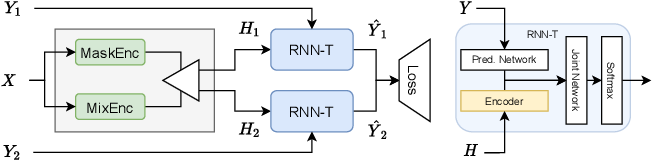
Figure 1 from Continuous Streaming Multi-Talker ASR with Dual-Path ...
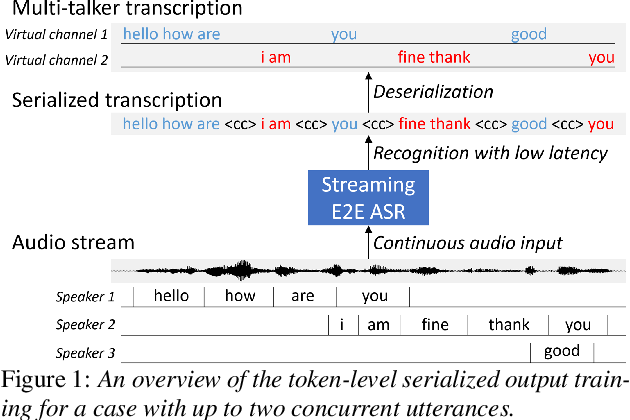
Figure 1 from Streaming Multi-Talker ASR with Token-Level Serialized ...
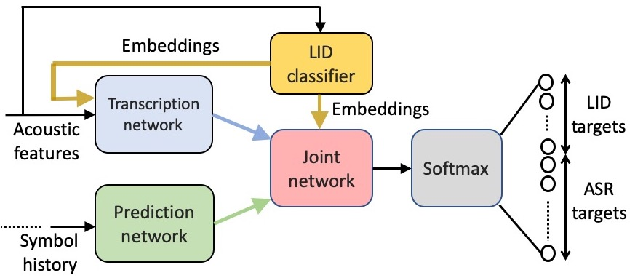
Figure 1 from Streaming End-to-End Bilingual ASR Systems with Joint ...
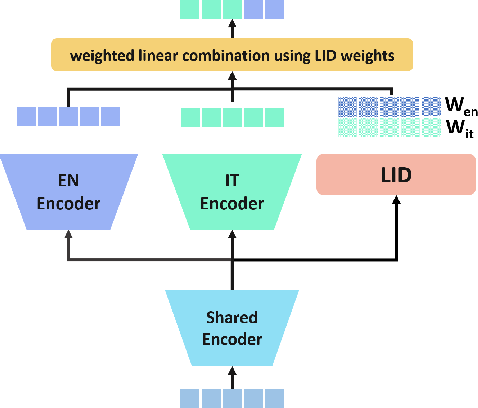
Figure 1 from Bilingual Streaming ASR with Grapheme units and Auxiliary ...
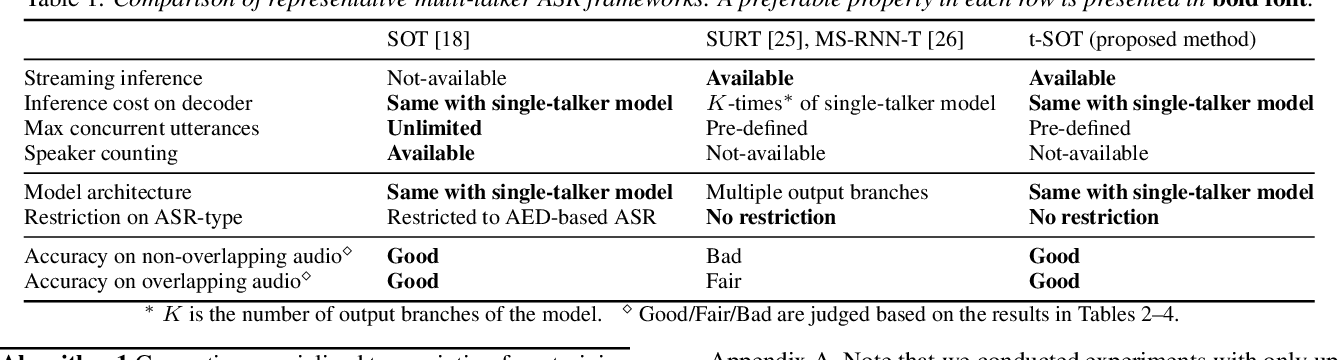
Figure 1 from Streaming Multi-Talker ASR with Token-Level Serialized ...
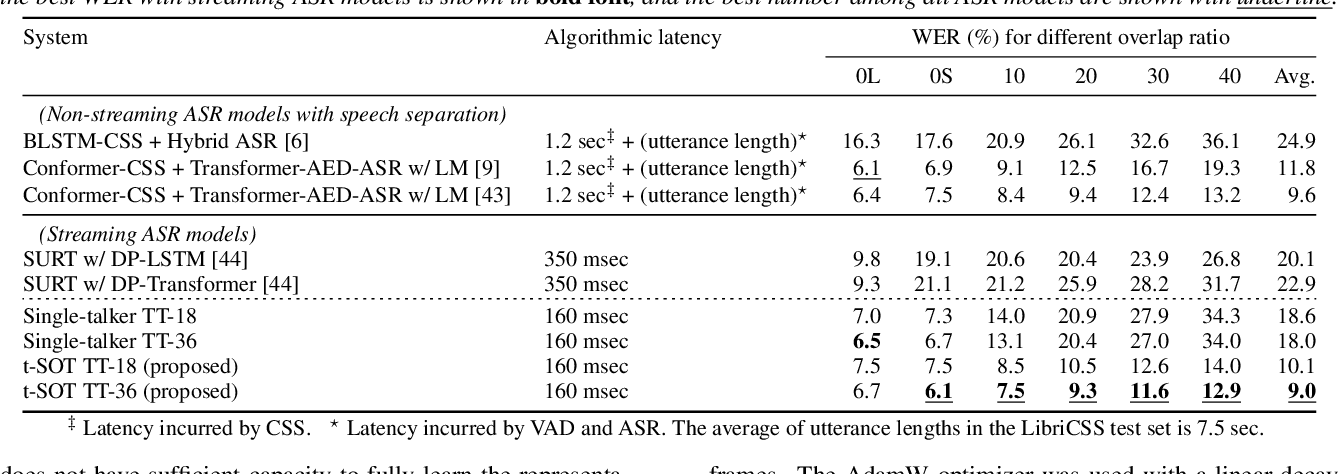
Figure 1 from Streaming Multi-Talker ASR with Token-Level Serialized ...

Figure 1 from Improving RNN Transducer Based ASR with Auxiliary Tasks ...
Advertisement Space (300x250)
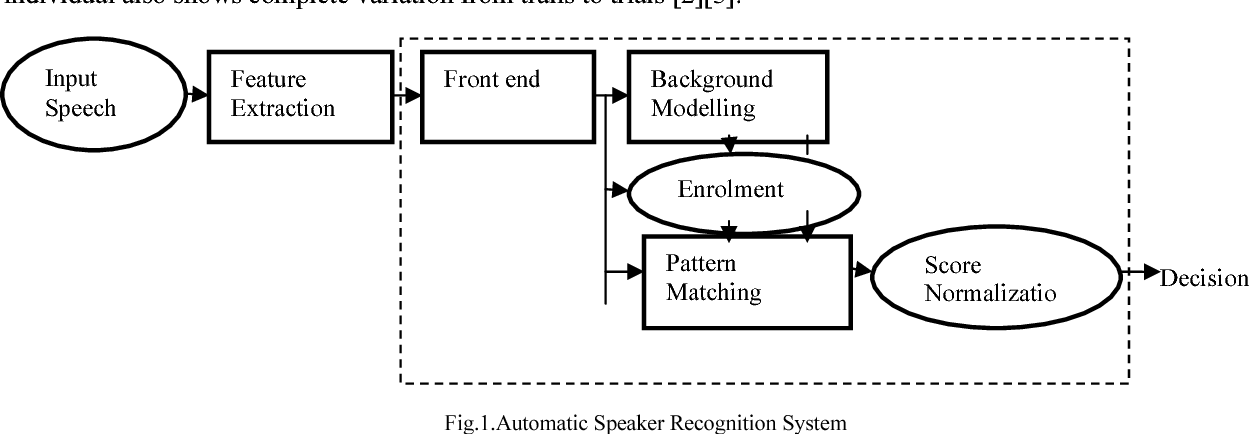
Figure 1 from A Review on Speaker Recognition | Semantic Scholar
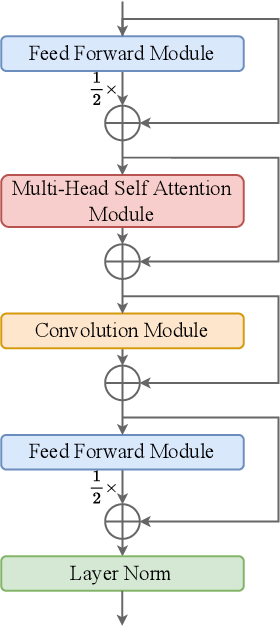
Figure 1 from Pretraining Conformer with ASR for Speaker Verification ...

Figure 1 from Speaker diarization assisted ASR for multi-speaker ...

Figure 1 from MSA-ASR: Efficient Multilingual Speaker Attribution with ...

Figure 1 from Multi-Task RNN-T with Semantic Decoder for Streamable ...

Figure 1 from Enhancing Monotonic Multihead Attention for Streaming ASR ...

Figure 1 from Streaming Bilingual End-to-End ASR Model Using Attention ...

Figure 1 from A Method to Reveal Speaker Identity in Distributed ASR ...

Figure 1 from Multi-modal ASR error correction with joint ASR error ...

Figure 1 from Improving ASR Performance with OCR Through Using Word ...
Advertisement Space (336x280)

Table 1 from Continuous Streaming Multi-Talker ASR with Dual-Path ...
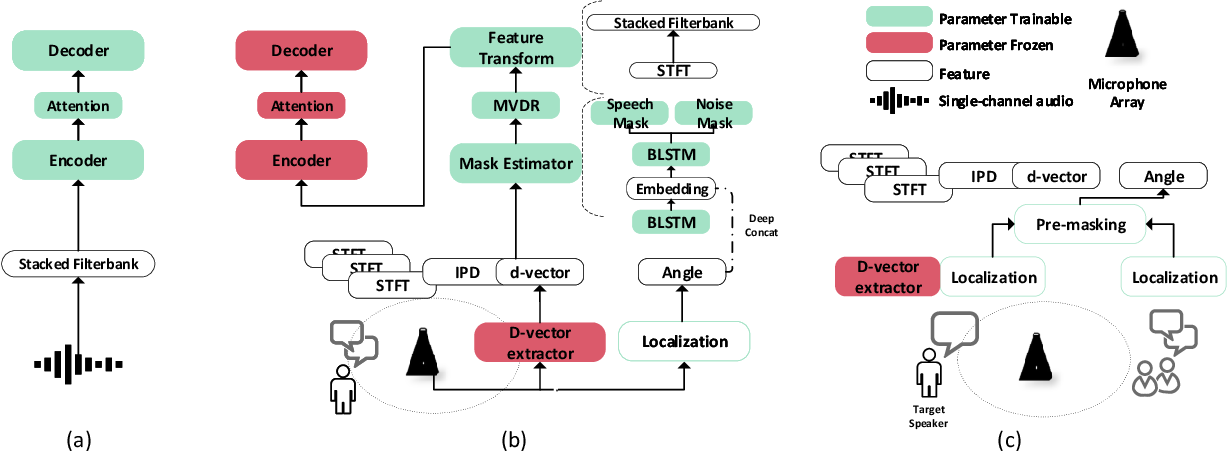
Figure 1 from Exploring End-to-End Multi-Channel ASR with Bias ...

Figure 1 from A Language Agnostic Multilingual Streaming On-Device ASR ...
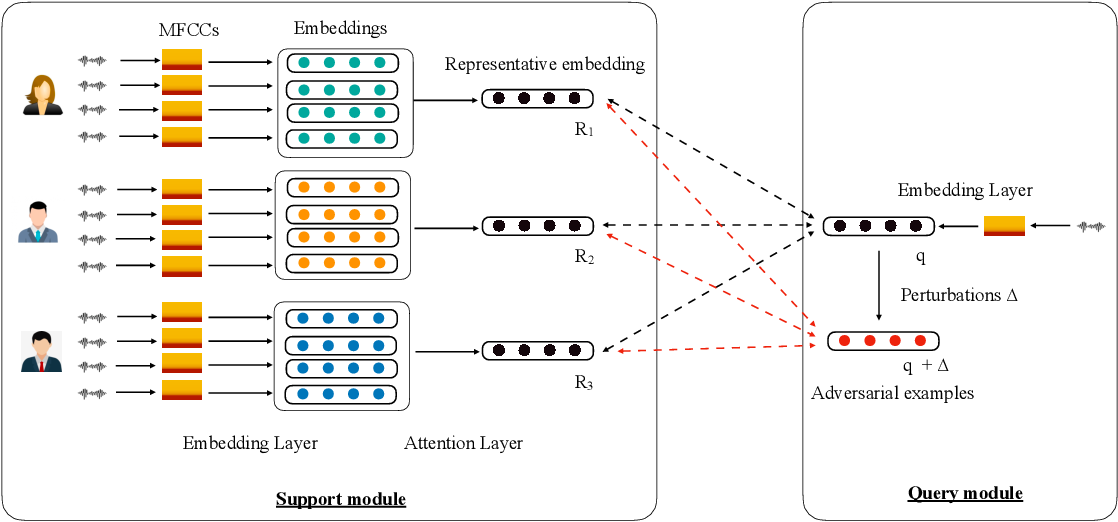
Figure 1 from Automatic Speaker Recognition with Limited Data ...

Figure 1 from Towards interfacing large language models with ASR ...

Figure 1 from An ASR system using MFCC and VQ/GMM with emphasis on ...

Figure 1 from Advancing Multi-Talker ASR Performance With Large ...

Figure 1 from Robust Audio-Visual ASR with Unified Cross-Modal ...

Figure 1 from LA-RAG:Enhancing LLM-based ASR Accuracy with Retrieval ...
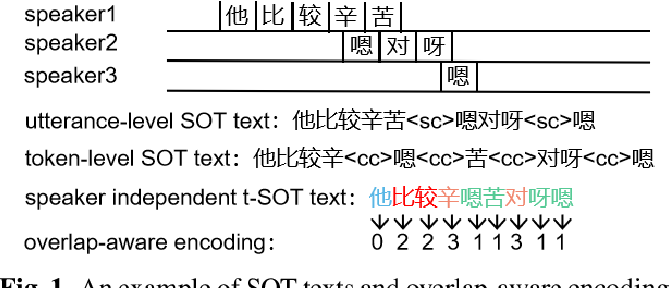
Figure 1 from Improving Multi-Speaker ASR With Overlap-Aware Encoding ...
Advertisement Space (336x280)

Figure 1 from Speaker adaptation for Wav2vec2 based dysarthric ASR ...
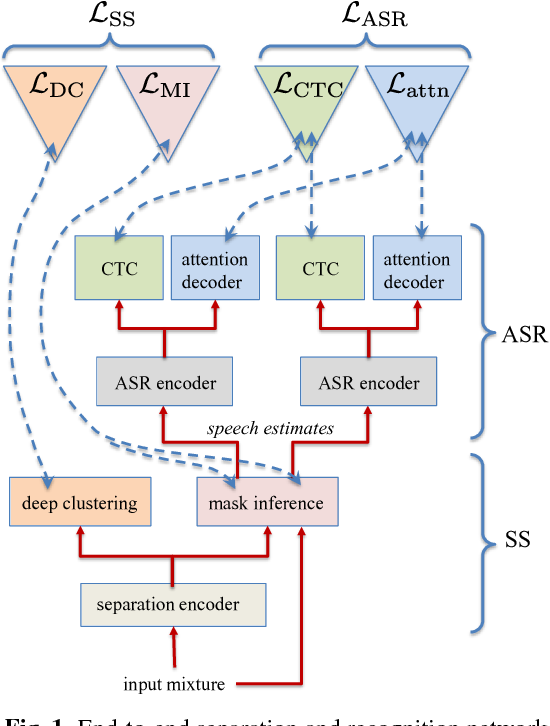
Figure 1 from End-to-End Multi-Speaker Speech Recognition | Semantic ...

Figure 1 from End-to-End Multi-Speaker Speech Recognition using Speaker ...
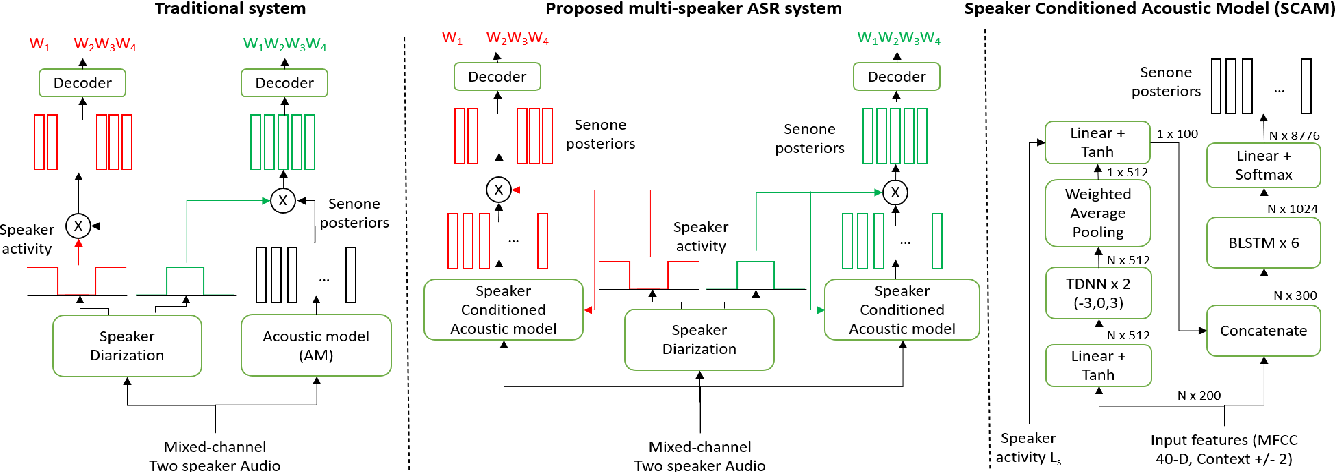
Figure 1 from Speaker conditioned acoustic modeling for multi-speaker ...
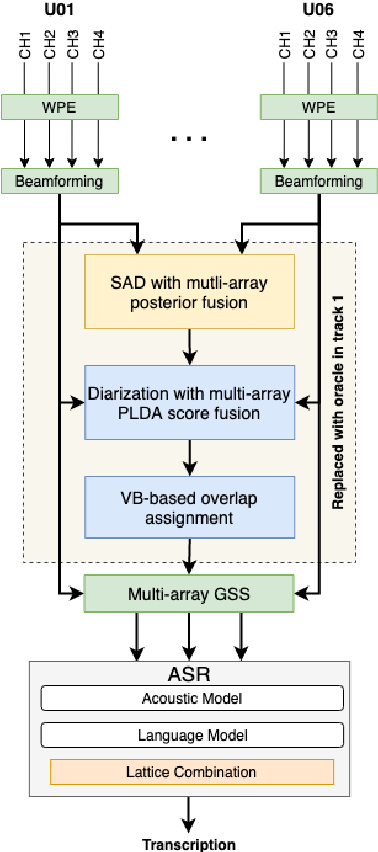
Figure 1 from The JHU Multi-Microphone Multi-Speaker ASR System for the ...
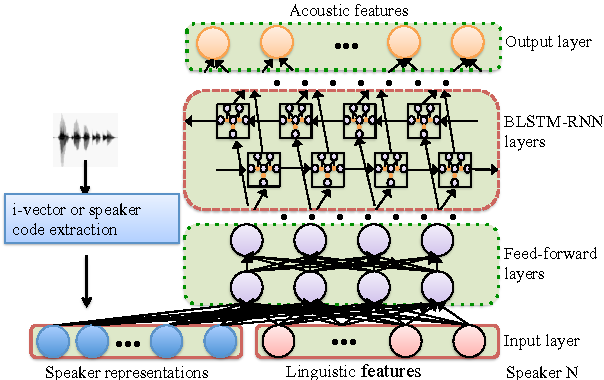
Figure 1 from Speaker Representations for Speaker Adaptation in ...