
Table 1 From Streaming Multi Speaker Asr With Rnn T Semantic Scholar

Table 1 from Streaming Multi-Speaker ASR with RNN-T | Semantic Scholar

Figure 1 from Streaming Multi-Speaker ASR with RNN-T | Semantic Scholar

Table 1 from Continuous Streaming Multi-Talker ASR with Dual-Path ...

Table 1 from Streaming Target-Speaker ASR with Neural Transducer ...

Table 1 from Partial Rewriting for Multi-Stage ASR | Semantic Scholar
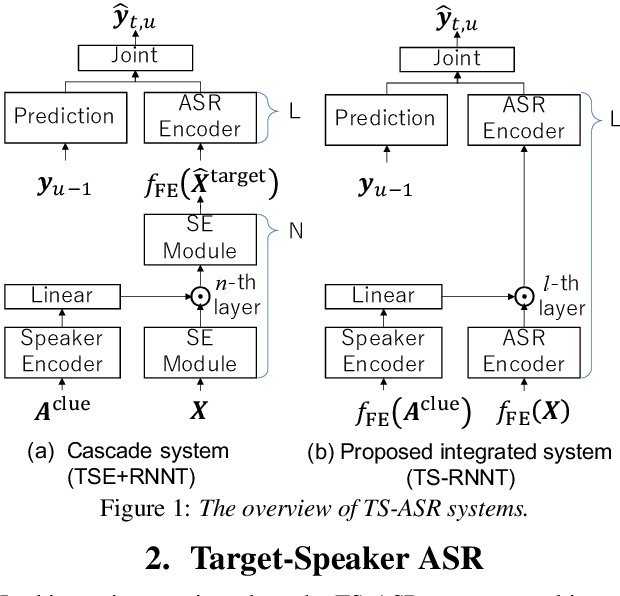
Figure 1 from Streaming Target-Speaker ASR with Neural Transducer ...

Table 1 from Speaker diarization assisted ASR for multi-speaker ...
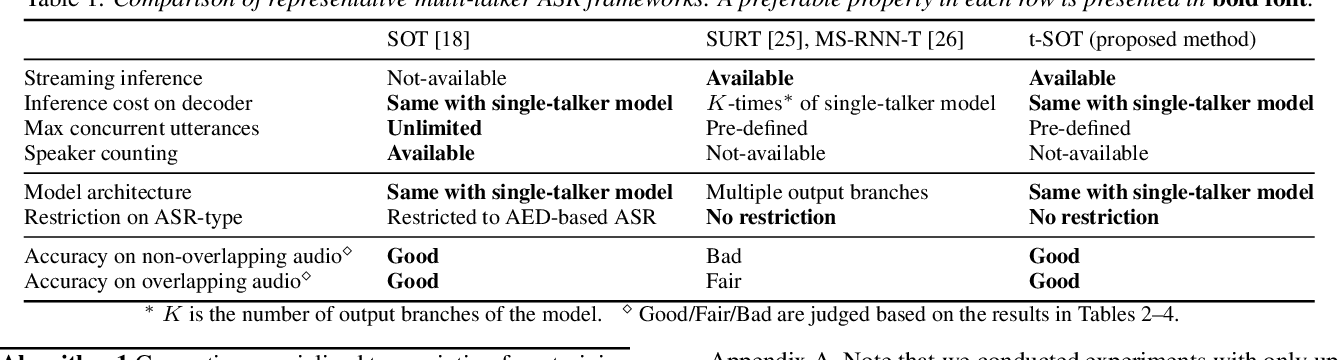
Figure 1 from Streaming Multi-Talker ASR with Token-Level Serialized ...
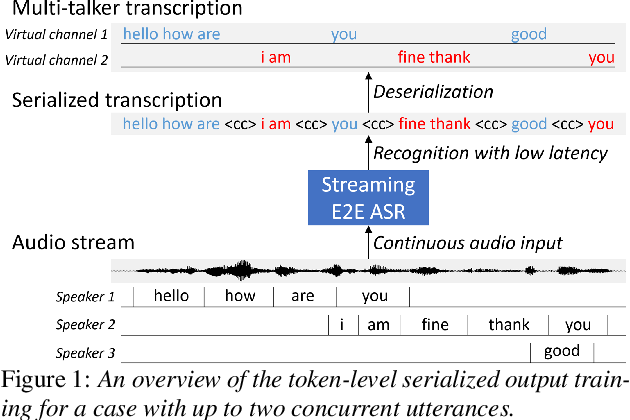
Figure 1 from Streaming Multi-Talker ASR with Token-Level Serialized ...
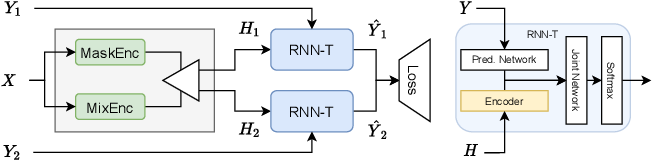
Figure 1 from Continuous Streaming Multi-Talker ASR with Dual-Path ...
Advertisement Space (300x250)

Table 1 from Advancing Multi-Talker ASR Performance With Large Language ...

Table 1 from Multi-Task RNN-T with Semantic Decoder for Streamable ...
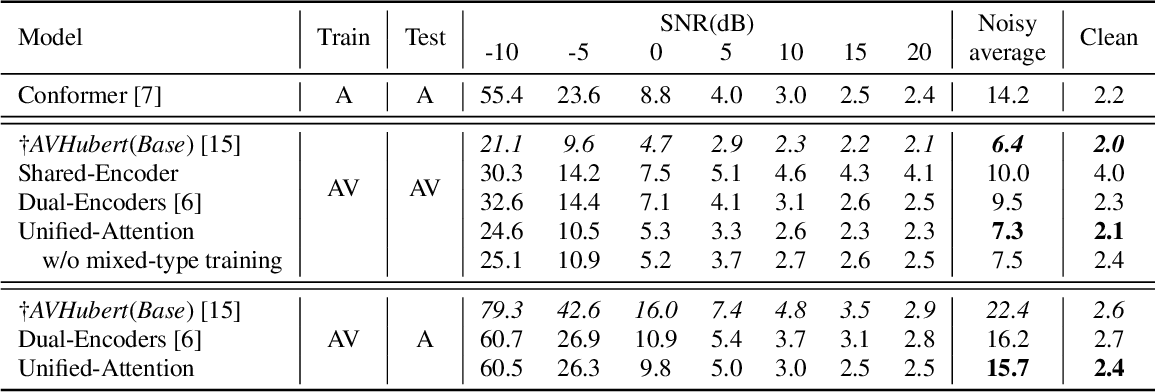
Table 1 from Robust Audio-Visual ASR with Unified Cross-Modal Attention ...
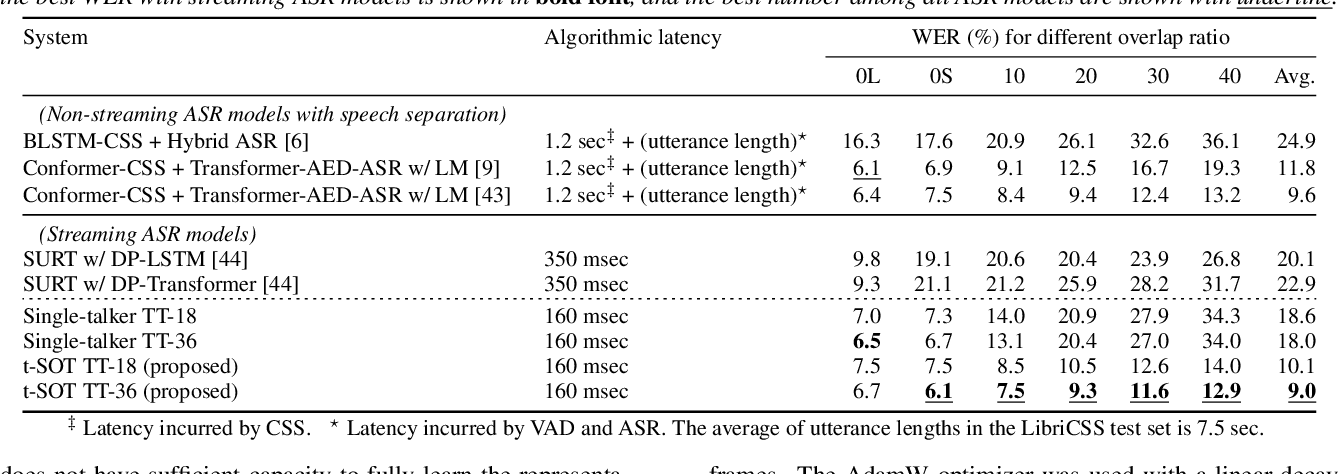
Figure 1 from Streaming Multi-Talker ASR with Token-Level Serialized ...

Table 2 from Streaming Multi-Talker ASR with Token-Level Serialized ...
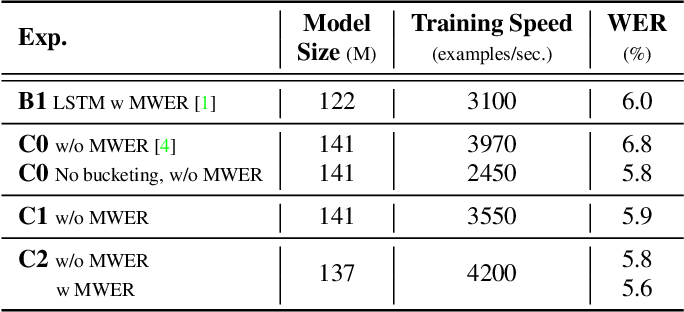
Table 1 from A Better and Faster end-to-end Model for Streaming ASR ...
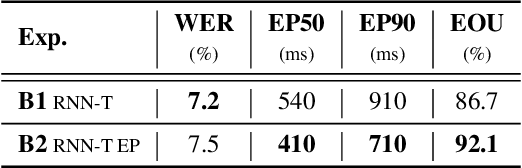
Table 1 from Towards Fast and Accurate Streaming End-To-End ASR ...

Table 1 from Robust multi-modal speech emotion recognition with ASR ...

Table 1 from Investigations on speaker adaptation of LSTM RNN models ...

Table 1 from Improving Massively Multilingual ASR with Auxiliary CTC ...
Advertisement Space (336x280)

Figure 1 from Bilingual Streaming ASR with Grapheme units and Auxiliary ...

Table 1 from Speaker Change Detection For Transformer Transducer ASR ...

Table 1 from RNN-T For Latency Controlled ASR With Improved Beam Search ...

Table 1 from Multi-modal ASR error correction with joint ASR error ...
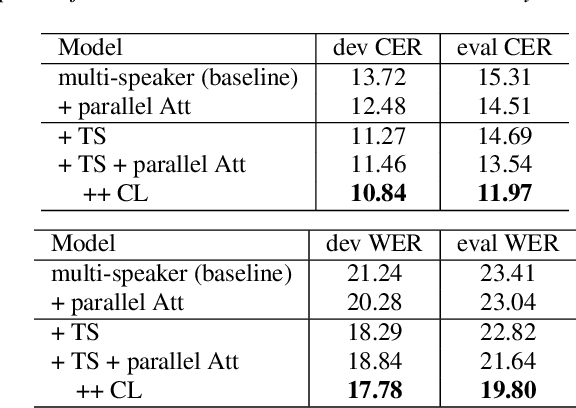
Table 1 from Knowledge Distillation for End-to-End Monaural Multi ...

Table 1 from End-to-End Joint Target and Non-Target Speakers ASR ...

Table 1 from End-To-End Multi-Speaker Speech Recognition With ...

Figure 1 from MSA-ASR: Efficient Multilingual Speaker Attribution with ...

Figure 1 from Speaker diarization assisted ASR for multi-speaker ...
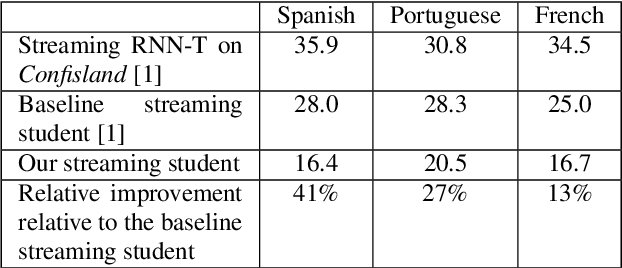
Table 5 from Bridging the gap between streaming and non-streaming ASR ...
Advertisement Space (336x280)

Table 1 from Improving ASR Robustness in Noisy Condition Through VAD ...
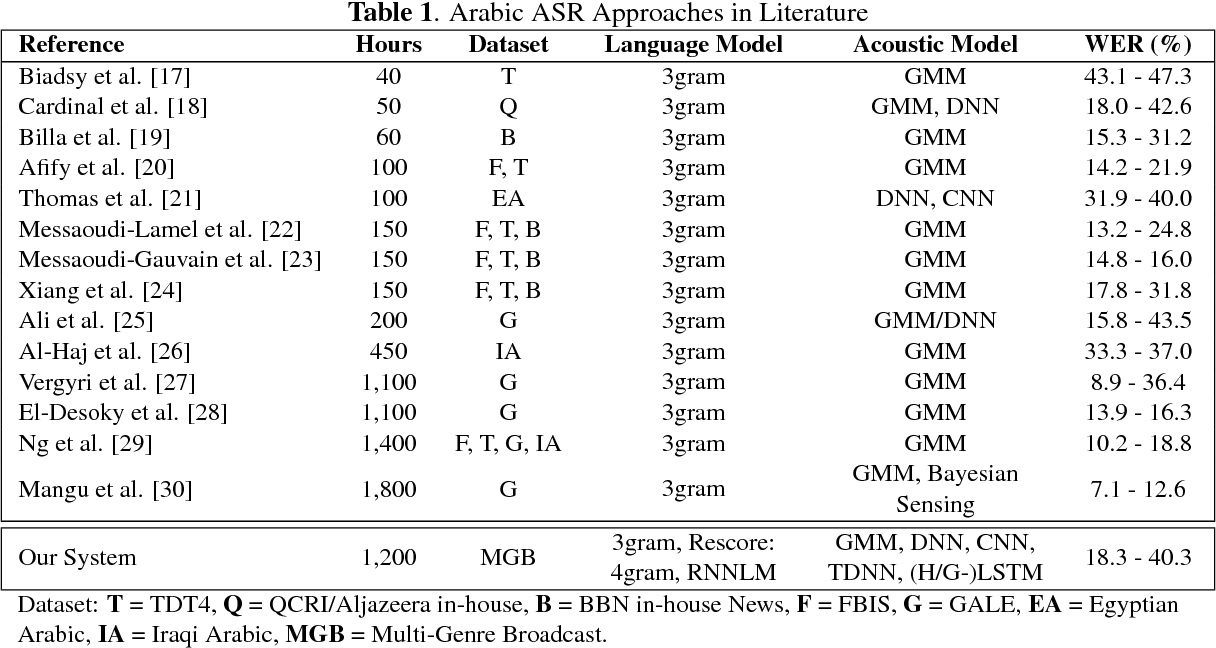
Table 1 from Development of the MIT ASR system for the 2016 Arabic ...

Figure 1 from Multi-Task RNN-T with Semantic Decoder for Streamable ...
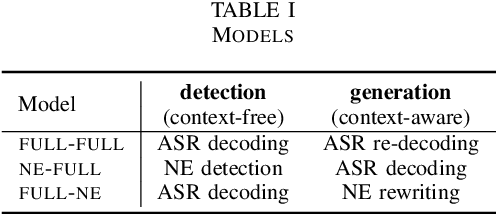
Table I from Contextualization of ASR with LLM using phonetic retrieval ...

Table 1 from Low Resource Comparison of Attention-based and Hybrid ASR ...

Figure 1 from Improving Multi-Speaker ASR With Overlap-Aware Encoding ...